-
-
-
-
-
-
-
-
-
-
-
-
-
+
+
+
+ B站历史
+
+
+
+
{{ syncMessage }}
+
+
+
+
+
+
+
+
正在加载…
+
+ {{ errorMessage }}
+
+
+
{{ query.trim() ? '暂无匹配的历史记录。' : '暂无历史记录,请在设置中登录 B站后同步。' }}
+
+
已显示全部匹配记录。
-
-
+
+watch(query, () => loadRecords(true))
+onMounted(() => loadRecords(true))
+
diff --git a/frontend/src/components/tailwind/page/Images.vue b/frontend/src/components/tailwind/page/Images.vue
deleted file mode 100644
index 508ec2d..0000000
--- a/frontend/src/components/tailwind/page/Images.vue
+++ /dev/null
@@ -1,397 +0,0 @@
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
封面图片
- 最后更新: {{ formatTime(status?.last_update) }}
-
-
-
-
-
- 下载进度
- {{ getProgressPercentage(status?.covers, 'covers') }}%
-
-
-
-
-
-
-
-
{{ status?.covers?.total || 0 }}
-
计划下载
-
-
-
{{ status?.covers?.downloaded || 0 }}
-
已下载
-
-
-
{{ status?.covers?.failed || 0 }}
-
失败数
-
-
-
{{ status?.covers?.total_planned || 0 }}
-
待下载
-
-
-
-
-
-
-
-
-
- 错误: {{ item.error }}
- {{ formatTime(item.timestamp) }}
-
-
URL: {{ item.url }}
-
-
-
-
-
-
-
-
-
头像图片
-
-
-
-
-
- 下载进度
- {{ getProgressPercentage(status?.avatars, 'avatars') }}%
-
-
-
-
-
-
-
-
{{ status?.avatars?.total || 0 }}
-
计划下载
-
-
-
{{ status?.avatars?.downloaded || 0 }}
-
已下载
-
-
-
{{ status?.avatars?.failed || 0 }}
-
失败数
-
-
-
{{ status?.avatars?.total_planned || 0 }}
-
待下载
-
-
-
-
-
-
-
-
-
- 错误: {{ item.error }}
- {{ formatTime(item.timestamp) }}
-
-
URL: {{ item.url }}
-
-
-
-
-
-
-
-
-
-
diff --git a/frontend/src/components/tailwind/page/MediaManager.vue b/frontend/src/components/tailwind/page/MediaManager.vue
deleted file mode 100644
index bf83400..0000000
--- a/frontend/src/components/tailwind/page/MediaManager.vue
+++ /dev/null
@@ -1,197 +0,0 @@
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
\ No newline at end of file
diff --git a/frontend/src/components/tailwind/page/Remarks.vue b/frontend/src/components/tailwind/page/Remarks.vue
deleted file mode 100644
index 04a3989..0000000
--- a/frontend/src/components/tailwind/page/Remarks.vue
+++ /dev/null
@@ -1,348 +0,0 @@
-
-
-
-
-
-
- 共 {{ total }} 条备注
-
-
-
-
-
-
-
-
-
-
-
-
![]()
-
-
- {{ formatDuration(record.duration) }}
-
-
-
-
-
-
-
-
-
-
-
-
![]()
-
-
-
-
-
{{ formatTimestamp(record.view_at) }}
-
-
-
-
-
-
-
-
- 最后更新: {{ formatRemarkTime(record.remark_time) }}
-
-
-
-
-
-
-
-
-
-
暂无备注
-
当你添加备注后,将在这里显示
-
-
-
-
-
-
-
-
-
-
diff --git a/frontend/src/components/tailwind/page/SchedulerTasks.vue b/frontend/src/components/tailwind/page/SchedulerTasks.vue
deleted file mode 100644
index 83865fd..0000000
--- a/frontend/src/components/tailwind/page/SchedulerTasks.vue
+++ /dev/null
@@ -1,726 +0,0 @@
-
-
-
-
-
-
-
-
-
-
-
-
-
计划任务
-
-
-
-
-
暂无计划任务
-
点击"新建任务"按钮创建您的第一个计划任务
-
-
-
-
-
-
计划任务
-
-
-
-
-
-
-
- | 任务ID |
- 名称 |
- 调度类型 |
- 调度时间 |
- 成功率 |
- 最后执行 |
- 状态 |
-
-
- 操作
- |
-
-
-
-
-
-
-
-
-
- {{ task.task_id }}
- |
-
-
- {{ task.config?.name || task.task_id }}
-
- {{ task.sub_tasks.length }}个子任务
-
-
- |
-
-
- {{
- task.config?.schedule_type === 'daily' ? '每日' :
- task.config?.schedule_type === 'chain' ? '链式' :
- task.config?.schedule_type === 'once' ? '一次性' :
- task.config?.schedule_type === 'interval' ? '间隔' :
- task.config?.schedule_type
- }}
-
- |
-
- {{
- task.config?.schedule_type === 'chain' ? '依赖主任务' :
- task.config?.schedule_type === 'interval' ?
- (task.config?.interval_value || '-') + ' ' +
- (task.config?.interval_unit === 'minutes' ? '分钟' :
- task.config?.interval_unit === 'hours' ? '小时' :
- task.config?.interval_unit === 'days' ? '天' :
- task.config?.interval_unit === 'months' ? '月' :
- task.config?.interval_unit === 'years' ? '年' :
- task.config?.interval_unit || '') :
- task.config?.schedule_time || '-'
- }}
- |
-
-
- {{ Math.round(task.execution.success_rate) }}%
-
-
- -
- |
-
- {{ task.execution?.last_run || '未记录' }}
- |
-
-
- {{ task.config?.enabled ? '已启用' : '已禁用' }}
-
- |
-
-
-
-
-
-
-
-
-
- |
-
-
-
-
-
-
-
- {{ subTask.task_id }}
- |
-
- {{ subTask.config?.name || subTask.task_id }}
- |
-
-
- 链式
-
- |
-
- 依赖主任务
- |
-
-
- {{ Math.round(subTask.execution.success_rate) }}%
-
-
- -
- |
-
- {{ subTask.execution?.last_run || '未记录' }}
- |
-
-
- {{ subTask.config?.enabled ? '已启用' : '已禁用' }}
-
- |
-
-
-
-
-
-
-
- |
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
\ No newline at end of file
diff --git a/frontend/src/components/tailwind/page/Search.vue b/frontend/src/components/tailwind/page/Search.vue
deleted file mode 100644
index 45f9dd5..0000000
--- a/frontend/src/components/tailwind/page/Search.vue
+++ /dev/null
@@ -1,238 +0,0 @@
-
-
-
-
-
-
-
-
-
-
-
- 共 {{ totalResults }} 条数据和
- {{ keyword }} 相关
-
-
-
-
-
-
-
-
-
-
-
-
diff --git a/frontend/src/components/tailwind/page/VideoActions.vue b/frontend/src/components/tailwind/page/VideoActions.vue
deleted file mode 100644
index 4c3faac..0000000
--- a/frontend/src/components/tailwind/page/VideoActions.vue
+++ /dev/null
@@ -1,582 +0,0 @@
-
-
-
-
-
-
-
-
-
-
-
-
-
-
![]()
-
-
- {{ formatDuration(record.progress) }} / {{ formatDuration(record.duration) }}
-
-
-
-
-
-
-
-
-
-
-
![]()
-
- {{ isPrivacyMode ? '******' : record.author_name }}
-
-
·
-
{{ formatTimestamp(record.view_at) }}
-
-
-
-
- {{ record.business === 'archive' ? record.tag_name : getBusinessType(record.business) }}
-
-
- 已下载
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
- 最后修改于 {{ formatRemarkTime(remarkTime) }}
-
-
-
-
-
- 未找到这条记录,请从列表重新进入。
-
-
-
-
-
-
-
-
-
-
-
-
-
-
diff --git a/frontend/src/components/tailwind/page/VideoDetailsManager.vue b/frontend/src/components/tailwind/page/VideoDetailsManager.vue
deleted file mode 100644
index 8cd9b4a..0000000
--- a/frontend/src/components/tailwind/page/VideoDetailsManager.vue
+++ /dev/null
@@ -1,457 +0,0 @@
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
- 历史记录视频总数
- {{ stats.totalHistoryVideos }}
-
-
-
- 已获取详情
- {{ stats.existingVideosCount }}
-
-
-
- 已知失效视频
- {{ stats.invalidVideosCount }}
-
-
-
- 待获取视频
-
- {{ stats.pendingVideosCount }}
-
-
-
-
-
-
-
-
-
-
- 处理进度: {{ progress.processedVideos || 0 }}/{{ progress.totalVideos || 0 }}
- {{ progress.progressPercentage ? `${progress.progressPercentage.toFixed(1)}%` : '0%' }}
-
-
-
-
-
-
-
-
-
-
-
成功获取
-
{{ progress.successCount || 0 }}
-
-
-
-
-
-
-
获取失败
-
{{ progress.failedCount || 0 }}
-
-
-
-
-
-
-
跳过失效
-
{{ progress.skippedInvalidCount || 0 }}
-
-
-
-
-
-
-
已用时间
-
{{ progress.elapsedTime || '0秒' }}
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
diff --git a/frontend/src/components/tailwind/page/VideoDownloader.vue b/frontend/src/components/tailwind/page/VideoDownloader.vue
deleted file mode 100644
index 33d0e97..0000000
--- a/frontend/src/components/tailwind/page/VideoDownloader.vue
+++ /dev/null
@@ -1,825 +0,0 @@
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
- {{ getDownloadTypeLabel(downloadType) }}
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
- {{ downloadType === 'video' ? '支持完整链接或 BV 号,例如:BV1xx411c7mD' : '在 UP 主空间页面 URL 中查看 UID' }}
-
-
-
-
-
-
-
-
开始下载视频
-
- {{ downloadType === 'video'
- ? '请输入视频的 BV 号或完整链接,支持单个视频下载'
- : '请输入 UP 主的 UID,支持批量下载 UP 主的所有投稿视频' }}
-
-
-
-
-
-
-
-
-
-
-
-
-
-
{{ formatCount(videoInfo.stat?.view) }}
-
-
-
-
-
-
{{ formatCount(videoInfo.stat?.danmaku) }}
-
-
-
-
-
-
{{ formatDetailedTimestamp(videoInfo.pubdate) }}
-
-
-
-
- 提示:{{ videoInfo.argue_info.argue_msg }}
-
-
-
-
-
-
-
-
-
-
-
![]()
-
-
-
-
- {{ formatDuration(videoInfo.duration) }}
-
-
-
-
-
-
-
-
-
-
-
-
{{ formatCount(videoInfo.stat?.like) }}
-
-
-
-
{{ formatCount(videoInfo.stat?.coin) }}
-
-
-
-
{{ formatCount(videoInfo.stat?.favorite) }}
-
-
-
-
{{ formatCount(videoInfo.stat?.share) }}
-
-
-
-
-
-
-
-
- {{ videoInfo.title }}
-
-
-
-
-
-
-
- 视频同步发布的动态:{{ videoInfo.dynamic }}
-
-
-
-
-
-
-
-
{{ videoInfo.tname + (videoInfo.tname_v2 ? `-${videoInfo.tname_v2}` : '') }}
-
-
-
-
-
-
{{ videoInfo.copyright === 1 ? '原创' : '转载' }}
-
-
-
-
-
-
{{ videoInfo.dimension.width }}x{{ videoInfo.dimension.height }}
-
-
-
-
-
-
{{ formatCount(videoInfo.stat?.reply) }} 条评论
-
-
-
-
-
-
🎬 检测到合集
-
- {{ collectionInfo.collection_title }}
-
-
- 共 {{ collectionInfo.total_videos }} 个视频,当前是第 {{ collectionInfo.current_video_index }} 个
-
-
-
-
-
-
分 P 列表
-
-
- {{ page.page }}
- {{ page.part }}
- {{ formatDuration(page.duration) }}
-
-
-
-
-
-
-
-
-
视频简介
-
{{ videoInfo.desc }}
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
检测到合集视频
-
-
-
- 此视频属于合集:{{ collectionInfo.collection_title }}
-
-
- 合集共包含 {{ collectionInfo.total_videos }} 个视频,当前是第 {{ collectionInfo.current_video_index }} 个
-
-
-
- 请选择下载方式:
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
\ No newline at end of file
diff --git a/frontend/src/components/tailwind/scheduler/SelectDialog.vue b/frontend/src/components/tailwind/scheduler/SelectDialog.vue
deleted file mode 100644
index fd81c08..0000000
--- a/frontend/src/components/tailwind/scheduler/SelectDialog.vue
+++ /dev/null
@@ -1,307 +0,0 @@
-
-
-
-
-
{{ title }}
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
\ No newline at end of file
diff --git a/frontend/src/components/tailwind/scheduler/TaskDetail.vue b/frontend/src/components/tailwind/scheduler/TaskDetail.vue
deleted file mode 100644
index 5665563..0000000
--- a/frontend/src/components/tailwind/scheduler/TaskDetail.vue
+++ /dev/null
@@ -1,364 +0,0 @@
-
-
-
-
-
任务详情
-
-
-
-
-
-
-
-
-
-
-
-
{{ task.config?.name }}
-
-
ID: {{ task.task_id }}
-
-
-
-
-
- {{ statusLabel }}
-
-
- {{ task.config.enabled ? '已启用' : '已禁用' }}
-
-
-
-
-
-
-
-
-
-
-
- 基本信息
-
-
-
-
API端点
-
{{ task.config?.endpoint }}
-
-
-
请求方法
-
{{ task.config?.method }}
-
-
-
优先级
-
{{ task.config?.priority || 0 }}
-
-
-
最后修改
-
{{ task.last_modified?.replace('T', ' ') }}
-
-
-
-
-
-
-
-
- 调度信息
-
-
-
-
调度类型
-
{{ scheduleTypeLabel }}
-
-
-
执行时间
-
-
-
- {{ task.config?.interval_value || '-' }}
- {{
- task.config?.interval_unit === 'minutes' ? '分钟' :
- task.config?.interval_unit === 'hours' ? '小时' :
- task.config?.interval_unit === 'days' ? '天' :
- task.config?.interval_unit === 'months' ? '月' :
- task.config?.interval_unit === 'years' ? '年' :
- task.config?.interval_unit || ''
- }}
-
-
- {{ task.config?.schedule_time || '未设置' }}
-
-
-
- 依赖于主任务
-
-
-
-
-
上次执行
-
{{ task.execution?.last_run?.replace('T', ' ') || '从未执行' }}
-
-
-
下次执行
-
-
- {{ task.execution?.next_run || '未排定' }}
-
-
- 依赖于主任务
-
-
-
-
-
-
-
-
-
-
- 执行统计
-
-
-
-
- 成功率
-
- {{ Math.round(executionInfo.successRate) }}%
-
-
-
-
-
-
平均耗时
-
- {{ executionInfo.avgDuration.toFixed(2) }}秒
-
-
-
-
总执行次数
-
- {{ executionInfo.totalRuns }}
-
-
-
-
成功/失败
-
- {{ executionInfo.successRuns }}
- /
- {{ executionInfo.failRuns }}
-
-
-
-
-
-
-
-
-
- 依赖任务
-
-
-
- {{ task.depends_on.name }} ({{ task.depends_on.task_id }})
-
-
-
无依赖
-
-
-
-
-
-
- 最近错误
-
-
{{ task.execution.last_error }}
-
-
-
-
-
-
-
-
-
\ No newline at end of file
diff --git a/frontend/src/components/tailwind/scheduler/TaskForm.vue b/frontend/src/components/tailwind/scheduler/TaskForm.vue
deleted file mode 100644
index 0a7fef6..0000000
--- a/frontend/src/components/tailwind/scheduler/TaskForm.vue
+++ /dev/null
@@ -1,1104 +0,0 @@
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
diff --git a/frontend/src/components/tailwind/scheduler/TaskHistory.vue b/frontend/src/components/tailwind/scheduler/TaskHistory.vue
deleted file mode 100644
index 4c3d99e..0000000
--- a/frontend/src/components/tailwind/scheduler/TaskHistory.vue
+++ /dev/null
@@ -1,273 +0,0 @@
-
-
-
-
-
-
-
-
-
-
-
{{ taskName }}
-
ID: {{ taskId }}
-
-
-
-
-
-
-
-
-
- 暂无执行历史
-
-
-
-
-
-
- {{ statusLabel(record.status) }}
-
- {{ record.start_time?.replace('T', ' ') }}
-
-
- 耗时: {{ record.duration?.toFixed(2) || 0 }}秒
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
{{ selectedRecord.error }}
-
-
-
-
-
-
-
-
\ No newline at end of file
diff --git a/frontend/src/main.js b/frontend/src/main.js
index a19b60c..9038425 100644
--- a/frontend/src/main.js
+++ b/frontend/src/main.js
@@ -1,66 +1,18 @@
import { createApp } from 'vue'
import './style.css'
-// Vant的库,会在桌面端自动将 mouse 事件转换成对应的 touch 事件,使得组件能够在桌面端使用
-import '@vant/touch-emulator'
import App from './App.vue'
-import { createMyRouter } from './router/router' // 使用命名导入
-import Vant from 'vant'
-// 引入Vant组件样式
-import 'vant/lib/index.css'
+import { createMyRouter } from './router/router'
-// 初始化custom event用于API模块间通信
-window.addEventListener('api-baseurl-updated', (event) => {
- console.log('API BaseURL 已更新:', event.detail?.url)
-})
-
-async function initTauri() {
- try {
- // 尝试导入Tauri core API
+async function bootstrap() {
+ const isTauri = Boolean(window.__TAURI_INTERNALS__)
+ if (isTauri) {
const { invoke } = await import('@tauri-apps/api/core')
- if (typeof invoke === 'function') {
- // 设置全局标识
- window.__TAURI_INVOKE__ = invoke
- window.__TAURI__ = true
- console.log('Tauri API 初始化成功')
- return true
- }
- } catch (error) {
- return false
+ window.__TAURI_INVOKE__ = invoke
}
-}
-
-;(async function bootstrap () {
- // 初始化Tauri API
- let isTauri = await initTauri()
-
- // 根据环境创建适当的路由实例
- const router = createMyRouter(isTauri ? 'hash' : 'history')
- const app = createApp(App)
- app.use(router)
- app.use(Vant)
- app.mount('#app')
-
- // 在 Tauri 环境中设置所有链接在当前窗口打开
- if (isTauri) {
- // 重写默认的链接打开行为
- document.addEventListener('click', function(e) {
- // 查找点击事件中是否包含链接元素
- let target = e.target;
- while (target && target !== document) {
- if (target.tagName === 'A' && target.getAttribute('href')) {
- // 获取链接地址
- const href = target.getAttribute('href');
+ createApp(App)
+ .use(createMyRouter(isTauri ? 'hash' : 'history'))
+ .mount('#app')
+}
- // 如果是外部链接或绝对路径,则在当前窗口打开
- if (href.startsWith('http') || href.startsWith('//') || href.startsWith('/')) {
- e.preventDefault();
- window.location.href = href;
- }
- break;
- }
- target = target.parentNode;
- }
- }, true);
- }
-})()
+bootstrap()
diff --git a/frontend/src/router/router.js b/frontend/src/router/router.js
index 459bb03..fc551d6 100644
--- a/frontend/src/router/router.js
+++ b/frontend/src/router/router.js
@@ -1,122 +1,18 @@
import { createRouter, createWebHashHistory, createWebHistory } from 'vue-router'
+import MainLayout from '../components/tailwind/layout/MainLayout.vue'
import History from '../components/tailwind/page/History.vue'
import BrowserHistory from '../components/tailwind/page/BrowserHistory.vue'
-import Search from '../components/tailwind/page/Search.vue'
-import AnimatedAnalytics from '../components/tailwind/page/AnimatedAnalytics.vue'
import Settings from '../components/tailwind/Settings.vue'
-import MainLayout from '../components/tailwind/layout/MainLayout.vue'
-import Images from '../components/tailwind/page/Images.vue'
-import SchedulerTasks from '../components/tailwind/page/SchedulerTasks.vue'
-import Downloads from '../components/tailwind/page/Downloads.vue'
-import MediaManager from '../components/tailwind/page/MediaManager.vue'
-import Favorites from '../components/tailwind/page/Favorites.vue'
-import BiliTools from '../components/tailwind/page/BiliTools.vue'
-import VideoActions from '../components/tailwind/page/VideoActions.vue'
-const routes = [
- {
+export const createMyRouter = (mode = 'hash') => createRouter({
+ history: mode === 'hash' ? createWebHashHistory() : createWebHistory(),
+ routes: [{
path: '/',
component: MainLayout,
children: [
- {
- path: '',
- component: History,
- },
- {
- path: 'browser-history',
- name: 'BrowserHistory',
- component: BrowserHistory,
- },
- {
- path: 'page/:pageNumber',
- component: History,
- },
- {
- path: 'search/:keyword',
- name: 'Search',
- component: Search,
- },
- {
- path: 'search/:keyword/page/:pageNumber',
- name: 'SearchPage',
- component: Search,
- },
- {
- path: 'analytics',
- name: 'AnimatedAnalytics',
- component: AnimatedAnalytics,
- },
- {
- path: 'settings',
- name: 'Settings',
- component: Settings,
- },
- {
- path: 'remarks',
- name: 'Remarks',
- redirect: '/media?tab=remarks'
- },
- {
- path: 'images',
- name: 'Images',
- component: Images
- },
- {
- path: 'scheduler',
- name: 'SchedulerTasks',
- component: SchedulerTasks
- },
- {
- path: 'downloads',
- name: 'Downloads',
- component: Downloads
- },
- {
- path: 'comments',
- name: 'Comments',
- redirect: '/media?tab=comments'
- },
- {
- path: 'media',
- name: 'MediaManager',
- component: MediaManager
- },
- {
- path: 'about',
- name: 'About',
- redirect: '/settings?tab=about'
- },
- {
- path: 'favorites',
- name: 'Favorites',
- component: Favorites
- },
- {
- path: 'video-downloader',
- name: 'VideoDownloader',
- redirect: '/bili-tools?tab=video-download'
- },
- {
- path: 'bili-tools',
- name: 'BiliTools',
- component: BiliTools
- },
- {
- path: 'record/:bvid/:viewAt',
- name: 'VideoActions',
- component: VideoActions
- }
- ]
- }
-]
-
-// 创建路由实例的工厂函数
-export const createMyRouter = (mode = 'hash') => {
-
- const history = mode === 'hash' ? createWebHashHistory() : createWebHistory()
-
- return createRouter({
- history,
- routes,
- })
-}
+ { path: '', component: History },
+ { path: 'browser-history', component: BrowserHistory },
+ { path: 'settings', component: Settings },
+ ],
+ }],
+})
diff --git a/frontend/src/style.css b/frontend/src/style.css
index b941673..ba07e45 100644
--- a/frontend/src/style.css
+++ b/frontend/src/style.css
@@ -2,41 +2,8 @@
@tailwind components;
@tailwind utilities;
-/* 深色模式全局样式 */
@layer base {
- /* 确保html和body支持深色模式 */
- html {
- transition: background-color 0.3s, color 0.3s;
- }
-
body {
- @apply bg-white dark:bg-gray-900 text-gray-900 dark:text-gray-100;
- transition: background-color 0.3s, color 0.3s;
+ @apply bg-white text-gray-900 dark:bg-gray-900 dark:text-gray-100;
}
}
-:root:root {
- --van-primary-color: #ff6699; /* 修改Vant主颜色 */
-}
-
-
-
-
-
-
-
-/* 计算弹窗管理样式 */
-.van-dialog {
- position: fixed !important;
- top: 50% !important;
- left: 50% !important;
- transform: translate(-50%, -50%) !important;
- margin: 0 !important;
- max-height: 95vh !important;
- overflow-y: auto !important;
-}
-
-/* 弹窗内容滚动样式 */
-.van-dialog__content {
- max-height: 85vh;
- overflow-y: auto;
-}
diff --git a/frontend/src/utils/historyRecordStore.js b/frontend/src/utils/historyRecordStore.js
deleted file mode 100644
index 12d5197..0000000
--- a/frontend/src/utils/historyRecordStore.js
+++ /dev/null
@@ -1,25 +0,0 @@
-const STORAGE_PREFIX = 'history-record:'
-
-export const buildHistoryRecordKey = (bvid, viewAt) => `${STORAGE_PREFIX}${bvid}_${viewAt}`
-
-export const saveHistoryRecord = (record) => {
- if (!record?.bvid || !record?.view_at) return null
-
- const key = buildHistoryRecordKey(record.bvid, record.view_at)
- sessionStorage.setItem(key, JSON.stringify(record))
- return key
-}
-
-export const getHistoryRecord = (bvid, viewAt) => {
- const key = buildHistoryRecordKey(bvid, viewAt)
- const rawValue = sessionStorage.getItem(key)
-
- if (!rawValue) return null
-
- try {
- return JSON.parse(rawValue)
- } catch (error) {
- console.error('解析历史记录缓存失败:', error)
- return null
- }
-}
diff --git a/frontend/src/utils/imageProxy.js b/frontend/src/utils/imageProxy.js
deleted file mode 100644
index 2f10bb6..0000000
--- a/frontend/src/utils/imageProxy.js
+++ /dev/null
@@ -1,31 +0,0 @@
-/**
- * 图片代理服务
- * 使用公共代理服务获取跨域图片
- */
-
-/**
- * 从原始URL获取代理图片URL
- * @param {string} originalUrl 原始图片URL
- * @returns {string} 处理后的URL
- */
-export const getImageProxyUrl = (originalUrl) => {
- // 检查是否需要代理
- if (!originalUrl) return originalUrl;
-
- // 数据URL和blob URL不需要代理
- if (originalUrl.startsWith('data:') || originalUrl.startsWith('blob:')) {
- return originalUrl;
- }
-
- // 相对URL不需要代理
- if (!/^https?:\/\/|^\/\//.test(originalUrl)) {
- return originalUrl;
- }
-
- // 使用images.weserv.nl (较稳定的公共代理)
- return `https://images.weserv.nl/?url=${encodeURIComponent(originalUrl)}`;
-};
-
-export default {
- getImageProxyUrl
-};
\ No newline at end of file
diff --git a/frontend/src/utils/imageUrl.js b/frontend/src/utils/imageUrl.js
deleted file mode 100644
index 4a1b384..0000000
--- a/frontend/src/utils/imageUrl.js
+++ /dev/null
@@ -1,61 +0,0 @@
-// 规范化图片 URL:
-// - data:/blob: 保持不变
-// - // 开头的协议相对地址 -> https:
-// - http/https 绝对地址 -> 保持不变
-// - 以 / 开头或相对路径 -> 拼接当前 API BaseURL
-import { getCurrentBaseUrl } from '@/api/api'
-
-export const normalizeImageUrl = (url) => {
- if (!url) return ''
- if (typeof url !== 'string') return url
-
- // 数据或 blob URL
- if (url.startsWith('data:') || url.startsWith('blob:')) return url
-
- // 协议相对 URL
- if (url.startsWith('//')) return `https:${url}`
-
- // 已是绝对 URL
- if (/^https?:\/\//i.test(url)) return url
-
- // 其余按相对路径处理,拼接当前 API BaseURL
- const base = getCurrentBaseUrl && getCurrentBaseUrl()
- if (!base) return url
- const baseNormalized = String(base).replace(/\/$/, '')
- const pathNormalized = url.startsWith('/') ? url : `/${url}`
- return `${baseNormalized}${pathNormalized}`
-}
-
-/**
- * 将相对 output 路径转换为可访问的静态 URL(自动拼接 /static/ 前缀,并处理反斜杠)
- * 例如:"dynamic\\341376543\\face.jpg" -> "
/static/dynamic/341376543/face.jpg"
- * 若已是 http(s)/data/blob,则保持不变
- * 若已以 /static/ 开头,则直接规范化为完整 URL
- */
-export const toStaticUrl = (relativePath) => {
- if (!relativePath) return ''
- if (typeof relativePath !== 'string') return relativePath
-
- // 已是绝对/数据/Blob URL
- if (relativePath.startsWith('data:') || relativePath.startsWith('blob:') || /^https?:\/\//i.test(relativePath)) {
- return relativePath
- }
-
- // 统一分隔符
- const normalized = relativePath.replace(/\\/g, '/').replace(/^\/+/, '')
-
- // 已包含 /static/ 前缀
- const staticPath = normalized.startsWith('static/') || normalized.startsWith('/static/')
- ? (normalized.startsWith('/') ? normalized : `/${normalized}`)
- : `/static/${normalized}`
-
- // 拼接域名
- return normalizeImageUrl(staticPath)
-}
-
-export default {
- normalizeImageUrl,
- toStaticUrl,
-}
-
-
diff --git a/frontend/src/utils/openUrl.js b/frontend/src/utils/openUrl.js
index 05e7087..ccbeef8 100644
--- a/frontend/src/utils/openUrl.js
+++ b/frontend/src/utils/openUrl.js
@@ -51,5 +51,5 @@ export async function openInBrowser(url) {
}
// 回退到window.open
- window.open(url, '_blank')
+ window.open(url, '_blank', 'noopener,noreferrer')
}
diff --git a/frontend/src/utils/privacyManager.js b/frontend/src/utils/privacyManager.js
deleted file mode 100644
index a65bb6c..0000000
--- a/frontend/src/utils/privacyManager.js
+++ /dev/null
@@ -1,86 +0,0 @@
-/**
- * 隐私模式管理工具
- * 集中管理隐私模式状态,提供全局API
- */
-
-// 隐私模式事件名称
-const PRIVACY_MODE_EVENT = 'privacy-mode-changed'
-
-/**
- * 检查隐私模式是否启用
- * @returns {boolean} 隐私模式是否启用
- */
-export const isPrivacyModeEnabled = () => {
- return localStorage.getItem('privacyMode') === 'true'
-}
-
-/**
- * 启用隐私模式
- */
-export const enablePrivacyMode = () => {
- localStorage.setItem('privacyMode', 'true')
-
- // 触发隐私模式变更事件
- dispatchPrivacyModeChanged(true)
-
- console.log('隐私模式已启用')
-}
-
-/**
- * 禁用隐私模式
- */
-export const disablePrivacyMode = () => {
- localStorage.setItem('privacyMode', 'false')
-
- // 触发隐私模式变更事件
- dispatchPrivacyModeChanged(false)
-
- console.log('隐私模式已禁用')
-}
-
-/**
- * 切换隐私模式
- * @returns {boolean} 切换后的状态
- */
-export const togglePrivacyMode = () => {
- const currentState = isPrivacyModeEnabled()
- const newState = !currentState
-
- if (newState) {
- enablePrivacyMode()
- } else {
- disablePrivacyMode()
- }
-
- return newState
-}
-
-/**
- * 分发隐私模式变更事件
- * @param {boolean} enabled 隐私模式是否启用
- */
-export const dispatchPrivacyModeChanged = (enabled) => {
- window.dispatchEvent(new CustomEvent(PRIVACY_MODE_EVENT, {
- detail: { enabled }
- }))
-}
-
-/**
- * 添加隐私模式变更监听器
- * @param {Function} callback 回调函数
- */
-export const addPrivacyModeListener = (callback) => {
- window.addEventListener(PRIVACY_MODE_EVENT, (event) => {
- if (event.detail && typeof event.detail.enabled === 'boolean') {
- callback(event.detail.enabled)
- }
- })
-}
-
-export default {
- isEnabled: isPrivacyModeEnabled,
- enable: enablePrivacyMode,
- disable: disablePrivacyMode,
- toggle: togglePrivacyMode,
- addListener: addPrivacyModeListener
-}
\ No newline at end of file
diff --git a/main.py b/main.py
index 76302b6..0e1b737 100644
--- a/main.py
+++ b/main.py
@@ -1,579 +1,59 @@
-import asyncio
import os
-import sys
-import traceback
-import warnings
-from contextlib import AsyncExitStack, asynccontextmanager
from datetime import datetime
-# 忽略jieba库中的无效转义序列警告
-warnings.filterwarnings("ignore", category=SyntaxWarning, message="invalid escape sequence")
-
-from fastapi import FastAPI, HTTPException
+from fastapi import FastAPI
from fastapi.middleware.cors import CORSMiddleware
-from fastapi.staticfiles import StaticFiles
-from loguru import logger
-
-from routers import (
- analysis,
- clean_data,
- export,
- fetch_bili_history,
- import_data_mysql,
- import_data_sqlite,
- heatmap,
- send_log,
- download,
- collection_download,
- history,
- categories,
- viewing_analytics,
- title_analytics,
- daily_count,
- login,
- delete_history,
- image_downloader,
- scheduler,
- email_config,
- apprise_config,
- comment,
- data_sync,
- favorite,
- popular_videos,
- popular_analytics,
- bilibili_history_delete,
- video_details,
- dynamic,
- interaction_records
-)
-from routers import browser_history
-from scripts.scheduler_db_enhanced import EnhancedSchedulerDB
-from scripts.scheduler_manager import SchedulerManager
-from scripts.utils import load_config, get_output_path
-
-
-# 配置日志系统
-def setup_logging():
- """设置Loguru日志系统"""
- # 使用统一的日志初始化函数
- from scripts.utils import setup_logger
-
- # 初始化日志系统
- log_info = setup_logger()
-
- # 重定向 print 输出到日志
- class PrintToLogger:
- def __init__(self, stdout):
- self.stdout = stdout
- self._line_buffer = []
- self._is_shutting_down = False # 标记系统是否正在关闭
- self._logging_in_progress = False # 防止日志重入
- self._is_docker = os.environ.get('DOCKER_ENV') == 'true' # 检测是否在Docker环境
- self._resource_warning_pattern = "系统资源不足" # 用于识别资源警告的模式
- self._low_memory_detected = False # 标记是否检测到内存不足
-
- def write(self, buf):
- # 如果系统正在关闭或在Docker环境中,直接写入原始stdout而不经过logger
- if self._is_shutting_down or self._is_docker:
- self.stdout.write(buf)
- return
-
- # 检查是否包含资源警告信息
- if self._resource_warning_pattern in buf:
- # 如果已经检测到内存不足,跳过重复的警告
- if self._low_memory_detected:
- return
- # 标记已检测到内存不足
- self._low_memory_detected = True
- # 直接写入原始stdout,避免通过logger触发循环
- self.stdout.write(buf)
- return
-
- # 跳过uvicorn日志
- if any(skip in buf for skip in [
- 'INFO:', 'ERROR:', 'WARNING:', '[32m', '[0m',
- 'Application', 'Started', 'Waiting', 'HTTP',
- 'uvicorn', 'DEBUG'
- ]):
- # 只写入到控制台
- self.stdout.write(buf)
- return
-
- # 检测是否是关闭信息
- if "应用关闭" in buf or "Shutting down" in buf:
- self._is_shutting_down = True
-
- # 防止日志重入 - 如果已经在记录日志中,直接写入原始stdout
- if self._logging_in_progress:
- self.stdout.write(buf)
- return
-
- # 收集完整的行
- for c in buf:
- if c == '\n':
- line = ''.join(self._line_buffer).rstrip()
- if line: # 只记录非空行
- try:
- # 设置日志记录锁
- self._logging_in_progress = True
- # 使用loguru记录,但保持控制台干净
- if not self._is_shutting_down:
- try:
- logger.opt(depth=1).log("INFO", line)
- except Exception as e:
- # 记录失败,写入原始stdout
- self.stdout.write(f"日志记录失败: {e}\n")
- self.stdout.write(f"{line}\n")
- else:
- # 关闭阶段直接写入控制台
- self.stdout.write(f"{line}\n")
- except Exception as e:
- # 如果记录失败,写入原始stdout
- self.stdout.write(f"日志异常: {e}\n")
- self.stdout.write(f"{line}\n")
- finally:
- # 释放日志记录锁
- self._logging_in_progress = False
- self._line_buffer = []
- else:
- self._line_buffer.append(c)
-
- def flush(self):
- if self._line_buffer:
- line = ''.join(self._line_buffer).rstrip()
- if line:
- # 检查是否包含资源警告信息
- if self._resource_warning_pattern in line:
- if not self._low_memory_detected:
- self._low_memory_detected = True
- self.stdout.write(f"{line}\n")
- self._line_buffer = []
- self.stdout.flush()
- return
-
- # 防止日志重入
- if self._logging_in_progress:
- self.stdout.write(f"{line}\n")
- else:
- try:
- self._logging_in_progress = True
- if not self._is_shutting_down:
- try:
- logger.opt(depth=1).log("INFO", line)
- except Exception:
- self.stdout.write(f"{line}\n")
- else:
- self.stdout.write(f"{line}\n")
- except Exception:
- self.stdout.write(f"{line}\n")
- finally:
- self._logging_in_progress = False
- self._line_buffer = []
- self.stdout.flush()
-
- def isatty(self):
- return self.stdout.isatty()
-
- def fileno(self):
- return self.stdout.fileno()
-
- # 在应用关闭阶段调用,标记关闭状态
- def mark_shutdown(self):
- self._is_shutting_down = True
-
- # 保存原始的stdout并重定向
- original_stdout = sys.stdout
- sys.stdout = PrintToLogger(original_stdout)
-
- # 配置uvicorn日志与loguru集成
- # 拦截标准库logging
- import logging
- class InterceptHandler(logging.Handler):
- def __init__(self):
- super().__init__()
- self._is_docker = os.environ.get('DOCKER_ENV') == 'true'
- self._in_emit = False # 防止循环调用的标志
- self._resource_warning_pattern = "系统资源不足" # 用于识别资源警告的模式
-
- def emit(self, record):
- # 防止循环调用
- if self._in_emit:
- # 如果已经在处理日志,直接返回
- return
-
- # 检查是否是资源警告消息,如果是则直接使用原始stdout输出
- message = record.getMessage()
- if self._resource_warning_pattern in message:
- # 对于资源警告,直接使用原始stdout输出,避免循环
- print(f"[{record.levelname}] {message}")
- return
-
- # 在Docker环境中,简化处理以避免循环
- if self._is_docker:
- # 使用原始的logging输出,不进行重定向
- print(f"[{record.levelname}] {message}")
- return
-
- # 设置处理标志,防止循环
- self._in_emit = True
-
- try:
- # 获取对应的Loguru级别名称
- try:
- level = logger.level(record.levelname).name
- except ValueError:
- level = record.levelno
-
- # 获取调用者的文件名和行号
- frame, depth = sys._getframe(6), 6
- while frame and frame.f_code.co_filename == logging.__file__:
- frame = frame.f_back
- depth += 1
-
- # 记录到日志文件,但不输出到控制台
- logger.opt(depth=depth, exception=record.exc_info).log(
- level, message
- )
- finally:
- # 重置处理标志
- self._in_emit = False
-
- # 替换所有标准库的日志处理器
- logging.basicConfig(handlers=[InterceptHandler()], level=0, force=True)
-
- return log_info
-
-# 在应用启动时调用
-setup_logging()
-
-# 全局调度器实例
-scheduler_manager = None
-mcp_session_manager = None
-
-def setup_mcp_mount(app: FastAPI):
- """挂载只读 MCP 服务,并由中间件按配置实时控制访问。"""
- try:
- from mcp_server import create_mcp_app, get_mcp_config
+from routers import browser_history, fetch_bili_history, history, import_data_sqlite, login
+from scripts.utils import load_config, setup_logger
- mcp_config = get_mcp_config()
- mcp_app, session_manager = create_mcp_app(mcp_config)
- app.mount(mcp_config["path"], mcp_app)
- logger.info(
- f"已挂载 MCP 服务: {mcp_config['path']},当前状态: "
- f"{'启用' if mcp_config['enabled'] else '禁用'}"
- )
- return session_manager
- except ImportError as e:
- logger.warning(f"MCP 服务依赖未安装,已跳过挂载: {e}")
- return None
- except Exception as e:
- logger.warning(f"MCP 服务挂载失败,已跳过: {e}")
- return None
-@asynccontextmanager
-async def lifespan(app: FastAPI):
- """应用生命周期管理"""
- global scheduler_manager, mcp_session_manager
+setup_logger()
- logger.info("正在启动应用...")
-
- try:
- # 初始化增强版数据库
- EnhancedSchedulerDB.get_instance()
- logger.info("已初始化增强版调度器数据库")
-
- # 初始化调度器
- scheduler_manager = SchedulerManager.get_instance(app)
-
- # 显示调度器配置
- logger.info(f"调度器配置:")
- logger.info(f" 基础URL: {scheduler_manager.base_url}")
- logger.info(" (从 config/config.yaml 的 server 配置生成;当 host 为 0.0.0.0/:: 时自动使用 127.0.0.1)")
-
- # 检查基础URL是否包含协议前缀
- if not scheduler_manager.base_url.startswith(('http://', 'https://')):
- logger.warning(f" 警告: 基础URL不包含协议前缀,这可能导致任务执行错误")
- logger.warning(f" 建议: 检查服务器配置确保正确构建URL")
-
- # 创建异步任务运行调度器
- scheduler_task = asyncio.create_task(scheduler_manager.run_scheduler())
-
- # 加载配置并决定是否执行数据完整性校验
- current_config = load_config()
- if mcp_session_manager:
- logger.info("正在启动 MCP 会话管理器...")
-
- check_on_startup = current_config.get('server', {}).get('data_integrity', {}).get('check_on_startup', True)
- if check_on_startup:
- logger.info("正在执行启动时数据完整性校验...")
- try:
- from scripts.check_data_integrity import check_data_integrity
- result = check_data_integrity()
- if result["success"]:
- if result["difference"] == 0:
- logger.success("数据完整性校验通过,数据库和JSON文件记录数一致")
- else:
- logger.warning(f"数据完整性校验发现差异: {result['difference']} 条记录")
- logger.info(f"详细报告已保存到 {result['report_file']}")
- else:
- logger.error("数据完整性校验失败")
- except Exception as e:
- logger.error(f"执行数据完整性校验时出错: {str(e)}")
- else:
- logger.info("已跳过启动时数据完整性校验")
-
- async with AsyncExitStack() as stack:
- if mcp_session_manager:
- await stack.enter_async_context(mcp_session_manager.run())
- logger.info("MCP 会话管理器已启动")
-
- logger.success("=== 应用启动完成 ===")
- logger.info(f"启动时间: {datetime.now().isoformat()}")
-
- yield
-
- # 关闭时
- logger.info("\n=== 应用关闭阶段 ===")
- logger.info(f"开始时间: {datetime.now().isoformat()}")
-
- # 标记stdout重定向器为关闭状态,防止重入
- if hasattr(sys.stdout, 'mark_shutdown'):
- sys.stdout.mark_shutdown()
-
- if scheduler_manager:
- logger.info("正在停止调度器...")
- scheduler_manager.stop_scheduler()
- # 取消调度器任务
- scheduler_task.cancel()
- try:
- logger.info("等待调度器任务完成...")
- await scheduler_task
- except asyncio.CancelledError:
- logger.info("调度器任务已取消")
-
- # 恢复原始的 stdout
- if hasattr(sys.stdout, 'stdout'):
- logger.info("正在恢复标准输出...")
- sys.stdout = sys.stdout.stdout
-
- logger.success("=== 应用关闭完成 ===")
- logger.info(f"结束时间: {datetime.now().isoformat()}")
-
- # 清理日志处理器,防止关闭时的死锁
- # 注意:必须在所有日志记录之后调用
- try:
- print("正在安全关闭日志系统...")
- # 复制处理器列表,避免在迭代过程中修改
- logger_handlers = list(logger._core.handlers.keys())
- # 设置最小日志级别为ERROR,避免继续记录非关键日志
- for handler_id in logger_handlers:
- try:
- # 修改处理器的最小记录级别为ERROR (40)
- handler = logger._core.handlers.get(handler_id)
- if handler:
- handler._levelno = 40 # ERROR级别
- except Exception:
- # 忽略修改失败的情况
- pass
- # 逐个移除处理器
- for handler_id in logger_handlers:
- try:
- logger.remove(handler_id)
- except Exception as log_ex:
- print(f"移除日志处理器时出错 (忽略): {log_ex}")
- print("日志系统已安全关闭")
- except Exception as e:
- print(f"关闭日志系统时出错 (忽略): {e}")
-
- except Exception as e:
- logger.error(f"\n=== 应用生命周期出错 ===")
- logger.error(f"错误信息: {str(e)}")
- logger.error(f"错误类型: {type(e).__name__}")
- # Loguru会自动提供详细堆栈
- logger.exception("应用生命周期异常")
- raise
-
-# 创建 FastAPI 应用实例
app = FastAPI(
title="HistoryHub",
- description="浏览器历史同步、检索与 B 站观看历史管理",
+ description="浏览器历史同步、检索与 B 站观看历史获取",
version="1.7.2",
- lifespan=lifespan
)
-mcp_session_manager = setup_mcp_mount(app)
-# 添加启动状态端点
@app.get("/health")
async def health_check():
- """健康检查端点"""
- return {
- "status": "running",
- "timestamp": datetime.now().isoformat(),
- "scheduler_status": "running" if scheduler_manager and scheduler_manager.is_running else "stopped"
- }
+ return {"status": "running", "timestamp": datetime.now().isoformat()}
+
-# 添加 CORS 中间件
app.add_middleware(
CORSMiddleware,
- allow_origins=["*"], # 允许所有来源
+ allow_origins=["*"],
allow_credentials=True,
- allow_methods=["*"], # 允许所有方法
- allow_headers=["*"], # 允许所有头部
+ allow_methods=["*"],
+ allow_headers=["*"],
)
-# 注册路由
app.include_router(login.router, prefix="/login", tags=["用户登录"])
-app.include_router(analysis.router, prefix="/analysis", tags=["数据分析"])
-app.include_router(clean_data.router, prefix="/clean", tags=["数据清洗"])
-app.include_router(export.router, prefix="/export", tags=["数据导出"])
app.include_router(fetch_bili_history.router, prefix="/fetch", tags=["历史记录获取"])
-app.include_router(import_data_mysql.router, prefix="/importMysql", tags=["MySQL数据导入"])
app.include_router(import_data_sqlite.router, prefix="/importSqlite", tags=["SQLite数据导入"])
-app.include_router(heatmap.router, prefix="/heatmap", tags=["热力图生成"])
-app.include_router(send_log.router, prefix="/log", tags=["日志发送"])
-app.include_router(download.router, prefix="/download", tags=["视频下载"])
-app.include_router(collection_download.router, prefix="/collection", tags=["合集下载"])
-app.include_router(history.router, prefix="/history", tags=["历史记录管理"])
-app.include_router(categories.router, prefix="/categories", tags=["分类管理"])
-app.include_router(viewing_analytics.router, prefix="/viewing", tags=["观看时间分析"])
-app.include_router(title_analytics.router, prefix="/title", tags=["标题分析"])
-app.include_router(daily_count.router, prefix="/daily", tags=["每日观看统计"])
-app.include_router(delete_history.router, prefix="/delete", tags=["删除历史记录"])
-app.include_router(image_downloader.router, prefix="/images", tags=["图片下载管理"])
-app.include_router(scheduler.router, prefix="/scheduler", tags=["计划任务管理"])
-app.include_router(email_config.router, prefix="/config", tags=["配置管理"])
-app.include_router(apprise_config.router, prefix="/config", tags=["配置管理"])
-app.include_router(comment.router, prefix="/comment", tags=["评论管理"])
-app.include_router(data_sync.router, prefix="/data_sync", tags=["数据同步与完整性检查"])
-app.include_router(favorite.router, prefix="/favorite", tags=["收藏夹管理"])
-app.include_router(popular_videos.router, prefix="/bilibili", tags=["B站热门"])
-app.include_router(popular_analytics.router, prefix="/popular", tags=["热门视频分析"])
-app.include_router(bilibili_history_delete.router, prefix="/bilibili/history", tags=["B站历史记录删除"])
-app.include_router(video_details.router, prefix="/video_details", tags=["视频详情"])
-app.include_router(dynamic.router, prefix="/dynamic", tags=["用户动态"])
-app.include_router(interaction_records.router, prefix="/interactions", tags=["互动记录"])
+app.include_router(history.router, prefix="/history", tags=["历史记录查询"])
app.include_router(browser_history.router, prefix="/browser-history", tags=["浏览历史"])
-class HistoryHubStaticFiles(StaticFiles):
- async def get_response(self, path, scope):
- filename = path.replace("\\", "/").rsplit("/", 1)[-1].lower()
- if filename in {
- "browser_history.sqlite3" + suffix
- for suffix in ("", "-wal", "-shm", "-journal")
- }:
- raise HTTPException(status_code=404)
- return await super().get_response(path, scope)
-
-# 挂载静态目录,提供 output 下资源的访问(/static/ 相对路径)
-try:
- static_dir = os.path.dirname(get_output_path("__base__"))
- app.mount("/static", HistoryHubStaticFiles(directory=static_dir), name="static")
- logger.info(f"已挂载静态目录: /static -> {static_dir}")
-except Exception as e:
- logger.warning(f"静态目录挂载失败(忽略): {e}")
-
-# 入口点,启动应用
if __name__ == "__main__":
import uvicorn
- import atexit
- import signal
-
- # 配置日志系统
- log_info = setup_logging()
-
- # 标记是否正在关闭
- is_shutting_down = False
-
- # 信号处理函数
- def signal_handler(sig, frame):
- global is_shutting_down
- if is_shutting_down:
- print("正在关闭中,请稍候...")
- return
- is_shutting_down = True
- print(f"\n接收到信号 {sig},正在优雅关闭...")
- # 标记stdout为关闭状态
- if hasattr(sys.stdout, 'mark_shutdown'):
- sys.stdout.mark_shutdown()
- sys.exit(0)
-
- # 注册信号处理函数
- signal.signal(signal.SIGINT, signal_handler) # Ctrl+C
- signal.signal(signal.SIGTERM, signal_handler) # 终止信号
-
- # 注册退出时清理函数
- @atexit.register
- def cleanup_at_exit():
- global is_shutting_down
- if is_shutting_down:
- return
- is_shutting_down = True
- print("程序退出,正在清理资源...")
- # 恢复原始stdout
- if hasattr(sys.stdout, 'stdout'):
- sys.stdout = sys.stdout.stdout
- # 移除所有日志处理器
- print("正在关闭日志系统...")
- try:
- handlers = list(logger._core.handlers.keys())
- for handler_id in handlers:
- try:
- logger.remove(handler_id)
- except Exception as e:
- print(f"移除日志处理器时出错 (忽略): {e}")
- except Exception as e:
- print(f"获取日志处理器时出错 (忽略): {e}")
- print("日志系统已关闭")
-
- # 加载配置
- config = load_config()
- server_config = config.get('server', {})
-
- # 检查是否启用SSL
- ssl_enabled = server_config.get('ssl_enabled', False)
- ssl_certfile = server_config.get('ssl_certfile', None)
- ssl_keyfile = server_config.get('ssl_keyfile', None)
-
- # 使用SSL证书启动应用(如果启用)
- if ssl_enabled and ssl_certfile and ssl_keyfile:
- logger.info(f"使用HTTPS启动服务,端口: {server_config.get('port', 8899)}")
- logger.info(f"SSL证书路径: {ssl_certfile}")
- logger.info(f"SSL密钥路径: {ssl_keyfile}")
- try:
- # 检查证书文件是否存在
- if not os.path.exists(ssl_certfile):
- logger.error(f"错误: SSL证书文件不存在: {ssl_certfile}")
- sys.exit(1)
-
- if not os.path.exists(ssl_keyfile):
- logger.error(f"错误: SSL密钥文件不存在: {ssl_keyfile}")
- sys.exit(1)
-
- # 检查文件权限
- logger.info(f"证书文件权限: {oct(os.stat(ssl_certfile).st_mode)[-3:]}")
- logger.info(f"密钥文件权限: {oct(os.stat(ssl_keyfile).st_mode)[-3:]}")
- uvicorn.run(
- "main:app",
- host=server_config.get('host', "0.0.0.0"), # 默认使用0.0.0.0允许所有IP访问
- port=server_config.get('port', 8899),
- log_level="debug", # 修改为debug级别
- reload=False, # 禁用热重载以避免多个调度器实例
- ssl_certfile=ssl_certfile,
- ssl_keyfile=ssl_keyfile
- )
- except Exception as e:
- logger.error(f"启动服务时出错: {e}")
- traceback.print_exc()
- else:
- logger.info(f"使用HTTP启动服务,主机: {server_config.get('host', '0.0.0.0')},端口: {server_config.get('port', 8899)}")
- uvicorn.run(
- "main:app",
- host=server_config.get('host', "0.0.0.0"), # 默认使用0.0.0.0允许所有IP访问
- port=server_config.get('port', 8899),
- log_level="info",
- reload=False # 禁用热重载以避免多个调度器实例
- )
+ server_config = load_config().get("server", {})
+ ssl_options = {}
+ if server_config.get("ssl_enabled", False):
+ for option in ("ssl_certfile", "ssl_keyfile"):
+ path = server_config.get(option)
+ if not path or not os.path.isfile(path):
+ raise FileNotFoundError(f"SSL文件不存在: {option}")
+ ssl_options[option] = path
+
+ uvicorn.run(
+ "main:app",
+ host=server_config.get("host", "0.0.0.0"),
+ port=server_config.get("port", 8899),
+ log_level="info",
+ reload=False,
+ **ssl_options,
+ )
diff --git a/mcp_server.py b/mcp_server.py
deleted file mode 100644
index 2769797..0000000
--- a/mcp_server.py
+++ /dev/null
@@ -1,802 +0,0 @@
-import inspect
-import json
-import os
-from datetime import datetime
-from pathlib import Path
-from typing import Any, Callable, Optional
-
-from fastapi import HTTPException
-
-from scripts.utils import get_base_path, load_config
-
-
-MAX_DEFAULT_PAGE_SIZE = 100
-SENSITIVE_CONFIG_KEYS = {
- "SESSDATA",
- "bili_jct",
- "DedeUserID",
- "DedeUserID__ckMd5",
- "password",
- "token",
-}
-
-
-class BearerTokenASGIMiddleware:
- """为 MCP ASGI 应用增加实时开关和轻量 Bearer Token 校验。"""
-
- def __init__(
- self,
- app: Callable,
- token: Optional[str],
- auth_enabled: bool = True,
- config_loader: Optional[Callable[[], dict[str, Any]]] = None,
- ):
- self.app = app
- self.token = token
- self.auth_enabled = auth_enabled
- self.config_loader = config_loader
-
- async def __call__(self, scope: dict, receive: Callable, send: Callable) -> None:
- if scope.get("type") != "http":
- await self.app(scope, receive, send)
- return
-
- try:
- runtime_config = self.config_loader() if self.config_loader else {}
- except Exception as e:
- await self._json_response(
- send,
- 503,
- {
- "status": "error",
- "message": f"MCP config is unavailable: {e}",
- },
- )
- return
-
- if runtime_config and not runtime_config.get("enabled", False):
- await self._json_response(
- send,
- 503,
- {
- "status": "error",
- "message": "MCP service is disabled.",
- },
- )
- return
-
- auth_enabled = runtime_config.get("auth_enabled", self.auth_enabled)
- if not auth_enabled:
- await self.app(scope, receive, send)
- return
-
- token = runtime_config.get("token", self.token)
- if not token:
- await self._json_response(
- send,
- 503,
- {
- "status": "error",
- "message": "MCP token is not configured.",
- },
- )
- return
-
- headers = dict(scope.get("headers") or [])
- authorization = headers.get(b"authorization", b"").decode("utf-8")
- expected = f"Bearer {token}"
- if authorization != expected:
- await self._json_response(
- send,
- 401,
- {
- "status": "error",
- "message": "Unauthorized MCP request.",
- },
- {"WWW-Authenticate": "Bearer"},
- )
- return
-
- await self.app(scope, receive, send)
-
- async def _json_response(
- self,
- send: Callable,
- status_code: int,
- payload: dict,
- extra_headers: Optional[dict[str, str]] = None,
- ) -> None:
- body = json.dumps(payload, ensure_ascii=False).encode("utf-8")
- headers = {
- "content-type": "application/json; charset=utf-8",
- "content-length": str(len(body)),
- }
- if extra_headers:
- headers.update(extra_headers)
-
- await send(
- {
- "type": "http.response.start",
- "status": status_code,
- "headers": [
- (key.lower().encode("latin-1"), value.encode("latin-1"))
- for key, value in headers.items()
- ],
- }
- )
- await send({"type": "http.response.body", "body": body})
-
-
-def get_mcp_config() -> dict[str, Any]:
- config = load_config()
- server_config = config.get("server", {})
- mcp_config = server_config.get("mcp", {})
- token = os.environ.get("BHF_MCP_TOKEN") or mcp_config.get("token")
-
- return {
- "enabled": bool(mcp_config.get("enabled", False)),
- "path": mcp_config.get("path", "/mcp"),
- "host": server_config.get("host", "127.0.0.1"),
- "port": int(server_config.get("port", 8899)),
- "token": token,
- "auth_enabled": bool(mcp_config.get("auth_enabled", True)),
- "max_page_size": int(mcp_config.get("max_page_size", MAX_DEFAULT_PAGE_SIZE)),
- }
-
-
-def create_mcp_app(config: Optional[dict[str, Any]] = None) -> tuple[Callable, Any]:
- from mcp.server.fastmcp import FastMCP
-
- mcp_config = config or get_mcp_config()
- mcp = FastMCP(
- "HistoryHub",
- instructions=(
- "Read-only MCP server for local Bilibili history data. "
- "Use paginated tools for records and do not request write operations."
- ),
- host=mcp_config["host"],
- port=mcp_config["port"],
- streamable_http_path="/",
- json_response=True,
- )
- _register_resources(mcp)
- _register_prompts(mcp)
- _register_tools(mcp, max_page_size=mcp_config["max_page_size"])
-
- mcp_app = mcp.streamable_http_app()
- protected_app = BearerTokenASGIMiddleware(
- mcp_app,
- token=mcp_config.get("token"),
- auth_enabled=mcp_config.get("auth_enabled", True),
- config_loader=get_mcp_config,
- )
- return protected_app, mcp.session_manager
-
-
-def _register_resources(mcp: Any) -> None:
- @mcp.resource(
- "bili://project/overview",
- name="project_overview",
- description="HistoryHub project capability overview.",
- mime_type="application/json",
- )
- async def project_overview() -> str:
- return _json_text(
- {
- "name": "HistoryHub",
- "summary": "Bilibili history fetching, storage, analysis and visualization backend.",
- "mcp_policy": "Read-only by default. Full history records are readable through paginated tools.",
- "primary_data": [
- "output/bilibili_history.db",
- "output/database/*.db",
- "output/history_by_date/YYYY/MM/DD.json",
- "output/logs/YYYY/MM/DD/*.log",
- ],
- "recommended_flow": [
- "Read bili://project/data-status first.",
- "Use summary tools before reading large record pages.",
- "Use page and size on every record-list tool.",
- ],
- }
- )
-
- @mcp.resource(
- "bili://project/tool-guide",
- name="tool_guide",
- description="When to use each read-only MCP tool.",
- mime_type="application/json",
- )
- async def tool_guide() -> str:
- return _json_text(_tool_guide())
-
- @mcp.resource(
- "bili://project/data-status",
- name="data_status",
- description="Current local data inventory and available years.",
- mime_type="application/json",
- )
- async def data_status() -> str:
- return _json_text(await _build_project_status())
-
- @mcp.resource(
- "bili://project/privacy-policy",
- name="privacy_policy",
- description="MCP privacy and safety policy.",
- mime_type="application/json",
- )
- async def privacy_policy() -> str:
- return _json_text(
- {
- "access": "LAN HTTP MCP protected by Bearer Token.",
- "readable": [
- "Paginated watch history records",
- "Local video details",
- "Aggregated analytics",
- "Scheduler status and execution history",
- "Data integrity reports",
- ],
- "blocked_in_v1": [
- "Login",
- "Sync/fetch from Bilibili",
- "Download",
- "Delete",
- "Reset database",
- "Update configuration",
- ],
- "sensitive_fields_never_returned_by_status_tools": sorted(SENSITIVE_CONFIG_KEYS),
- "record_tools": "Record tools may return full local record fields, but image URLs default to no SESSDATA.",
- }
- )
-
-
-def _register_prompts(mcp: Any) -> None:
- @mcp.prompt(
- name="analyze_viewing_pattern",
- description="Analyze viewing habits with minimum context.",
- )
- def analyze_viewing_pattern(year: Optional[int] = None) -> str:
- year_hint = f" for year {year}" if year else ""
- return (
- f"Analyze Bilibili viewing patterns{year_hint}. "
- "First read bili://project/data-status, then call get_annual_summary and "
- "get_viewing_analytics. Only call query_history_records when concrete examples are needed."
- )
-
- @mcp.prompt(name="find_video_or_author", description="Find history records by video or author.")
- def find_video_or_author(keyword: str) -> str:
- return (
- f"Find local Bilibili history records related to '{keyword}'. "
- "Use search_history_records first, then get_video_detail for any important bvid."
- )
-
- @mcp.prompt(name="annual_report_insight", description="Generate annual report insights.")
- def annual_report_insight(year: Optional[int] = None) -> str:
- year_hint = f" for year {year}" if year else ""
- return (
- f"Create a concise annual Bilibili viewing report{year_hint}. "
- "Use get_annual_summary first and add only a few paginated examples if needed."
- )
-
- @mcp.prompt(name="data_health_check", description="Check local data health.")
- def data_health_check() -> str:
- return (
- "Check local HistoryHub data health. "
- "Read bili://project/data-status, then call get_data_integrity_report, "
- "get_sync_result, and get_scheduler_tasks."
- )
-
-
-def _register_tools(mcp: Any, max_page_size: int) -> None:
- @mcp.tool(description="Get project, database and MCP status without sensitive configuration.")
- async def get_project_status() -> dict[str, Any]:
- return await _build_project_status()
-
- @mcp.tool(description="List available years in the local watch history database.")
- async def list_available_years() -> dict[str, Any]:
- from routers import history
-
- return await _call_route("/history/available-years", history.get_years)
-
- @mcp.tool(description="Query paginated local watch history records.")
- async def query_history_records(
- page: int = 1,
- size: int = 30,
- sort_order: int = 0,
- tag_name: Optional[str] = None,
- main_category: Optional[str] = None,
- date_range: Optional[str] = None,
- business: Optional[str] = None,
- use_local_images: bool = False,
- ) -> dict[str, Any]:
- from routers import history
-
- size = _limit_page_size(size, max_page_size)
- return await _call_route(
- "/history/all",
- history.get_history_page,
- page=max(1, page),
- size=size,
- sort_order=sort_order,
- tag_name=tag_name,
- main_category=main_category,
- date_range=date_range,
- use_local_images=use_local_images,
- use_sessdata=False,
- business=business,
- meta={"page": page, "size": size},
- )
-
- @mcp.tool(description="Search paginated local watch history records.")
- async def search_history_records(
- search: str,
- search_type: str = "all",
- page: int = 1,
- size: int = 30,
- sort_order: int = 0,
- use_local_images: bool = False,
- ) -> dict[str, Any]:
- from routers import history
-
- size = _limit_page_size(size, max_page_size)
- return await _call_route(
- "/history/search",
- history.search_history,
- page=max(1, page),
- size=size,
- sortOrder=sort_order,
- search=search,
- search_type=search_type,
- use_sessdata=False,
- use_local_images=use_local_images,
- meta={"page": page, "size": size, "search_type": search_type},
- )
-
- @mcp.tool(description="Get one local watch history video by CID.")
- async def get_history_by_cid(cid: int, use_local_images: bool = False) -> dict[str, Any]:
- from routers import history
-
- return await _call_route(
- f"/history/by_cid/{cid}",
- history.get_video_by_cid,
- cid=cid,
- use_local_images=use_local_images,
- use_sessdata=False,
- )
-
- @mcp.tool(description="Get statistics for a specific date. Date format is MMDD, for example 0113.")
- async def get_daily_count(date: str, year: Optional[int] = None) -> dict[str, Any]:
- from routers import daily_count
-
- return await _call_route(
- "/daily/daily-count",
- daily_count.get_daily_count,
- date=date,
- year=year,
- )
-
- @mcp.tool(description="Get full annual summary JSON for a year without writing files.")
- async def get_annual_summary(year: Optional[int] = None, use_cache: bool = True) -> dict[str, Any]:
- from routers import viewing_analytics
-
- return await _call_route(
- "/viewing/annual-summary/json",
- viewing_analytics.get_annual_summary_json,
- year=year,
- use_cache=use_cache,
- save_to_file=False,
- )
-
- @mcp.tool(
- description=(
- "Get one viewing analytics component: monthly, weekly, time_slots, "
- "continuity, watch_counts, or completion_rates."
- )
- )
- async def get_viewing_analytics(
- analysis_type: str,
- year: Optional[int] = None,
- use_cache: bool = True,
- ) -> dict[str, Any]:
- from routers import viewing_analytics
-
- mapping = {
- "monthly": ("/viewing/monthly-stats", viewing_analytics.get_monthly_stats),
- "weekly": ("/viewing/weekly-stats", viewing_analytics.get_weekly_stats),
- "time_slots": ("/viewing/time-slots", viewing_analytics.get_time_slots),
- "continuity": ("/viewing/continuity", viewing_analytics.get_viewing_continuity),
- "watch_counts": ("/viewing/watch-counts", viewing_analytics.get_viewing_watch_counts),
- "completion_rates": (
- "/viewing/completion-rates",
- viewing_analytics.get_viewing_completion_rates,
- ),
- }
- route = mapping.get(analysis_type)
- if not route:
- return _error(
- "Unsupported analysis_type.",
- data={"allowed": sorted(mapping)},
- source_route="/viewing/*",
- )
- source_route, func = route
- return await _call_route(source_route, func, year=year, use_cache=use_cache)
-
- @mcp.tool(
- description=(
- "Get one title analytics component: keyword, length, sentiment, trend, or interaction."
- )
- )
- async def get_title_analytics(
- analysis_type: str,
- year: Optional[int] = None,
- use_cache: bool = True,
- ) -> dict[str, Any]:
- from routers import title_analytics
-
- mapping = {
- "keyword": ("/title/keyword-analysis", title_analytics.get_keyword_analysis),
- "length": ("/title/length-analysis", title_analytics.get_length_analysis),
- "sentiment": ("/title/sentiment-analysis", title_analytics.get_sentiment_analysis),
- "trend": ("/title/trend-analysis", title_analytics.get_trend_analysis),
- "interaction": ("/title/interaction-analysis", title_analytics.get_interaction_analysis),
- }
- route = mapping.get(analysis_type)
- if not route:
- return _error(
- "Unsupported analysis_type.",
- data={"allowed": sorted(mapping)},
- source_route="/title/*",
- )
- source_route, func = route
- return await _call_route(source_route, func, year=year, use_cache=use_cache)
-
- @mcp.tool(description="Get aggregated local interaction summary.")
- async def get_interaction_summary(year: Optional[int] = None) -> dict[str, Any]:
- from routers import interaction_records
-
- return await _call_route(
- "/interactions/summary",
- interaction_records.get_interaction_summary,
- year=year,
- )
-
- @mcp.tool(description="Query paginated local interaction records.")
- async def query_interaction_records(
- page: int = 1,
- size: int = 30,
- source: Optional[str] = None,
- year: Optional[int] = None,
- search: Optional[str] = None,
- ) -> dict[str, Any]:
- from routers import interaction_records
-
- size = _limit_page_size(size, max_page_size)
- return await _call_route(
- "/interactions/records",
- interaction_records.get_interaction_records,
- page=max(1, page),
- size=size,
- source=source,
- year=year,
- search=search,
- meta={"page": page, "size": size},
- )
-
- @mcp.tool(description="Get local interaction sync state without triggering sync.")
- async def get_interaction_status() -> dict[str, Any]:
- from routers import interaction_records
-
- return await _call_route("/interactions/status", interaction_records.get_interaction_status)
-
- @mcp.tool(description="Get one local video detail record by BV id.")
- async def get_video_detail(bvid: str) -> dict[str, Any]:
- from routers import video_details
-
- return await _call_route(
- f"/video_details/info/{bvid}",
- video_details.get_video_info_from_db,
- bvid=bvid,
- )
-
- @mcp.tool(description="Search local video details database.")
- async def search_video_details(
- keyword: Optional[str] = None,
- uploader_mid: Optional[int] = None,
- page: int = 1,
- per_page: int = 20,
- ) -> dict[str, Any]:
- from routers import video_details
-
- per_page = _limit_page_size(per_page, max_page_size)
- return await _call_route(
- "/video_details/search",
- video_details.search_videos,
- keyword=keyword,
- uploader_mid=uploader_mid,
- page=max(1, page),
- per_page=per_page,
- meta={"page": page, "per_page": per_page},
- )
-
- @mcp.tool(description="Get local video details database statistics.")
- async def get_video_detail_stats() -> dict[str, Any]:
- from routers import video_details
-
- return await _call_route(
- "/video_details/stats",
- video_details.get_video_details_database_stats,
- )
-
- @mcp.tool(description="Get scheduler task status without creating, updating or executing tasks.")
- async def get_scheduler_tasks(
- task_id: Optional[str] = None,
- include_subtasks: bool = True,
- detail_level: str = "basic",
- ) -> dict[str, Any]:
- from routers import scheduler
- from scripts.scheduler_db_enhanced import EnhancedSchedulerDB
-
- return await _call_route(
- "/scheduler/tasks",
- scheduler.get_tasks,
- task_id=task_id,
- include_subtasks=include_subtasks,
- detail_level=detail_level,
- db=EnhancedSchedulerDB.get_instance(),
- )
-
- @mcp.tool(description="Get paginated scheduler execution history.")
- async def get_scheduler_history(
- task_id: Optional[str] = None,
- include_subtasks: bool = True,
- status: Optional[str] = None,
- start_date: Optional[str] = None,
- end_date: Optional[str] = None,
- page: int = 1,
- page_size: int = 20,
- ) -> dict[str, Any]:
- from routers import scheduler
- from scripts.scheduler_db_enhanced import EnhancedSchedulerDB
-
- page_size = _limit_page_size(page_size, max_page_size)
- return await _call_route(
- "/scheduler/tasks/history",
- scheduler.get_task_history,
- task_id=task_id,
- include_subtasks=include_subtasks,
- status=status,
- start_date=start_date,
- end_date=end_date,
- page=max(1, page),
- page_size=page_size,
- db=EnhancedSchedulerDB.get_instance(),
- )
-
- @mcp.tool(description="Get latest data integrity report content if it exists.")
- async def get_data_integrity_report() -> dict[str, Any]:
- from routers import data_sync
-
- return await _call_route("/data_sync/report", data_sync.get_report)
-
- @mcp.tool(description="Get latest JSON/database sync result if it exists.")
- async def get_sync_result() -> dict[str, Any]:
- from routers import data_sync
-
- return await _call_route("/data_sync/sync/result", data_sync.get_sync_result)
-
- @mcp.tool(description="Get local output directory inventory for key data files.")
- async def get_local_data_inventory() -> dict[str, Any]:
- return _ok(
- _build_data_inventory(),
- source_route="local:output-inventory",
- )
-
-
-async def _call_route(
- source_route: str,
- func: Callable[..., Any],
- meta: Optional[dict[str, Any]] = None,
- **kwargs: Any,
-) -> dict[str, Any]:
- try:
- result = func(**kwargs)
- if inspect.isawaitable(result):
- result = await result
-
- route_status = result.get("status") if isinstance(result, dict) else None
- if route_status == "error":
- return _error(
- result.get("message", "Route returned an error."),
- data=result,
- source_route=source_route,
- meta=meta,
- )
- return _ok(result, source_route=source_route, meta=meta)
- except HTTPException as exc:
- return _error(
- str(exc.detail),
- error_type="HTTPException",
- source_route=source_route,
- meta={"status_code": exc.status_code, **(meta or {})},
- )
- except Exception as exc:
- return _error(
- str(exc),
- error_type=type(exc).__name__,
- source_route=source_route,
- meta=meta,
- )
-
-
-def _ok(data: Any, source_route: str, meta: Optional[dict[str, Any]] = None) -> dict[str, Any]:
- return {
- "status": "success",
- "data": data,
- "error": None,
- "meta": {
- "source_route": source_route,
- "generated_at": datetime.now().isoformat(),
- **(meta or {}),
- },
- }
-
-
-def _error(
- message: str,
- error_type: str = "Error",
- data: Any = None,
- source_route: Optional[str] = None,
- meta: Optional[dict[str, Any]] = None,
-) -> dict[str, Any]:
- return {
- "status": "error",
- "data": data,
- "error": {
- "type": error_type,
- "message": message,
- },
- "meta": {
- "source_route": source_route,
- "generated_at": datetime.now().isoformat(),
- **(meta or {}),
- },
- }
-
-
-async def _build_project_status() -> dict[str, Any]:
- config = load_config()
- server_config = config.get("server", {})
- mcp_config = get_mcp_config()
- history_years: list[int] = []
-
- try:
- from routers.history import get_available_years
-
- history_years = get_available_years()
- except Exception:
- history_years = []
-
- return {
- "status": "success",
- "project": {
- "name": "HistoryHub",
- "base_path": get_base_path(),
- "output_path": str(Path(get_base_path()) / "output"),
- },
- "server": {
- "host": server_config.get("host"),
- "port": server_config.get("port"),
- "ssl_enabled": bool(server_config.get("ssl_enabled", False)),
- },
- "mcp": {
- "enabled": mcp_config["enabled"],
- "path": mcp_config["path"],
- "host": mcp_config["host"],
- "port": mcp_config["port"],
- "auth_enabled": mcp_config["auth_enabled"],
- "token_configured": bool(mcp_config.get("token")),
- "max_page_size": mcp_config["max_page_size"],
- },
- "data": {
- "available_years": history_years,
- "inventory": _build_data_inventory(),
- },
- "generated_at": datetime.now().isoformat(),
- }
-
-
-def _build_data_inventory() -> dict[str, Any]:
- base_path = Path(get_base_path())
- output_path = base_path / "output"
- database_path = output_path / "database"
-
- watched_paths = {
- "main_history_db": output_path / "bilibili_history.db",
- "video_details_db": database_path / "bilibili_video_details.db",
- "history_by_date": output_path / "history_by_date",
- "analytics": output_path / "analytics",
- "logs": output_path / "logs",
- "database_dir": database_path,
- "data_integrity_report": output_path / "check" / "data_integrity_report.md",
- "sync_result": output_path / "check" / "sync_result.json",
- }
-
- return {
- name: _path_status(path)
- for name, path in watched_paths.items()
- }
-
-
-def _path_status(path: Path) -> dict[str, Any]:
- exists = path.exists()
- status: dict[str, Any] = {
- "path": str(path),
- "exists": exists,
- "type": "missing",
- }
- if not exists:
- return status
-
- stat = path.stat()
- status.update(
- {
- "type": "directory" if path.is_dir() else "file",
- "modified_at": datetime.fromtimestamp(stat.st_mtime).isoformat(),
- }
- )
- if path.is_file():
- status["size_bytes"] = stat.st_size
- else:
- try:
- status["item_count"] = sum(1 for _ in path.iterdir())
- except OSError:
- status["item_count"] = None
- return status
-
-
-def _limit_page_size(size: int, max_page_size: int) -> int:
- try:
- normalized = int(size)
- except (TypeError, ValueError):
- normalized = 30
- return max(1, min(normalized, max_page_size))
-
-
-def _json_text(payload: Any) -> str:
- return json.dumps(payload, ensure_ascii=False, indent=2)
-
-
-def _tool_guide() -> dict[str, Any]:
- return {
- "status": "success",
- "tools": {
- "get_project_status": "Read service, MCP and data status without secrets.",
- "list_available_years": "Check which history years can be queried.",
- "query_history_records": "Read paginated watch history records.",
- "search_history_records": "Search watch history by title, author, tag or remark.",
- "get_history_by_cid": "Read one watch-history video by CID.",
- "get_daily_count": "Analyze one calendar day.",
- "get_annual_summary": "Read the full annual summary JSON.",
- "get_viewing_analytics": "Read one viewing behavior analytics component.",
- "get_title_analytics": "Read one title analytics component.",
- "get_interaction_summary": "Read aggregated favorite/like/coin summary.",
- "query_interaction_records": "Read paginated favorite/like/coin records.",
- "get_interaction_status": "Read interaction sync status without syncing.",
- "get_video_detail": "Read one local video detail by bvid.",
- "search_video_details": "Search local video details.",
- "get_video_detail_stats": "Read video detail database statistics.",
- "get_scheduler_tasks": "Read scheduler task status.",
- "get_scheduler_history": "Read scheduler execution history.",
- "get_data_integrity_report": "Read latest data integrity report.",
- "get_sync_result": "Read latest JSON/database sync result.",
- "get_local_data_inventory": "Read key output directory file status.",
- },
- "blocked_operations": [
- "fetch",
- "sync",
- "download",
- "delete",
- "reset",
- "login",
- "update_config",
- ],
- }
diff --git a/pyproject.toml b/pyproject.toml
index dbed24e..1f574ae 100644
--- a/pyproject.toml
+++ b/pyproject.toml
@@ -5,33 +5,13 @@ description = "HistoryHub personal browsing and viewing history"
readme = "README.md"
requires-python = ">=3.10"
dependencies = [
- "aiohttp~=3.11.13",
- "email-validator>=2.1.0",
"fastapi~=0.115.8",
- "httpx~=0.28.1",
- "jieba~=0.42.1",
- "jinja2~=3.1.5",
"loguru>=0.7.2",
- "mcp[cli]>=1.27.2",
- "numpy~=1.26.4",
- "openpyxl~=3.1.5",
- "pandas~=2.2.3",
- "apprise>=1.11.0",
"pillow~=10.2.0",
- "psutil>=5.9.0",
"pydantic>=2.11,<3",
- "pyecharts~=2.0.8",
"pyinstaller>=6.12.0",
- "pymysql~=1.1.1",
- "python-dateutil>=2.8.2",
"pyyaml~=6.0.2",
"qrcode~=8.0",
"requests~=2.32.3",
- "schedule~=1.2.2",
- "scikit-learn~=1.5.2",
- "snownlp~=0.12.3",
- "tqdm>=4.66.0",
- "urllib3~=2.3.0",
"uvicorn~=0.32.1",
- "yutto~=2.0.0",
]
diff --git a/requirements.txt b/requirements.txt
index 3fd1d95..b734c32 100644
--- a/requirements.txt
+++ b/requirements.txt
@@ -1,45 +1,15 @@
# This file was autogenerated by uv via the following command:
-# uv export --format requirements-txt --no-hashes -o requirements.txt
-aiofiles==24.1.0
- # via yutto
-aiohappyeyeballs==2.6.1
- # via aiohttp
-aiohttp==3.11.16
- # via bilibilihistoryfetcher
-aiosignal==1.3.2
- # via aiohttp
+# uv export --format requirements-txt --no-hashes --no-dev -o requirements.txt
altgraph==0.17.4
# via
# macholib
# pyinstaller
-annotated-doc==0.0.4
- # via typer
annotated-types==0.7.0
# via pydantic
-apprise==1.11.0
- # via bilibilihistoryfetcher
anyio==4.9.0
- # via
- # httpx
- # mcp
- # sse-starlette
- # starlette
-async-timeout==5.0.1 ; python_full_version < '3.11'
- # via aiohttp
-attrs==25.3.0
- # via
- # aiohttp
- # jsonschema
- # referencing
-biliass==2.2.0
- # via yutto
+ # via starlette
certifi==2025.1.31
- # via
- # httpcore
- # httpx
- # requests
-cffi==2.0.0 ; platform_python_implementation != 'PyPy'
- # via cryptography
+ # via requests
charset-normalizer==3.4.1
# via requests
click==8.1.8
@@ -49,238 +19,67 @@ colorama==0.4.6 ; sys_platform == 'win32'
# click
# loguru
# qrcode
- # tqdm
- # typer
- # yutto
-cryptography==48.0.1
- # via pyjwt
-dict2xml==1.7.6
- # via yutto
-dnspython==2.7.0
- # via email-validator
-email-validator==2.2.0
- # via bilibilihistoryfetcher
-et-xmlfile==2.0.0
- # via openpyxl
exceptiongroup==1.2.2 ; python_full_version < '3.11'
# via anyio
fastapi==0.115.12
- # via bilibilihistoryfetcher
-frozenlist==1.5.0
- # via
- # aiohttp
- # aiosignal
+ # via historyhub
h11==0.14.0
- # via
- # httpcore
- # uvicorn
-h2==4.2.0
- # via httpx
-hpack==4.1.0
- # via h2
-httpcore==1.0.7
- # via httpx
-httpx==0.28.1
- # via
- # bilibilihistoryfetcher
- # mcp
- # yutto
-httpx-sse==0.4.3
- # via mcp
-hyperframe==6.1.0
- # via h2
+ # via uvicorn
idna==3.10
# via
# anyio
- # email-validator
- # httpx
# requests
- # yarl
-jieba==0.42.1
- # via bilibilihistoryfetcher
-jinja2==3.1.6
- # via
- # bilibilihistoryfetcher
- # pyecharts
-joblib==1.4.2
- # via scikit-learn
-jsonschema==4.26.0
- # via mcp
-jsonschema-specifications==2025.9.1
- # via jsonschema
loguru==0.7.3
- # via bilibilihistoryfetcher
+ # via historyhub
macholib==1.16.3 ; sys_platform == 'darwin'
# via pyinstaller
-markdown-it-py==4.2.0
- # via rich
-markupsafe==3.0.2
- # via jinja2
-mcp==1.27.2
- # via bilibilihistoryfetcher
-mdurl==0.1.2
- # via markdown-it-py
-multidict==6.3.2
- # via
- # aiohttp
- # yarl
-numpy==1.26.4
- # via
- # bilibilihistoryfetcher
- # pandas
- # scikit-learn
- # scipy
-openpyxl==3.1.5
- # via bilibilihistoryfetcher
packaging==24.2
# via
# pyinstaller
# pyinstaller-hooks-contrib
-pandas==2.2.3
- # via bilibilihistoryfetcher
pefile==2023.2.7 ; sys_platform == 'win32'
# via pyinstaller
pillow==10.2.0
- # via bilibilihistoryfetcher
-prettytable==3.16.0
- # via pyecharts
-propcache==0.3.1
- # via
- # aiohttp
- # yarl
-psutil==7.0.0
- # via bilibilihistoryfetcher
-pycparser==3.0 ; implementation_name != 'PyPy' and platform_python_implementation != 'PyPy'
- # via cffi
+ # via historyhub
pydantic==2.13.4
# via
- # bilibilihistoryfetcher
# fastapi
- # mcp
- # pydantic-settings
- # yutto
+ # historyhub
pydantic-core==2.46.4
# via pydantic
-pydantic-settings==2.14.1
- # via mcp
-pyecharts==2.0.8
- # via bilibilihistoryfetcher
-pygments==2.20.0
- # via rich
pyinstaller==6.12.0
- # via bilibilihistoryfetcher
+ # via historyhub
pyinstaller-hooks-contrib==2025.2
# via pyinstaller
-pyjwt==2.13.0
- # via mcp
-pymysql==1.1.1
- # via bilibilihistoryfetcher
-python-dateutil==2.9.0.post0
- # via
- # bilibilihistoryfetcher
- # pandas
-python-dotenv==1.2.2
- # via
- # mcp
- # pydantic-settings
-python-multipart==0.0.32
- # via mcp
-pytz==2025.2
- # via pandas
-pywin32==312 ; sys_platform == 'win32'
- # via mcp
pywin32-ctypes==0.2.3 ; sys_platform == 'win32'
# via pyinstaller
pyyaml==6.0.2
- # via bilibilihistoryfetcher
+ # via historyhub
qrcode==8.1
- # via bilibilihistoryfetcher
-referencing==0.37.0
- # via
- # jsonschema
- # jsonschema-specifications
+ # via historyhub
requests==2.32.3
- # via bilibilihistoryfetcher
-rich==15.0.0
- # via typer
-rpds-py==0.30.0 ; python_full_version < '3.11'
- # via
- # jsonschema
- # referencing
-rpds-py==2026.5.1 ; python_full_version >= '3.11'
- # via
- # jsonschema
- # referencing
-schedule==1.2.2
- # via bilibilihistoryfetcher
-scikit-learn==1.5.2
- # via bilibilihistoryfetcher
-scipy==1.15.2
- # via scikit-learn
+ # via historyhub
setuptools==78.1.0
# via
# pyinstaller
# pyinstaller-hooks-contrib
-shellingham==1.5.4
- # via typer
-simplejson==3.20.1
- # via pyecharts
-six==1.17.0
- # via python-dateutil
sniffio==1.3.1
# via anyio
-snownlp==0.12.3
- # via bilibilihistoryfetcher
-socksio==1.0.0
- # via httpx
-sse-starlette==3.0.3
- # via mcp
starlette==0.46.1
- # via
- # fastapi
- # mcp
-threadpoolctl==3.6.0
- # via scikit-learn
-tomli==2.2.1 ; python_full_version < '3.11'
- # via yutto
-tqdm==4.67.1
- # via bilibilihistoryfetcher
-typer==0.26.7
- # via mcp
+ # via fastapi
typing-extensions==4.15.0
# via
# anyio
- # cryptography
# fastapi
- # mcp
- # multidict
# pydantic
# pydantic-core
- # pyjwt
- # referencing
# typing-inspection
# uvicorn
- # yutto
typing-inspection==0.4.2
- # via
- # mcp
- # pydantic
- # pydantic-settings
-tzdata==2025.2
- # via pandas
+ # via pydantic
urllib3==2.3.0
- # via
- # bilibilihistoryfetcher
- # requests
+ # via requests
uvicorn==0.32.1
- # via
- # bilibilihistoryfetcher
- # mcp
-wcwidth==0.2.13
- # via prettytable
+ # via historyhub
win32-setctime==1.2.0 ; sys_platform == 'win32'
# via loguru
-yarl==1.19.0
- # via aiohttp
-yutto==2.0.2
- # via bilibilihistoryfetcher
diff --git a/routers/analysis.py b/routers/analysis.py
deleted file mode 100644
index c257a1b..0000000
--- a/routers/analysis.py
+++ /dev/null
@@ -1,45 +0,0 @@
-from fastapi import APIRouter, Query
-from typing import Optional
-from datetime import datetime
-
-from scripts.analyze_bilibili_history import get_daily_and_monthly_counts, get_available_years
-
-router = APIRouter()
-
-@router.post("/analyze", summary="分析历史数据")
-async def analyze_history(
- year: Optional[int] = Query(None, description="要分析的年份,不传则使用当前年份")
-):
- """分析历史数据
-
- Args:
- year: 要分析的年份,不传则使用当前年份
- """
- # 获取可用年份列表
- available_years = get_available_years()
- if not available_years:
- return {
- "status": "error",
- "message": "未找到任何历史记录数据"
- }
-
- # 如果未指定年份,使用最新的年份
- target_year = year if year is not None else available_years[0]
-
- # 检查指定的年份是否可用
- if year is not None and year not in available_years:
- return {
- "status": "error",
- "message": f"未找到 {year} 年的历史记录数据。可用的年份有:{', '.join(map(str, available_years))}"
- }
-
- result = get_daily_and_monthly_counts(target_year)
- if "error" in result:
- return {"status": "error", "message": result["error"]}
- return {
- "status": "success",
- "message": "分析完成",
- "data": result,
- "year": target_year,
- "available_years": available_years
- }
diff --git a/routers/apprise_config.py b/routers/apprise_config.py
deleted file mode 100644
index d7cfde6..0000000
--- a/routers/apprise_config.py
+++ /dev/null
@@ -1,140 +0,0 @@
-from typing import Optional
-from fastapi import APIRouter, HTTPException
-from pydantic import BaseModel
-import yaml
-import os
-import re
-
-from scripts.utils import load_config
-from scripts.apprise_notify import test_apprise_urls
-
-router = APIRouter()
-
-
-def get_config_path():
- base_dir = os.path.dirname(os.path.dirname(os.path.abspath(__file__)))
- return os.path.join(base_dir, 'config', 'config.yaml')
-
-
-def update_yaml_section(content: str, section: str, data: dict) -> str:
- """更新YAML文件中的整个section"""
- lines = content.split('\n')
- section_indent = ' '
-
- # 查找section起始位置
- start_idx = -1
- for i, line in enumerate(lines):
- if re.match(rf'^{section}:', line.strip()):
- start_idx = i
- break
-
- # 构建新section内容
- new_lines = [f'{section}:']
- for key, value in data.items():
- if value is None:
- new_lines.append(f'{section_indent}{key}:')
- elif isinstance(value, list):
- new_lines.append(f'{section_indent}{key}:')
- for item in value:
- new_lines.append(f'{section_indent} - "{item}"')
- elif isinstance(value, bool):
- new_lines.append(f'{section_indent}{key}: {str(value).lower()}')
- elif isinstance(value, str):
- new_lines.append(f'{section_indent}{key}: "{value}"')
- else:
- new_lines.append(f'{section_indent}{key}: {value}')
-
- if start_idx == -1:
- if lines and lines[-1].strip() != '':
- lines.append('')
- lines.extend(new_lines)
- else:
- end_idx = start_idx + 1
- while end_idx < len(lines):
- if lines[end_idx].strip() == '' or lines[end_idx].startswith(' '):
- end_idx += 1
- else:
- break
- if end_idx < len(lines) and lines[end_idx].strip() != '':
- new_lines.append('')
- lines = lines[:start_idx] + new_lines + lines[end_idx:]
-
- return '\n'.join(lines)
-
-
-class AppriseConfigUpdate(BaseModel):
- enabled: Optional[bool] = None
- urls: Optional[str] = None
-
-
-class AppriseTestRequest(BaseModel):
- urls: str
-
-
-@router.get("/apprise-config", summary="获取Apprise推送配置")
-async def get_apprise_config():
- """获取当前Apprise推送配置"""
- try:
- config = load_config()
- apprise_config = config.get('apprise', {})
- urls = apprise_config.get('urls', [])
- return {
- "enabled": apprise_config.get('enabled', True),
- "urls": '\n'.join(urls) if isinstance(urls, list) else str(urls or '')
- }
- except Exception as e:
- raise HTTPException(status_code=500, detail=f"获取Apprise配置失败: {str(e)}")
-
-
-@router.post("/apprise-config", summary="更新Apprise推送配置")
-async def update_apprise_config(request: AppriseConfigUpdate):
- """更新Apprise推送配置"""
- try:
- config_path = get_config_path()
- with open(config_path, 'r', encoding='utf-8') as f:
- content = f.read()
-
- config = yaml.safe_load(content) or {}
- apprise_config = config.get('apprise', {})
-
- if request.enabled is not None:
- apprise_config['enabled'] = request.enabled
-
- if request.urls is not None:
- urls = [line.strip() for line in request.urls.splitlines() if line.strip()]
- apprise_config['urls'] = urls
-
- content = update_yaml_section(content, 'apprise', apprise_config)
- with open(config_path, 'w', encoding='utf-8') as f:
- f.write(content)
-
- return {
- "status": "success",
- "message": "Apprise配置更新成功",
- "config": {
- "enabled": apprise_config.get('enabled', True),
- "urls": '\n'.join(apprise_config.get('urls', []))
- }
- }
- except Exception as e:
- raise HTTPException(status_code=500, detail=f"更新Apprise配置失败: {str(e)}")
-
-
-@router.post("/test-apprise", summary="测试Apprise推送")
-async def send_test_apprise(request: AppriseTestRequest):
- """测试Apprise推送配置"""
- try:
- urls = [line.strip() for line in request.urls.splitlines() if line.strip()]
- if not urls:
- raise ValueError("请至少填写一个推送地址")
-
- result = await test_apprise_urls(urls)
- if result['status'] == 'error':
- raise HTTPException(status_code=400, detail=result['message'])
- return result
- except ValueError as e:
- raise HTTPException(status_code=400, detail=str(e))
- except HTTPException:
- raise
- except Exception as e:
- raise HTTPException(status_code=500, detail=f"测试推送失败: {str(e)}")
diff --git a/routers/bilibili_history_delete.py b/routers/bilibili_history_delete.py
deleted file mode 100644
index 789d801..0000000
--- a/routers/bilibili_history_delete.py
+++ /dev/null
@@ -1,210 +0,0 @@
-"""
-B站历史记录删除API
-实现B站历史记录的删除功能,支持单条和批量删除
-"""
-
-from typing import List
-
-import requests
-from fastapi import APIRouter, Query
-from pydantic import BaseModel, Field
-
-from scripts.utils import load_config
-
-router = APIRouter()
-
-class DeleteHistoryItem(BaseModel):
- """删除历史记录项目模型"""
- kid: str = Field(..., description="删除的目标记录,格式为{业务类型}_{目标id}")
- sync_to_bilibili: bool = Field(True, description="是否同步删除B站服务器上的记录")
-
-class BatchDeleteRequest(BaseModel):
- """批量删除请求模型"""
- items: List[DeleteHistoryItem] = Field(..., description="要删除的历史记录列表")
-
-def get_headers():
- """获取请求头"""
- # 动态读取配置文件,获取最新的SESSDATA
- current_config = load_config()
- headers = {
- 'User-Agent': 'Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/91.0.4472.124 Safari/537.36',
- 'Referer': 'https://www.bilibili.com/',
- 'Origin': 'https://www.bilibili.com',
- 'Content-Type': 'application/x-www-form-urlencoded',
- }
-
- # 添加Cookie
- cookies = []
- if 'SESSDATA' in current_config:
- cookies.append(f"SESSDATA={current_config['SESSDATA']}")
- if 'bili_jct' in current_config:
- cookies.append(f"bili_jct={current_config['bili_jct']}")
- if 'DedeUserID' in current_config:
- cookies.append(f"DedeUserID={current_config['DedeUserID']}")
-
- if cookies:
- headers['Cookie'] = '; '.join(cookies)
-
- return headers
-
-@router.delete("/single", summary="删除单条历史记录")
-async def delete_single_history(
- kid: str = Query(..., description="删除的目标记录,格式为{业务类型}_{目标id}"),
- sync_to_bilibili: bool = Query(True, description="是否同步删除B站服务器上的记录")
-):
- """
- 删除单条历史记录
-
- - **kid**: 删除的目标记录,格式为{业务类型}_{目标id}
- - 视频:archive_{稿件bvid}
- - 直播:live_{直播间id}
- - 专栏:article_{专栏cvid}
- - 剧集:pgc_{剧集ssid}
- - 文集:article-list_{文集rlid}
- - **sync_to_bilibili**: 是否同步删除B站服务器上的记录
- """
- try:
- # 如果需要同步删除B站服务器上的记录
- if sync_to_bilibili:
- # 获取配置
- current_config = load_config()
- bili_jct = current_config.get("bili_jct", "")
-
- if not bili_jct:
- return {
- "status": "error",
- "message": "缺少CSRF Token (bili_jct),请先使用QR码登录并确保已正确获取bili_jct"
- }
-
- # 准备请求参数
- data = {
- "kid": kid,
- "csrf": bili_jct
- }
-
- # 发送请求
- headers = get_headers()
- response = requests.post(
- "https://api.bilibili.com/x/v2/history/delete",
- data=data, # 使用form-urlencoded格式
- headers=headers
- )
-
- # 解析响应
- result = response.json()
-
- if result.get("code") != 0:
- return {
- "status": "error",
- "message": f"删除B站历史记录失败: {result.get('message', '未知错误')}",
- "code": result.get("code"),
- "data": result
- }
-
- # 返回成功结果
- return {
- "status": "success",
- "message": "历史记录删除成功",
- "data": {
- "kid": kid,
- "sync_to_bilibili": sync_to_bilibili
- }
- }
-
- except Exception as e:
- return {
- "status": "error",
- "message": f"删除历史记录失败: {str(e)}"
- }
-
-@router.delete("/batch", summary="批量删除历史记录")
-async def batch_delete_history(request: BatchDeleteRequest):
- """
- 批量删除历史记录
-
- - **items**: 要删除的历史记录列表,每个记录包含kid和是否同步删除B站服务器上的记录的标志
- """
- try:
- # 获取配置
- current_config = load_config()
- bili_jct = current_config.get("bili_jct", "")
-
- if not bili_jct:
- return {
- "status": "error",
- "message": "缺少CSRF Token (bili_jct),请先使用QR码登录并确保已正确获取bili_jct"
- }
-
- # 处理结果
- results = []
- success_count = 0
- error_count = 0
-
- # 需要同步删除B站服务器上的记录的项目
- sync_items = [item for item in request.items if item.sync_to_bilibili]
-
- # 如果有需要同步删除的记录
- if sync_items:
- # 准备请求参数 - 支持批量删除,用逗号分隔多个kid
- kids = ",".join([item.kid for item in sync_items])
- data = {
- "kid": kids,
- "csrf": bili_jct
- }
-
- # 发送请求
- headers = get_headers()
- response = requests.post(
- "https://api.bilibili.com/x/v2/history/delete",
- data=data, # 使用form-urlencoded格式
- headers=headers
- )
-
- # 解析响应
- result = response.json()
-
- if result.get("code") == 0:
- success_count += len(sync_items)
- for item in sync_items:
- results.append({
- "kid": item.kid,
- "sync_to_bilibili": True,
- "status": "success"
- })
- else:
- error_count += len(sync_items)
- error_message = result.get('message', '未知错误')
- for item in sync_items:
- results.append({
- "kid": item.kid,
- "sync_to_bilibili": True,
- "status": "error",
- "message": error_message
- })
-
- # 处理不需要同步删除的记录
- for item in request.items:
- if not item.sync_to_bilibili:
- success_count += 1
- results.append({
- "kid": item.kid,
- "sync_to_bilibili": False,
- "status": "success"
- })
-
- # 返回结果
- return {
- "status": "success" if error_count == 0 else "partial_success",
- "message": f"成功删除 {success_count} 条历史记录,失败 {error_count} 条",
- "data": {
- "success_count": success_count,
- "error_count": error_count,
- "results": results
- }
- }
-
- except Exception as e:
- return {
- "status": "error",
- "message": f"批量删除历史记录失败: {str(e)}"
- }
diff --git a/routers/categories.py b/routers/categories.py
deleted file mode 100644
index e536c12..0000000
--- a/routers/categories.py
+++ /dev/null
@@ -1,177 +0,0 @@
-import sqlite3
-from fastapi import APIRouter
-from scripts.init_categories import init_categories
-from scripts.utils import get_output_path, load_config
-
-router = APIRouter()
-
-def get_db():
- """获取数据库连接"""
- config = load_config()
- db_path = get_output_path(config['db_file'])
- return sqlite3.connect(db_path)
-
-def ensure_table_exists():
- """确保分类表存在,如果不存在则初始化"""
- try:
- conn = get_db()
- cursor = conn.cursor()
-
- # 检查表是否存在
- cursor.execute('''
- SELECT name FROM sqlite_master
- WHERE type='table' AND name='video_categories'
- ''')
-
- if not cursor.fetchone():
- print("分类表不存在,正在初始化...")
- init_categories()
- print("分类表初始化完成")
-
- except sqlite3.Error as e:
- print(f"检查表存在时发生错误: {e}")
- finally:
- if conn:
- conn.close()
-
-@router.post("/init", summary="初始化视频分类数据")
-async def initialize_categories():
- """初始化视频分类数据"""
- try:
- init_categories()
- return {
- "status": "success",
- "message": "视频分类表初始化成功"
- }
- except Exception as e:
- return {
- "status": "error",
- "message": f"初始化失败: {str(e)}"
- }
-
-@router.get("/categories", summary="获取所有分类信息")
-async def get_categories():
- """获取所有分类信息"""
- try:
- # 确保表存在
- ensure_table_exists()
-
- conn = get_db()
- cursor = conn.cursor()
-
- # 查询所有分类
- cursor.execute('''
- SELECT main_category, sub_category, alias, tid, image
- FROM video_categories
- ORDER BY main_category, sub_category
- ''')
-
- # 构建分类树
- categories = {}
- for row in cursor.fetchall():
- main_cat, sub_cat, alias, tid, image = row
-
- if main_cat not in categories:
- categories[main_cat] = {
- "name": main_cat,
- "image": image,
- "sub_categories": []
- }
-
- # 只有当子分类名称不等于主分类名称时才添加
- if sub_cat != main_cat:
- categories[main_cat]["sub_categories"].append({
- "name": sub_cat,
- "alias": alias,
- "tid": tid
- })
-
- # 打印结果
- print("\n=== 分类数据 ===")
- print(f"主分类数量: {len(categories)}")
- for main_cat, data in categories.items():
- print(f"{main_cat}: {len(data['sub_categories'])} 个子分类")
- print("===============\n")
-
- return {
- "status": "success",
- "data": list(categories.values())
- }
-
- except sqlite3.Error as e:
- error_msg = f"数据库错误: {str(e)}"
- print(f"=== 错误 ===\n{error_msg}\n===========")
- return {"status": "error", "message": error_msg}
- finally:
- if conn:
- conn.close()
-
-@router.get("/main-categories", summary="获取所有主分类")
-async def get_main_categories():
- """获取所有主分类"""
- try:
- # 确保表存在
- ensure_table_exists()
-
- conn = get_db()
- cursor = conn.cursor()
-
- cursor.execute('''
- SELECT DISTINCT main_category, image
- FROM video_categories
- ORDER BY main_category
- ''')
-
- categories = []
- for row in cursor.fetchall():
- categories.append({
- "name": row[0],
- "image": row[1]
- })
-
- return {
- "status": "success",
- "data": categories
- }
-
- except sqlite3.Error as e:
- return {"status": "error", "message": f"数据库错误: {str(e)}"}
- finally:
- if conn:
- conn.close()
-
-@router.get("/sub-categories/{main_category}", summary="获取指定主分类下的所有子分类")
-async def get_sub_categories(main_category: str):
- """获取指定主分类下的所有子分类"""
- try:
- # 确保表存在
- ensure_table_exists()
-
- conn = get_db()
- cursor = conn.cursor()
-
- cursor.execute('''
- SELECT sub_category, alias, tid
- FROM video_categories
- WHERE main_category = ? AND sub_category != main_category
- ORDER BY sub_category
- ''', (main_category,))
-
- categories = []
- for row in cursor.fetchall():
- categories.append({
- "name": row[0],
- "alias": row[1],
- "tid": row[2]
- })
-
- return {
- "status": "success",
- "data": categories
- }
-
- except sqlite3.Error as e:
- return {"status": "error", "message": f"数据库错误: {str(e)}"}
- finally:
- if conn:
- conn.close()
\ No newline at end of file
diff --git a/routers/clean_data.py b/routers/clean_data.py
deleted file mode 100644
index 005e077..0000000
--- a/routers/clean_data.py
+++ /dev/null
@@ -1,8 +0,0 @@
-from fastapi import APIRouter
-from scripts.clean_data import clean_history_data
-
-router = APIRouter()
-
-@router.post("/clean_data", summary="清理Bilibili历史数据")
-def api_clean_data():
- return clean_history_data()
diff --git a/routers/collection_download.py b/routers/collection_download.py
deleted file mode 100644
index 74ac39f..0000000
--- a/routers/collection_download.py
+++ /dev/null
@@ -1,422 +0,0 @@
-import os
-import re
-from typing import Optional, List, Dict, Any, Tuple
-
-from fastapi import APIRouter, HTTPException
-from fastapi.responses import StreamingResponse
-from pydantic import BaseModel, Field
-import httpx
-
-from scripts.utils import load_config
-from scripts.yutto_runner import run_yutto
-
-router = APIRouter()
-config = load_config()
-
-class CollectionInfo(BaseModel):
- """合集信息"""
- is_collection: bool = Field(..., description="是否为合集")
- collection_id: Optional[str] = Field(None, description="合集ID")
- collection_title: Optional[str] = Field(None, description="合集标题")
- total_videos: Optional[int] = Field(None, description="合集中视频总数")
- current_video_index: Optional[int] = Field(None, description="当前视频在合集中的位置")
- videos: Optional[List[Dict[str, Any]]] = Field(None, description="合集中的视频列表")
- uploader_mid: Optional[int] = Field(None, description="UP主的UID")
-
-class CollectionDownloadRequest(BaseModel):
- """合集下载请求 - 简化版,只用于整个合集下载"""
- url: str = Field(..., description="合集URL")
- cid: int = Field(..., description="视频的 CID,用于分类存储")
-
- # 基础下载参数
- sessdata: Optional[str] = Field(None, description="用户的 SESSDATA")
- download_cover: Optional[bool] = Field(True, description="是否下载视频封面")
- only_audio: Optional[bool] = Field(False, description="是否仅下载音频")
- video_quality: Optional[int] = Field(None, description="视频清晰度等级")
- audio_quality: Optional[int] = Field(None, description="音频码率等级")
- vcodec: Optional[str] = Field(None, description="视频编码")
- acodec: Optional[str] = Field(None, description="音频编码")
- download_vcodec_priority: Optional[str] = Field(None, description="视频下载编码优先级")
- output_format: Optional[str] = Field(None, description="输出格式")
- output_format_audio_only: Optional[str] = Field(None, description="仅包含音频流时的输出格式")
- video_only: Optional[bool] = Field(False, description="是否仅下载视频流")
- danmaku_only: Optional[bool] = Field(False, description="是否仅生成弹幕文件")
- no_danmaku: Optional[bool] = Field(False, description="是否不生成弹幕文件")
- subtitle_only: Optional[bool] = Field(False, description="是否仅生成字幕文件")
- no_subtitle: Optional[bool] = Field(False, description="是否不生成字幕文件")
- metadata_only: Optional[bool] = Field(False, description="是否仅生成媒体元数据文件")
- save_cover: Optional[bool] = Field(False, description="生成视频流封面时是否单独保存封面")
- cover_only: Optional[bool] = Field(False, description="是否仅生成视频封面")
- no_chapter_info: Optional[bool] = Field(False, description="是否不生成章节信息")
-
-def extract_video_info_from_url(url: str) -> Dict[str, Any]:
- """
- 从URL中提取视频信息
-
- Args:
- url: 视频URL
-
- Returns:
- 包含视频信息的字典
- """
- # 提取BV号或AV号
- bv_match = re.search(r'BV[a-zA-Z0-9]+', url)
- av_match = re.search(r'av(\d+)', url)
-
- video_id = None
- if bv_match:
- video_id = bv_match.group()
- elif av_match:
- video_id = f"av{av_match.group(1)}"
-
- # 提取分P信息
- p_match = re.search(r'[?&]p=(\d+)', url)
- page = int(p_match.group(1)) if p_match else 1
-
- return {
- "video_id": video_id,
- "page": page,
- "original_url": url
- }
-
-async def get_video_collection_info(url: str, sessdata: Optional[str] = None) -> CollectionInfo:
- """
- 获取视频的合集信息
-
- Args:
- url: 视频URL
- sessdata: 可选的SESSDATA用于认证
-
- Returns:
- 合集信息对象
- """
- try:
- video_info = extract_video_info_from_url(url)
- if not video_info["video_id"]:
- return CollectionInfo(is_collection=False)
-
- # 构建API请求
- api_url = f"https://api.bilibili.com/x/web-interface/view"
- headers = {
- 'User-Agent': 'Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/91.0.4472.124 Safari/537.36',
- 'Referer': 'https://www.bilibili.com/'
- }
-
- if sessdata:
- headers['Cookie'] = f'SESSDATA={sessdata}'
- elif config.get('SESSDATA'):
- headers['Cookie'] = f'SESSDATA={config["SESSDATA"]}'
-
- params = {}
- if video_info["video_id"].startswith('BV'):
- params['bvid'] = video_info["video_id"]
- else:
- params['aid'] = video_info["video_id"][2:] # 去掉'av'前缀
-
- async with httpx.AsyncClient() as client:
- response = await client.get(api_url, params=params, headers=headers)
- response.raise_for_status()
- data = response.json()
-
- if data.get('code') != 0:
- return CollectionInfo(is_collection=False)
-
- video_data = data.get('data', {})
-
- # 检查是否有合集信息
- ugc_season = video_data.get('ugc_season')
- if ugc_season:
- # 这是一个合集
- collection_info = CollectionInfo(
- is_collection=True,
- collection_id=str(ugc_season.get('id')),
- collection_title=ugc_season.get('title'),
- total_videos=len(ugc_season.get('sections', [{}])[0].get('episodes', [])),
- videos=[],
- # 添加UP主信息用于构建合集URL
- uploader_mid=video_data.get('owner', {}).get('mid')
- )
-
- # 获取合集中的视频列表
- episodes = ugc_season.get('sections', [{}])[0].get('episodes', [])
- for i, episode in enumerate(episodes):
- video_item = {
- "index": i + 1,
- "title": episode.get('title'),
- "bvid": episode.get('bvid'),
- "cid": episode.get('cid'),
- "duration": episode.get('arc', {}).get('duration'),
- "page": episode.get('page', 1)
- }
- collection_info.videos.append(video_item)
-
- # 检查当前视频在合集中的位置
- if episode.get('bvid') == video_info["video_id"]:
- collection_info.current_video_index = i + 1
-
- return collection_info
-
- # 检查是否有分P视频(多P视频也可以视为一种合集)
- pages = video_data.get('pages', [])
- if len(pages) > 1:
- collection_info = CollectionInfo(
- is_collection=True,
- collection_id=video_info["video_id"],
- collection_title=video_data.get('title'),
- total_videos=len(pages),
- current_video_index=video_info["page"],
- videos=[],
- uploader_mid=video_data.get('owner', {}).get('mid')
- )
-
- for page in pages:
- video_item = {
- "index": page.get('page'),
- "title": page.get('part'),
- "bvid": video_info["video_id"],
- "cid": page.get('cid'),
- "duration": page.get('duration'),
- "page": page.get('page')
- }
- collection_info.videos.append(video_item)
-
- return collection_info
-
- # 不是合集,只是单个视频
- return CollectionInfo(is_collection=False)
-
- except Exception as e:
- print(f"获取合集信息时出错:{str(e)}")
- return CollectionInfo(is_collection=False)
-
-def check_download_directories() -> Tuple[str, str]:
- """
- 检查下载目录和临时目录是否存在且有写入权限
-
- Returns:
- 下载目录和临时目录的路径元组
-
- Raises:
- HTTPException: 如果目录不存在或没有写入权限
- """
- download_dir = os.path.normpath(config['yutto']['basic']['dir'])
- tmp_dir = os.path.normpath(config['yutto']['basic']['tmp_dir'])
-
- # 创建目录(如果不存在)
- os.makedirs(download_dir, exist_ok=True)
- os.makedirs(tmp_dir, exist_ok=True)
-
- # 检查目录权限
- if not os.access(download_dir, os.W_OK):
- raise HTTPException(
- status_code=500,
- detail=f"没有下载目录的写入权限:{download_dir}"
- )
- if not os.access(tmp_dir, os.W_OK):
- raise HTTPException(
- status_code=500,
- detail=f"没有临时目录的写入权限:{tmp_dir}"
- )
-
- return download_dir, tmp_dir
-
-def add_download_params_to_command(command: List[str], params: CollectionDownloadRequest) -> List[str]:
- """
- 将下载参数添加到命令中
-
- Args:
- command: 命令列表
- params: 包含下载参数的对象
-
- Returns:
- 添加了下载参数的命令列表
- """
- # 基础参数
- if params.video_quality is not None:
- command.extend(['--video-quality', str(params.video_quality)])
-
- if params.audio_quality is not None:
- command.extend(['--audio-quality', str(params.audio_quality)])
-
- if params.vcodec:
- command.extend(['--vcodec', params.vcodec])
-
- if params.acodec:
- command.extend(['--acodec', params.acodec])
-
- if params.download_vcodec_priority:
- command.extend(['--download-vcodec-priority', params.download_vcodec_priority])
-
- if params.output_format:
- command.extend(['--output-format', params.output_format])
-
- if params.output_format_audio_only:
- command.extend(['--output-format-audio-only', params.output_format_audio_only])
-
- # 资源选择参数
- if params.video_only:
- command.append('--video-only')
-
- if params.only_audio:
- command.append('--audio-only')
-
- if params.no_danmaku:
- command.append('--no-danmaku')
-
- if params.danmaku_only:
- command.append('--danmaku-only')
-
- if params.no_subtitle or not config['yutto']['resource']['require_subtitle']:
- command.append('--no-subtitle')
-
- if params.subtitle_only:
- command.append('--subtitle-only')
-
- if params.metadata_only:
- command.append('--metadata-only')
-
- if not params.download_cover:
- command.append('--no-cover')
-
- if params.save_cover:
- command.append('--save-cover')
-
- if params.cover_only:
- command.append('--cover-only')
-
- if params.no_chapter_info:
- command.append('--no-chapter-info')
-
- # 添加其他 yutto 配置
- if config['yutto']['danmaku']['font_size']:
- command.extend(['--danmaku-font-size', str(config['yutto']['danmaku']['font_size'])])
-
- if config['yutto']['batch']['with_section']:
- command.append('--with-section')
-
- # 如果提供了 SESSDATA,添加到命令中
- if params.sessdata:
- command.extend(['--sessdata', params.sessdata])
- elif config.get('SESSDATA'):
- command.extend(['--sessdata', config['SESSDATA']])
-
- return command
-
-@router.get("/check_collection", summary="检查视频是否为合集")
-async def check_collection(url: str, sessdata: Optional[str] = None):
- """
- 检查给定的视频URL是否为合集
-
- Args:
- url: 视频URL
- sessdata: 可选的SESSDATA用于认证
-
- Returns:
- 合集信息
- """
- try:
- collection_info = await get_video_collection_info(url, sessdata)
- return {
- "status": "success",
- "data": collection_info.model_dump()
- }
- except Exception as e:
- raise HTTPException(
- status_code=500,
- detail=f"检查合集信息时出错:{str(e)}"
- )
-
-@router.post("/download_collection", summary="下载整个合集")
-async def download_collection(request: CollectionDownloadRequest):
- """
- 下载B站整个合集或多P视频的所有分P
-
- Args:
- request: 包含合集下载参数的请求对象
- """
- try:
- # 检查下载目录和临时目录
- download_dir, tmp_dir = check_download_directories()
-
- # 首先检查是否为合集
- collection_info = await get_video_collection_info(request.url, request.sessdata)
-
- if not collection_info.is_collection:
- raise HTTPException(
- status_code=400,
- detail="提供的URL不是合集或多P视频"
- )
-
- # 构建下载整个合集的命令
- # 使用安全的文件名(移除特殊字符)
- safe_collection_title = "".join(c for c in collection_info.collection_title if c.isalnum() or c in (' ', '-', '_')).rstrip()
-
- if collection_info.collection_id and collection_info.collection_id != collection_info.videos[0]["bvid"]:
- # 真正的合集,构建合集的专用URL
- if collection_info.uploader_mid:
- # 使用合集的专用URL格式
- collection_url = f"https://space.bilibili.com/{collection_info.uploader_mid}/channel/collectiondetail?sid={collection_info.collection_id}"
- command = [
- collection_url,
- '--batch', # 批量下载模式
- '--dir', download_dir,
- '--tmp-dir', tmp_dir,
- '--subpath-template', f'{safe_collection_title}_collection/{{title}}_{{username}}_{{download_date@%Y%m%d_%H%M%S}}/{{title}}',
- '--with-metadata'
- ]
- else:
- # 如果没有UP主信息,回退到使用单个视频URL + batch模式
- video_info = extract_video_info_from_url(request.url)
- base_url = f"https://www.bilibili.com/video/{video_info['video_id']}"
- command = [
- base_url,
- '--batch', # 批量下载模式
- '--dir', download_dir,
- '--tmp-dir', tmp_dir,
- '--subpath-template', f'{safe_collection_title}_collection/{{title}}_{{username}}_{{download_date@%Y%m%d_%H%M%S}}/{{title}}',
- '--with-metadata'
- ]
- else:
- # 多P视频,下载所有分P
- video_info = extract_video_info_from_url(request.url)
- base_url = f"https://www.bilibili.com/video/{video_info['video_id']}"
- command = [
- base_url,
- '--batch', # 批量下载模式
- '--dir', download_dir,
- '--tmp-dir', tmp_dir,
- '--subpath-template', f'{safe_collection_title}_multipart/{{title}}_{{username}}_{{download_date@%Y%m%d_%H%M%S}}/{{title}}',
- '--with-metadata'
- ]
-
- # 添加下载参数
- command = add_download_params_to_command(command, request)
-
- print(f"执行合集下载命令:yutto {' '.join(command)}")
- print(f"合集信息:{collection_info.collection_title},共 {collection_info.total_videos} 个视频")
- print("注意:如果合集中包含分P视频,yutto可能会报错,这是yutto限制,和本项目无关")
-
- async def event_stream():
- # 发送开始信息
- yield f"event: info\ndata: 开始下载合集:{collection_info.collection_title}\n\n"
- yield f"event: info\ndata: 合集共包含 {collection_info.total_videos} 个视频\n\n"
- yield f"event: info\ndata: 注意:如遇到分P视频,yutto可能会报错停止,这是yutto限制,和本项目无关\n\n"
-
- async for chunk in run_yutto(command):
- yield chunk
- yield "event: close\ndata: close\n\n"
-
- return StreamingResponse(event_stream(), media_type="text/event-stream")
-
- except HTTPException:
- raise
- except FileNotFoundError:
- raise HTTPException(
- status_code=500,
- detail="找不到 yutto 命令,请确保已正确安装"
- )
- except Exception as e:
- raise HTTPException(
- status_code=500,
- detail=f"下载过程出错:{str(e)}"
- )
diff --git a/routers/comment.py b/routers/comment.py
deleted file mode 100644
index 41cdb2d..0000000
--- a/routers/comment.py
+++ /dev/null
@@ -1,64 +0,0 @@
-from fastapi import APIRouter, HTTPException, Query
-from typing import Optional
-from scripts.comment_fetcher import fetch_and_save_comments, get_user_comments
-from enum import Enum
-
-router = APIRouter()
-
-class CommentType(str, Enum):
- ALL = "all"
- ROOT = "root"
- REPLY = "reply"
-
-@router.post("/fetch/{uid}", summary="获取用户评论")
-async def fetch_user_comments(uid: str):
- """
- 获取并保存用户的评论数据
-
- Args:
- uid: 用户ID
-
- Returns:
- dict: 包含操作结果、评论总数和最新评论时间的字典
- """
- try:
- result = fetch_and_save_comments(uid)
- return result
- except Exception as e:
- raise HTTPException(status_code=500, detail=str(e))
-
-@router.get("/query/{uid}", summary="查询用户评论")
-async def query_user_comments(
- uid: str,
- page: int = Query(1, description="页码,从1开始"),
- page_size: int = Query(20, description="每页数量"),
- comment_type: CommentType = Query(CommentType.ALL, description="评论类型:all-全部, root-一级评论, reply-二级评论"),
- keyword: Optional[str] = Query(None, description="关键词,用于模糊匹配评论内容"),
- type_filter: Optional[int] = Query(None, description="评论类型筛选,例如:1(视频评论),17(动态评论)等")
-):
- """
- 查询用户的评论数据,如果数据库中没有该用户的数据会自动获取
-
- Args:
- uid: 用户ID
- page: 页码,从1开始
- page_size: 每页数量
- comment_type: 评论类型,可选值:all(全部), root(一级评论), reply(二级评论)
- keyword: 关键词,用于模糊匹配评论内容
- type_filter: 评论类型筛选,例如:1(视频评论),17(动态评论)等
-
- Returns:
- dict: 包含评论列表和分页信息的字典
- """
- try:
- result = get_user_comments(
- uid=uid,
- page=page,
- page_size=page_size,
- comment_type=comment_type,
- keyword=keyword or "",
- comment_type_filter=type_filter
- )
- return result
- except Exception as e:
- raise HTTPException(status_code=500, detail=str(e))
\ No newline at end of file
diff --git a/routers/daily_count.py b/routers/daily_count.py
deleted file mode 100644
index ac39c5d..0000000
--- a/routers/daily_count.py
+++ /dev/null
@@ -1,227 +0,0 @@
-import sqlite3
-from datetime import datetime
-from typing import Optional
-
-from fastapi import APIRouter, HTTPException, Query
-
-from scripts.utils import load_config, get_output_path
-
-router = APIRouter()
-config = load_config()
-
-def get_db():
- """获取数据库连接"""
- db_path = get_output_path(config['db_file'])
- return sqlite3.connect(db_path)
-
-def get_available_years():
- """获取数据库中所有可用的年份"""
- conn = get_db()
- try:
- cursor = conn.cursor()
- cursor.execute("""
- SELECT name FROM sqlite_master
- WHERE type='table' AND name LIKE 'bilibili_history_%'
- ORDER BY name DESC
- """)
-
- years = []
- for (table_name,) in cursor.fetchall():
- try:
- year = int(table_name.split('_')[-1])
- years.append(year)
- except (ValueError, IndexError):
- continue
-
- return sorted(years, reverse=True)
- except sqlite3.Error as e:
- print(f"获取年份列表时发生错误: {e}")
- return []
- finally:
- if conn:
- conn.close()
-
-def get_daily_video_count(cursor, table_name: str, date: str) -> dict:
- """获取指定日期的视频数量统计
-
- Args:
- cursor: 数据库游标
- table_name: 表名
- date: 日期字符串,格式为MMDD
-
- Returns:
- dict: 包含视频数量统计的字典
- """
- try:
- # 解析日期
- month = int(date[:2])
- day = int(date[2:])
-
- # 从表名中获取年份
- year = int(table_name.split('_')[-1])
-
- # 构建日期范围
- start_timestamp = int(datetime(year, month, day, 0, 0, 0).timestamp())
- end_timestamp = int(datetime(year, month, day, 23, 59, 59).timestamp())
-
- # 查询总视频数
- cursor.execute(f"""
- SELECT COUNT(*) as total_count,
- COUNT(DISTINCT author_mid) as unique_authors,
- AVG(duration) as avg_duration,
- AVG(CAST(progress AS FLOAT) / CAST(duration AS FLOAT)) as avg_completion_rate,
- COUNT(CASE WHEN progress >= duration * 0.9 THEN 1 END) as completed_videos
- FROM {table_name}
- WHERE view_at >= ? AND view_at <= ?
- """, (start_timestamp, end_timestamp))
-
- result = cursor.fetchone()
- total_count, unique_authors, avg_duration, avg_completion_rate, completed_videos = result
-
- # 查询分区分布
- cursor.execute(f"""
- SELECT tag_name, COUNT(*) as count
- FROM {table_name}
- WHERE view_at >= ? AND view_at <= ?
- GROUP BY tag_name
- ORDER BY count DESC
- LIMIT 5
- """, (start_timestamp, end_timestamp))
-
- tag_distribution = {row[0]: row[1] for row in cursor.fetchall()}
-
- # 查询UP主分布
- cursor.execute(f"""
- SELECT author_name, COUNT(*) as count
- FROM {table_name}
- WHERE view_at >= ? AND view_at <= ?
- GROUP BY author_mid
- ORDER BY count DESC
- LIMIT 5
- """, (start_timestamp, end_timestamp))
-
- author_distribution = {row[0]: row[1] for row in cursor.fetchall()}
-
- return {
- "date": f"{year}-{month:02d}-{day:02d}",
- "total_videos": total_count,
- "unique_authors": unique_authors,
- "avg_duration": round(avg_duration if avg_duration else 0, 2),
- "avg_completion_rate": round(avg_completion_rate * 100 if avg_completion_rate else 0, 2),
- "completed_videos": completed_videos,
- "tag_distribution": tag_distribution,
- "author_distribution": author_distribution,
- "insights": [
- f"这一天你一共观看了 {total_count} 个视频",
- f"来自 {unique_authors} 个不同的UP主",
- f"平均时长 {round(avg_duration/60 if avg_duration else 0, 1)} 分钟",
- f"平均完成率 {round(avg_completion_rate * 100 if avg_completion_rate else 0, 1)}%",
- f"完整看完 {completed_videos} 个视频"
- ]
- }
- except ValueError as e:
- raise HTTPException(status_code=400, detail=f"日期格式错误: {str(e)}")
-
-@router.get("/daily-count", summary="获取指定日期的观看记录统计")
-async def get_daily_count(
- date: str = Query(..., description="日期,格式为MMDD,例如0113表示1月13日"),
- year: Optional[int] = Query(None, description="年份,不传则使用当前年份")
-):
- """获取指定日期的所有条目统计
-
- Args:
- date: 日期,格式为MMDD
- year: 年份,不传则使用当前年份
- """
- try:
- # 如果未指定年份,使用当前年份
- if year is None:
- year = datetime.now().year
-
- # 构建完整日期
- try:
- month = int(date[:2])
- day = int(date[2:])
- target_date = datetime(year, month, day)
- except ValueError:
- return {
- "status": "error",
- "message": "日期格式无效,应为MMDD格式,例如0113表示1月13日"
- }
-
- # 获取当日起止时间戳
- start_timestamp = int(datetime(year, month, day).timestamp())
- end_timestamp = start_timestamp + 86400 # 加一天的秒数
-
- conn = get_db()
- cursor = conn.cursor()
-
- # 检查年份表是否存在
- table_name = f"bilibili_history_{year}"
- cursor.execute("""
- SELECT name FROM sqlite_master
- WHERE type='table' AND name=?
- """, (table_name,))
-
- if not cursor.fetchone():
- return {
- "status": "error",
- "message": f"未找到 {year} 年的历史记录数据"
- }
-
- # 查询所有类型的条目数量
- query = f"""
- SELECT
- business,
- COUNT(*) as count
- FROM {table_name}
- WHERE view_at >= ? AND view_at < ?
- GROUP BY business
- """
-
- cursor.execute(query, (start_timestamp, end_timestamp))
- results = cursor.fetchall()
-
- # 统计当天观看总时长(秒)
- cursor.execute(f"""
- SELECT
- SUM(
- CASE
- WHEN progress = -1 THEN duration
- WHEN progress IS NULL THEN 0
- WHEN progress >= 0 THEN
- CASE WHEN progress > duration THEN duration ELSE progress END
- ELSE 0
- END
- ) AS total_watch_seconds
- FROM {table_name}
- WHERE view_at >= ? AND view_at < ?
- """, (start_timestamp, end_timestamp))
- watch_row = cursor.fetchone()
- total_watch_seconds = int(watch_row[0]) if watch_row and watch_row[0] is not None else 0
-
- # 计算总数并按类型分类
- total_count = 0
- type_counts = {}
-
- for business, count in results:
- total_count += count
- # 使用实际的business类型作为键,如果为空则使用'other'
- type_key = business if business else 'other'
- type_counts[type_key] = count
-
- return {
- "status": "success",
- "data": {
- "date": target_date.strftime("%Y-%m-%d"),
- "total_count": total_count,
- "type_counts": type_counts,
- "total_watch_seconds": total_watch_seconds
- }
- }
-
- except sqlite3.Error as e:
- return {"status": "error", "message": f"数据库错误: {str(e)}"}
- finally:
- if conn:
- conn.close()
\ No newline at end of file
diff --git a/routers/data_sync.py b/routers/data_sync.py
deleted file mode 100644
index a6616ad..0000000
--- a/routers/data_sync.py
+++ /dev/null
@@ -1,337 +0,0 @@
-import json
-import os
-import yaml
-from datetime import datetime
-from typing import Optional, List
-
-from fastapi import APIRouter, BackgroundTasks, Query, HTTPException
-from pydantic import BaseModel
-
-from scripts.check_data_integrity import check_data_integrity
-from scripts.sync_db_json import sync_data
-from scripts.utils import load_config, get_output_path
-
-router = APIRouter()
-
-class SyncedDayInfo(BaseModel):
- date: str
- imported_count: int
- source: str
- titles: List[str]
-
-class SyncDBJsonResponse(BaseModel):
- success: bool
- json_to_db_count: int
- db_to_json_count: int
- total_synced: int
- timestamp: str
- synced_days: Optional[List[SyncedDayInfo]] = None
- message: Optional[str] = None
-
-class CheckDataIntegrityResponse(BaseModel):
- success: bool
- total_json_files: int
- total_json_records: int
- total_db_records: int
- missing_records_count: int
- extra_records_count: int
- difference: int
- result_file: str
- report_file: str
- timestamp: str
-
-class IntegrityCheckConfigRequest(BaseModel):
- check_on_startup: bool
-
-class IntegrityCheckConfigResponse(BaseModel):
- success: bool
- message: str
- check_on_startup: bool
-
-def run_sync_data(db_path: Optional[str] = None, json_root_path: Optional[str] = None):
- """在后台运行数据同步任务"""
- # 确保输出目录存在
- os.makedirs("output/check", exist_ok=True)
-
- # 调用同步函数
- result = sync_data(db_path, json_root_path)
- return result
-
-def run_check_integrity(db_path: Optional[str] = None, json_root_path: Optional[str] = None):
- """在后台运行数据完整性检查任务"""
- # 确保输出目录存在
- os.makedirs("output/check", exist_ok=True)
-
- # 调用检查函数
- result = check_data_integrity(db_path, json_root_path)
- return result
-
-@router.post("/sync", response_model=SyncDBJsonResponse, summary="同步数据库和JSON文件")
-async def sync_db_json(
- background_tasks: BackgroundTasks,
- db_path: Optional[str] = Query(None, description="数据库文件路径,默认为 output/bilibili_history.db"),
- json_path: Optional[str] = Query(None, description="JSON文件根目录,默认为 output/history_by_date"),
- async_mode: bool = Query(False, description="是否异步执行(后台任务)")
-):
- """
- 同步数据库和JSON文件中的历史记录数据。
-
- - 将JSON文件中的新记录导入到数据库
- - 将数据库中的新记录导出到JSON文件
-
- 返回:
- - 导入和导出的记录数量
- - 按日期同步的详细信息,包括每天同步的记录数和记录标题
- """
- if async_mode:
- # 异步模式下,将任务放入后台执行
- background_tasks.add_task(run_sync_data, db_path, json_path)
- return {
- "success": True,
- "json_to_db_count": 0,
- "db_to_json_count": 0,
- "total_synced": 0,
- "timestamp": datetime.now().isoformat(),
- "message": "同步任务已在后台启动,请稍后查看日志获取结果"
- }
- else:
- # 同步模式下,直接执行并返回结果
- result = run_sync_data(db_path, json_path)
-
- # 如果result不包含synced_days字段,添加一个空列表
- if "synced_days" not in result:
- result["synced_days"] = []
-
- # 添加timestamp如果不存在
- if "timestamp" not in result:
- result["timestamp"] = datetime.now().isoformat()
-
- return result
-
-@router.post("/check", response_model=CheckDataIntegrityResponse, summary="检查数据完整性")
-async def check_integrity(
- background_tasks: BackgroundTasks,
- db_path: Optional[str] = Query(None, description="数据库文件路径,默认为 output/bilibili_history.db"),
- json_path: Optional[str] = Query(None, description="JSON文件根目录,默认为 output/history_by_date"),
- async_mode: bool = Query(False, description="是否异步执行(后台任务)"),
- force_check: bool = Query(False, description="是否强制执行检查,忽略配置设置")
-):
- """
- 检查数据库和JSON文件之间的数据完整性。
-
- - 检查JSON文件是否都被正确导入到数据库
- - 检查数据库中的记录是否都存在于JSON文件中
- - 生成详细的差异报告
-
- 返回检查结果和报告文件路径。
- """
- # 检查配置是否允许执行数据完整性校验
- if not force_check:
- config = load_config()
- check_enabled = config.get('server', {}).get('data_integrity', {}).get('check_on_startup', True)
- if not check_enabled:
- return {
- "success": True,
- "total_json_files": 0,
- "total_json_records": 0,
- "total_db_records": 0,
- "missing_records_count": 0,
- "extra_records_count": 0,
- "difference": 0,
- "result_file": "",
- "report_file": "",
- "timestamp": datetime.now().isoformat(),
- "message": "数据完整性校验已在配置中禁用,跳过检查。如需强制检查,请使用force_check=true参数。"
- }
-
- if async_mode:
- # 异步模式下,将任务放入后台执行
- background_tasks.add_task(run_check_integrity, db_path, json_path)
- return {
- "success": True,
- "total_json_files": 0,
- "total_json_records": 0,
- "total_db_records": 0,
- "missing_records_count": 0,
- "extra_records_count": 0,
- "difference": 0,
- "result_file": "output/check/data_integrity_results.json",
- "report_file": "output/check/data_integrity_report.md",
- "timestamp": datetime.now().isoformat(),
- "message": "数据完整性检查任务已在后台启动,请稍后查看报告文件获取结果"
- }
- else:
- # 同步模式下,直接执行并返回结果
- result = run_check_integrity(db_path, json_path)
- return {
- **result,
- "timestamp": datetime.now().isoformat()
- }
-
-@router.get("/report", summary="获取最新的数据完整性报告")
-async def get_report():
- """
- 获取最新的数据完整性检查报告的内容。
-
- 返回报告的内容和最后修改时间。
- """
- # 检查配置是否允许执行数据完整性校验
- config = load_config()
- check_enabled = config.get('server', {}).get('data_integrity', {}).get('check_on_startup', True)
-
- report_file = "output/check/data_integrity_report.md"
-
- if not os.path.exists(report_file):
- # 如果报告文件不存在,检查是否是因为配置禁用了校验
- if not check_enabled:
- return {
- "message": "数据完整性校验已在配置中禁用,无法获取报告。如需查看报告,请先执行数据完整性检查。"
- }
- else:
- raise HTTPException(status_code=404, detail="报告文件不存在,请先执行数据完整性检查")
-
- try:
- with open(report_file, "r", encoding="utf-8") as f:
- content = f.read()
-
- # 获取文件修改时间
- mod_time = os.path.getmtime(report_file)
- mod_time_str = datetime.fromtimestamp(mod_time).isoformat()
-
- return {
- "content": content,
- "modified_time": mod_time_str,
- "file_path": report_file
- }
- except Exception as e:
- raise HTTPException(status_code=500, detail=f"读取报告文件时出错: {str(e)}")
-
-@router.get("/sync/result", summary="获取最新的同步结果")
-async def get_sync_result():
- """
- 获取最新的数据同步结果。
-
- 返回同步的详细信息,包括每天同步的记录数量和记录标题。
- """
- result_file = "output/check/sync_result.json"
-
- if not os.path.exists(result_file):
- raise HTTPException(status_code=404, detail="同步结果文件不存在,请先执行数据同步")
-
- try:
- with open(result_file, "r", encoding="utf-8") as f:
- result = json.load(f)
-
- # 获取文件修改时间
- mod_time = os.path.getmtime(result_file)
- mod_time_str = datetime.fromtimestamp(mod_time).isoformat()
-
- # 添加文件修改时间
- result["file_modified_time"] = mod_time_str
-
- return result
- except Exception as e:
- raise HTTPException(status_code=500, detail=f"读取同步结果文件时出错: {str(e)}")
-
-@router.get("/config", summary="获取数据完整性校验配置")
-async def get_integrity_check_config():
- """
- 获取数据完整性校验配置。
-
- 返回当前的数据完整性校验配置,包括是否在启动时进行校验。
- """
- try:
- # 加载配置
- config = load_config()
-
- # 获取数据完整性校验配置
- check_on_startup = config.get('server', {}).get('data_integrity', {}).get('check_on_startup', True)
-
- return IntegrityCheckConfigResponse(
- success=True,
- message="获取配置成功",
- check_on_startup=check_on_startup
- )
- except Exception as e:
- raise HTTPException(status_code=500, detail=f"获取数据完整性校验配置时出错: {str(e)}")
-
-@router.post("/config", response_model=IntegrityCheckConfigResponse, summary="更新数据完整性校验配置")
-async def update_integrity_check_config(request: IntegrityCheckConfigRequest):
- """
- 更新数据完整性校验配置。
-
- - 设置是否在启动时进行数据完整性校验
-
- 返回更新后的配置。
- """
- try:
- # 获取配置文件路径
- config_path = os.path.join(os.path.dirname(os.path.dirname(os.path.abspath(__file__))), "config", "config.yaml")
-
- # 读取当前配置文件内容
- with open(config_path, 'r', encoding='utf-8') as f:
- content = f.read()
- config = yaml.safe_load(content) # 仅用于获取当前配置和检查结构
-
- # 确保server和data_integrity配置存在
- if 'server' not in config:
- config['server'] = {}
- if 'data_integrity' not in config['server']:
- config['server']['data_integrity'] = {}
-
- # 使用正则表达式精确更新配置值
- import re
-
- # 检查是否已存在data_integrity配置
- data_integrity_exists = False
- server_exists = False
- check_on_startup_exists = False
-
- lines = content.split('\n')
- for i, line in enumerate(lines):
- if re.match(r'^\s*server\s*:', line):
- server_exists = True
- elif server_exists and re.match(r'^\s{2}data_integrity\s*:', line):
- data_integrity_exists = True
- elif data_integrity_exists and re.match(r'^\s{4}check_on_startup\s*:', line):
- check_on_startup_exists = True
- # 更新check_on_startup的值
- indent = line[:line.find('check_on_startup')]
- lines[i] = f"{indent}check_on_startup: {str(request.check_on_startup).lower()}"
- break
-
- # 如果没有找到check_on_startup配置,需要添加
- if not check_on_startup_exists:
- if data_integrity_exists:
- # 找到data_integrity行,在其后添加check_on_startup
- for i, line in enumerate(lines):
- if re.match(r'^\s{2}data_integrity\s*:', line):
- lines.insert(i + 1, f" check_on_startup: {str(request.check_on_startup).lower()}")
- break
- elif server_exists:
- # 找到server行,在其后添加data_integrity和check_on_startup
- for i, line in enumerate(lines):
- if re.match(r'^\s*server\s*:', line):
- lines.insert(i + 1, f" data_integrity:")
- lines.insert(i + 2, f" check_on_startup: {str(request.check_on_startup).lower()}")
- break
- else:
- # 如果没有server配置,在文件末尾添加
- lines.append("server:")
- lines.append(" data_integrity:")
- lines.append(f" check_on_startup: {str(request.check_on_startup).lower()}")
-
- # 写回配置文件
- with open(config_path, 'w', encoding='utf-8') as f:
- f.write('\n'.join(lines))
-
- # 更新内存中的配置
- config['server']['data_integrity']['check_on_startup'] = request.check_on_startup
-
- return IntegrityCheckConfigResponse(
- success=True,
- message="配置已更新",
- check_on_startup=request.check_on_startup
- )
- except Exception as e:
- raise HTTPException(status_code=500, detail=f"更新数据完整性校验配置时出错: {str(e)}")
\ No newline at end of file
diff --git a/routers/delete_history.py b/routers/delete_history.py
deleted file mode 100644
index a78f0c6..0000000
--- a/routers/delete_history.py
+++ /dev/null
@@ -1,135 +0,0 @@
-import json
-import sqlite3
-from datetime import datetime
-from typing import List
-
-from fastapi import APIRouter, HTTPException
-from pydantic import BaseModel
-
-from scripts.utils import load_config, get_output_path
-
-router = APIRouter()
-config = load_config()
-
-class DeleteHistoryItem(BaseModel):
- bvid: str
- view_at: int # 观看时间戳
-
-def get_db():
- """获取数据库连接"""
- db_path = get_output_path(config['db_file'])
- return sqlite3.connect(db_path)
-
-def update_last_import_time(timestamp: int):
- """更新最后导入时间记录"""
- record = {
- "last_import_file": "",
- "last_import_time": timestamp,
- "last_import_date": datetime.fromtimestamp(timestamp).strftime("%Y-%m-%d")
- }
-
- record_file = get_output_path('last_import.json')
- with open(record_file, 'w', encoding='utf-8') as f:
- json.dump(record, f, ensure_ascii=False, indent=4)
-
-@router.delete("/batch-delete", summary="批量删除历史记录")
-async def batch_delete_history(items: List[DeleteHistoryItem]):
- """批量删除历史记录
-
- Args:
- items: 要删除的视频记录列表,每个记录包含BV号和观看时间戳
-
- Returns:
- dict: 删除操作的结果
- """
- if not items:
- raise HTTPException(status_code=400, detail="请提供要删除的视频记录列表")
-
- try:
- conn = get_db()
- cursor = conn.cursor()
-
- # 获取当前所有年份的表
- cursor.execute("""
- SELECT name FROM sqlite_master
- WHERE type='table' AND name LIKE 'bilibili_history_%'
- """)
- tables = [table[0] for table in cursor.fetchall()]
-
- total_deleted = 0
- deleted_details = []
- min_timestamp = float('inf') # 记录最早的删除时间
-
- # 确保删除记录表存在
- cursor.execute("""
- CREATE TABLE IF NOT EXISTS deleted_history (
- id INTEGER PRIMARY KEY,
- bvid TEXT NOT NULL,
- view_at INTEGER NOT NULL,
- delete_time INTEGER NOT NULL,
- UNIQUE(bvid, view_at)
- )
- """)
-
- # 获取当前时间戳作为删除时间
- current_time = int(datetime.now().timestamp())
-
- for item in items:
- # 从时间戳获取年份
- year = datetime.fromtimestamp(item.view_at).year
- table_name = f"bilibili_history_{year}"
-
- if table_name in tables:
- # 在对应年份的表中删除指定的记录
- query = f"""
- DELETE FROM {table_name}
- WHERE bvid = ? AND view_at = ?
- """
- cursor.execute(query, (item.bvid, item.view_at))
- if cursor.rowcount > 0:
- total_deleted += cursor.rowcount
- deleted_details.append({
- "bvid": item.bvid,
- "view_at": item.view_at,
- "view_time": datetime.fromtimestamp(item.view_at).strftime("%Y-%m-%d %H:%M:%S")
- })
- # 更新最早的删除时间
- min_timestamp = min(min_timestamp, item.view_at)
-
- # 将删除的记录添加到删除记录表中
- try:
- cursor.execute("""
- INSERT INTO deleted_history (bvid, view_at, delete_time)
- VALUES (?, ?, ?)
- """, (item.bvid, item.view_at, current_time))
- except sqlite3.IntegrityError:
- # 如果记录已存在,则更新删除时间
- cursor.execute("""
- UPDATE deleted_history
- SET delete_time = ?
- WHERE bvid = ? AND view_at = ?
- """, (current_time, item.bvid, item.view_at))
-
- conn.commit()
-
- # 如果有记录被删除,更新last_import.json
- if total_deleted > 0 and min_timestamp != float('inf'):
- update_last_import_time(min_timestamp - 1) # 减1秒以确保能获取到被删除时间点的记录
-
- return {
- "status": "success",
- "message": f"成功删除 {total_deleted} 条历史记录",
- "data": {
- "deleted_count": total_deleted,
- "deleted_records": deleted_details
- }
- }
-
- except sqlite3.Error as e:
- raise HTTPException(
- status_code=500,
- detail=f"数据库操作失败: {str(e)}"
- )
- finally:
- if 'conn' in locals() and conn:
- conn.close()
\ No newline at end of file
diff --git a/routers/download.py b/routers/download.py
deleted file mode 100644
index c48670b..0000000
--- a/routers/download.py
+++ /dev/null
@@ -1,1943 +0,0 @@
-import asyncio
-import os
-import re
-import subprocess
-import sys
-from datetime import datetime
-from typing import Optional, List, Dict, Any, Tuple
-
-import requests
-from fastapi import APIRouter, HTTPException, Query
-from fastapi.responses import StreamingResponse, FileResponse
-from pydantic import BaseModel, Field
-import httpx
-import json
-
-from scripts.utils import load_config
-from scripts.yutto_runner import run_yutto
-
-# 尝试导入 history 模块,用于处理图像 URL
-try:
- from routers.history import _process_image_url, get_video_by_cid, _process_record
-except ImportError:
- # 如果无法直接导入,则在运行时动态加载
- _process_image_url = None
- get_video_by_cid = None
- _process_record = None
- print("无法从 history 模块导入_process_image_url、get_video_by_cid 和_process_record 函数")
-
-router = APIRouter()
-config = load_config()
-
-
-
-# 辅助函数:检查下载目录和临时目录
-def check_download_directories() -> Tuple[str, str]:
- """
- 检查下载目录和临时目录是否存在且有写入权限
-
- Returns:
- 下载目录和临时目录的路径元组
-
- Raises:
- HTTPException: 如果目录不存在或没有写入权限
- """
- download_dir = os.path.normpath(config['yutto']['basic']['dir'])
- tmp_dir = os.path.normpath(config['yutto']['basic']['tmp_dir'])
-
- # 创建目录(如果不存在)
- os.makedirs(download_dir, exist_ok=True)
- os.makedirs(tmp_dir, exist_ok=True)
-
- # 检查目录权限
- if not os.access(download_dir, os.W_OK):
- raise HTTPException(
- status_code=500,
- detail=f"没有下载目录的写入权限:{download_dir}"
- )
- if not os.access(tmp_dir, os.W_OK):
- raise HTTPException(
- status_code=500,
- detail=f"没有临时目录的写入权限:{tmp_dir}"
- )
-
- return download_dir, tmp_dir
-
-# 辅助函数:准备进程参数
-def prepare_process_kwargs() -> Dict[str, Any]:
- """
- 准备进程参数
-
- Returns:
- 进程参数字典
- """
- # 设置环境变量
- env = os.environ.copy()
- env['PYTHONIOENCODING'] = 'utf-8'
- env['PYTHONUTF8'] = '1'
- env['PYTHONUNBUFFERED'] = '1' # 确保 Python 输出不被缓存
-
- # 在 Linux 上确保 PATH 包含 python 环境
- if sys.platform != 'win32':
- env['PATH'] = f"{os.path.dirname(sys.executable)}:{env.get('PATH', '')}"
- # 添加 virtualenv 的 site-packages 路径(如果存在)
- site_packages = os.path.join(os.path.dirname(os.path.dirname(sys.executable)), 'lib', 'python*/site-packages')
- env['PYTHONPATH'] = f"{site_packages}:{env.get('PYTHONPATH', '')}"
-
- # 准备进程参数
- popen_kwargs = {
- 'stdout': subprocess.PIPE,
- 'stderr': subprocess.PIPE,
- 'encoding': 'utf-8',
- 'errors': 'replace',
- 'universal_newlines': True,
- 'env': env,
- 'bufsize': 1, # 行缓冲
- 'shell': sys.platform != 'win32' # 在非 Windows 系统上使用 shell
- }
-
- # 在 Windows 系统上添加 CREATE_NO_WINDOW 标志
- if sys.platform == 'win32':
- popen_kwargs['creationflags'] = subprocess.CREATE_NO_WINDOW if hasattr(subprocess, 'CREATE_NO_WINDOW') else 0
- popen_kwargs['shell'] = False # Windows 上不使用 shell
-
- return popen_kwargs
-
-# 辅助函数:格式化命令
-def format_command(command: List[str]) -> str:
- """
- 格式化命令,处理特殊字符
-
- Args:
- command: 命令列表
-
- Returns:
- 格式化后的命令字符串
- """
- if sys.platform != 'win32':
- return ' '.join(f"'{arg}'" if ((' ' in arg) or ("'" in arg) or ('"' in arg)) else arg for arg in command)
- return ' '.join(command)
-
-# 辅助函数:添加下载参数到命令
-def add_download_params_to_command(command: List[str], params: Any) -> List[str]:
- """
- 将下载参数添加到命令中
-
- Args:
- command: 命令列表
- params: 包含下载参数的对象
-
- Returns:
- 添加了下载参数的命令列表
- """
- # 基础参数
- # 视频清晰度
- if params.video_quality is not None:
- command.extend(['--video-quality', str(params.video_quality)])
-
- # 音频码率
- if params.audio_quality is not None:
- command.extend(['--audio-quality', str(params.audio_quality)])
-
- # 视频编码
- if params.vcodec:
- command.extend(['--vcodec', params.vcodec])
-
- # 音频编码
- if params.acodec:
- command.extend(['--acodec', params.acodec])
-
- # 视频下载编码优先级
- if params.download_vcodec_priority:
- command.extend(['--download-vcodec-priority', params.download_vcodec_priority])
-
- # 输出格式
- if params.output_format:
- command.extend(['--output-format', params.output_format])
-
- # 仅包含音频流时的输出格式
- if params.output_format_audio_only:
- command.extend(['--output-format-audio-only', params.output_format_audio_only])
-
- # 资源选择参数
- # 仅下载视频流
- if params.video_only:
- command.append('--video-only')
-
- # 仅下载音频流
- if params.only_audio:
- command.append('--audio-only')
-
- # 不生成弹幕文件
- if params.no_danmaku:
- command.append('--no-danmaku')
-
- # 仅生成弹幕文件
- if params.danmaku_only:
- command.append('--danmaku-only')
-
- # 不生成字幕文件
- if params.no_subtitle or not config['yutto']['resource']['require_subtitle']:
- command.append('--no-subtitle')
-
- # 仅生成字幕文件
- if params.subtitle_only:
- command.append('--subtitle-only')
-
- # 仅生成媒体元数据文件
- if params.metadata_only:
- command.append('--metadata-only')
-
- # 不生成视频封面
- if not params.download_cover:
- command.append('--no-cover')
-
- # 生成视频流封面时单独保存封面
- if params.save_cover:
- command.append('--save-cover')
-
- # 仅生成视频封面
- if params.cover_only:
- command.append('--cover-only')
-
- # 不生成章节信息
- if params.no_chapter_info:
- command.append('--no-chapter-info')
-
- # 添加其他 yutto 配置
- if config['yutto']['danmaku']['font_size']:
- command.extend(['--danmaku-font-size', str(config['yutto']['danmaku']['font_size'])])
-
- if config['yutto']['batch']['with_section']:
- command.append('--with-section')
-
- # 如果提供了 SESSDATA,添加到命令中
- if hasattr(params, 'sessdata') and params.sessdata:
- command.extend(['--sessdata', params.sessdata])
- elif config.get('SESSDATA'):
- command.extend(['--sessdata', config['SESSDATA']])
-
- return command
-
-def extract_datetime_from_string(text):
- """
- 从字符串中提取日期时间
-
- 支持的格式:
- 1. YYYYMMDD_HHMMSS
- 2. YYYYMMDD_HHMM
- 3. YYYYMMDD
- 4. Unix 时间戳
-
- Args:
- text: 要检查的字符串
-
- Returns:
- 格式化的日期时间字符串或 None
- """
- # 调试信息
- print(f"【时间提取】尝试从'{text}'中提取日期时间")
-
- # 尝试匹配 YYYYMMDD_HHMMSS 格式
- match1 = re.match(r'.*?(\d{4})(\d{2})(\d{2})_(\d{2})(\d{2})(\d{2}).*', text)
- if match1:
- year, month, day, hour, minute, second = match1.groups()
- result = f"{year}-{month}-{day} {hour}:{minute}:{second}"
- print(f"【时间提取】匹配 YYYYMMDD_HHMMSS 格式:{result}")
- return result
-
- # 尝试匹配 YYYYMMDD_HHMM 格式
- match2 = re.match(r'.*?(\d{4})(\d{2})(\d{2})_(\d{2})(\d{2}).*', text)
- if match2:
- year, month, day, hour, minute = match2.groups()
- result = f"{year}-{month}-{day} {hour}:{minute}:00"
- print(f"【时间提取】匹配 YYYYMMDD_HHMM 格式:{result}")
- return result
-
- # 尝试匹配纯 YYYYMMDD 格式
- match3 = re.match(r'.*?(\d{4})(\d{2})(\d{2}).*', text)
- if match3:
- year, month, day = match3.groups()
- result = f"{year}-{month}-{day} 00:00:00"
- print(f"【时间提取】匹配 YYYYMMDD 格式:{result}")
- return result
-
- # 尝试匹配 Unix 时间戳(最后 10 位数字)
- match4 = re.match(r'^(\d{10})$', text)
- if match4:
- try:
- timestamp = int(match4.group(1))
- dt = datetime.fromtimestamp(timestamp)
- result = dt.strftime("%Y-%m-%d %H:%M:%S")
- print(f"【时间提取】匹配 Unix 时间戳:{result}")
- return result
- except:
- pass
-
- print(f"【时间提取】未能从'{text}'中提取日期时间")
- return None
-
-# 基础下载参数模型类
-class BaseDownloadParams(BaseModel):
- """所有下载请求的基础参数"""
- sessdata: Optional[str] = Field(None, description="用户的 SESSDATA")
- download_cover: Optional[bool] = Field(True, description="是否下载视频封面")
- only_audio: Optional[bool] = Field(False, description="是否仅下载音频")
-
- # 基础参数
- video_quality: Optional[int] = Field(None, description="视频清晰度等级,可选值:127|126|125|120|116|112|100|80|74|64|32|16")
- audio_quality: Optional[int] = Field(None, description="音频码率等级,可选值:30251|30255|30250|30280|30232|30216")
- vcodec: Optional[str] = Field(None, description="视频编码,格式为'下载编码:保存编码',如'avc:copy'")
- acodec: Optional[str] = Field(None, description="音频编码,格式为'下载编码:保存编码',如'mp4a:copy'")
- download_vcodec_priority: Optional[str] = Field(None, description="视频下载编码优先级,如'hevc,avc,av1'")
- output_format: Optional[str] = Field(None, description="输出格式,可选值:infer|mp4|mkv|mov")
- output_format_audio_only: Optional[str] = Field(None, description="仅包含音频流时的输出格式,可选值:infer|m4a|aac|mp3|flac|mp4|mkv|mov")
-
- # 资源选择参数
- video_only: Optional[bool] = Field(False, description="是否仅下载视频流")
- danmaku_only: Optional[bool] = Field(False, description="是否仅生成弹幕文件")
- no_danmaku: Optional[bool] = Field(False, description="是否不生成弹幕文件")
- subtitle_only: Optional[bool] = Field(False, description="是否仅生成字幕文件")
- no_subtitle: Optional[bool] = Field(False, description="是否不生成字幕文件")
- metadata_only: Optional[bool] = Field(False, description="是否仅生成媒体元数据文件")
- save_cover: Optional[bool] = Field(False, description="生成视频流封面时是否单独保存封面")
- cover_only: Optional[bool] = Field(False, description="是否仅生成视频封面")
- no_chapter_info: Optional[bool] = Field(False, description="是否不生成章节信息")
-
-class DownloadRequest(BaseDownloadParams):
- """单个视频下载请求"""
- url: str = Field(..., description="视频URL")
- cid: int = Field(..., description="视频的 CID,用于分类存储和音频文件命名前缀")
-
-class UserSpaceDownloadRequest(BaseDownloadParams):
- """用户空间视频下载请求"""
- user_id: str = Field(..., description="用户 UID,例如:100969474")
-
-class FavoriteDownloadRequest(BaseDownloadParams):
- """收藏夹下载请求"""
- user_id: str = Field(..., description="用户 UID,例如:100969474")
- fid: Optional[str] = Field(None, description="收藏夹 ID,不提供时下载所有收藏夹")
-
-class VideoInfo(BaseModel):
- """视频信息"""
- bvid: str = Field(..., description="视频的 BVID")
- cid: int = Field(..., description="视频的 CID")
- title: Optional[str] = Field(None, description="视频标题")
- author: Optional[str] = Field(None, description="视频作者")
- cover: Optional[str] = Field(None, description="视频封面URL")
-
-class BatchDownloadRequest(BaseDownloadParams):
- """批量下载请求"""
- videos: List[VideoInfo] = Field(..., description="要下载的视频列表")
-
-async def stream_process_output(process: subprocess.Popen):
- """实时流式输出进程的输出"""
- try:
- # 创建异步迭代器来读取输出
- async def read_output():
- while True:
- line = await asyncio.get_event_loop().run_in_executor(None, process.stdout.readline)
- if not line:
- break
- yield line.strip()
-
- # 实时读取并发送标准输出
- async for line in read_output():
- if line:
- yield f"data: {line}\n\n"
- # 立即刷新输出
- await asyncio.sleep(0)
-
- # 等待进程完成
- return_code = await asyncio.get_event_loop().run_in_executor(None, process.wait)
-
- # 读取可能的错误输出
- stderr_output = await asyncio.get_event_loop().run_in_executor(None, process.stderr.read)
- if stderr_output:
- # 将错误输出按行分割并发送
- for line in stderr_output.strip().split('\n'):
- yield f"data: ERROR: {line}\n\n"
- await asyncio.sleep(0)
-
- # 发送完成事件
- if return_code == 0:
- yield "data: 下载完成\n\n"
- else:
- # 如果有错误码,发送更详细的错误信息
- yield f"data: 下载失败,错误码:{return_code}\n\n"
- # 尝试获取更多错误信息
- try:
- if process.stderr:
- process.stderr.seek(0)
- full_error = process.stderr.read()
- if full_error:
- yield f"data: 完整错误信息:\n{full_error}\n\n"
- except Exception as e:
- yield f"data: 无法获取完整错误信息:{str(e)}\n\n"
-
- except Exception as e:
- yield f"data: 处理过程出错:{str(e)}\n\n"
- import traceback
- yield f"data: 错误堆栈:\n{traceback.format_exc()}\n\n"
- finally:
- # 确保进程已结束
- if process.poll() is None:
- process.terminate()
- await asyncio.get_event_loop().run_in_executor(None, process.wait)
- yield "event: close\ndata: close\n\n"
-
-@router.post("/download_video", summary="下载 B 站视频")
-async def download_video(request: DownloadRequest):
- """
- 下载 B 站视频
-
- Args:
- request: 包含视频 URL 和可选 SESSDATA 的请求对象
- """
- try:
- # 检查下载目录和临时目录
- download_dir, tmp_dir = check_download_directories()
-
- # 构建基本命令
- command = [
- request.url,
- '--dir', download_dir,
- '--tmp-dir', tmp_dir,
- '--subpath-template', f'{{title}}_{{username}}_{{download_date@%Y%m%d_%H%M%S}}_{request.cid}/{{title}}_{request.cid}',
- '--with-metadata' # 添加元数据文件保存
- ]
-
- # 添加下载参数
- command = add_download_params_to_command(command, request)
-
- print(f"执行下载命令:yutto {' '.join(command)}")
-
- async def event_stream():
- async for chunk in run_yutto(command):
- yield chunk
- yield "event: close\ndata: close\n\n"
-
- return StreamingResponse(event_stream(), media_type="text/event-stream")
- except FileNotFoundError:
- raise HTTPException(
- status_code=500,
- detail="找不到 yutto 命令,请确保已正确安装"
- )
- except Exception as e:
- raise HTTPException(
- status_code=500,
- detail=f"下载过程出错:{str(e)}"
- )
-
-@router.get("/check_ffmpeg", summary="检查 FFmpeg 版本")
-async def check_ffmpeg():
- """
- 检查 FFmpeg 是否安装及其版本信息
-
- Returns:
- 如果安装了 FFmpeg,返回版本信息
- 如果未安装,返回简单的未安装信息
- """
- try:
- # 获取系统信息
- import platform
- system = platform.system().lower()
- release = platform.release()
- os_info = {
- "system": system,
- "release": release,
- "platform": platform.platform()
- }
-
- # 根据不同系统使用不同的命令检查 FFmpeg
- if system == 'windows':
- ffmpeg_check_cmd = 'where ffmpeg'
- else:
- ffmpeg_check_cmd = 'which ffmpeg'
-
- # 检查 FFmpeg 是否安装
- ffmpeg_process = subprocess.run(
- ffmpeg_check_cmd.split(),
- capture_output=True,
- text=True
- )
-
- if ffmpeg_process.returncode == 0:
- # FFmpeg 已安装,获取版本信息
- version_process = subprocess.run(['ffmpeg', '-version'], capture_output=True, text=True)
- if version_process.returncode == 0:
- version_info = version_process.stdout.splitlines()[0]
- return {
- "status": "success",
- "installed": True,
- "version": version_info,
- "path": ffmpeg_process.stdout.strip(),
- "os_info": os_info
- }
-
- # FFmpeg 未安装,返回简单的未安装信息
- return {
- "status": "error",
- "installed": False,
- "message": "FFmpeg 未安装",
- "os_info": os_info
- }
-
- except Exception as e:
- return {
- "status": "error",
- "installed": False,
- "message": f"检查 FFmpeg 失败:{str(e)}",
- "error": str(e),
- "os_info": os_info if 'os_info' in locals() else {
- "system": platform.system().lower(),
- "release": platform.release(),
- "platform": platform.platform()
- }
- }
-
-@router.get("/check_video_download", summary="检查视频是否已下载")
-async def check_video_download(cids: str):
- """
- 检查指定 CID 的视频是否已下载,如果已下载则返回保存路径
- 支持批量检查多个 CID,使用逗号分隔
-
- Args:
- cids: 视频的 CID,多个 CID 用逗号分隔,如"12345,67890"
-
- Returns:
- dict: 包含检查结果和视频保存信息的字典
- """
- try:
- # 解析 CID 列表
- cid_list = [int(cid.strip()) for cid in cids.split(",") if cid.strip()]
-
- if not cid_list:
- return {
- "status": "error",
- "message": "未提供有效的 CID"
- }
-
- # 获取下载目录路径
- download_dir = os.path.normpath(config['yutto']['basic']['dir'])
-
- # 确保下载目录存在
- if not os.path.exists(download_dir):
- return {
- "status": "success",
- "results": {cid: {"downloaded": False, "message": "下载目录不存在,视频尚未下载"} for cid in cid_list}
- }
-
- # 存储每个 CID 的检查结果
- result_dict = {}
-
- # 递归遍历下载目录查找匹配的视频文件
- for cid in cid_list:
- found_files = []
- found_directory = None
- download_time = None
-
- for root, dirs, files in os.walk(download_dir):
- # 检查目录名是否包含 CID
- dir_name = os.path.basename(root)
- if f"_{cid}" in dir_name:
- found_directory = root
-
- # 从目录名中提取下载时间
- try:
- # 首先尝试从目录名中直接提取
- download_time = extract_datetime_from_string(dir_name)
-
- # 如果没找到,尝试从目录名的各个部分提取
- if not download_time:
- dir_parts = dir_name.split('_')
- for part in dir_parts:
- extracted_time = extract_datetime_from_string(part)
- if extracted_time:
- download_time = extracted_time
- break
-
- # 如果仍然没找到,尝试使用文件的创建时间
- if not download_time and files: # 确保有文件存在
- # 使用第一个文件的创建时间
- first_file_path = os.path.join(root, files[0])
- if os.path.exists(first_file_path):
- creation_time = os.path.getctime(first_file_path)
- download_time = datetime.fromtimestamp(creation_time).strftime("%Y-%m-%d %H:%M:%S")
- print(f"【调试】使用文件创建时间作为下载时间:{download_time}")
-
- # 额外记录调试信息
- if not download_time:
- print(f"【调试】无法从目录名提取日期时间:{dir_name}")
- print(f"【调试】目录名各部分:{dir_name.split('_')}")
- except Exception as e:
- print(f"提取下载时间出错:{str(e)}")
-
- # 检查目录中的文件
- for file in files:
- # 检查文件名是否包含 CID
- if f"_{cid}" in file:
- # 检查是否为视频或音频文件
- if file.endswith(('.mp4', '.flv', '.m4a', '.mp3')):
- file_path = os.path.join(root, file)
- file_size = os.path.getsize(file_path)
- file_size_mb = round(file_size / (1024 * 1024), 2)
-
- found_files.append({
- "file_name": file,
- "file_path": file_path,
- "size_bytes": file_size,
- "size_mb": file_size_mb,
- "created_time": os.path.getctime(file_path),
- "modified_time": os.path.getmtime(file_path)
- })
-
- if found_files:
- result_dict[cid] = {
- "downloaded": True,
- "message": f"已找到{len(found_files)}个匹配的视频文件",
- "files": found_files,
- "directory": found_directory,
- "download_time": download_time
- }
- else:
- result_dict[cid] = {
- "downloaded": False,
- "message": "未找到已下载的视频文件"
- }
-
- return {
- "status": "success",
- "results": result_dict
- }
-
- except Exception as e:
- return {
- "status": "error",
- "message": f"检查视频下载状态时出错:{str(e)}"
- }
-
-@router.get("/list_downloaded_videos", summary="获取或搜索已下载视频列表")
-async def list_downloaded_videos(search_term: Optional[str] = None, limit: int = 100, page: int = 1, use_local_images: bool = False):
- """
- 获取已下载的视频列表,支持通过标题搜索
-
- Args:
- search_term: 可选,搜索关键词,会在文件名和目录名中查找
- limit: 每页返回的结果数量,默认 100
- page: 页码,从 1 开始,默认为第 1 页
- use_local_images: 是否使用本地图片,默认为 false
-
- Returns:
- dict: 包含已下载视频列表的字典
- """
- try:
- # 获取下载目录路径
- download_dir = os.path.normpath(config['yutto']['basic']['dir'])
-
- # 确保下载目录存在
- if not os.path.exists(download_dir):
- return {
- "status": "success",
- "message": "下载目录不存在,尚未下载任何视频",
- "videos": [],
- "total": 0,
- "page": page,
- "limit": limit,
- "pages": 0
- }
-
- # 获取数据库连接
- try:
- import sqlite3
- db_path = os.path.join('output', 'bilibili_history.db')
- conn = sqlite3.connect(db_path)
- conn.row_factory = sqlite3.Row # 将结果转换为字典形式
- db_available = True
- except Exception as e:
- print(f"无法连接到数据库:{str(e)}")
- db_available = False
- conn = None
-
- # 递归遍历下载目录查找视频文件
- videos = []
-
- for root, dirs, files in os.walk(download_dir):
- # 过滤仅包含视频文件的目录
- video_files = []
- dir_name = os.path.basename(root)
-
- # 如果指定了搜索关键词,检查目录名
- if search_term and search_term.lower() not in dir_name.lower():
- # 跳过不匹配的目录,除非发现其中的文件名匹配
- file_match = False
- for file in files:
- if search_term.lower() in file.lower() and file.endswith(('.mp4', '.flv', '.m4a', '.mp3')):
- file_match = True
- break
-
- if not file_match:
- continue
-
- # 检查是否存在元数据文件
- metadata_file = os.path.join(root, "metadata.json")
- metadata = None
- if os.path.exists(metadata_file):
- try:
- with open(metadata_file, 'r', encoding='utf-8') as f:
- import json
- metadata = json.load(f)
- print(f"【调试】从元数据文件获取数据:{metadata_file}")
-
- # 显示元数据文件内容摘要
- if 'title' in metadata:
- print(f"【调试】元数据标题:{metadata['title']}")
- if 'id' in metadata:
- if 'bvid' in metadata['id']:
- print(f"【调试】元数据 BVID: {metadata['id']['bvid']}")
- if 'cid' in metadata['id']:
- print(f"【调试】元数据 CID: {metadata['id']['cid']}")
- if 'owner' in metadata and 'name' in metadata['owner']:
- print(f"【调试】元数据作者:{metadata['owner']['name']}")
- if 'cover_url' in metadata:
- print(f"【调试】元数据封面:{metadata['cover_url']}")
-
- except Exception as e:
- print(f"读取元数据文件出错:{str(e)}")
-
- # 尝试查找.nfo 文件
- nfo_files = [f for f in files if f.endswith('.nfo')]
- nfo_data = None
- if nfo_files:
- try:
- import xml.etree.ElementTree as ET
- nfo_file = os.path.join(root, nfo_files[0])
- tree = ET.parse(nfo_file)
- nfo_data = tree.getroot()
- print(f"【调试】从 NFO 文件获取数据:{nfo_file}")
- except Exception as e:
- print(f"读取 NFO 文件出错:{str(e)}")
-
- for file in files:
- # 检查是否为视频或音频文件
- if file.endswith(('.mp4', '.flv', '.m4a', '.mp3')):
- # 如果指定了搜索关键词,检查文件名
- if search_term and search_term.lower() not in file.lower() and search_term.lower() not in dir_name.lower():
- continue
-
- file_path = os.path.join(root, file)
- file_size = os.path.getsize(file_path)
- file_size_mb = round(file_size / (1024 * 1024), 2)
-
- # 从目录名和文件名中提取信息
- dir_parts = dir_name.split('_')
- file_parts = file.split('_')
-
- # 尝试提取 CID
- cid = None
- try:
- if len(dir_parts) > 3:
- cid = dir_parts[-1] # 最后一部分应该是 CID
- elif len(file_parts) > 1:
- cid = file_parts[-1].split('.')[0] # 文件名最后一部分的。前部分
- except:
- pass
-
- # 尝试从目录名提取标题
- title = None
- try:
- if len(dir_parts) > 0:
- # 除去最后 3 个部分(用户名_日期_CID),剩下的应该是标题
- title = '_'.join(dir_parts[:-3]) if len(dir_parts) > 3 else dir_name
- except:
- title = dir_name
-
- # 尝试提取日期时间
- date_time = None
- try:
- print(f"【调试】处理目录:{dir_name}")
-
- # 首先尝试从完整目录名中直接提取
- date_time = extract_datetime_from_string(dir_name)
-
- # 如果没找到,尝试从目录名的各个部分提取
- if not date_time:
- dir_parts = dir_name.split('_')
- print(f"【调试】目录名各部分:{dir_parts}")
- for part in dir_parts:
- print(f"【调试】检查部分:{part}")
- extracted_time = extract_datetime_from_string(part)
- if extracted_time:
- date_time = extracted_time
- print(f"【调试】从部分'{part}'提取到时间:{date_time}")
- break
-
- # 如果仍然没找到,尝试使用文件的创建时间
- if not date_time:
- # 使用即将添加到 video_files 的文件创建时间
- creation_time = os.path.getctime(file_path)
- date_time = datetime.fromtimestamp(creation_time).strftime("%Y-%m-%d %H:%M:%S")
- print(f"【调试】使用文件创建时间作为下载时间:{date_time}")
-
- # 额外记录调试信息
- print(f"【调试】无法从目录名提取日期时间:{dir_name}")
- except Exception as e:
- print(f"提取下载时间出错:{str(e)}")
-
- video_files.append({
- "file_name": file,
- "file_path": file_path,
- "size_bytes": file_size,
- "size_mb": file_size_mb,
- "created_time": os.path.getctime(file_path),
- "modified_time": os.path.getmtime(file_path),
- "is_audio_only": file.endswith(('.m4a', '.mp3'))
- })
-
- if video_files:
- video_info = {
- "directory": root,
- "dir_name": dir_name,
- "title": title,
- "cid": cid,
- "bvid": None, # 初始化 bvid 字段为 None
- "download_date": date_time,
- "files": video_files,
- "cover": None,
- "author_face": None,
- "author_name": None,
- "author_mid": None
- }
-
- # 如果存在元数据,优先使用元数据中的信息
- if metadata:
- try:
- # 提取 bvid 和 cid
- if 'id' in metadata:
- video_id = metadata['id']
- if 'bvid' in video_id:
- video_info["bvid"] = video_id['bvid']
- if 'cid' in video_id and not video_info["cid"]:
- video_info["cid"] = str(video_id['cid'])
-
- # 提取标题
- if 'title' in metadata and metadata['title']:
- video_info["title"] = metadata['title']
-
- # 提取封面 URL
- if 'cover_url' in metadata and metadata['cover_url']:
- video_info["cover"] = metadata['cover_url']
-
- # 提取作者信息
- if 'owner' in metadata:
- owner = metadata['owner']
- if 'name' in owner:
- video_info["author_name"] = owner['name']
- if 'face' in owner:
- video_info["author_face"] = owner['face']
- if 'mid' in owner:
- video_info["author_mid"] = owner['mid']
-
- # 处理图片 URL
- if _process_image_url:
- # 使用导入的函数处理图片 URL
- if video_info["cover"]:
- video_info["cover"] = _process_image_url(video_info["cover"], 'covers', use_local_images)
- if video_info["author_face"]:
- video_info["author_face"] = _process_image_url(video_info["author_face"], 'avatars', use_local_images)
- elif hasattr(sys.modules.get('routers.history'), '_process_image_url'):
- # 如果导入失败但模块运行时可访问,再次尝试
- process_url = getattr(sys.modules.get('routers.history'), '_process_image_url')
- if video_info["cover"]:
- video_info["cover"] = process_url(video_info["cover"], 'covers', use_local_images)
- if video_info["author_face"]:
- video_info["author_face"] = process_url(video_info["author_face"], 'avatars', use_local_images)
- elif use_local_images:
- # 简单的 URL 处理逻辑,作为后备方案
- import hashlib
- if video_info["cover"]:
- cover_hash = hashlib.md5(video_info["cover"].encode()).hexdigest()
- video_info["cover"] = f"/images/local/covers/{cover_hash}"
- if video_info["author_face"]:
- avatar_hash = hashlib.md5(video_info["author_face"].encode()).hexdigest()
- video_info["author_face"] = f"/images/local/avatars/{avatar_hash}"
-
- print(f"【调试】从元数据获取到视频信息:{video_info['title']},封面 URL: {video_info['cover'][:50]}...")
- except Exception as e:
- print(f"解析元数据时出错:{str(e)}")
-
- # 如果有 NFO 数据且信息不完整,尝试从 NFO 提取
- if nfo_data and (not video_info["cover"] or not video_info["author_name"] or not video_info["author_face"]):
- try:
- # 提取标题
- title_elem = nfo_data.find('title')
- if title_elem is not None and title_elem.text and not video_info["title"]:
- video_info["title"] = title_elem.text
-
- # 提取封面 URL
- thumb_elem = nfo_data.find('thumb')
- if thumb_elem is not None and thumb_elem.text and not video_info["cover"]:
- video_info["cover"] = thumb_elem.text
-
- # 提取作者信息
- actor_elem = nfo_data.find('actor')
- if actor_elem is not None:
- # 作者名
- actor_name = actor_elem.find('name')
- if actor_name is not None and actor_name.text and not video_info["author_name"]:
- video_info["author_name"] = actor_name.text
-
- # 作者头像
- actor_thumb = actor_elem.find('thumb')
- if actor_thumb is not None and actor_thumb.text and not video_info["author_face"]:
- video_info["author_face"] = actor_thumb.text
-
- # 作者 ID/主页
- actor_profile = actor_elem.find('profile')
- if actor_profile is not None and actor_profile.text and not video_info["author_mid"]:
- profile_url = actor_profile.text
- # 尝试从 URL 中提取 mid
- mid_match = re.search(r"space\.bilibili\.com/(\d+)", profile_url)
- if mid_match:
- video_info["author_mid"] = int(mid_match.group(1))
-
- # 提取 BV 号
- website_elem = nfo_data.find('website')
- if website_elem is not None and website_elem.text and not video_info["bvid"]:
- bvid_match = re.search(r"video/(BV\w+)", website_elem.text)
- if bvid_match:
- video_info["bvid"] = bvid_match.group(1)
-
- # 处理 NFO 文件中的图片 URL
- if _process_image_url:
- # 使用导入的函数处理图片 URL
- if video_info["cover"]:
- video_info["cover"] = _process_image_url(video_info["cover"], 'covers', use_local_images)
- if video_info["author_face"]:
- video_info["author_face"] = _process_image_url(video_info["author_face"], 'avatars', use_local_images)
- elif hasattr(sys.modules.get('routers.history'), '_process_image_url'):
- # 如果导入失败但模块运行时可访问,再次尝试
- process_url = getattr(sys.modules.get('routers.history'), '_process_image_url')
- if video_info["cover"]:
- video_info["cover"] = process_url(video_info["cover"], 'covers', use_local_images)
- if video_info["author_face"]:
- video_info["author_face"] = process_url(video_info["author_face"], 'avatars', use_local_images)
- elif use_local_images:
- # 简单的 URL 处理逻辑,作为后备方案
- import hashlib
- if video_info["cover"]:
- cover_hash = hashlib.md5(video_info["cover"].encode()).hexdigest()
- video_info["cover"] = f"/images/local/covers/{cover_hash}"
- if video_info["author_face"]:
- avatar_hash = hashlib.md5(video_info["author_face"].encode()).hexdigest()
- video_info["author_face"] = f"/images/local/avatars/{avatar_hash}"
-
- print(f"【调试】从 NFO 文件获取到视频信息:{video_info['title']},封面 URL: {video_info['cover'][:50] if video_info['cover'] else 'None'}")
- except Exception as e:
- print(f"解析 NFO 文件时出错:{str(e)}")
-
- # 如果有 CID 但没有其他信息,尝试通过 API 获取
- if not metadata and not nfo_data and cid and cid.isdigit() and (not video_info["cover"] or not video_info["author_name"] or not video_info["author_face"]):
- try:
- # 仅当没有元数据和 NFO 文件时,才尝试通过 API 或数据库获取
- print(f"【调试】没有找到元数据或 NFO 文件,尝试通过 API/数据库获取 CID={cid}的视频信息")
-
- # 方式 1: 直接调用 get_video_by_cid 函数(如果已成功导入)
- if get_video_by_cid:
- print(f"【调试】使用导入的 get_video_by_cid 函数获取 CID={cid}的视频信息")
- # 调用 API 函数获取视频信息
- api_response = await get_video_by_cid(int(cid), use_local_images)
-
- if api_response["status"] == "success" and "data" in api_response:
- video_data = api_response["data"]
- video_info["title"] = video_data.get("title") or video_info["title"]
- video_info["cover"] = video_data.get("cover")
- video_info["author_face"] = video_data.get("author_face")
- video_info["author_name"] = video_data.get("author_name")
- video_info["author_mid"] = video_data.get("author_mid")
- video_info["bvid"] = video_data.get("bvid") # 添加 bvid 字段
- print(f"【调试】成功通过 API 获取到视频信息:{video_data.get('title')}")
- # 方式 2: 如果 API 函数未导入,则回退到直接查询数据库
- elif db_available:
- print(f"【调试】回退到直接查询数据库获取 CID={cid}的视频信息")
- cursor = conn.cursor()
- # 查询所有历史记录表
- years = [table_name.split('_')[-1]
- for (table_name,) in cursor.execute(
- "SELECT name FROM sqlite_master WHERE type='table' AND name LIKE 'bilibili_history_%'"
- ).fetchall()
- if table_name.split('_')[-1].isdigit()]
-
- # 构建 UNION ALL 查询所有年份表
- if years:
- queries = []
- for year in years:
- queries.append(f"SELECT title, cover, author_face, author_name, author_mid, bvid FROM bilibili_history_{year} WHERE cid = {cid} LIMIT 1")
-
- # 执行联合查询
- union_query = " UNION ALL ".join(queries) + " LIMIT 1"
- result = cursor.execute(union_query).fetchone()
-
- if result:
- # 设置封面和作者信息
- video_info["title"] = result["title"] or video_info["title"]
- video_info["cover"] = result["cover"]
- video_info["author_face"] = result["author_face"]
- video_info["author_name"] = result["author_name"]
- video_info["author_mid"] = result["author_mid"]
- video_info["bvid"] = result["bvid"] # 添加 bvid 字段
-
- # 处理图片 URL
- if _process_image_url:
- # 使用导入的函数处理图片 URL
- if video_info["cover"]:
- video_info["cover"] = _process_image_url(video_info["cover"], 'covers', use_local_images)
- if video_info["author_face"]:
- video_info["author_face"] = _process_image_url(video_info["author_face"], 'avatars', use_local_images)
- elif hasattr(sys.modules.get('routers.history'), '_process_image_url'):
- # 如果导入失败但模块运行时可访问,再次尝试
- process_url = getattr(sys.modules.get('routers.history'), '_process_image_url')
- if video_info["cover"]:
- video_info["cover"] = process_url(video_info["cover"], 'covers', use_local_images)
- if video_info["author_face"]:
- video_info["author_face"] = process_url(video_info["author_face"], 'avatars', use_local_images)
- else:
- # 简单的 URL 处理逻辑,作为后备方案
- if use_local_images:
- import hashlib
- if video_info["cover"]:
- cover_hash = hashlib.md5(video_info["cover"].encode()).hexdigest()
- video_info["cover"] = f"/images/local/covers/{cover_hash}"
- if video_info["author_face"]:
- avatar_hash = hashlib.md5(video_info["author_face"].encode()).hexdigest()
- video_info["author_face"] = f"/images/local/avatars/{avatar_hash}"
- except Exception as e:
- print(f"获取视频信息时出错:{str(e)}")
-
- # 检查是否为合集或多P视频
- is_collection = False
- collection_type = "single" # single, multipart, collection
- collection_info = None
-
- if len(video_files) > 1:
- # 检查是否为同一个视频的多个文件(不同格式/质量)
- unique_titles = set()
- unique_bvids = set()
- for file_info in video_files:
- # 从文件名中提取标题部分(去掉CID和扩展名)
- file_name = file_info["file_name"]
- # 移除文件扩展名
- name_without_ext = os.path.splitext(file_name)[0]
- # 尝试移除CID部分(假设CID在文件名末尾)
- if f"_{cid}" in name_without_ext:
- title_part = name_without_ext.replace(f"_{cid}", "")
- else:
- title_part = name_without_ext
- unique_titles.add(title_part)
-
- # 尝试从文件名或目录名中提取BVID
- bv_match = re.search(r'BV[a-zA-Z0-9]+', file_name)
- if not bv_match:
- bv_match = re.search(r'BV[a-zA-Z0-9]+', dir_name)
- if bv_match:
- unique_bvids.add(bv_match.group())
-
- if len(unique_titles) > 1 or len(unique_bvids) > 1:
- is_collection = True
- collection_type = "collection" # 真正的合集
-
- # 尝试从目录名中提取合集信息
- if "_collection" in dir_name:
- collection_title = dir_name.split("_collection")[0]
- elif "_multipart" in dir_name:
- collection_title = dir_name.split("_multipart")[0]
- collection_type = "multipart"
- else:
- collection_title = dir_name
-
- collection_info = {
- "type": collection_type,
- "title": collection_title,
- "total_videos": len(unique_titles) if len(unique_titles) > 1 else len(unique_bvids),
- "video_list": []
- }
-
- # 构建合集中的视频列表
- for file_info in video_files:
- file_name = file_info["file_name"]
- name_without_ext = os.path.splitext(file_name)[0]
-
- # 提取视频标题
- if f"_{cid}" in name_without_ext:
- video_title = name_without_ext.replace(f"_{cid}", "")
- else:
- video_title = name_without_ext
-
- # 提取BVID
- bv_match = re.search(r'BV[a-zA-Z0-9]+', file_name)
- if not bv_match:
- bv_match = re.search(r'BV[a-zA-Z0-9]+', dir_name)
- video_bvid = bv_match.group() if bv_match else ""
-
- # 尝试为每个子视频获取独立的封面信息
- video_cover = None
- video_author_face = None
- video_author_name = None
- video_author_mid = None
-
- # 查找对应的.nfo文件
- nfo_file_path = os.path.join(root, f"{name_without_ext}.nfo")
- if os.path.exists(nfo_file_path):
- try:
- import xml.etree.ElementTree as ET
- tree = ET.parse(nfo_file_path)
- nfo_root = tree.getroot()
-
- # 提取封面
- thumb_elem = nfo_root.find('thumb')
- if thumb_elem is not None and thumb_elem.text:
- video_cover = thumb_elem.text
-
- # 提取作者信息
- actor_elem = nfo_root.find('actor')
- if actor_elem is not None:
- actor_name = actor_elem.find('name')
- if actor_name is not None and actor_name.text:
- video_author_name = actor_name.text
-
- actor_thumb = actor_elem.find('thumb')
- if actor_thumb is not None and actor_thumb.text:
- video_author_face = actor_thumb.text
-
- actor_profile = actor_elem.find('profile')
- if actor_profile is not None and actor_profile.text:
- profile_url = actor_profile.text
- mid_match = re.search(r"space\.bilibili\.com/(\d+)", profile_url)
- if mid_match:
- video_author_mid = int(mid_match.group(1))
-
- # 处理图片URL
- if _process_image_url:
- if video_cover:
- video_cover = _process_image_url(video_cover, 'covers', use_local_images)
- if video_author_face:
- video_author_face = _process_image_url(video_author_face, 'avatars', use_local_images)
- elif use_local_images:
- import hashlib
- if video_cover:
- cover_hash = hashlib.md5(video_cover.encode()).hexdigest()
- video_cover = f"/images/local/covers/{cover_hash}"
- if video_author_face:
- avatar_hash = hashlib.md5(video_author_face.encode()).hexdigest()
- video_author_face = f"/images/local/avatars/{avatar_hash}"
-
- except Exception as e:
- print(f"解析子视频NFO文件时出错:{str(e)}")
-
- collection_info["video_list"].append({
- "title": video_title,
- "bvid": video_bvid,
- "file_info": file_info,
- "cover": video_cover,
- "author_face": video_author_face,
- "author_name": video_author_name,
- "author_mid": video_author_mid
- })
- else:
- collection_type = "multipart" # 多P或不同格式的同一视频
-
- # 添加合集信息到video_info
- video_info["is_collection"] = is_collection
- video_info["collection_type"] = collection_type
- video_info["collection_info"] = collection_info
-
- videos.append(video_info)
-
- # 如果数据库连接已打开,关闭它
- if conn:
- conn.close()
-
- # 计算分页
- total_videos = len(videos)
- total_pages = (total_videos + limit - 1) // limit if total_videos > 0 else 0
-
- # 根据修改时间排序,最新的在前面
- videos.sort(key=lambda x: max([f["modified_time"] for f in x["files"]]) if x["files"] else 0, reverse=True)
-
- # 分页
- start_idx = (page - 1) * limit
- end_idx = min(start_idx + limit, total_videos)
- paginated_videos = videos[start_idx:end_idx] if start_idx < total_videos else []
-
- return {
- "status": "success",
- "message": f"找到{total_videos}个视频" + (f",匹配'{search_term}'" if search_term else ""),
- "videos": paginated_videos,
- "total": total_videos,
- "page": page,
- "limit": limit,
- "pages": total_pages
- }
-
- except Exception as e:
- return {
- "status": "error",
- "message": f"获取已下载视频列表时出错:{str(e)}"
- }
-
-@router.get("/stream_video", summary="获取已下载视频的流媒体数据")
-async def stream_video(file_path: str):
- """
- 返回已下载视频的流媒体数据,用于在线播放
-
- Args:
- file_path: 视频文件的完整路径
-
- Returns:
- StreamingResponse: 视频流响应
- """
- try:
- # 检查文件是否存在
- if not os.path.exists(file_path):
- raise HTTPException(
- status_code=404,
- detail=f"文件不存在:{file_path}"
- )
-
- # 检查是否是支持的媒体文件
- if not file_path.endswith(('.mp4', '.flv', '.m4a', '.mp3')):
- raise HTTPException(
- status_code=400,
- detail="不支持的媒体文件格式,仅支持 mp4、flv、m4a、mp3 格式"
- )
-
- # 获取文件大小
- file_size = os.path.getsize(file_path)
-
- # 获取文件名
- file_name = os.path.basename(file_path)
-
- # 设置适当的媒体类型
- if file_path.endswith('.mp4'):
- media_type = 'video/mp4'
- elif file_path.endswith('.flv'):
- media_type = 'video/x-flv'
- elif file_path.endswith('.m4a'):
- media_type = 'audio/mp4'
- elif file_path.endswith('.mp3'):
- media_type = 'audio/mpeg'
- else:
- media_type = 'application/octet-stream'
-
- # 返回文件响应
- return FileResponse(
- file_path,
- media_type=media_type,
- filename=file_name
- )
-
- except HTTPException:
- raise
- except Exception as e:
- raise HTTPException(
- status_code=500,
- detail=f"获取视频流时出错:{str(e)}"
- )
-
-@router.delete("/delete_downloaded_video", summary="删除已下载的视频")
-async def delete_downloaded_video(
- delete_directory: bool = False,
- directory: Optional[str] = None,
- cid: Optional[int] = Query(None, description="视频的 CID,可选项")
-):
- """
- 删除已下载的视频文件
-
- Args:
- delete_directory: 是否删除整个目录,默认为 False(只删除视频文件)
- directory: 可选,指定要删除文件的目录路径,如果提供则只在该目录中查找和删除文件
- cid: 可选,视频的 CID
-
- Returns:
- dict: 包含删除结果信息的字典
- """
- try:
- # 获取下载目录路径
- download_dir = os.path.normpath(config['yutto']['basic']['dir'])
-
- # 确保下载目录存在
- if not os.path.exists(download_dir):
- return {
- "status": "error",
- "message": "下载目录不存在"
- }
-
- # 检查参数有效性
- if not cid and not directory:
- return {
- "status": "error",
- "message": "必须提供 cid 或 directory 参数中的至少一个"
- }
-
- # 查找匹配 CID 的视频文件和目录
- found_files = []
- found_directory = directory # 如果提供了目录,则使用它
-
- # 如果提供了 directory 参数,并且它确实存在,只在该目录中查找文件
- if directory and os.path.exists(directory):
- # 根据 directory 直接处理
- if delete_directory:
- # 删除整个目录
- import shutil
- try:
- shutil.rmtree(directory)
- return {
- "status": "success",
- "message": f"已删除目录:{directory}",
- "deleted_directory": directory
- }
- except Exception as e:
- return {
- "status": "error",
- "message": f"删除目录时出错:{str(e)}",
- "directory": directory
- }
- else:
- # 查找目录中的视频文件并删除
- for file in os.listdir(directory):
- # 仅查找视频或音频文件
- if file.endswith(('.mp4', '.flv', '.m4a', '.mp3')):
- file_path = os.path.join(directory, file)
- if cid is None or f"_{cid}" in file: # 如果指定了 CID 则检查文件名是否包含它
- found_files.append({
- "file_name": file,
- "file_path": file_path
- })
- elif cid is not None:
- # 如果没有提供 directory 参数但提供了 cid,执行原来的逻辑
- for root, dirs, files in os.walk(download_dir):
- # 检查目录名是否包含 CID
- if f"_{cid}" in os.path.basename(root):
- # 如果没有指定目录,保存找到的第一个匹配目录
- if not found_directory:
- found_directory = root
-
- # 检查目录中的文件
- for file in files:
- # 检查文件名是否包含 CID
- if f"_{cid}" in file:
- # 检查是否为视频或音频文件
- if file.endswith(('.mp4', '.flv', '.m4a', '.mp3')):
- file_path = os.path.join(root, file)
- found_files.append({
- "file_name": file,
- "file_path": file_path
- })
-
- if not found_files and not found_directory:
- error_message = "未找到匹配的视频文件"
- if cid is not None:
- error_message += f", CID: {cid}"
- if directory:
- error_message += f",目录:{directory}"
-
- return {
- "status": "error",
- "message": error_message
- }
-
- # 执行删除操作
- deleted_files = []
-
- if delete_directory and found_directory:
- # 删除整个目录
- import shutil
- try:
- shutil.rmtree(found_directory)
- return {
- "status": "success",
- "message": f"已删除目录:{found_directory}",
- "deleted_directory": found_directory
- }
- except Exception as e:
- return {
- "status": "error",
- "message": f"删除目录时出错:{str(e)}",
- "directory": found_directory
- }
- else:
- # 只删除视频文件
- for file_info in found_files:
- try:
- os.remove(file_info["file_path"])
- deleted_files.append(file_info)
- except Exception as e:
- return {
- "status": "error",
- "message": f"删除文件时出错:{str(e)}",
- "file": file_info["file_path"]
- }
-
- return {
- "status": "success",
- "message": f"已删除{len(deleted_files)}个文件",
- "deleted_files": deleted_files,
- "directory": found_directory
- }
-
- except Exception as e:
- return {
- "status": "error",
- "message": f"删除视频文件时出错:{str(e)}"
- }
-
-@router.get("/stream_danmaku", summary="获取视频弹幕文件")
-async def stream_danmaku(file_path: Optional[str] = None, cid: Optional[int] = None):
- """
- 返回视频弹幕文件 (.ass),用于前端播放时显示弹幕
-
- Args:
- file_path: 视频文件的完整路径,会自动查找对应的 ass 文件
- cid: 可选,如果提供 CID 而不是文件路径,将尝试查找对应 CID 的弹幕文件
-
- Returns:
- FileResponse: 弹幕文件响应
- """
- try:
- if not file_path and not cid:
- raise HTTPException(
- status_code=400,
- detail="必须提供视频文件路径 (file_path) 或视频 CID(cid) 参数"
- )
-
- danmaku_path = None
-
- # 1. 如果提供了文件路径,尝试查找对应的 ass 文件
- if file_path:
- # 检查视频文件是否存在
- if not os.path.exists(file_path):
- raise HTTPException(
- status_code=404,
- detail=f"视频文件不存在:{file_path}"
- )
-
- # 尝试找到同名的.ass 文件
- base_path = file_path.rsplit('.', 1)[0] # 移除扩展名
- possible_ass_path = f"{base_path}.ass"
-
- if os.path.exists(possible_ass_path):
- danmaku_path = possible_ass_path
- else:
- # 尝试在同一目录下查找任何包含相同 CID 的.ass 文件
- directory = os.path.dirname(file_path)
- file_name = os.path.basename(file_path)
-
- # 尝试从文件名提取 CID
- cid_match = None
- file_parts = file_name.split('_')
- if len(file_parts) > 1:
- try:
- # 尝试获取最后一部分中的 CID (去掉扩展名)
- last_part = file_parts[-1].split('.')[0]
- if last_part.isdigit():
- cid_match = last_part
- except:
- pass
-
- if cid_match:
- # 在同一目录下查找包含相同 CID 的.ass 文件
- for file in os.listdir(directory):
- if file.endswith('.ass') and cid_match in file:
- danmaku_path = os.path.join(directory, file)
- break
-
- # 2. 如果提供了 CID,在下载目录中查找对应的弹幕文件
- elif cid:
- download_dir = os.path.normpath(config['yutto']['basic']['dir'])
-
- # 确保下载目录存在
- if not os.path.exists(download_dir):
- raise HTTPException(
- status_code=404,
- detail="下载目录不存在"
- )
-
- # 递归遍历下载目录查找匹配 CID 的弹幕文件
- for root, dirs, files in os.walk(download_dir):
- # 检查目录名是否包含 CID
- if f"_{cid}" in os.path.basename(root):
- # 检查目录中的文件
- for file in files:
- # 检查是否为弹幕文件
- if file.endswith('.ass') and f"_{cid}" in file:
- danmaku_path = os.path.join(root, file)
- break
-
- # 如果在当前目录找到了弹幕文件,就不再继续查找
- if danmaku_path:
- break
-
- # 检查是否找到弹幕文件
- if not danmaku_path:
- raise HTTPException(
- status_code=404,
- detail=f"未找到匹配的弹幕文件"
- )
-
- # 返回文件响应
- return FileResponse(
- danmaku_path,
- media_type='text/plain',
- filename=os.path.basename(danmaku_path)
- )
-
- except HTTPException:
- raise
- except Exception as e:
- raise HTTPException(
- status_code=500,
- detail=f"获取弹幕文件时出错:{str(e)}"
- )
-
-@router.post("/download_user_videos", summary="下载用户全部投稿视频")
-async def download_user_videos(request: UserSpaceDownloadRequest):
- """
- 下载指定用户的全部投稿视频
-
- Args:
- request: 包含用户 ID 和可选 SESSDATA 的请求对象
- """
- try:
- # 检查下载目录和临时目录
- download_dir, tmp_dir = check_download_directories()
-
- # 构建用户空间 URL
- user_space_url = f"https://space.bilibili.com/{request.user_id}/video"
-
- # 构建基本命令
- command = [
- user_space_url,
- '--batch', # 批量下载
- '--dir', download_dir,
- '--tmp-dir', tmp_dir,
- '--subpath-template', f'{{username}}的全部投稿视频/{{title}}_{{download_date@%Y%m%d_%H%M%S}}/{{title}}',
- '--with-metadata' # 添加元数据文件保存
- ]
-
- # 添加下载参数
- command = add_download_params_to_command(command, request)
-
- print(f"执行下载命令:yutto {' '.join(command)}")
-
- async def event_stream():
- async for chunk in run_yutto(command):
- yield chunk
- yield "event: close\ndata: close\n\n"
-
- return StreamingResponse(event_stream(), media_type="text/event-stream")
-
- except HTTPException:
- raise
- except Exception as e:
- raise HTTPException(status_code=500, detail=f"下载过程出错:{str(e)}")
-
-@router.post("/batch_download", summary="批量下载多个B站视频")
-async def batch_download(request: BatchDownloadRequest):
- """
- 批量下载多个B站视频
-
- Args:
- request: 包含多个视频信息和下载选项的请求对象
- """
- try:
- # 检查下载目录和临时目录
- download_dir, tmp_dir = check_download_directories()
-
- # 准备批量下载
- total_videos = len(request.videos)
- current_index = 0
-
- # 创建一个异步生成器来处理批量下载
- async def batch_download_generator():
- nonlocal current_index
-
- # 发送初始信息
- yield f"data: 开始批量下载,共 {total_videos} 个视频\n\n"
-
- for video in request.videos:
- current_index += 1
-
- # 发送当前下载信息
- yield f"data: 正在下载第 {current_index}/{total_videos} 个视频: {video.title or video.bvid}\n\n"
-
- # 构建视频 URL
- video_url = f"https://www.bilibili.com/video/{video.bvid}"
-
- # -------------------- 组装 yutto 参数 --------------------
- argv = [
- video_url,
- '--dir', download_dir,
- '--tmp-dir', tmp_dir,
- '--subpath-template',
- f'{{title}}_{{username}}_{{download_date@%Y%m%d_%H%M%S}}_{video.cid}/{{title}}_{video.cid}',
- '--with-metadata' # 保存元数据文件
- ]
- # 注:add_download_params_to_command 内部会按需追加其它参数
- argv = add_download_params_to_command(argv, request)
-
- # 打印调试信息
- print("执行下载命令:yutto " + ' '.join(argv))
-
- # -------------------- 执行下载 --------------------
- try:
- # 进程内调用 yutto,并实时转发输出
- async for line in run_yutto(argv):
- yield line
-
- # 发送当前视频下载完成信息
- yield f"data: 第 {current_index}/{total_videos} 个视频下载完成: {video.title or video.bvid}\n\n"
-
- except Exception as e:
- error_msg = f"下载视频 {video.bvid} 时出错:{str(e)}"
- print(error_msg)
- yield f"data: ERROR: {error_msg}\n\n"
-
- # 发送批量下载完成信息
- yield f"data: 批量下载完成,共 {total_videos} 个视频\n\n"
- yield "event: close\ndata: close\n\n"
-
- # 返回 SSE 响应
- return StreamingResponse(
- batch_download_generator(),
- media_type="text/event-stream"
- )
-
- except HTTPException:
- raise
- except Exception as e:
- raise HTTPException(status_code=500, detail=f"批量下载过程出错:{str(e)}")
-
-@router.post("/download_favorites", summary="下载用户收藏夹视频")
-async def download_favorites(request: FavoriteDownloadRequest):
- """
- 下载用户的收藏夹视频
-
- Args:
- request: 包含用户 ID、收藏夹 ID 和可选 SESSDATA 的请求对象
- 注意:不提供收藏夹 ID 时,将下载所有收藏夹
- """
- try:
- # 收藏夹必须登录
- sessdata = request.sessdata or config.get('SESSDATA')
- if not sessdata:
- raise HTTPException(
- status_code=401,
- detail="未登录:下载收藏夹必须提供 SESSDATA"
- )
-
- # 检查下载目录和临时目录
- download_dir, tmp_dir = check_download_directories()
-
- # 构建收藏夹 URL
- if request.fid:
- # 指定收藏夹
- favorite_url = f"https://space.bilibili.com/{request.user_id}/favlist?fid={request.fid}"
- else:
- # 所有收藏夹
- favorite_url = f"https://space.bilibili.com/{request.user_id}/favlist"
-
- # 构建基本命令
- command = [
- favorite_url,
- '--batch', # 批量下载
- '--dir', download_dir,
- '--tmp-dir', tmp_dir,
- '--subpath-template', f'{{username}}的收藏夹/{{title}}_{{download_date@%Y%m%d_%H%M%S}}/{{title}}',
- '--with-metadata' # 添加元数据文件保存
- ]
-
- # 添加下载参数
- command = add_download_params_to_command(command, request)
-
- # 确保添加 SESSDATA (收藏夹必须登录)
- if '--sessdata' not in command:
- command.extend(['--sessdata', sessdata])
-
- print(f"执行下载命令:yutto {' '.join(command)}")
-
- async def event_stream():
- async for chunk in run_yutto(command):
- yield chunk
- yield "event: close\ndata: close\n\n"
-
- return StreamingResponse(event_stream(), media_type="text/event-stream")
-
- except HTTPException:
- raise
- except Exception as e:
- raise HTTPException(status_code=500, detail=f"下载过程出错:{str(e)}")
-
-# 定义响应模型
-class VideoInfo(BaseModel):
- path: str
- size: int
- title: str
- create_time: datetime
- cover: str = ""
- cid: str = ""
- bvid: str = ""
- author_name: str = ""
- author_face: str = ""
- author_mid: int = 0
-
-class VideoSearchResponse(BaseModel):
- total: int
- videos: list[VideoInfo]
-
-# 视频详细信息响应模型
-class VideoDetailResponse(BaseModel):
- status: str
- message: str
- data: Optional[dict] = None
-
-@router.get("/video_info", summary="获取 B 站视频详细信息")
-async def get_video_info(aid: Optional[int] = None, bvid: Optional[str] = None, sessdata: Optional[str] = None, headers: Optional[dict] = None, use_sessdata: bool = True):
- """
- 获取B站视频详细信息
-
- Args:
- aid: 视频aid
- bvid: 视频bvid
- sessdata: B站会话ID
- headers: 自定义请求头
- use_sessdata: 是否使用SESSDATA认证,默认为True
- """
- try:
- if not aid and not bvid:
- return VideoDetailResponse(
- status="error",
- message="至少需要提供aid或bvid参数",
- data=None
- )
-
- # 配置请求信息
- default_headers = {
- 'User-Agent': 'Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/91.0.4472.124 Safari/537.36',
- 'Referer': 'https://www.bilibili.com',
- }
-
- # 合并自定义请求头
- if headers:
- default_headers.update(headers)
-
- # 仅在需要使用SESSDATA且提供了SESSDATA时,加入到请求头中
- if sessdata and use_sessdata:
- default_headers['Cookie'] = f'SESSDATA={sessdata};'
-
- # 准备请求参数
- params = {}
- if aid:
- params['aid'] = aid
- if bvid:
- params['bvid'] = bvid
-
- url = "https://api.bilibili.com/x/web-interface/view"
-
- # 使用httpx发送请求
- async with httpx.AsyncClient() as client:
- response = await client.get(url, params=params, headers=default_headers, timeout=20.0)
-
- # 首先检查内容类型
- content_type = response.headers.get('content-type', '')
- if 'application/json' not in content_type:
- return VideoDetailResponse(
- status="error",
- message=f"非JSON响应: {content_type},视频可能无法访问",
- data=None
- )
-
- # 尝试多种解码方式
- content = None
- for encoding in ['utf-8', 'gbk', 'gb2312', 'utf-16', 'latin1']:
- try:
- content = response.content.decode(encoding)
- break
- except UnicodeDecodeError:
- continue
-
- # 如果所有解码方式都失败,使用bytes的十六进制表示
- if content is None:
- hex_content = response.content.hex()
- return VideoDetailResponse(
- status="error",
- message=f"无法解码响应内容,可能是非文本数据",
- data={"raw_hex": hex_content[:100] + "..."}
- )
-
- # 尝试解析JSON
- try:
- response_json = json.loads(content)
- except json.JSONDecodeError:
- return VideoDetailResponse(
- status="error",
- message=f"无法解析JSON: {content[:200]}...",
- data=None
- )
-
- # 检查是否API错误
- code = response_json.get('code', 0)
- if code != 0:
- error_msg = response_json.get('message', '未知错误')
-
- # 特殊处理一些常见错误
- if code == -404:
- error_msg = "视频不存在或已被删除"
- elif code == 62002:
- error_msg = "视频不可见(可能是私有或被删除)"
-
- return VideoDetailResponse(
- status="error",
- message=f"API错误 {code}: {error_msg}",
- data=response_json
- )
-
- # 正常返回
- return VideoDetailResponse(
- status="success",
- message="获取视频信息成功",
- data=response_json.get('data', {})
- )
-
- except httpx.RequestError as e:
- return VideoDetailResponse(
- status="error",
- message=f"请求错误: {str(e)}",
- data=None
- )
- except Exception as e:
- return VideoDetailResponse(
- status="error",
- message=f"获取视频信息时出错:{str(e)}",
- data=None
- )
-
-# 用户投稿视频查询参数模型
-class UserVideosQueryParams(BaseModel):
- mid: int = Field(..., description="目标用户 mid")
- pn: int = Field(1, description="页码")
- ps: int = Field(30, description="每页项数")
- tid: int = Field(0, description="分区筛选,0:全部")
- keyword: str = Field("", description="关键词筛选")
- order: str = Field("pubdate", description="排序方式")
- platform: str = Field("web", description="平台标识")
-
-# 用户投稿视频响应模型
-class UserVideosResponse(BaseModel):
- status: str
- message: str
- data: Optional[dict] = None
-
-@router.get("/user_videos", summary="查询用户投稿视频明细")
-async def get_user_videos(
- mid: int,
- pn: int = 1,
- ps: int = 30,
- tid: int = 0,
- keyword: str = "",
- order: str = "pubdate",
- sessdata: Optional[str] = None,
- use_sessdata: bool = True
-):
- """
- 查询用户投稿视频明细
-
- Args:
- mid: 目标用户 mid
- pn: 页码,默认为 1
- ps: 每页项数,默认为 30
- tid: 分区 ID,默认为 0(全部)
- keyword: 关键词过滤,默认为空
- order: 排序方式,默认为 pubdate(发布日期)
- 可选值:pubdate(发布日期)、click(播放量)、stow(收藏量)
- sessdata: 可选,用户的 SESSDATA,用于获取限制查看的视频
- use_sessdata: 是否使用SESSDATA认证,默认为True
-
- Returns:
- 用户投稿视频列表
- """
- try:
- # 设置请求头
- headers = {
- 'User-Agent': 'Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/91.0.4472.124 Safari/537.36',
- 'Accept': 'application/json',
- 'Referer': f'https://space.bilibili.com/{mid}/video',
- 'Origin': 'https://space.bilibili.com'
- }
-
- # 仅在需要使用SESSDATA且提供了SESSDATA时,加入到请求头中
- if sessdata and use_sessdata:
- headers['Cookie'] = f'SESSDATA={sessdata}'
- elif config.get('SESSDATA') and use_sessdata:
- headers['Cookie'] = f'SESSDATA={config["SESSDATA"]}'
-
- # 构建请求参数
- params = {
- 'mid': mid,
- 'pn': pn,
- 'ps': ps,
- 'tid': tid,
- 'keyword': keyword,
- 'order': order,
- 'platform': 'web'
- }
-
- # 使用 WBI 签名
- from scripts.wbi_sign import get_wbi_sign
- signed_params = get_wbi_sign(params)
-
- # 发送请求获取用户视频列表
- response = requests.get(
- 'https://api.bilibili.com/x/space/wbi/arc/search',
- params=signed_params,
- headers=headers,
- timeout=10
- )
-
- # 显式设置响应编码
- response.encoding = 'utf-8'
-
- # 打印响应状态和内容预览,便于调试
- print(f"请求 URL: {response.url}")
- print(f"响应状态码:{response.status_code}")
- content_preview = response.text[:100] if len(response.text) > 100 else response.text
- print(f"响应内容预览:{content_preview}")
-
- # 解析响应
- response_json = response.json()
-
- # 处理可能的错误
- if response_json.get('code') != 0:
- return UserVideosResponse(
- status="error",
- message=f"获取用户投稿视频列表失败:{response_json.get('message', '未知错误')}",
- data=response_json
- )
-
- # 返回成功响应
- return UserVideosResponse(
- status="success",
- message="获取用户投稿视频列表成功",
- data=response_json.get('data')
- )
-
- except Exception as e:
- import traceback
- error_trace = traceback.format_exc()
- print(f"获取用户投稿视频列表时出错:{str(e)}")
- print(f"错误堆栈:{error_trace}")
-
- return UserVideosResponse(
- status="error",
- message=f"获取用户投稿视频列表时出错:{str(e)}",
- data={"error_trace": error_trace}
- )
diff --git a/routers/dynamic.py b/routers/dynamic.py
deleted file mode 100644
index 5c053b5..0000000
--- a/routers/dynamic.py
+++ /dev/null
@@ -1,1221 +0,0 @@
-import os
-import shutil
-import asyncio
-from typing import Optional, Dict, Any, List
-from fastapi import APIRouter, HTTPException, Query, Response
-from fastapi.responses import StreamingResponse
-from loguru import logger
-import aiohttp
-import aiofiles
-
-from scripts.utils import load_config, setup_logger, get_output_path
-from scripts.dynamic_db import (
- get_connection,
- save_normalized_dynamic_item,
- list_hosts_with_stats,
- list_dynamics_for_host,
- dynamic_core_exists,
- purge_host,
-)
-from scripts.dynamic_media import collect_image_urls, download_images, predict_image_path, collect_live_media_urls, download_live_media, collect_emoji_urls, download_emojis
-from scripts.wbi_sign import get_wbi_sign
-
-# 确保日志系统已初始化
-setup_logger()
-
-router = APIRouter()
-
-# 任务管理:按 host_mid 管理抓取任务、停止信号与进度
-_tasks = {}
-_stop_events = {}
-_progress = {}
-
-def _get_or_create_event(host_mid: int) -> asyncio.Event:
- if host_mid not in _stop_events:
- _stop_events[host_mid] = asyncio.Event()
- return _stop_events[host_mid]
-
-def _clear_event(host_mid: int) -> None:
- """清除停止事件"""
- if host_mid in _stop_events:
- try:
- _stop_events[host_mid].clear()
- logger.info(f"[DEBUG] 已清除停止事件 host_mid={host_mid}")
- except Exception as e:
- logger.warning(f"[DEBUG] 清除停止事件失败: {e}")
- else:
- logger.info(f"[DEBUG] 停止事件不存在于缓存中 host_mid={host_mid}")
-
-def _set_progress(host_mid: int, page: int, total_items: int, last_offset: str, message: str) -> None:
- _progress[host_mid] = {
- "page": page,
- "total_items": total_items,
- "last_offset": last_offset or "",
- "message": message,
- }
-
-def _get_progress(host_mid: int) -> Dict[str, Any]:
- return _progress.get(host_mid, {"page": 0, "total_items": 0, "last_offset": "", "message": "空闲状态,未开始抓取"})
-
-
-@router.get("/space/auto/{host_mid}/progress", summary="SSE 实时获取自动抓取进度")
-async def auto_fetch_progress(host_mid: int):
- """
- 以 SSE 流方式每秒推送一次当前抓取进度。
- 数据格式为 text/event-stream,data 为 JSON 字符串。
- """
- async def event_generator():
- while True:
- progress = _get_progress(host_mid)
- # 构造 SSE 包
- import json
- payload = json.dumps({
- "host_mid": host_mid,
- "page": progress.get("page", 0),
- "total_items": progress.get("total_items", 0),
- "last_offset": progress.get("last_offset", ""),
- "message": progress.get("message", "idle"),
- }, ensure_ascii=False)
- yield f"event: progress\ndata: {payload}\n\n"
- await asyncio.sleep(1)
-
- return StreamingResponse(event_generator(), media_type="text/event-stream")
-
-
-@router.post("/space/auto/{host_mid}/stop", summary="停止当前自动抓取(页级停止)")
-async def stop_auto_fetch(host_mid: int):
- """
- 发送停止信号,当前页完成后停止抓取,并记录 offset 以便下次继续。
- 注意:下次开始抓取时会自动清除停止信号。
- """
- ev = _get_or_create_event(host_mid)
- ev.set()
- logger.info(f"[DEBUG] 发送停止信号 host_mid={host_mid}, 事件状态: is_set={ev.is_set()}")
- return {"status": "ok", "message": "stop signal sent", "event_is_set": ev.is_set()}
-
-
-@router.get("/db/hosts", summary="列出数据库中已有动态的UP列表")
-async def list_db_hosts(
- limit: int = Query(50, ge=1, le=200, description="每页数量"),
- offset: int = Query(0, ge=0, description="偏移量"),
-):
- try:
- conn = get_connection()
- except Exception as e:
- logger.error(f"打开动态数据库失败: {e}")
- raise HTTPException(status_code=500, detail=f"打开动态数据库失败: {str(e)}")
- try:
- data = list_hosts_with_stats(conn, limit=limit, offset=offset)
-
- # 基础输出根目录(用于拼接相对路径)
- base_output_dir = os.path.dirname(get_output_path("__base__"))
-
- # 为每个 host_mid 增补 up_name 与 face_path(若存在则返回相对路径)
- cursor = conn.cursor()
- for rec in data:
- host_mid = rec.get("host_mid")
- up_name = None
- face_rel = None
- try:
- # 查询最近一条记录的作者名
- row = cursor.execute(
- """
- SELECT author_name
- FROM dynamic_core
- WHERE host_mid = ? AND author_name IS NOT NULL AND author_name <> ''
- ORDER BY (publish_ts IS NULL) ASC, publish_ts DESC, fetch_time DESC
- LIMIT 1
- """,
- (str(host_mid),),
- ).fetchone()
- if row and row[0]:
- up_name = row[0]
- except Exception as e:
- logger.warning(f"查询作者名失败(忽略) host_mid={host_mid}: {e}")
-
- # 头像:output/dynamic/{mid}/face.*
- try:
- host_dir = os.path.dirname(get_output_path("dynamic", str(host_mid), "__host_meta.json"))
- if os.path.isdir(host_dir):
- for name in os.listdir(host_dir):
- if os.path.isfile(os.path.join(host_dir, name)) and name.lower().startswith("face."):
- face_rel = os.path.relpath(os.path.join(host_dir, name), base_output_dir)
- break
- except Exception as e:
- logger.warning(f"定位头像失败(忽略) host_mid={host_mid}: {e}")
-
- # 写回扩展字段
- rec["up_name"] = up_name
- rec["face_path"] = face_rel
-
- return {"data": data, "limit": limit, "offset": offset}
- finally:
- try:
- conn.close()
- except Exception:
- pass
-
-
-@router.get("/db/space/{host_mid}", summary="列出指定UP的动态(来自数据库)")
-async def list_db_space(
- host_mid: int,
- limit: int = Query(20, ge=1, le=200, description="每页数量"),
- offset: int = Query(0, ge=0, description="偏移量"),
-):
- try:
- conn = get_connection()
- except Exception as e:
- logger.error(f"打开动态数据库失败: {e}")
- raise HTTPException(status_code=500, detail=f"打开动态数据库失败: {str(e)}")
- try:
- result = list_dynamics_for_host(conn, host_mid=host_mid, limit=limit, offset=offset)
-
- # 将 media_locals 和 live_media_locals 从逗号分隔字符串转换为数组,便于前端使用
- try:
- items = result.get("items", []) if isinstance(result, dict) else []
- for item in items:
- # 处理普通媒体
- ml = item.get("media_locals")
- if isinstance(ml, str):
- ml_str = ml.strip()
- if ml_str:
- item["media_locals"] = [p for p in (s.strip() for s in ml_str.split(",")) if p]
- else:
- item["media_locals"] = []
- elif ml is None:
- item["media_locals"] = []
-
- # 处理实况媒体
- lml = item.get("live_media_locals")
- if isinstance(lml, str):
- lml_str = lml.strip()
- if lml_str:
- item["live_media_locals"] = [p for p in (s.strip() for s in lml_str.split(",")) if p]
- else:
- item["live_media_locals"] = []
- elif lml is None:
- item["live_media_locals"] = []
- except Exception as e:
- logger.warning(f"媒体路径转换失败(忽略) host_mid={host_mid}: {e}")
-
- return {"host_mid": str(host_mid), **result, "limit": limit, "offset": offset}
- finally:
- try:
- conn.close()
- except Exception:
- pass
-
-
-def get_headers() -> Dict[str, str]:
- """获取请求头(包含完整的浏览器模拟 Headers 以避免 412 风控)"""
- config = load_config()
- sessdata = config.get("SESSDATA", "")
-
- headers = {
- 'User-Agent': 'Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/91.0.4472.124 Safari/537.36',
- 'Accept': 'application/json, text/plain, */*',
- 'Accept-Language': 'zh-CN,zh;q=0.9,en;q=0.8',
- }
-
- cookie_parts = []
- if sessdata:
- cookie_parts.append(f'SESSDATA={sessdata}')
- bili_jct = config.get("bili_jct", "")
- if bili_jct:
- cookie_parts.append(f'bili_jct={bili_jct}')
- dede_user_id = config.get("DedeUserID", "")
- if dede_user_id:
- cookie_parts.append(f'DedeUserID={dede_user_id}')
- dede_ck = config.get("DedeUserID__ckMd5", "")
- if dede_ck:
- cookie_parts.append(f'DedeUserID__ckMd5={dede_ck}')
- buvid3 = config.get("buvid3", "")
- if buvid3:
- cookie_parts.append(f'buvid3={buvid3}')
-
- if cookie_parts:
- headers['Cookie'] = '; '.join(cookie_parts)
-
- return headers
-
-
-async def fetch_dynamic_data(api_url: str, params: Dict[str, Any]) -> Dict[str, Any]:
- """获取动态数据的通用函数"""
- headers = get_headers()
-
- async with aiohttp.ClientSession() as session:
- try:
- async with session.get(api_url, headers=headers, params=params) as response:
- if response.status == 200:
- # 内容类型保护:仅当返回为 JSON 时才解析为 JSON
- content_type = response.headers.get("Content-Type", "")
- if "application/json" in content_type or "text/json" in content_type or "application/vnd" in content_type:
- data = await response.json()
- else:
- # 非JSON返回,读取少量文本用于错误提示(不抛出二次异常)
- try:
- snippet = (await response.text())[:256]
- except Exception:
- snippet = "
"
- logger.error(f"请求返回非JSON,Content-Type={content_type} url={api_url} params={params} snippet={snippet}")
- raise HTTPException(status_code=500, detail="非JSON响应,无法解析")
- logger.info(f"成功获取动态数据,状态码: {response.status}")
- return data
- else:
- try:
- error_text = (await response.text())[:512]
- except Exception:
- error_text = ""
- logger.error(f"请求失败,状态码: {response.status} url={api_url} params={params} body={error_text}")
- raise HTTPException(status_code=response.status, detail=f"请求失败: {response.status}")
- except aiohttp.ClientError as e:
- logger.error(f"网络请求错误: {e}")
- raise HTTPException(status_code=500, detail=f"网络请求错误: {str(e)}")
-
-
-@router.get("/space/auto/{host_mid}", summary="自动从前到后抓取直至完成")
-async def auto_fetch_all(
- host_mid: int,
- need_top: bool = Query(False, description="是否需要置顶动态"),
- save_to_db: bool = Query(True, description="是否保存到数据库"),
- save_media: bool = Query(True, description="是否保存图片等多媒体"),
-):
- """
- 自动连续抓取用户空间动态:
- - 从上次记录的offset继续;若存在 fully_fetched=true 则从头开始
- - 每页3-5秒随机延迟
- - 当 offset 为空时终止,写 fully_fetched=true
- - 若从头开始抓取遇到连续10条已存在的动态ID则停止,并不保存这10条
- """
- import json, time, random
-
- api_url = "https://api.bilibili.com/x/polymer/web-dynamic/v1/feed/space"
- base_params = {
- "host_mid": host_mid,
- "need_top": 1 if need_top else 0,
- "features": "itemOpusStyle,listOnlyfans,opusBigCover,onlyfansVote,forwardListHidden,decorationCard,commentsNewVersion,onlyfansAssetsV2,ugcDelete,onlyfansQaCard",
- "timezone_offset": -480,
- "platform": "web",
- "web_location": "333.1387",
- }
-
- # 读取 host 元数据
- host_dir = os.path.dirname(get_output_path("dynamic", str(host_mid), "__host_meta.json"))
- os.makedirs(host_dir, exist_ok=True)
- meta_path = os.path.join(host_dir, "__host_meta.json")
- meta = {"host_mid": str(host_mid), "last_fetch_time": 0, "last_offset": {"offset": "", "update_baseline": "", "update_num": 0}, "fully_fetched": False}
- if os.path.exists(meta_path):
- try:
- with open(meta_path, "r", encoding="utf-8") as rf:
- old = json.load(rf)
- if isinstance(old, dict):
- meta.update(old)
- except Exception:
- pass
-
- # 确定起点
- start_from_head = bool(meta.get("fully_fetched", False))
- next_offset = None if start_from_head else (meta.get("last_offset", {}) or {}).get("offset") or None
-
- # 调试信息:打印offset使用情况
- logger.info(f"[DEBUG] 抓取开始 host_mid={host_mid}")
- logger.info(f"[DEBUG] 元数据内容: {meta}")
- logger.info(f"[DEBUG] fully_fetched={meta.get('fully_fetched')}, start_from_head={start_from_head}")
- logger.info(f"[DEBUG] last_offset对象: {meta.get('last_offset', {})}")
- logger.info(f"[DEBUG] 将使用的next_offset: {next_offset}")
- if start_from_head:
- logger.info(f"[DEBUG] 模式: 从头开始抓取 (因为fully_fetched=True)")
- elif next_offset:
- logger.info(f"[DEBUG] 模式: 从offset继续抓取 (offset={next_offset})")
- else:
- logger.info(f"[DEBUG] 模式: 从头开始抓取 (无有效offset)")
-
- # DB 连接
- if save_to_db:
- try:
- conn = get_connection()
- except Exception as e:
- logger.error(f"打开动态数据库失败: {e}")
- raise HTTPException(status_code=500, detail=f"打开动态数据库失败: {str(e)}")
- else:
- conn = None
-
- all_items = []
- consecutive_duplicates = 0
-
- # 页计数
- current_page = 0
-
- # 自动重置停止信号:每次开始抓取前都清除之前的停止状态
- logger.info(f"[DEBUG] 自动重置停止信号 host_mid={host_mid}")
- _clear_event(host_mid) # 确保清除任何遗留的停止信号
- stop_event = _get_or_create_event(host_mid) # 创建新的事件对象
-
- # 验证重置结果
- logger.info(f"[DEBUG] 重置后停止事件状态: is_set={stop_event.is_set()}")
-
- _set_progress(host_mid, current_page, 0, next_offset or "", "准备开始抓取动态")
-
- try:
- while True:
- # 调试信息:打印每页请求的参数
- logger.info(f"[DEBUG] === 第 {current_page + 1} 页请求 ===")
- logger.info(f"[DEBUG] 当前next_offset: {next_offset}")
-
- # 基础参数 + 当页 offset
- params = dict(base_params)
- if next_offset:
- params["offset"] = next_offset
- logger.info(f"[DEBUG] 设置offset参数: {next_offset}")
- else:
- logger.info(f"[DEBUG] 本次请求不带offset(从头开始或已到底)")
-
- # 为参数添加 WBI 签名
- signed_params = get_wbi_sign(params)
- logger.info(f"[DEBUG] 最终请求参数(已签名): {signed_params}")
-
- # 更新进度:准备抓取下一页
- if current_page > 0:
- _set_progress(host_mid, current_page, len(all_items), next_offset or "", f"准备抓取第 {current_page + 1} 页...")
-
- # 随机延迟3-5秒
- await asyncio.sleep(random.uniform(3, 5))
-
- data = await fetch_dynamic_data(api_url, signed_params)
-
- # 调试信息:打印API响应中的offset信息
- logger.info(f"[DEBUG] API响应结构检查:")
- logger.info(f"[DEBUG] - response.code: {data.get('code')}")
- logger.info(f"[DEBUG] - response.data存在: {bool(data.get('data'))}")
-
- # 兼容B站原始结构:从data.data中获取items和offset
- data_section = data.get("data", {}) if isinstance(data, dict) else {}
- items = data_section.get("items", []) if isinstance(data_section, dict) else []
- # offset 既可能是字符串,也可能在对象中
- off = data_section.get("offset") if isinstance(data_section, dict) else None
-
- logger.info(f"[DEBUG] - data_section.offset原始值: {off} (类型: {type(off)})")
-
- if isinstance(off, dict):
- next_offset = off.get("offset")
- logger.info(f"[DEBUG] - 从offset对象提取: {next_offset}")
- else:
- next_offset = off
- logger.info(f"[DEBUG] - 直接使用offset: {next_offset}")
-
- logger.info(f"[DEBUG] - 本页获取items数量: {len(items)}")
- logger.info(f"[DEBUG] - 下一页的offset: {next_offset}")
-
- # 若从头开始,并且出现连续10条都已存在,则停止
- if start_from_head and conn is not None:
- for item in items:
- id_str = item.get("id_str") or item.get("basic", {}).get("id_str") or str(item.get("id"))
- if id_str and dynamic_core_exists(conn, host_mid, str(id_str)):
- consecutive_duplicates += 1
- if consecutive_duplicates >= 10:
- next_offset = None # 触发终止
- items = [] # 不保存这10条
- break
- else:
- consecutive_duplicates = 0
-
- all_items.extend(items)
- current_page += 1
- _set_progress(host_mid, current_page, len(all_items), next_offset or "", f"第 {current_page} 页抓取完成,本页获取 {len(items)} 条动态,累计 {len(all_items)} 条")
-
- # 保存页面数据(去掉item.json保存,只有包含多媒体文件时才创建文件夹)
- if save_to_db and items:
- base_output_dir = os.path.dirname(get_output_path("__base__"))
-
- # 头像保存:仅保存一次到 output/dynamic/{host_mid}/face.(ext)
- try:
- # 尝试从items提取用户头像
- face_url = None
- for item in items:
- modules_raw = item.get("modules")
- if isinstance(modules_raw, dict):
- face_url = modules_raw.get("module_author", {}).get("face")
- elif isinstance(modules_raw, list):
- for mod in modules_raw:
- if isinstance(mod, dict) and mod.get("module_type") == "MODULE_TYPE_AUTHOR":
- face_url = mod.get("module_author", {}).get("user", {}).get("face") or mod.get("module_author", {}).get("face")
- if face_url:
- break
- if not face_url:
- face_url = item.get("user", {}).get("face")
- if face_url:
- break
-
- if face_url:
- # 若已存在头像文件则跳过
- host_dir = os.path.dirname(get_output_path("dynamic", str(host_mid), "__host_meta.json"))
- os.makedirs(host_dir, exist_ok=True)
-
- # 检查是否已有任何文件以 face.* 命名
- exists = any(
- name.lower().startswith("face.")
- for name in os.listdir(host_dir)
- if os.path.isfile(os.path.join(host_dir, name))
- )
- if not exists:
- # 下载头像一次
- results = await download_images([face_url], host_dir)
- # 将下载的哈希文件重命名为 face.扩展名
- for url, local_path, ok in results:
- if ok:
- _, ext = os.path.splitext(local_path)
- new_path = os.path.join(host_dir, f"face{ext}")
- try:
- if os.path.exists(new_path):
- os.remove(new_path)
- except Exception:
- pass
- try:
- os.replace(local_path, new_path)
- except Exception:
- pass
- break
- except Exception as e:
- logger.warning(f"保存头像失败(忽略):{e}")
-
- for item in items:
- try:
- id_str = (
- item.get("id_str")
- or item.get("basic", {}).get("id_str")
- or str(item.get("id"))
- )
- if not id_str:
- continue
-
- # 检查是否有多媒体文件需要下载
- has_media = False
- predicted_locals = []
- live_predicted_locals = []
- if save_media:
- # 处理普通图片
- image_urls = collect_image_urls(item)
- if image_urls:
- has_media = True
- # 只有当包含多媒体文件时才创建文件夹
- item_dir = os.path.dirname(
- get_output_path("dynamic", str(host_mid), str(id_str), "media")
- )
- os.makedirs(item_dir, exist_ok=True)
-
- # 预测本地路径
- for u in image_urls:
- predicted_locals.append(os.path.relpath(predict_image_path(u, item_dir), base_output_dir))
-
- results = await download_images(image_urls, item_dir)
- media_records = []
- for media_url, local_path, ok in results:
- if ok:
- rel_path = os.path.relpath(local_path, base_output_dir)
- media_records.append((media_url, rel_path, "image"))
-
- # 处理实况媒体(live图片+视频)
- live_media_pairs = collect_live_media_urls(item)
- if live_media_pairs:
- has_media = True
- # 创建文件夹(如果还未创建)
- if not image_urls:
- item_dir = os.path.dirname(
- get_output_path("dynamic", str(host_mid), str(id_str), "media")
- )
- os.makedirs(item_dir, exist_ok=True)
-
- live_results = await download_live_media(live_media_pairs, item_dir)
- for image_url, video_url, image_path, video_path, ok in live_results:
- if ok:
- # 将实况媒体路径分别记录
- image_rel = os.path.relpath(image_path, base_output_dir)
- video_rel = os.path.relpath(video_path, base_output_dir)
- live_predicted_locals.extend([image_rel, video_rel])
-
- # 处理表情
- emoji_pairs = collect_emoji_urls(item)
- if emoji_pairs:
- has_media = True
- # 创建文件夹(如果还未创建)
- if not image_urls and not live_media_pairs:
- item_dir = os.path.dirname(
- get_output_path("dynamic", str(host_mid), str(id_str), "media")
- )
- os.makedirs(item_dir, exist_ok=True)
-
- emoji_results = await download_emojis(emoji_pairs, item_dir)
- for emoji_url, emoji_path, ok in emoji_results:
- if ok:
- # 将表情路径记录到普通媒体中
- emoji_rel = os.path.relpath(emoji_path, base_output_dir)
- predicted_locals.append(emoji_rel)
-
- # 规范化保存到数据库
- logger.info(f"normalize.core.call begin host_mid={host_mid} id_str={id_str}")
- try:
- save_normalized_dynamic_item(conn, host_mid, item)
- logger.info(f"normalize.core.call done host_mid={host_mid} id_str={id_str}")
- # 回写本地路径逗号串(只有当有多媒体文件时)
- if predicted_locals or live_predicted_locals:
- cursor = conn.cursor()
- cursor.execute(
- """
- UPDATE dynamic_core SET
- media_locals = CASE
- WHEN media_locals IS NULL OR media_locals = '' THEN ?
- ELSE media_locals
- END,
- live_media_locals = CASE
- WHEN live_media_locals IS NULL OR live_media_locals = '' THEN ?
- ELSE live_media_locals
- END,
- live_media_count = ?
- WHERE host_mid = ? AND id_str = ?
- """,
- (
- ",".join(predicted_locals) if predicted_locals else "",
- ",".join(live_predicted_locals) if live_predicted_locals else "",
- len(live_predicted_locals),
- str(host_mid),
- str(id_str),
- ),
- )
- conn.commit()
- except Exception as norm_err:
- logger.warning(f"规范化保存失败(忽略): {norm_err}")
- except Exception as perr:
- logger.warning(f"保存页面数据失败: {perr}")
-
- # 更新 meta
- meta["last_fetch_time"] = int(time.time())
- meta["last_offset"] = {"offset": next_offset or "", "update_baseline": "", "update_num": 0}
- meta["fully_fetched"] = not bool(next_offset)
-
- # 调试信息:保存状态
- logger.info(f"[DEBUG] 保存元数据:")
- logger.info(f"[DEBUG] - last_offset.offset: {next_offset or ''}")
- logger.info(f"[DEBUG] - fully_fetched: {meta['fully_fetched']}")
-
- try:
- async with aiofiles.open(meta_path, "w", encoding="utf-8") as wf:
- await wf.write(json.dumps(meta, ensure_ascii=False, indent=2))
- logger.info(f"[DEBUG] 元数据已保存到: {meta_path}")
- except Exception as e:
- logger.error(f"[DEBUG] 保存元数据失败: {e}")
-
- # 终止条件:offset 为空
- logger.info(f"[DEBUG] 检查终止条件: next_offset={next_offset}, 是否为空: {not bool(next_offset)}")
- if not next_offset:
- _set_progress(host_mid, current_page, len(all_items), next_offset or "", f"[全部抓取完毕] 抓取完成!共获取 {len(all_items)} 条动态,总计 {current_page} 页")
- break
-
- # 页级停止:如收到停止信号,则抓取完本页后停止并记录 offset
- logger.info(f"[DEBUG] 检查停止信号: is_set={stop_event.is_set()}")
- if stop_event.is_set():
- logger.warning(f"[DEBUG] 🛑 收到停止信号,停止抓取")
- _set_progress(host_mid, current_page, len(all_items), next_offset or "", f"用户停止抓取,已完成 {current_page} 页,共获取 {len(all_items)} 条动态")
- break
-
- # 返回B站原始结构,合并所有items
- return {
- "code": 0,
- "message": "0",
- "ttl": 1,
- "data": {
- "has_more": bool(next_offset),
- "items": all_items,
- "offset": next_offset or "",
- "update_baseline": "",
- "update_num": 0,
- "fully_fetched": meta.get("fully_fetched", False),
- }
- }
- finally:
- if conn is not None:
- try:
- conn.close()
- except Exception:
- pass
- # 关闭后保持最后一次进度
-
-
-@router.get("/space/{host_mid}", summary="获取用户空间动态")
-async def get_space_dynamic(
- host_mid: int,
- pages: int = Query(1, description="获取页数,0 表示获取全部"),
- need_top: bool = Query(False, description="是否需要置顶动态"),
- save_to_db: bool = Query(True, description="是否保存到数据库"),
- save_media: bool = Query(True, description="是否保存图片等多媒体")
-):
- """
- 获取指定用户空间的动态列表
-
- Args:
- host_mid: 目标用户的UID
- offset: 分页偏移量
- need_top: 是否获取置顶动态
- """
- try:
- api_url = "https://api.bilibili.com/x/polymer/web-dynamic/v1/feed/space"
-
- params = {
- "host_mid": host_mid,
- "need_top": 1 if need_top else 0,
- "features": "itemOpusStyle,listOnlyfans,opusBigCover,onlyfansVote,forwardListHidden,decorationCard,commentsNewVersion,onlyfansAssetsV2,ugcDelete,onlyfansQaCard",
- }
-
- logger.info(f"请求用户 {host_mid} 的空间动态,参数: {params}, pages={pages}")
-
- # 多页抓取:至多 pages 页;若 pages=0 则直到 offset 为空
- all_items = []
- next_offset: Optional[str] = None
- current_page = 0
- while True:
- # 注入偏移
- if next_offset:
- params["offset"] = next_offset
-
- data = await fetch_dynamic_data(api_url, params)
- # 兼容B站原始结构:从data.data中获取items和offset
- data_section = data.get("data", {}) if isinstance(data, dict) else {}
- items = data_section.get("items", []) if isinstance(data_section, dict) else []
- off = data_section.get("offset") if isinstance(data_section, dict) else None
- if isinstance(off, dict):
- next_offset = off.get("offset")
- else:
- next_offset = off
-
- all_items.extend(items)
- current_page += 1
-
- # 终止条件
- if pages == 0:
- if not next_offset:
- break
- else:
- if current_page >= max(1, pages):
- break
- if not next_offset:
- break
-
- # 可选保存
- if save_to_db:
- try:
- conn = get_connection()
- except Exception as e:
- logger.error(f"打开动态数据库失败: {e}")
- raise HTTPException(status_code=500, detail=f"打开动态数据库失败: {str(e)}")
-
- items: List[Dict[str, Any]] = all_items
-
- base_output_dir = os.path.dirname(get_output_path("__base__"))
-
- # 头像保存:仅保存一次到 output/dynamic/{host_mid}/face.(ext)
- try:
- # 尝试从items提取用户头像
- face_url = None
- for item in items:
- modules_raw = item.get("modules")
- if isinstance(modules_raw, dict):
- face_url = modules_raw.get("module_author", {}).get("face")
- elif isinstance(modules_raw, list):
- for mod in modules_raw:
- if isinstance(mod, dict) and mod.get("module_type") == "MODULE_TYPE_AUTHOR":
- face_url = mod.get("module_author", {}).get("user", {}).get("face") or mod.get("module_author", {}).get("face")
- if face_url:
- break
- if not face_url:
- face_url = item.get("user", {}).get("face")
- if face_url:
- break
-
- if face_url:
- # 若已存在头像文件则跳过
- host_dir = os.path.dirname(get_output_path("dynamic", str(host_mid), "__host_meta.json"))
- os.makedirs(host_dir, exist_ok=True)
-
- # 检查是否已有任何文件以 face.* 命名
- exists = any(
- name.lower().startswith("face.")
- for name in os.listdir(host_dir)
- if os.path.isfile(os.path.join(host_dir, name))
- )
- if not exists:
- # 下载头像一次
- results = await download_images([face_url], host_dir)
- # 将下载的哈希文件重命名为 face.扩展名
- for url, local_path, ok in results:
- if ok:
- _, ext = os.path.splitext(local_path)
- new_path = os.path.join(host_dir, f"face{ext}")
- try:
- if os.path.exists(new_path):
- os.remove(new_path)
- except Exception:
- pass
- try:
- os.replace(local_path, new_path)
- except Exception:
- pass
- break
- except Exception as e:
- logger.warning(f"保存头像失败(忽略):{e}")
-
- # 写 host_mid 元数据:最后一次获取的时间与offset
- try:
- import json, time
- host_dir = os.path.dirname(get_output_path("dynamic", str(host_mid), "__host_meta.json"))
- meta_path = os.path.join(host_dir, "__host_meta.json")
-
- last_offset_obj = {"offset": next_offset or "", "update_baseline": "", "update_num": 0}
- meta = {
- "host_mid": str(host_mid),
- "last_fetch_time": int(time.time()),
- "last_offset": last_offset_obj,
- "fully_fetched": False,
- }
-
- # 合并旧值(保留 fully_fetched 等状态)
- if os.path.exists(meta_path):
- try:
- with open(meta_path, "r", encoding="utf-8") as rf:
- old = json.load(rf)
- if isinstance(old, dict):
- meta.update({k: old.get(k, meta.get(k)) for k in ("fully_fetched",)})
- except Exception:
- pass
-
- async with aiofiles.open(meta_path, "w", encoding="utf-8") as wf:
- await wf.write(json.dumps(meta, ensure_ascii=False, indent=2))
- except Exception as e:
- logger.warning(f"写入 host_mid 元数据失败(忽略):{e}")
-
- for item in items:
- try:
- id_str = (
- item.get("id_str")
- or item.get("basic", {}).get("id_str")
- or str(item.get("id"))
- )
- if not id_str:
- # 跳过无法定位ID的记录
- continue
-
- # 检查是否有多媒体文件需要下载
- has_media = False
- predicted_locals = []
- live_predicted_locals = []
- if save_media:
- # 处理普通图片
- image_urls = collect_image_urls(item)
- if image_urls:
- has_media = True
- # 只有当包含多媒体文件时才创建文件夹
- item_dir = os.path.dirname(
- get_output_path("dynamic", str(host_mid), str(id_str), "media")
- )
- os.makedirs(item_dir, exist_ok=True)
-
- # 预测本地路径
- for u in image_urls:
- predicted_locals.append(os.path.relpath(predict_image_path(u, item_dir), base_output_dir))
-
- # 下载多媒体文件
- results = await download_images(image_urls, item_dir)
- media_records = []
- for media_url, local_path, ok in results:
- if ok:
- rel_path = os.path.relpath(local_path, base_output_dir)
- media_records.append((media_url, rel_path, "image"))
-
- # 处理实况媒体(live图片+视频)
- live_media_pairs = collect_live_media_urls(item)
- if live_media_pairs:
- has_media = True
- # 创建文件夹(如果还未创建)
- if not image_urls:
- item_dir = os.path.dirname(
- get_output_path("dynamic", str(host_mid), str(id_str), "media")
- )
- os.makedirs(item_dir, exist_ok=True)
-
- live_results = await download_live_media(live_media_pairs, item_dir)
- for image_url, video_url, image_path, video_path, ok in live_results:
- if ok:
- # 将实况媒体路径分别记录
- image_rel = os.path.relpath(image_path, base_output_dir)
- video_rel = os.path.relpath(video_path, base_output_dir)
- live_predicted_locals.extend([image_rel, video_rel])
-
- # 处理表情
- emoji_pairs = collect_emoji_urls(item)
- if emoji_pairs:
- has_media = True
- # 创建文件夹(如果还未创建)
- if not image_urls and not live_media_pairs:
- item_dir = os.path.dirname(
- get_output_path("dynamic", str(host_mid), str(id_str), "media")
- )
- os.makedirs(item_dir, exist_ok=True)
-
- emoji_results = await download_emojis(emoji_pairs, item_dir)
- for emoji_url, emoji_path, ok in emoji_results:
- if ok:
- # 将表情路径记录到普通媒体中
- emoji_rel = os.path.relpath(emoji_path, base_output_dir)
- predicted_locals.append(emoji_rel)
-
- # 规范化保存到数据库
- logger.info(f"normalize.core.call begin host_mid={host_mid} id_str={id_str}")
- try:
- save_normalized_dynamic_item(conn, host_mid, item)
- logger.info(f"normalize.core.call done host_mid={host_mid} id_str={id_str}")
- # 回写本地路径逗号串(只有当有多媒体文件时)
- if predicted_locals or live_predicted_locals:
- cursor = conn.cursor()
- cursor.execute(
- """
- UPDATE dynamic_core SET
- media_locals = CASE
- WHEN media_locals IS NULL OR media_locals = '' THEN ?
- ELSE media_locals
- END,
- live_media_locals = CASE
- WHEN live_media_locals IS NULL OR live_media_locals = '' THEN ?
- ELSE live_media_locals
- END,
- live_media_count = ?
- WHERE host_mid = ? AND id_str = ?
- """,
- (
- ",".join(predicted_locals) if predicted_locals else "",
- ",".join(live_predicted_locals) if live_predicted_locals else "",
- len(live_predicted_locals),
- str(host_mid),
- str(id_str),
- ),
- )
- conn.commit()
- except Exception as norm_err:
- logger.warning(f"规范化保存失败(忽略): {norm_err}")
- except Exception as perr:
- logger.error(f"保存动态项失败 id_str={item.get('id_str')}: {perr}")
-
- try:
- conn.close()
- except Exception:
- pass
-
- # 返回B站原始结构,合并所有items
- return {
- "code": 0,
- "message": "0",
- "ttl": 1,
- "data": {
- "has_more": bool(next_offset),
- "items": all_items,
- "offset": next_offset or "",
- "update_baseline": "",
- "update_num": 0
- }
- }
-
- except HTTPException:
- raise
- except Exception as e:
- logger.error(f"获取用户空间动态失败: {e}")
- raise HTTPException(status_code=500, detail=f"获取用户空间动态失败: {str(e)}")
-
-
-@router.get("/detail/{dynamic_id}", summary="获取动态详情")
-async def get_dynamic_detail(
- dynamic_id: str,
- save_to_db: bool = Query(True, description="是否保存到数据库"),
- save_media: bool = Query(True, description="是否保存图片等多媒体")
-):
- """
- 获取单条动态的详细信息
-
- Args:
- dynamic_id: 动态ID
- """
- try:
- api_url = "https://api.bilibili.com/x/polymer/web-dynamic/v1/detail"
-
- params = {
- "id": dynamic_id
- }
-
- logger.info(f"请求动态详情,ID: {dynamic_id}")
-
- data = await fetch_dynamic_data(api_url, params)
-
- if save_to_db:
- try:
- conn = get_connection()
- except Exception as e:
- logger.error(f"打开动态数据库失败: {e}")
- raise HTTPException(status_code=500, detail=f"打开动态数据库失败: {str(e)}")
-
- # detail 接口通常返回一个 item
- data_section = data.get("data", {}) if isinstance(data, dict) else {}
- item = data_section.get("item") or data_section.get("card") or data_section
-
- if isinstance(item, dict):
- try:
- id_str = (
- item.get("id_str")
- or item.get("basic", {}).get("id_str")
- or str(item.get("id") or dynamic_id)
- )
-
- # 尝试从作者信息解析 host_mid,失败则用 0
- host_mid_val = (
- item.get("modules", {})
- .get("module_author", {})
- .get("mid")
- )
- try:
- host_mid_int = int(host_mid_val) if host_mid_val is not None else 0
- except Exception:
- host_mid_int = 0
-
- # 检查是否有多媒体文件需要下载
- base_output_dir = os.path.dirname(get_output_path("__base__"))
- has_media = False
- predicted_locals = []
- live_predicted_locals = []
- if save_media:
- # 处理普通图片
- image_urls = collect_image_urls(item)
- if image_urls:
- has_media = True
- # 只有当包含多媒体文件时才创建文件夹
- item_dir = os.path.dirname(
- get_output_path("dynamic", str(host_mid_int), str(id_str), "media")
- )
- os.makedirs(item_dir, exist_ok=True)
-
- # 预测本地路径
- for u in image_urls:
- predicted_locals.append(os.path.relpath(predict_image_path(u, item_dir), base_output_dir))
-
- # 下载多媒体文件
- results = await download_images(image_urls, item_dir)
- media_records = []
- for media_url, local_path, ok in results:
- if ok:
- rel_path = os.path.relpath(local_path, base_output_dir)
- media_records.append((media_url, rel_path, "image"))
-
- # 处理实况媒体(live图片+视频)
- live_media_pairs = collect_live_media_urls(item)
- if live_media_pairs:
- has_media = True
- # 创建文件夹(如果还未创建)
- if not image_urls:
- item_dir = os.path.dirname(
- get_output_path("dynamic", str(host_mid_int), str(id_str), "media")
- )
- os.makedirs(item_dir, exist_ok=True)
-
- live_results = await download_live_media(live_media_pairs, item_dir)
- for image_url, video_url, image_path, video_path, ok in live_results:
- if ok:
- # 将实况媒体路径分别记录
- image_rel = os.path.relpath(image_path, base_output_dir)
- video_rel = os.path.relpath(video_path, base_output_dir)
- live_predicted_locals.extend([image_rel, video_rel])
-
- # 处理表情
- emoji_pairs = collect_emoji_urls(item)
- if emoji_pairs:
- has_media = True
- # 创建文件夹(如果还未创建)
- if not image_urls and not live_media_pairs:
- item_dir = os.path.dirname(
- get_output_path("dynamic", str(host_mid_int), str(id_str), "media")
- )
- os.makedirs(item_dir, exist_ok=True)
-
- emoji_results = await download_emojis(emoji_pairs, item_dir)
- for emoji_url, emoji_path, ok in emoji_results:
- if ok:
- # 将表情路径记录到普通媒体中
- emoji_rel = os.path.relpath(emoji_path, base_output_dir)
- predicted_locals.append(emoji_rel)
-
- # 保存头像一次(若存在)
- try:
- face_url = None
- modules_raw = item.get("modules")
- if isinstance(modules_raw, dict):
- face_url = modules_raw.get("module_author", {}).get("face")
- elif isinstance(modules_raw, list):
- for mod in modules_raw:
- if isinstance(mod, dict) and mod.get("module_type") == "MODULE_TYPE_AUTHOR":
- face_url = mod.get("module_author", {}).get("user", {}).get("face") or mod.get("module_author", {}).get("face")
- if face_url:
- break
- if not face_url:
- face_url = item.get("user", {}).get("face")
- if face_url and host_mid_int:
- host_dir = os.path.dirname(get_output_path("dynamic", str(host_mid_int), "__host_meta.json"))
- os.makedirs(host_dir, exist_ok=True)
- exists = any(
- name.lower().startswith("face.")
- for name in os.listdir(host_dir)
- if os.path.isfile(os.path.join(host_dir, name))
- )
- if not exists:
- results = await download_images([face_url], host_dir)
- for media_url, local_path, ok in results:
- if ok:
- _, ext = os.path.splitext(local_path)
- new_path = os.path.join(host_dir, f"face{ext}")
- try:
- if os.path.exists(new_path):
- os.remove(new_path)
- except Exception:
- pass
- try:
- os.replace(local_path, new_path)
- except Exception:
- pass
- break
- except Exception as e:
- logger.warning(f"保存头像失败(忽略):{e}")
-
- # 规范化保存 + 回写预测路径(逗号分隔)
- try:
- save_normalized_dynamic_item(conn, host_mid_int, item)
- if predicted_locals or live_predicted_locals:
- cursor = conn.cursor()
- cursor.execute(
- """
- UPDATE dynamic_core SET
- media_locals = CASE
- WHEN media_locals IS NULL OR media_locals = '' THEN ?
- ELSE media_locals
- END,
- live_media_locals = CASE
- WHEN live_media_locals IS NULL OR live_media_locals = '' THEN ?
- ELSE live_media_locals
- END,
- live_media_count = ?
- WHERE host_mid = ? AND id_str = ?
- """,
- (
- ",".join(predicted_locals) if predicted_locals else "",
- ",".join(live_predicted_locals) if live_predicted_locals else "",
- len(live_predicted_locals),
- str(host_mid_int),
- str(id_str),
- ),
- )
- conn.commit()
- except Exception as norm_err:
- logger.warning(f"规范化保存失败(忽略): {norm_err}")
- except Exception as perr:
- logger.error(f"保存动态详情失败 dynamic_id={dynamic_id}: {perr}")
-
- try:
- conn.close()
- except Exception:
- pass
-
- # 直接返回B站API的原始响应数据
- return data
-
- except HTTPException:
- raise
- except Exception as e:
- logger.error(f"获取动态详情失败: {e}")
- raise HTTPException(status_code=500, detail=f"获取动态详情失败: {str(e)}")
-
-
-@router.get("/types", summary="获取动态类型说明")
-async def get_dynamic_types():
- """
- 获取动态类型的说明信息
- """
- dynamic_types = {
- "DYNAMIC_TYPE_NONE": "无类型",
- "DYNAMIC_TYPE_FORWARD": "转发动态",
- "DYNAMIC_TYPE_AV": "视频动态",
- "DYNAMIC_TYPE_PGC": "番剧/影视动态",
- "DYNAMIC_TYPE_COURSES": "课程动态",
- "DYNAMIC_TYPE_WORD": "文字动态",
- "DYNAMIC_TYPE_DRAW": "图片动态",
- "DYNAMIC_TYPE_ARTICLE": "文章动态",
- "DYNAMIC_TYPE_MUSIC": "音频动态",
- "DYNAMIC_TYPE_COMMON_SQUARE": "普通方形动态",
- "DYNAMIC_TYPE_COMMON_VERTICAL": "普通竖版动态",
- "DYNAMIC_TYPE_LIVE": "直播动态",
- "DYNAMIC_TYPE_MEDIALIST": "收藏夹动态",
- "DYNAMIC_TYPE_COURSES_SEASON": "课程合集动态",
- "DYNAMIC_TYPE_COURSES_BATCH": "课程批次动态",
- "DYNAMIC_TYPE_AD": "广告动态",
- "DYNAMIC_TYPE_APPLET": "小程序动态",
- "DYNAMIC_TYPE_SUBSCRIPTION": "订阅动态",
- "DYNAMIC_TYPE_LIVE_RCMD": "直播推荐动态",
- "DYNAMIC_TYPE_BANNER": "横幅动态",
- "DYNAMIC_TYPE_UGC_SEASON": "合集动态",
- "DYNAMIC_TYPE_SUBSCRIPTION_NEW": "新订阅动态"
- }
-
- return {"types": dynamic_types}
-
-
-@router.delete("/space/{host_mid}", summary="删除指定UP的动态数据(文件+数据库)")
-async def delete_space_data(host_mid: int) -> Dict[str, Any]:
- """
- 删除指定 host_mid 的本地动态数据目录以及数据库中所有关联记录。
- - 文件夹: output/dynamic/{host_mid}
- - 数据库表: dynamic_core / dynamic_author / dynamic_stat / dynamic_topic / major_opus_pics / major_archive_jump_urls
- """
- # 发送停止信号(若存在正在抓取的任务,页级停止)
- try:
- ev = _get_or_create_event(host_mid)
- ev.set()
- except Exception as e:
- logger.warning(f"[purge] 发送停止信号失败(忽略) host_mid={host_mid}: {e}")
-
- # 定位并删除文件夹
- dir_path: Optional[str] = None
- dir_existed = False
- dir_deleted = False
- try:
- dir_path = os.path.dirname(get_output_path("dynamic", str(host_mid), "__host_meta.json"))
- dir_existed = os.path.isdir(dir_path)
- if dir_existed:
- shutil.rmtree(dir_path, ignore_errors=True)
- dir_deleted = not os.path.exists(dir_path)
- except Exception as e:
- logger.error(f"[purge] 删除目录失败 host_mid={host_mid}: {e}")
-
- # 删除数据库记录
- try:
- conn = get_connection()
- except Exception as e:
- logger.error(f"[purge] 打开动态数据库失败: {e}")
- raise HTTPException(status_code=500, detail=f"打开动态数据库失败: {str(e)}")
-
- try:
- db_stats = purge_host(conn, host_mid)
- finally:
- try:
- conn.close()
- except Exception:
- pass
-
- return {
- "host_mid": str(host_mid),
- "dir": {
- "path": dir_path,
- "existed": dir_existed,
- "deleted": dir_deleted,
- },
- "db_deleted": db_stats,
- }
\ No newline at end of file
diff --git a/routers/email_config.py b/routers/email_config.py
deleted file mode 100644
index 83d8a74..0000000
--- a/routers/email_config.py
+++ /dev/null
@@ -1,410 +0,0 @@
-from typing import Any, Optional
-from fastapi import APIRouter, Body, HTTPException, Request
-from pydantic import BaseModel, EmailStr
-import yaml
-import os
-import re
-from scripts.utils import load_config
-from scripts.send_log_email import send_email
-
-router = APIRouter()
-
-def get_config_path():
- """获取配置文件路径"""
- base_dir = os.path.dirname(os.path.dirname(os.path.abspath(__file__)))
- return os.path.join(base_dir, 'config', 'config.yaml')
-
-def get_mcp_skill_path():
- """获取MCP配套skill文件路径"""
- base_dir = os.path.dirname(os.path.dirname(os.path.abspath(__file__)))
- return os.path.join(base_dir, 'skills', 'bilibili-history-mcp', 'SKILL.md')
-
-def update_yaml_field(content: str, field_path: list, new_value: Optional[str]) -> str:
- """
- 更新YAML文件中特定字段的值,保持其他内容不变
-
- Args:
- content: YAML文件内容
- field_path: 字段路径,如 ['email', 'smtp_server']
- new_value: 新的值,如果为None则删除该字段
- """
- # 构建YAML路径的正则表达式
- indent = ' ' * (2 * (len(field_path) - 1)) # YAML标准缩进
- field = field_path[-1]
- pattern = f"^{indent}{re.escape(field)}:.*$"
-
- # 处理多行内容
- lines = content.split('\n')
- for i, line in enumerate(lines):
- if re.match(pattern, line, re.MULTILINE):
- if new_value is None or new_value == "":
- lines[i] = f"{indent}{field}:" # 设置为空值
- else:
- lines[i] = f"{indent}{field}: {new_value}"
- break
- else:
- # 如果字段不存在且传入了有效值,则插入到父级 YAML 节点末尾。
- # 这用于为旧配置文件补充新增字段,例如 email.auth_username。
- if new_value is None or new_value == "":
- return content
-
- new_line = f"{indent}{field}: {new_value}"
-
- if len(field_path) == 1:
- lines.append(new_line)
- else:
- parent_indent = ' ' * (2 * (len(field_path) - 2))
- parent_field = field_path[-2]
- parent_pattern = f"^{parent_indent}{re.escape(parent_field)}:.*$"
-
- for parent_index, line in enumerate(lines):
- if re.match(parent_pattern, line, re.MULTILINE):
- insert_index = parent_index + 1
- while insert_index < len(lines):
- current_line = lines[insert_index]
- if current_line.strip() == "":
- break
- current_indent = len(current_line) - len(current_line.lstrip(' '))
- if current_indent <= len(parent_indent):
- break
- insert_index += 1
- lines.insert(insert_index, new_line)
- break
- else:
- lines.append(new_line)
-
- return '\n'.join(lines)
-
-class EmailConfig(BaseModel):
- """邮件配置模型"""
- smtp_server: Optional[str] = None
- smtp_port: Optional[int] = None
- sender: Optional[EmailStr] = None
- auth_username: Optional[str] = None
- password: Optional[str] = None
- receiver: Optional[EmailStr] = None
-
-class TestEmailRequest(BaseModel):
- """测试邮件请求模型"""
- to_email: Optional[EmailStr] = None # 可选,如果为空则使用配置中的接收者邮箱
- subject: str = "测试邮件"
- content: str = "这是一封测试邮件,用于验证邮箱配置是否有效。"
-
-class McpConfigUpdate(BaseModel):
- """MCP配置更新模型"""
- enabled: bool
-
-def normalize_mcp_path(path: Optional[str]) -> str:
- """规范化MCP挂载路径"""
- normalized = (path or "/mcp").strip()
- if not normalized.startswith("/"):
- normalized = f"/{normalized}"
- if len(normalized) > 1:
- normalized = normalized.rstrip("/")
- return normalized or "/mcp"
-
-def build_server_url(request: Request, server_config: dict[str, Any]) -> str:
- """优先使用当前请求来源生成客户端可访问地址。"""
- request_origin = str(request.base_url).rstrip("/")
- if request_origin:
- return request_origin
-
- scheme = "https" if server_config.get("ssl_enabled") else "http"
- host = server_config.get("host") or "127.0.0.1"
- if host in {"0.0.0.0", "::", "[::]"}:
- host = "127.0.0.1"
-
- port = int(server_config.get("port", 8899))
- if ":" in host and not host.startswith("["):
- host = f"[{host}]"
- return f"{scheme}://{host}:{port}"
-
-def build_mcp_config_response(
- config: dict[str, Any],
- request: Request,
- restart_required: bool = False
-) -> dict[str, Any]:
- """构造前端设置页需要的MCP配置。"""
- server_config = config.get("server", {}) or {}
- mcp_config = server_config.get("mcp", {}) or {}
- path = normalize_mcp_path(mcp_config.get("path", "/mcp"))
- server_url = build_server_url(request, server_config)
- mcp_url = f"{server_url}{path if path == '/' else path + '/'}"
- token = os.environ.get("BHF_MCP_TOKEN") or mcp_config.get("token")
- skill_content = ""
- skill_path = get_mcp_skill_path()
- if os.path.exists(skill_path):
- with open(skill_path, 'r', encoding='utf-8') as f:
- skill_content = f.read()
-
- return {
- "status": "success",
- "enabled": bool(mcp_config.get("enabled", False)),
- "path": path,
- "auth_enabled": bool(mcp_config.get("auth_enabled", True)),
- "token": token or "",
- "token_configured": bool(token),
- "max_page_size": int(mcp_config.get("max_page_size", 100)),
- "server_url": server_url,
- "mcp_url": mcp_url,
- "skill_content": skill_content,
- "restart_required": restart_required
- }
-
-def get_line_indent(line: str) -> int:
- """获取YAML行缩进宽度。"""
- return len(line) - len(line.lstrip(" "))
-
-def is_yaml_key(line: str, key: str, indent: Optional[int] = None) -> bool:
- """判断某行是否为指定缩进层级的YAML键。"""
- stripped = line.strip()
- if not stripped or stripped.startswith("#"):
- return False
- if indent is not None and get_line_indent(line) != indent:
- return False
- return bool(re.match(rf"^{re.escape(key)}\s*:", stripped))
-
-def find_block_end(lines: list[str], start_index: int, parent_indent: int) -> int:
- """查找YAML块结束位置,返回可插入的行下标。"""
- for index in range(start_index + 1, len(lines)):
- stripped = lines[index].strip()
- if stripped and get_line_indent(lines[index]) <= parent_indent:
- return index
- return len(lines)
-
-def update_mcp_enabled_field(content: str, enabled: bool) -> str:
- """只更新server.mcp.enabled,尽量保持配置文件其他内容不变。"""
- enabled_value = str(enabled).lower()
- lines = content.split("\n")
-
- server_index = next((i for i, line in enumerate(lines) if is_yaml_key(line, "server", 0)), None)
- if server_index is None:
- if lines and lines[-1].strip():
- lines.append("")
- lines.extend(["server:", " mcp:", f" enabled: {enabled_value}"])
- return "\n".join(lines)
-
- server_indent = get_line_indent(lines[server_index])
- server_end = find_block_end(lines, server_index, server_indent)
- mcp_indent = server_indent + 2
- enabled_indent = mcp_indent + 2
-
- mcp_index = next(
- (i for i in range(server_index + 1, server_end) if is_yaml_key(lines[i], "mcp", mcp_indent)),
- None
- )
- if mcp_index is None:
- lines.insert(server_end, f"{' ' * mcp_indent}mcp:")
- lines.insert(server_end + 1, f"{' ' * enabled_indent}enabled: {enabled_value}")
- return "\n".join(lines)
-
- mcp_end = find_block_end(lines, mcp_index, mcp_indent)
- enabled_index = next(
- (i for i in range(mcp_index + 1, mcp_end) if is_yaml_key(lines[i], "enabled", enabled_indent)),
- None
- )
- if enabled_index is None:
- lines.insert(mcp_index + 1, f"{' ' * enabled_indent}enabled: {enabled_value}")
- else:
- current_indent = lines[enabled_index][:get_line_indent(lines[enabled_index])]
- lines[enabled_index] = f"{current_indent}enabled: {enabled_value}"
-
- return "\n".join(lines)
-
-@router.get("/email-config", summary="获取邮件配置")
-async def get_email_config():
- """获取当前邮件配置"""
- try:
- config = load_config()
- email_config = config.get('email', {})
- return {
- "smtp_server": email_config.get('smtp_server'),
- "smtp_port": email_config.get('smtp_port'),
- "sender": email_config.get('sender'),
- "auth_username": email_config.get('auth_username') or email_config.get('username'),
- "receiver": email_config.get('receiver'),
- "password": email_config.get('password') # 返回明文密码
- }
- except Exception as e:
- raise HTTPException(
- status_code=500,
- detail=f"获取邮件配置失败: {str(e)}"
- )
-
-@router.post("/email-config", summary="更新邮件配置")
-async def update_email_config(
- request: Request,
- smtp_server: Optional[str] = Body(default=...),
- smtp_port: Optional[int] = Body(default=...),
- sender: Optional[str] = Body(default=...), # 改为str类型以接受空字符串
- auth_username: Optional[str] = Body(default=None),
- password: Optional[str] = Body(default=...),
- receiver: Optional[str] = Body(default=...) # 改为str类型以接受空字符串
-):
- """
- 更新邮件配置
-
- - **smtp_server**: SMTP服务器地址,可以为空
- - **smtp_port**: SMTP服务器端口,可以为空
- - **sender**: 发件人邮箱,可以为空
- - **auth_username**: SMTP认证用户名,可选;为空则使用发件人邮箱
- - **password**: 邮箱授权码,可以为空
- - **receiver**: 收件人邮箱,可以为空
- """
- try:
- request_body = await request.json()
-
- # 读取当前配置文件内容
- config_path = get_config_path()
- with open(config_path, 'r', encoding='utf-8') as f:
- content = f.read()
- config = yaml.safe_load(content) # 仅用于获取当前配置
-
- # 获取当前邮件配置
- email_config = config.get('email', {})
-
- # 逐个更新配置字段
- if smtp_server is not ...: # 检查是否提供了该参数
- value = f'"{smtp_server}"' if smtp_server else None
- content = update_yaml_field(content, ['email', 'smtp_server'], value)
- email_config['smtp_server'] = smtp_server
-
- if smtp_port is not ...:
- value = str(smtp_port) if smtp_port is not None else None
- content = update_yaml_field(content, ['email', 'smtp_port'], value)
- email_config['smtp_port'] = smtp_port
-
- if sender is not ...:
- value = f'"{sender}"' if sender else None
- content = update_yaml_field(content, ['email', 'sender'], value)
- email_config['sender'] = sender
-
- if 'auth_username' in request_body:
- value = f'"{auth_username}"' if auth_username else None
- content = update_yaml_field(content, ['email', 'auth_username'], value)
- email_config['auth_username'] = auth_username
-
- if password is not ...:
- value = f'"{password}"' if password else None
- content = update_yaml_field(content, ['email', 'password'], value)
- email_config['password'] = password
-
- if receiver is not ...:
- value = f'"{receiver}"' if receiver else None
- content = update_yaml_field(content, ['email', 'receiver'], value)
- email_config['receiver'] = receiver
-
- # 写回配置文件
- with open(config_path, 'w', encoding='utf-8') as f:
- f.write(content)
-
- return {
- "status": "success",
- "message": "邮件配置更新成功",
- "config": {
- "smtp_server": email_config.get('smtp_server'),
- "smtp_port": email_config.get('smtp_port'),
- "sender": email_config.get('sender'),
- "auth_username": email_config.get('auth_username') or email_config.get('username'),
- "receiver": email_config.get('receiver'),
- "password": email_config.get('password') # 返回明文密码
- }
- }
- except Exception as e:
- raise HTTPException(
- status_code=500,
- detail=f"更新邮件配置失败: {str(e)}"
- )
-
-@router.post("/test-email", summary="发送测试邮件")
-async def send_test_email(request: TestEmailRequest):
- """
- 发送测试邮件以验证邮箱配置是否有效
-
- - **to_email**: 收件人邮箱,可选,如果为空则使用配置中的收件人
- - **subject**: 邮件主题,默认为"测试邮件"
- - **content**: 邮件内容,默认为"这是一封测试邮件,用于验证邮箱配置是否有效。"
-
- 返回:
- - **status**: 发送状态,"success"或"error"
- - **message**: 状态描述信息
- """
- try:
- # 获取当前邮件配置
- config = load_config()
- email_config = config.get('email', {})
-
- # 检查邮件配置是否完整
- if not all([
- email_config.get('smtp_server'),
- email_config.get('smtp_port'),
- email_config.get('sender'),
- email_config.get('password'),
- request.to_email or email_config.get('receiver')
- ]):
- raise ValueError("邮件配置不完整,请先完善邮件配置")
-
- # 发送测试邮件
- result = await send_email(
- subject=request.subject,
- content=request.content,
- to_email=request.to_email
- )
-
- return result
-
- except ValueError as e:
- raise HTTPException(
- status_code=400,
- detail=str(e)
- )
- except Exception as e:
- raise HTTPException(
- status_code=500,
- detail=f"发送测试邮件失败: {str(e)}"
- )
-
-@router.get("/mcp-config", summary="获取MCP配置")
-async def get_mcp_config(request: Request):
- """获取当前MCP配置,供前端设置页生成连接提示词。"""
- try:
- config = load_config()
- return build_mcp_config_response(config, request)
- except Exception as e:
- raise HTTPException(
- status_code=500,
- detail=f"获取MCP配置失败: {str(e)}"
- )
-
-@router.post("/mcp-config", summary="更新MCP开关配置")
-async def update_mcp_config(request_data: McpConfigUpdate, request: Request):
- """
- 更新MCP启用状态。
-
- MCP请求会实时读取配置,因此开关保存后立即生效。
- """
- try:
- config_path = get_config_path()
- with open(config_path, 'r', encoding='utf-8') as f:
- content = f.read()
- config = yaml.safe_load(content) or {}
-
- server_config = config.setdefault("server", {})
- mcp_config = server_config.setdefault("mcp", {})
- updated_content = update_mcp_enabled_field(content, request_data.enabled)
- with open(config_path, 'w', encoding='utf-8') as f:
- f.write(updated_content)
-
- mcp_config["enabled"] = request_data.enabled
- response = build_mcp_config_response(
- config,
- request,
- restart_required=False
- )
- response["message"] = "MCP配置已更新"
- return response
- except Exception as e:
- raise HTTPException(
- status_code=500,
- detail=f"更新MCP配置失败: {str(e)}"
- )
diff --git a/routers/export.py b/routers/export.py
deleted file mode 100644
index 3ac3add..0000000
--- a/routers/export.py
+++ /dev/null
@@ -1,143 +0,0 @@
-from fastapi import APIRouter, HTTPException, Query
-from fastapi.responses import FileResponse
-from scripts.export_to_excel import export_bilibili_history
-from scripts.utils import get_output_path, load_config
-from typing import Dict, Any
-import os
-from datetime import datetime
-
-router = APIRouter()
-config = load_config()
-
-@router.post(
- "/export_history",
- summary="导出Bilibili历史记录到Excel",
- response_model=Dict[str, Any],
- description="将历史记录数据导出为Excel文件,支持按年份、月份或日期范围导出数据"
-)
-def export_history(
- year: int = Query(None, description="要导出的年份,不指定则使用当前年份"),
- month: int = Query(None, description="要导出的月份(1-12),如果指定则只导出该月数据", ge=1, le=12),
- start_date: str = Query(None, description="开始日期,格式为'YYYY-MM-DD',如果指定则从该日期开始导出"),
- end_date: str = Query(None, description="结束日期,格式为'YYYY-MM-DD',如果指定则导出到该日期为止")
-):
- """
- 导出Bilibili历史记录到Excel文件。
-
- Args:
- year: 要导出的年份,不指定则使用当前年份
- month: 要导出的月份(1-12),如果指定则只导出该月数据
- start_date: 开始日期,格式为'YYYY-MM-DD',如果指定则从该日期开始导出
- end_date: 结束日期,格式为'YYYY-MM-DD',如果指定则导出到该日期为止
-
- Returns:
- Dict[str, Any]: 包含状态和消息的响应
- """
- # 验证日期格式
- if start_date:
- try:
- datetime.strptime(start_date, '%Y-%m-%d')
- except ValueError:
- raise HTTPException(status_code=400, detail="开始日期格式错误,应为'YYYY-MM-DD'")
-
- if end_date:
- try:
- datetime.strptime(end_date, '%Y-%m-%d')
- except ValueError:
- raise HTTPException(status_code=400, detail="结束日期格式错误,应为'YYYY-MM-DD'")
-
- result = export_bilibili_history(year, month, start_date, end_date)
-
- if result["status"] == "success":
- # 返回文件名信息,便于前端下载
- filename = os.path.basename(result["message"].split("数据已成功导出到 ")[-1])
- return {"status": "success", "message": result["message"], "filename": filename}
- else:
- raise HTTPException(status_code=500, detail=result["message"])
-
-@router.get(
- "/download_excel/{filename}",
- summary="下载Excel文件",
- description="下载指定的Excel文件,支持浏览器直接下载",
- response_class=FileResponse,
- responses={
- 200: {
- "description": "Excel文件",
- "content": {
- "application/vnd.openxmlformats-officedocument.spreadsheetml.sheet": {
- "schema": {"type": "string", "format": "binary"}
- }
- }
- },
- 404: {
- "description": "文件不存在",
- "content": {
- "application/json": {
- "example": {"detail": "未找到指定的Excel文件"}
- }
- }
- }
- }
-)
-def download_excel(filename: str):
- """
- 下载指定的Excel文件。
-
- Args:
- filename: 要下载的文件名
-
- Returns:
- FileResponse: Excel文件响应
- """
- file_path = get_output_path(filename)
-
- if not os.path.exists(file_path):
- raise HTTPException(status_code=404, detail=f"未找到文件 {filename}")
-
- return FileResponse(
- path=file_path,
- filename=filename,
- media_type="application/vnd.openxmlformats-officedocument.spreadsheetml.sheet"
- )
-
-@router.get(
- "/download_db",
- summary="下载SQLite数据库",
- description="下载完整的SQLite数据库文件,包含所有年份的历史记录数据",
- response_class=FileResponse,
- responses={
- 200: {
- "description": "SQLite数据库文件",
- "content": {
- "application/x-sqlite3": {
- "schema": {"type": "string", "format": "binary"}
- }
- }
- },
- 404: {
- "description": "文件不存在",
- "content": {
- "application/json": {
- "example": {"detail": "数据库文件不存在"}
- }
- }
- }
- }
-)
-def download_db():
- """
- 下载完整的SQLite数据库文件。
-
- Returns:
- FileResponse: 数据库文件响应
- """
- db_path = get_output_path(config['db_file'])
-
- if not os.path.exists(db_path):
- raise HTTPException(status_code=404, detail="数据库文件不存在")
-
- return FileResponse(
- path=db_path,
- filename="bilibili_history.db",
- media_type="application/x-sqlite3"
- )
diff --git a/routers/favorite.py b/routers/favorite.py
deleted file mode 100644
index ed284e6..0000000
--- a/routers/favorite.py
+++ /dev/null
@@ -1,1475 +0,0 @@
-import os
-import sqlite3
-import time
-from datetime import datetime
-from typing import Optional, List, Dict, Any
-
-import requests
-from fastapi import APIRouter, Query
-from pydantic import BaseModel, Field
-
-from scripts.utils import load_config
-
-router = APIRouter()
-config = load_config()
-
-# 数据库路径 - 存储在output/database目录下
-DB_PATH = os.path.join("output", "database", "bilibili_favorites.db")
-
-# 确保目录存在
-os.makedirs(os.path.dirname(DB_PATH), exist_ok=True)
-
-# 数据库表创建语句
-CREATE_FAVORITES_FOLDER_TABLE = """
-CREATE TABLE IF NOT EXISTS favorites_folder (
- id INTEGER PRIMARY KEY,
- media_id INTEGER NOT NULL,
- fid INTEGER NOT NULL,
- mid INTEGER NOT NULL,
- title TEXT NOT NULL,
- cover TEXT,
- attr INTEGER,
- intro TEXT,
- ctime INTEGER,
- mtime INTEGER,
- state INTEGER,
- media_count INTEGER,
- fav_state INTEGER,
- like_state INTEGER,
- fetch_time INTEGER,
- UNIQUE(media_id)
-);
-"""
-
-CREATE_FAVORITES_CREATOR_TABLE = """
-CREATE TABLE IF NOT EXISTS favorites_creator (
- mid INTEGER PRIMARY KEY,
- name TEXT NOT NULL,
- face TEXT,
- followed INTEGER,
- vip_type INTEGER,
- vip_status INTEGER,
- fetch_time INTEGER
-);
-"""
-
-CREATE_FAVORITES_CONTENT_TABLE = """
-CREATE TABLE IF NOT EXISTS favorites_content (
- id INTEGER PRIMARY KEY,
- media_id INTEGER NOT NULL,
- content_id INTEGER NOT NULL,
- type INTEGER NOT NULL,
- title TEXT NOT NULL,
- cover TEXT,
- bvid TEXT,
- intro TEXT,
- page INTEGER,
- duration INTEGER,
- upper_mid INTEGER,
- attr INTEGER,
- ctime INTEGER,
- pubtime INTEGER,
- fav_time INTEGER,
- link TEXT,
- fetch_time INTEGER,
- creator_name TEXT,
- creator_face TEXT,
- bv_id TEXT,
- collect INTEGER,
- play INTEGER,
- danmaku INTEGER,
- play_switch INTEGER,
- reply INTEGER,
- view_text_1 TEXT,
- first_cid INTEGER,
- media_list_link TEXT,
- UNIQUE(media_id, content_id)
-);
-"""
-
-CREATE_INDEXES = [
- "CREATE INDEX IF NOT EXISTS idx_favorites_folder_mid ON favorites_folder (mid);",
- "CREATE INDEX IF NOT EXISTS idx_favorites_folder_mtime ON favorites_folder (mtime);",
- "CREATE INDEX IF NOT EXISTS idx_favorites_content_media_id ON favorites_content (media_id);",
- "CREATE INDEX IF NOT EXISTS idx_favorites_content_upper_mid ON favorites_content (upper_mid);",
- "CREATE INDEX IF NOT EXISTS idx_favorites_content_fav_time ON favorites_content (fav_time);"
-]
-
-# 数据模型
-class FolderMetadata(BaseModel):
- id: int
- fid: int
- mid: int
- attr: Optional[int] = None
- title: str
- cover: Optional[str] = None
- upper: Dict[str, Any]
- cover_type: Optional[int] = None
- cnt_info: Dict[str, int]
- type: Optional[int] = None
- intro: Optional[str] = None
- ctime: int
- mtime: int
- state: Optional[int] = None
- fav_state: Optional[int] = None
- like_state: Optional[int] = None
- media_count: int
-
-class FavoriteContent(BaseModel):
- id: int
- type: int
- title: str
- cover: Optional[str] = None
- bvid: Optional[str] = None
- bv_id: Optional[str] = None
- intro: Optional[str] = None
- page: Optional[int] = None
- duration: Optional[int] = None
- upper: Dict[str, Any]
- attr: Optional[int] = None
- cnt_info: Dict[str, int]
- link: Optional[str] = None
- ctime: Optional[int] = None
- pubtime: Optional[int] = None
- fav_time: Optional[int] = None
- season: Optional[Any] = None
-
-def get_headers(sessdata=None):
- """获取请求头"""
- # 如果未提供SESSDATA,尝试从配置中获取
- if sessdata is None:
- current_config = load_config()
- sessdata = current_config.get("SESSDATA", "")
-
- headers = {
- "User-Agent": "Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/91.0.4472.124 Safari/537.36",
- "Referer": "https://www.bilibili.com/",
- }
-
- # 构建完整Cookie字符串
- cookies = []
- if sessdata:
- cookies.append(f"SESSDATA={sessdata}")
-
- # 如果配置中有bili_jct,也添加到Cookie中
- current_config = load_config()
- bili_jct = current_config.get("bili_jct", "")
- if bili_jct:
- cookies.append(f"bili_jct={bili_jct}")
-
- # 如果配置中有DedeUserID,也添加到Cookie中
- dede_user_id = current_config.get("DedeUserID", "")
- if dede_user_id:
- cookies.append(f"DedeUserID={dede_user_id}")
-
- # 如果配置中有DedeUserID__ckMd5,也添加到Cookie中
- dede_user_id_ckmd5 = current_config.get("DedeUserID__ckMd5", "")
- if dede_user_id_ckmd5:
- cookies.append(f"DedeUserID__ckMd5={dede_user_id_ckmd5}")
-
- # 将所有Cookie合并为一个字符串
- if cookies:
- headers["Cookie"] = "; ".join(cookies)
-
- return headers
-
-async def get_current_user_info(sessdata=None):
- """获取当前登录用户信息"""
- try:
- headers = get_headers(sessdata)
-
- # 使用B站官方API获取用户信息
- response = requests.get("https://api.bilibili.com/x/web-interface/nav", headers=headers)
- data = response.json()
-
- if data.get("code") == 0 and data.get("data", {}).get("isLogin"):
- user_data = data.get("data", {})
- return {
- "uid": user_data.get("mid"),
- "uname": user_data.get("uname"),
- "level": user_data.get("level_info", {}).get("current_level")
- }
- return None
- except Exception as e:
- print(f"获取用户信息时出错: {str(e)}")
- return None
-
-def get_db_connection():
- """获取数据库连接"""
- # 确保数据库目录存在
- os.makedirs(os.path.dirname(DB_PATH), exist_ok=True)
-
- conn = sqlite3.connect(DB_PATH)
- conn.row_factory = sqlite3.Row
-
- # 创建表和索引
- cursor = conn.cursor()
- cursor.execute(CREATE_FAVORITES_FOLDER_TABLE)
- cursor.execute(CREATE_FAVORITES_CREATOR_TABLE)
- cursor.execute(CREATE_FAVORITES_CONTENT_TABLE)
-
- for index_sql in CREATE_INDEXES:
- cursor.execute(index_sql)
-
- conn.commit()
- return conn
-
-def save_json_response(data, prefix, identifier):
- """不再保存JSON响应到文件,直接返回数据"""
- # 保留此函数是为了保持代码兼容性,但不再执行实际的保存操作
- return None
-
-@router.get("/folder/created/list-all", summary="获取指定用户创建的所有收藏夹信息")
-async def get_created_folders(
- up_mid: Optional[int] = Query(None, description="目标用户mid,不提供则使用当前登录用户"),
- type: int = Query(0, description="目标内容属性,0=全部,2=视频稿件"),
- rid: Optional[int] = Query(None, description="目标内容id,视频稿件为avid"),
- sessdata: Optional[str] = Query(None, description="用户的 SESSDATA")
-):
- """
- 获取指定用户创建的所有收藏夹信息
-
- 需要用户登录才能查看私密收藏夹
- """
- try:
- # 如果未提供up_mid,获取当前登录用户的UID
- if up_mid is None:
- user_info = await get_current_user_info(sessdata)
- if user_info is None:
- return {
- "status": "error",
- "message": "未提供up_mid且未登录,无法获取收藏夹信息"
- }
- up_mid = user_info.get("uid")
- print(f"使用当前登录用户UID: {up_mid}")
-
- url = "https://api.bilibili.com/x/v3/fav/folder/created/list-all"
- params = {"up_mid": up_mid, "type": type}
- if rid is not None:
- params["rid"] = rid
-
- headers = get_headers(sessdata)
-
- response = requests.get(url, params=params, headers=headers)
- data = response.json()
-
- # 检查API响应
- if data.get('code') != 0:
- return {
- "status": "error",
- "message": data.get('message', '未知错误'),
- "code": data.get('code')
- }
-
- folders_data = data.get('data', {})
-
- # 保存到数据库
- conn = get_db_connection()
- try:
- cursor = conn.cursor()
- timestamp = int(time.time())
-
- # 遍历所有收藏夹
- for folder in folders_data.get('list', []):
- # 保存创建者信息
- upper = folder.get('upper', {})
- if upper and 'mid' in upper:
- cursor.execute("""
- INSERT OR REPLACE INTO favorites_creator
- (mid, name, face, followed, vip_type, vip_status, fetch_time)
- VALUES (?, ?, ?, ?, ?, ?, ?)
- """, (
- upper.get('mid'),
- upper.get('name', ''),
- upper.get('face', ''),
- 1 if upper.get('followed') else 0,
- upper.get('vip_type', 0),
- upper.get('vip_statue', 0), # API返回的字段名可能有误
- timestamp
- ))
-
- # 保存收藏夹信息
- cursor.execute("""
- INSERT OR REPLACE INTO favorites_folder
- (media_id, fid, mid, title, cover, attr, intro, ctime, mtime, state, media_count, fav_state, like_state, fetch_time)
- VALUES (?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?)
- """, (
- folder.get('id'),
- folder.get('fid'),
- folder.get('mid'),
- folder.get('title', ''),
- folder.get('cover', ''),
- folder.get('attr'),
- folder.get('intro', ''),
- folder.get('ctime'),
- folder.get('mtime'),
- folder.get('state'),
- folder.get('media_count', 0),
- folder.get('fav_state', 0),
- folder.get('like_state', 0),
- timestamp
- ))
-
- conn.commit()
- except Exception as e:
- conn.rollback()
- print(f"保存用户收藏夹信息到数据库时出错: {str(e)}")
- finally:
- conn.close()
-
- return {
- "status": "success",
- "message": "获取用户创建的收藏夹列表成功",
- "data": folders_data
- }
-
- except Exception as e:
- print(f"获取用户创建的收藏夹列表时出错: {str(e)}")
- return {
- "status": "error",
- "message": f"获取用户创建的收藏夹列表失败: {str(e)}"
- }
-
-@router.get("/folder/collected/list", summary="查询用户收藏的视频收藏夹")
-async def get_collected_folders(
- up_mid: Optional[int] = Query(None, description="目标用户mid,不提供则使用当前登录用户"),
- pn: int = Query(1, description="页码"),
- ps: int = Query(40, description="每页项数"),
- keyword: Optional[str] = Query(None, description="搜索关键词"),
- sessdata: Optional[str] = Query(None, description="用户的 SESSDATA")
-):
- """
- 查询用户收藏的视频收藏夹
- """
- try:
- # 如果未提供up_mid,获取当前登录用户的UID
- if up_mid is None:
- user_info = await get_current_user_info(sessdata)
- if user_info is None:
- return {
- "status": "error",
- "message": "未提供up_mid且未登录,无法获取收藏夹信息"
- }
- up_mid = user_info.get("uid")
- print(f"使用当前登录用户UID: {up_mid}")
-
- url = "https://api.bilibili.com/x/v3/fav/folder/collected/list"
- params = {"up_mid": up_mid, "pn": pn, "ps": ps}
- if keyword:
- params["keyword"] = keyword
-
- headers = get_headers(sessdata)
-
- response = requests.get(url, params=params, headers=headers)
- data = response.json()
-
- # 检查API响应
- if data.get('code') != 0:
- return {
- "status": "error",
- "message": data.get('message', '未知错误'),
- "code": data.get('code')
- }
-
- collected_data = data.get('data', {})
-
- # 保存到数据库
- conn = get_db_connection()
- try:
- cursor = conn.cursor()
- timestamp = int(time.time())
-
- # 遍历所有收藏夹
- for folder in collected_data.get('list', []):
- # 保存创建者信息
- upper = folder.get('upper', {})
- if upper and 'mid' in upper:
- cursor.execute("""
- INSERT OR REPLACE INTO favorites_creator
- (mid, name, face, followed, vip_type, vip_status, fetch_time)
- VALUES (?, ?, ?, ?, ?, ?, ?)
- """, (
- upper.get('mid'),
- upper.get('name', ''),
- upper.get('face', ''),
- 1 if upper.get('followed') else 0,
- upper.get('vip_type', 0),
- upper.get('vip_statue', 0), # API返回的字段名可能有误
- timestamp
- ))
-
- # 保存收藏夹信息
- cursor.execute("""
- INSERT OR REPLACE INTO favorites_folder
- (media_id, fid, mid, title, cover, attr, intro, ctime, mtime, state, media_count, fav_state, like_state, fetch_time)
- VALUES (?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?)
- """, (
- folder.get('id'),
- folder.get('fid'),
- folder.get('mid'),
- folder.get('title', ''),
- folder.get('cover', ''),
- folder.get('attr'),
- folder.get('intro', ''),
- folder.get('ctime'),
- folder.get('mtime'),
- folder.get('state'),
- folder.get('media_count', 0),
- folder.get('fav_state', 0),
- folder.get('like_state', 0),
- timestamp
- ))
-
- conn.commit()
- except Exception as e:
- conn.rollback()
- print(f"保存用户收藏的收藏夹信息到数据库时出错: {str(e)}")
- finally:
- conn.close()
-
- return {
- "status": "success",
- "message": "获取用户收藏的收藏夹列表成功",
- "data": collected_data
- }
-
- except Exception as e:
- print(f"获取用户收藏的收藏夹列表时出错: {str(e)}")
- return {
- "status": "error",
- "message": f"获取用户收藏的收藏夹列表失败: {str(e)}"
- }
-
-@router.get("/resource/infos", summary="批量获取指定收藏id的内容")
-async def get_resource_infos(
- resources: str = Query(..., description="资源列表,格式为id:type,id:type,如583785685:2,15664:12"),
- sessdata: Optional[str] = Query(None, description="用户的 SESSDATA")
-):
- """
- 批量获取指定收藏id的内容
-
- type: 2=视频稿件,12=音频,...
- """
- try:
- url = "https://api.bilibili.com/x/v3/fav/resource/infos"
- params = {"resources": resources}
- headers = get_headers(sessdata)
-
- response = requests.get(url, params=params, headers=headers)
- data = response.json()
-
- # 检查API响应
- if data.get('code') != 0:
- return {
- "status": "error",
- "message": data.get('message', '未知错误'),
- "code": data.get('code')
- }
-
- resources_data = data.get('data', [])
-
- # 保存到数据库
- conn = get_db_connection()
- try:
- cursor = conn.cursor()
- timestamp = int(time.time())
-
- # 为每个资源创建一个虚拟的media_id,因为这个API不返回对应的media_id
- # 使用当前时间戳作为标识
- virtual_media_id = timestamp
-
- # 遍历所有资源
- for resource in resources_data:
- # 保存UP主信息
- upper = resource.get('upper', {})
- if upper and 'mid' in upper:
- cursor.execute("""
- INSERT OR REPLACE INTO favorites_creator
- (mid, name, face, followed, vip_type, vip_status, fetch_time)
- VALUES (?, ?, ?, ?, ?, ?, ?)
- """, (
- upper.get('mid'),
- upper.get('name', ''),
- upper.get('face', ''),
- 0, # API不返回是否关注
- 0, # API不返回会员类型
- 0, # API不返回会员状态
- timestamp
- ))
-
- # 保存资源信息
- cursor.execute("""
- INSERT OR REPLACE INTO favorites_content
- (media_id, content_id, type, title, cover, bvid, intro, page, duration, upper_mid, attr, ctime, pubtime, fav_time, link, fetch_time,
- creator_name, creator_face, bv_id, collect, play, danmaku, play_switch, reply, view_text_1, first_cid, media_list_link)
- VALUES (?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?)
- """, (
- virtual_media_id,
- resource.get('id'),
- resource.get('type'),
- resource.get('title', ''),
- resource.get('cover', ''),
- resource.get('bvid', ''),
- resource.get('intro', ''),
- resource.get('page', 0),
- resource.get('duration', 0),
- upper.get('mid') if upper else 0,
- resource.get('attr', 0),
- resource.get('ctime', 0),
- resource.get('pubtime', 0),
- resource.get('fav_time', 0),
- resource.get('link', ''),
- timestamp,
- upper.get('name', '') if upper else '',
- upper.get('face', '') if upper else '',
- resource.get('bv_id', ''),
- resource.get('cnt_info', {}).get('collect', 0),
- resource.get('cnt_info', {}).get('play', 0),
- resource.get('cnt_info', {}).get('danmaku', 0),
- resource.get('cnt_info', {}).get('play_switch', 0),
- resource.get('cnt_info', {}).get('reply', 0),
- resource.get('cnt_info', {}).get('view_text_1', ''),
- resource.get('ugc', {}).get('first_cid', 0) if resource.get('ugc') else 0,
- resource.get('media_list_link', '')
- ))
-
- conn.commit()
- except Exception as e:
- conn.rollback()
- print(f"保存资源信息到数据库时出错: {str(e)}")
- finally:
- conn.close()
-
- return {
- "status": "success",
- "message": "获取资源信息成功",
- "data": resources_data
- }
-
- except Exception as e:
- print(f"获取资源信息时出错: {str(e)}")
- return {
- "status": "error",
- "message": f"获取资源信息失败: {str(e)}"
- }
-
-@router.get("/folder/resource/list", summary="获取收藏夹内容列表")
-async def get_folder_resource_list(
- media_id: int = Query(..., description="目标收藏夹id(完整id)"),
- pn: int = Query(1, description="页码"),
- ps: int = Query(40, description="每页项数"),
- keyword: Optional[str] = Query(None, description="搜索关键词"),
- order: str = Query("mtime", description="排序方式,mtime(收藏时间)或view(播放量)"),
- type: int = Query(0, description="筛选类型,0=全部,2=视频"),
- tid: int = Query(0, description="分区ID,0=全部"),
- platform: str = Query("web", description="平台标识"),
- sessdata: Optional[str] = Query(None, description="用户的 SESSDATA")
-):
- """
- 获取收藏夹内容列表
-
- 需要登录才能查看私密收藏夹
- """
- try:
- url = "https://api.bilibili.com/x/v3/fav/resource/list"
- params = {
- "media_id": media_id,
- "pn": pn,
- "ps": ps,
- "order": order,
- "type": type,
- "tid": tid,
- "platform": platform
- }
- if keyword:
- params["keyword"] = keyword
-
- headers = get_headers(sessdata)
-
- response = requests.get(url, params=params, headers=headers)
- data = response.json()
-
- # 检查API响应
- if data.get('code') != 0:
- return {
- "status": "error",
- "message": data.get('message', '未知错误'),
- "code": data.get('code')
- }
-
- result_data = data.get('data', {})
-
- # 保存到数据库
- conn = get_db_connection()
- try:
- cursor = conn.cursor()
- timestamp = int(time.time())
-
- # 保存收藏夹元数据
- info = result_data.get('info', {})
- if info and 'id' in info:
- # 保存创建者信息
- upper = info.get('upper', {})
- if upper and 'mid' in upper:
- cursor.execute("""
- INSERT OR REPLACE INTO favorites_creator
- (mid, name, face, followed, vip_type, vip_status, fetch_time)
- VALUES (?, ?, ?, ?, ?, ?, ?)
- """, (
- upper.get('mid'),
- upper.get('name', ''),
- upper.get('face', ''),
- 1 if upper.get('followed') else 0,
- upper.get('vip_type', 0),
- upper.get('vip_statue', 0), # API返回的字段名可能有误
- timestamp
- ))
-
- # 保存收藏夹信息
- cursor.execute("""
- INSERT OR REPLACE INTO favorites_folder
- (media_id, fid, mid, title, cover, attr, intro, ctime, mtime, state, media_count, fav_state, like_state, fetch_time)
- VALUES (?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?)
- """, (
- info.get('id'),
- info.get('fid'),
- info.get('mid'),
- info.get('title', ''),
- info.get('cover', ''),
- info.get('attr'),
- info.get('intro', ''),
- info.get('ctime'),
- info.get('mtime'),
- info.get('state'),
- info.get('media_count', 0),
- info.get('fav_state', 0),
- info.get('like_state', 0),
- timestamp
- ))
-
- # 保存收藏夹内容
- for resource in result_data.get('medias', []):
- # 保存UP主信息
- upper = resource.get('upper', {})
- if upper and 'mid' in upper:
- cursor.execute("""
- INSERT OR REPLACE INTO favorites_creator
- (mid, name, face, followed, vip_type, vip_status, fetch_time)
- VALUES (?, ?, ?, ?, ?, ?, ?)
- """, (
- upper.get('mid'),
- upper.get('name', ''),
- upper.get('face', ''),
- 0, # API不返回是否关注
- 0, # API不返回会员类型
- 0, # API不返回会员状态
- timestamp
- ))
-
- # 保存资源信息
- cursor.execute("""
- INSERT OR REPLACE INTO favorites_content
- (media_id, content_id, type, title, cover, bvid, intro, page, duration, upper_mid, attr, ctime, pubtime, fav_time, link, fetch_time,
- creator_name, creator_face, bv_id, collect, play, danmaku, play_switch, reply, view_text_1, first_cid, media_list_link)
- VALUES (?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?)
- """, (
- media_id,
- resource.get('id'),
- resource.get('type'),
- resource.get('title', ''),
- resource.get('cover', ''),
- resource.get('bvid', ''),
- resource.get('intro', ''),
- resource.get('page', 0),
- resource.get('duration', 0),
- upper.get('mid') if upper else 0,
- resource.get('attr', 0),
- resource.get('ctime', 0),
- resource.get('pubtime', 0),
- resource.get('fav_time', 0),
- resource.get('link', ''),
- timestamp,
- upper.get('name', '') if upper else '',
- upper.get('face', '') if upper else '',
- resource.get('bv_id', ''),
- resource.get('cnt_info', {}).get('collect', 0),
- resource.get('cnt_info', {}).get('play', 0),
- resource.get('cnt_info', {}).get('danmaku', 0),
- resource.get('cnt_info', {}).get('play_switch', 0),
- resource.get('cnt_info', {}).get('reply', 0),
- resource.get('cnt_info', {}).get('view_text_1', ''),
- resource.get('ugc', {}).get('first_cid', 0) if resource.get('ugc') else 0,
- resource.get('media_list_link', '')
- ))
-
- conn.commit()
- except Exception as e:
- conn.rollback()
- print(f"保存收藏夹内容到数据库时出错: {str(e)}")
- finally:
- conn.close()
-
- return {
- "status": "success",
- "message": "获取收藏夹内容成功",
- "data": result_data
- }
-
- except Exception as e:
- print(f"获取收藏夹内容时出错: {str(e)}")
- return {
- "status": "error",
- "message": f"获取收藏夹内容失败: {str(e)}"
- }
-
-@router.get("/list", summary="获取数据库中的收藏夹列表")
-async def get_favorites_list(
- mid: Optional[int] = Query(None, description="用户UID,不提供则返回所有收藏夹"),
- page: int = Query(1, description="页码"),
- size: int = Query(40, description="每页数量")
-):
- """获取已保存到数据库中的收藏夹列表"""
- try:
- conn = get_db_connection()
- cursor = conn.cursor()
-
- # 构建查询条件
- where_clause = "WHERE 1=1"
- params = []
-
- if mid is not None:
- where_clause += " AND mid = ?"
- params.append(mid)
-
- # 计算总数
- cursor.execute(f"SELECT COUNT(*) FROM favorites_folder {where_clause}", params)
- total = cursor.fetchone()[0]
-
- # 分页查询
- offset = (page - 1) * size
- cursor.execute(f"""
- SELECT f.*,
- c.name as creator_name, c.face as creator_face
- FROM favorites_folder f
- LEFT JOIN favorites_creator c ON f.mid = c.mid
- {where_clause}
- ORDER BY f.mtime DESC
- LIMIT ? OFFSET ?
- """, params + [size, offset])
-
- rows = cursor.fetchall()
- folders = []
-
- for row in rows:
- folder = dict(row)
- folders.append(folder)
-
- conn.close()
-
- return {
- "status": "success",
- "message": "获取收藏夹列表成功",
- "data": {
- "list": folders,
- "total": total,
- "page": page,
- "size": size
- }
- }
-
- except Exception as e:
- print(f"获取收藏夹列表时出错: {str(e)}")
- return {
- "status": "error",
- "message": f"获取收藏夹列表失败: {str(e)}"
- }
-
-@router.get("/content/list", summary="获取数据库中的收藏内容列表")
-async def get_favorites_content(
- media_id: int = Query(..., description="收藏夹ID"),
- page: int = Query(1, description="页码"),
- size: int = Query(40, description="每页数量")
-):
- """获取已保存到数据库中的收藏内容列表"""
- try:
- conn = get_db_connection()
- cursor = conn.cursor()
-
- # 计算总数
- cursor.execute("SELECT COUNT(*) FROM favorites_content WHERE media_id = ?", (media_id,))
- total = cursor.fetchone()[0]
-
- # 分页查询
- offset = (page - 1) * size
- cursor.execute("""
- SELECT c.*,
- cr.name as creator_name, cr.face as creator_face
- FROM favorites_content c
- LEFT JOIN favorites_creator cr ON c.upper_mid = cr.mid
- WHERE c.media_id = ?
- ORDER BY c.fav_time DESC
- LIMIT ? OFFSET ?
- """, (media_id, size, offset))
-
- rows = cursor.fetchall()
- contents = []
-
- for row in rows:
- content = dict(row)
- contents.append(content)
-
- conn.close()
-
- return {
- "status": "success",
- "message": "获取收藏内容列表成功",
- "data": {
- "list": contents,
- "total": total,
- "page": page,
- "size": size
- }
- }
-
- except Exception as e:
- print(f"获取收藏内容列表时出错: {str(e)}")
- return {
- "status": "error",
- "message": f"获取收藏内容列表失败: {str(e)}"
- }
-
-# 添加请求体数据模型
-class FavoriteResourceRequest(BaseModel):
- rid: int = Field(..., description="稿件avid")
- add_media_ids: Optional[str] = Field(None, description="需要加入的收藏夹ID,多个用逗号分隔")
- del_media_ids: Optional[str] = Field(None, description="需要取消的收藏夹ID,多个用逗号分隔")
- sessdata: Optional[str] = Field(None, description="用户的SESSDATA")
-
-@router.post("/resource/deal", summary="收藏或取消收藏单个视频")
-async def favorite_resource(
- request: Optional[FavoriteResourceRequest] = None,
- rid: Optional[int] = Query(None, description="稿件avid"),
- add_media_ids: Optional[str] = Query(None, description="需要加入的收藏夹ID,多个用逗号分隔"),
- del_media_ids: Optional[str] = Query(None, description="需要取消的收藏夹ID,多个用逗号分隔"),
- sessdata: Optional[str] = Query(None, description="用户的SESSDATA")
-):
- """
- 收藏或取消收藏单个视频到指定收藏夹
-
- 可以通过查询参数或请求体提交参数,支持两种方式
-
- - rid: 视频的av号(不含av前缀)
- - add_media_ids: 需要添加到的收藏夹ID,多个用逗号分隔
- - del_media_ids: 需要从中取消的收藏夹ID,多个用逗号分隔
- - sessdata: 用户的SESSDATA,不提供则从配置文件读取
-
- 需要用户登录才能操作
- """
- try:
- # 优先使用请求体中的参数
- if request:
- rid = request.rid
- add_media_ids = request.add_media_ids
- del_media_ids = request.del_media_ids
- if request.sessdata:
- sessdata = request.sessdata
-
- # 检查必填参数
- if rid is None:
- return {
- "status": "error",
- "message": "缺少必填参数: rid (稿件avid)"
- }
-
- if not add_media_ids and not del_media_ids:
- return {
- "status": "error",
- "message": "需要提供至少一个收藏夹ID (add_media_ids 或 del_media_ids)"
- }
-
- # 获取请求头和Cookie
- headers = get_headers(sessdata)
-
- # 从配置或Cookie中获取bili_jct (CSRF Token)
- current_config = load_config()
- bili_jct = current_config.get("bili_jct", "")
-
- if not bili_jct:
- return {
- "status": "error",
- "message": "缺少CSRF Token (bili_jct),请先使用QR码登录并确保已正确获取bili_jct"
- }
-
- # 准备请求参数
- data = {
- "rid": rid,
- "type": 2, # 固定为2,表示视频稿件
- "csrf": bili_jct,
- "platform": "web",
- "eab_x": 1,
- "ramval": 0,
- "ga": 1,
- "gaia_source": "web_normal"
- }
-
- if add_media_ids:
- data["add_media_ids"] = add_media_ids
-
- if del_media_ids:
- data["del_media_ids"] = del_media_ids
-
- # 发起请求
- url = "https://api.bilibili.com/x/v3/fav/resource/deal"
- response = requests.post(url, data=data, headers=headers)
- result = response.json()
-
- # 检查响应
- if result.get('code') != 0:
- return {
- "status": "error",
- "message": result.get('message', '未知错误'),
- "code": result.get('code')
- }
-
- return {
- "status": "success",
- "message": "操作成功",
- "data": result.get('data', {})
- }
-
- except Exception as e:
- print(f"收藏操作失败: {str(e)}")
- return {
- "status": "error",
- "message": f"收藏操作失败: {str(e)}"
- }
-
-# 添加批量请求体数据模型
-class BatchFavoriteResourceRequest(BaseModel):
- rids: str = Field(..., description="稿件avid列表,多个用逗号分隔")
- add_media_ids: Optional[str] = Field(None, description="需要加入的收藏夹ID,多个用逗号分隔")
- del_media_ids: Optional[str] = Field(None, description="需要取消的收藏夹ID,多个用逗号分隔")
- sessdata: Optional[str] = Field(None, description="用户的SESSDATA")
-
-@router.post("/resource/batch-deal", summary="批量收藏或取消收藏视频")
-async def batch_favorite_resource(
- request: Optional[BatchFavoriteResourceRequest] = None,
- rids: Optional[str] = Query(None, description="稿件avid列表,多个用逗号分隔"),
- add_media_ids: Optional[str] = Query(None, description="需要加入的收藏夹ID,多个用逗号分隔"),
- del_media_ids: Optional[str] = Query(None, description="需要取消的收藏夹ID,多个用逗号分隔"),
- sessdata: Optional[str] = Query(None, description="用户的SESSDATA")
-):
- """
- 批量收藏或取消收藏多个视频到指定收藏夹
-
- 可以通过查询参数或请求体提交参数,支持两种方式
-
- - rids: 视频的av号列表(不含av前缀),多个用逗号分隔
- - add_media_ids: 需要添加到的收藏夹ID,多个用逗号分隔
- - del_media_ids: 需要从中取消的收藏夹ID,多个用逗号分隔
- - sessdata: 用户的SESSDATA,不提供则从配置文件读取
-
- 需要用户登录才能操作
- """
- try:
- # 优先使用请求体中的参数
- if request:
- rids = request.rids
- add_media_ids = request.add_media_ids
- del_media_ids = request.del_media_ids
- if request.sessdata:
- sessdata = request.sessdata
-
- # 检查必填参数
- if not rids:
- return {
- "status": "error",
- "message": "缺少必填参数: rids (稿件avid列表)"
- }
-
- if not add_media_ids and not del_media_ids:
- return {
- "status": "error",
- "message": "需要提供至少一个收藏夹ID (add_media_ids 或 del_media_ids)"
- }
-
- # 处理输入参数
- try:
- rid_list = [int(rid.strip()) for rid in rids.split(',') if rid.strip()]
- except ValueError:
- return {
- "status": "error",
- "message": "无效的rids参数格式,请使用逗号分隔的整数列表"
- }
-
- if not rid_list:
- return {
- "status": "error",
- "message": "请提供至少一个有效的视频ID"
- }
-
- # 获取请求头和Cookie
- headers = get_headers(sessdata)
-
- # 从配置或Cookie中获取bili_jct (CSRF Token)
- current_config = load_config()
- bili_jct = current_config.get("bili_jct", "")
-
- if not bili_jct:
- return {
- "status": "error",
- "message": "缺少CSRF Token (bili_jct),请先使用QR码登录并确保已正确获取bili_jct"
- }
-
- # 批量处理每个视频
- results = []
- for rid in rid_list:
- # 准备请求参数
- data = {
- "rid": rid,
- "type": 2, # 固定为2,表示视频稿件
- "csrf": bili_jct,
- "platform": "web",
- "eab_x": 1,
- "ramval": 0,
- "ga": 1,
- "gaia_source": "web_normal"
- }
-
- if add_media_ids:
- data["add_media_ids"] = add_media_ids
-
- if del_media_ids:
- data["del_media_ids"] = del_media_ids
-
- # 发起请求
- url = "https://api.bilibili.com/x/v3/fav/resource/deal"
- response = requests.post(url, data=data, headers=headers)
- result = response.json()
-
- # 添加结果
- results.append({
- "rid": rid,
- "code": result.get('code'),
- "message": result.get('message'),
- "data": result.get('data')
- })
-
- # 添加短暂延迟,防止频繁请求
- time.sleep(0.5)
-
- # 检查是否全部成功
- all_success = all(result["code"] == 0 for result in results)
-
- return {
- "status": "success" if all_success else "partial_success",
- "message": "所有操作成功完成" if all_success else "部分操作成功",
- "results": results
- }
-
- except Exception as e:
- print(f"批量收藏操作失败: {str(e)}")
- return {
- "status": "error",
- "message": f"批量收藏操作失败: {str(e)}"
- }
-
-class CheckFavoritesRequest(BaseModel):
- oids: List[int] = Field(..., description="视频的av号列表")
- sessdata: Optional[str] = Field(None, description="用户的SESSDATA")
-
-@router.post("/check/batch", summary="批量检查视频是否已被收藏", tags=["收藏夹管理"])
-async def check_favorites_batch(request: CheckFavoritesRequest):
- """
- 批量检查多个视频是否已被收藏
-
- - oids: 视频的av号列表
- - sessdata: 用户的SESSDATA,不提供则从配置文件读取
-
- 响应格式:
- ```json
- {
- "status": "success",
- "data": {
- "results": [
- {
- "oid": 123456,
- "is_favorited": true,
- "favorite_folders": [
- {"media_id": 1234567, "title": "收藏夹名称"}
- ]
- }
- ]
- }
- }
- ```
- """
- try:
- # 获取请求参数
- oids = request.oids
- sessdata = request.sessdata
-
- if not oids:
- return {
- "status": "error",
- "message": "请提供至少一个视频av号"
- }
-
- # 查询B站API获取用户的收藏夹列表
- user_info = await get_current_user_info(sessdata)
- if not user_info:
- return {
- "status": "error",
- "message": "无法获取用户信息,请确保已登录"
- }
-
- # 获取本地数据库中的相关收藏信息
- conn = get_db_connection()
- cursor = conn.cursor()
-
- results = []
- # 遍历每个视频av号
- for oid in oids:
- # 查询本地数据库中是否收藏了该视频
- cursor.execute("""
- SELECT fc.media_id, ff.title
- FROM favorites_content fc
- JOIN favorites_folder ff ON fc.media_id = ff.media_id
- WHERE fc.content_id = ? AND fc.type = 2
- """, (oid,))
-
- rows = cursor.fetchall()
- is_favorited = len(rows) > 0
- favorite_folders = []
-
- if is_favorited:
- for row in rows:
- favorite_folders.append({
- "media_id": row[0],
- "title": row[1]
- })
-
- results.append({
- "oid": oid,
- "is_favorited": is_favorited,
- "favorite_folders": favorite_folders
- })
-
- conn.close()
-
- return {
- "status": "success",
- "data": {
- "results": results
- }
- }
-
- except Exception as e:
- print(f"批量检查收藏状态时出错: {str(e)}")
- return {
- "status": "error",
- "message": f"批量检查收藏状态失败: {str(e)}"
- }
-
-@router.get("/check", summary="检查单个视频是否已被收藏", tags=["收藏夹管理"])
-async def check_favorite(
- oid: int = Query(..., description="视频的av号"),
- sessdata: Optional[str] = Query(None, description="用户的SESSDATA")
-):
- """
- 检查单个视频是否已被收藏
-
- - oid: 视频的av号
- - sessdata: 用户的SESSDATA,不提供则从配置文件读取
-
- 响应格式:
- ```json
- {
- "status": "success",
- "data": {
- "oid": 123456,
- "is_favorited": true,
- "favorite_folders": [
- {"media_id": 1234567, "title": "收藏夹名称"}
- ]
- }
- }
- ```
- """
- try:
- # 查询本地数据库中是否收藏了该视频
- conn = get_db_connection()
- cursor = conn.cursor()
-
- cursor.execute("""
- SELECT fc.media_id, ff.title
- FROM favorites_content fc
- JOIN favorites_folder ff ON fc.media_id = ff.media_id
- WHERE fc.content_id = ? AND fc.type = 2
- """, (oid,))
-
- rows = cursor.fetchall()
- is_favorited = len(rows) > 0
- favorite_folders = []
-
- if is_favorited:
- for row in rows:
- favorite_folders.append({
- "media_id": row[0],
- "title": row[1]
- })
-
- conn.close()
-
- return {
- "status": "success",
- "data": {
- "oid": oid,
- "is_favorited": is_favorited,
- "favorite_folders": favorite_folders
- }
- }
-
- except Exception as e:
- print(f"检查收藏状态时出错: {str(e)}")
- return {
- "status": "error",
- "message": f"检查收藏状态失败: {str(e)}"
- }
-
-class BatchLocalFavoriteRequest(BaseModel):
- rids: str = Field(..., description="稿件avid列表,多个用逗号分隔")
- add_media_ids: Optional[str] = Field(None, description="需要加入的收藏夹ID,多个用逗号分隔")
- del_media_ids: Optional[str] = Field(None, description="需要取消的收藏夹ID,多个用逗号分隔")
- operation_type: str = Field("sync", description="操作类型,sync=同步到远程,local=仅本地操作")
-
-@router.post("/resource/local-batch-deal", summary="本地批量收藏或取消收藏视频")
-async def local_batch_favorite_resource(
- request: BatchLocalFavoriteRequest,
- sessdata: Optional[str] = Query(None, description="用户的SESSDATA")
-):
- """
- 在本地数据库中批量收藏或取消收藏多个视频
-
- - rids: 视频的av号列表(不含av前缀),多个用逗号分隔
- - add_media_ids: 需要添加到的收藏夹ID,多个用逗号分隔
- - del_media_ids: 需要从中取消的收藏夹ID,多个用逗号分隔
- - operation_type: 操作类型,sync=同步到远程,local=仅本地操作
-
- 此接口用于本地数据库和远程B站的收藏同步管理
- """
- try:
- # 获取请求参数
- rids = request.rids
- add_media_ids = request.add_media_ids
- del_media_ids = request.del_media_ids
- operation_type = request.operation_type
-
- # 检查必填参数
- if not rids:
- return {
- "status": "error",
- "message": "缺少必填参数: rids (稿件avid列表)"
- }
-
- if not add_media_ids and not del_media_ids:
- return {
- "status": "error",
- "message": "需要提供至少一个收藏夹ID (add_media_ids 或 del_media_ids)"
- }
-
- # 处理输入参数
- try:
- rid_list = [int(rid.strip()) for rid in rids.split(',') if rid.strip()]
- except ValueError:
- return {
- "status": "error",
- "message": "无效的rids参数格式,请使用逗号分隔的整数列表"
- }
-
- if not rid_list:
- return {
- "status": "error",
- "message": "请提供至少一个有效的视频ID"
- }
-
- # 解析收藏夹ID
- add_folders = []
- if add_media_ids:
- add_folders = [int(mid.strip()) for mid in add_media_ids.split(',') if mid.strip()]
-
- del_folders = []
- if del_media_ids:
- del_folders = [int(mid.strip()) for mid in del_media_ids.split(',') if mid.strip()]
-
- # 连接数据库
- conn = get_db_connection()
- cursor = conn.cursor()
-
- # 获取当前时间戳
- timestamp = int(datetime.now().timestamp())
-
- # 获取用户信息
- user_info = await get_current_user_info(sessdata)
- user_mid = user_info.get("uid") if user_info else 0
-
- results = []
-
- # 同步到远程B站
- if operation_type == "sync":
- # 复用现有的批量收藏接口
- batch_request = BatchFavoriteResourceRequest(
- rids=rids,
- add_media_ids=add_media_ids,
- del_media_ids=del_media_ids,
- sessdata=sessdata
- )
- remote_result = await batch_favorite_resource(request=batch_request)
-
- # 如果远程操作失败,则只返回远程结果不进行本地操作
- if remote_result.get("status") != "success" and remote_result.get("status") != "partial_success":
- return remote_result
-
- # 遍历每个视频,处理本地数据库操作
- for rid in rid_list:
- result_item = {"rid": rid, "code": 0, "message": "success", "data": {}}
-
- try:
- # 处理取消收藏 (删除记录)
- if del_folders:
- for media_id in del_folders:
- cursor.execute("""
- DELETE FROM favorites_content
- WHERE content_id = ? AND media_id = ? AND type = 2
- """, (rid, media_id))
-
- if cursor.rowcount > 0:
- result_item["data"]["removed_folders"] = result_item.get("data", {}).get("removed_folders", 0) + 1
-
- # 处理添加收藏 (添加记录)
- if add_folders:
- for media_id in add_folders:
- # 检查收藏夹是否存在
- cursor.execute("SELECT * FROM favorites_folder WHERE media_id = ?", (media_id,))
- folder = cursor.fetchone()
-
- if not folder:
- # 收藏夹不存在,跳过
- result_item["data"]["folder_not_found"] = result_item.get("data", {}).get("folder_not_found", 0) + 1
- continue
-
- # 检查视频是否已在收藏夹中
- cursor.execute("""
- SELECT * FROM favorites_content
- WHERE content_id = ? AND media_id = ? AND type = 2
- """, (rid, media_id))
-
- if cursor.fetchone():
- # 已收藏,跳过
- result_item["data"]["already_favorited"] = result_item.get("data", {}).get("already_favorited", 0) + 1
- continue
-
- # 获取视频信息 (如标题等) - 尝试从数据库中其他收藏夹获取
- cursor.execute("""
- SELECT * FROM favorites_content
- WHERE content_id = ? AND type = 2
- """, (rid,))
-
- existing_content = cursor.fetchone()
-
- # 如果在数据库中找到了视频信息,使用这些信息
- if existing_content:
- title = existing_content["title"]
- cover = existing_content["cover"]
- bvid = existing_content["bvid"]
- intro = existing_content["intro"]
- page = existing_content["page"]
- duration = existing_content["duration"]
- upper_mid = existing_content["upper_mid"]
- attr = existing_content["attr"]
- ctime = existing_content["ctime"]
- pubtime = existing_content["pubtime"]
- link = existing_content["link"]
- else:
- # 未找到视频信息,使用默认值
- title = f"视频 av{rid}"
- cover = ""
- bvid = ""
- intro = ""
- page = 1
- duration = 0
- upper_mid = 0
- attr = 0
- ctime = timestamp
- pubtime = timestamp
- link = f"https://www.bilibili.com/video/av{rid}"
-
- # 添加收藏
- cursor.execute("""
- INSERT OR REPLACE INTO favorites_content
- (media_id, content_id, type, title, cover, bvid, intro, page, duration, upper_mid, attr, ctime, pubtime, fav_time, link, fetch_time,
- creator_name, creator_face, bv_id, collect, play, danmaku, play_switch, reply, view_text_1, first_cid, media_list_link)
- VALUES (?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?)
- """, (
- media_id,
- rid,
- 2, # 固定为2,表示视频稿件
- title,
- cover,
- bvid,
- intro,
- page,
- duration,
- upper_mid,
- attr,
- ctime,
- pubtime,
- timestamp, # 当前时间作为收藏时间
- link,
- timestamp,
- existing_content["creator_name"] if existing_content and "creator_name" in existing_content else "",
- existing_content["creator_face"] if existing_content and "creator_face" in existing_content else "",
- existing_content["bv_id"] if existing_content and "bv_id" in existing_content else "",
- existing_content["collect"] if existing_content and "collect" in existing_content else 0,
- existing_content["play"] if existing_content and "play" in existing_content else 0,
- existing_content["danmaku"] if existing_content and "danmaku" in existing_content else 0,
- existing_content["play_switch"] if existing_content and "play_switch" in existing_content else 0,
- existing_content["reply"] if existing_content and "reply" in existing_content else 0,
- existing_content["view_text_1"] if existing_content and "view_text_1" in existing_content else "",
- existing_content["first_cid"] if existing_content and "first_cid" in existing_content else 0,
- existing_content["media_list_link"] if existing_content and "media_list_link" in existing_content else ""
- ))
-
- result_item["data"]["added_folders"] = result_item.get("data", {}).get("added_folders", 0) + 1
-
- # 添加成功消息
- result_item["data"]["prompt"] = True
- result_item["data"]["toast_msg"] = "本地收藏更新成功"
- results.append(result_item)
-
- except Exception as e:
- print(f"处理视频 {rid} 时出错: {str(e)}")
- result_item["code"] = -1
- result_item["message"] = f"本地操作失败: {str(e)}"
- results.append(result_item)
-
- # 提交事务
- conn.commit()
- conn.close()
-
- # 检查是否全部成功
- all_success = all(result["code"] == 0 for result in results)
-
- return {
- "status": "success" if all_success else "partial_success",
- "message": "所有本地操作成功完成" if all_success else "部分本地操作成功",
- "operation_type": operation_type,
- "results": results
- }
-
- except Exception as e:
- print(f"本地批量收藏操作失败: {str(e)}")
- return {
- "status": "error",
- "message": f"本地批量收藏操作失败: {str(e)}"
- }
diff --git a/routers/fetch_bili_history.py b/routers/fetch_bili_history.py
index dfd9943..e7d7d4c 100644
--- a/routers/fetch_bili_history.py
+++ b/routers/fetch_bili_history.py
@@ -1,274 +1,36 @@
-from typing import Optional, Union
+from fastapi import APIRouter
-from fastapi import APIRouter, Query, HTTPException
-from loguru import logger
-from pydantic import BaseModel, Field
-
-from scripts.bilibili_history import fetch_history, find_latest_local_history, fetch_and_compare_history, save_history, \
- load_cookie, get_invalid_videos_from_db
+from scripts.bilibili_history import fetch_history
from scripts.import_sqlite import import_all_history_files
-from scripts.utils import load_config, setup_logger
-from .interaction_records import (
- InteractionSyncRequest,
- has_interaction_history_import_completed,
- import_interactions_to_history_once,
- sync_interactions as run_interaction_sync,
-)
-# 确保日志系统已初始化
-setup_logger()
router = APIRouter()
-config = load_config()
-
-# 定义请求体模型
-class FetchHistoryRequest(BaseModel):
- sessdata: Optional[str] = Field(None, description="用户的 SESSDATA")
-
-
-# 定义响应模型
-class ResponseModel(BaseModel):
- status: str
- message: str
- data: Optional[Union[list, dict]] = None
+async def sync_history(skip_exists: bool):
+ result = await fetch_history(skip_exists=skip_exists)
+ if result["status"] != "success":
+ return result
-def get_headers():
- """获取请求头"""
- # 动态读取配置文件,获取最新的SESSDATA
- current_config = load_config()
- headers = {
- 'User-Agent': 'Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/91.0.4472.124 Safari/537.36',
- 'Cookie': f'SESSDATA={current_config["SESSDATA"]}'
+ imported = import_all_history_files(incremental=skip_exists)
+ if imported["status"] != "success":
+ return imported
+
+ return {
+ "status": "success",
+ "message": f"历史记录获取完成,导入 {imported['inserted_count']} 条记录",
+ "data": {
+ "new_records_count": result["data"]["new_records_count"],
+ "inserted_count": imported["inserted_count"],
+ },
}
- return headers
-
-
-def sync_interactions_safely(enabled: bool = True, import_to_history: bool = True) -> dict:
- """自动补充互动记录;失败时返回错误信息但不影响历史同步主流程。"""
- if not enabled:
- return {
- "status": "skipped",
- "message": "Interaction sync skipped",
- }
- if has_interaction_history_import_completed():
- return {
- "status": "skipped",
- "message": "Interaction supplement already imported; skip one-time interaction sync.",
- "data": {
- "history_import": {
- "status": "skipped",
- "message": "Interaction history supplement already imported.",
- "already_imported": True,
- }
- },
- }
-
- try:
- request = InteractionSyncRequest(
- include_favorites=True,
- include_likes=True,
- include_coins=True,
- max_favorite_pages=0,
- favorite_page_size=20,
- )
- sync_result = run_interaction_sync(request)
- sync_result.setdefault("data", {})
- if import_to_history:
- sync_result["data"]["history_import"] = import_interactions_to_history_once()
- else:
- sync_result["data"]["history_import"] = {
- "status": "deferred",
- "message": "Interaction history import will run after SQLite history import.",
- }
- return sync_result
- except Exception as e:
- logger.exception("自动同步互动记录失败")
- return {
- "status": "error",
- "message": f"Interaction sync failed: {str(e)}",
- }
@router.get("/bili-history", summary="获取B站历史记录")
-async def get_bili_history(
- output_dir: Optional[str] = "history_by_date",
- skip_exists: bool = True,
- process_video_details: bool = False,
- sync_interactions: bool = True,
-):
- """获取B站历史记录"""
- try:
- result = await fetch_history(output_dir, skip_exists, process_video_details)
- interaction_result = None
- if result.get("status") != "success":
- return {
- "status": "error",
- "message": result.get("message", "获取历史记录失败"),
- "data": result,
- }
-
- if result.get("status") == "success":
- interaction_result = sync_interactions_safely(sync_interactions, import_to_history=False)
- result["interaction_sync_result"] = interaction_result
-
- message = "历史记录获取成功"
- if interaction_result and interaction_result.get("status") == "success":
- message += ",互动记录同步完成"
- return {
- "status": "success",
- "message": message,
- "data": result
- }
- except Exception as e:
- return {
- "status": "error",
- "message": f"获取历史记录失败: {str(e)}"
- }
-
-
-@router.get("/bili-history-realtime", summary="实时获取B站历史记录", response_model=ResponseModel)
-async def get_bili_history_realtime(
- sync_deleted: bool = False,
- process_video_details: bool = False,
- sync_interactions: bool = True,
-):
- """实时获取B站历史记录"""
- try:
- # 获取最新的本地历史记录时间戳
- latest_history = find_latest_local_history()
- if not latest_history:
- return {"status": "error", "message": "未找到本地历史记录"}
-
- # 获取cookie
- cookie = load_cookie()
- if not cookie:
- return {"status": "error", "message": "未找到有效的cookie"}
-
- # 获取新的历史记录 - 使用await,因为fetch_and_compare_history现在是异步函数
- new_records = await fetch_and_compare_history(cookie, latest_history, True, process_video_details) # 传递process_video_details参数
+async def get_bili_history(skip_exists: bool = True):
+ return await sync_history(skip_exists)
- # 保存新历史记录的结果信息
- history_result = {"new_records_count": 0, "inserted_count": 0}
- video_details_result = {"processed": False}
- if new_records:
- # 保存新记录
- save_result = save_history(new_records)
- logger.info("成功保存新记录到本地文件")
- history_result["new_records_count"] = len(new_records)
-
- # 更新SQLite数据库
- logger.info("=== 开始更新SQLite数据库 ===")
- logger.info(f"同步已删除记录: {sync_deleted}")
- db_result = import_all_history_files(sync_deleted=sync_deleted)
-
- if db_result["status"] == "success":
- history_result["inserted_count"] = db_result['inserted_count']
- history_result["status"] = "success"
- else:
- history_result["status"] = "error"
- history_result["message"] = db_result["message"]
- else:
- history_result["status"] = "success"
- history_result["message"] = "没有新记录"
-
- # 处理视频详情 - 已经在fetch_and_compare_history中处理过,这里不需要重复处理
- # 只需生成结果信息
- if process_video_details:
- logger.info("视频详情已在历史记录获取过程中处理")
- video_details_result = {
- "status": "success",
- "message": "视频详情已在历史记录获取过程中处理",
- "processed": True
- }
-
- interaction_result = None
- if history_result.get("status") == "success":
- interaction_result = sync_interactions_safely(sync_interactions, import_to_history=True)
-
- # 返回综合结果
- if history_result.get("status") == "success" and (not process_video_details or video_details_result.get("status") == "success"):
- message = "实时更新成功"
- if history_result.get("new_records_count", 0) > 0:
- message += f",获取到 {history_result['new_records_count']} 条新记录"
- if history_result.get("inserted_count", 0) > 0:
- message += f",成功导入 {history_result['inserted_count']} 条记录到SQLite数据库"
- else:
- message += ",暂无新历史记录"
-
- if process_video_details:
- message += "。视频详情已在历史记录获取过程中处理"
-
- if interaction_result and interaction_result.get("status") == "success":
- message += ",互动记录同步完成"
- elif interaction_result and interaction_result.get("status") == "error":
- message += ",互动记录同步失败但不影响历史记录"
-
- return {
- "status": "success",
- "message": message,
- "data": {
- "history": history_result,
- "video_details": video_details_result.get("data", {}),
- "interaction_sync": interaction_result,
- }
- }
- else:
- # 有一个失败就返回错误
- error_message = []
- if history_result.get("status") == "error":
- error_message.append(f"历史记录处理失败: {history_result.get('message', '未知错误')}")
- if process_video_details and video_details_result.get("status") == "error":
- error_message.append(f"视频详情处理失败: {video_details_result.get('message', '未知错误')}")
-
- return {
- "status": "error",
- "message": " | ".join(error_message),
- "data": {
- "history": history_result,
- "video_details": video_details_result.get("data", {}),
- "interaction_sync": interaction_result,
- }
- }
-
- except Exception as e:
- error_msg = f"实时更新失败: {str(e)}"
- logger.error(error_msg)
- import traceback
- logger.error(traceback.format_exc()) # 添加详细的堆栈跟踪
- return {"status": "error", "message": error_msg}
-
-
-# 全局变量,用于存储处理进度
-video_details_progress = {
- "is_processing": False,
- "total_videos": 0,
- "processed_videos": 0,
- "success_count": 0,
- "failed_count": 0,
- "error_videos": [],
- "skipped_invalid_count": 0,
- "start_time": 0,
- "last_update_time": 0,
- "is_complete": False
-}
-
-# 添加新的API端点用于查询失效视频列表
-@router.get("/invalid-videos", summary="获取失效视频列表")
-async def get_invalid_videos(
- page: int = Query(1, description="页码,从1开始"),
- limit: int = Query(50, description="每页返回数量,最大100"),
- error_type: Optional[str] = Query(None, description="按错误类型筛选")
-):
- """获取失效视频列表"""
- try:
- result = await get_invalid_videos_from_db(page, limit, error_type)
- return result
- except Exception as e:
- print(f"获取失效视频列表失败: {str(e)}")
- raise HTTPException(
- status_code=500,
- detail=f"获取失效视频列表失败: {str(e)}"
- )
+@router.get("/bili-history-realtime", summary="增量获取B站历史记录")
+async def get_bili_history_realtime():
+ return await sync_history(True)
diff --git a/routers/heatmap.py b/routers/heatmap.py
deleted file mode 100644
index 1f1317f..0000000
--- a/routers/heatmap.py
+++ /dev/null
@@ -1,8 +0,0 @@
-from fastapi import APIRouter
-from scripts.heatmap_visualizer import generate_heatmap
-
-router = APIRouter()
-
-@router.post("/generate_heatmap", summary="生成Bilibili观看历史热力图")
-def api_generate_heatmap():
- return generate_heatmap()
diff --git a/routers/history.py b/routers/history.py
index 467ff49..a5fe6c0 100644
--- a/routers/history.py
+++ b/routers/history.py
@@ -1,22 +1,17 @@
import json
import os
-import hashlib
-try:
- import pysqlite3 as sqlite3
-except ImportError:
- import sqlite3
+import sqlite3
from datetime import datetime
from typing import Optional
-from fastapi import APIRouter, Query, HTTPException
-from pydantic import BaseModel
+from fastapi import APIRouter, HTTPException, Query
from scripts.utils import get_output_path, load_config
-from scripts.image_downloader import ImageDownloader
+
router = APIRouter()
config = load_config()
-downloader = ImageDownloader()
+
def get_db():
"""获取数据库连接,并确保数据库版本兼容性"""
@@ -57,118 +52,24 @@ def get_db():
detail=f"数据库连接失败: {str(e)}"
)
+
def get_available_years():
- """获取数据库中所有可用的年份"""
- print("开始获取可用年份列表")
- conn = None
+ """获取数据库中已有历史记录表的年份。"""
+ conn = get_db()
try:
- # 获取数据库连接
- conn = get_db()
- if conn is None:
- print("无法连接到数据库")
- return [datetime.now().year] # 返回当前年份作为默认值
-
- cursor = conn.cursor()
-
- # 查询所有历史记录表
- cursor.execute("""
- SELECT name FROM sqlite_master
- WHERE type='table' AND name LIKE 'bilibili_history_%'
- ORDER BY name DESC
- """)
-
- tables = cursor.fetchall()
- print(f"找到的表: {tables}")
-
- years = []
- for (table_name,) in tables:
- try:
- year = int(table_name.split('_')[-1])
- years.append(year)
- print(f"添加年份: {year} (来自表 {table_name})")
- except (ValueError, IndexError) as e:
- print(f"处理表名 {table_name} 时出错: {e}")
- continue
-
- sorted_years = sorted(years, reverse=True)
- print(f"最终年份列表: {sorted_years}")
-
- # 如果没有找到年份,返回当前年份
- if not sorted_years:
- current_year = datetime.now().year
- print(f"未找到年份,返回当前年份: {current_year}")
- return [current_year]
-
- return sorted_years
- except sqlite3.Error as e:
- print(f"获取年份列表时发生数据库错误: {e}")
- return [datetime.now().year] # 返回当前年份作为默认值
- except Exception as e:
- print(f"获取年份列表时发生未知错误: {e}")
- return [datetime.now().year] # 返回当前年份作为默认值
+ tables = conn.execute(
+ "SELECT name FROM sqlite_master WHERE type='table' AND name LIKE 'bilibili_history_%'"
+ ).fetchall()
+ return sorted(
+ (int(name.rsplit('_', 1)[-1]) for (name,) in tables if name.rsplit('_', 1)[-1].isdigit()),
+ reverse=True,
+ )
finally:
- if conn:
- try:
- conn.close()
- print("数据库连接已关闭")
- except Exception as e:
- print(f"关闭数据库连接时出错: {e}")
+ conn.close()
@router.get("/available-years", summary="获取可用的年份列表")
async def get_years():
- """获取所有可用的年份列表"""
- years = get_available_years()
- if not years:
- return {
- "status": "error",
- "message": "未找到任何历史记录数据"
- }
-
- return {
- "status": "success",
- "data": years
- }
-
-def _process_image_url(url: str, image_type: str, use_local: bool, use_sessdata: bool = True) -> str:
- """处理图片URL,根据需要返回本地路径或原始URL
-
- Args:
- url: 原始图片URL
- image_type: 图片类型 (covers 或 avatars)
- use_local: 是否使用本地图片
- use_sessdata: 是否在下载图片时使用SESSDATA(对于公开内容如视频封面和头像,可以不使用SESSDATA)
-
- Returns:
- str: 处理后的URL
- """
-
- # 如果不使用本地图片或URL为空,直接返回原始URL
- if not use_local or not url:
- # 如果不使用SESSDATA,移除URL中可能包含的SESSDATA参数
- if not use_sessdata and '?' in url:
- # 移除URL中的所有参数,保留纯净的图片URL
- url = url.split('?')[0]
- return url
-
- try:
- # 计算URL的哈希值(只使用基本URL部分,不包含参数)
- base_url = url.split('?')[0] if '?' in url else url
- file_hash = hashlib.md5(base_url.encode()).hexdigest()
-
- # 检查图片类型是否有效
- if image_type not in ('covers', 'avatars'):
- print(f"无效的图片类型: {image_type}")
- return url
-
- # 构建本地图片URL(返回相对路径,前端自行拼接域名)
- base_url = "/images/local"
- local_url = f"{base_url}/{image_type}/{file_hash}"
-
- return local_url
-
- except Exception as e:
- print(f"处理图片URL时出错: {str(e)}")
- return url
+ return {"status": "success", "data": get_available_years()}
def _build_original_url(record: dict) -> str:
"""根据历史记录字段构建可打开的B站原始链接"""
@@ -210,58 +111,27 @@ def _build_original_url(record: dict) -> str:
return ''
-def _process_record(record: dict, use_local: bool, use_sessdata: bool = True) -> dict:
- """处理单条记录,转换图片URL
-
- Args:
- record: 原始记录
- use_local: 是否使用本地图片
- use_sessdata: 是否在下载图片时使用SESSDATA
-
- Returns:
- dict: 处理后的记录
- """
- # 处理封面图片
- if 'cover' in record and record['cover']:
- record['cover'] = _process_image_url(record['cover'], 'covers', use_local, use_sessdata)
-
- # 处理作者头像
- if 'author_face' in record and record['author_face']:
- record['author_face'] = _process_image_url(record['author_face'], 'avatars', use_local, use_sessdata)
- # 解析 covers 字段的 JSON 字符串
- if 'covers' in record and record['covers']:
+def _process_record(record: dict) -> dict:
+ """解析封面列表并提供历史记录的原始链接。"""
+ covers = record.get("covers")
+ if isinstance(covers, str):
try:
- # 如果是字符串,尝试解析为 JSON
- if isinstance(record['covers'], str):
- covers = json.loads(record['covers'])
- # 处理每个封面URL
- if isinstance(covers, list):
- record['covers'] = [_process_image_url(url, 'covers', use_local, use_sessdata) for url in covers]
- else:
- record['covers'] = []
- else:
- record['covers'] = []
+ covers = json.loads(covers)
except json.JSONDecodeError:
- print(f"解析 covers JSON 失败: {record['covers']}")
- record['covers'] = []
- else:
- record['covers'] = []
-
- record['original_url'] = _build_original_url(record)
-
+ covers = []
+ record["covers"] = covers if isinstance(covers, list) else []
+ record["original_url"] = _build_original_url(record)
return record
@router.get("/all", summary="分页查询历史记录")
async def get_history_page(
- page: int = Query(1, description="当前页码"),
- size: int = Query(10, description="每页记录数"),
+ page: int = Query(1, ge=1, description="当前页码"),
+ size: int = Query(10, ge=1, description="每页记录数"),
sort_order: int = Query(0, description="排序顺序,0为降序,1为升序"),
tag_name: Optional[str] = Query(None, description="视频子分区名称"),
main_category: Optional[str] = Query(None, description="主分区名称"),
date_range: Optional[str] = Query(None, description="日期范围,格式为yyyyMMdd-yyyyMMdd"),
- use_local_images: bool = Query(False, description="是否使用本地图片"),
- use_sessdata: bool = Query(True, description="是否在图片URL中使用SESSDATA"),
business: Optional[str] = Query(None, description="业务类型,如archive(普通视频)、pgc(番剧)、live(直播)、article-list(文集)、article(文章)")
):
"""分页查询历史记录,支持跨年份查询"""
@@ -272,11 +142,10 @@ async def get_history_page(
print(f"子分区名称(tag_name): {tag_name if tag_name else '无'}")
print(f"主分区名称(main_category): {main_category if main_category else '无'}")
print(f"日期范围(date_range): {date_range if date_range else '无'}")
- print(f"是否使用本地图片(use_local_images): {use_local_images}")
- print(f"是否使用SESSDATA(use_sessdata): {use_sessdata}")
print(f"业务类型(business): {business if business else '全部'}")
print("=====================\n")
+ conn = None
try:
conn = get_db()
cursor = conn.cursor()
@@ -285,8 +154,14 @@ async def get_history_page(
available_years = get_available_years()
if not available_years:
return {
- "status": "error",
- "message": "未找到任何历史记录数据"
+ "status": "success",
+ "data": {
+ "records": [],
+ "total": 0,
+ "size": size,
+ "current": page,
+ "available_years": [],
+ },
}
# 构建UNION ALL查询
@@ -357,7 +232,7 @@ async def get_history_page(
for row in cursor.fetchall():
record = dict(zip(columns, row))
- record = _process_record(record, use_local_images, use_sessdata)
+ record = _process_record(record)
records.append(record)
print("=== 响应结果 ===")
@@ -400,80 +275,6 @@ def process_search_keyword(keyword: str) -> str:
keyword = ' '.join(keyword.split())
return keyword
-def create_fts_table(conn, table_name: str):
- """创建全文搜索虚拟表"""
- cursor = conn.cursor()
-
- try:
- # 检查原表是否存在
- cursor.execute(f"""
- SELECT name FROM sqlite_master
- WHERE type='table' AND name='bilibili_history_{table_name}'
- """)
- if not cursor.fetchone():
- return False
-
- # 创建FTS5虚拟表
- fts_table = f"bilibili_history_{table_name}_fts"
- cursor.execute(f"""
- CREATE VIRTUAL TABLE IF NOT EXISTS {fts_table} USING fts5(
- title,
- author_name,
- tag_name,
- main_category,
- remark,
- title_pinyin,
- content='bilibili_history_{table_name}',
- content_rowid='id'
- )
- """)
-
- # 创建触发器以保持FTS表同步
- cursor.execute(f"""
- CREATE TRIGGER IF NOT EXISTS history_{table_name}_ai AFTER INSERT ON bilibili_history_{table_name} BEGIN
- INSERT INTO {fts_table}(
- rowid, title, author_name, tag_name, main_category, remark, title_pinyin
- )
- VALUES (
- new.id, new.title, new.author_name, new.tag_name, new.main_category,
- new.remark, new.title
- );
- END;
- """)
-
- cursor.execute(f"""
- CREATE TRIGGER IF NOT EXISTS history_{table_name}_ad AFTER DELETE ON bilibili_history_{table_name} BEGIN
- INSERT INTO {fts_table}({fts_table}, rowid, title, author_name, tag_name, main_category, remark)
- VALUES('delete', old.id, old.title, old.author_name, old.tag_name, old.main_category, old.remark);
- END;
- """)
-
- cursor.execute(f"""
- CREATE TRIGGER IF NOT EXISTS history_{table_name}_au AFTER UPDATE ON bilibili_history_{table_name} BEGIN
- INSERT INTO {fts_table}({fts_table}, rowid, title, author_name, tag_name, main_category, remark)
- VALUES('delete', old.id, old.title, old.author_name, old.tag_name, old.main_category, old.remark);
- INSERT INTO {fts_table}(rowid, title, author_name, tag_name, main_category, remark)
- VALUES (new.id, new.title, new.author_name, new.tag_name, new.main_category, new.remark);
- END;
- """)
-
- # 初始化FTS表数据
- cursor.execute(f"""
- INSERT OR REPLACE INTO {fts_table}(
- rowid, title, author_name, tag_name, main_category, remark, title_pinyin
- )
- SELECT
- id, title, author_name, tag_name, main_category, remark, title
- FROM bilibili_history_{table_name}
- """)
-
- conn.commit()
- return True
-
- except sqlite3.Error as e:
- print(f"创建FTS表时出错: {str(e)}")
- conn.rollback()
- return False
def build_field_search_conditions(field: str, search: str, exact_match: bool) -> tuple:
"""构建字段搜索条件"""
@@ -498,25 +299,23 @@ def build_field_search_conditions(field: str, search: str, exact_match: bool) ->
print("===================")
return condition, params
+
@router.get("/search", summary="搜索历史记录")
async def search_history(
- page: int = Query(1, description="当前页码"),
- size: int = Query(30, description="每页记录数"),
+ page: int = Query(1, ge=1, description="当前页码"),
+ size: int = Query(30, ge=1, description="每页记录数"),
sortOrder: int = Query(0, description="排序顺序,0为降序,1为升序"),
search: Optional[str] = Query(None, description="搜索关键词"),
- search_type: Optional[str] = Query("all", description="搜索类型:all-全部, title-标题, author-作者, tag-分区, remark-备注"),
- use_sessdata: bool = Query(True, description="是否在图片URL中使用SESSDATA"),
- use_local_images: bool = Query(False, description="是否使用本地图片")
+ search_type: Optional[str] = Query("all", description="搜索类型:all-全部, title-标题, author-作者, tag-分区"),
):
"""高级搜索历史记录,按观看时间排序,使用模糊匹配"""
+ conn = None
try:
print("\n=== 搜索开始 ===")
print(f"关键词: {search}")
print(f"类型: {search_type}")
print(f"匹配方式: 模糊匹配")
print(f"排序顺序: {'升序' if sortOrder == 1 else '降序'}")
- print(f"是否使用SESSDATA: {use_sessdata}")
- print(f"是否使用本地图片: {use_local_images}")
print("==============\n")
conn = get_db()
@@ -526,8 +325,14 @@ async def search_history(
available_years = get_available_years()
if not available_years:
return {
- "status": "error",
- "message": "未找到任何历史记录数据"
+ "status": "success",
+ "data": {
+ "records": [],
+ "total": 0,
+ "size": size,
+ "current": page,
+ "available_years": [],
+ },
}
# 构建每个年份的子查询
@@ -538,8 +343,7 @@ async def search_history(
field_map = {
"title": "title",
"author": "author_name",
- "tag": "tag_name",
- "remark": "remark"
+ "tag": "tag_name"
}
where_clause = ""
@@ -620,7 +424,7 @@ async def search_history(
for row in cursor.fetchall():
record = dict(zip(columns, row))
- record = _process_record(record, use_local_images, use_sessdata)
+ record = _process_record(record)
records.append(record)
return {
@@ -647,479 +451,3 @@ async def search_history(
finally:
if conn:
conn.close()
-
-@router.get("/remarks", summary="获取所有备注")
-async def get_all_remarks(
- page: int = Query(1, description="当前页码"),
- size: int = Query(10, description="每页记录数"),
- sort_order: int = Query(0, description="排序顺序,0为降序,1为升序")
-):
- """获取所有带有备注的视频记录
-
- Args:
- page: 当前页码
- size: 每页记录数
- sort_order: 排序顺序,0为降序,1为升序
-
- Returns:
- dict: 包含分页的备注记录列表
- """
- try:
- conn = get_db()
- cursor = conn.cursor()
-
- # 获取所有年份的表
- years = get_available_years()
- if not years:
- return {
- "status": "error",
- "message": "未找到任何历史记录数据"
- }
-
- # 构建UNION ALL查询,只查询有备注的记录
- queries = []
- for year in years:
- table_name = f"bilibili_history_{year}"
- queries.append(f"""
- SELECT *
- FROM {table_name}
- WHERE remark != ''
- """)
-
- # 组合所有查询,添加排序和分页
- base_query = " UNION ALL ".join(queries)
- count_query = f"SELECT COUNT(*) FROM ({base_query})"
-
- # 添加排序和分页(按备注时间排序)
- final_query = f"""
- SELECT * FROM ({base_query})
- ORDER BY remark_time {('ASC' if sort_order == 1 else 'DESC')}
- LIMIT ? OFFSET ?
- """
-
- # 获取总记录数
- cursor.execute(count_query)
- total = cursor.fetchone()[0]
-
- # 执行分页查询
- cursor.execute(final_query, [size, (page - 1) * size])
-
- # 获取列名
- columns = [description[0] for description in cursor.description]
- records = []
-
- # 构建记录
- for row in cursor.fetchall():
- record = dict(zip(columns, row))
- # 解析JSON字符串
- if 'covers' in record and record['covers']:
- try:
- record['covers'] = json.loads(record['covers'])
- except json.JSONDecodeError:
- record['covers'] = []
- records.append(record)
-
- return {
- "status": "success",
- "data": {
- "records": records,
- "total": total,
- "size": size,
- "current": page
- }
- }
-
- except sqlite3.Error as e:
- raise HTTPException(
- status_code=500,
- detail=f"数据库操作失败: {str(e)}"
- )
- finally:
- if conn:
- conn.close()
-
-class UpdateRemarkRequest(BaseModel):
- bvid: str
- view_at: int
- remark: str
-
-@router.post("/update-remark", summary="更新视频备注")
-async def update_video_remark(request: UpdateRemarkRequest):
- """更新视频备注
-
- Args:
- request: 包含bvid、view_at和remark的请求体
-
- Returns:
- dict: 更新操作的结果
- """
- try:
- conn = get_db()
- cursor = conn.cursor()
-
- # 从时间戳获取年份
- year = datetime.fromtimestamp(request.view_at).year
- table_name = f"bilibili_history_{year}"
-
- # 检查表是否存在
- cursor.execute("""
- SELECT name FROM sqlite_master
- WHERE type='table' AND name=?
- """, (table_name,))
-
- if not cursor.fetchone():
- raise HTTPException(
- status_code=404,
- detail=f"未找到 {year} 年的历史记录数据"
- )
-
- # 更新备注和备注时间
- current_time = int(datetime.now().timestamp())
- query = f"""
- UPDATE {table_name}
- SET remark = ?, remark_time = ?
- WHERE bvid = ? AND view_at = ?
- """
- cursor.execute(query, (request.remark, current_time, request.bvid, request.view_at))
- conn.commit()
-
- if cursor.rowcount == 0:
- raise HTTPException(
- status_code=404,
- detail="未找到指定的视频记录"
- )
-
- return {
- "status": "success",
- "message": "备注更新成功",
- "data": {
- "bvid": request.bvid,
- "view_at": request.view_at,
- "remark": request.remark,
- "remark_time": current_time
- }
- }
-
- except sqlite3.Error as e:
- raise HTTPException(
- status_code=500,
- detail=f"数据库操作失败: {str(e)}"
- )
- finally:
- if conn:
- conn.close()
-
-@router.post("/reset-database", summary="重置数据库")
-async def reset_database():
- """重置数据库
-
- 删除现有的数据库文件和last_import.json文件,用于重新导入数据
-
- Returns:
- dict: 操作结果
- """
- try:
- # 获取文件路径
- db_path = get_output_path(config['db_file'])
- last_import_path = get_output_path('last_import.json')
-
- # 删除数据库文件
- if os.path.exists(db_path):
- try:
- os.remove(db_path)
- except Exception as e:
- raise HTTPException(
- status_code=500,
- detail=f"删除数据库文件失败: {str(e)}"
- )
-
- # 删除last_import.json文件
- if os.path.exists(last_import_path):
- try:
- os.remove(last_import_path)
- except Exception as e:
- raise HTTPException(
- status_code=500,
- detail=f"删除last_import.json文件失败: {str(e)}"
- )
-
- return {
- "status": "success",
- "message": "数据库已重置",
- "data": {
- "deleted_files": [
- os.path.basename(db_path),
- os.path.basename(last_import_path)
- ]
- }
- }
-
- except Exception as e:
- raise HTTPException(
- status_code=500,
- detail=f"重置数据库失败: {str(e)}"
- )
-
-@router.get("/sqlite-version", summary="获取SQLite版本")
-async def get_sqlite_version():
- """获取 SQLite 版本信息"""
- try:
- conn = get_db()
- cursor = conn.cursor()
-
- version_info = {
- "sqlite_version": None,
- "user_version": None,
- "database_settings": {
- "journal_mode": None,
- "synchronous": None,
- "legacy_format": None,
- "page_size": None,
- "cache_size": None,
- "encoding": None
- }
- }
-
- # 获取 SQLite 版本信息
- try:
- cursor.execute('SELECT sqlite_version()')
- result = cursor.fetchone()
- version_info["sqlite_version"] = result[0] if result else "未知"
- except sqlite3.Error as e:
- print(f"获取 SQLite 版本失败: {e}")
-
- # 获取所有 PRAGMA 设置
- pragmas = {
- "user_version": None,
- "journal_mode": "journal_mode",
- "synchronous": "synchronous",
- "legacy_file_format": "legacy_format",
- "page_size": "page_size",
- "cache_size": "cache_size",
- "encoding": "encoding"
- }
-
- # 获取用户版本
- try:
- cursor.execute('PRAGMA user_version')
- result = cursor.fetchone()
- version_info["user_version"] = result[0] if result else 0
- except sqlite3.Error as e:
- print(f"获取用户版本失败: {e}")
-
- # 获取其他 PRAGMA 设置
- for pragma_name, setting_name in pragmas.items():
- if setting_name: # 跳过已经处理的 user_version
- try:
- cursor.execute(f'PRAGMA {pragma_name}')
- result = cursor.fetchone()
- if result is not None:
- value = result[0]
- # 特殊处理某些值
- if pragma_name == "legacy_file_format":
- value = bool(int(value)) if value is not None else False
- elif pragma_name == "synchronous":
- value = {0: "OFF", 1: "NORMAL", 2: "FULL"}.get(value, value)
- version_info["database_settings"][setting_name] = value
- except sqlite3.Error as e:
- print(f"获取 {pragma_name} 设置失败: {e}")
-
- # 获取数据库文件信息
- db_path = get_output_path(config['db_file'])
- db_exists = os.path.exists(db_path)
- db_size = os.path.getsize(db_path) if db_exists else 0
-
- # 添加数据库文件信息
- version_info["database_file"] = {
- "exists": db_exists,
- "size_bytes": db_size,
- "size_mb": round(db_size / (1024 * 1024), 2) if db_exists else 0,
- "path": db_path
- }
-
- return {
- "status": "success",
- "data": version_info
- }
-
- except Exception as e:
- return {
- "status": "error",
- "message": f"获取版本信息失败: {str(e)}"
- }
- finally:
- if conn:
- conn.close()
-
-class BatchRemarksRequest(BaseModel):
- items: list[dict]
-
-@router.post("/batch-remarks", summary="批量获取视频备注")
-async def get_video_remarks(request: BatchRemarksRequest):
- """批量获取视频备注
-
- Args:
- request: 包含 items 列表的请求体,每个 item 包含 bvid 和 view_at
-
- Returns:
- dict: 包含所有视频备注信息的响应
- """
- try:
- conn = get_db()
- cursor = conn.cursor()
-
- # 按年份分组记录
- records_by_year = {}
- for record in request.items:
- year = datetime.fromtimestamp(record['view_at']).year
- if year not in records_by_year:
- records_by_year[year] = []
- records_by_year[year].append((record['bvid'], record['view_at']))
-
- # 存储所有查询结果
- results = {}
-
- # 处理每个年份的数据
- for year, year_records in records_by_year.items():
- table_name = f"bilibili_history_{year}"
-
- # 检查表是否存在
- cursor.execute("""
- SELECT name FROM sqlite_master
- WHERE type='table' AND name=?
- """, (table_name,))
-
- if not cursor.fetchone():
- print(f"未找到 {year} 年的历史记录数据")
- continue
-
- # 为每个(bvid, view_at)对执行单独的查询
- for bvid, view_at in year_records:
- query = f"""
- SELECT bvid, view_at, title, remark, remark_time
- FROM {table_name}
- WHERE bvid = ? AND view_at = ?
- """
-
- cursor.execute(query, (bvid, view_at))
- row = cursor.fetchone()
-
- if row:
- bvid, view_at, title, remark, remark_time = row
- results[f"{bvid}_{view_at}"] = {
- "bvid": bvid,
- "view_at": view_at,
- "title": title,
- "remark": remark,
- "remark_time": remark_time
- }
-
- return {
- "status": "success",
- "data": results
- }
-
- except sqlite3.Error as e:
- raise HTTPException(
- status_code=500,
- detail=f"数据库操作失败: {str(e)}"
- )
- finally:
- if conn:
- conn.close()
-
-@router.get("/by_cid/{cid}", summary="根据CID查询视频详情")
-async def get_video_by_cid(
- cid: int,
- use_local_images: bool = Query(False, description="是否使用本地图片"),
- use_sessdata: bool = Query(True, description="是否在图片URL中使用SESSDATA")
-):
- """
- 根据视频CID查询详细信息
-
- Args:
- cid: 视频的CID
- use_local_images: 是否使用本地图片
- use_sessdata: 是否在图片URL中使用SESSDATA
-
- Returns:
- 视频的详细信息,包括标题、封面和作者信息
- """
- print(f"【调试】开始根据CID={cid}查询视频信息")
- try:
- conn = get_db()
- cursor = conn.cursor()
-
- # 获取所有年份表
- years = get_available_years()
- if not years:
- print(f"【调试】未找到任何历史记录数据表")
- return {
- "status": "error",
- "message": "未找到任何历史记录数据"
- }
-
- print(f"【调试】找到以下年份表: {years}")
-
- # 构建UNION ALL查询
- queries = []
- for year in years:
- table_name = f"bilibili_history_{year}"
- # 选择与视频相关的所有字段
- queries.append(f"""
- SELECT
- id, title, long_title, cover, covers, uri, oid, epid, bvid, page,
- cid, part, business, dt, videos, author_name, author_face, author_mid,
- view_at, progress, badge, show_title, duration, current, total,
- new_desc, is_finish, is_fav, kid, tag_name, live_status, main_category
- FROM {table_name}
- WHERE cid = {cid}
- """)
-
- # 组合所有查询,LIMIT放在最后,不使用括号
- union_query = f"{' UNION ALL '.join(queries)} LIMIT 1"
- print(f"【调试】CID查询SQL: {union_query}")
-
- # 执行查询
- cursor.execute(union_query)
- columns = [description[0] for description in cursor.description]
-
- record = cursor.fetchone()
- if not record:
- print(f"【调试】未找到CID为{cid}的视频记录")
- return {
- "status": "error",
- "message": f"未找到CID为{cid}的视频记录"
- }
-
- print(f"【调试】找到CID={cid}的记录,开始处理")
-
- # 构建记录字典
- record_dict = dict(zip(columns, record))
-
- # 打印记录内容以便调试
- print(f"【调试】原始记录: {record_dict}")
-
- # 处理图片URL
- record_dict = _process_record(record_dict, use_local_images, use_sessdata)
-
- # 添加视频的播放时间(人类可读格式)
- if 'view_at' in record_dict and record_dict['view_at']:
- record_dict['view_time'] = datetime.fromtimestamp(record_dict['view_at']).strftime("%Y-%m-%d %H:%M:%S")
-
- print(f"【调试】处理后的记录: {record_dict}")
-
- conn.close()
-
- return {
- "status": "success",
- "data": record_dict
- }
- except Exception as e:
- print(f"查询CID时出错: {str(e)}")
- if 'conn' in locals() and conn:
- conn.close()
- return {
- "status": "error",
- "message": f"查询视频详情时出错: {str(e)}"
- }
diff --git a/routers/image_downloader.py b/routers/image_downloader.py
deleted file mode 100644
index 5263178..0000000
--- a/routers/image_downloader.py
+++ /dev/null
@@ -1,183 +0,0 @@
-import os
-import sqlite3
-from typing import Optional
-
-from fastapi import APIRouter, BackgroundTasks, HTTPException
-from fastapi.responses import FileResponse
-
-from scripts.image_downloader import ImageDownloader
-from scripts.utils import get_output_path
-
-router = APIRouter()
-downloader = ImageDownloader()
-
-def get_history_db():
- """获取历史记录数据库连接"""
- db_path = get_output_path('bilibili_history.db')
- return sqlite3.connect(db_path)
-
-@router.post("/start", summary="开始下载图片")
-async def start_download(
- background_tasks: BackgroundTasks,
- year: Optional[int] = None,
- use_sessdata: bool = True
-):
- """开始下载图片
-
- Args:
- year: 指定年份,不指定则下载所有年份
- use_sessdata: 是否在下载图片时使用SESSDATA(对于公开内容如视频封面和头像,可以不使用SESSDATA)
- """
- # 包装下载函数和状态更新
- def download_with_status_update(year=None, use_sessdata=True):
- try:
- # 执行下载
- downloader.start_download(year, use_sessdata)
- except Exception as e:
- print(f"下载过程发生错误: {str(e)}")
- finally:
- # 确保无论下载成功还是失败,状态都会被设置为已完成
- print("\n=== 下载任务完成,更新状态 ===")
- downloader.is_downloading = False
- print("下载状态已设置为已完成")
-
- # 在后台任务中执行包装函数
- background_tasks.add_task(download_with_status_update, year, use_sessdata)
-
- return {
- "status": "success",
- "message": f"开始下载{'所有年份' if year is None else f'{year}年'}的图片"
- }
-
-@router.post("/stop", summary="停止下载图片")
-async def stop_download():
- """停止当前下载任务
-
- Returns:
- dict: 包含停止状态和当前下载统计的响应
- """
- try:
- result = downloader.stop_download()
- return result
- except Exception as e:
- return {
- "status": "error",
- "message": f"停止下载失败: {str(e)}"
- }
-
-@router.get("/status", summary="获取下载状态")
-async def get_status():
- """获取下载状态"""
- stats = downloader.get_download_stats()
-
- return {
- "status": "success",
- "data": stats
- }
-
-@router.post("/clear", summary="清空所有图片")
-async def clear_images():
- """清空所有图片和下载状态"""
- try:
- success = downloader.clear_all_images()
- if success:
- return {
- "status": "success",
- "message": "已清空所有图片和下载状态",
- "data": {
- "cleared_paths": [
- "output/images/covers",
- "output/images/avatars",
- "output/images/orphaned_covers",
- "output/images/orphaned_avatars"
- ],
- "status_file": "output/download_status.json"
- }
- }
- else:
- return {
- "status": "error",
- "message": "清空图片失败,请查看日志了解详细信息"
- }
- except Exception as e:
- return {
- "status": "error",
- "message": f"清空图片时发生错误: {str(e)}"
- }
-
-@router.get("/local/{image_type}/{file_hash}", summary="获取本地图片")
-async def get_local_image(image_type: str, file_hash: str):
- """获取本地图片
-
- Args:
- image_type: 图片类型 (covers 或 avatars)
- file_hash: 图片文件的哈希值
-
- Returns:
- FileResponse: 图片文件响应
- """
-
- # 验证图片类型
- if image_type not in ('covers', 'avatars'):
- raise HTTPException(
- status_code=400,
- detail=f"无效的图片类型: {image_type}"
- )
-
- try:
- # 构建图片路径
- base_path = get_output_path('images')
- type_path = os.path.join(base_path, image_type)
- sub_dir = file_hash[:2] # 使用哈希的前两位作为子目录
-
- # 获取所有年份目录
- years = []
- if os.path.exists(type_path):
- for item in os.listdir(type_path):
- if item.isdigit():
- years.append(item)
-
- # 按年份倒序搜索图片
- for year in sorted(years, reverse=True):
- year_path = os.path.join(type_path, year)
- img_dir = os.path.join(year_path, sub_dir)
-
- if not os.path.exists(img_dir):
- continue
-
- # 查找所有可能的图片文件扩展名
- for ext in ('.jpg', '.jpeg', '.png', '.webp', '.gif'):
- img_path = os.path.join(img_dir, f"{file_hash}{ext}")
- if os.path.exists(img_path):
- print(f"找到图片文件: {img_path}")
- return FileResponse(
- img_path,
- media_type=f"image/{ext[1:]}" if ext != '.jpg' else "image/jpeg"
- )
-
- # 如果在年份目录中没有找到,尝试在根目录中查找
- img_dir = os.path.join(type_path, sub_dir)
- if os.path.exists(img_dir):
- for ext in ('.jpg', '.jpeg', '.png', '.webp', '.gif'):
- img_path = os.path.join(img_dir, f"{file_hash}{ext}")
- if os.path.exists(img_path):
- print(f"找到图片文件: {img_path}")
- return FileResponse(
- img_path,
- media_type=f"image/{ext[1:]}" if ext != '.jpg' else "image/jpeg"
- )
-
- # 如果没有找到任何匹配的文件
- raise HTTPException(
- status_code=404,
- detail=f"图片不存在: {file_hash}"
- )
-
- except Exception as e:
- if isinstance(e, HTTPException):
- raise e
- print(f"获取本地图片时出错: {str(e)}")
- raise HTTPException(
- status_code=500,
- detail=f"获取图片失败: {str(e)}"
- )
\ No newline at end of file
diff --git a/routers/import_data_mysql.py b/routers/import_data_mysql.py
deleted file mode 100644
index b4e43dc..0000000
--- a/routers/import_data_mysql.py
+++ /dev/null
@@ -1,12 +0,0 @@
-from fastapi import APIRouter, HTTPException, BackgroundTasks
-from scripts.import_database import import_history
-
-router = APIRouter()
-
-@router.post("/import_data_mysql", summary="导入 Bilibili 历史数据到 MySQL")
-def import_bilibili_history(background_tasks: BackgroundTasks):
- try:
- background_tasks.add_task(import_history)
- return {"status": "success", "message": "数据导入任务已开始。"}
- except Exception as e:
- raise HTTPException(status_code=500, detail=str(e))
diff --git a/routers/import_data_sqlite.py b/routers/import_data_sqlite.py
index 8039f19..b80446f 100644
--- a/routers/import_data_sqlite.py
+++ b/routers/import_data_sqlite.py
@@ -1,7 +1,6 @@
from fastapi import APIRouter, HTTPException
from pydantic import BaseModel
from scripts.import_sqlite import import_all_history_files
-from .interaction_records import import_interactions_to_history_once
router = APIRouter()
@@ -15,14 +14,10 @@ def import_history():
result = import_all_history_files()
if result["status"] == "success":
- interaction_import = import_interactions_to_history_once()
return {
"status": "success",
"message": result["message"],
- "data": {
- "history_import": result,
- "interaction_history_import": interaction_import,
- },
+ "data": result,
}
else:
raise HTTPException(status_code=500, detail=result["message"])
diff --git a/routers/interaction_records.py b/routers/interaction_records.py
deleted file mode 100644
index ee21a83..0000000
--- a/routers/interaction_records.py
+++ /dev/null
@@ -1,1227 +0,0 @@
-import json
-import os
-import sqlite3
-import time
-from collections import defaultdict
-from datetime import datetime
-from typing import Any, Dict, List, Optional, Tuple
-
-import requests
-from fastapi import APIRouter, Query
-from pydantic import BaseModel, Field
-
-from scripts.utils import get_database_path, get_output_path, load_config
-
-router = APIRouter()
-
-DB_PATH = get_database_path("bilibili_interactions.db")
-BILI_NAV_URL = "https://api.bilibili.com/x/web-interface/nav"
-BILI_CREATED_FOLDERS_URL = "https://api.bilibili.com/x/v3/fav/folder/created/list-all"
-BILI_FAVORITE_CONTENTS_URL = "https://api.bilibili.com/x/v3/fav/resource/list"
-BILI_LIKE_VIDEOS_URL = "https://api.bilibili.com/x/space/like/video"
-BILI_COIN_VIDEOS_URL = "https://api.bilibili.com/x/space/coin/video"
-HISTORY_IMPORT_SOURCE = "__history_import__"
-HISTORY_IMPORT_BADGE = "互动补充"
-HISTORY_IMPORT_REMARK_PREFIX = "互动补充:"
-SOURCE_LABELS = {"favorite": "收藏", "like": "点赞", "coin": "投币"}
-
-
-CREATE_INTERACTION_TABLE = """
-CREATE TABLE IF NOT EXISTS interaction_records (
- id INTEGER PRIMARY KEY AUTOINCREMENT,
- dedupe_key TEXT NOT NULL UNIQUE,
- source TEXT NOT NULL,
- oid INTEGER DEFAULT 0,
- aid INTEGER DEFAULT 0,
- bvid TEXT,
- title TEXT NOT NULL,
- cover TEXT,
- author_mid INTEGER DEFAULT 0,
- author_name TEXT,
- author_face TEXT,
- tname TEXT,
- duration INTEGER DEFAULT 0,
- pubtime INTEGER DEFAULT 0,
- ctime INTEGER DEFAULT 0,
- action_time INTEGER DEFAULT 0,
- action_time_source TEXT DEFAULT 'unknown',
- effective_time INTEGER DEFAULT 0,
- media_id INTEGER DEFAULT 0,
- media_title TEXT,
- raw_json TEXT,
- fetch_time INTEGER NOT NULL
-);
-"""
-
-CREATE_SYNC_STATE_TABLE = """
-CREATE TABLE IF NOT EXISTS interaction_sync_state (
- source TEXT PRIMARY KEY,
- last_sync_time INTEGER NOT NULL,
- status TEXT NOT NULL,
- message TEXT,
- total_records INTEGER DEFAULT 0,
- inserted_count INTEGER DEFAULT 0,
- updated_count INTEGER DEFAULT 0,
- details_json TEXT
-);
-"""
-
-CREATE_INDEXES = [
- "CREATE INDEX IF NOT EXISTS idx_interaction_source ON interaction_records (source);",
- "CREATE INDEX IF NOT EXISTS idx_interaction_bvid ON interaction_records (bvid);",
- "CREATE INDEX IF NOT EXISTS idx_interaction_author_mid ON interaction_records (author_mid);",
- "CREATE INDEX IF NOT EXISTS idx_interaction_action_time ON interaction_records (action_time);",
- "CREATE INDEX IF NOT EXISTS idx_interaction_effective_time ON interaction_records (effective_time);",
- "CREATE INDEX IF NOT EXISTS idx_interaction_media_id ON interaction_records (media_id);",
-]
-
-
-class InteractionSyncRequest(BaseModel):
- include_favorites: bool = Field(True, description="是否同步收藏记录")
- include_likes: bool = Field(True, description="是否同步点赞记录")
- include_coins: bool = Field(True, description="是否同步投币记录")
- max_favorite_pages: int = Field(0, ge=0, description="每个收藏夹最多同步页数,0表示不限")
- favorite_page_size: int = Field(20, ge=1, le=20, description="收藏夹分页大小")
- request_interval: float = Field(0.6, ge=0, le=10, description="请求间隔秒数")
- sessdata: Optional[str] = Field(None, description="用户的SESSDATA")
- up_mid: Optional[int] = Field(None, description="目标用户MID,不传则使用当前登录用户")
-
-
-def get_db_connection() -> sqlite3.Connection:
- """获取互动记录数据库连接并确保表结构存在。"""
- os.makedirs(os.path.dirname(DB_PATH), exist_ok=True)
- conn = sqlite3.connect(DB_PATH)
- conn.row_factory = sqlite3.Row
- cursor = conn.cursor()
- cursor.execute(CREATE_INTERACTION_TABLE)
- cursor.execute(CREATE_SYNC_STATE_TABLE)
- for index_sql in CREATE_INDEXES:
- cursor.execute(index_sql)
- conn.commit()
- return conn
-
-
-def get_headers(sessdata: Optional[str] = None) -> Dict[str, str]:
- """构建B站请求头。"""
- current_config = load_config()
- if sessdata is None:
- sessdata = current_config.get("SESSDATA", "")
-
- cookies = []
- if sessdata:
- clean_sessdata = str(sessdata).strip('"')
- cookies.append(f"SESSDATA={clean_sessdata}")
-
- for key in ("bili_jct", "DedeUserID", "DedeUserID__ckMd5"):
- value = current_config.get(key, "")
- if value:
- cookies.append(f"{key}={value}")
-
- headers = {
- "User-Agent": (
- "Mozilla/5.0 (Windows NT 10.0; Win64; x64) "
- "AppleWebKit/537.36 (KHTML, like Gecko) "
- "Chrome/116.0.0.0 Safari/537.36"
- ),
- "Referer": "https://www.bilibili.com/",
- }
- if cookies:
- headers["Cookie"] = "; ".join(cookies)
- return headers
-
-
-def _to_int(value: Any, default: int = 0) -> int:
- try:
- if value is None or value == "":
- return default
- return int(value)
- except (TypeError, ValueError):
- return default
-
-
-def _first_non_empty(*values: Any) -> Any:
- for value in values:
- if value not in (None, ""):
- return value
- return ""
-
-
-def _normalize_media_list(data: Any) -> List[Dict[str, Any]]:
- if isinstance(data, list):
- return [item for item in data if isinstance(item, dict)]
- if isinstance(data, dict):
- for key in ("list", "medias", "archives", "items"):
- value = data.get(key)
- if isinstance(value, list):
- return [item for item in value if isinstance(item, dict)]
- return []
-
-
-def _request_bili_json(
- url: str,
- headers: Dict[str, str],
- params: Optional[Dict[str, Any]] = None,
- timeout: int = 15,
-) -> Dict[str, Any]:
- response = requests.get(url, params=params, headers=headers, timeout=timeout)
- response.raise_for_status()
- data = response.json()
- if data.get("code") != 0:
- return {
- "status": "error",
- "code": data.get("code"),
- "message": data.get("message", "Unknown Bilibili API error"),
- "raw": data,
- }
- return {"status": "success", "data": data.get("data")}
-
-
-def get_current_user_info(headers: Dict[str, str]) -> Optional[Dict[str, Any]]:
- result = _request_bili_json(BILI_NAV_URL, headers)
- if result.get("status") != "success":
- return None
-
- data = result.get("data") or {}
- if not data.get("isLogin"):
- return None
- return {
- "uid": data.get("mid"),
- "uname": data.get("uname"),
- "face": data.get("face"),
- }
-
-
-def _normalize_interaction_record(
- source: str,
- item: Dict[str, Any],
- fetch_time: int,
- media_id: int = 0,
- media_title: str = "",
-) -> Dict[str, Any]:
- upper = item.get("upper") if isinstance(item.get("upper"), dict) else {}
- owner = item.get("owner") if isinstance(item.get("owner"), dict) else {}
- stat = item.get("stat") if isinstance(item.get("stat"), dict) else {}
-
- oid = _to_int(_first_non_empty(item.get("id"), item.get("oid"), item.get("aid")))
- aid = _to_int(_first_non_empty(item.get("aid"), item.get("id"), item.get("oid")))
- bvid = str(_first_non_empty(item.get("bvid"), item.get("bv_id")) or "")
- title = str(_first_non_empty(item.get("title"), item.get("name"), "Untitled"))
- cover = str(_first_non_empty(item.get("cover"), item.get("pic"), item.get("first_frame")) or "")
-
- author_mid = _to_int(_first_non_empty(upper.get("mid"), owner.get("mid"), item.get("author_mid"), item.get("mid")))
- author_name = str(_first_non_empty(upper.get("name"), owner.get("name"), item.get("author"), item.get("author_name")) or "")
- author_face = str(_first_non_empty(upper.get("face"), owner.get("face"), item.get("author_face")) or "")
-
- pubtime = _to_int(_first_non_empty(item.get("pubtime"), item.get("pubdate"), item.get("publish_time")))
- ctime = _to_int(item.get("ctime"))
- duration = _to_int(item.get("duration"))
- tname = str(_first_non_empty(item.get("tname"), item.get("typename"), item.get("type_name")) or "")
-
- if source == "favorite":
- action_time = _to_int(item.get("fav_time"))
- action_time_source = "fav_time" if action_time > 0 else "unknown"
- elif source == "coin":
- action_time = _to_int(item.get("time"))
- action_time_source = "time" if action_time > 0 else "unavailable"
- else:
- action_time = 0
- action_time_source = "unavailable"
-
- effective_time = action_time or pubtime or ctime or fetch_time
- identity = bvid or str(aid or oid or title)
- dedupe_key = f"{source}:{media_id}:{identity}"
-
- raw_item = dict(item)
- if stat and "cnt_info" not in raw_item:
- raw_item["cnt_info"] = stat
-
- return {
- "dedupe_key": dedupe_key,
- "source": source,
- "oid": oid,
- "aid": aid,
- "bvid": bvid,
- "title": title,
- "cover": cover,
- "author_mid": author_mid,
- "author_name": author_name,
- "author_face": author_face,
- "tname": tname,
- "duration": duration,
- "pubtime": pubtime,
- "ctime": ctime,
- "action_time": action_time,
- "action_time_source": action_time_source,
- "effective_time": effective_time,
- "media_id": media_id,
- "media_title": media_title,
- "raw_json": json.dumps(raw_item, ensure_ascii=False),
- "fetch_time": fetch_time,
- }
-
-
-def save_interaction_records(conn: sqlite3.Connection, records: List[Dict[str, Any]]) -> Dict[str, int]:
- """保存互动记录并返回新增/更新数量。"""
- if not records:
- return {"inserted": 0, "updated": 0}
-
- cursor = conn.cursor()
- inserted = 0
- updated = 0
-
- for record in records:
- cursor.execute(
- "SELECT id FROM interaction_records WHERE dedupe_key = ?",
- (record["dedupe_key"],),
- )
- exists = cursor.fetchone() is not None
- cursor.execute(
- """
- INSERT INTO interaction_records (
- dedupe_key, source, oid, aid, bvid, title, cover, author_mid,
- author_name, author_face, tname, duration, pubtime, ctime,
- action_time, action_time_source, effective_time, media_id,
- media_title, raw_json, fetch_time
- ) VALUES (
- :dedupe_key, :source, :oid, :aid, :bvid, :title, :cover, :author_mid,
- :author_name, :author_face, :tname, :duration, :pubtime, :ctime,
- :action_time, :action_time_source, :effective_time, :media_id,
- :media_title, :raw_json, :fetch_time
- )
- ON CONFLICT(dedupe_key) DO UPDATE SET
- oid = excluded.oid,
- aid = excluded.aid,
- bvid = excluded.bvid,
- title = excluded.title,
- cover = excluded.cover,
- author_mid = excluded.author_mid,
- author_name = excluded.author_name,
- author_face = excluded.author_face,
- tname = excluded.tname,
- duration = excluded.duration,
- pubtime = excluded.pubtime,
- ctime = excluded.ctime,
- action_time = excluded.action_time,
- action_time_source = excluded.action_time_source,
- effective_time = excluded.effective_time,
- media_title = excluded.media_title,
- raw_json = excluded.raw_json,
- fetch_time = excluded.fetch_time
- """,
- record,
- )
- if exists:
- updated += 1
- else:
- inserted += 1
-
- conn.commit()
- return {"inserted": inserted, "updated": updated}
-
-
-def update_sync_state(
- conn: sqlite3.Connection,
- source: str,
- status: str,
- message: str,
- total_records: int,
- inserted_count: int,
- updated_count: int,
- details: Optional[Dict[str, Any]] = None,
-) -> None:
- cursor = conn.cursor()
- cursor.execute(
- """
- INSERT INTO interaction_sync_state (
- source, last_sync_time, status, message, total_records,
- inserted_count, updated_count, details_json
- ) VALUES (?, ?, ?, ?, ?, ?, ?, ?)
- ON CONFLICT(source) DO UPDATE SET
- last_sync_time = excluded.last_sync_time,
- status = excluded.status,
- message = excluded.message,
- total_records = excluded.total_records,
- inserted_count = excluded.inserted_count,
- updated_count = excluded.updated_count,
- details_json = excluded.details_json
- """,
- (
- source,
- int(time.time()),
- status,
- message,
- total_records,
- inserted_count,
- updated_count,
- json.dumps(details or {}, ensure_ascii=False),
- ),
- )
- conn.commit()
-
-
-def _get_history_db_path() -> str:
- return get_output_path(load_config()["db_file"])
-
-
-def _get_history_tables(history_conn: sqlite3.Connection) -> List[str]:
- cursor = history_conn.cursor()
- cursor.execute("""
- SELECT name FROM sqlite_master
- WHERE type='table' AND name LIKE 'bilibili_history_%'
- ORDER BY name
- """)
- tables = []
- for (table_name,) in cursor.fetchall():
- try:
- int(str(table_name).split("_")[-1])
- except (ValueError, IndexError):
- continue
- tables.append(table_name)
- return tables
-
-
-def _history_import_state_completed(conn: sqlite3.Connection) -> bool:
- cursor = conn.cursor()
- cursor.execute(
- "SELECT status FROM interaction_sync_state WHERE source = ?",
- (HISTORY_IMPORT_SOURCE,),
- )
- row = cursor.fetchone()
- return bool(row and row["status"] == "success")
-
-
-def _has_imported_history_rows(history_conn: sqlite3.Connection) -> bool:
- cursor = history_conn.cursor()
- for table_name in _get_history_tables(history_conn):
- cursor.execute(
- f"""
- SELECT 1
- FROM {table_name}
- WHERE badge = ? OR remark LIKE ?
- LIMIT 1
- """,
- (HISTORY_IMPORT_BADGE, f"{HISTORY_IMPORT_REMARK_PREFIX}%"),
- )
- if cursor.fetchone():
- return True
- return False
-
-
-def has_interaction_history_import_completed() -> bool:
- """判断互动补充记录是否已经导入过主历史库。"""
- conn = get_db_connection()
- try:
- if _history_import_state_completed(conn):
- return True
- finally:
- conn.close()
-
- history_db_path = _get_history_db_path()
- if not os.path.exists(history_db_path):
- return False
-
- history_conn = sqlite3.connect(history_db_path)
- try:
- return _has_imported_history_rows(history_conn)
- finally:
- history_conn.close()
-
-
-def _create_history_table(history_conn: sqlite3.Connection, table_name: str) -> None:
- from config.sql_statements_sqlite import CREATE_INDEXES, CREATE_TABLE_DEFAULT
-
- cursor = history_conn.cursor()
- cursor.execute(CREATE_TABLE_DEFAULT.format(table=table_name))
- for index_sql in CREATE_INDEXES:
- cursor.execute(index_sql.format(table=table_name))
- history_conn.commit()
-
-
-def _ensure_history_fts(history_conn: sqlite3.Connection, year: int) -> None:
- try:
- from .history import create_fts_table
-
- create_fts_table(history_conn, str(year))
- except Exception:
- # FTS 只是搜索加速能力,失败不应阻断历史补充导入。
- pass
-
-
-def _history_table_exists(history_conn: sqlite3.Connection, table_name: str) -> bool:
- cursor = history_conn.cursor()
- cursor.execute(
- "SELECT 1 FROM sqlite_master WHERE type='table' AND name=?",
- (table_name,),
- )
- return cursor.fetchone() is not None
-
-
-def _load_existing_history_bvids(history_conn: sqlite3.Connection) -> set:
- existing_bvids = set()
- cursor = history_conn.cursor()
- for table_name in _get_history_tables(history_conn):
- cursor.execute(f"SELECT DISTINCT bvid FROM {table_name} WHERE bvid IS NOT NULL AND bvid != ''")
- existing_bvids.update(row[0] for row in cursor.fetchall())
- return existing_bvids
-
-
-def _next_history_id(sequence: int) -> int:
- return ((int(time.time() * 1000) - 1609459200000) << 22) | (sequence & 0x3FFFFF)
-
-
-def _interaction_row_to_history_record(row: sqlite3.Row, sequence: int) -> Optional[Tuple[Any, ...]]:
- source = row["source"]
- bvid = row["bvid"] or ""
- view_at = _to_int(row["effective_time"])
- if not bvid or view_at <= 0:
- return None
-
- source_label = SOURCE_LABELS.get(source, source)
- time_note = ""
- if row["action_time_source"] in ("unavailable", "unknown"):
- time_note = ",时间为系统推断"
-
- return (
- _next_history_id(sequence),
- row["title"] or "Untitled",
- "",
- row["cover"] or "",
- json.dumps([row["cover"]] if row["cover"] else [], ensure_ascii=False),
- f"https://www.bilibili.com/video/{bvid}",
- _to_int(row["aid"]) or _to_int(row["oid"]),
- 0,
- bvid,
- 1,
- 0,
- "",
- "archive",
- 0,
- 1,
- row["author_name"] or "",
- row["author_face"] or "",
- _to_int(row["author_mid"]),
- view_at,
- 0,
- HISTORY_IMPORT_BADGE,
- f"{source_label}记录",
- 0,
- "",
- 0,
- "Interaction supplement record; not a real viewing history item.",
- 0,
- 1 if source == "favorite" else 0,
- _to_int(row["aid"]) or _to_int(row["oid"]),
- row["tname"] or "",
- 0,
- "待定",
- f"{HISTORY_IMPORT_REMARK_PREFIX}{source_label}{time_note}",
- int(time.time()),
- )
-
-
-def import_interactions_to_history_once() -> Dict[str, Any]:
- """将互动记录一次性补充进主历史库,已导入过则直接跳过。"""
- interaction_conn = get_db_connection()
- history_conn: Optional[sqlite3.Connection] = None
- try:
- history_db_path = _get_history_db_path()
- os.makedirs(os.path.dirname(history_db_path), exist_ok=True)
- history_conn = sqlite3.connect(history_db_path)
-
- if _history_import_state_completed(interaction_conn) or _has_imported_history_rows(history_conn):
- return {
- "status": "skipped",
- "message": "Interaction history supplement already imported.",
- "inserted_count": 0,
- "already_imported": True,
- }
-
- existing_bvids = _load_existing_history_bvids(history_conn)
- cursor = interaction_conn.cursor()
- cursor.execute("""
- SELECT *
- FROM interaction_records
- WHERE bvid IS NOT NULL AND bvid != '' AND effective_time > 0
- ORDER BY effective_time ASC, fetch_time ASC
- """)
-
- records_by_year: Dict[int, List[Tuple[Any, ...]]] = defaultdict(list)
- source_counts = {"favorite": 0, "like": 0, "coin": 0}
- seen_bvids = set()
- candidates = 0
- skipped_existing = 0
- skipped_invalid = 0
- sequence = 0
-
- for row in cursor.fetchall():
- candidates += 1
- bvid = row["bvid"]
- if bvid in existing_bvids or bvid in seen_bvids:
- skipped_existing += 1
- continue
-
- history_record = _interaction_row_to_history_record(row, sequence)
- if history_record is None:
- skipped_invalid += 1
- continue
-
- year = datetime.fromtimestamp(_to_int(row["effective_time"])).year
- records_by_year[year].append(history_record)
- source_counts[row["source"]] = source_counts.get(row["source"], 0) + 1
- seen_bvids.add(bvid)
- sequence += 1
-
- inserted_count = 0
- from config.sql_statements_sqlite import INSERT_DATA
-
- placeholders = ",".join(["?" for _ in range(34)])
- history_cursor = history_conn.cursor()
- for year, records in records_by_year.items():
- table_name = f"bilibili_history_{year}"
- if not _history_table_exists(history_conn, table_name):
- _create_history_table(history_conn, table_name)
- _ensure_history_fts(history_conn, year)
-
- insert_sql = INSERT_DATA.format(table=table_name, placeholders=placeholders)
- history_cursor.executemany(insert_sql, records)
- inserted_count += len(records)
-
- history_conn.commit()
- status = "success" if inserted_count > 0 else "skipped"
- message = (
- f"Imported {inserted_count} interaction supplement records into history."
- if inserted_count > 0
- else "No interaction supplement records need importing."
- )
- details = {
- "candidates": candidates,
- "source_counts": source_counts,
- "skipped_existing": skipped_existing,
- "skipped_invalid": skipped_invalid,
- }
- update_sync_state(
- interaction_conn,
- HISTORY_IMPORT_SOURCE,
- status,
- message,
- candidates,
- inserted_count,
- 0,
- details,
- )
- return {
- "status": status,
- "message": message,
- "inserted_count": inserted_count,
- "already_imported": inserted_count == 0 and status == "skipped",
- "details": details,
- }
- finally:
- if history_conn is not None:
- history_conn.close()
- interaction_conn.close()
-
-
-def fetch_created_folders(headers: Dict[str, str], up_mid: int) -> Tuple[List[Dict[str, Any]], Optional[str]]:
- result = _request_bili_json(
- BILI_CREATED_FOLDERS_URL,
- headers,
- params={"up_mid": up_mid, "type": 0},
- )
- if result.get("status") != "success":
- return [], result.get("message", "Failed to fetch favorite folders")
-
- data = result.get("data") or {}
- folders = data.get("list", []) if isinstance(data, dict) else []
- return [folder for folder in folders if isinstance(folder, dict)], None
-
-
-def fetch_favorite_contents(
- headers: Dict[str, str],
- media_id: int,
- media_title: str,
- page_size: int,
- max_pages: int,
- request_interval: float,
-) -> Dict[str, Any]:
- all_records: List[Dict[str, Any]] = []
- errors: List[Dict[str, Any]] = []
- fetch_time = int(time.time())
- page = 1
- total = 0
-
- while True:
- result = _request_bili_json(
- BILI_FAVORITE_CONTENTS_URL,
- headers,
- params={
- "media_id": media_id,
- "pn": page,
- "ps": page_size,
- "order": "mtime",
- "type": 0,
- "tid": 0,
- "platform": "web",
- },
- )
-
- if result.get("status") != "success":
- errors.append({
- "media_id": media_id,
- "page": page,
- "message": result.get("message", "Failed to fetch favorite contents"),
- "code": result.get("code"),
- })
- break
-
- data = result.get("data") or {}
- info = data.get("info", {}) if isinstance(data, dict) else {}
- total = _to_int(info.get("media_count"), total)
- medias = _normalize_media_list(data)
-
- for item in medias:
- all_records.append(_normalize_interaction_record("favorite", item, fetch_time, media_id, media_title))
-
- has_more = bool(data.get("has_more")) if isinstance(data, dict) else False
- inferred_total_reached = total > 0 and page * page_size >= total
- if not medias or inferred_total_reached or (not has_more and len(medias) < page_size):
- break
-
- page += 1
- if max_pages > 0 and page > max_pages:
- break
- if request_interval > 0:
- time.sleep(request_interval)
-
- return {
- "records": all_records,
- "errors": errors,
- "pages": page,
- "total": total or len(all_records),
- }
-
-
-def fetch_space_interactions(headers: Dict[str, str], source: str, up_mid: int) -> Dict[str, Any]:
- fetch_time = int(time.time())
- url = BILI_LIKE_VIDEOS_URL if source == "like" else BILI_COIN_VIDEOS_URL
- result = _request_bili_json(url, headers, params={"vmid": up_mid})
-
- if result.get("status") != "success":
- return {
- "records": [],
- "status": "error",
- "message": result.get("message", f"Failed to fetch {source} records"),
- "code": result.get("code"),
- }
-
- items = _normalize_media_list(result.get("data"))
- records = [_normalize_interaction_record(source, item, fetch_time) for item in items]
- return {
- "records": records,
- "status": "success",
- "message": "OK",
- "code": 0,
- }
-
-
-def sync_interactions(request: InteractionSyncRequest) -> Dict[str, Any]:
- headers = get_headers(request.sessdata)
- user_info = get_current_user_info(headers)
- up_mid = request.up_mid or (user_info or {}).get("uid")
- if not up_mid:
- return {
- "status": "error",
- "message": "Unable to determine current user MID. Please login first.",
- }
-
- conn = get_db_connection()
- results: Dict[str, Any] = {}
- try:
- if request.include_favorites:
- folders, folder_error = fetch_created_folders(headers, int(up_mid))
- favorite_records: List[Dict[str, Any]] = []
- folder_errors: List[Dict[str, Any]] = []
-
- if folder_error:
- update_sync_state(conn, "favorite", "error", folder_error, 0, 0, 0)
- results["favorite"] = {"status": "error", "message": folder_error}
- else:
- for folder in folders:
- media_id = _to_int(_first_non_empty(folder.get("id"), folder.get("media_id")))
- if not media_id:
- continue
- media_title = str(folder.get("title") or "")
- contents = fetch_favorite_contents(
- headers,
- media_id,
- media_title,
- request.favorite_page_size,
- request.max_favorite_pages,
- request.request_interval,
- )
- favorite_records.extend(contents["records"])
- folder_errors.extend(contents["errors"])
- if request.request_interval > 0:
- time.sleep(request.request_interval)
-
- save_result = save_interaction_records(conn, favorite_records)
- status = "partial" if folder_errors else "success"
- message = "Favorite records synced"
- if folder_errors:
- message = f"Favorite records synced with {len(folder_errors)} folder/page errors"
- update_sync_state(
- conn,
- "favorite",
- status,
- message,
- len(favorite_records),
- save_result["inserted"],
- save_result["updated"],
- {"folder_count": len(folders), "errors": folder_errors[:20]},
- )
- results["favorite"] = {
- "status": status,
- "message": message,
- "folder_count": len(folders),
- "total_records": len(favorite_records),
- **save_result,
- "errors": folder_errors,
- }
-
- for source, enabled in (("like", request.include_likes), ("coin", request.include_coins)):
- if not enabled:
- continue
- fetch_result = fetch_space_interactions(headers, source, int(up_mid))
- records = fetch_result["records"]
- save_result = save_interaction_records(conn, records)
- update_sync_state(
- conn,
- source,
- fetch_result["status"],
- fetch_result["message"],
- len(records),
- save_result["inserted"],
- save_result["updated"],
- {"code": fetch_result.get("code"), "api_scope": "recent_space_records"},
- )
- results[source] = {
- "status": fetch_result["status"],
- "message": fetch_result["message"],
- "total_records": len(records),
- **save_result,
- "api_scope": "recent_space_records",
- }
-
- return {
- "status": "success",
- "message": "Interaction sync finished",
- "data": {
- "mid": up_mid,
- "user": user_info,
- "sources": results,
- },
- }
- finally:
- conn.close()
-
-
-def _row_to_dict(row: sqlite3.Row) -> Dict[str, Any]:
- data = dict(row)
- raw_json = data.pop("raw_json", None)
- if raw_json:
- try:
- data["raw"] = json.loads(raw_json)
- except json.JSONDecodeError:
- data["raw"] = None
- return data
-
-
-def _get_available_history_years() -> List[int]:
- db_path = get_output_path(load_config()["db_file"])
- if not os.path.exists(db_path):
- return []
- conn = sqlite3.connect(db_path)
- try:
- cursor = conn.cursor()
- cursor.execute("""
- SELECT name FROM sqlite_master
- WHERE type='table' AND name LIKE 'bilibili_history_%'
- ORDER BY name DESC
- """)
- years = []
- for (table_name,) in cursor.fetchall():
- try:
- years.append(int(table_name.split("_")[-1]))
- except (ValueError, IndexError):
- continue
- return sorted(years, reverse=True)
- finally:
- conn.close()
-
-
-def _get_history_overlap(year: int, interaction_bvids: set) -> Dict[str, int]:
- db_path = get_output_path(load_config()["db_file"])
- table_name = f"bilibili_history_{year}"
- if not os.path.exists(db_path):
- return {"history_unique_videos": 0, "matched_history_videos": 0, "supplement_videos": len(interaction_bvids)}
-
- conn = sqlite3.connect(db_path)
- try:
- cursor = conn.cursor()
- cursor.execute("SELECT name FROM sqlite_master WHERE type='table' AND name=?", (table_name,))
- if cursor.fetchone() is None:
- return {
- "history_unique_videos": 0,
- "matched_history_videos": 0,
- "supplement_videos": len(interaction_bvids),
- }
- cursor.execute(f"SELECT DISTINCT bvid FROM {table_name} WHERE bvid IS NOT NULL AND bvid != ''")
- history_bvids = {row[0] for row in cursor.fetchall()}
- matched = history_bvids & interaction_bvids
- return {
- "history_unique_videos": len(history_bvids),
- "matched_history_videos": len(matched),
- "supplement_videos": len(interaction_bvids - history_bvids),
- }
- finally:
- conn.close()
-
-
-def _effective_year_expr() -> str:
- return "CAST(strftime('%Y', datetime(effective_time + 28800, 'unixepoch')) AS INTEGER)"
-
-
-def collect_interaction_summary(year: Optional[int] = None) -> Dict[str, Any]:
- """收集互动记录统计数据,供接口和年度总结复用。"""
- if not os.path.exists(DB_PATH):
- selected_year = year or (datetime.now().year)
- return {
- "year": selected_year,
- "generated_at": datetime.now().isoformat(),
- "totals": {
- "total_records": 0,
- "unique_videos": 0,
- "history_unique_videos": 0,
- "matched_history_videos": 0,
- "supplement_videos": 0,
- },
- "source_counts": {"favorite": 0, "like": 0, "coin": 0},
- "monthly": {},
- "top_authors": [],
- "top_tags": [],
- "recent_records": [],
- "time_quality": {},
- "sync_state": [],
- "api_notes": get_api_capabilities()["data"]["notes"],
- }
-
- conn = get_db_connection()
- try:
- cursor = conn.cursor()
- available_years = _get_available_history_years()
- if year is None:
- cursor.execute(f"""
- SELECT {_effective_year_expr()} AS year_value
- FROM interaction_records
- WHERE effective_time > 0
- GROUP BY year_value
- ORDER BY year_value DESC
- LIMIT 1
- """)
- row = cursor.fetchone()
- selected_year = row["year_value"] if row and row["year_value"] else (available_years[0] if available_years else datetime.now().year)
- else:
- selected_year = year
-
- where_sql = f"WHERE {_effective_year_expr()} = ?"
- params = [selected_year]
-
- cursor.execute(f"SELECT COUNT(*) FROM interaction_records {where_sql}", params)
- total_records = cursor.fetchone()[0]
-
- cursor.execute(f"""
- SELECT COUNT(DISTINCT bvid)
- FROM interaction_records
- {where_sql} AND bvid IS NOT NULL AND bvid != ''
- """, params)
- unique_videos = cursor.fetchone()[0]
-
- cursor.execute(f"""
- SELECT source, COUNT(*) AS count
- FROM interaction_records
- {where_sql}
- GROUP BY source
- """, params)
- source_counts = {"favorite": 0, "like": 0, "coin": 0}
- source_counts.update({row["source"]: row["count"] for row in cursor.fetchall()})
-
- cursor.execute(f"""
- SELECT
- strftime('%Y-%m', datetime(effective_time + 28800, 'unixepoch')) AS month,
- source,
- COUNT(*) AS count
- FROM interaction_records
- {where_sql}
- GROUP BY month, source
- ORDER BY month
- """, params)
- monthly = defaultdict(lambda: {"favorite": 0, "like": 0, "coin": 0, "total": 0})
- for row in cursor.fetchall():
- monthly[row["month"]][row["source"]] = row["count"]
- monthly[row["month"]]["total"] += row["count"]
-
- cursor.execute(f"""
- SELECT author_mid, author_name, author_face, COUNT(*) AS count
- FROM interaction_records
- {where_sql}
- GROUP BY author_mid, author_name, author_face
- ORDER BY count DESC
- LIMIT 10
- """, params)
- top_authors = [dict(row) for row in cursor.fetchall()]
-
- cursor.execute(f"""
- SELECT tname, COUNT(*) AS count
- FROM interaction_records
- {where_sql} AND tname IS NOT NULL AND tname != ''
- GROUP BY tname
- ORDER BY count DESC
- LIMIT 10
- """, params)
- top_tags = [dict(row) for row in cursor.fetchall()]
-
- cursor.execute(f"""
- SELECT action_time_source, COUNT(*) AS count
- FROM interaction_records
- {where_sql}
- GROUP BY action_time_source
- """, params)
- time_quality = {row["action_time_source"]: row["count"] for row in cursor.fetchall()}
-
- cursor.execute(f"""
- SELECT *
- FROM interaction_records
- {where_sql}
- ORDER BY effective_time DESC
- LIMIT 12
- """, params)
- recent_records = [_row_to_dict(row) for row in cursor.fetchall()]
-
- cursor.execute(f"""
- SELECT DISTINCT bvid
- FROM interaction_records
- {where_sql} AND bvid IS NOT NULL AND bvid != ''
- """, params)
- interaction_bvids = {row["bvid"] for row in cursor.fetchall()}
- overlap = _get_history_overlap(selected_year, interaction_bvids)
-
- cursor.execute("SELECT * FROM interaction_sync_state ORDER BY last_sync_time DESC")
- sync_state = []
- for row in cursor.fetchall():
- item = dict(row)
- try:
- item["details"] = json.loads(item.pop("details_json") or "{}")
- except json.JSONDecodeError:
- item["details"] = {}
- sync_state.append(item)
-
- return {
- "year": selected_year,
- "available_years": available_years,
- "generated_at": datetime.now().isoformat(),
- "totals": {
- "total_records": total_records,
- "unique_videos": unique_videos,
- **overlap,
- },
- "source_counts": source_counts,
- "monthly": dict(monthly),
- "top_authors": top_authors,
- "top_tags": top_tags,
- "recent_records": recent_records,
- "time_quality": time_quality,
- "sync_state": sync_state,
- "api_notes": get_api_capabilities()["data"]["notes"],
- }
- finally:
- conn.close()
-
-
-def build_interaction_insights(summary: Dict[str, Any]) -> Dict[str, str]:
- totals = summary.get("totals", {})
- source_counts = summary.get("source_counts", {})
- insights = {}
-
- total_records = totals.get("total_records", 0)
- supplement_videos = totals.get("supplement_videos", 0)
- if total_records:
- insights["interaction_coverage"] = (
- f"互动记录为年度总结补充了{total_records}条点赞、投币和收藏数据,"
- f"其中有{supplement_videos}个视频不在当年观看历史表中。"
- )
-
- if source_counts:
- source_labels = {"favorite": "收藏", "like": "点赞", "coin": "投币"}
- top_source = max(source_counts.items(), key=lambda item: item[1])
- if top_source[1] > 0:
- insights["primary_interaction"] = f"你最常留下痕迹的互动类型是{source_labels.get(top_source[0], top_source[0])},共{top_source[1]}条。"
-
- time_quality = summary.get("time_quality", {})
- unavailable = time_quality.get("unavailable", 0)
- if unavailable:
- insights["time_quality"] = (
- f"有{unavailable}条互动记录缺少可靠动作时间,系统使用发布时间或抓取时间作为统计兜底。"
- )
-
- return insights
-
-
-def get_api_capabilities() -> Dict[str, Any]:
- return {
- "status": "success",
- "data": {
- "sources": [
- {
- "source": "favorite",
- "endpoint": BILI_FAVORITE_CONTENTS_URL,
- "time_field": "fav_time",
- "scope": "created favorite folders, paginated",
- "confidence": "high",
- },
- {
- "source": "like",
- "endpoint": BILI_LIKE_VIDEOS_URL,
- "time_field": None,
- "scope": "space recent liked videos",
- "confidence": "medium",
- },
- {
- "source": "coin",
- "endpoint": BILI_COIN_VIDEOS_URL,
- "time_field": "time",
- "scope": "space recent coined videos",
- "confidence": "medium",
- },
- ],
- "notes": [
- "Favorite folder contents are paginated and include fav_time, so all available favorite records can be counted by year reliably.",
- "The Web coin API includes time for returned records, but the endpoint is still a recent space list rather than a proven full-history archive.",
- "The Web like API exposes recent liked videos but does not provide a stable like timestamp in the documented response.",
- "Bilibili's documented space info fields include jointime, but current documented responses return 0, so sync cannot reliably start from account registration time.",
- "Records without an action timestamp use publish time, ctime, or fetch time as a conservative effective_time fallback.",
- ],
- },
- }
-
-
-@router.get("/api-capabilities", summary="查看互动记录可用的B站接口")
-async def api_capabilities():
- return get_api_capabilities()
-
-
-@router.post("/sync", summary="同步点赞、投币、收藏互动记录")
-async def sync_interaction_records(
- include_favorites: bool = Query(True, description="是否同步收藏记录"),
- include_likes: bool = Query(True, description="是否同步点赞记录"),
- include_coins: bool = Query(True, description="是否同步投币记录"),
- max_favorite_pages: int = Query(0, ge=0, description="每个收藏夹最多同步页数,0表示不限"),
- favorite_page_size: int = Query(20, ge=1, le=20, description="收藏夹分页大小"),
- request_interval: float = Query(0.6, ge=0, le=10, description="请求间隔秒数"),
- sessdata: Optional[str] = Query(None, description="用户的SESSDATA"),
- up_mid: Optional[int] = Query(None, description="目标用户MID,不传则使用当前登录用户"),
-):
- request = InteractionSyncRequest(
- include_favorites=include_favorites,
- include_likes=include_likes,
- include_coins=include_coins,
- max_favorite_pages=max_favorite_pages,
- favorite_page_size=favorite_page_size,
- request_interval=request_interval,
- sessdata=sessdata,
- up_mid=up_mid,
- )
- return sync_interactions(request)
-
-
-@router.get("/summary", summary="获取互动记录年度统计")
-async def get_interaction_summary(
- year: Optional[int] = Query(None, description="要统计的年份,不传则使用最新互动年份"),
-):
- summary = collect_interaction_summary(year)
- return {
- "status": "success",
- "data": summary,
- "insights": build_interaction_insights(summary),
- }
-
-
-@router.get("/records", summary="分页查询互动记录")
-async def get_interaction_records(
- page: int = Query(1, ge=1, description="页码"),
- size: int = Query(30, ge=1, le=100, description="每页数量"),
- source: Optional[str] = Query(None, description="互动来源 favorite/like/coin"),
- year: Optional[int] = Query(None, description="按统计年份筛选"),
- search: Optional[str] = Query(None, description="标题或UP主关键词"),
-):
- conn = get_db_connection()
- try:
- cursor = conn.cursor()
- where = ["1=1"]
- params: List[Any] = []
- if source:
- where.append("source = ?")
- params.append(source)
- if year:
- where.append(f"{_effective_year_expr()} = ?")
- params.append(year)
- if search:
- where.append("(title LIKE ? OR author_name LIKE ? OR bvid LIKE ?)")
- keyword = f"%{search}%"
- params.extend([keyword, keyword, keyword])
-
- where_sql = "WHERE " + " AND ".join(where)
- cursor.execute(f"SELECT COUNT(*) FROM interaction_records {where_sql}", params)
- total = cursor.fetchone()[0]
-
- offset = (page - 1) * size
- cursor.execute(
- f"""
- SELECT *
- FROM interaction_records
- {where_sql}
- ORDER BY effective_time DESC, fetch_time DESC
- LIMIT ? OFFSET ?
- """,
- params + [size, offset],
- )
- records = [_row_to_dict(row) for row in cursor.fetchall()]
- return {
- "status": "success",
- "data": {
- "records": records,
- "total": total,
- "page": page,
- "size": size,
- },
- }
- finally:
- conn.close()
-
-
-@router.get("/status", summary="获取互动记录同步状态")
-async def get_interaction_status():
- conn = get_db_connection()
- try:
- cursor = conn.cursor()
- cursor.execute("SELECT * FROM interaction_sync_state ORDER BY last_sync_time DESC")
- states = []
- for row in cursor.fetchall():
- item = dict(row)
- try:
- item["details"] = json.loads(item.pop("details_json") or "{}")
- except json.JSONDecodeError:
- item["details"] = {}
- states.append(item)
- return {"status": "success", "data": states}
- finally:
- conn.close()
diff --git a/routers/login.py b/routers/login.py
index 43af647..c2ac218 100644
--- a/routers/login.py
+++ b/routers/login.py
@@ -6,9 +6,7 @@
from fastapi import APIRouter, HTTPException
from fastapi.responses import JSONResponse, FileResponse
from loguru import logger
-from scripts.utils import load_config, get_output_path, setup_logger
-from datetime import datetime
-from scripts.send_log_email import send_email
+from scripts.utils import get_config_path, load_config, get_output_path, setup_logger
# 确保日志系统已初始化
setup_logger()
@@ -23,7 +21,7 @@ def save_cookies(cookies):
"""保存cookies到配置文件"""
try:
# 使用绝对路径
- config_path = os.path.join(os.path.dirname(os.path.dirname(os.path.abspath(__file__))), 'config', 'config.yaml')
+ config_path = get_config_path('config.yaml')
logger.info(f"配置文件路径: {config_path}")
if not os.path.exists(config_path):
@@ -51,14 +49,12 @@ def save_cookies(cookies):
if field in cookies:
lines[i] = f'{field}: {cookies[field]}'
updated_fields.add(field)
- print(f"更新配置 {field}: {cookies[field]}")
break
# 添加不存在的字段
for field in cookie_fields:
if field in cookies and field not in updated_fields:
lines.append(f'{field}: {cookies[field]}')
- print(f"添加配置 {field}: {cookies[field]}")
# 保存更新后的配置
config_data = '\n'.join(lines)
@@ -92,7 +88,6 @@ async def generate_qrcode():
)
logger.info(f"API响应状态码: {response.status_code}")
- logger.debug(f"API响应内容: {response.text}")
# 检查响应状态码
if response.status_code != 200:
@@ -106,7 +101,6 @@ async def generate_qrcode():
data = response.json()
except json.JSONDecodeError as e:
print(f"JSON解析错误: {str(e)}")
- print(f"响应内容: {response.text}")
raise HTTPException(
status_code=500,
detail=f"解析B站API响应失败: {str(e)}"
@@ -193,8 +187,6 @@ async def get_qrcode_image():
async def poll_scan_status(qrcode_key: str):
"""轮询扫码状态"""
try:
- print(f"开始轮询扫码状态,qrcode_key: {qrcode_key}")
-
if not qrcode_key:
raise HTTPException(
status_code=400,
@@ -216,9 +208,6 @@ async def poll_scan_status(qrcode_key: str):
)
print(f"API响应状态码: {response.status_code}")
- print(f"API响应内容: {response.text}")
- print(f"响应头: {response.headers}")
- print(f"响应Cookies: {response.cookies}")
# 检查响应状态码
if response.status_code != 200:
@@ -232,7 +221,6 @@ async def poll_scan_status(qrcode_key: str):
data = response.json()
except json.JSONDecodeError as e:
print(f"JSON解析错误: {str(e)}")
- print(f"响应内容: {response.text}")
raise HTTPException(
status_code=500,
detail=f"解析B站API响应失败: {str(e)}"
@@ -252,7 +240,6 @@ async def poll_scan_status(qrcode_key: str):
}
scan_data = data.get('data', {})
- print(f"扫码状态数据: {scan_data}")
# 如果登录成功,保存cookies
if scan_data.get('code') == 0:
@@ -264,14 +251,11 @@ async def poll_scan_status(qrcode_key: str):
# 从响应cookie中获取
for cookie in response.cookies:
cookies[cookie.name] = cookie.value
- print(f"从响应cookies获取到: {cookie.name}={cookie.value}")
# 从响应头中获取(有些Cookie可能在响应头的set-cookie中,但不在cookies中)
if 'set-cookie' in response.headers:
- # 修复: 使用正确的方法获取set-cookie头
# CaseInsensitiveDict不支持getlist方法
set_cookie_header = response.headers.get('set-cookie', '')
- print(f"从响应头获取到set-cookie: {set_cookie_header}")
# 如果是单个cookie
if set_cookie_header:
@@ -279,7 +263,6 @@ async def poll_scan_status(qrcode_key: str):
if len(parts) == 2:
name, value = parts
cookies[name.strip()] = value.strip()
- print(f"解析出cookie: {name.strip()}={value.strip()}")
# 可能多个cookie在不同的Set-Cookie头中
# 遍历所有响应头来查找所有的Set-Cookie
@@ -289,7 +272,6 @@ async def poll_scan_status(qrcode_key: str):
if len(cookie_parts) == 2:
cookie_name, cookie_value = cookie_parts
cookies[cookie_name.strip()] = cookie_value.strip()
- print(f"从头部遍历解析出cookie: {cookie_name.strip()}={cookie_value.strip()}")
# 如果响应数据中包含cookie_info字段(TV端QR登录模式),从中提取cookies
if 'cookie_info' in scan_data:
@@ -297,12 +279,10 @@ async def poll_scan_status(qrcode_key: str):
for cookie in cookie_info.get('cookies', []):
if 'name' in cookie and 'value' in cookie:
cookies[cookie['name']] = cookie['value']
- print(f"从cookie_info获取到: {cookie['name']}={cookie['value']}")
# 如果必要的cookie不在响应中,从url中解析
if 'url' in scan_data and scan_data['url'] and ('SESSDATA' not in cookies or 'bili_jct' not in cookies):
url = scan_data['url']
- print(f"从url中解析cookie: {url}")
if '?' in url:
query = url.split('?', 1)[1]
for param in query.split('&'):
@@ -310,10 +290,6 @@ async def poll_scan_status(qrcode_key: str):
name, value = param.split('=', 1)
if name in ['DedeUserID', 'DedeUserID__ckMd5', 'SESSDATA', 'bili_jct']:
cookies[name] = value
- print(f"从URL解析出cookie: {name}={value}")
-
- # 记录找到的所有cookie
- print(f"找到的所有cookies: {cookies}")
# 检查是否有必要的鉴权字段
if 'SESSDATA' not in cookies:
@@ -326,15 +302,6 @@ async def poll_scan_status(qrcode_key: str):
save_cookies(cookies)
print("cookies已保存")
- # 记录获取到的鉴权信息
- auth_info = {
- "SESSDATA": cookies.get("SESSDATA", "未获取"),
- "bili_jct": cookies.get("bili_jct", "未获取"),
- "DedeUserID": cookies.get("DedeUserID", "未获取"),
- "DedeUserID__ckMd5": cookies.get("DedeUserID__ckMd5", "未获取")
- }
- print(f"鉴权信息摘要: {auth_info}")
-
return {
"status": "success",
"data": {
@@ -367,7 +334,7 @@ async def logout():
logger.info("开始退出登录...")
# 使用绝对路径
- config_path = os.path.join(os.path.dirname(os.path.dirname(os.path.abspath(__file__))), 'config', 'config.yaml')
+ config_path = get_config_path('config.yaml')
logger.info(f"配置文件路径: {config_path}")
if not os.path.exists(config_path):
@@ -458,135 +425,3 @@ async def check_login_status():
status_code=500,
detail=f"检查登录状态失败: {str(e)}"
)
-@router.get("/check-and-notify", summary="检查SESSDATA并在失效时发送邮件")
-async def check_and_notify():
- """检查SESSDATA有效性;若失效则发送邮件告警(状态变为失效时仅告警一次)"""
- try:
- print("检查SESSDATA并发送告警(如失效)...")
-
- # 获取配置与SESSDATA
- current_config = get_current_config()
- sessdata = current_config.get('SESSDATA', '')
-
- headers = {
- 'User-Agent': 'Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/91.0.4472.124 Safari/537.36',
- 'Cookie': f'SESSDATA={sessdata}'
- }
-
- valid = False
- detail = {}
- error_message = None
-
- if not sessdata:
- error_message = "SESSDATA 未配置或为空"
- else:
- try:
- resp = requests.get(
- 'https://api.bilibili.com/x/web-interface/nav',
- headers=headers,
- timeout=10
- )
- status_code = resp.status_code
- print(f"API响应状态码: {status_code}")
- try:
- data = resp.json() if status_code == 200 else {}
- except Exception:
- data = {}
- detail = data
-
- # code == 0 表示已登录有效
- if status_code == 200 and isinstance(data, dict) and data.get('code') == 0:
- valid = True
- else:
- err_msg = ""
- if isinstance(data, dict):
- err_msg = data.get('message', '') or (data.get('data', {}) or {}).get('message', '')
- if not err_msg:
- err_msg = f"HTTP {status_code}"
- error_message = f"登录失效或异常: {err_msg}"
- except Exception as e:
- error_message = f"请求验证接口失败: {str(e)}"
-
- # 状态文件(用于去重,仅在状态从有效->失效时告警一次)
- state_path = get_output_path('state/sessdata_monitor.json')
- last_alert_ts = 0
- last_status = "unknown"
- try:
- if os.path.exists(state_path):
- with open(state_path, 'r', encoding='utf-8') as f:
- st = json.load(f)
- last_alert_ts = st.get('last_alert_ts', 0)
- last_status = st.get('last_status', 'unknown')
- except Exception:
- pass
-
- now_ts = int(time.time())
- notified = False
-
- if valid:
- # 更新状态为有效
- try:
- os.makedirs(os.path.dirname(state_path), exist_ok=True)
- with open(state_path, 'w', encoding='utf-8') as f:
- json.dump({
- 'last_status': 'valid',
- 'last_valid_ts': now_ts
- }, f, ensure_ascii=False, indent=2)
- except Exception as e:
- print(f"写入状态文件失败: {e}")
-
- return {
- "status": "success",
- "message": "SESSDATA 有效",
- "data": {"valid": True, "detail": detail}
- }
-
- # 若失效则发送邮件(仅当上次状态不是 invalid 时触发)
- if last_status != 'invalid':
- subject = "B站登录状态失效,请尽快重新登录"
- body = "\n".join([
- f"时间: {datetime.now().strftime('%Y-%m-%d %H:%M:%S')}",
- f"原因: {error_message or '未知'}",
- f"原始返回: {json.dumps(detail, ensure_ascii=False) if isinstance(detail, dict) else str(detail)}"
- ])
-
- try:
- send_res = await send_email(subject=subject, content=body)
- print(f"告警邮件发送结果: {send_res}")
- notified = (send_res or {}).get("status") == "success"
- except Exception as e:
- print(f"发送告警邮件失败: {e}")
-
- try:
- from scripts.apprise_notify import send_apprise_notification
- apprise_result = await send_apprise_notification(title=subject, body=body)
- logger.info(f"登录失效 Apprise 通知结果: {apprise_result['message']}")
- except Exception as e:
- print(f"发送Apprise推送失败: {e}")
-
- # 更新为失效状态
- try:
- os.makedirs(os.path.dirname(state_path), exist_ok=True)
- with open(state_path, 'w', encoding='utf-8') as f:
- json.dump({
- 'last_status': 'invalid',
- 'last_alert_ts': now_ts,
- 'last_error': error_message
- }, f, ensure_ascii=False, indent=2)
- except Exception as e:
- print(f"写入状态文件失败: {e}")
- else:
- print("状态已为失效,跳过重复告警")
-
- return {
- "status": "success",
- "message": "SESSDATA 已失效" + ("(已发送邮件)" if notified else "(未重复发送)"),
- "data": {"valid": False, "notified": notified, "detail": detail}
- }
-
- except Exception as e:
- print(f"检查与告警流程失败: {str(e)}")
- raise HTTPException(
- status_code=500,
- detail=f"检查与告警流程失败: {str(e)}"
- )
diff --git a/routers/popular_analytics.py b/routers/popular_analytics.py
deleted file mode 100644
index 8328c7a..0000000
--- a/routers/popular_analytics.py
+++ /dev/null
@@ -1,1068 +0,0 @@
-import sqlite3
-from typing import Optional
-
-from fastapi import APIRouter, Query, HTTPException
-
-from scripts.utils import load_config, get_output_path
-
-router = APIRouter()
-config = load_config()
-
-def get_db():
- """获取数据库连接"""
- db_path = get_output_path(config['db_file'])
- return sqlite3.connect(db_path)
-
-def validate_year_and_get_table(year: Optional[int]) -> tuple:
- """验证年份并获取对应的表名"""
- from scripts.analyze_bilibili_history import get_available_years
-
- # 获取可用年份列表
- available_years = get_available_years()
- if not available_years:
- return None, None, {
- "status": "error",
- "message": "未找到任何历史记录数据"
- }
-
- # 如果未指定年份,使用最新的年份;如果指定年份不存在,则自动回退到最新可用年份
- if year is None:
- target_year = available_years[0]
- elif year in available_years:
- target_year = year
- else:
- target_year = available_years[0]
-
- table_name = f"bilibili_history_{target_year}"
- return table_name, target_year, available_years
-
-def analyze_popular_hit_rate(cursor, table_name: str, target_year: int) -> dict:
- """分析热门视频命中率"""
-
- # 1. 获取用户观看的所有视频
- cursor.execute(f"""
- SELECT DISTINCT bvid, title, author_name, view_at, duration, progress
- FROM {table_name}
- WHERE bvid IS NOT NULL AND bvid != ''
- ORDER BY view_at ASC
- """)
-
- user_videos = cursor.fetchall()
- total_watched = len(user_videos)
-
- if total_watched == 0:
- return {
- "total_watched": 0,
- "popular_hit_count": 0,
- "hit_rate": 0,
- "insights": ["本年度没有观看记录"]
- }
-
- # 2. 获取热门视频数据库连接
- popular_connections = {}
- try:
- # 获取所有年份的热门视频数据库连接
- from scripts.popular_videos import get_multi_year_connections
- popular_connections = get_multi_year_connections()
- except Exception as e:
- print(f"获取热门视频数据库连接失败: {e}")
- return {
- "total_watched": total_watched,
- "popular_hit_count": 0,
- "hit_rate": 0,
- "insights": [f"观看了 {total_watched} 个视频,但无法获取热门视频数据进行对比"]
- }
-
- # 3. 检查哪些视频曾经是热门,并获取时间信息
- popular_hits = []
- popular_bvids = set()
- popular_video_times = {} # bvid -> {"pubdate": timestamp}
-
- for year, conn in popular_connections.items():
- try:
- pop_cursor = conn.cursor()
- # 查询所有热门视频的bvid和发布时间
- pop_cursor.execute("SELECT DISTINCT bvid, pubdate FROM popular_videos WHERE bvid IS NOT NULL AND pubdate IS NOT NULL")
- for row in pop_cursor.fetchall():
- bvid, pubdate = row
- popular_bvids.add(bvid)
- if bvid not in popular_video_times:
- popular_video_times[bvid] = {"pubdate": pubdate}
- except Exception as e:
- print(f"查询 {year} 年热门视频数据失败: {e}")
- continue
-
- # 4. 统计命中的热门视频并分析观看时机
- time_patterns = {
- "immediate_watch": 0, # 发布后立即观看(7天内)
- "trending_watch": 0, # 热门期观看(7天后)
- "unknown_timing": 0 # 无法确定时机
- }
-
- import datetime
-
- for video in user_videos:
- bvid = video[0]
- view_timestamp = video[3]
-
- if bvid in popular_bvids:
- popular_hits.append({
- "bvid": bvid,
- "title": video[1],
- "author": video[2],
- "view_at": video[3],
- "duration": video[4],
- "progress": video[5]
- })
-
- # 分析观看时机
- if bvid in popular_video_times and popular_video_times[bvid]["pubdate"]:
- try:
- view_date = datetime.datetime.fromtimestamp(view_timestamp)
- pub_date = datetime.datetime.fromtimestamp(popular_video_times[bvid]["pubdate"])
- days_diff = (view_date - pub_date).days
-
- if days_diff <= 7:
- time_patterns["immediate_watch"] += 1
- else:
- time_patterns["trending_watch"] += 1
-
- except Exception as e:
- print(f"处理视频 {bvid} 时间数据失败: {e}")
- time_patterns["unknown_timing"] += 1
- else:
- time_patterns["unknown_timing"] += 1
-
- hit_count = len(popular_hits)
- hit_rate = (hit_count / total_watched) * 100 if total_watched > 0 else 0
-
- # 5. 生成洞察
- insights = []
- insights.append(f"今年观看了 {total_watched} 个视频")
- insights.append(f"其中 {hit_count} 个曾经是热门视频")
- insights.append(f"热门视频命中率为 {hit_rate:.1f}%")
-
- # 添加观看时机洞察
- total_timed_videos = sum([time_patterns["immediate_watch"], time_patterns["trending_watch"]])
- if total_timed_videos > 0:
- immediate_rate = (time_patterns["immediate_watch"] / total_timed_videos) * 100
- if immediate_rate >= 50:
- insights.append("你是热门视频的早期发现者")
- else:
- insights.append("你喜欢在视频热门期观看")
-
- if hit_rate >= 50:
- insights.append("你很喜欢追热门内容!")
- elif hit_rate >= 30:
- insights.append("你对热门内容有一定关注")
- elif hit_rate >= 10:
- insights.append("你更偏爱小众内容")
- else:
- insights.append("你是真正的小众爱好者!")
-
- # 6. 关闭热门视频数据库连接
- for conn in popular_connections.values():
- if conn:
- conn.close()
-
- return {
- "total_watched": total_watched,
- "popular_hit_count": hit_count,
- "hit_rate": round(hit_rate, 2),
- "popular_videos": popular_hits[:10], # 只返回前10个热门视频
- "time_pattern_analysis": time_patterns,
- "insights": insights
- }
-
-def analyze_popular_prediction_ability(cursor, table_name: str, target_year: int) -> dict:
- """分析热门预测能力"""
-
- # 1. 获取用户观看的所有视频(按观看时间排序)
- cursor.execute(f"""
- SELECT DISTINCT bvid, title, author_name, view_at, duration, progress
- FROM {table_name}
- WHERE bvid IS NOT NULL AND bvid != ''
- ORDER BY view_at ASC
- """)
-
- user_videos = cursor.fetchall()
- total_watched = len(user_videos)
-
- if total_watched == 0:
- return {
- "total_watched": 0,
- "predicted_count": 0,
- "prediction_rate": 0,
- "insights": ["本年度没有观看记录"]
- }
-
- # 2. 获取热门视频数据库连接
- popular_connections = {}
- try:
- from scripts.popular_videos import get_multi_year_connections
- popular_connections = get_multi_year_connections()
- except Exception as e:
- print(f"获取热门视频数据库连接失败: {e}")
- return {
- "total_watched": total_watched,
- "predicted_count": 0,
- "prediction_rate": 0,
- "insights": [f"观看了 {total_watched} 个视频,但无法获取热门视频数据进行预测分析"]
- }
-
- # 3. 分析每个观看的视频是否后来成为热门
- predicted_videos = []
-
- for video in user_videos:
- bvid = video[0]
- view_timestamp = video[3] # 用户观看时间戳
-
- # 在所有年份的热门视频数据库中查找该视频
- for year, conn in popular_connections.items():
- try:
- pop_cursor = conn.cursor()
-
- # 查询该视频在热门列表中的首次出现时间
- pop_cursor.execute("""
- SELECT first_seen, title, highest_rank, appearances
- FROM popular_video_tracking
- WHERE bvid = ?
- """, (bvid,))
-
- tracking_result = pop_cursor.fetchone()
-
- if tracking_result:
- first_seen_timestamp = tracking_result[0]
- video_title = tracking_result[1]
- highest_rank = tracking_result[2]
- appearances = tracking_result[3]
-
- # 如果用户观看时间早于视频首次成为热门的时间,说明预测成功
- if view_timestamp < first_seen_timestamp:
- # 计算预测提前时间(天数)
- advance_days = (first_seen_timestamp - view_timestamp) / (24 * 3600)
-
- predicted_videos.append({
- "bvid": bvid,
- "title": video_title or video[1],
- "author": video[2],
- "view_at": video[3],
- "became_popular_at": first_seen_timestamp,
- "advance_days": round(advance_days, 1),
- "highest_rank": highest_rank,
- "appearances": appearances
- })
- break # 找到就跳出年份循环
-
- except Exception as e:
- print(f"查询 {year} 年热门视频跟踪数据失败: {e}")
- continue
-
- predicted_count = len(predicted_videos)
- prediction_rate = (predicted_count / total_watched) * 100 if total_watched > 0 else 0
-
- # 4. 生成洞察
- insights = []
- insights.append(f"今年观看了 {total_watched} 个视频")
- insights.append(f"其中 {predicted_count} 个后来成为了热门视频")
- insights.append(f"热门预测成功率为 {prediction_rate:.1f}%")
-
- if prediction_rate >= 10:
- insights.append("你有超强的慧眼识珠能力!")
- elif prediction_rate >= 5:
- insights.append("你对优质内容很有嗅觉")
- elif prediction_rate >= 2:
- insights.append("你偶尔能发现潜力视频")
- else:
- insights.append("你更专注于自己的兴趣领域")
-
- # 5. 计算平均提前天数
- if predicted_videos:
- avg_advance_days = sum(v["advance_days"] for v in predicted_videos) / len(predicted_videos)
- insights.append(f"平均提前 {avg_advance_days:.1f} 天发现热门视频")
-
- # 6. 关闭热门视频数据库连接
- for conn in popular_connections.values():
- if conn:
- conn.close()
-
- return {
- "total_watched": total_watched,
- "predicted_count": predicted_count,
- "prediction_rate": round(prediction_rate, 2),
- "predicted_videos": sorted(predicted_videos, key=lambda x: x["advance_days"], reverse=True)[:10],
- "insights": insights
- }
-
-def analyze_author_popular_association(cursor, table_name: str, target_year: int) -> dict:
- """分析UP主热门关联"""
-
- # 1. 获取用户观看的所有UP主及其视频
- cursor.execute(f"""
- SELECT author_name, bvid, title, view_at, duration, progress
- FROM {table_name}
- WHERE bvid IS NOT NULL AND bvid != '' AND author_name IS NOT NULL AND author_name != ''
- ORDER BY author_name, view_at ASC
- """)
-
- user_videos = cursor.fetchall()
-
- if not user_videos:
- return {
- "total_authors": 0,
- "popular_authors": [],
- "author_stats": [],
- "insights": ["本年度没有观看记录"]
- }
-
- # 2. 按UP主分组统计
- author_videos = {}
- for video in user_videos:
- author_name = video[0]
- if author_name not in author_videos:
- author_videos[author_name] = []
- author_videos[author_name].append({
- "bvid": video[1],
- "title": video[2],
- "view_at": video[3],
- "duration": video[4],
- "progress": video[5]
- })
-
- # 3. 获取热门视频数据库连接
- popular_connections = {}
- try:
- from scripts.popular_videos import get_multi_year_connections
- popular_connections = get_multi_year_connections()
- except Exception as e:
- print(f"获取热门视频数据库连接失败: {e}")
- return {
- "total_authors": len(author_videos),
- "popular_authors": [],
- "author_stats": [],
- "insights": [f"观看了 {len(author_videos)} 个UP主的视频,但无法获取热门视频数据进行分析"]
- }
-
- # 4. 获取所有热门视频的bvid和作者信息
- popular_bvids = set()
- popular_video_authors = {} # bvid -> author_name
-
- for year, conn in popular_connections.items():
- try:
- pop_cursor = conn.cursor()
- # 查询所有热门视频的bvid和作者
- pop_cursor.execute("SELECT DISTINCT bvid, owner_name FROM popular_videos WHERE bvid IS NOT NULL AND owner_name IS NOT NULL")
- for row in pop_cursor.fetchall():
- bvid, owner_name = row
- popular_bvids.add(bvid)
- popular_video_authors[bvid] = owner_name
- except Exception as e:
- print(f"查询 {year} 年热门视频数据失败: {e}")
- continue
-
- # 5. 分析每个UP主的热门视频产出能力
- author_stats = []
-
- for author_name, videos in author_videos.items():
- total_videos = len(videos)
- popular_videos = []
-
- # 检查该UP主的哪些视频成为了热门
- for video in videos:
- bvid = video["bvid"]
- if bvid in popular_bvids:
- popular_videos.append({
- "bvid": bvid,
- "title": video["title"],
- "view_at": video["view_at"]
- })
-
- popular_count = len(popular_videos)
- popular_rate = (popular_count / total_videos) * 100 if total_videos > 0 else 0
-
- # 计算该UP主在热门视频数据库中的总热门视频数
- author_total_popular = 0
- for bvid, owner_name in popular_video_authors.items():
- if owner_name == author_name:
- author_total_popular += 1
-
- author_stats.append({
- "author_name": author_name,
- "total_videos_watched": total_videos,
- "popular_videos_watched": popular_count,
- "popular_rate": round(popular_rate, 2),
- "total_popular_videos": author_total_popular,
- "popular_videos": popular_videos[:5], # 只返回前5个热门视频
- "efficiency_score": round(popular_rate * (popular_count + 1), 2) # 综合评分
- })
-
- # 6. 按热门视频数量和热门率排序
- author_stats.sort(key=lambda x: (x["popular_videos_watched"], x["popular_rate"]), reverse=True)
-
- # 7. 筛选出热门制造机UP主(至少有1个热门视频)
- popular_authors = [author for author in author_stats if author["popular_videos_watched"] > 0]
-
- # 8. 生成洞察
- insights = []
- total_authors = len(author_videos)
- popular_author_count = len(popular_authors)
-
- insights.append(f"观看了 {total_authors} 个UP主的视频")
- insights.append(f"其中 {popular_author_count} 个UP主制作过热门视频")
-
- if popular_author_count > 0:
- avg_popular_rate = sum(author["popular_rate"] for author in popular_authors) / popular_author_count
- insights.append(f"热门UP主平均热门率为 {avg_popular_rate:.1f}%")
-
- top_author = popular_authors[0]
- insights.append(f"最强热门制造机:{top_author['author_name']}({top_author['popular_videos_watched']}个热门视频)")
- else:
- insights.append("你关注的UP主都很小众哦")
-
- # 9. 关闭热门视频数据库连接
- for conn in popular_connections.values():
- if conn:
- conn.close()
-
- return {
- "total_authors": total_authors,
- "popular_author_count": popular_author_count,
- "popular_authors": popular_authors[:20], # 返回前20个热门UP主
- "author_stats": author_stats[:10], # 返回前10个UP主的详细统计
- "insights": insights
- }
-
-def analyze_category_popular_distribution(cursor, table_name: str, target_year: int) -> dict:
- """分析热门视频分区分布"""
-
- # 1. 获取用户观看的所有视频
- cursor.execute(f"""
- SELECT DISTINCT bvid, title, author_name, view_at, duration, progress
- FROM {table_name}
- WHERE bvid IS NOT NULL AND bvid != ''
- ORDER BY view_at ASC
- """)
-
- user_videos = cursor.fetchall()
- total_watched = len(user_videos)
-
- if total_watched == 0:
- return {
- "total_watched": 0,
- "category_stats": [],
- "popular_categories": [],
- "insights": ["本年度没有观看记录"]
- }
-
- # 2. 获取热门视频数据库连接
- popular_connections = {}
- try:
- from scripts.popular_videos import get_multi_year_connections
- popular_connections = get_multi_year_connections()
- except Exception as e:
- print(f"获取热门视频数据库连接失败: {e}")
- return {
- "total_watched": total_watched,
- "category_stats": [],
- "popular_categories": [],
- "insights": [f"观看了 {total_watched} 个视频,但无法获取热门视频数据进行分区分析"]
- }
-
- # 3. 获取所有热门视频的bvid和分区信息
- popular_video_categories = {} # bvid -> {"tid": tid, "tname": tname}
- popular_bvids = set()
-
- for year, conn in popular_connections.items():
- try:
- pop_cursor = conn.cursor()
- # 查询所有热门视频的bvid、分区ID和分区名称
- pop_cursor.execute("SELECT DISTINCT bvid, tid, tname FROM popular_videos WHERE bvid IS NOT NULL AND tid IS NOT NULL AND tname IS NOT NULL")
- for row in pop_cursor.fetchall():
- bvid, tid, tname = row
- popular_bvids.add(bvid)
- popular_video_categories[bvid] = {"tid": tid, "tname": tname}
- except Exception as e:
- print(f"查询 {year} 年热门视频数据失败: {e}")
- continue
-
- # 4. 统计用户观看的热门视频按分区分布
- category_stats = {} # tname -> {"total_popular": count, "videos": []}
-
- for video in user_videos:
- bvid = video[0]
- if bvid in popular_bvids and bvid in popular_video_categories:
- category_info = popular_video_categories[bvid]
- tname = category_info["tname"]
-
- if tname not in category_stats:
- category_stats[tname] = {
- "category_name": tname,
- "tid": category_info["tid"],
- "total_popular": 0,
- "videos": []
- }
-
- category_stats[tname]["total_popular"] += 1
- category_stats[tname]["videos"].append({
- "bvid": bvid,
- "title": video[1],
- "author": video[2],
- "view_at": video[3]
- })
-
- # 5. 转换为列表并排序
- category_list = list(category_stats.values())
- category_list.sort(key=lambda x: x["total_popular"], reverse=True)
-
- # 6. 计算统计数据
- total_popular_watched = sum(cat["total_popular"] for cat in category_list)
- popular_rate = (total_popular_watched / total_watched) * 100 if total_watched > 0 else 0
-
- # 7. 生成洞察
- insights = []
- insights.append(f"今年观看了 {total_watched} 个视频")
- insights.append(f"其中 {total_popular_watched} 个曾经是热门视频")
- insights.append(f"热门视频分布在 {len(category_list)} 个分区")
-
- if category_list:
- top_category = category_list[0]
- insights.append(f"最爱的热门分区:{top_category['category_name']}({top_category['total_popular']}个热门视频)")
-
- # 分析分区偏好
- if len(category_list) >= 3:
- top_3_count = sum(cat["total_popular"] for cat in category_list[:3])
- top_3_rate = (top_3_count / total_popular_watched) * 100 if total_popular_watched > 0 else 0
- if top_3_rate >= 70:
- insights.append("你的热门视频偏好很集中")
- else:
- insights.append("你的热门视频偏好很多样化")
-
- # 分析热门敏感度
- if popular_rate >= 50:
- insights.append("你对各分区的热门内容都很敏感")
- elif popular_rate >= 30:
- insights.append("你在某些分区有不错的热门嗅觉")
- else:
- insights.append("你更专注于特定分区的小众内容")
-
- # 8. 关闭热门视频数据库连接
- for conn in popular_connections.values():
- if conn:
- conn.close()
-
- return {
- "total_watched": total_watched,
- "total_popular_watched": total_popular_watched,
- "popular_rate": round(popular_rate, 2),
- "category_count": len(category_list),
- "category_stats": category_list,
- "popular_categories": category_list[:10], # 返回前10个热门分区
- "insights": insights
- }
-
-def analyze_duration_popular_distribution(cursor, table_name: str, target_year: int) -> dict:
- """分析热门视频时长分布"""
-
- # 1. 获取用户观看的所有视频
- cursor.execute(f"""
- SELECT DISTINCT bvid, title, author_name, view_at, duration, progress
- FROM {table_name}
- WHERE bvid IS NOT NULL AND bvid != '' AND duration IS NOT NULL AND duration > 0
- ORDER BY view_at ASC
- """)
-
- user_videos = cursor.fetchall()
- total_watched = len(user_videos)
-
- if total_watched == 0:
- return {
- "total_watched": 0,
- "duration_stats": [],
- "popular_duration_videos": [],
- "insights": ["本年度没有观看记录"]
- }
-
- # 2. 获取热门视频数据库连接
- popular_connections = {}
- try:
- from scripts.popular_videos import get_multi_year_connections
- popular_connections = get_multi_year_connections()
- except Exception as e:
- print(f"获取热门视频数据库连接失败: {e}")
- return {
- "total_watched": total_watched,
- "duration_stats": [],
- "popular_duration_videos": [],
- "insights": [f"观看了 {total_watched} 个视频,但无法获取热门视频数据进行时长分析"]
- }
-
- # 3. 获取所有热门视频的bvid和时长信息
- popular_video_durations = {} # bvid -> duration
- popular_bvids = set()
-
- for year, conn in popular_connections.items():
- try:
- pop_cursor = conn.cursor()
- # 查询所有热门视频的bvid和时长
- pop_cursor.execute("SELECT DISTINCT bvid, duration FROM popular_videos WHERE bvid IS NOT NULL AND duration IS NOT NULL AND duration > 0")
- for row in pop_cursor.fetchall():
- bvid, duration = row
- popular_bvids.add(bvid)
- popular_video_durations[bvid] = duration
- except Exception as e:
- print(f"查询 {year} 年热门视频数据失败: {e}")
- continue
-
- # 4. 定义时长区间(秒)
- duration_ranges = {
- "短视频": {"min": 0, "max": 300, "videos": [], "count": 0}, # ≤5分钟
- "中等视频": {"min": 300, "max": 1200, "videos": [], "count": 0}, # 5-20分钟
- "长视频": {"min": 1200, "max": 3600, "videos": [], "count": 0}, # 20-60分钟
- "超长视频": {"min": 3600, "max": float('inf'), "videos": [], "count": 0} # >60分钟
- }
-
- # 5. 统计用户观看的热门视频按时长分布
- total_popular_watched = 0
-
- for video in user_videos:
- bvid = video[0]
- user_duration = video[4] # 用户历史记录中的时长
-
- if bvid in popular_bvids:
- total_popular_watched += 1
- # 使用热门视频数据库中的时长,如果没有则使用用户记录中的时长
- duration = popular_video_durations.get(bvid, user_duration)
-
- # 分类到对应的时长区间
- for range_name, range_info in duration_ranges.items():
- if range_info["min"] <= duration < range_info["max"]:
- range_info["count"] += 1
- range_info["videos"].append({
- "bvid": bvid,
- "title": video[1],
- "author": video[2],
- "view_at": video[3],
- "duration": duration,
- "formatted_duration": format_duration(duration)
- })
- break
-
- # 6. 计算统计数据
- popular_rate = (total_popular_watched / total_watched) * 100 if total_watched > 0 else 0
-
- # 7. 生成洞察
- insights = []
- insights.append(f"今年观看了 {total_watched} 个视频")
- insights.append(f"其中 {total_popular_watched} 个曾经是热门视频")
-
- if total_popular_watched > 0:
- # 找出最偏爱的时长类型
- max_count = 0
- favorite_duration_type = ""
- for range_name, range_info in duration_ranges.items():
- if range_info["count"] > max_count:
- max_count = range_info["count"]
- favorite_duration_type = range_name
-
- if favorite_duration_type:
- favorite_rate = (max_count / total_popular_watched) * 100
- insights.append(f"最偏爱{favorite_duration_type}热门内容({max_count}个,占{favorite_rate:.1f}%)")
-
- # 分析时长偏好特征
- short_count = duration_ranges["短视频"]["count"]
- medium_count = duration_ranges["中等视频"]["count"]
- long_count = duration_ranges["长视频"]["count"]
- super_long_count = duration_ranges["超长视频"]["count"]
-
- if short_count >= total_popular_watched * 0.5:
- insights.append("你偏爱快节奏的短视频内容")
- elif long_count + super_long_count >= total_popular_watched * 0.5:
- insights.append("你喜欢深度的长视频内容")
- elif medium_count >= total_popular_watched * 0.4:
- insights.append("你偏爱适中时长的视频内容")
- else:
- insights.append("你对各种时长的视频都有涉猎")
-
- # 8. 准备返回数据
- duration_stats = []
- for range_name, range_info in duration_ranges.items():
- if range_info["count"] > 0:
- duration_stats.append({
- "duration_type": range_name,
- "count": range_info["count"],
- "percentage": round((range_info["count"] / total_popular_watched) * 100, 1) if total_popular_watched > 0 else 0,
- "videos": sorted(range_info["videos"], key=lambda x: x["view_at"], reverse=True)[:5] # 最近观看的5个
- })
-
- # 按数量排序
- duration_stats.sort(key=lambda x: x["count"], reverse=True)
-
- # 9. 关闭热门视频数据库连接
- for conn in popular_connections.values():
- if conn:
- conn.close()
-
- return {
- "total_watched": total_watched,
- "total_popular_watched": total_popular_watched,
- "popular_rate": round(popular_rate, 2),
- "duration_stats": duration_stats,
- "popular_duration_videos": duration_stats[:4], # 返回前4个时长类型
- "insights": insights
- }
-
-def format_duration(seconds):
- """格式化时长显示"""
- if seconds < 60:
- return f"{int(seconds)}秒"
- elif seconds < 3600:
- minutes = int(seconds // 60)
- secs = int(seconds % 60)
- return f"{minutes}分{secs}秒" if secs > 0 else f"{minutes}分钟"
- else:
- hours = int(seconds // 3600)
- minutes = int((seconds % 3600) // 60)
- return f"{hours}小时{minutes}分钟" if minutes > 0 else f"{hours}小时"
-
-
-
-@router.get("/popular-hit-rate", summary="获取热门视频命中率分析")
-async def get_popular_hit_rate(
- year: Optional[int] = Query(None, description="要分析的年份,不传则使用当前年份"),
- use_cache: bool = Query(True, description="是否使用缓存,默认为True。如果为False则重新分析数据")
-):
- """获取热门视频命中率分析
-
- 分析用户观看的视频中有多少曾经是热门视频
-
- Args:
- year: 要分析的年份,不传则使用当前年份
- use_cache: 是否使用缓存,默认为True。如果为False则重新分析数据
-
- Returns:
- dict: 包含热门视频命中率分析的数据
- """
- # 验证年份并获取表名
- table_name, target_year, available_years = validate_year_and_get_table(year)
- if table_name is None:
- return available_years # 这里是错误响应
-
- # 检查缓存
- if use_cache:
- try:
- from .title_pattern_discovery import pattern_cache
- cached_data = pattern_cache.get_cached_patterns(table_name, 'popular_hit_rate')
- if cached_data:
- print(f"使用 {target_year} 年的热门命中率分析缓存数据")
- return cached_data
- except Exception as e:
- print(f"获取缓存失败: {e}")
-
- conn = None
- try:
- # 连接数据库
- conn = get_db()
- cursor = conn.cursor()
-
- # 分析热门视频命中率
- hit_rate_analysis = analyze_popular_hit_rate(cursor, table_name, target_year)
-
- # 构建响应
- response = {
- "status": "success",
- "data": {
- "hit_rate_analysis": hit_rate_analysis,
- "year": target_year,
- "available_years": available_years
- }
- }
-
- # 更新缓存
- if use_cache:
- try:
- from .title_pattern_discovery import pattern_cache
- print(f"更新 {target_year} 年的热门命中率分析数据缓存")
- pattern_cache.cache_patterns(table_name, 'popular_hit_rate', response)
- except Exception as e:
- print(f"更新缓存失败: {e}")
-
- return response
-
- except Exception as e:
- raise HTTPException(status_code=500, detail=str(e))
- finally:
- if conn:
- conn.close()
-
-@router.get("/popular-prediction-ability", summary="获取热门预测能力分析")
-async def get_popular_prediction_ability(
- year: Optional[int] = Query(None, description="要分析的年份,不传则使用当前年份"),
- use_cache: bool = Query(True, description="是否使用缓存,默认为True。如果为False则重新分析数据")
-):
- """获取热门预测能力分析
-
- 分析用户观看的视频中,有多少后来成为了热门视频,评估用户的"慧眼识珠"能力
-
- Args:
- year: 要分析的年份,不传则使用当前年份
- use_cache: 是否使用缓存,默认为True。如果为False则重新分析数据
-
- Returns:
- dict: 包含热门预测能力分析的数据
- """
- # 验证年份并获取表名
- table_name, target_year, available_years = validate_year_and_get_table(year)
- if table_name is None:
- return available_years # 这里是错误响应
-
- # 检查缓存
- if use_cache:
- try:
- from .title_pattern_discovery import pattern_cache
- cached_data = pattern_cache.get_cached_patterns(table_name, 'popular_prediction_ability')
- if cached_data:
- print(f"使用 {target_year} 年的热门预测能力分析缓存数据")
- return cached_data
- except Exception as e:
- print(f"获取缓存失败: {e}")
-
- conn = None
- try:
- # 连接数据库
- conn = get_db()
- cursor = conn.cursor()
-
- # 分析热门预测能力
- prediction_analysis = analyze_popular_prediction_ability(cursor, table_name, target_year)
-
- # 构建响应
- response = {
- "status": "success",
- "data": {
- "prediction_analysis": prediction_analysis,
- "year": target_year,
- "available_years": available_years
- }
- }
-
- # 更新缓存
- if use_cache:
- try:
- from .title_pattern_discovery import pattern_cache
- print(f"更新 {target_year} 年的热门预测能力分析数据缓存")
- pattern_cache.cache_patterns(table_name, 'popular_prediction_ability', response)
- except Exception as e:
- print(f"更新缓存失败: {e}")
-
- return response
-
- except Exception as e:
- raise HTTPException(status_code=500, detail=str(e))
- finally:
- if conn:
- conn.close()
-
-@router.get("/author-popular-association", summary="获取UP主热门关联分析")
-async def get_author_popular_association(
- year: Optional[int] = Query(None, description="要分析的年份,不传则使用当前年份"),
- use_cache: bool = Query(True, description="是否使用缓存,默认为True。如果为False则重新分析数据")
-):
- """获取UP主热门关联分析
-
- 分析关注UP主的热门视频产出能力,统计"热门制造机"UP主
-
- Args:
- year: 要分析的年份,不传则使用当前年份
- use_cache: 是否使用缓存,默认为True。如果为False则重新分析数据
-
- Returns:
- dict: 包含UP主热门关联分析的数据
- """
- # 验证年份并获取表名
- table_name, target_year, available_years = validate_year_and_get_table(year)
- if table_name is None:
- return available_years # 这里是错误响应
-
- # 检查缓存
- if use_cache:
- try:
- from .title_pattern_discovery import pattern_cache
- cached_data = pattern_cache.get_cached_patterns(table_name, 'author_popular_association')
- if cached_data:
- print(f"使用 {target_year} 年的UP主热门关联分析缓存数据")
- return cached_data
- except Exception as e:
- print(f"获取缓存失败: {e}")
-
- conn = None
- try:
- # 连接数据库
- conn = get_db()
- cursor = conn.cursor()
-
- # 分析UP主热门关联
- association_analysis = analyze_author_popular_association(cursor, table_name, target_year)
-
- # 构建响应
- response = {
- "status": "success",
- "data": {
- "association_analysis": association_analysis,
- "year": target_year,
- "available_years": available_years
- }
- }
-
- # 更新缓存
- if use_cache:
- try:
- from .title_pattern_discovery import pattern_cache
- print(f"更新 {target_year} 年的UP主热门关联分析数据缓存")
- pattern_cache.cache_patterns(table_name, 'author_popular_association', response)
- except Exception as e:
- print(f"更新缓存失败: {e}")
-
- return response
-
- except Exception as e:
- raise HTTPException(status_code=500, detail=str(e))
- finally:
- if conn:
- conn.close()
-
-@router.get("/category-popular-distribution", summary="获取热门视频分区分布分析")
-async def get_category_popular_distribution(
- year: Optional[int] = Query(None, description="要分析的年份,不传则使用当前年份"),
- use_cache: bool = Query(True, description="是否使用缓存,默认为True。如果为False则重新分析数据")
-):
- """获取热门视频分区分布分析
-
- 分析用户观看的热门视频在各个分区的分布情况
-
- Args:
- year: 要分析的年份,不传则使用当前年份
- use_cache: 是否使用缓存,默认为True。如果为False则重新分析数据
-
- Returns:
- dict: 包含热门视频分区分布分析的数据
- """
- # 验证年份并获取表名
- table_name, target_year, available_years = validate_year_and_get_table(year)
- if table_name is None:
- return available_years # 这里是错误响应
-
- # 检查缓存
- if use_cache:
- try:
- from .title_pattern_discovery import pattern_cache
- cached_data = pattern_cache.get_cached_patterns(table_name, 'category_popular_distribution')
- if cached_data:
- print(f"使用 {target_year} 年的热门视频分区分布分析缓存数据")
- return cached_data
- except Exception as e:
- print(f"获取缓存失败: {e}")
-
- conn = None
- try:
- # 连接数据库
- conn = get_db()
- cursor = conn.cursor()
-
- # 分析热门视频分区分布
- distribution_analysis = analyze_category_popular_distribution(cursor, table_name, target_year)
-
- # 构建响应
- response = {
- "status": "success",
- "data": {
- "distribution_analysis": distribution_analysis,
- "year": target_year,
- "available_years": available_years
- }
- }
-
- # 更新缓存
- if use_cache:
- try:
- from .title_pattern_discovery import pattern_cache
- print(f"更新 {target_year} 年的热门视频分区分布分析数据缓存")
- pattern_cache.cache_patterns(table_name, 'category_popular_distribution', response)
- except Exception as e:
- print(f"更新缓存失败: {e}")
-
- return response
-
- except Exception as e:
- raise HTTPException(status_code=500, detail=str(e))
- finally:
- if conn:
- conn.close()
-
-@router.get("/duration-popular-distribution", summary="获取热门视频时长分布分析")
-async def get_duration_popular_distribution(
- year: Optional[int] = Query(None, description="要分析的年份,不传则使用当前年份"),
- use_cache: bool = Query(True, description="是否使用缓存,默认为True。如果为False则重新分析数据")
-):
- """获取热门视频时长分布分析
-
- 分析用户观看的热门视频在不同时长区间的分布情况
-
- Args:
- year: 要分析的年份,不传则使用当前年份
- use_cache: 是否使用缓存,默认为True。如果为False则重新分析数据
-
- Returns:
- dict: 包含热门视频时长分布分析的数据
- """
- # 验证年份并获取表名
- table_name, target_year, available_years = validate_year_and_get_table(year)
- if table_name is None:
- return available_years # 这里是错误响应
-
- # 检查缓存
- if use_cache:
- try:
- from .title_pattern_discovery import pattern_cache
- cached_data = pattern_cache.get_cached_patterns(table_name, 'duration_popular_distribution')
- if cached_data:
- print(f"使用 {target_year} 年的热门视频时长分布分析缓存数据")
- return cached_data
- except Exception as e:
- print(f"获取缓存失败: {e}")
-
- conn = None
- try:
- # 连接数据库
- conn = get_db()
- cursor = conn.cursor()
-
- # 分析热门视频时长分布
- duration_analysis = analyze_duration_popular_distribution(cursor, table_name, target_year)
-
- # 构建响应
- response = {
- "status": "success",
- "data": {
- "duration_analysis": duration_analysis,
- "year": target_year,
- "available_years": available_years
- }
- }
-
- # 更新缓存
- if use_cache:
- try:
- from .title_pattern_discovery import pattern_cache
- print(f"更新 {target_year} 年的热门视频时长分布分析数据缓存")
- pattern_cache.cache_patterns(table_name, 'duration_popular_distribution', response)
- except Exception as e:
- print(f"更新缓存失败: {e}")
-
- return response
-
- except Exception as e:
- raise HTTPException(status_code=500, detail=str(e))
- finally:
- if conn:
- conn.close()
-
diff --git a/routers/popular_videos.py b/routers/popular_videos.py
deleted file mode 100644
index 1a8359f..0000000
--- a/routers/popular_videos.py
+++ /dev/null
@@ -1,472 +0,0 @@
-from fastapi import APIRouter, Query, HTTPException, BackgroundTasks
-from typing import Dict, Any, List, Optional
-from pydantic import BaseModel, Field
-import asyncio
-import time
-from datetime import datetime
-
-from scripts.popular_videos import (
- get_all_popular_videos,
- query_recent_videos,
- get_fetch_history,
- get_video_tracking_stats,
- get_all_year_dbs,
- cleanup_inactive_video_records
-)
-
-# 创建路由器
-router = APIRouter()
-
-class PopularVideosResponse(BaseModel):
- status: str
- message: Optional[str] = None
- total_videos: Optional[int] = None
- fetch_stats: Optional[Dict[str, Any]] = None
- data: Optional[List[Dict[str, Any]]] = None
- task_id: Optional[str] = None
-
-class FetchHistoryResponse(BaseModel):
- status: str
- message: Optional[str] = None
- data: Optional[List[Dict[str, Any]]] = None
-
-class TrackingStatsResponse(BaseModel):
- status: str
- message: Optional[str] = None
- total: Optional[int] = None
- data: Optional[List[Dict[str, Any]]] = None
-
-class PopularYearsResponse(BaseModel):
- status: str
- message: Optional[str] = None
- data: List[int] = Field(default_factory=list, description="热门视频数据库可用年份(降序)")
- default_year: Optional[int] = Field(default=None, description="建议默认选择年份(最新年份)")
-
-# 用于存储后台任务的状态和清理机制
-task_status = {}
-MAX_TASKS_HISTORY = 100 # 最多保存的任务数量
-TASK_EXPIRY_TIME = 3600 # 任务过期时间(秒)
-
-# 清理过期任务
-def cleanup_old_tasks():
- """清理过期的任务"""
- current_time = time.time()
- expired_tasks = []
-
- for task_id, task_info in task_status.items():
- # 检查任务是否有时间戳,如果没有则添加
- if "timestamp" not in task_info:
- task_info["timestamp"] = current_time
- continue
-
- # 检查任务是否已完成且超过过期时间
- if (task_info["status"] in ["completed", "failed"] and
- current_time - task_info["timestamp"] > TASK_EXPIRY_TIME):
- expired_tasks.append(task_id)
-
- # 删除过期任务
- for task_id in expired_tasks:
- del task_status[task_id]
-
- # 如果任务数量过多,按时间戳删除最旧的任务
- if len(task_status) > MAX_TASKS_HISTORY:
- # 按时间戳排序
- sorted_tasks = sorted(
- task_status.items(),
- key=lambda x: x[1].get("timestamp", 0)
- )
-
- # 计算需要删除的任务数量
- tasks_to_remove = len(task_status) - MAX_TASKS_HISTORY
-
- # 删除最旧的任务
- for i in range(tasks_to_remove):
- if i < len(sorted_tasks):
- del task_status[sorted_tasks[i][0]]
-
-@router.get("/popular/all", summary="获取B站所有热门视频", response_model=PopularVideosResponse)
-async def get_all_popular_videos_api(
- background_tasks: BackgroundTasks,
- size: int = Query(20, description="每页视频数量", ge=1, le=50),
- max_pages: int = Query(100, description="最大获取页数", ge=1, le=500),
- save_to_db: bool = Query(True, description="是否保存到数据库"),
- include_videos: bool = Query(False, description="是否在响应中包含视频数据")
-):
- """
- 获取B站当前所有热门视频并保存到数据库(异步后台处理)
-
- 此接口会立即返回一个任务ID,然后在后台处理获取视频的请求。
- 使用返回的任务ID通过 `/popular/task/{task_id}` 端点查询任务状态和结果。
-
- - **size**: 每页视频数量,默认为20,范围1-50
- - **max_pages**: 最大获取页数,默认为100,范围1-500
- - **save_to_db**: 是否保存到数据库,默认为True
- - **include_videos**: 是否在响应中包含视频数据,默认为False
-
- 返回:
- - **status**: 请求状态,"accepted"表示已接受任务
- - **message**: 状态消息
- - **task_id**: 用于查询任务状态的唯一ID
- """
- # 清理过期任务
- cleanup_old_tasks()
-
- # 生成唯一任务ID
- import uuid
- task_id = str(uuid.uuid4())
-
- # 创建初始状态响应
- task_status[task_id] = {
- "status": "processing",
- "message": "任务已开始处理",
- "progress": 0,
- "result": None,
- "timestamp": time.time()
- }
-
- # 定义后台任务函数
- async def process_popular_videos_task():
- try:
- # 定义进度回调函数
- def update_progress(progress, message, current_page, total_pages, success=True):
- nonlocal task_id
- task_status[task_id].update({
- "status": "processing" if success else "error",
- "message": message,
- "progress": progress,
- "current_page": current_page,
- "total_pages": total_pages,
- "timestamp": time.time() # 更新时间戳
- })
-
- # 在后台线程中执行耗时操作
- loop = asyncio.get_event_loop()
- videos, success, fetch_stats = await loop.run_in_executor(
- None,
- lambda: get_all_popular_videos(
- page_size=size,
- max_pages=max_pages,
- save_to_db=save_to_db,
- progress_callback=update_progress
- )
- )
-
- # 构建结果
- result = {
- "status": "success" if success else "error",
- "total_videos": len(videos),
- "fetch_stats": fetch_stats["fetch_stats"] if "fetch_stats" in fetch_stats else fetch_stats
- }
-
- # 如果需要包含视频数据
- if include_videos and videos:
- result["data"] = videos
-
- if not success:
- result["message"] = fetch_stats.get("message", "获取热门视频失败")
-
- # 更新任务状态为完成
- task_status[task_id] = {
- "status": "completed" if success else "failed",
- "progress": 100,
- "result": result,
- "timestamp": time.time(),
- "message": "热门视频获取完成" if success else fetch_stats.get("message", "获取热门视频失败")
- }
- except Exception as e:
- # 更新任务状态为失败
- task_status[task_id] = {
- "status": "failed",
- "message": f"处理任务失败: {str(e)}",
- "progress": 0,
- "result": None,
- "timestamp": time.time()
- }
-
- # 添加到后台任务
- background_tasks.add_task(process_popular_videos_task)
-
- # 立即返回响应,不等待任务完成
- return PopularVideosResponse(
- status="accepted",
- message="任务已开始处理,请使用任务ID查询进度",
- task_id=task_id
- )
-
-@router.get("/popular/task/{task_id}", summary="获取热门视频获取任务状态")
-async def get_task_status(task_id: str):
- """
- 获取热门视频获取任务的处理状态和结果
-
- 使用从 `/popular/all` 接口获取的任务ID查询任务进度和结果。
-
- - 如果任务仍在处理中,将返回进度信息
- - 如果任务已完成,将返回完整的结果
- - 如果任务失败,将返回错误信息
-
- 任务状态会在服务器上保留一段时间(默认1小时),过期后会被自动清理。
- """
- if task_id not in task_status:
- raise HTTPException(status_code=404, detail="未找到指定任务ID")
-
- task_info = task_status[task_id]
-
- # 如果任务完成且有结果,返回结果
- if task_info["status"] == "completed" and task_info["result"]:
- return task_info["result"]
-
- # 否则返回任务状态
- return {
- "status": task_info["status"],
- "message": task_info.get("message", "任务正在处理中"),
- "progress": task_info.get("progress", 0)
- }
-
-@router.get("/popular/recent", summary="获取最近保存的热门视频", response_model=PopularVideosResponse)
-async def get_recent_popular_videos_api(
- limit: int = Query(20, description="返回视频的数量限制", ge=1, le=200)
-):
- """
- 从数据库获取最近保存的热门视频
-
- - **limit**: 返回视频的数量限制,默认为20
- """
- try:
- # 从数据库查询最近的热门视频
- videos = query_recent_videos(limit=limit)
-
- if not videos:
- return PopularVideosResponse(
- status="success",
- message="未找到任何热门视频记录",
- total_videos=0,
- data=[]
- )
-
- return PopularVideosResponse(
- status="success",
- total_videos=len(videos),
- data=videos
- )
- except Exception as e:
- raise HTTPException(
- status_code=500,
- detail=f"获取热门视频记录失败: {str(e)}"
- )
-
-@router.get("/popular/history", summary="获取热门视频抓取历史", response_model=FetchHistoryResponse)
-async def get_fetch_history_api(
- limit: int = Query(10, description="返回历史记录的数量限制", ge=1, le=100)
-):
- """
- 获取热门视频的抓取历史记录
-
- - **limit**: 返回历史记录的数量限制,默认为10
- """
- try:
- # 获取抓取历史记录
- history = get_fetch_history(limit=limit)
-
- if not history:
- return FetchHistoryResponse(
- status="success",
- message="未找到任何抓取历史记录",
- data=[]
- )
-
- return FetchHistoryResponse(
- status="success",
- data=history
- )
- except Exception as e:
- raise HTTPException(
- status_code=500,
- detail=f"获取抓取历史记录失败: {str(e)}"
- )
-
-@router.get("/popular/tracking", summary="获取视频热门持续时间统计", response_model=TrackingStatsResponse)
-async def get_video_tracking_stats_api(
- limit: int = Query(20, description="返回视频的数量限制", ge=1, le=100)
-):
- """
- 获取视频在热门列表中持续时间的统计信息
-
- - **limit**: 返回视频的数量限制,默认为20
- """
- try:
- # 获取视频热门跟踪统计
- stats = get_video_tracking_stats(limit=limit)
-
- if not stats:
- return TrackingStatsResponse(
- status="success",
- message="未找到任何视频热门跟踪记录",
- total=0,
- data=[]
- )
-
- return TrackingStatsResponse(
- status="success",
- total=len(stats),
- data=stats
- )
- except Exception as e:
- raise HTTPException(
- status_code=500,
- detail=f"获取视频热门跟踪统计失败: {str(e)}"
- )
-
-@router.get("/popular/years", summary="获取热门视频数据库可用年份", response_model=PopularYearsResponse)
-async def get_popular_db_years_api():
- """
- 获取热门视频按年分库的可用年份列表(用于前端下拉菜单)
- """
- try:
- years = sorted(get_all_year_dbs(), reverse=True)
- if not years:
- return PopularYearsResponse(
- status="success",
- message="未找到任何热门视频数据库文件",
- data=[],
- default_year=None
- )
-
- return PopularYearsResponse(
- status="success",
- data=years,
- default_year=years[0]
- )
- except Exception as e:
- raise HTTPException(
- status_code=500,
- detail=f"获取热门视频数据库年份失败: {str(e)}"
- )
-
-@router.get("/popular/tasks", summary="获取所有热门视频获取任务")
-async def list_all_tasks():
- """
- 获取所有热门视频获取任务的状态列表
-
- 返回当前服务器上所有正在处理中和已完成的热门视频获取任务,
- 包括每个任务的ID、状态、进度和创建时间等信息。
-
- 可以使用返回的任务ID通过 `/popular/task/{task_id}` 端点查询具体任务的详细信息。
- """
- # 清理过期任务
- cleanup_old_tasks()
-
- # 返回任务基本信息
- tasks_info = {}
- for task_id, task_info in task_status.items():
- task_summary = {
- "status": task_info["status"],
- "message": task_info.get("message", ""),
- "progress": task_info.get("progress", 0),
- "timestamp": task_info.get("timestamp", 0),
- "created": datetime.fromtimestamp(
- task_info.get("timestamp", 0)
- ).strftime("%Y-%m-%d %H:%M:%S") if task_info.get("timestamp") else ""
- }
- tasks_info[task_id] = task_summary
-
- return {
- "status": "success",
- "total_tasks": len(tasks_info),
- "tasks": tasks_info
- }
-
-@router.post("/popular/cleanup", summary="清理已经不在热门列表的视频数据")
-async def trigger_data_cleanup(
- background_tasks: BackgroundTasks,
- year: Optional[int] = Query(None, description="要清理的年份,不传则清理所有年份")
-):
- """
- 触发清理已经不在热门列表的视频数据的操作
-
- 此操作会删除所有已经不在热门列表的视频中间的记录,只保留首条和末条记录。
- 由于清理操作可能需要较长时间,此API会在后台执行清理并立即返回。
- 清理结果将记录在日志中,也可通过任务ID查询结果。
-
- - **year**: 指定清理的年份;不传则清理所有年份数据库
- """
- available_years = sorted(get_all_year_dbs(), reverse=True)
- if year is not None and year not in available_years:
- return {
- "status": "error",
- "message": f"未找到 {year} 年的热门视频数据库。可用年份:{', '.join(map(str, available_years)) if available_years else '无'}",
- "available_years": available_years
- }
-
- # 清理过期任务
- cleanup_old_tasks()
-
- # 生成唯一任务ID
- import uuid
- task_id = str(uuid.uuid4())
-
- # 创建初始状态响应
- task_status[task_id] = {
- "status": "processing",
- "message": "数据清理任务已开始处理",
- "progress": 0,
- "result": None,
- "timestamp": time.time(),
- "meta": {
- "task_type": "cleanup",
- "year": year,
- "available_years": available_years,
- "target_years": [year] if year is not None else available_years
- }
- }
-
- # 定义后台任务函数
- async def run_cleanup_task():
- # 在异步上下文中执行同步耗时操作
- loop = asyncio.get_event_loop()
- try:
- # 使用run_in_executor在线程池中执行同步操作
- stats = await loop.run_in_executor(None, cleanup_inactive_video_records, year)
- print(f"数据清理完成,统计信息:{stats}")
-
- task_status[task_id] = {
- "status": "completed",
- "message": "数据清理完成",
- "progress": 100,
- "timestamp": time.time(),
- "result": {
- "status": "success",
- "message": "数据清理完成",
- "year": year,
- "available_years": available_years,
- "data": stats
- },
- "meta": task_status[task_id].get("meta", {})
- }
- except Exception as e:
- error_message = f"数据清理过程中出错:{str(e)}"
- print(error_message)
- task_status[task_id] = {
- "status": "failed",
- "message": error_message,
- "progress": 0,
- "timestamp": time.time(),
- "result": {
- "status": "error",
- "message": error_message,
- "year": year,
- "available_years": available_years
- },
- "meta": task_status[task_id].get("meta", {})
- }
-
- # 添加到后台任务
- background_tasks.add_task(run_cleanup_task)
-
- # 立即返回响应
- return {
- "status": "accepted",
- "message": "数据清理任务已开始,将在后台执行。可通过 /bilibili/popular/task/{task_id} 查询状态。",
- "task_id": task_id,
- "year": year,
- "available_years": available_years
- }
diff --git a/routers/scheduler.py b/routers/scheduler.py
deleted file mode 100644
index f57b13e..0000000
--- a/routers/scheduler.py
+++ /dev/null
@@ -1,768 +0,0 @@
-import asyncio
-import os
-
-import yaml
-from fastapi import APIRouter, HTTPException, Depends, Request, Query
-from loguru import logger
-
-from scripts.scheduler_db_enhanced import EnhancedSchedulerDB
-from scripts.scheduler_manager import SchedulerManager
-from scripts.utils import get_config_path as utils_get_config_path, setup_logger
-
-# 确保日志系统已初始化
-setup_logger()
-
-router = APIRouter()
-
-# 获取调度器实例
-def get_scheduler():
- return SchedulerManager.get_instance()
-
-# 获取调度器数据库实例
-def get_scheduler_db():
- return EnhancedSchedulerDB.get_instance()
-
-def get_config_path():
- """获取配置文件路径"""
- # 使用utils中的公共函数来保持一致性
- return utils_get_config_path('scheduler_config.yaml')
-
-def save_config(config):
- """保存配置到文件"""
- config_path = get_config_path()
- os.makedirs(os.path.dirname(config_path), exist_ok=True)
- with open(config_path, 'w', encoding='utf-8') as f:
- yaml.dump(config, f, allow_unicode=True, sort_keys=False)
- return True
-
-@router.get("/tasks", summary="获取任务信息")
-async def get_tasks(
- task_id: str = None,
- include_subtasks: bool = True,
- detail_level: str = "basic",
- db: EnhancedSchedulerDB = Depends(get_scheduler_db)
-):
- """
- 获取任务信息
-
- - 不指定task_id时返回所有任务
- - 指定task_id时返回特定任务详情
- - include_subtasks控制是否包含子任务信息
- - detail_level控制返回信息详细程度
- """
- try:
- tasks = []
- if task_id:
- if db.is_main_task(task_id):
- task_data = db.get_main_task_by_id(task_id)
- if not task_data:
- return {"status": "error", "message": f"任务 {task_id} 不存在"}
- if include_subtasks:
- task_data['sub_tasks'] = db.get_sub_tasks(task_id)
- tasks.append(_build_task_info(task_data))
- else:
- task_data = db.get_subtask_by_id(task_id)
- if not task_data:
- return {"status": "error", "message": f"任务 {task_id} 不存在"}
- tasks.append(_build_task_info(task_data))
- else:
- main_tasks = db.get_all_main_tasks()
- for task_data in main_tasks:
- if include_subtasks:
- task_data['sub_tasks'] = db.get_sub_tasks(task_data['task_id'])
- tasks.append(_build_task_info(task_data))
-
- return {
- "status": "success",
- "message": "获取任务信息成功",
- "tasks": tasks
- }
-
- except Exception as e:
- logger.error(f"获取任务信息失败: {str(e)}", exc_info=True)
- return {
- "status": "error",
- "message": f"获取任务信息失败: {str(e)}"
- }
-
-def _build_task_info(task_data):
- """构建任务信息"""
- # 从配置文件中获取调度类型
- config_path = get_config_path()
- schedule_type = 'daily' # 默认值
-
- if os.path.exists(config_path):
- try:
- with open(config_path, 'r', encoding='utf-8') as f:
- config = yaml.safe_load(f)
- task_id = task_data.get('task_id')
- if task_id and 'tasks' in config and task_id in config['tasks']:
- schedule_type = config['tasks'][task_id].get('schedule', {}).get('type', 'daily')
- except Exception as e:
- logger.error(f"读取配置文件失败: {str(e)}")
-
- config = {
- "name": task_data.get('name', ''),
- "endpoint": task_data.get('endpoint', ''),
- "method": task_data.get('method', 'GET'),
- "params": task_data.get('params', {}),
- "schedule_type": task_data.get('schedule_type') or schedule_type,
- "schedule_time": task_data.get('schedule_time'),
- "schedule_delay": task_data.get('schedule_delay'),
- "interval_value": task_data.get('interval_value'),
- "interval_unit": task_data.get('interval_unit'),
- "enabled": bool(task_data.get('enabled', True)),
- "priority": task_data.get('priority', 0),
- "tags": task_data.get('tags') or []
- }
-
- # 安全处理数值类型
- avg_duration = task_data.get('avg_duration')
- if avg_duration is not None:
- try:
- avg_duration = float(avg_duration)
- except (TypeError, ValueError):
- avg_duration = 0.0
- else:
- avg_duration = 0.0
-
- execution = {
- "last_run": task_data.get('last_run_time'),
- "next_run": task_data.get('next_run_time'),
- "status": task_data.get('last_status') or 'pending',
- "success_rate": task_data.get('success_rate', 0.0),
- "avg_duration": avg_duration,
- "total_runs": int(task_data.get('total_runs') or 0),
- "success_runs": int(task_data.get('success_runs') or 0),
- "fail_runs": int(task_data.get('fail_runs') or 0),
- "last_error": task_data.get('last_error')
- }
-
- task_type = task_data.get('task_type')
- if not task_type:
- task_type = 'sub' if task_data.get('parent_id') else 'main'
-
- result = {
- "task_id": task_data['task_id'],
- "task_type": task_type,
- "config": config,
- "execution": execution,
- "parent_id": task_data.get('parent_id'),
- "sub_tasks": [_build_subtask_info(sub_task) for sub_task in task_data.get('sub_tasks', [])] if task_data.get('sub_tasks') else None,
- "created_at": task_data.get('created_at'),
- "last_modified": task_data.get('last_modified')
- }
-
- # 添加依赖信息
- if task_data.get('depends_on'):
- result['depends_on'] = task_data['depends_on']
-
- return result
-
-def _build_subtask_info(task_data):
- """构建子任务信息"""
- task_info = _build_task_info(task_data)
- return {
- "task_id": task_info["task_id"],
- "config": task_info["config"],
- "execution": task_info["execution"],
- "sequence_number": task_data.get('sequence_number', 0),
- "created_at": task_data.get('created_at'),
- "last_modified": task_data.get('last_modified')
- }
-
-@router.post("/tasks", summary="创建新任务")
-async def create_task(
- task_data: dict,
- db: EnhancedSchedulerDB = Depends(get_scheduler_db),
- scheduler: SchedulerManager = Depends(get_scheduler)
-):
- """
- 创建新任务
-
- - 支持创建主任务和子任务
- - 子任务需要指定parent_id和sequence_number
- """
- try:
- task_id = task_data.get('task_id')
- task_type = task_data.get('task_type', 'main')
-
- if task_type == "main":
- success = scheduler.add_main_task(task_id, task_data.get('config', {}))
- else:
- parent_id = task_data.get('parent_id')
- if not parent_id:
- return {"status": "error", "message": "创建子任务时必须指定parent_id"}
- success = scheduler.add_sub_task(parent_id, task_id, task_data.get('config', {}))
-
- if success:
- # 重新加载调度器配置
- scheduler.reload_scheduler()
-
- task_info = None
- if task_type == "main":
- task_info = _build_task_info(db.get_main_task_by_id(task_id))
- else:
- task_info = _build_task_info(db.get_subtask_by_id(task_id))
-
- return {
- "status": "success",
- "message": f"成功创建{task_type}任务",
- "task_id": task_id,
- "task_info": task_info
- }
-
- return {
- "status": "error",
- "message": "创建任务失败",
- "task_id": task_id
- }
-
- except Exception as e:
- logger.error(f"创建任务失败: {str(e)}", exc_info=True)
- return {
- "status": "error",
- "message": f"创建任务失败: {str(e)}"
- }
-
-@router.put("/tasks/{task_id}", summary="更新任务配置")
-async def update_task(
- task_id: str,
- task_data: dict,
- db: EnhancedSchedulerDB = Depends(get_scheduler_db),
- scheduler: SchedulerManager = Depends(get_scheduler)
-):
- """
- 更新任务配置
-
- - 支持更新主任务和子任务
- - 支持更新任务配置、状态、优先级、标签等
- - 支持更新子任务执行顺序
- """
- try:
- if db.is_main_task(task_id):
- success = db.update_main_task(task_id, task_data)
- else:
- success = db.update_subtask(task_id, task_data)
-
- if success:
- # 重新加载调度器配置
- scheduler.reload_scheduler()
-
- task_info = None
- if db.is_main_task(task_id):
- task_info = _build_task_info(db.get_main_task_by_id(task_id))
- else:
- task_info = _build_task_info(db.get_subtask_by_id(task_id))
-
- return {
- "status": "success",
- "message": "任务更新成功",
- "task_id": task_id,
- "task_info": task_info
- }
- else:
- return {
- "status": "error",
- "message": "任务更新失败",
- "task_id": task_id
- }
-
- except Exception as e:
- logger.error(f"更新任务失败: {str(e)}", exc_info=True)
- return {
- "status": "error",
- "message": f"更新任务失败: {str(e)}"
- }
-
-@router.delete("/tasks/{task_id}", summary="删除任务")
-async def delete_task(
- task_id: str,
- db: EnhancedSchedulerDB = Depends(get_scheduler_db)
-):
- """
- 删除任务
-
- - 支持删除主任务和子任务
- - 删除主任务时会自动删除其所有子任务
- """
- try:
- if db.is_main_task(task_id):
- success = db.delete_main_task(task_id)
- else:
- success = db.delete_subtask(task_id)
-
- if success:
- return {
- "status": "success",
- "message": "任务删除成功",
- "task_id": task_id
- }
- else:
- return {
- "status": "error",
- "message": "任务删除失败",
- "task_id": task_id
- }
-
- except Exception as e:
- logger.error(f"删除任务失败: {str(e)}", exc_info=True)
- return {
- "status": "error",
- "message": f"删除任务失败: {str(e)}"
- }
-
-@router.post("/tasks/{task_id}/execute", summary="执行任务")
-async def execute_task(
- task_id: str,
- execute_params: dict = None,
- scheduler: SchedulerManager = Depends(get_scheduler)
-):
- """
- 执行任务
-
- - 支持执行主任务和子任务
- - 可控制是否执行子任务
- - 可选择是否等待任务完成
- """
- try:
- wait_for_completion = execute_params.get('wait_for_completion', False) if execute_params else False
-
- if wait_for_completion:
- success = await scheduler.execute_task(task_id)
- else:
- asyncio.create_task(scheduler.execute_task(task_id))
- success = True
-
- if success:
- return {
- "status": "success",
- "message": "任务执行已启动",
- "task_id": task_id
- }
-
- return {
- "status": "error",
- "message": "任务执行失败",
- "task_id": task_id
- }
-
- except Exception as e:
- logger.error(f"执行任务失败: {str(e)}", exc_info=True)
- return {
- "status": "error",
- "message": f"执行任务失败: {str(e)}"
- }
-
-@router.get("/tasks/history", summary="查询任务执行历史")
-async def get_task_history(
- task_id: str = None,
- include_subtasks: bool = True,
- status: str = None,
- start_date: str = None,
- end_date: str = None,
- page: int = 1,
- page_size: int = 20,
- db: EnhancedSchedulerDB = Depends(get_scheduler_db)
-):
- """
- 查询任务执行历史
-
- - 支持查询主任务和子任务历史
- - 支持按时间范围和状态过滤
- - 支持分页查询
- """
- try:
- conditions = {
- 'status': status,
- 'start_date': start_date,
- 'end_date': end_date
- }
-
- if task_id:
- # 无论是主任务还是子任务,都使用 get_task_execution_history_enhanced
- result = db.get_task_execution_history_enhanced(
- task_id,
- include_subtasks=include_subtasks if db.is_main_task(task_id) else False,
- conditions=conditions,
- page=page,
- page_size=page_size
- )
- else:
- result = db.get_recent_task_executions_enhanced(
- include_subtasks=include_subtasks,
- conditions=conditions,
- page=page,
- page_size=page_size
- )
-
- return {
- "status": "success",
- "message": "获取任务执行历史成功",
- "history": result['records'],
- "total_count": result['total'],
- "page": page,
- "page_size": page_size
- }
-
- except Exception as e:
- logger.error(f"获取任务执行历史失败: {str(e)}", exc_info=True)
- return {
- "status": "error",
- "message": f"获取任务执行历史失败: {str(e)}"
- }
-
-@router.get("/available-endpoints", summary="获取可用API端点")
-async def get_available_endpoints(request: Request):
- """
- 获取所有可用的API端点信息
-
- - 返回系统中所有已注册的API端点
- - 包含路径、方法、描述等信息
- - 不包含系统内置的文档相关端点
- """
- try:
- # 需要过滤的内置端点路径
- builtin_paths = {
- '/openapi.json',
- '/docs',
- '/docs/oauth2-redirect',
- '/redoc',
- '/redoc-models.js'
- }
-
- endpoints = []
- for route in request.app.routes:
- if hasattr(route, 'methods'):
- # 跳过内置的文档相关端点
- if route.path in builtin_paths:
- continue
-
- # 跳过HEAD方法(通常是自动生成的)
- methods = [m for m in route.methods if m != 'HEAD']
- if not methods:
- continue
-
- endpoints.append({
- "path": route.path,
- "method": methods[0],
- "summary": getattr(route, 'summary', None),
- "tags": getattr(route, 'tags', []),
- "operationId": route.name if hasattr(route, 'name') else None
- })
-
- # 按路径排序,使输出更有序
- endpoints.sort(key=lambda x: x['path'])
-
- return {
- "status": "success",
- "message": f"获取API端点列表成功,共 {len(endpoints)} 个端点",
- "total": len(endpoints),
- "endpoints": endpoints
- }
-
- except Exception as e:
- logger.error(f"获取API端点列表失败: {str(e)}", exc_info=True)
- return {
- "status": "error",
- "message": f"获取API端点列表失败: {str(e)}"
- }
-
-@router.post("/tasks/{task_id}/subtasks", summary="添加子任务")
-async def add_sub_task(
- task_id: str,
- sub_task_data: dict,
- scheduler: SchedulerManager = Depends(get_scheduler),
- db: EnhancedSchedulerDB = Depends(get_scheduler_db)
-):
- """
- 为主任务添加子任务
-
- - 需要指定子任务名称、执行顺序、API端点等信息
- - 自动设置子任务为启用状态
- - 从配置文件读取调度类型,默认为'daily'
- """
- try:
- if task_id not in scheduler.tasks:
- return {"status": "error", "message": f"主任务 {task_id} 不存在"}
-
- if not db.is_main_task(task_id):
- return {"status": "error", "message": f"任务 {task_id} 不是主任务"}
-
- # 从配置文件获取调度类型
- config_path = get_config_path()
- schedule_type = 'daily' # 默认值
-
- if os.path.exists(config_path):
- try:
- with open(config_path, 'r', encoding='utf-8') as f:
- config = yaml.safe_load(f)
- sub_task_id = sub_task_data.get('task_id')
- if sub_task_id and 'tasks' in config and sub_task_id in config['tasks']:
- schedule_type = config['tasks'][sub_task_id].get('schedule', {}).get('type', 'daily')
- except Exception as e:
- logger.error(f"读取配置文件失败: {str(e)}")
-
- sub_task_config = {
- "task_id": sub_task_data.get('task_id'),
- "name": sub_task_data.get('name'),
- "sequence_number": sub_task_data.get('sequence_number'),
- "endpoint": sub_task_data.get('endpoint'),
- "method": sub_task_data.get('method', 'GET'),
- "params": sub_task_data.get('params'),
- "enabled": True,
- "task_type": "sub",
- "schedule_type": sub_task_data.get('schedule_type') or schedule_type,
- "depends_on": sub_task_data.get('depends_on') # 添加依赖关系
- }
-
- # 获取子任务ID
- sub_task_id = sub_task_data.get('task_id')
- if not sub_task_id:
- return {"status": "error", "message": "子任务ID不能为空"}
-
- result = scheduler.add_sub_task(task_id, sub_task_id, sub_task_config)
-
- if not result:
- return {"status": "error", "message": "添加子任务失败"}
-
- # 重新加载调度器配置
- scheduler.reload_scheduler()
-
- return {
- "status": "success",
- "message": f"成功为主任务 {task_id} 添加子任务",
- "task_id": task_id
- }
- except Exception as e:
- logger.error(f"添加子任务失败: {str(e)}")
- return {"status": "error", "message": f"添加子任务失败: {str(e)}"}
-
-@router.get("/tasks/{task_id}/subtasks", summary="获取子任务列表")
-async def get_sub_tasks(
- task_id: str,
- db: EnhancedSchedulerDB = Depends(get_scheduler_db),
- scheduler: SchedulerManager = Depends(get_scheduler)
-):
- """
- 获取主任务的所有子任务
-
- - 返回子任务的详细信息,包括调度类型
- - 包含执行状态、成功率等统计数据
- - 按执行顺序排序
- """
- try:
- # 检查主任务是否存在
- if task_id not in scheduler.tasks:
- raise HTTPException(status_code=404, detail=f"主任务 {task_id} 不存在")
-
- # 检查是否为主任务
- if not db.is_main_task(task_id):
- raise HTTPException(status_code=400, detail=f"任务 {task_id} 不是主任务")
-
- # 获取子任务列表
- sub_tasks = db.get_sub_tasks(task_id)
-
- # 处理每个子任务的状态
- processed_sub_tasks = []
- for sub_task in sub_tasks:
- sub_task_id = sub_task['task_id']
-
- # 获取子任务状态
- status = '未执行'
- if sub_task.get('last_run_time'):
- status = '成功' if sub_task.get('last_status') == 'success' else '失败'
-
- # 计算成功率
- total_runs = sub_task.get('total_runs', 0)
- success_runs = sub_task.get('success_runs', 0)
- success_rate = round(success_runs / total_runs * 100, 2) if total_runs > 0 else None
-
- processed_sub_task = {
- 'task_id': sub_task_id,
- 'name': sub_task.get('name', sub_task_id),
- 'sequence_number': sub_task.get('sequence_number', 0),
- 'endpoint': sub_task.get('endpoint'),
- 'method': sub_task.get('method', 'GET'),
- 'params': sub_task.get('params'),
- 'status': status,
- 'enabled': bool(sub_task.get('enabled', True)),
- 'success_rate': success_rate,
- 'total_runs': total_runs,
- 'success_runs': success_runs,
- 'fail_runs': sub_task.get('fail_runs', 0),
- 'last_error': sub_task.get('last_error'),
- 'tags': sub_task.get('tags', []),
- 'task_type': 'sub',
- 'schedule_type': sub_task.get('schedule_type', 'daily')
- }
- processed_sub_tasks.append(processed_sub_task)
-
- # 按序号排序
- processed_sub_tasks.sort(key=lambda x: x['sequence_number'])
-
- return {
- "status": "success",
- "message": f"成功获取主任务 {task_id} 的子任务列表",
- "sub_tasks": processed_sub_tasks
- }
- except HTTPException:
- raise
- except Exception as e:
- logger.error(f"获取子任务列表失败: {str(e)}")
- raise HTTPException(status_code=500, detail=f"获取子任务列表失败: {str(e)}")
-
-@router.delete("/tasks/{task_id}/subtasks/{sub_task_id}", summary="删除子任务")
-async def delete_sub_task(
- task_id: str,
- sub_task_id: str,
- db: EnhancedSchedulerDB = Depends(get_scheduler_db),
- scheduler: SchedulerManager = Depends(get_scheduler)
-):
- """
- 删除子任务
-
- - 从主任务中移除指定的子任务
- - 同时删除子任务的执行历史记录
- """
- try:
- # 检查主任务是否存在
- if task_id not in scheduler.tasks:
- raise HTTPException(status_code=404, detail=f"主任务 {task_id} 不存在")
-
- # 检查是否为主任务
- if not db.is_main_task(task_id):
- raise HTTPException(status_code=400, detail=f"任务 {task_id} 不是主任务")
-
- # 检查子任务是否存在
- sub_task = db.get_sub_task(task_id, sub_task_id)
- if not sub_task:
- raise HTTPException(status_code=404, detail=f"子任务 {sub_task_id} 不存在")
-
- # 删除子任务
- result = db.delete_sub_task(task_id, sub_task_id)
-
- if not result:
- raise HTTPException(status_code=500, detail="删除子任务失败")
-
- return {
- "status": "success",
- "message": f"成功删除子任务 {sub_task_id}",
- "task_id": task_id,
- "sub_task_id": sub_task_id
- }
- except HTTPException:
- raise
- except Exception as e:
- logger.error(f"删除子任务失败: {str(e)}")
- raise HTTPException(status_code=500, detail=f"删除子任务失败: {str(e)}")
-
-@router.put("/tasks/{task_id}/subtasks/{sub_task_id}/sequence", summary="更新子任务顺序")
-async def update_sub_task_sequence(
- task_id: str,
- sub_task_id: str,
- sequence: int = Query(..., description="新的执行顺序"),
- db: EnhancedSchedulerDB = Depends(get_scheduler_db),
- scheduler: SchedulerManager = Depends(get_scheduler)
-):
- """
- 更新子任务的执行顺序
-
- - 修改子任务在主任务中的执行顺序
- - 自动调整其他子任务的顺序
- """
- try:
- # 检查主任务是否存在
- if task_id not in scheduler.tasks:
- raise HTTPException(status_code=404, detail=f"主任务 {task_id} 不存在")
-
- # 检查是否为主任务
- if not db.is_main_task(task_id):
- raise HTTPException(status_code=400, detail=f"任务 {task_id} 不是主任务")
-
- # 检查子任务是否存在
- sub_task = db.get_sub_task(task_id, sub_task_id)
- if not sub_task:
- raise HTTPException(status_code=404, detail=f"子任务 {sub_task_id} 不存在")
-
- # 更新执行顺序
- result = db.update_sub_task_sequence(task_id, sub_task_id, sequence)
-
- if not result:
- raise HTTPException(status_code=500, detail="更新子任务执行顺序失败")
-
- return {
- "status": "success",
- "message": f"成功更新子任务 {sub_task_id} 的执行顺序为 {sequence}",
- "task_id": task_id,
- "sub_task_id": sub_task_id,
- "sequence": sequence
- }
- except HTTPException:
- raise
- except Exception as e:
- logger.error(f"更新子任务执行顺序失败: {str(e)}")
- raise HTTPException(status_code=500, detail=f"更新子任务执行顺序失败: {str(e)}")
-
-@router.post("/tasks/{task_id}/enable", summary="启用/禁用任务")
-async def enable_task(
- task_id: str,
- request: dict,
- db: EnhancedSchedulerDB = Depends(get_scheduler_db),
- scheduler: SchedulerManager = Depends(get_scheduler)
-):
- """
- 启用或禁用任务
-
- - 支持启用/禁用主任务和子任务
- - 禁用主任务时会自动禁用其所有子任务
- - 启用主任务不会自动启用子任务
- - 子任务的启用/禁用不影响其他任务
- """
- try:
- # 检查任务是否存在
- is_main = db.is_main_task(task_id)
- task = None
-
- if is_main:
- task = db.get_main_task_by_id(task_id)
- else:
- task = db.get_subtask_by_id(task_id)
-
- if not task:
- raise HTTPException(status_code=404, detail=f"任务 {task_id} 不存在")
-
- enabled = request.get('enabled', True)
-
- if is_main:
- # 更新主任务状态
- result = db.update_main_task(task_id, {'enabled': enabled})
-
- if enabled is False:
- # 如果是禁用主任务,同时禁用所有子任务
- sub_tasks = db.get_sub_tasks(task_id)
- for sub_task in sub_tasks:
- db.update_subtask(sub_task['task_id'], {'enabled': False})
-
- success_message = f"已禁用主任务 {task_id} 及其所有子任务"
- else:
- success_message = f"已启用主任务 {task_id}"
- else:
- # 更新子任务状态
- result = db.update_subtask(task_id, {'enabled': enabled})
- success_message = f"已{'启用' if enabled else '禁用'}子任务 {task_id}"
-
- if not result:
- raise HTTPException(status_code=500, detail=f"更新任务状态失败")
-
- return {
- "status": "success",
- "message": success_message,
- "task_id": task_id,
- "enabled": enabled
- }
- except HTTPException:
- raise
- except Exception as e:
- logger.error(f"更新任务状态失败: {str(e)}")
- raise HTTPException(status_code=500, detail=f"更新任务状态失败: {str(e)}")
\ No newline at end of file
diff --git a/routers/send_log.py b/routers/send_log.py
deleted file mode 100644
index e77bc20..0000000
--- a/routers/send_log.py
+++ /dev/null
@@ -1,40 +0,0 @@
-from datetime import datetime
-from typing import Optional
-
-from fastapi import APIRouter, Body
-
-from scripts.send_log_email import send_email, get_task_execution_logs
-
-router = APIRouter()
-
-@router.post("/send-email", summary="发送日志邮件")
-async def send_log_email(
- subject: str = Body(..., description="邮件主题"),
- content: Optional[str] = Body(None, description="邮件内容,如果为None则发送当前任务执行的日志内容"),
- to_email: Optional[str] = Body(None, description="收件人邮箱,不填则使用配置文件中的默认收件人")
-):
- """发送日志邮件"""
- try:
- # 如果没有提供内容,则获取任务执行期间的日志
- if content is None:
- content = get_task_execution_logs()
- if not content or content == "未找到任务执行记录":
- content = "当前没有任务执行记录"
-
- # 格式化内容,添加时间戳
- formatted_content = f"""
-时间: {datetime.now().strftime("%Y-%m-%d %H:%M:%S")}
-
-=== 执行日志 ===
-{content}
-=============
-"""
-
- result = await send_email(
- subject=subject,
- content=formatted_content,
- to_email=to_email
- )
- return {"status": "success", "message": "邮件发送成功"}
- except Exception as e:
- return {"status": "error", "message": f"邮件发送失败: {str(e)}"}
diff --git a/routers/title_analytics.py b/routers/title_analytics.py
deleted file mode 100644
index 4ed0100..0000000
--- a/routers/title_analytics.py
+++ /dev/null
@@ -1,698 +0,0 @@
-import sqlite3
-from collections import Counter
-from collections import defaultdict
-from datetime import datetime
-from typing import Dict, List, Tuple, Optional
-
-import jieba
-import numpy as np
-from fastapi import APIRouter, HTTPException, Query
-from snownlp import SnowNLP
-
-from scripts.utils import load_config, get_output_path
-from .title_pattern_discovery import discover_interaction_patterns
-
-router = APIRouter()
-config = load_config()
-
-def get_db():
- """获取数据库连接"""
- db_path = get_output_path(config['db_file'])
- return sqlite3.connect(db_path)
-
-def analyze_keywords(titles_data: List[tuple]) -> List[Tuple[str, int]]:
- """
- 从标题数据中提取关键词及其频率
-
- Args:
- titles_data: 包含(title, duration, progress, tag_name, view_at)的元组列表
-
- Returns:
- List[Tuple[str, int]]: 关键词和频率的列表
- """
- # 停用词列表(可以根据需要扩展)
- stop_words = {'的', '了', '是', '在', '我', '有', '和', '就', '不', '人', '都', '一', '一个', '上', '也', '很', '到', '说', '要', '去', '你', '会', '着', '没有', '看', '好', '自己', '这'}
-
- # 所有标题分词后的结果
- all_words = []
- for title_data in titles_data:
- title = title_data[0] # 标题在元组的第一个位置
- if not title: # 跳过空标题
- continue
- words = jieba.cut(title)
- # 过滤停用词和单字词(通常单字词不能很好地表达含义)
- words = [w for w in words if w not in stop_words and len(w) > 1]
- all_words.extend(words)
-
- # 统计词频
- word_freq = Counter(all_words)
-
- # 返回前20个最常见的词
- return word_freq.most_common(20)
-
-def analyze_completion_rates(titles_data: List[tuple]) -> Dict:
- """
- 分析标题特征与完成率的关系
-
- Args:
- titles_data: 包含(title, duration, progress, tag_name, view_at)的元组列表
-
- Returns:
- Dict: 完成率分析结果
- """
- # 计算每个视频的完成率
- completion_rates = []
- titles = []
- for title_data in titles_data:
- title = title_data[0]
- duration = float(title_data[1]) if title_data[1] is not None else 0
- progress = float(title_data[2]) if title_data[2] is not None else 0
-
- if duration and duration > 0: # 确保duration有效且大于0
- if progress == -1.0: # progress为-1表示看完了
- completion_rate = 1.0
- elif progress > 0:
- completion_rate = min(progress / duration, 1.0) # 限制最大值为1
- else:
- completion_rate = 0.0
- completion_rates.append(completion_rate)
- titles.append(title)
-
- # 提取关键词
- keywords = analyze_keywords([(title,) for title in titles])
-
- # 分析包含每个关键词的视频的平均完成率
- keyword_completion_rates = {}
- for keyword, _ in keywords:
- rates = []
- for title, rate in zip(titles, completion_rates):
- if keyword in title:
- rates.append(rate)
- if rates: # 如果有包含该关键词的视频
- avg_rate = sum(rates) / len(rates)
- keyword_completion_rates[keyword] = {
- 'average_completion_rate': avg_rate,
- 'video_count': len(rates)
- }
-
- return keyword_completion_rates
-
-def generate_insights(keywords: List[Tuple[str, int]], completion_rates: Dict) -> List[str]:
- """
- 根据关键词和完成率生成洞察
-
- Args:
- keywords: 关键词和频率的列表
- completion_rates: 完成率分析结果
-
- Returns:
- List[str]: 洞察列表
- """
- insights = []
-
- # 1. 关键词频率洞察
- top_keywords = [(word, count) for word, count in keywords[:5]]
- if top_keywords:
- insights.append(f"在您观看的视频中,最常出现的关键词是:{', '.join([f'{word}({count}次)' for word, count in top_keywords])}")
-
- # 2. 完成率洞察
- if completion_rates:
- # 按完成率排序
- sorted_rates = sorted(
- [(k, v['average_completion_rate'], v['video_count'])
- for k, v in completion_rates.items()],
- key=lambda x: x[1],
- reverse=True
- )
-
- # 高完成率关键词(前3个)
- high_completion = sorted_rates[:3]
- if high_completion:
- insights.append(f"包含关键词 {', '.join([f'{k}({rate:.1%})' for k, rate, count in high_completion])} 的视频往往会被您看完。")
-
- # 低完成率关键词(后3个)
- low_completion = sorted_rates[-3:]
- low_completion.reverse() # 从低到高显示
- if low_completion:
- insights.append(f"而包含关键词 {', '.join([f'{k}({rate:.1%})' for k, rate, count in low_completion])} 的视频较少被看完。")
-
- return insights
-
-def analyze_title_length(cursor, table_name: str) -> dict:
- """分析标题长度与观看行为的关系"""
- cursor.execute(f"""
- SELECT title, duration, progress
- FROM {table_name}
- WHERE duration > 0 AND title IS NOT NULL
- AND strftime('%Y', datetime(view_at, 'unixepoch')) = ?
- """, (table_name.split('_')[-1],))
-
- length_stats = defaultdict(lambda: {'count': 0, 'completion_rates': []})
-
- for title, duration, progress in cursor.fetchall():
- length = len(title)
- completion_rate = progress / duration if duration > 0 else 0
- length_group = (length // 5) * 5 # 按5个字符分组
- length_stats[length_group]['count'] += 1
- length_stats[length_group]['completion_rates'].append(completion_rate)
-
- # 计算每个长度组的平均完成率
- results = {}
- for length_group, stats in length_stats.items():
- avg_completion = np.mean(stats['completion_rates'])
- results[f"{length_group}-{length_group+4}字"] = {
- 'count': stats['count'],
- 'avg_completion_rate': avg_completion
- }
-
- # 找出最佳长度范围
- best_length = max(results.items(), key=lambda x: x[1]['avg_completion_rate'])
- most_common = max(results.items(), key=lambda x: x[1]['count'])
-
- return {
- 'length_stats': results,
- 'best_length': best_length[0],
- 'most_common_length': most_common[0],
- 'insights': [
- f"标题长度在{best_length[0]}的视频最容易被你看完,平均完成率为{best_length[1]['avg_completion_rate']:.1%}",
- f"你观看的视频中,标题长度最常见的是{most_common[0]},共有{most_common[1]['count']}个视频"
- ]
- }
-
-def analyze_title_sentiment(cursor, table_name: str) -> dict:
- """分析标题情感与观看行为的关系"""
- cursor.execute(f"""
- SELECT title, duration, progress
- FROM {table_name}
- WHERE duration > 0 AND title IS NOT NULL
- AND strftime('%Y', datetime(view_at, 'unixepoch')) = ?
- """, (table_name.split('_')[-1],))
-
- sentiment_stats = {
- '积极': {'count': 0, 'completion_rates': []},
- '中性': {'count': 0, 'completion_rates': []},
- '消极': {'count': 0, 'completion_rates': []}
- }
-
- for title, duration, progress in cursor.fetchall():
- sentiment = SnowNLP(title).sentiments
- completion_rate = progress / duration if duration > 0 else 0
-
- # 情感分类
- if sentiment > 0.6:
- category = '积极'
- elif sentiment < 0.4:
- category = '消极'
- else:
- category = '中性'
-
- sentiment_stats[category]['count'] += 1
- sentiment_stats[category]['completion_rates'].append(completion_rate)
-
- # 计算每种情感的平均完成率
- results = {}
- for sentiment, stats in sentiment_stats.items():
- if stats['count'] > 0:
- results[sentiment] = {
- 'count': stats['count'],
- 'avg_completion_rate': np.mean(stats['completion_rates'])
- }
-
- # 找出最受欢迎的情感类型
- best_sentiment = max(results.items(), key=lambda x: x[1]['avg_completion_rate'])
- most_common = max(results.items(), key=lambda x: x[1]['count'])
-
- return {
- 'sentiment_stats': results,
- 'best_sentiment': best_sentiment[0],
- 'most_common_sentiment': most_common[0],
- 'insights': [
- f"{best_sentiment[0]}情感的视频最容易引起你的兴趣,平均完成率为{best_sentiment[1]['avg_completion_rate']:.1%}",
- f"在你观看的视频中,{most_common[0]}情感的内容最多,共有{most_common[1]['count']}个视频"
- ]
- }
-
-def analyze_title_trends(cursor, table_name: str) -> dict:
- """分析标题趋势与观看行为的关系"""
- cursor.execute(f"""
- SELECT title, duration, progress, view_at
- FROM {table_name}
- WHERE duration > 0 AND title IS NOT NULL
- AND strftime('%Y', datetime(view_at, 'unixepoch')) = ?
- ORDER BY view_at ASC
- """, (table_name.split('_')[-1],))
-
- # 按月分组的关键词统计和视频计数
- monthly_keywords = defaultdict(lambda: defaultdict(int))
- monthly_video_count = defaultdict(int) # 新增:每月视频计数
-
- for title, duration, progress, view_at in cursor.fetchall():
- month = datetime.fromtimestamp(view_at).strftime('%Y-%m')
- monthly_video_count[month] += 1 # 新增:增加月度视频计数
- words = jieba.cut(title)
- for word in words:
- if len(word) > 1: # 排除单字词
- monthly_keywords[month][word] += 1
-
- # 分析每个月的热门关键词
- trending_keywords = {}
- for month, keywords in monthly_keywords.items():
- # 获取当月TOP5关键词
- top_keywords = sorted(keywords.items(), key=lambda x: x[1], reverse=True)[:5]
- trending_keywords[month] = {
- 'top_keywords': top_keywords,
- 'total_videos': monthly_video_count[month] # 修改:使用实际的月度视频数量
- }
-
- # 识别关键词趋势
- all_months = sorted(trending_keywords.keys())
- if len(all_months) >= 2:
- first_month = all_months[0]
- last_month = all_months[-1]
-
- # 计算关键词增长率
- first_keywords = set(k for k, _ in trending_keywords[first_month]['top_keywords'])
- last_keywords = set(k for k, _ in trending_keywords[last_month]['top_keywords'])
-
- new_trending = last_keywords - first_keywords
- fading = first_keywords - last_keywords
- consistent = first_keywords & last_keywords
-
- trend_insights = []
- if new_trending:
- trend_insights.append(f"新兴关键词: {', '.join(new_trending)}")
- if consistent:
- trend_insights.append(f"持续热门: {', '.join(consistent)}")
- if fading:
- trend_insights.append(f"减少关注: {', '.join(fading)}")
- else:
- trend_insights = ["数据量不足以分析趋势"]
-
- return {
- 'monthly_trends': trending_keywords,
- 'insights': trend_insights
- }
-
-def analyze_title_interaction(cursor, table_name: str) -> dict:
- """分析标题与用户互动的关系"""
- cursor.execute(f"""
- SELECT title, duration, progress, tag_name, view_at
- FROM {table_name}
- WHERE duration > 0 AND title IS NOT NULL
- AND strftime('%Y', datetime(view_at, 'unixepoch')) = ?
- """, (table_name.split('_')[-1],))
-
- titles_data = cursor.fetchall()
-
- # 使用互动模式发现功能,不再传递table_name参数
- discovered_patterns = discover_interaction_patterns(titles_data)
-
- interaction_stats = defaultdict(lambda: {'count': 0, 'completion_rates': []})
-
- for title, duration, progress, *_ in titles_data:
- completion_rate = progress / duration if duration > 0 else 0
- found_pattern = False
-
- for pattern_type, pattern_info in discovered_patterns.items():
- if any(keyword in title for keyword in pattern_info['keywords']):
- interaction_stats[pattern_type]['count'] += 1
- interaction_stats[pattern_type]['completion_rates'].append(completion_rate)
- found_pattern = True
-
- if not found_pattern:
- interaction_stats['其他']['count'] += 1
- interaction_stats['其他']['completion_rates'].append(completion_rate)
-
- results = {}
- for pattern, stats in interaction_stats.items():
- if stats['count'] > 0:
- results[pattern] = {
- 'count': stats['count'],
- 'avg_completion_rate': np.mean(stats['completion_rates']),
- 'keywords': discovered_patterns[pattern]['keywords'] if pattern in discovered_patterns else []
- }
-
- best_pattern = max(results.items(), key=lambda x: x[1]['avg_completion_rate'])
- most_common = max(results.items(), key=lambda x: x[1]['count'])
-
- return {
- 'interaction_stats': results,
- 'best_pattern': best_pattern[0],
- 'most_common_pattern': most_common[0],
- 'insights': [
- f"{best_pattern[0]}互动方式的标题最容易引起互动,平均完成率为{best_pattern[1]['avg_completion_rate']:.1%}",
- f"在你观看的视频中,{most_common[0]}互动方式最常见,共有{most_common[1]['count']}个视频"
- ]
- }
-
-def validate_year_and_get_table(year: Optional[int]) -> tuple:
- """验证年份并返回表名和可用年份列表
-
- Args:
- year: 要验证的年份,None表示使用最新年份
-
- Returns:
- tuple: (table_name, target_year, available_years) 或 (None, None, error_response)
- """
- # 导入已有的函数,避免重复代码
- from .viewing_analytics import get_available_years
-
- # 获取可用年份列表
- available_years = get_available_years()
- if not available_years:
- error_response = {
- "status": "error",
- "message": "未找到任何历史记录数据"
- }
- return None, None, error_response
-
- # 如果未指定年份,使用最新的年份;如果指定年份不存在,则自动回退到最新可用年份
- if year is None:
- target_year = available_years[0]
- elif year in available_years:
- target_year = year
- else:
- target_year = available_years[0]
-
- table_name = f"bilibili_history_{target_year}"
- return table_name, target_year, available_years
-
-@router.get("/keyword-analysis", summary="获取标题关键词分析")
-async def get_keyword_analysis(
- year: Optional[int] = Query(None, description="要分析的年份,不传则使用当前年份"),
- use_cache: bool = Query(True, description="是否使用缓存,默认为True。如果为False则重新分析数据")
-):
- """获取标题关键词分析数据
-
- Args:
- year: 要分析的年份,不传则使用当前年份
- use_cache: 是否使用缓存,默认为True。如果为False则重新分析数据
-
- Returns:
- dict: 包含关键词分析的数据
- """
- # 验证年份并获取表名
- table_name, target_year, available_years = validate_year_and_get_table(year)
- if table_name is None:
- return available_years # 这里是错误响应
-
- conn = get_db()
- try:
- cursor = conn.cursor()
-
- # 如果启用缓存,尝试从缓存获取
- if use_cache:
- from .title_pattern_discovery import pattern_cache
- cached_response = pattern_cache.get_cached_patterns(table_name, 'keyword_analysis')
- if cached_response:
- print(f"从缓存获取 {target_year} 年的关键词分析数据")
- return cached_response
-
- print(f"开始分析 {target_year} 年的标题关键词数据")
-
- # 获取所有标题数据
- cursor.execute(f"""
- SELECT title, duration, progress
- FROM {table_name}
- WHERE title IS NOT NULL AND title != ''
- """)
-
- titles_data = cursor.fetchall()
-
- if not titles_data:
- return {
- "status": "error",
- "message": "未找到任何有效的标题数据"
- }
-
- # 分词和关键词提取
- keywords = analyze_keywords(titles_data)
-
- # 分析完成率
- completion_analysis = analyze_completion_rates(titles_data)
-
- # 生成洞察
- insights = generate_insights(keywords, completion_analysis)
-
- # 构建响应
- response = {
- "status": "success",
- "data": {
- "keyword_analysis": {
- "top_keywords": [{"word": word, "count": count} for word, count in keywords],
- "completion_rates": completion_analysis
- },
- "insights": insights,
- "year": target_year,
- "available_years": available_years
- }
- }
-
- # 更新缓存
- from .title_pattern_discovery import pattern_cache
- print(f"更新 {target_year} 年的关键词分析数据缓存")
- pattern_cache.cache_patterns(table_name, 'keyword_analysis', response)
-
- return response
-
- except Exception as e:
- raise HTTPException(status_code=500, detail=str(e))
- finally:
- if conn:
- conn.close()
-
-@router.get("/length-analysis", summary="获取标题长度分析")
-async def get_length_analysis(
- year: Optional[int] = Query(None, description="要分析的年份,不传则使用当前年份"),
- use_cache: bool = Query(True, description="是否使用缓存,默认为True。如果为False则重新分析数据")
-):
- """获取标题长度分析数据
-
- Args:
- year: 要分析的年份,不传则使用当前年份
- use_cache: 是否使用缓存,默认为True。如果为False则重新分析数据
-
- Returns:
- dict: 包含标题长度分析的数据
- """
- # 验证年份并获取表名
- table_name, target_year, available_years = validate_year_and_get_table(year)
- if table_name is None:
- return available_years # 这里是错误响应
-
- conn = get_db()
- try:
- cursor = conn.cursor()
-
- # 如果启用缓存,尝试从缓存获取
- if use_cache:
- from .title_pattern_discovery import pattern_cache
- cached_response = pattern_cache.get_cached_patterns(table_name, 'length_analysis')
- if cached_response:
- print(f"从缓存获取 {target_year} 年的标题长度分析数据")
- return cached_response
-
- print(f"开始分析 {target_year} 年的标题长度数据")
-
- # 获取标题长度分析
- length_analysis = analyze_title_length(cursor, table_name)
-
- # 构建响应
- response = {
- "status": "success",
- "data": {
- "length_analysis": length_analysis,
- "year": target_year,
- "available_years": available_years
- }
- }
-
- # 更新缓存
- from .title_pattern_discovery import pattern_cache
- print(f"更新 {target_year} 年的标题长度分析数据缓存")
- pattern_cache.cache_patterns(table_name, 'length_analysis', response)
-
- return response
-
- except Exception as e:
- raise HTTPException(status_code=500, detail=str(e))
- finally:
- if conn:
- conn.close()
-
-@router.get("/sentiment-analysis", summary="获取标题情感分析")
-async def get_sentiment_analysis(
- year: Optional[int] = Query(None, description="要分析的年份,不传则使用当前年份"),
- use_cache: bool = Query(True, description="是否使用缓存,默认为True。如果为False则重新分析数据")
-):
- """获取标题情感分析数据
-
- Args:
- year: 要分析的年份,不传则使用当前年份
- use_cache: 是否使用缓存,默认为True。如果为False则重新分析数据
-
- Returns:
- dict: 包含标题情感分析的数据
- """
- # 验证年份并获取表名
- table_name, target_year, available_years = validate_year_and_get_table(year)
- if table_name is None:
- return available_years # 这里是错误响应
-
- conn = get_db()
- try:
- cursor = conn.cursor()
-
- # 如果启用缓存,尝试从缓存获取
- if use_cache:
- from .title_pattern_discovery import pattern_cache
- cached_response = pattern_cache.get_cached_patterns(table_name, 'sentiment_analysis')
- if cached_response:
- print(f"从缓存获取 {target_year} 年的标题情感分析数据")
- return cached_response
-
- print(f"开始分析 {target_year} 年的标题情感数据")
-
- # 获取标题情感分析
- sentiment_analysis = analyze_title_sentiment(cursor, table_name)
-
- # 构建响应
- response = {
- "status": "success",
- "data": {
- "sentiment_analysis": sentiment_analysis,
- "year": target_year,
- "available_years": available_years
- }
- }
-
- # 更新缓存
- from .title_pattern_discovery import pattern_cache
- print(f"更新 {target_year} 年的标题情感分析数据缓存")
- pattern_cache.cache_patterns(table_name, 'sentiment_analysis', response)
-
- return response
-
- except Exception as e:
- raise HTTPException(status_code=500, detail=str(e))
- finally:
- if conn:
- conn.close()
-
-@router.get("/trend-analysis", summary="获取标题趋势分析")
-async def get_trend_analysis(
- year: Optional[int] = Query(None, description="要分析的年份,不传则使用当前年份"),
- use_cache: bool = Query(True, description="是否使用缓存,默认为True。如果为False则重新分析数据")
-):
- """获取标题趋势分析数据
-
- Args:
- year: 要分析的年份,不传则使用当前年份
- use_cache: 是否使用缓存,默认为True。如果为False则重新分析数据
-
- Returns:
- dict: 包含标题趋势分析的数据
- """
- # 验证年份并获取表名
- table_name, target_year, available_years = validate_year_and_get_table(year)
- if table_name is None:
- return available_years # 这里是错误响应
-
- conn = get_db()
- try:
- cursor = conn.cursor()
-
- # 如果启用缓存,尝试从缓存获取
- if use_cache:
- from .title_pattern_discovery import pattern_cache
- cached_response = pattern_cache.get_cached_patterns(table_name, 'trend_analysis')
- if cached_response:
- print(f"从缓存获取 {target_year} 年的标题趋势分析数据")
- return cached_response
-
- print(f"开始分析 {target_year} 年的标题趋势数据")
-
- # 获取标题趋势分析
- trend_analysis = analyze_title_trends(cursor, table_name)
-
- # 构建响应
- response = {
- "status": "success",
- "data": {
- "trend_analysis": trend_analysis,
- "year": target_year,
- "available_years": available_years
- }
- }
-
- # 更新缓存
- from .title_pattern_discovery import pattern_cache
- print(f"更新 {target_year} 年的标题趋势分析数据缓存")
- pattern_cache.cache_patterns(table_name, 'trend_analysis', response)
-
- return response
-
- except Exception as e:
- raise HTTPException(status_code=500, detail=str(e))
- finally:
- if conn:
- conn.close()
-
-@router.get("/interaction-analysis", summary="获取标题互动分析")
-async def get_interaction_analysis(
- year: Optional[int] = Query(None, description="要分析的年份,不传则使用当前年份"),
- use_cache: bool = Query(True, description="是否使用缓存,默认为True。如果为False则重新分析数据")
-):
- """获取标题互动分析数据
-
- Args:
- year: 要分析的年份,不传则使用当前年份
- use_cache: 是否使用缓存,默认为True。如果为False则重新分析数据
-
- Returns:
- dict: 包含标题互动分析的数据
- """
- # 验证年份并获取表名
- table_name, target_year, available_years = validate_year_and_get_table(year)
- if table_name is None:
- return available_years # 这里是错误响应
-
- conn = get_db()
- try:
- cursor = conn.cursor()
-
- # 如果启用缓存,尝试从缓存获取
- if use_cache:
- from .title_pattern_discovery import pattern_cache
- cached_response = pattern_cache.get_cached_patterns(table_name, 'interaction_analysis')
- if cached_response:
- print(f"从缓存获取 {target_year} 年的标题互动分析数据")
- return cached_response
-
- print(f"开始分析 {target_year} 年的标题互动数据")
-
- # 获取标题互动分析
- interaction_analysis = analyze_title_interaction(cursor, table_name)
-
- # 构建响应
- response = {
- "status": "success",
- "data": {
- "interaction_analysis": interaction_analysis,
- "year": target_year,
- "available_years": available_years
- }
- }
-
- # 更新缓存
- from .title_pattern_discovery import pattern_cache
- print(f"更新 {target_year} 年的标题互动分析数据缓存")
- pattern_cache.cache_patterns(table_name, 'interaction_analysis', response)
-
- return response
-
- except Exception as e:
- raise HTTPException(status_code=500, detail=str(e))
- finally:
- if conn:
- conn.close()
diff --git a/routers/title_pattern_discovery.py b/routers/title_pattern_discovery.py
deleted file mode 100644
index bffb8f5..0000000
--- a/routers/title_pattern_discovery.py
+++ /dev/null
@@ -1,724 +0,0 @@
-import json
-import os
-import sqlite3
-from collections import Counter, defaultdict
-from typing import List, Dict, Tuple, Set, Optional
-
-import jieba
-import numpy as np
-from sklearn.cluster import KMeans
-from sklearn.feature_extraction.text import TfidfVectorizer
-from snownlp import SnowNLP
-
-
-class PatternCache:
- """模式缓存管理器"""
- def __init__(self, cache_dir: str = None):
- if cache_dir is None:
- # 使用项目根目录下的cache文件夹
- import sys
- import os
- project_root = os.path.dirname(os.path.dirname(os.path.abspath(__file__)))
- self.cache_dir = os.path.join(project_root, "cache")
- else:
- self.cache_dir = cache_dir
-
- # 确保缓存目录存在并设置正确的权限
- try:
- print(f"尝试创建缓存目录: {self.cache_dir}")
-
- # 如果目录不存在,创建它
- if not os.path.exists(self.cache_dir):
- os.makedirs(self.cache_dir, mode=0o755, exist_ok=True)
- print(f"缓存目录已创建: {self.cache_dir}")
-
- # 确保目录权限正确
- os.chmod(self.cache_dir, 0o755)
- print(f"缓存目录权限已设置为755")
-
- # 根据操作系统获取用户信息
- if sys.platform != 'win32':
- import pwd
- import grp
- current_user = pwd.getpwuid(os.getuid()).pw_name
- current_group = grp.getgrgid(os.getgid()).gr_name
- print(f"当前用户: {current_user}")
- print(f"当前用户组: {current_group}")
- else:
- current_user = os.getlogin() if hasattr(os, 'getlogin') else 'unknown'
- print(f"当前用户: {current_user}")
-
- # 检查目录权限
- mode = oct(os.stat(self.cache_dir).st_mode)[-3:]
- print(f"缓存目录权限: {mode}")
-
- # 尝试创建测试文件以验证写入权限
- test_file = os.path.join(self.cache_dir, "test.txt")
- try:
- with open(test_file, 'w') as f:
- f.write("test")
- os.remove(test_file)
- print("缓存目录写入权限验证成功")
- except Exception as e:
- print(f"缓存目录写入权限验证失败: {str(e)}")
- print(f"错误类型: {type(e).__name__}")
- print(f"错误详情: {str(e)}")
-
- except Exception as e:
- print(f"创建缓存目录时出错: {str(e)}")
- print(f"错误类型: {type(e).__name__}")
- print(f"错误详情: {str(e)}")
- # 如果是权限问题,打印更多信息
- if isinstance(e, PermissionError):
- print(f"当前用户: {os.getlogin() if hasattr(os, 'getlogin') else 'unknown'}")
- print(f"当前工作目录: {os.getcwd()}")
- print(f"目录是否存在: {os.path.exists(self.cache_dir)}")
- if os.path.exists(self.cache_dir):
- print(f"目录权限: {oct(os.stat(self.cache_dir).st_mode)[-3:]}")
-
- def _get_cache_path(self, table_name: str, pattern_type: str) -> str:
- """获取缓存文件路径"""
- cache_file = f"{table_name}_{pattern_type}_patterns.json"
- cache_path = os.path.join(self.cache_dir, cache_file)
- print(f"缓存文件路径: {cache_path}")
- return cache_path
-
- def get_cached_patterns(self, table_name: str, pattern_type: str) -> Optional[Dict]:
- """
- 获取缓存的模式数据
-
- Args:
- table_name: 数据表名
- pattern_type: 模式类型('title' 或 'interaction')
-
- Returns:
- Dict | None: 缓存的模式数据,如果缓存不存在则返回None
- """
- try:
- cache_path = self._get_cache_path(table_name, pattern_type)
- if not os.path.exists(cache_path):
- print(f"缓存文件不存在: {cache_path}")
- return None
-
- print(f"读取缓存文件: {cache_path}")
- with open(cache_path, 'r', encoding='utf-8') as f:
- data = json.load(f)
- print(f"成功读取缓存数据,包含 {len(data)} 个模式")
- return data
-
- except Exception as e:
- print(f"读取缓存时出错: {str(e)}")
- print(f"错误类型: {type(e).__name__}")
- print(f"错误详情: {str(e)}")
- return None
-
- def cache_patterns(self, table_name: str, pattern_type: str, patterns: Dict) -> None:
- """
- 缓存模式数据
-
- Args:
- table_name: 数据表名
- pattern_type: 模式类型('title' 或 'interaction')
- patterns: 要缓存的模式数据
- """
- try:
- if not patterns:
- print("没有模式数据需要缓存")
- return
-
- cache_path = self._get_cache_path(table_name, pattern_type)
- print(f"准备写入缓存: {cache_path}")
- print(f"缓存数据包含 {len(patterns)} 个模式")
-
- # 确保目录存在
- os.makedirs(os.path.dirname(cache_path), exist_ok=True)
-
- with open(cache_path, 'w', encoding='utf-8') as f:
- json.dump(patterns, f, ensure_ascii=False, indent=2)
- print(f"成功写入缓存: {cache_path}")
-
- except Exception as e:
- print(f"写入缓存时出错: {str(e)}")
- print(f"错误类型: {type(e).__name__}")
- print(f"错误详情: {str(e)}")
- # 如果是权限问题,打印更多信息
- if isinstance(e, PermissionError):
- print(f"缓存目录权限: {oct(os.stat(self.cache_dir).st_mode)[-3:]}")
- print(f"当前用户: {os.getlogin()}")
- print(f"当前工作目录: {os.getcwd()}")
- print(f"目录是否存在: {os.path.exists(self.cache_dir)}")
- if os.path.exists(self.cache_dir):
- print(f"目录权限: {oct(os.stat(self.cache_dir).st_mode)[-3:]}")
-
-# 创建全局缓存管理器实例
-pattern_cache = PatternCache()
-
-def get_stop_words() -> Set[str]:
- """获取停用词列表"""
- return {
- '的', '了', '是', '在', '我', '有', '和', '就', '不', '人', '都', '一', '一个', '上', '也', '很',
- '到', '说', '要', '去', '你', '会', '着', '没有', '看', '好', '自己', '这', '那', '啊', '呢', '吧',
- '吗', '啦', '呀', '哦', '哈', '嘿', '哎', '哟', '唉', '嗯', '嘛', '哼', '哇', '咦', '诶', '喂',
- '么', '什么', '这个', '那个', '这样', '那样', '怎么', '为什么', '如何', '哪里', '谁', '什么时候',
- '多少', '几', '怎样', '为何', '哪个', '哪些', '几个', '多久', '多长时间', '什么样'
- }
-
-def collect_title_data(cursor: sqlite3.Cursor, table_name: str) -> List[Tuple[str, float, float, str, int]]:
- """
- 从数据库收集标题数据
-
- Args:
- cursor: 数据库游标
- table_name: 表名
-
- Returns:
- List[Tuple]: 包含(title, duration, progress, tag_name, view_at)的元组列表
- """
- cursor.execute(f"""
- SELECT title, duration, progress, tag_name, view_at
- FROM {table_name}
- WHERE title IS NOT NULL AND title != ''
- """)
- return cursor.fetchall()
-
-def preprocess_titles(titles_data: List[Tuple[str, float, float, str, int]]) -> List[str]:
- """
- 预处理标题文本
-
- Args:
- titles_data: 原始标题数据
-
- Returns:
- List[str]: 预处理后的标题列表
- """
- stop_words = get_stop_words()
- processed_titles = []
-
- for title_data in titles_data:
- title = title_data[0]
- # 分词
- words = jieba.cut(title)
- # 过滤停用词和单字词
- filtered_words = [w for w in words if w not in stop_words and len(w) > 1]
- # 重新组合成句子
- processed_title = ' '.join(filtered_words)
- processed_titles.append(processed_title)
-
- return processed_titles
-
-def extract_title_features(processed_titles: List[str], n_features: int = 1000) -> Tuple[TfidfVectorizer, np.ndarray]:
- """
- 提取标题特征
-
- Args:
- processed_titles: 预处理后的标题列表
- n_features: 特征数量
-
- Returns:
- Tuple: (TF-IDF向量器, 特征矩阵)
- """
- vectorizer = TfidfVectorizer(max_features=n_features)
- features = vectorizer.fit_transform(processed_titles)
- return vectorizer, features
-
-def validate_patterns(titles_data: List[Tuple[str, float, float, str, int]], patterns: Dict) -> Dict:
- """
- 验证和优化发现的模式
-
- Args:
- titles_data: 原始标题数据
- patterns: 发现的模式字典
-
- Returns:
- Dict: 优化后的模式字典
- """
- print(f"开始验证模式,标题数量: {len(titles_data)}, 模式数量: {len(patterns)}")
- # 计算每个模式的覆盖率和区分度
- pattern_metrics = {}
- total_titles = len(titles_data)
- if total_titles == 0: # 如果没有标题数据,直接返回原始模式
- return {name: {**info, 'metrics': {
- 'coverage': 0,
- 'distinctiveness': 0,
- 'unique_matches': 0,
- 'shared_matches': 0
- }} for name, info in patterns.items()}
-
- titles = [t[0] for t in titles_data] # 提取标题文本
-
- # 计算每个模式的覆盖率和区分度
- for pattern_name, pattern_info in patterns.items():
- # 计算该模式覆盖的标题数量
- covered_titles = sum(1 for title in titles
- if any(keyword in title for keyword in pattern_info['keywords']))
-
- # 计算覆盖率
- coverage = covered_titles / total_titles
-
- # 计算区分度(独特性)
- unique_coverage = 0
- shared_coverage = 0
- for title in titles:
- # 检查当前模式是否匹配
- current_matches = any(keyword in title for keyword in pattern_info['keywords'])
- if current_matches:
- # 检查其他模式是否也匹配
- other_matches = sum(1 for other_name, other_info in patterns.items()
- if other_name != pattern_name and
- any(keyword in title for keyword in other_info['keywords']))
- if other_matches == 0:
- unique_coverage += 1
- else:
- shared_coverage += 1
-
- # 计算区分度,避免除零错误
- total_matches = unique_coverage + shared_coverage
- distinctiveness = unique_coverage / total_matches if total_matches > 0 else 0
-
- pattern_metrics[pattern_name] = {
- 'coverage': coverage,
- 'distinctiveness': distinctiveness,
- 'unique_matches': unique_coverage,
- 'shared_matches': shared_coverage
- }
-
- # 优化模式
- optimized_patterns = {}
- for pattern_name, pattern_info in patterns.items():
- metrics = pattern_metrics[pattern_name]
-
- # 如果模式的覆盖率太低或区分度太低,尝试优化
- if metrics['coverage'] < 0.05 or metrics['distinctiveness'] < 0.3:
- # 获取该模式下的所有标题
- pattern_titles = [title for title in titles
- if any(keyword in title for keyword in pattern_info['keywords'])]
-
- # 重新提取关键词,使用更严格的TF-IDF阈值
- if pattern_titles:
- try:
- vectorizer = TfidfVectorizer(max_features=5) # 减少关键词数量,提高精确性
- features = vectorizer.fit_transform(pattern_titles)
- keywords = vectorizer.get_feature_names_out()
-
- # 更新模式信息
- optimized_patterns[pattern_name] = {
- 'keywords': list(keywords),
- 'sentiment': pattern_info['sentiment'],
- 'sample_size': len(pattern_titles),
- 'metrics': metrics
- }
- except Exception:
- # 如果TF-IDF提取失败,保持原有关键词
- optimized_patterns[pattern_name] = {
- **pattern_info,
- 'metrics': metrics
- }
- else:
- # 如果没有匹配的标题,保持原有模式
- optimized_patterns[pattern_name] = {
- **pattern_info,
- 'metrics': metrics
- }
- else:
- # 保持原有模式,只添加指标信息
- optimized_patterns[pattern_name] = {
- **pattern_info,
- 'metrics': metrics
- }
-
- return optimized_patterns
-
-def discover_title_patterns(titles_data: List[Tuple[str, float, float, str, int]], n_clusters: int = 5) -> Dict:
- """
- 发现标题模式
-
- Args:
- titles_data: 原始标题数据
- n_clusters: 聚类数量
-
- Returns:
- Dict: 发现的模式及其关键词
- """
- # 数据验证
- if not titles_data:
- return {
- 'default': {
- 'keywords': [],
- 'sentiment': 0.5,
- 'sample_size': 0,
- 'metrics': {
- 'coverage': 0,
- 'distinctiveness': 0,
- 'unique_matches': 0,
- 'shared_matches': 0
- }
- }
- }
-
- # 预处理标题
- processed_titles = preprocess_titles(titles_data)
- if not processed_titles: # 如果预处理后没有有效标题
- return {
- 'default': {
- 'keywords': [],
- 'sentiment': 0.5,
- 'sample_size': 0,
- 'metrics': {
- 'coverage': 0,
- 'distinctiveness': 0,
- 'unique_matches': 0,
- 'shared_matches': 0
- }
- }
- }
-
- # 调整聚类数量,确保不超过标题数量
- actual_n_clusters = min(n_clusters, len(processed_titles))
- if actual_n_clusters < 2: # 如果数据太少,不进行聚类
- # 直接使用TF-IDF提取关键词
- try:
- vectorizer = TfidfVectorizer(max_features=10)
- features = vectorizer.fit_transform(processed_titles)
- keywords = list(vectorizer.get_feature_names_out())
-
- # 计算情感倾向
- sentiments = [SnowNLP(title).sentiments for title in processed_titles]
- avg_sentiment = float(np.mean(sentiments))
-
- patterns = {
- '默认模式': {
- 'keywords': keywords,
- 'sentiment': avg_sentiment,
- 'sample_size': len(processed_titles)
- }
- }
-
- # 验证和优化模式
- optimized_patterns = validate_patterns(titles_data, patterns)
- return optimized_patterns
-
- except Exception as e:
- print(f"Error in TF-IDF processing: {str(e)}")
- return {
- 'default': {
- 'keywords': [],
- 'sentiment': 0.5,
- 'sample_size': 0,
- 'metrics': {
- 'coverage': 0,
- 'distinctiveness': 0,
- 'unique_matches': 0,
- 'shared_matches': 0
- }
- }
- }
-
- try:
- # 提取特征
- vectorizer, features = extract_title_features(processed_titles)
-
- # 聚类
- kmeans = KMeans(n_clusters=actual_n_clusters, random_state=42)
- clusters = kmeans.fit_predict(features)
-
- # 分析每个聚类的特征词
- patterns = {}
- for i in range(actual_n_clusters):
- # 获取该聚类的标题索引
- cluster_indices = np.where(clusters == i)[0]
- if len(cluster_indices) == 0: # 如果聚类为空,跳过
- continue
-
- cluster_titles = [processed_titles[idx] for idx in cluster_indices]
-
- try:
- # 为该聚类创建新的TF-IDF向量器
- cluster_vectorizer = TfidfVectorizer(max_features=10)
- cluster_features = cluster_vectorizer.fit_transform(cluster_titles)
-
- # 获取特征词
- feature_names = cluster_vectorizer.get_feature_names_out()
-
- # 计算该聚类的主要情感倾向
- sentiments = [SnowNLP(title).sentiments for title in cluster_titles]
- avg_sentiment = float(np.mean(sentiments))
-
- # 根据情感和关键词确定模式名称
- if avg_sentiment > 0.6:
- pattern_type = '积极'
- elif avg_sentiment < 0.4:
- pattern_type = '消极'
- else:
- pattern_type = '中性'
-
- # 存储模式信息
- patterns[f'模式{i+1}_{pattern_type}'] = {
- 'keywords': list(feature_names),
- 'sentiment': avg_sentiment,
- 'sample_size': len(cluster_titles)
- }
- except Exception as e:
- print(f"Error processing cluster {i}: {str(e)}")
- continue
-
- # 如果没有成功创建任何模式,返回默认模式
- if not patterns:
- return {
- 'default': {
- 'keywords': [],
- 'sentiment': 0.5,
- 'sample_size': 0,
- 'metrics': {
- 'coverage': 0,
- 'distinctiveness': 0,
- 'unique_matches': 0,
- 'shared_matches': 0
- }
- }
- }
-
- # 验证和优化模式
- optimized_patterns = validate_patterns(titles_data, patterns)
- return optimized_patterns
-
- except Exception as e:
- print(f"Error in pattern discovery: {str(e)}")
- return {
- 'default': {
- 'keywords': [],
- 'sentiment': 0.5,
- 'sample_size': 0,
- 'metrics': {
- 'coverage': 0,
- 'distinctiveness': 0,
- 'unique_matches': 0,
- 'shared_matches': 0
- }
- }
- }
-
-def discover_interaction_patterns(titles_data: List[Tuple[str, float, float, str, int]]) -> Dict:
- """
- 发现互动模式
-
- Args:
- titles_data: 原始标题数据
-
- Returns:
- Dict: 发现的互动模式及其关键词
- """
- try:
- # 数据验证
- if not titles_data:
- return {
- 'default': {
- 'keywords': [],
- 'sample_size': 0,
- 'metrics': {
- 'coverage': 0,
- 'distinctiveness': 0,
- 'unique_matches': 0,
- 'shared_matches': 0
- }
- }
- }
-
- # 预处理标题
- processed_titles = preprocess_titles(titles_data)
- if not processed_titles: # 如果预处理后没有有效标题
- return {
- 'default': {
- 'keywords': [],
- 'sample_size': 0,
- 'metrics': {
- 'coverage': 0,
- 'distinctiveness': 0,
- 'unique_matches': 0,
- 'shared_matches': 0
- }
- }
- }
-
- # 定义基本的语言模式特征
- question_markers = {
- # 基础疑问词
- '?', '?', '吗', '呢', '么', '嘛', '吧',
- # 特定疑问词
- '什么', '为什么', '如何', '怎么', '怎样', '几时', '哪里', '谁', '多少',
- '哪个', '哪些', '几个', '多久', '怎么办', '怎么样', '为何', '是不是',
- # 疑问词组
- '难道说', '究竟是', '到底是', '是否', '能否', '可否', '何必', '何不',
- '为何要', '怎么会', '怎么能', '如何才能', '为什么会', '是不是要',
- # 反问词组
- '岂不是', '难道不', '怎能不', '何尝不', '谁不',
- # 网络流行疑问
- '啥玩意', '啥情况', '咋回事', '咋办', '咋整', '啥意思',
- '这是啥', '这是什么', '这啥啊', '这怎么回事',
- '这合理吗', '这能行吗', '这靠谱吗', '这玩意儿',
- '搞啥呢', '闹哪样', '整啥活', '整这出'
- }
-
- exclamation_markers = {
- # 基础感叹词
- '!', '!', '啊', '哇', '哦', '呀', '呐', '哎', '诶', '咦',
- # 程度词
- '太', '真', '好', '非常', '超级', '特别', '极其', '格外', '分外',
- '相当', '十分', '很是', '尤其', '特', '超', '贼', '巨',
- # 感叹词组
- '太棒了', '真棒', '好厉害', '太强了', '太牛了', '太秀了', '绝了',
- '震惊', '惊呆了', '厉害了', '牛逼', '卧槽', '我的天', '天呐',
- '要命', '要死了', '受不了', '没谁了', '绝绝子', '太可了', '太爱了',
- # 正面评价
- '完美', '神级', '顶级', '极品', '优秀', '精彩', '精品', '经典',
- '必看', '值得', '推荐', '珍藏', '收藏', '赞', '好评',
- # 负面感叹
- '可怕', '恐怖', '吓人', '要命', '糟糕', '完蛋', '惨', '惨了',
- '可恶', '气死', '无语', '离谱', '扯淡', '要疯了',
- # B站特色感叹
- '草', '蚌埠住了', '绷不住了', '崩溃', '破防了', '麻了', '顶不住了',
- '笑死', '笑yue了', '笑死我了', '乐死我了', '乐', '孝死',
- '爷青回', '爷青结', '爷哭了', '泪目', '呜呜呜', '呜呜',
- '啊这', '这河里吗', '这不河里', '这不对劲', '这不科学',
- # 2023-2024热梗
- '鼠鼠我啊', '答应我', '不要再', '给我狠狠', '给我使劲',
- '啊对对对', '好似', '开香槟咯', '大胆', '荒谬',
- '我说不要', '我说要要要', '不认识', '很会', '很懂',
- '不懂就问', '求求了', '人生建议', '建议', '速速',
- '狠狠', '使劲', '疯狂', '大声', '大胆',
- # 2024新梗
- '纯纯', '典典', '润润', '狂狂', '疯疯',
- '笑死个人', '急急国王', '急急子', '急了急了',
- '慌慌子', '慌了慌了', '酸酸子', '酸了酸了',
- '急了蚌', '笑死蚌', '破防蚌', '麻了蚌',
- # 网络流行语
- '太上头了', '上头', '太香了', '香疯了', '太戳了', '戳爆了',
- '太欧了', '太非了', '太悲伤了', '太难了', '太难蚌了',
- '太难绷了', '太离谱了', '太荒谬了', '太逆天了', '太致命了',
- '太邪门了', '太魔幻了', '太真实了', '太炸裂了', '太生草了',
- # 新增流行语
- '真的会谢', '真的会哭', '真的会笑', '真的会玩',
- '狠狠地心动', '狠狠地心疼', '狠狠地感动', '狠狠地共情',
- '生死时速', '生死时刻', '生死时分', '生死关头',
- '一整个', '一整个爱了', '一整个哭了', '一整个笑了',
- # 夸张表达
- '吊炸天', '厉害炸了', '牛炸了', '强炸了', '秀炸了',
- '猛炸了', '狠炸了', '吓死人', '笑死人', '气死人',
- '玩明白了', '玩懂了', '玩透了', '整明白了', '整懂了',
- '整透了', '搞明白了', '搞懂了', '搞透了'
- }
-
- dialogue_markers = {
- # 基础对话词
- '来', '一起', '让我们', '跟着', '教你', '告诉你',
- # 邀请词组
- '带你', '陪你', '和你', '跟你', '请你', '邀请你',
- '一块儿', '一块', '一同', '共同', '大家', '咱们',
- # 引导词组
- '看看', '来看', '快看', '瞧瞧', '听听', '试试',
- '学习', '了解', '探索', '发现', '感受', '体验',
- # 分享词组
- '分享', '推荐', '介绍', '安利', '种草', '测评',
- '解说', '讲解', '教程', '攻略', '指南', '技巧',
- # 互动词组
- '互动', '交流', '讨论', '聊聊', '说说', '谈谈',
- '评论', '留言', '关注', '订阅', '点赞', '转发',
- # B站特色互动
- '三连', '一键三连', '点个三连', '求三连', '给个三连',
- '投币', '充电', '收藏', '关注', '催更', '别走',
- '别急', '慢慢看', '细细品', '仔细看', '往后看',
- # 2023-2024新增互动
- '速来', '速看', '速冲', '速进', '速食',
- '必看合集', '珍藏合集', '收藏合集', '经典合集',
- '建议收藏', '建议点赞', '建议三连', '建议关注',
- '记得一键三连', '记得关注', '记得收藏', '记得转发',
- '务必三连', '务必收藏', '务必关注', '务必转发',
- # 网络流行互动
- '整活', '搞起来', '安排上', '冲冲冲', '搞快点',
- '安排', '奥利给', '搞起', '整起来', '冲它',
- '搞这个', '整这个', '来这个', '整一个', '搞一个',
- # 口语化表达
- '咱整个', '咱搞个', '咱来个', '给你整个', '给你搞个',
- '跟你说个', '给你说个', '告诉你个', '说个事', '整点刺激的',
- '搞点刺激的', '来点刺激的', '整点意思', '搞点意思',
- # 新增口语化
- '给大家整个', '给大家搞个', '给大家来个',
- '给你们整个', '给你们搞个', '给你们来个',
- '速速来个', '速速整个', '速速搞个',
- # 亲切称呼
- '老铁', '兄弟', '姐妹', '小伙伴', '小可爱', '小宝贝',
- '宝', '亲', '朋友', '兄弟姐妹', '铁子', '老哥',
- '老姐', '老弟', '老妹', '小老弟', '小老妹',
- # 新增称呼
- '宝贝们', '亲们', '朋友们', '兄弟们', '姐妹们',
- '小伙伴们', '铁子们', '老铁们', '粉丝们', '观众们'
- }
-
- # 统计各种模式的出现
- pattern_stats = defaultdict(lambda: {'titles': [], 'keywords': Counter()})
-
- for title, processed_title in zip([t[0] for t in titles_data], processed_titles):
- words = processed_title.split()
-
- try:
- # 检测问句模式
- if any(marker in title for marker in question_markers):
- pattern_stats['疑问式']['titles'].append(title)
- pattern_stats['疑问式']['keywords'].update(words)
-
- # 检测感叹句模式
- if any(marker in title for marker in exclamation_markers):
- pattern_stats['感叹式']['titles'].append(title)
- pattern_stats['感叹式']['keywords'].update(words)
-
- # 检测对话式模式
- if any(marker in title for marker in dialogue_markers):
- pattern_stats['对话式']['titles'].append(title)
- pattern_stats['对话式']['keywords'].update(words)
- except Exception as e:
- print(f"Error processing title: {str(e)}")
- continue
-
- # 处理统计结果
- interaction_patterns = {}
- for pattern_name, stats in pattern_stats.items():
- if stats['titles']: # 如果有匹配的标题
- try:
- interaction_patterns[pattern_name] = {
- 'keywords': [word for word, _ in stats['keywords'].most_common(10)],
- 'sample_size': len(stats['titles'])
- }
- except Exception as e:
- print(f"Error processing pattern {pattern_name}: {str(e)}")
- continue
-
- # 如果没有发现任何模式,返回默认模式
- if not interaction_patterns:
- interaction_patterns = {
- 'default': {
- 'keywords': [],
- 'sample_size': 0,
- 'metrics': {
- 'coverage': 0,
- 'distinctiveness': 0,
- 'unique_matches': 0,
- 'shared_matches': 0
- }
- }
- }
-
- return interaction_patterns
-
- except Exception as e:
- print(f"Error in interaction pattern discovery: {str(e)}")
- return {
- 'default': {
- 'keywords': [],
- 'sample_size': 0,
- 'metrics': {
- 'coverage': 0,
- 'distinctiveness': 0,
- 'unique_matches': 0,
- 'shared_matches': 0
- }
- }
- }
\ No newline at end of file
diff --git a/routers/video_details.py b/routers/video_details.py
deleted file mode 100644
index 2b177a5..0000000
--- a/routers/video_details.py
+++ /dev/null
@@ -1,2058 +0,0 @@
-import asyncio
-import concurrent.futures
-import json
-import os
-import random
-import sqlite3
-import time
-from typing import Dict, Any, Optional, List
-
-import httpx
-from fastapi import APIRouter, HTTPException, Query, BackgroundTasks
-from fastapi.responses import StreamingResponse
-from loguru import logger
-
-from scripts.utils import load_config, get_output_path
-from scripts.bilibili_history import check_invalid_video, save_invalid_video, create_invalid_videos_table
-
-router = APIRouter(tags=["视频详情"])
-
-# 数据库路径
-DB_PATH = os.path.join("output", "database", "bilibili_video_details.db")
-
-# 全局进度状态
-video_details_progress = {
- "is_processing": False,
- "is_complete": False,
- "is_stopped": False, # 新增:是否被用户停止
- "total_videos": 0,
- "processed_videos": 0,
- "success_count": 0,
- "failed_count": 0,
- "error_videos": [],
- "skipped_invalid_count": 0,
- "start_time": 0,
- "last_update_time": 0
-}
-
-# 确保数据库目录存在
-os.makedirs(os.path.join("output", "database"), exist_ok=True)
-
-def _build_video_original_url(video: Dict[str, Any]) -> str:
- """根据视频详情字段构建可打开的B站视频链接"""
- bvid = (video.get("bvid") or "").strip()
- if not bvid:
- return ""
- return f"https://www.bilibili.com/video/{bvid}"
-
-
-def init_db() -> None:
- """初始化数据库"""
- with sqlite3.connect(DB_PATH) as conn:
- cursor = conn.cursor()
-
- # 视频基本信息表
- cursor.execute("""
- CREATE TABLE IF NOT EXISTS video_base_info (
- id INTEGER PRIMARY KEY,
- bvid TEXT NOT NULL UNIQUE,
- aid INTEGER NOT NULL,
- videos INTEGER DEFAULT 1,
- tid INTEGER,
- tid_v2 INTEGER,
- tname TEXT,
- tname_v2 TEXT,
- copyright INTEGER,
- pic TEXT,
- title TEXT NOT NULL,
- pubdate INTEGER,
- ctime INTEGER,
- desc TEXT,
- desc_v2 TEXT,
- state INTEGER DEFAULT 0,
- duration INTEGER,
- mission_id INTEGER,
- dynamic TEXT,
- cid INTEGER,
- season_id INTEGER,
- premiere INTEGER,
- teenage_mode INTEGER DEFAULT 0,
- is_chargeable_season INTEGER DEFAULT 0,
- is_story INTEGER DEFAULT 0,
- is_upower_exclusive INTEGER DEFAULT 0,
- is_upower_play INTEGER DEFAULT 0,
- is_upower_preview INTEGER DEFAULT 0,
- is_upower_exclusive_with_qa INTEGER DEFAULT 0,
- no_cache INTEGER DEFAULT 0,
- is_season_display INTEGER DEFAULT 0,
- like_icon TEXT,
- need_jump_bv INTEGER DEFAULT 0,
- disable_show_up_info INTEGER DEFAULT 0,
- is_story_play INTEGER DEFAULT 0,
- owner_mid INTEGER,
- owner_name TEXT,
- owner_face TEXT,
- stat_view INTEGER DEFAULT 0,
- stat_danmaku INTEGER DEFAULT 0,
- stat_reply INTEGER DEFAULT 0,
- stat_favorite INTEGER DEFAULT 0,
- stat_coin INTEGER DEFAULT 0,
- stat_share INTEGER DEFAULT 0,
- stat_like INTEGER DEFAULT 0,
- stat_dislike INTEGER DEFAULT 0,
- stat_his_rank INTEGER DEFAULT 0,
- stat_now_rank INTEGER DEFAULT 0,
- stat_evaluation TEXT,
- dimension_width INTEGER,
- dimension_height INTEGER,
- dimension_rotate INTEGER DEFAULT 0,
- rights_bp INTEGER DEFAULT 0,
- rights_elec INTEGER DEFAULT 0,
- rights_download INTEGER DEFAULT 0,
- rights_movie INTEGER DEFAULT 0,
- rights_pay INTEGER DEFAULT 0,
- rights_hd5 INTEGER DEFAULT 0,
- rights_no_reprint INTEGER DEFAULT 0,
- rights_autoplay INTEGER DEFAULT 0,
- rights_ugc_pay INTEGER DEFAULT 0,
- rights_is_cooperation INTEGER DEFAULT 0,
- rights_ugc_pay_preview INTEGER DEFAULT 0,
- rights_no_background INTEGER DEFAULT 0,
- rights_clean_mode INTEGER DEFAULT 0,
- rights_is_stein_gate INTEGER DEFAULT 0,
- rights_is_360 INTEGER DEFAULT 0,
- rights_no_share INTEGER DEFAULT 0,
- rights_arc_pay INTEGER DEFAULT 0,
- rights_free_watch INTEGER DEFAULT 0,
- argue_msg TEXT,
- argue_type INTEGER DEFAULT 0,
- argue_link TEXT,
- fetch_time INTEGER NOT NULL,
- update_time INTEGER DEFAULT 0
- )
- """)
-
- # 视频分P信息表
- cursor.execute("""
- CREATE TABLE IF NOT EXISTS video_pages (
- id INTEGER PRIMARY KEY,
- bvid TEXT NOT NULL,
- cid INTEGER NOT NULL,
- page INTEGER NOT NULL,
- part TEXT,
- duration INTEGER,
- from_source TEXT,
- vid TEXT,
- weblink TEXT,
- dimension_width INTEGER,
- dimension_height INTEGER,
- dimension_rotate INTEGER DEFAULT 0,
- first_frame TEXT,
- ctime INTEGER DEFAULT 0,
- UNIQUE(bvid, cid)
- )
- """)
-
- # 视频标签信息表
- cursor.execute("""
- CREATE TABLE IF NOT EXISTS video_tags (
- id INTEGER PRIMARY KEY,
- bvid TEXT NOT NULL,
- tag_id INTEGER NOT NULL,
- tag_name TEXT NOT NULL,
- music_id TEXT,
- tag_type TEXT,
- jump_url TEXT,
- cover TEXT,
- content TEXT,
- short_content TEXT,
- type INTEGER,
- state INTEGER,
- UNIQUE(bvid, tag_id)
- )
- """)
-
- # UP主详细信息表
- cursor.execute("""
- CREATE TABLE IF NOT EXISTS uploader_info (
- mid INTEGER PRIMARY KEY,
- name TEXT NOT NULL,
- sex TEXT,
- face TEXT,
- face_nft INTEGER DEFAULT 0,
- face_nft_type INTEGER DEFAULT 0,
- sign TEXT,
- rank TEXT,
- level INTEGER DEFAULT 0,
- regtime INTEGER DEFAULT 0,
- spacesta INTEGER DEFAULT 0,
- birthday TEXT,
- place TEXT,
- description TEXT,
- article INTEGER DEFAULT 0,
- fans INTEGER DEFAULT 0,
- friend INTEGER DEFAULT 0,
- attention INTEGER DEFAULT 0,
- official_role INTEGER DEFAULT 0,
- official_title TEXT,
- official_desc TEXT,
- official_type INTEGER DEFAULT 0,
- vip_type INTEGER DEFAULT 0,
- vip_status INTEGER DEFAULT 0,
- vip_due_date INTEGER DEFAULT 0,
- vip_pay_type INTEGER DEFAULT 0,
- vip_theme_type INTEGER DEFAULT 0,
- vip_avatar_subscript INTEGER DEFAULT 0,
- vip_nickname_color TEXT,
- vip_role INTEGER DEFAULT 0,
- vip_avatar_subscript_url TEXT,
- pendant_pid INTEGER DEFAULT 0,
- pendant_name TEXT,
- pendant_image TEXT,
- pendant_expire INTEGER DEFAULT 0,
- nameplate_nid INTEGER DEFAULT 0,
- nameplate_name TEXT,
- nameplate_image TEXT,
- nameplate_image_small TEXT,
- nameplate_level TEXT,
- nameplate_condition TEXT,
- is_senior_member INTEGER DEFAULT 0,
- following INTEGER DEFAULT 0,
- archive_count INTEGER DEFAULT 0,
- article_count INTEGER DEFAULT 0,
- like_num INTEGER DEFAULT 0,
- fetch_time INTEGER NOT NULL,
- update_time INTEGER DEFAULT 0
- )
- """)
-
- # 视频荣誉信息表
- cursor.execute("""
- CREATE TABLE IF NOT EXISTS video_honors (
- id INTEGER PRIMARY KEY,
- bvid TEXT NOT NULL,
- aid INTEGER NOT NULL,
- type INTEGER NOT NULL,
- desc TEXT,
- weekly_recommend_num INTEGER DEFAULT 0,
- UNIQUE(bvid, type)
- )
- """)
-
- # 视频字幕信息表
- cursor.execute("""
- CREATE TABLE IF NOT EXISTS video_subtitles (
- id INTEGER PRIMARY KEY,
- bvid TEXT NOT NULL,
- allow_submit INTEGER DEFAULT 0,
- subtitle_id INTEGER,
- lan TEXT,
- lan_doc TEXT,
- is_lock INTEGER DEFAULT 0,
- subtitle_url TEXT,
- UNIQUE(bvid, subtitle_id)
- )
- """)
-
- # 相关视频信息表
- cursor.execute("""
- CREATE TABLE IF NOT EXISTS related_videos (
- id INTEGER PRIMARY KEY,
- bvid TEXT NOT NULL,
- related_bvid TEXT NOT NULL,
- related_aid INTEGER NOT NULL,
- related_title TEXT,
- related_pic TEXT,
- related_owner_mid INTEGER,
- related_owner_name TEXT,
- related_owner_face TEXT,
- UNIQUE(bvid, related_bvid)
- )
- """)
-
- # 创建索引
- cursor.execute("CREATE INDEX IF NOT EXISTS idx_video_base_info_owner_mid ON video_base_info (owner_mid)")
- cursor.execute("CREATE INDEX IF NOT EXISTS idx_video_base_info_fetch_time ON video_base_info (fetch_time)")
- cursor.execute("CREATE INDEX IF NOT EXISTS idx_video_pages_bvid ON video_pages (bvid)")
- cursor.execute("CREATE INDEX IF NOT EXISTS idx_video_tags_bvid ON video_tags (bvid)")
- cursor.execute("CREATE INDEX IF NOT EXISTS idx_video_honors_bvid ON video_honors (bvid)")
- cursor.execute("CREATE INDEX IF NOT EXISTS idx_video_subtitles_bvid ON video_subtitles (bvid)")
- cursor.execute("CREATE INDEX IF NOT EXISTS idx_related_videos_bvid ON related_videos (bvid)")
-
- # 提交更改
- conn.commit()
-
-
-async def get_video_detail(bvid: str) -> Dict[str, Any]:
- """
- 获取视频超详细信息
-
- Args:
- bvid: 视频的BV号
-
- Returns:
- 视频详细信息
- """
- config = load_config()
- cookies = config.get("cookies", {})
-
- cookie_str = "; ".join([f"{k}={v}" for k, v in cookies.items()]) if cookies else ""
-
- headers = {
- "User-Agent": "Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/116.0.0.0 Safari/537.36",
- "Referer": "https://www.bilibili.com",
- "Cookie": cookie_str
- }
-
- url = f"https://api.bilibili.com/x/web-interface/view/detail?bvid={bvid}"
-
- try:
- async with httpx.AsyncClient(timeout=30) as client:
- response = await client.get(url, headers=headers)
- response.raise_for_status()
- data = response.json()
-
- if data.get("code") != 0:
- raise HTTPException(status_code=400, detail=f"API错误: {data.get('message', '未知错误')}")
-
- return data
- except httpx.HTTPError as e:
- logger.error(f"请求视频详情API失败: {e}")
- raise HTTPException(status_code=500, detail=f"请求API失败: {str(e)}")
-
-
-def get_video_detail_sync(bvid: str, cookie_str: str = "", use_sessdata: bool = True) -> Dict[str, Any]:
- """
- 同步获取视频超详细信息(用于线程池)
-
- Args:
- bvid: 视频的BV号
- cookie_str: Cookie字符串
- use_sessdata: 是否使用SESSDATA
-
- Returns:
- 视频详细信息
- """
- import requests
-
- headers = {
- "User-Agent": "Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/116.0.0.0 Safari/537.36",
- "Referer": "https://www.bilibili.com"
- }
-
- if use_sessdata and cookie_str:
- headers["Cookie"] = cookie_str
-
- url = f"https://api.bilibili.com/x/web-interface/view/detail?bvid={bvid}"
-
- try:
- response = requests.get(url, headers=headers, timeout=30)
- response.raise_for_status()
- data = response.json()
-
- if data.get("code") != 0:
- logger.warning(f"API错误 {bvid}: {data.get('message', '未知错误')}")
- return data # 返回错误数据,让调用者处理
-
- return data
- except requests.RequestException as e:
- logger.error(f"请求视频详情API失败 {bvid}: {e}")
- return {"code": -1, "message": f"请求失败: {str(e)}"}
-
-
-def save_video_detail_to_db(data: Dict[str, Any]) -> None:
- """
- 将视频详细信息保存到数据库
-
- Args:
- data: 视频详细信息数据
- """
- # 确保数据库已初始化
- init_db()
-
- # 打印原始响应数据,方便调试
- logger.info(f"保存视频详情原始数据: {json.dumps(data, ensure_ascii=False)[:500]}...")
-
- # 保存完整的API响应到文件,方便排查错误
- try:
- os.makedirs(os.path.join("output", "api_responses"), exist_ok=True)
- response_file = os.path.join("output", "api_responses", f"video_detail_{int(time.time())}.json")
- with open(response_file, "w", encoding="utf-8") as f:
- json.dump(data, f, ensure_ascii=False, indent=2)
- logger.info(f"已保存完整API响应到文件: {response_file}")
- except Exception as e:
- logger.error(f"保存API响应到文件时出错: {e}")
-
- now_timestamp = int(time.time())
- view_data = data.get("data", {}).get("View", {})
- card_data = data.get("data", {}).get("Card", {})
- tags_data = data.get("data", {}).get("Tags", [])
- related_data = data.get("data", {}).get("Related", [])
- honor_reply_data = view_data.get("honor_reply", {}).get("honor", []) if view_data.get("honor_reply") else []
- subtitle_data = view_data.get("subtitle", {}) if view_data.get("subtitle") else {}
-
- # 调试: 获取表中实际的列名和数量
- try:
- with sqlite3.connect(DB_PATH) as conn:
- cursor = conn.cursor()
- cursor.execute("PRAGMA table_info(video_base_info)")
- table_columns = cursor.fetchall()
- column_names = [column[1] for column in table_columns]
- logger.info(f"数据库video_base_info表中实际的列名: {column_names}")
- logger.info(f"数据库video_base_info表中实际的列数: {len(column_names)}")
- except Exception as e:
- logger.error(f"获取表结构时出错: {e}")
-
- # 调试: 计算并打印值的数量,检查SQL语句列数是否匹配
- debug_values_count = [
- "bvid", "aid", "videos", "tid", "tid_v2", "tname", "tname_v2", "copyright", "pic", "title",
- "pubdate", "ctime", "desc", "desc_v2", "state", "duration", "mission_id", "dynamic", "cid",
- "season_id", "premiere", "teenage_mode", "is_chargeable_season", "is_story",
- "is_upower_exclusive", "is_upower_play", "is_upower_preview",
- "is_upower_exclusive_with_qa", "no_cache", "is_season_display", "like_icon",
- "need_jump_bv", "disable_show_up_info", "is_story_play", "owner_mid", "owner_name",
- "owner_face", "stat_view", "stat_danmaku", "stat_reply", "stat_favorite", "stat_coin",
- "stat_share", "stat_like", "stat_dislike", "stat_his_rank", "stat_now_rank",
- "stat_evaluation", "dimension_width", "dimension_height", "dimension_rotate",
- "rights_bp", "rights_elec", "rights_download", "rights_movie", "rights_pay", "rights_hd5",
- "rights_no_reprint", "rights_autoplay", "rights_ugc_pay", "rights_is_cooperation",
- "rights_ugc_pay_preview", "rights_no_background", "rights_clean_mode",
- "rights_is_stein_gate", "rights_is_360", "rights_no_share", "rights_arc_pay",
- "rights_free_watch", "argue_msg", "argue_type", "argue_link", "fetch_time", "update_time"
- ]
- logger.info(f"调试: 插入表的列数量={len(debug_values_count)}, VALUES 参数数量应为: {len(debug_values_count)}")
-
- # 调试: 尝试找出我们定义的列和表中实际列之间的差异
- try:
- with sqlite3.connect(DB_PATH) as conn:
- cursor = conn.cursor()
- cursor.execute("PRAGMA table_info(video_base_info)")
- table_columns = cursor.fetchall()
- db_column_names = [column[1] for column in table_columns]
-
- # 比较列名
- our_columns = set(debug_values_count)
- db_columns = set(db_column_names)
- missing_in_our_def = db_columns - our_columns
- extra_in_our_def = our_columns - db_columns
-
- if missing_in_our_def:
- logger.warning(f"我们定义中缺少的列: {missing_in_our_def}")
- if extra_in_our_def:
- logger.warning(f"我们定义中多余的列: {extra_in_our_def}")
-
- # 检查顺序是否一致
- if len(debug_values_count) == len(db_column_names) - 1: # 减1是因为id列是自增的
- for i, (ours, db) in enumerate(zip(debug_values_count, db_column_names[1:])): # 跳过id列
- if ours != db:
- logger.warning(f"列顺序不匹配: 索引{i},我们的定义是 '{ours}',数据库是 '{db}'")
- except Exception as e:
- logger.error(f"比较列名时出错: {e}")
-
- if not view_data:
- logger.error("视频数据为空")
- return
-
- bvid = view_data.get("bvid")
- if not bvid:
- logger.error("视频BV号为空")
- return
-
- # 记录详细的数据结构信息
- logger.debug(f"保存视频 {bvid} 详情: view_data keys: {view_data.keys()}")
- logger.debug(f"rights keys: {view_data.get('rights', {}).keys()}")
-
- try:
- with sqlite3.connect(DB_PATH) as conn:
- conn.execute("PRAGMA foreign_keys = ON")
- cursor = conn.cursor()
-
- # 1. 保存视频基本信息
- owner = view_data.get("owner", {})
- stat = view_data.get("stat", {})
- dimension = view_data.get("dimension", {})
- rights = view_data.get("rights", {})
- argue_info = view_data.get("argue_info", {})
-
- # 检查视频是否已存在
- cursor.execute("SELECT bvid FROM video_base_info WHERE bvid = ?", (bvid,))
- existing = cursor.fetchone()
-
- if existing:
- # 更新现有数据
- cursor.execute("""
- UPDATE video_base_info SET
- videos = ?, tid = ?, tid_v2 = ?, tname = ?, tname_v2 = ?,
- copyright = ?, pic = ?, title = ?, pubdate = ?, ctime = ?,
- desc = ?, desc_v2 = ?, state = ?, duration = ?, mission_id = ?,
- dynamic = ?, cid = ?, season_id = ?, premiere = ?, teenage_mode = ?,
- is_chargeable_season = ?, is_story = ?, is_upower_exclusive = ?,
- is_upower_play = ?, is_upower_preview = ?,
- is_upower_exclusive_with_qa = ?, no_cache = ?,
- is_season_display = ?, like_icon = ?, need_jump_bv = ?,
- disable_show_up_info = ?, is_story_play = ?,
- owner_mid = ?, owner_name = ?, owner_face = ?,
- stat_view = ?, stat_danmaku = ?, stat_reply = ?, stat_favorite = ?,
- stat_coin = ?, stat_share = ?, stat_like = ?, stat_dislike = ?,
- stat_his_rank = ?, stat_now_rank = ?, stat_evaluation = ?,
- dimension_width = ?, dimension_height = ?, dimension_rotate = ?,
- rights_bp = ?, rights_elec = ?, rights_download = ?, rights_movie = ?,
- rights_pay = ?, rights_hd5 = ?, rights_no_reprint = ?, rights_autoplay = ?,
- rights_ugc_pay = ?, rights_is_cooperation = ?, rights_ugc_pay_preview = ?,
- rights_no_background = ?, rights_clean_mode = ?, rights_is_stein_gate = ?,
- rights_is_360 = ?, rights_no_share = ?, rights_arc_pay = ?, rights_free_watch = ?,
- argue_msg = ?, argue_type = ?, argue_link = ?,
- update_time = ?
- WHERE bvid = ?
- """, (
- view_data.get("videos", 1),
- view_data.get("tid"),
- view_data.get("tid_v2"),
- view_data.get("tname"),
- view_data.get("tname_v2"),
- view_data.get("copyright"),
- view_data.get("pic"),
- view_data.get("title"),
- view_data.get("pubdate"),
- view_data.get("ctime"),
- view_data.get("desc"),
- # 对于desc_v2字段,如果是列表且有内容,只取第一项的raw_text值
- (view_data.get("desc_v2")[0].get("raw_text") if isinstance(view_data.get("desc_v2"), list) and view_data.get("desc_v2") else ""),
- view_data.get("state", 0),
- view_data.get("duration"),
- view_data.get("mission_id"),
- view_data.get("dynamic"),
- view_data.get("cid"),
- view_data.get("season_id"),
- 1 if view_data.get("premiere") else 0,
- view_data.get("teenage_mode", 0),
- 1 if view_data.get("is_chargeable_season") else 0,
- 1 if view_data.get("is_story") else 0,
- 1 if view_data.get("is_upower_exclusive") else 0,
- 1 if view_data.get("is_upower_play") else 0,
- 1 if view_data.get("is_upower_preview") else 0,
- 1 if view_data.get("is_upower_exclusive_with_qa") else 0,
- 1 if view_data.get("no_cache") else 0,
- 1 if view_data.get("is_season_display") else 0,
- view_data.get("like_icon", ""),
- 1 if view_data.get("need_jump_bv") else 0,
- 1 if view_data.get("disable_show_up_info") else 0,
- view_data.get("is_story_play", 0),
- owner.get("mid"),
- owner.get("name"),
- owner.get("face"),
- stat.get("view", 0),
- stat.get("danmaku", 0),
- stat.get("reply", 0),
- stat.get("favorite", 0),
- stat.get("coin", 0),
- stat.get("share", 0),
- stat.get("like", 0),
- stat.get("dislike", 0),
- stat.get("his_rank", 0),
- stat.get("now_rank", 0),
- stat.get("evaluation", ""),
- dimension.get("width"),
- dimension.get("height"),
- dimension.get("rotate", 0),
- rights.get("bp", 0),
- rights.get("elec", 0),
- rights.get("download", 0),
- rights.get("movie", 0),
- rights.get("pay", 0),
- rights.get("hd5", 0),
- rights.get("no_reprint", 0),
- rights.get("autoplay", 0),
- rights.get("ugc_pay", 0),
- rights.get("is_cooperation", 0),
- rights.get("ugc_pay_preview", 0),
- rights.get("no_background", 0),
- rights.get("clean_mode", 0),
- rights.get("is_stein_gate", 0),
- rights.get("is_360", 0),
- rights.get("no_share", 0),
- rights.get("arc_pay", 0),
- rights.get("free_watch", 0),
- argue_info.get("argue_msg", ""),
- argue_info.get("argue_type", 0),
- argue_info.get("argue_link", ""),
- now_timestamp,
- bvid
- ))
- else:
- # 插入新数据
- # 创建参数列表,先明确所有参数,便于调试
- insert_params = [
- bvid, # 1. bvid
- view_data.get("aid"), # 2. aid
- view_data.get("videos", 1), # 3. videos
- view_data.get("tid"), # 4. tid
- view_data.get("tid_v2"), # 5. tid_v2
- view_data.get("tname"), # 6. tname
- view_data.get("tname_v2"), # 7. tname_v2
- view_data.get("copyright"), # 8. copyright
- view_data.get("pic"), # 9. pic
- view_data.get("title"), # 10. title
- view_data.get("pubdate"), # 11. pubdate
- view_data.get("ctime"), # 12. ctime
- view_data.get("desc"), # 13. desc
- # 对于desc_v2字段,如果是列表且有内容,只取第一项的raw_text值
- (view_data.get("desc_v2")[0].get("raw_text") if isinstance(view_data.get("desc_v2"), list) and view_data.get("desc_v2") else ""), # 14. desc_v2
- view_data.get("state", 0), # 15. state
- view_data.get("duration"), # 16. duration
- view_data.get("mission_id"), # 17. mission_id
- view_data.get("dynamic"), # 18. dynamic
- view_data.get("cid"), # 19. cid
- view_data.get("season_id"), # 20. season_id
- 1 if view_data.get("premiere") else 0, # 21. premiere
- view_data.get("teenage_mode", 0), # 22. teenage_mode
- 1 if view_data.get("is_chargeable_season") else 0, # 23. is_chargeable_season
- 1 if view_data.get("is_story") else 0, # 24. is_story
- 1 if view_data.get("is_upower_exclusive") else 0, # 25. is_upower_exclusive
- 1 if view_data.get("is_upower_play") else 0, # 26. is_upower_play
- 1 if view_data.get("is_upower_preview") else 0, # 27. is_upower_preview
- 1 if view_data.get("is_upower_exclusive_with_qa") else 0, # 30. is_upower_exclusive_with_qa
- 1 if view_data.get("no_cache") else 0, # 31. no_cache
- 1 if view_data.get("is_season_display") else 0, # 32. is_season_display
- view_data.get("like_icon", ""), # 33. like_icon
- 1 if view_data.get("need_jump_bv") else 0, # 34. need_jump_bv
- 1 if view_data.get("disable_show_up_info") else 0, # 35. disable_show_up_info
- view_data.get("is_story_play", 0), # 36. is_story_play
- owner.get("mid"), # 37. owner_mid
- owner.get("name"), # 38. owner_name
- owner.get("face"), # 39. owner_face
- stat.get("view", 0), # 40. stat_view
- stat.get("danmaku", 0), # 41. stat_danmaku
- stat.get("reply", 0), # 42. stat_reply
- stat.get("favorite", 0), # 43. stat_favorite
- stat.get("coin", 0), # 44. stat_coin
- stat.get("share", 0), # 45. stat_share
- stat.get("like", 0), # 46. stat_like
- stat.get("dislike", 0), # 47. stat_dislike
- stat.get("his_rank", 0), # 48. stat_his_rank
- stat.get("now_rank", 0), # 49. stat_now_rank
- stat.get("evaluation", ""), # 50. stat_evaluation
- dimension.get("width"), # 52. dimension_width
- dimension.get("height"), # 53. dimension_height
- dimension.get("rotate", 0), # 54. dimension_rotate
- rights.get("bp", 0), # 55. rights_bp
- rights.get("elec", 0), # 56. rights_elec
- rights.get("download", 0), # 57. rights_download
- rights.get("movie", 0), # 58. rights_movie
- rights.get("pay", 0), # 59. rights_pay
- rights.get("hd5", 0), # 60. rights_hd5
- rights.get("no_reprint", 0), # 61. rights_no_reprint
- rights.get("autoplay", 0), # 62. rights_autoplay
- rights.get("ugc_pay", 0), # 63. rights_ugc_pay
- rights.get("is_cooperation", 0), # 64. rights_is_cooperation
- rights.get("ugc_pay_preview", 0), # 65. rights_ugc_pay_preview
- rights.get("no_background", 0), # 66. rights_no_background
- rights.get("clean_mode", 0), # 67. rights_clean_mode
- rights.get("is_stein_gate", 0), # 68. rights_is_stein_gate
- rights.get("is_360", 0), # 69. rights_is_360
- rights.get("no_share", 0), # 70. rights_no_share
- rights.get("arc_pay", 0), # 71. rights_arc_pay
- rights.get("free_watch", 0), # 72. rights_free_watch
- argue_info.get("argue_msg", ""), # 73. argue_msg
- argue_info.get("argue_type", 0), # 74. argue_type
- argue_info.get("argue_link", ""), # 75. argue_link
- now_timestamp, # 76. fetch_time
- now_timestamp # 77. update_time
- ]
-
- # 打印参数数量以便调试
- logger.info(f"实际准备插入的参数数量: {len(insert_params)}")
-
- # 计算VALUES子句中的问号数量
- values_clause = """(
- ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, /* 1-20 */
- ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, /* 21-40 */
- ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, /* 41-60 */
- ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ? /* 61-74 */
- )"""
- question_marks_count = values_clause.count('?')
- logger.info(f"VALUES子句中的问号数量: {question_marks_count}")
-
- # 确保问号数量和参数数量匹配
- if question_marks_count != len(insert_params):
- logger.error(f"问号数量({question_marks_count})和参数数量({len(insert_params)})不匹配!")
- for i, param in enumerate(insert_params):
- logger.debug(f"参数 {i+1}: {param}")
- raise ValueError(f"SQL绑定参数不匹配: 需要 {question_marks_count} 个值,但提供了 {len(insert_params)} 个")
-
- # 检查所有参数的类型,确保它们是SQLite支持的类型
- for i, param in enumerate(insert_params):
- if isinstance(param, (list, dict)):
- logger.warning(f"参数 {i+1} 是不支持的类型: {type(param)}, 值: {param}")
- # 将不支持的类型转换为JSON字符串
- insert_params[i] = json.dumps(param, ensure_ascii=False)
- logger.info(f"已将参数 {i+1} 转换为字符串: {insert_params[i]}")
-
- # 我们已经在上面的代码中处理了所有参数的类型转换,包括desc_v2
-
- # 确保列和值的数量匹配 - 使用明确的格式确保77个问号
- cursor.execute("""
- INSERT INTO video_base_info (
- bvid, aid, videos, tid, tid_v2, tname, tname_v2, copyright, pic, title,
- pubdate, ctime, desc, desc_v2, state, duration, mission_id, dynamic, cid,
- season_id, premiere, teenage_mode, is_chargeable_season, is_story,
- is_upower_exclusive, is_upower_play, is_upower_preview,
- is_upower_exclusive_with_qa, no_cache, is_season_display, like_icon,
- need_jump_bv, disable_show_up_info, is_story_play, owner_mid, owner_name,
- owner_face, stat_view, stat_danmaku, stat_reply, stat_favorite, stat_coin,
- stat_share, stat_like, stat_dislike, stat_his_rank, stat_now_rank,
- stat_evaluation, dimension_width, dimension_height, dimension_rotate,
- rights_bp, rights_elec, rights_download, rights_movie, rights_pay, rights_hd5,
- rights_no_reprint, rights_autoplay, rights_ugc_pay, rights_is_cooperation,
- rights_ugc_pay_preview, rights_no_background, rights_clean_mode,
- rights_is_stein_gate, rights_is_360, rights_no_share, rights_arc_pay,
- rights_free_watch, argue_msg, argue_type, argue_link, fetch_time, update_time
- ) VALUES (
- ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, /* 1-20 */
- ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, /* 21-40 */
- ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, /* 41-60 */
- ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ? /* 61-74 */
- )
- """, insert_params)
-
- # 2. 保存视频分P信息
- # 先删除旧的分P信息
- cursor.execute("DELETE FROM video_pages WHERE bvid = ?", (bvid,))
-
- # 插入新的分P信息
- pages = view_data.get("pages", [])
- if pages:
- for page in pages:
- page_dimension = page.get("dimension", {})
- cursor.execute("""
- INSERT INTO video_pages (
- bvid, cid, page, part, duration, from_source, vid, weblink,
- dimension_width, dimension_height, dimension_rotate, first_frame, ctime
- ) VALUES (?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?)
- """, (
- bvid,
- page.get("cid"),
- page.get("page"),
- page.get("part"),
- page.get("duration"),
- page.get("from"),
- page.get("vid", ""),
- page.get("weblink", ""),
- page_dimension.get("width"),
- page_dimension.get("height"),
- page_dimension.get("rotate", 0),
- page.get("first_frame"),
- page.get("ctime", 0)
- ))
-
- # 3. 保存视频标签信息
- # 先删除旧的标签信息
- cursor.execute("DELETE FROM video_tags WHERE bvid = ?", (bvid,))
-
- # 插入新的标签信息
- if tags_data:
- for tag in tags_data:
- cursor.execute("""
- INSERT INTO video_tags (
- bvid, tag_id, tag_name, music_id, tag_type, jump_url,
- cover, content, short_content, type, state
- ) VALUES (?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?)
- """, (
- bvid,
- tag.get("tag_id"),
- tag.get("tag_name"),
- tag.get("music_id", ""),
- tag.get("tag_type", ""),
- tag.get("jump_url", ""),
- tag.get("cover"),
- tag.get("content"),
- tag.get("short_content"),
- tag.get("type"),
- tag.get("state")
- ))
-
- # 4. 保存UP主信息
- if card_data and "card" in card_data:
- up_info = card_data["card"]
- mid = up_info.get("mid")
- if mid:
- # 检查UP主表结构,打印列信息用于调试
- cursor.execute("PRAGMA table_info(uploader_info)")
- up_table_columns = cursor.fetchall()
- up_column_names = [column[1] for column in up_table_columns]
- logger.info(f"uploader_info表中的列数: {len(up_column_names)}")
- logger.info(f"uploader_info表的列名: {up_column_names}")
-
- # 检查UP主是否已存在
- cursor.execute("SELECT mid FROM uploader_info WHERE mid = ?", (mid,))
- existing_up = cursor.fetchone()
-
- official = up_info.get("Official", {})
- level_info = up_info.get("level_info", {})
- vip = up_info.get("vip", {})
- pendant = up_info.get("pendant", {})
- nameplate = up_info.get("nameplate", {})
-
- if existing_up:
- # 更新UP主信息
- cursor.execute("""
- UPDATE uploader_info SET
- name = ?, sex = ?, face = ?, face_nft = ?, face_nft_type = ?,
- sign = ?, rank = ?, level = ?, regtime = ?, spacesta = ?,
- birthday = ?, place = ?, description = ?, article = ?,
- fans = ?, friend = ?, attention = ?,
- official_role = ?, official_title = ?, official_desc = ?, official_type = ?,
- vip_type = ?, vip_status = ?, vip_due_date = ?, vip_pay_type = ?,
- vip_theme_type = ?, vip_avatar_subscript = ?,
- vip_nickname_color = ?, vip_role = ?, vip_avatar_subscript_url = ?,
- pendant_pid = ?, pendant_name = ?, pendant_image = ?, pendant_expire = ?,
- nameplate_nid = ?, nameplate_name = ?, nameplate_image = ?,
- nameplate_image_small = ?, nameplate_level = ?, nameplate_condition = ?,
- is_senior_member = ?,
- following = ?, archive_count = ?, article_count = ?, like_num = ?,
- update_time = ?
- WHERE mid = ?
- """, (
- up_info.get("name"),
- up_info.get("sex"),
- up_info.get("face"),
- up_info.get("face_nft", 0),
- up_info.get("face_nft_type", 0),
- up_info.get("sign"),
- up_info.get("rank"),
- level_info.get("current_level", 0),
- up_info.get("regtime", 0),
- up_info.get("spacesta", 0),
- up_info.get("birthday", ""),
- up_info.get("place", ""),
- up_info.get("description", ""),
- up_info.get("article", 0),
- up_info.get("fans", 0),
- up_info.get("friend", 0),
- up_info.get("attention", 0),
- official.get("role", 0),
- official.get("title", ""),
- official.get("desc", ""),
- official.get("type", 0),
- vip.get("type", 0),
- vip.get("status", 0),
- vip.get("due_date", 0),
- vip.get("vip_pay_type", 0),
- vip.get("theme_type", 0),
- vip.get("avatar_subscript", 0),
- vip.get("nickname_color", ""),
- vip.get("role", 0),
- vip.get("avatar_subscript_url", ""),
- pendant.get("pid", 0),
- pendant.get("name", ""),
- pendant.get("image", ""),
- pendant.get("expire", 0),
- nameplate.get("nid", 0),
- nameplate.get("name", ""),
- nameplate.get("image", ""),
- nameplate.get("image_small", ""),
- nameplate.get("level", ""),
- nameplate.get("condition", ""),
- up_info.get("is_senior_member", 0),
- card_data.get("following", 0),
- card_data.get("archive_count", 0),
- card_data.get("article_count", 0),
- card_data.get("like_num", 0),
- now_timestamp,
- mid
- ))
- else:
- # 创建插入参数列表,便于调试
- uploader_params = [
- mid, # 1. mid
- up_info.get("name"), # 2. name
- up_info.get("sex"), # 3. sex
- up_info.get("face"), # 4. face
- up_info.get("face_nft", 0), # 5. face_nft
- up_info.get("face_nft_type", 0), # 6. face_nft_type
- up_info.get("sign"), # 7. sign
- up_info.get("rank"), # 8. rank
- level_info.get("current_level", 0), # 9. level
- up_info.get("regtime", 0), # 10. regtime
- up_info.get("spacesta", 0), # 11. spacesta
- up_info.get("birthday", ""), # 12. birthday
- up_info.get("place", ""), # 13. place
- up_info.get("description", ""), # 14. description
- up_info.get("article", 0), # 15. article
- up_info.get("fans", 0), # 16. fans
- up_info.get("friend", 0), # 17. friend
- up_info.get("attention", 0), # 18. attention
- official.get("role", 0), # 19. official_role
- official.get("title", ""), # 20. official_title
- official.get("desc", ""), # 21. official_desc
- official.get("type", 0), # 22. official_type
- vip.get("type", 0), # 23. vip_type
- vip.get("status", 0), # 24. vip_status
- vip.get("due_date", 0), # 25. vip_due_date
- vip.get("vip_pay_type", 0), # 26. vip_pay_type
- vip.get("theme_type", 0), # 27. vip_theme_type
- vip.get("avatar_subscript", 0), # 28. vip_avatar_subscript
- vip.get("nickname_color", ""), # 29. vip_nickname_color
- vip.get("role", 0), # 30. vip_role
- vip.get("avatar_subscript_url", ""), # 31. vip_avatar_subscript_url
- pendant.get("pid", 0), # 32. pendant_pid
- pendant.get("name", ""), # 33. pendant_name
- pendant.get("image", ""), # 34. pendant_image
- pendant.get("expire", 0), # 35. pendant_expire
- nameplate.get("nid", 0), # 36. nameplate_nid
- nameplate.get("name", ""), # 37. nameplate_name
- nameplate.get("image", ""), # 38. nameplate_image
- nameplate.get("image_small", ""), # 39. nameplate_image_small
- nameplate.get("level", ""), # 40. nameplate_level
- nameplate.get("condition", ""), # 41. nameplate_condition
- up_info.get("is_senior_member", 0), # 42. is_senior_member
- card_data.get("following", 0), # 43. following
- card_data.get("archive_count", 0), # 44. archive_count
- card_data.get("article_count", 0), # 45. article_count
- card_data.get("like_num", 0), # 46. like_num
- now_timestamp, # 47. fetch_time
- now_timestamp # 48. update_time
- ]
-
- # 打印参数数量和列数量
- logger.info(f"准备插入的UP主参数数量: {len(uploader_params)}")
-
- # 确保参数数量和问号一致
- # 插入新的UP主信息
- cursor.execute("""
- INSERT INTO uploader_info (
- mid, name, sex, face, face_nft, face_nft_type,
- sign, rank, level, regtime, spacesta,
- birthday, place, description, article,
- fans, friend, attention,
- official_role, official_title, official_desc, official_type,
- vip_type, vip_status, vip_due_date, vip_pay_type,
- vip_theme_type, vip_avatar_subscript,
- vip_nickname_color, vip_role, vip_avatar_subscript_url,
- pendant_pid, pendant_name, pendant_image, pendant_expire,
- nameplate_nid, nameplate_name, nameplate_image,
- nameplate_image_small, nameplate_level, nameplate_condition,
- is_senior_member,
- following, archive_count, article_count, like_num,
- fetch_time, update_time
- ) VALUES (
- ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, /* 1-10 */
- ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, /* 11-20 */
- ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, /* 21-30 */
- ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, /* 31-40 */
- ?, ?, ?, ?, ?, ?, ?, ? /* 41-48 */
- )
- """, uploader_params)
-
- # 5. 保存视频荣誉信息
- if honor_reply_data:
- # 先删除旧的荣誉信息
- cursor.execute("DELETE FROM video_honors WHERE bvid = ?", (bvid,))
-
- # 插入新的荣誉信息
- for honor in honor_reply_data:
- cursor.execute("""
- INSERT INTO video_honors (
- bvid, aid, type, desc, weekly_recommend_num
- ) VALUES (?, ?, ?, ?, ?)
- """, (
- bvid,
- honor.get("aid", view_data.get("aid")),
- honor.get("type", 0),
- honor.get("desc", ""),
- honor.get("weekly_recommend_num", 0)
- ))
-
- # 6. 保存视频字幕信息
- if subtitle_data:
- # 先删除旧的字幕信息
- cursor.execute("DELETE FROM video_subtitles WHERE bvid = ?", (bvid,))
-
- # 插入字幕允许提交状态
- allow_submit = 1 if subtitle_data.get("allow_submit") else 0
-
- # 插入字幕列表
- subtitle_list = subtitle_data.get("list", [])
- if subtitle_list:
- for subtitle in subtitle_list:
- cursor.execute("""
- INSERT INTO video_subtitles (
- bvid, allow_submit, subtitle_id, lan, lan_doc, is_lock, subtitle_url
- ) VALUES (?, ?, ?, ?, ?, ?, ?)
- """, (
- bvid,
- allow_submit,
- subtitle.get("id", 0),
- subtitle.get("lan", ""),
- subtitle.get("lan_doc", ""),
- 1 if subtitle.get("is_lock") else 0,
- subtitle.get("subtitle_url", "")
- ))
- else:
- # 如果没有字幕,但有allow_submit信息,也插入一条记录
- cursor.execute("""
- INSERT INTO video_subtitles (
- bvid, allow_submit, subtitle_id, lan, lan_doc, is_lock, subtitle_url
- ) VALUES (?, ?, ?, ?, ?, ?, ?)
- """, (
- bvid,
- allow_submit,
- 0,
- "",
- "",
- 0,
- ""
- ))
-
- # 7. 保存相关视频信息
- if related_data:
- # 先删除旧的相关视频信息
- cursor.execute("DELETE FROM related_videos WHERE bvid = ?", (bvid,))
-
- # 插入新的相关视频信息
- for related in related_data:
- related_owner = related.get("owner", {})
- cursor.execute("""
- INSERT INTO related_videos (
- bvid, related_bvid, related_aid, related_title, related_pic,
- related_owner_mid, related_owner_name, related_owner_face
- ) VALUES (?, ?, ?, ?, ?, ?, ?, ?)
- """, (
- bvid,
- related.get("bvid", ""),
- related.get("aid", 0),
- related.get("title", ""),
- related.get("pic", ""),
- related_owner.get("mid", 0),
- related_owner.get("name", ""),
- related_owner.get("face", "")
- ))
-
- conn.commit()
-
- logger.info(f"已保存视频 {bvid} 的超详细信息到数据库")
-
- except sqlite3.Error as e:
- logger.error(f"保存视频详情到数据库时出错: {e}")
- logger.debug(f"视频详情数据: {json.dumps(data, ensure_ascii=False)}")
- raise
-
-
-@router.get("/fetch/{bvid}", summary="获取单个视频详情")
-async def fetch_video_detail(bvid: str):
- """获取并保存视频超详细信息"""
- try:
- logger.info(f"开始获取视频 {bvid} 的超详细信息")
- # 已知失效预检查,避免重复请求
- try:
- create_invalid_videos_table()
- except Exception:
- pass
- invalid_info = check_invalid_video(bvid)
- if invalid_info.get("is_invalid"):
- logger.info(f"视频 {bvid} 已知失效(type={invalid_info.get('error_type')}), 跳过请求")
- return {
- "status": "skipped",
- "message": f"视频 {bvid} 已知失效,已跳过",
- "data": {"bvid": bvid, "error_type": invalid_info.get("error_type")}
- }
- data = await get_video_detail(bvid)
- logger.info(f"成功获取视频 {bvid} 的API响应,准备保存到数据库")
-
- # 检查关键数据是否存在
- view_data = data.get("data", {}).get("View", {})
- if not view_data:
- logger.error(f"视频 {bvid} 的View数据不存在: {json.dumps(data, ensure_ascii=False)[:500]}")
- raise HTTPException(status_code=400, detail=f"视频 {bvid} 的详情数据不完整")
-
- # 检查权限数据是否存在
- rights = view_data.get("rights", {})
- if not rights:
- logger.warning(f"视频 {bvid} 的rights数据不存在,将使用空字典")
-
- # 打印权限字段列表,确认完整性
- logger.info(f"视频 {bvid} 的rights字段: {list(rights.keys())}")
-
- # 打印统计字段列表
- stat = view_data.get("stat", {})
- logger.info(f"视频 {bvid} 的stat字段: {list(stat.keys())}")
-
- save_video_detail_to_db(data)
- logger.info(f"成功保存视频 {bvid} 的超详细信息到数据库")
- return {"status": "success", "message": f"成功获取并保存视频 {bvid} 的超详细信息"}
- except Exception as e:
- logger.exception(f"处理视频详情时出错: {e}")
- # 打印详细的错误堆栈
- import traceback
- error_stack = traceback.format_exc()
- logger.error(f"错误堆栈: {error_stack}")
- raise HTTPException(status_code=500, detail=f"处理视频详情时出错: {str(e)}")
-
-
-@router.get("/info/{bvid}", summary="从数据库获取视频信息")
-async def get_video_info_from_db(bvid: str):
- """从数据库获取视频信息"""
- try:
- with sqlite3.connect(DB_PATH) as conn:
- conn.row_factory = sqlite3.Row
- cursor = conn.cursor()
-
- # 获取视频基本信息
- cursor.execute("""
- SELECT * FROM video_base_info WHERE bvid = ?
- """, (bvid,))
- video_info = cursor.fetchone()
-
- if not video_info:
- raise HTTPException(status_code=404, detail=f"未找到视频 {bvid} 的信息")
-
- # 转换为字典
- video_info_dict = dict(video_info)
- video_info_dict["original_url"] = _build_video_original_url(video_info_dict)
-
- # 获取视频分P信息
- cursor.execute("""
- SELECT * FROM video_pages WHERE bvid = ? ORDER BY page
- """, (bvid,))
- pages = [dict(page) for page in cursor.fetchall()]
- video_info_dict["pages"] = pages
-
- # 获取视频标签信息
- cursor.execute("""
- SELECT * FROM video_tags WHERE bvid = ?
- """, (bvid,))
- tags = [dict(tag) for tag in cursor.fetchall()]
- video_info_dict["tags"] = tags
-
- # 获取UP主信息
- if "owner_mid" in video_info_dict and video_info_dict["owner_mid"]:
- cursor.execute("""
- SELECT * FROM uploader_info WHERE mid = ?
- """, (video_info_dict["owner_mid"],))
- up_info = cursor.fetchone()
- if up_info:
- video_info_dict["owner_info"] = dict(up_info)
-
- # 获取视频荣誉信息
- cursor.execute("""
- SELECT * FROM video_honors WHERE bvid = ?
- """, (bvid,))
- honors = [dict(honor) for honor in cursor.fetchall()]
- if honors:
- video_info_dict["honors"] = honors
-
- # 获取视频字幕信息
- cursor.execute("""
- SELECT * FROM video_subtitles WHERE bvid = ?
- """, (bvid,))
- subtitles = [dict(subtitle) for subtitle in cursor.fetchall()]
- if subtitles:
- video_info_dict["subtitles"] = subtitles
-
- # 获取相关视频信息
- cursor.execute("""
- SELECT * FROM related_videos WHERE bvid = ?
- """, (bvid,))
- related_videos = [dict(related) for related in cursor.fetchall()]
- if related_videos:
- video_info_dict["related_videos"] = related_videos
-
- return video_info_dict
- except sqlite3.Error as e:
- logger.exception(f"从数据库获取视频信息时出错: {e}")
- raise HTTPException(status_code=500, detail=f"从数据库获取视频信息时出错: {str(e)}")
-
-
-@router.get("/search", summary="搜索视频")
-async def search_videos(
- keyword: str = Query(None, description="关键词"),
- uploader_mid: int = Query(None, description="UP主ID"),
- page: int = Query(1, description="页码"),
- per_page: int = Query(20, description="每页数量")
-):
- """搜索视频"""
- try:
- with sqlite3.connect(DB_PATH) as conn:
- conn.row_factory = sqlite3.Row
- cursor = conn.cursor()
-
- params = []
- where_clauses = []
-
- if keyword:
- where_clauses.append("(title LIKE ? OR desc LIKE ?)")
- keyword_pattern = f"%{keyword}%"
- params.extend([keyword_pattern, keyword_pattern])
-
- if uploader_mid:
- where_clauses.append("owner_mid = ?")
- params.append(uploader_mid)
-
- # 构建WHERE子句
- where_clause = " AND ".join(where_clauses) if where_clauses else "1=1"
-
- # 计算总数
- cursor.execute(f"SELECT COUNT(*) as total FROM video_base_info WHERE {where_clause}", params)
- total = cursor.fetchone()["total"]
-
- # 查询数据
- offset = (page - 1) * per_page
- query = f"""
- SELECT * FROM video_base_info
- WHERE {where_clause}
- ORDER BY pubdate DESC
- LIMIT ? OFFSET ?
- """
- params.extend([per_page, offset])
-
- cursor.execute(query, params)
- videos = []
- for video in cursor.fetchall():
- video_dict = dict(video)
- video_dict["original_url"] = _build_video_original_url(video_dict)
- videos.append(video_dict)
-
- return {
- "total": total,
- "page": page,
- "per_page": per_page,
- "videos": videos
- }
- except sqlite3.Error as e:
- logger.exception(f"搜索视频时出错: {e}")
- raise HTTPException(status_code=500, detail=f"搜索视频时出错: {str(e)}")
-
-
-@router.post("/batch_fetch", summary="批量获取视频详情")
-async def batch_fetch_video_details(bvids: List[str]):
- """批量获取多个视频的超详细信息"""
- results = []
- errors = []
-
- for bvid in bvids:
- try:
- data = await get_video_detail(bvid)
- save_video_detail_to_db(data)
- results.append({"bvid": bvid, "status": "success"})
- except Exception as e:
- logger.error(f"处理视频 {bvid} 详情时出错: {e}")
- errors.append({"bvid": bvid, "error": str(e)})
-
- return {
- "success_count": len(results),
- "error_count": len(errors),
- "results": results,
- "errors": errors
- }
-
-
-@router.get("/batch_fetch_from_history", summary="从历史记录批量获取视频详情")
-async def batch_fetch_video_details_from_history(
- background_tasks: BackgroundTasks,
- max_videos: int = Query(100, description="本次最多处理的视频数量,0表示不限制"),
- specific_videos: Optional[str] = Query(None, description="要获取的特定视频ID列表,用逗号分隔"),
- use_sessdata: bool = Query(True, description="是否使用SESSDATA获取详情,某些视频需要登录才能查看"),
- batch_size: int = Query(20, description="批次大小,每批处理的视频数量")
-):
- """从历史记录中获取视频ID,批量获取视频超详细信息"""
- try:
- # 获取数据库路径
- db_path = os.path.join("output", "bilibili_history.db")
-
- if not os.path.exists(db_path):
- raise HTTPException(status_code=404, detail="历史记录数据库不存在,请先获取历史记录")
-
- # 连接数据库获取视频列表
- with sqlite3.connect(db_path) as conn:
- cursor = conn.cursor()
-
- # 获取所有历史记录表名
- cursor.execute("""
- SELECT name FROM sqlite_master
- WHERE type='table' AND name LIKE 'bilibili_history_%'
- """)
- table_names = [row[0] for row in cursor.fetchall()]
-
- if not table_names:
- raise HTTPException(status_code=404, detail="未找到任何历史记录表")
-
- if specific_videos:
- # 处理特定视频列表
- video_list = [v.strip() for v in specific_videos.split(',') if v.strip()]
- if not video_list:
- raise HTTPException(status_code=400, detail="特定视频列表为空")
-
- # 验证这些视频是否在历史记录中
- placeholders = ','.join(['?' for _ in video_list])
- union_queries = []
- for table_name in table_names:
- union_queries.append(f"SELECT DISTINCT bvid FROM {table_name} WHERE bvid IN ({placeholders}) AND bvid IS NOT NULL AND bvid != ''")
-
- if union_queries:
- union_query = " UNION ".join(union_queries)
- # 为每个表的查询准备参数
- all_params = video_list * len(table_names)
- cursor.execute(union_query, all_params)
-
- else:
- # 获取所有历史记录中的视频
- union_queries = []
- for table_name in table_names:
- if max_videos > 0:
- union_queries.append(f"SELECT DISTINCT bvid, view_at FROM {table_name} WHERE bvid IS NOT NULL AND bvid != ''")
- else:
- union_queries.append(f"SELECT DISTINCT bvid, view_at FROM {table_name} WHERE bvid IS NOT NULL AND bvid != ''")
-
- if union_queries:
- union_query = " UNION ".join(union_queries)
- final_query = f"SELECT DISTINCT bvid FROM ({union_query}) ORDER BY view_at DESC"
- if max_videos > 0:
- final_query += f" LIMIT {max_videos}"
- cursor.execute(final_query)
-
- video_rows = cursor.fetchall()
- all_video_list = [row[0] for row in video_rows]
-
- if not all_video_list:
- return {
- "status": "success",
- "message": "没有找到需要获取详情的视频",
- "data": {
- "total_videos": 0,
- "success_count": 0,
- "error_count": 0,
- "results": [],
- "errors": []
- }
- }
-
- # 过滤掉已存在的视频和已知失效的视频,只获取需要处理的视频
- video_list = []
- existing_count = 0
- invalid_known_count = 0
-
- # 确保失效视频表存在
- try:
- create_invalid_videos_table()
- except Exception as _:
- pass
-
- if os.path.exists(DB_PATH):
- with sqlite3.connect(DB_PATH) as details_conn:
- details_cursor = details_conn.cursor()
-
- for bvid in all_video_list:
- # 检查视频是否已存在于详情数据库
- details_cursor.execute("SELECT 1 FROM video_base_info WHERE bvid = ? LIMIT 1", (bvid,))
- if details_cursor.fetchone() is not None:
- existing_count += 1
- continue
-
- # 检查是否为已知失效视频(保存在 video_library.db 的 invalid_videos 表)
- invalid_info = check_invalid_video(bvid)
- if invalid_info.get("is_invalid"):
- invalid_known_count += 1
- continue
-
- video_list.append(bvid)
- else:
- # 如果详情数据库不存在,则过滤掉已知失效视频
- for bvid in all_video_list:
- invalid_info = check_invalid_video(bvid)
- if invalid_info.get("is_invalid"):
- invalid_known_count += 1
- continue
- video_list.append(bvid)
-
- logger.info(
- f"历史记录中共有 {len(all_video_list)} 个视频,已存在: {existing_count} 个,已知失效: {invalid_known_count} 个,需要获取: {len(video_list)} 个"
- )
-
- if not video_list:
- return {
- "status": "success",
- "message": (
- f"所有视频详情都已存在或已知失效,无需重复获取。"
- f"历史记录总数: {len(all_video_list)},已存在: {existing_count},已知失效: {invalid_known_count}"
- ),
- "data": {
- "total_videos": 0,
- "success_count": 0,
- "error_count": 0,
- "results": [],
- "errors": [],
- "existing_count": existing_count,
- "invalid_known_count": invalid_known_count,
- "total_history_videos": len(all_video_list)
- }
- }
-
- # 检查是否已有任务在运行
- if video_details_progress["is_processing"]:
- raise HTTPException(status_code=400, detail="已有视频详情获取任务在运行中")
-
- # 重置并初始化进度状态
- reset_video_details_progress()
- video_details_progress.update({
- "is_processing": True,
- "total_videos": len(video_list),
- "start_time": time.time(),
- "last_update_time": time.time()
- })
-
- # 使用后台任务异步执行详情获取
- background_tasks.add_task(
- fetch_video_details_background_task,
- video_list,
- batch_size,
- use_sessdata
- )
-
- # 立即返回响应,让用户看到任务已启动
- return {
- "status": "success",
- "message": (
- f"视频详情获取已在后台启动。历史记录总数: {len(all_video_list)},"
- f"已存在: {existing_count},已知失效: {invalid_known_count},需要获取: {len(video_list)}"
- ),
- "data": {
- "is_processing": True,
- "total_videos": len(video_list),
- "processed_videos": 0,
- "success_count": 0,
- "failed_count": 0,
- "progress_percentage": 0,
- "elapsed_time": "0.00秒",
- "existing_count": existing_count,
- "invalid_known_count": invalid_known_count,
- "total_history_videos": len(all_video_list)
- }
- }
-
- except Exception as e:
- logger.error(f"批量获取视频详情失败: {e}")
- raise HTTPException(status_code=500, detail=f"批量获取视频详情失败: {str(e)}")
-
-
-@router.get("/stats", summary="获取视频详情统计信息")
-async def get_video_details_database_stats():
- """获取视频详情数据库统计信息"""
- try:
- # 确保数据库已初始化
- init_db()
- # 获取历史记录数据库路径
- history_db_path = os.path.join("output", "bilibili_history.db")
- # 获取视频详情数据库路径
- details_db_path = DB_PATH
-
- if not os.path.exists(history_db_path):
- raise HTTPException(status_code=404, detail="历史记录数据库不存在")
-
- stats = {}
-
- # 连接历史记录数据库
- with sqlite3.connect(history_db_path) as history_conn:
- history_cursor = history_conn.cursor()
-
- # 获取所有历史记录表名
- history_cursor.execute("""
- SELECT name FROM sqlite_master
- WHERE type='table' AND name LIKE 'bilibili_history_%'
- """)
- table_names = [row[0] for row in history_cursor.fetchall()]
-
- total_videos = 0
- if table_names:
- # 构建联合查询来获取所有年份的视频总数
- union_queries = []
- for table_name in table_names:
- union_queries.append(f"SELECT DISTINCT bvid FROM {table_name} WHERE bvid IS NOT NULL AND bvid != ''")
-
- if union_queries:
- union_query = " UNION ".join(union_queries)
- final_query = f"SELECT COUNT(*) FROM ({union_query})"
- history_cursor.execute(final_query)
- total_videos = history_cursor.fetchone()[0]
-
- stats["total_videos"] = total_videos
-
- # 如果视频详情数据库存在,获取详情统计
- if os.path.exists(details_db_path):
- with sqlite3.connect(details_db_path) as details_conn:
- details_cursor = details_conn.cursor()
-
- try:
- # 获取已获取详情的视频数
- details_cursor.execute("SELECT COUNT(DISTINCT bvid) FROM video_base_info")
- videos_with_details = details_cursor.fetchone()[0]
- stats["videos_with_details"] = videos_with_details
-
- # 获取UP主信息数量
- details_cursor.execute("SELECT COUNT(*) FROM uploader_info")
- uploader_count = details_cursor.fetchone()[0]
- stats["uploader_count"] = uploader_count
-
- # 获取视频标签数量
- details_cursor.execute("SELECT COUNT(*) FROM video_tags")
- tag_count = details_cursor.fetchone()[0]
- stats["tag_count"] = tag_count
-
- # 获取视频分P数量
- details_cursor.execute("SELECT COUNT(*) FROM video_pages")
- page_count = details_cursor.fetchone()[0]
- stats["page_count"] = page_count
- except sqlite3.OperationalError as e:
- # 如果表不存在,设置为0
- logger.warning(f"视频详情数据库表不存在: {e}")
- stats["videos_with_details"] = 0
- stats["uploader_count"] = 0
- stats["tag_count"] = 0
- stats["page_count"] = 0
-
- else:
- stats["videos_with_details"] = 0
- stats["uploader_count"] = 0
- stats["tag_count"] = 0
- stats["page_count"] = 0
-
- # 重新统计:区分失效与待获取(排除失效)
- try:
- create_invalid_videos_table()
- except Exception:
- pass
-
- # 收集历史记录中的全部 bvid
- history_bvids: set = set()
- with sqlite3.connect(history_db_path) as history_conn2:
- history_cursor2 = history_conn2.cursor()
- history_cursor2.execute("""
- SELECT name FROM sqlite_master
- WHERE type='table' AND name LIKE 'bilibili_history_%'
- """)
- table_names2 = [row[0] for row in history_cursor2.fetchall()]
- if table_names2:
- union_query2 = " UNION ".join(
- [f"SELECT DISTINCT bvid FROM {t} WHERE bvid IS NOT NULL AND bvid != ''" for t in table_names2]
- )
- history_cursor2.execute(union_query2)
- history_bvids = {row[0] for row in history_cursor2.fetchall()}
-
- # 已有详情的视频集合
- details_bvids: set = set()
- if os.path.exists(details_db_path):
- with sqlite3.connect(details_db_path) as details_conn2:
- details_cursor2 = details_conn2.cursor()
- try:
- details_cursor2.execute("SELECT DISTINCT bvid FROM video_base_info")
- details_bvids = {row[0] for row in details_cursor2.fetchall()}
- except sqlite3.OperationalError:
- details_bvids = set()
-
- # 已知失效的视频集合(来自 video_library.db/invalid_videos)
- invalid_bvids: set = set()
- error_type_stats = {}
- invalid_db_path = get_output_path("video_library.db")
- if os.path.exists(invalid_db_path):
- with sqlite3.connect(invalid_db_path) as inv_conn:
- inv_cursor = inv_conn.cursor()
- try:
- inv_cursor.execute("SELECT DISTINCT bvid FROM invalid_videos")
- invalid_all = {row[0] for row in inv_cursor.fetchall()}
- invalid_bvids = invalid_all & history_bvids
-
- if invalid_bvids:
- placeholders = ",".join(["?"] * len(invalid_bvids))
- inv_cursor.execute(
- f"SELECT error_type, COUNT(*) FROM invalid_videos WHERE bvid IN ({placeholders}) GROUP BY error_type",
- tuple(invalid_bvids)
- )
- error_type_stats = {row[0]: row[1] for row in inv_cursor.fetchall()}
- except sqlite3.OperationalError:
- invalid_bvids = set()
-
- # 精确计数(仅针对历史记录中的视频)
- videos_with_details_exact = len(details_bvids & history_bvids)
- stats["videos_with_details"] = videos_with_details_exact
-
- invalid_videos_count = len(invalid_bvids)
- stats["invalid_videos_count"] = invalid_videos_count
-
- pending_videos_count = max(stats["total_videos"] - videos_with_details_exact - invalid_videos_count, 0)
- stats["pending_videos_count"] = pending_videos_count
-
- # 将 videos_without_details 调整为“未获取且非失效”的真实待获取数
- stats["videos_without_details"] = pending_videos_count
-
- # 计算两种完成百分比
- if stats["total_videos"] > 0:
- stats["completion_percentage"] = round((videos_with_details_exact / stats["total_videos"]) * 100, 2)
- stats["overall_completion_percentage"] = round(((videos_with_details_exact + invalid_videos_count) / stats["total_videos"]) * 100, 2)
- else:
- stats["completion_percentage"] = 0
- stats["overall_completion_percentage"] = 0
-
- if error_type_stats:
- stats["invalid_error_type_stats"] = error_type_stats
-
- return {
- "status": "success",
- "message": "成功获取视频详情统计数据",
- "data": stats
- }
-
- except Exception as e:
- logger.error(f"获取视频详情统计数据失败: {e}")
- raise HTTPException(status_code=500, detail=f"获取统计数据失败: {str(e)}")
-
-
-@router.get("/database_stats", summary="获取数据库详细统计")
-async def get_database_stats():
- """获取数据库统计信息"""
- try:
- with sqlite3.connect(DB_PATH) as conn:
- conn.row_factory = sqlite3.Row
- cursor = conn.cursor()
-
- # 获取视频总数
- cursor.execute("SELECT COUNT(*) as total FROM video_base_info")
- total_videos = cursor.fetchone()["total"]
-
- # 获取UP主总数
- cursor.execute("SELECT COUNT(*) as total FROM uploader_info")
- total_uploaders = cursor.fetchone()["total"]
-
- # 获取标签总数
- cursor.execute("SELECT COUNT(DISTINCT tag_id) as total FROM video_tags")
- total_tags = cursor.fetchone()["total"]
-
- # 获取最近添加的10个视频
- cursor.execute("""
- SELECT bvid, title, owner_name, fetch_time
- FROM video_base_info
- ORDER BY fetch_time DESC
- LIMIT 10
- """)
- recent_videos = [dict(video) for video in cursor.fetchall()]
-
- return {
- "total_videos": total_videos,
- "total_uploaders": total_uploaders,
- "total_tags": total_tags,
- "recent_videos": recent_videos,
- "database_path": DB_PATH
- }
- except sqlite3.Error as e:
- logger.exception(f"获取数据库统计信息时出错: {e}")
- raise HTTPException(status_code=500, detail=f"获取数据库统计信息时出错: {str(e)}")
-
-
-@router.get("/uploaders", summary="获取UP主列表")
-async def list_uploaders(
- page: int = Query(1, description="页码"),
- per_page: int = Query(20, description="每页数量"),
- order_by: str = Query("fans", description="排序字段")
-):
- """获取UP主列表"""
- valid_order_fields = ["mid", "name", "fans", "archive_count", "like_num", "fetch_time"]
- if order_by not in valid_order_fields:
- order_by = "fans"
-
- try:
- with sqlite3.connect(DB_PATH) as conn:
- conn.row_factory = sqlite3.Row
- cursor = conn.cursor()
-
- # 计算总数
- cursor.execute("SELECT COUNT(*) as total FROM uploader_info")
- total = cursor.fetchone()["total"]
-
- # 查询数据
- offset = (page - 1) * per_page
- query = f"""
- SELECT * FROM uploader_info
- ORDER BY {order_by} DESC
- LIMIT ? OFFSET ?
- """
-
- cursor.execute(query, (per_page, offset))
- uploaders = [dict(uploader) for uploader in cursor.fetchall()]
-
- return {
- "total": total,
- "page": page,
- "per_page": per_page,
- "uploaders": uploaders
- }
- except sqlite3.Error as e:
- logger.exception(f"获取UP主列表时出错: {e}")
- raise HTTPException(status_code=500, detail=f"获取UP主列表时出错: {str(e)}")
-
-
-@router.get("/tags", summary="获取视频标签列表")
-async def list_tags(
- page: int = Query(1, description="页码"),
- per_page: int = Query(100, description="每页数量")
-):
- """获取标签列表"""
- try:
- with sqlite3.connect(DB_PATH) as conn:
- conn.row_factory = sqlite3.Row
- cursor = conn.cursor()
-
- # 计算总数
- cursor.execute("SELECT COUNT(DISTINCT tag_id) as total FROM video_tags")
- total = cursor.fetchone()["total"]
-
- # 查询数据
- offset = (page - 1) * per_page
- query = """
- SELECT tag_id, tag_name, COUNT(*) as video_count
- FROM video_tags
- GROUP BY tag_id, tag_name
- ORDER BY video_count DESC
- LIMIT ? OFFSET ?
- """
-
- cursor.execute(query, (per_page, offset))
- tags = [dict(tag) for tag in cursor.fetchall()]
-
- return {
- "total": total,
- "page": page,
- "per_page": per_page,
- "tags": tags
- }
- except sqlite3.Error as e:
- logger.exception(f"获取标签列表时出错: {e}")
- raise HTTPException(status_code=500, detail=f"获取标签列表时出错: {str(e)}")
-
-
-@router.get("/uploader/{mid}", summary="获取UP主详细信息")
-async def get_uploader_details(mid: int):
- """获取UP主详细信息及其视频列表"""
- try:
- with sqlite3.connect(DB_PATH) as conn:
- conn.row_factory = sqlite3.Row
- cursor = conn.cursor()
-
- # 获取UP主基本信息
- cursor.execute("SELECT * FROM uploader_info WHERE mid = ?", (mid,))
- uploader = cursor.fetchone()
-
- if not uploader:
- raise HTTPException(status_code=404, detail=f"未找到UP主 {mid} 的信息")
-
- uploader_dict = dict(uploader)
-
- # 获取UP主的视频列表
- cursor.execute("""
- SELECT * FROM video_base_info WHERE owner_mid = ? ORDER BY pubdate DESC LIMIT 50
- """, (mid,))
- videos = [dict(video) for video in cursor.fetchall()]
- uploader_dict["videos"] = videos
-
- return uploader_dict
- except sqlite3.Error as e:
- logger.exception(f"获取UP主 {mid} 详情时出错: {e}")
- raise HTTPException(status_code=500, detail=f"获取UP主详情时出错: {str(e)}")
-
-
-async def fetch_video_details_background_task(video_list: List[str], batch_size: int, use_sessdata: bool):
- """后台任务:批量获取视频详情,支持秒级进度更新和停止功能"""
- try:
- logger.info(f"开始后台批量获取 {len(video_list)} 个视频的超详细信息")
-
- # 初始化数据库(确保表结构存在)和失效视频表
- try:
- init_db()
- logger.info("数据库初始化完成")
- # 确保失效视频表准备就绪(位于 video_library.db)
- try:
- create_invalid_videos_table()
- logger.info("失效视频表已准备就绪")
- except Exception as ie:
- logger.warning(f"初始化失效视频表失败: {ie}")
- except Exception as e:
- logger.error(f"数据库初始化失败: {e}")
- raise
-
- # 随机打乱视频顺序,避免按顺序请求被检测
- random.shuffle(video_list)
-
- # 降低并发线程数,避免过高并发导致412错误
- max_workers = min(8, batch_size) # 进一步降低并发数
-
- # 获取配置和cookie
- config = load_config()
- cookies = config.get("cookies", {})
- cookie_str = "; ".join([f"{k}={v}" for k, v in cookies.items()]) if cookies else ""
- cookie_to_use = cookie_str if use_sessdata else ""
-
- # 分批处理视频,每批之间有延迟
- total_videos = len(video_list)
-
- # 按批次处理视频
- for i in range(0, total_videos, batch_size):
- batch_videos = video_list[i:i + batch_size]
- batch_num = i // batch_size + 1
- total_batches = (total_videos + batch_size - 1) // batch_size
-
- logger.info(f"开始处理第 {batch_num}/{total_batches} 批,包含 {len(batch_videos)} 个视频")
-
- # 检查是否被用户停止
- if video_details_progress["is_stopped"]:
- logger.info("用户停止了视频详情获取任务")
- break
-
- # 使用线程池处理当前批次的视频
- # 先过滤已知失效视频,避免无效请求
- work_bvids = []
- for b in batch_videos:
- inv = check_invalid_video(b)
- if inv.get("is_invalid"):
- logger.info(f"已知失效视频,跳过: {b} ({inv.get('error_type')})")
- video_details_progress["skipped_invalid_count"] += 1
- video_details_progress["processed_videos"] += 1
- video_details_progress["last_update_time"] = time.time()
- else:
- work_bvids.append(b)
-
- if not work_bvids:
- logger.info(f"第 {batch_num} 批全部为已知失效视频,跳过执行")
- continue
-
- with concurrent.futures.ThreadPoolExecutor(max_workers=max_workers) as executor:
- # 提交当前批次的任务(过滤后的列表)
- future_to_bvid = {
- executor.submit(get_video_detail_sync, bvid, cookie_to_use, use_sessdata): bvid
- for bvid in work_bvids
- }
-
- # 逐个处理完成的任务,实现秒级更新
- for future in concurrent.futures.as_completed(future_to_bvid):
- # 检查是否被用户停止
- if video_details_progress["is_stopped"]:
- logger.info("用户停止了视频详情获取任务")
- # 取消剩余的任务
- for remaining_future in future_to_bvid:
- if not remaining_future.done():
- remaining_future.cancel()
- break
-
- bvid = future_to_bvid[future]
- try:
- # 在处理前再次检查是否已存在(防止并发情况下的重复)
- with sqlite3.connect(DB_PATH) as check_conn:
- check_cursor = check_conn.cursor()
- check_cursor.execute("SELECT 1 FROM video_base_info WHERE bvid = ? LIMIT 1", (bvid,))
- if check_cursor.fetchone() is not None:
- logger.info(f"视频 {bvid} 已存在于数据库中,跳过")
- video_details_progress["skipped_invalid_count"] += 1
- video_details_progress["processed_videos"] += 1
- video_details_progress["last_update_time"] = time.time()
- continue
-
- result = future.result()
- if result and result.get("code") == 0:
- # 保存到数据库
- try:
- save_video_detail_to_db(result)
- video_details_progress["success_count"] += 1
- logger.info(f"成功获取并保存视频 {bvid} 的详情")
- except Exception as e:
- logger.error(f"保存视频 {bvid} 详情到数据库失败: {e}")
- video_details_progress["failed_count"] += 1
- video_details_progress["error_videos"].append(bvid)
- else:
- video_details_progress["failed_count"] += 1
- video_details_progress["error_videos"].append(bvid)
- error_msg = result.get("message", "未知错误") if result else "请求失败"
- logger.warning(f"获取视频 {bvid} 详情失败: {error_msg}")
- # 对永久性错误进行失效标记,避免下次重复获取
- try:
- code = result.get("code") if result else None
- if code in (-404, 62002):
- err_type = "not_found" if code == -404 else "invisible"
- err_obj = type("ErrorResponse", (), {
- "status": "error",
- "message": error_msg,
- "data": None,
- "bvid": bvid,
- "error_type": err_type,
- "error_code": code,
- "raw_response": result
- })
- save_invalid_video(err_obj)
- logger.info(f"已记录失效视频 {bvid} 到 invalid_videos,类型: {err_type}")
- except Exception as se:
- logger.warning(f"记录失效视频 {bvid} 时异常: {se}")
- except Exception as e:
- logger.error(f"获取视频 {bvid} 详情失败: {e}")
- video_details_progress["failed_count"] += 1
- video_details_progress["error_videos"].append(bvid)
-
- # 更新进度(每个视频完成后立即更新)
- video_details_progress["processed_videos"] += 1
- video_details_progress["last_update_time"] = time.time()
-
- # 添加小延迟,避免请求过快
- await asyncio.sleep(0.1 + random.random() * 0.2) # 0.1-0.3秒随机延迟
-
- # 批次间延迟(除了最后一批)
- if batch_num < total_batches and not video_details_progress["is_stopped"]:
- delay_time = 3 + random.random() * 2 # 3-5秒随机延迟
- logger.info(f"第 {batch_num} 批处理完成,等待 {delay_time:.1f} 秒后处理下一批")
- await asyncio.sleep(delay_time)
-
- # 任务完成或被停止
- video_details_progress["is_processing"] = False
- video_details_progress["is_complete"] = True
- video_details_progress["last_update_time"] = time.time()
-
- if video_details_progress["is_stopped"]:
- logger.info(f"视频详情获取被用户停止,已处理: {video_details_progress['processed_videos']}/{len(video_list)}")
- else:
- logger.info(f"批量获取视频详情完成,成功: {video_details_progress['success_count']}, 失败: {video_details_progress['failed_count']}")
-
- except Exception as e:
- logger.error(f"后台获取视频详情任务失败: {e}")
- video_details_progress["is_processing"] = False
- video_details_progress["is_complete"] = True
- video_details_progress["last_update_time"] = time.time()
-
-
-def reset_video_details_progress():
- """重置视频详情进度状态到初始状态"""
- global video_details_progress
- video_details_progress.update({
- "is_processing": False,
- "is_complete": False,
- "is_stopped": False,
- "total_videos": 0,
- "processed_videos": 0,
- "success_count": 0,
- "failed_count": 0,
- "error_videos": [],
- "skipped_invalid_count": 0,
- "start_time": 0,
- "last_update_time": 0
- })
-
-
-@router.post("/stop", summary="停止视频详情获取任务")
-async def stop_video_details_fetch():
- """停止视频详情获取任务"""
- try:
- if not video_details_progress["is_processing"]:
- # 如果没有正在运行的任务,直接重置状态
- reset_video_details_progress()
- return {
- "status": "success",
- "message": "当前没有正在运行的任务,已重置状态"
- }
-
- # 设置停止标志
- video_details_progress["is_stopped"] = True
- video_details_progress["last_update_time"] = time.time()
-
- logger.info("用户请求停止视频详情获取任务")
-
- # 等待一小段时间让后台任务处理停止信号
- await asyncio.sleep(0.5)
-
- # 强制重置状态到初始状态
- reset_video_details_progress()
-
- return {
- "status": "success",
- "message": "任务已停止,状态已重置",
- "data": {
- "is_processing": False,
- "is_complete": False,
- "is_stopped": False
- }
- }
- except Exception as e:
- logger.error(f"停止视频详情获取任务失败: {e}")
- raise HTTPException(status_code=500, detail=f"停止任务失败: {str(e)}")
-
-
-@router.post("/reset", summary="重置视频详情获取状态")
-async def reset_video_details_status():
- """重置视频详情获取状态到初始状态"""
- try:
- reset_video_details_progress()
- logger.info("用户手动重置了视频详情获取状态")
-
- return {
- "status": "success",
- "message": "状态已重置到初始状态",
- "data": {
- "is_processing": False,
- "is_complete": False,
- "is_stopped": False,
- "total_videos": 0,
- "processed_videos": 0,
- "success_count": 0,
- "failed_count": 0
- }
- }
- except Exception as e:
- logger.error(f"重置视频详情状态失败: {e}")
- raise HTTPException(status_code=500, detail=f"重置状态失败: {str(e)}")
-
-
-@router.get("/progress", summary="获取视频详情获取进度")
-async def get_video_details_progress(
- update_interval: float = Query(0.1, description="更新间隔,单位秒")
-):
- """获取视频详情获取进度的SSE流"""
- async def generate_progress():
- while True:
- # 计算进度百分比
- progress_percentage = 0
- if video_details_progress["total_videos"] > 0:
- progress_percentage = (video_details_progress["processed_videos"] / video_details_progress["total_videos"]) * 100
-
- # 计算已用时间
- elapsed_time = "0.00秒"
- if video_details_progress["start_time"] > 0:
- elapsed_seconds = time.time() - video_details_progress["start_time"]
- elapsed_time = f"{elapsed_seconds:.2f}秒"
-
- # 构建进度数据
- progress_data = {
- "is_processing": video_details_progress["is_processing"],
- "is_complete": video_details_progress["is_complete"],
- "is_stopped": video_details_progress["is_stopped"],
- "total_videos": video_details_progress["total_videos"],
- "processed_videos": video_details_progress["processed_videos"],
- "success_count": video_details_progress["success_count"],
- "failed_count": video_details_progress["failed_count"],
- "error_videos": video_details_progress["error_videos"],
- "skipped_invalid_count": video_details_progress["skipped_invalid_count"],
- "progress_percentage": progress_percentage,
- "elapsed_time": elapsed_time,
- "last_update_time": video_details_progress["last_update_time"]
- }
-
- # 发送数据
- yield f"data: {json.dumps(progress_data, ensure_ascii=False)}\n\n"
-
- # 如果任务完成或停止,发送最后一次数据后退出
- if video_details_progress["is_complete"] or video_details_progress["is_stopped"]:
- break
-
- # 等待指定的更新间隔
- await asyncio.sleep(update_interval)
-
- return StreamingResponse(
- generate_progress(),
- media_type="text/event-stream",
- headers={
- "Cache-Control": "no-cache",
- "Connection": "keep-alive",
- "Access-Control-Allow-Origin": "*",
- "Access-Control-Allow-Headers": "*"
- }
- )
diff --git a/routers/viewing_analytics.py b/routers/viewing_analytics.py
deleted file mode 100644
index 7c9e897..0000000
--- a/routers/viewing_analytics.py
+++ /dev/null
@@ -1,2585 +0,0 @@
-import json
-import os
-import sqlite3
-from datetime import datetime
-from typing import Optional, Dict, Any
-
-from fastapi import APIRouter, Query, HTTPException
-
-from scripts.utils import load_config, get_output_path
-
-router = APIRouter()
-config = load_config()
-
-def get_db():
- """获取数据库连接"""
- db_path = get_output_path(config['db_file'])
- return sqlite3.connect(db_path)
-
-def generate_continuity_insights(continuity_data: dict) -> dict:
- """生成连续性相关的洞察"""
- insights = {}
-
- # 连续性洞察
- max_streak = continuity_data['max_streak']
- current_streak = continuity_data['current_streak']
-
- # 根据连续天数生成评价
- streak_comment = ""
- if max_streak >= 30:
- streak_comment = "看来是B站的重度使用者"
- elif max_streak >= 14:
- streak_comment = "看来你对B站情有独钟呢!"
- else:
- streak_comment = "你的观看习惯比较随性自由。"
-
- insights['continuity'] = f"你最长连续观看B站达到了{max_streak}天,{streak_comment}目前已经连续观看了{current_streak}天。"
-
- return insights
-
-def analyze_viewing_continuity(cursor, table_name: str) -> dict:
- """分析观看习惯的连续性
-
- Args:
- cursor: 数据库游标
- table_name: 表名
-
- Returns:
- dict: 连续性分析结果
- """
- # 获取所有观看日期
- cursor.execute(f"""
- SELECT DISTINCT date(datetime(view_at + 28800, 'unixepoch')) as view_date
- FROM {table_name}
- ORDER BY view_date
- """)
- dates = [row[0] for row in cursor.fetchall()]
-
- # 计算连续观看天数
- max_streak = current_streak = 1
- longest_streak_start = longest_streak_end = current_streak_start = dates[0] if dates else None
-
- for i in range(1, len(dates)):
- date1 = datetime.strptime(dates[i-1], '%Y-%m-%d')
- date2 = datetime.strptime(dates[i], '%Y-%m-%d')
- if (date2 - date1).days == 1:
- current_streak += 1
- if current_streak > max_streak:
- max_streak = current_streak
- longest_streak_start = datetime.strptime(dates[i-max_streak+1], '%Y-%m-%d').strftime('%Y-%m-%d')
- longest_streak_end = dates[i]
- else:
- current_streak = 1
- current_streak_start = dates[i]
-
- return {
- 'max_streak': max_streak,
- 'longest_streak_period': {
- 'start': longest_streak_start,
- 'end': longest_streak_end
- },
- 'current_streak': current_streak,
- 'current_streak_start': current_streak_start
- }
-
-def analyze_time_investment(cursor, table_name: str) -> dict:
- """分析时间投入强度
-
- Args:
- cursor: 数据库游标
- table_name: 表名
-
- Returns:
- dict: 时间投入分析结果
- """
- cursor.execute(f"""
- SELECT
- date(datetime(view_at + 28800, 'unixepoch')) as view_date,
- COUNT(*) as video_count,
- SUM(CASE WHEN progress = -1 THEN duration ELSE progress END) as total_duration
- FROM {table_name}
- GROUP BY view_date
- ORDER BY total_duration DESC
- LIMIT 1
- """)
- max_duration_day = cursor.fetchone()
-
- cursor.execute(f"""
- SELECT
- AVG(daily_duration) as avg_duration
- FROM (
- SELECT
- date(datetime(view_at + 28800, 'unixepoch')) as view_date,
- SUM(CASE WHEN progress = -1 THEN duration ELSE progress END) as daily_duration
- FROM {table_name}
- GROUP BY view_date
- )
- """)
- avg_daily_duration = cursor.fetchone()[0]
-
- return {
- 'max_duration_day': {
- 'date': max_duration_day[0],
- 'video_count': max_duration_day[1],
- 'total_duration': max_duration_day[2]
- },
- 'avg_daily_duration': avg_daily_duration
- }
-
-def analyze_completion_rates(cursor, table_name: str) -> dict:
- """分析视频完成率"""
- # 获取表结构
- cursor.execute(f"PRAGMA table_info({table_name})")
- columns = {col[1]: idx for idx, col in enumerate(cursor.fetchall())}
-
- # 确保必要的列存在
- required_columns = ['duration', 'progress', 'author_name', 'author_mid', 'tag_name']
- for col in required_columns:
- if col not in columns:
- raise ValueError(f"Required column '{col}' not found in table {table_name}")
-
- cursor.execute(f"SELECT * FROM {table_name}")
- histories = cursor.fetchall()
-
- # 基础统计
- total_videos = len(histories)
- total_completion = 0
- fully_watched = 0
- not_started = 0
-
- # UP主统计
- author_stats = {}
- # 分区统计
- tag_stats = {}
- # 时长分布统计
- duration_stats = {
- "短视频(≤5分钟)": {"video_count": 0, "total_completion": 0, "fully_watched": 0, "average_completion_rate": 0},
- "中等视频(5-20分钟)": {"video_count": 0, "total_completion": 0, "fully_watched": 0, "average_completion_rate": 0},
- "长视频(>20分钟)": {"video_count": 0, "total_completion": 0, "fully_watched": 0, "average_completion_rate": 0}
- }
- # 完成率分布
- completion_distribution = {
- "0-10%": 0,
- "10-30%": 0,
- "30-50%": 0,
- "50-70%": 0,
- "70-90%": 0,
- "90-100%": 0
- }
-
- for history in histories:
- # 获取并转换数据类型
- try:
- duration = float(history[columns['duration']]) if history[columns['duration']] else 0
- progress = float(history[columns['progress']]) if history[columns['progress']] else 0
- author_name = history[columns['author_name']]
- author_mid = history[columns['author_mid']]
- tag_name = history[columns['tag_name']]
- except (ValueError, TypeError) as e:
- print(f"Warning: Failed to process record: {history}")
- continue
-
- # 计算完成率
- # 当progress为-1时表示已完全观看,计算为100%
- if progress == -1:
- completion_rate = 100
- else:
- completion_rate = (progress / duration * 100) if duration > 0 else 0
-
- total_completion += completion_rate
-
- # 统计完整观看和未开始观看
- if completion_rate >= 90: # 90%以上视为完整观看
- fully_watched += 1
- elif completion_rate == 0:
- not_started += 1
-
- # 更新完成率分布
- if completion_rate <= 10:
- completion_distribution["0-10%"] += 1
- elif completion_rate <= 30:
- completion_distribution["10-30%"] += 1
- elif completion_rate <= 50:
- completion_distribution["30-50%"] += 1
- elif completion_rate <= 70:
- completion_distribution["50-70%"] += 1
- elif completion_rate <= 90:
- completion_distribution["70-90%"] += 1
- else:
- completion_distribution["90-100%"] += 1
-
- # UP主统计
- if author_name and author_mid:
- if author_name not in author_stats:
- author_stats[author_name] = {
- "author_mid": author_mid,
- "video_count": 0,
- "total_completion": 0,
- "fully_watched": 0
- }
- stats = author_stats[author_name]
- stats["video_count"] += 1
- stats["total_completion"] += completion_rate
- if completion_rate >= 90:
- stats["fully_watched"] += 1
-
- # 分区统计
- if tag_name:
- if tag_name not in tag_stats:
- tag_stats[tag_name] = {
- "video_count": 0,
- "total_completion": 0,
- "fully_watched": 0
- }
- stats = tag_stats[tag_name]
- stats["video_count"] += 1
- stats["total_completion"] += completion_rate
- if completion_rate >= 90:
- stats["fully_watched"] += 1
-
- # 时长分布统计
- if duration <= 300: # 5分钟
- category = "短视频(≤5分钟)"
- elif duration <= 1200: # 20分钟
- category = "中等视频(5-20分钟)"
- else:
- category = "长视频(>20分钟)"
-
- stats = duration_stats[category]
- stats["video_count"] += 1
- stats["total_completion"] += completion_rate
- if completion_rate >= 90:
- stats["fully_watched"] += 1
-
- # 计算总体统计
- overall_stats = {
- "total_videos": total_videos,
- "average_completion_rate": round(total_completion / total_videos, 2) if total_videos > 0 else 0,
- "fully_watched_count": fully_watched,
- "not_started_count": not_started,
- "fully_watched_rate": round(fully_watched / total_videos * 100, 2) if total_videos > 0 else 0,
- "not_started_rate": round(not_started / total_videos * 100, 2) if total_videos > 0 else 0
- }
-
- # 计算各类视频的平均完成率和完整观看率
- for category, stats in duration_stats.items():
- if stats["video_count"] > 0:
- stats["average_completion_rate"] = round(stats["total_completion"] / stats["video_count"], 2)
- stats["fully_watched_rate"] = round(stats["fully_watched"] / stats["video_count"] * 100, 2)
- else:
- stats["average_completion_rate"] = 0
- stats["fully_watched_rate"] = 0
-
- # 计算UP主平均完成率和完整观看率,并按观看数量筛选和排序
- filtered_authors = {}
- for name, stats in author_stats.items():
- if stats["video_count"] >= 5: # 只保留观看数量>=5的UP主
- stats["average_completion_rate"] = round(stats["total_completion"] / stats["video_count"], 2)
- stats["fully_watched_rate"] = round(stats["fully_watched"] / stats["video_count"] * 100, 2)
- filtered_authors[name] = stats
-
- most_watched_authors = {}
- highest_completion_authors = {}
-
- # 计算分区平均完成率和完整观看率,并按观看数量筛选和排序
- filtered_tags = {}
- for tag, stats in tag_stats.items():
- if stats["video_count"] >= 5: # 只保留视频数量>=5的分区
- stats["average_completion_rate"] = round(stats["total_completion"] / stats["video_count"], 2)
- stats["fully_watched_rate"] = round(stats["fully_watched"] / stats["video_count"] * 100, 2)
- filtered_tags[tag] = stats
-
- top_tags = {}
-
- return {
- "overall_stats": overall_stats,
- "duration_based_stats": duration_stats,
- "completion_distribution": completion_distribution,
- "tag_completion_rates": top_tags,
- "most_watched_authors": most_watched_authors,
- "highest_completion_authors": highest_completion_authors
- }
-
-def generate_completion_insights(completion_data: dict) -> dict:
- """生成视频完成率相关的洞察"""
- insights = {}
-
- try:
- # 整体完成率洞察
- overall = completion_data.get("overall_stats", {})
- if overall:
- insights["overall_completion"] = (
- f"在观看的{overall.get('total_videos', 0)}个视频中,你平均观看完成率为{overall.get('average_completion_rate', 0)}%,"
- f"完整看完的视频占比{overall.get('fully_watched_rate', 0)}%,未开始观看的占比{overall.get('not_started_rate', 0)}%。"
- )
-
- # 视频时长偏好洞察
- duration_stats = completion_data.get("duration_based_stats", {})
- if duration_stats:
- valid_durations = [(k, v) for k, v in duration_stats.items()
- if v.get("video_count", 0) > 0 and v.get("average_completion_rate", 0) > 0]
- if valid_durations:
- max_completion_duration = max(valid_durations, key=lambda x: x[1].get("average_completion_rate", 0))
- insights["duration_preference"] = (
- f"你最容易看完的是{max_completion_duration[0]},平均完成率达到{max_completion_duration[1].get('average_completion_rate', 0)}%,"
- f"其中完整看完的视频占比{max_completion_duration[1].get('fully_watched_rate', 0)}%。"
- )
-
- # 分区兴趣洞察
- tag_rates = completion_data.get("tag_completion_rates", {})
- if tag_rates:
- valid_tags = [(k, v) for k, v in tag_rates.items()
- if v.get("video_count", 0) >= 5] # 只考虑观看数量>=5的分区
- if valid_tags:
- top_tag = max(valid_tags, key=lambda x: x[1].get("average_completion_rate", 0))
- insights["tag_completion"] = (
- f"在经常观看的分区中,你对{top_tag[0]}分区的视频最感兴趣,平均完成率达到{top_tag[1].get('average_completion_rate', 0)}%,"
- f"观看过{top_tag[1].get('video_count', 0)}个该分区的视频。"
- )
-
- # UP主偏好洞察
- most_watched = completion_data.get("most_watched_authors", {})
- if most_watched:
- top_watched = next(iter(most_watched.items()), None)
- if top_watched:
- insights["most_watched_author"] = (
- f"你观看最多的UP主是{top_watched[0]},观看了{top_watched[1].get('video_count', 0)}个视频,"
- f"平均完成率为{top_watched[1].get('average_completion_rate', 0)}%。"
- )
-
- highest_completion = completion_data.get("highest_completion_authors", {})
- if highest_completion and most_watched:
- top_completion = next(iter(highest_completion.items()), None)
- if top_completion and top_completion[0] != next(iter(most_watched.keys())):
- insights["highest_completion_author"] = (
- f"在经常观看的UP主中,你对{top_completion[0]}的视频完成度最高,"
- f"平均完成率达到{top_completion[1].get('average_completion_rate', 0)}%,"
- f"观看过{top_completion[1].get('video_count', 0)}个视频。"
- )
-
- except Exception as e:
- print(f"Error generating completion insights: {str(e)}")
- # 返回一个基础的洞察信息
- insights["basic_completion"] = "暂时无法生成详细的观看完成率分析。"
-
- return insights
-
-def analyze_video_watch_counts(cursor, table_name: str) -> dict:
- """分析视频观看次数"""
- # 获取表结构
- cursor.execute(f"PRAGMA table_info({table_name})")
- columns = {col[1]: idx for idx, col in enumerate(cursor.fetchall())}
-
- # 确保必要的列存在
- required_columns = ['title', 'bvid', 'duration', 'tag_name', 'author_name']
- for col in required_columns:
- if col not in columns:
- raise ValueError(f"Required column '{col}' not found in table {table_name}")
-
- # 获取视频观看次数统计
- cursor.execute(f"""
- SELECT
- title,
- bvid,
- duration,
- tag_name,
- author_name,
- COUNT(*) as watch_count,
- MIN(view_at) as first_view,
- MAX(view_at) as last_view
- FROM {table_name}
- WHERE bvid IS NOT NULL AND bvid != ''
- GROUP BY bvid
- HAVING COUNT(*) > 1
- ORDER BY watch_count DESC
- """)
-
- results = cursor.fetchall()
-
- # 处理统计结果
- most_watched_videos = []
- total_rewatched = 0
- total_videos = len(results)
- duration_distribution = {
- "短视频(≤5分钟)": 0,
- "中等视频(5-20分钟)": 0,
- "长视频(>20分钟)": 0
- }
- tag_distribution = {}
-
- for row in results:
- title = row[0]
- bvid = row[1]
- duration = float(row[2]) if row[2] else 0
- tag_name = row[3]
- author_name = row[4]
- watch_count = row[5]
- first_view = row[6]
- last_view = row[7]
-
- # 统计重复观看的视频时长分布
- if duration <= 300:
- duration_distribution["短视频(≤5分钟)"] += 1
- elif duration <= 1200:
- duration_distribution["中等视频(5-20分钟)"] += 1
- else:
- duration_distribution["长视频(>20分钟)"] += 1
-
-
- # 记录观看次数最多的视频
- if len(most_watched_videos) < 10:
- most_watched_videos.append({
- "title": title,
- "bvid": bvid,
- "duration": duration,
- "tag_name": tag_name,
- "author_name": author_name,
- "watch_count": watch_count,
- "first_view": first_view,
- "last_view": last_view,
- "avg_interval": (last_view - first_view) / (watch_count - 1) if watch_count > 1 else 0
- })
-
- total_rewatched += watch_count - 1
-
- # 获取总视频数
- cursor.execute(f"SELECT COUNT(DISTINCT bvid) FROM {table_name}")
- total_unique_videos = cursor.fetchone()[0]
-
- # 计算重复观看率
- rewatch_rate = round(total_videos / total_unique_videos * 100, 2)
-
- # 获取分区排名
- tag_ranking = sorted(
- tag_distribution.items(),
- key=lambda x: x[1],
- reverse=True
- )[:10]
-
- return {
- "rewatch_stats": {
- "total_rewatched_videos": total_videos,
- "total_unique_videos": total_unique_videos,
- "rewatch_rate": rewatch_rate,
- "total_rewatch_count": total_rewatched
- },
- "most_watched_videos": most_watched_videos,
- "duration_distribution": duration_distribution,
- "tag_distribution": dict(tag_ranking)
- }
-
-def generate_watch_count_insights(watch_count_data: dict) -> dict:
- """生成视频观看次数相关的洞察"""
- insights = {}
-
- try:
- # 重复观看统计洞察
- rewatch_stats = watch_count_data.get("rewatch_stats", {})
- total_videos = rewatch_stats.get('total_unique_videos', 0)
- rewatched_videos = rewatch_stats.get('total_rewatched_videos', 0)
- rewatch_rate = rewatch_stats.get('rewatch_rate', 0)
- total_rewatches = rewatch_stats.get('total_rewatch_count', 0)
-
- if rewatched_videos > 0:
- avg_watches_per_video = round(total_rewatches/rewatched_videos + 1, 1)
- insights["rewatch_overview"] = (
- f"在你观看的{total_videos}个视频中,有{rewatched_videos}个视频被重复观看,"
- f"重复观看率为{rewatch_rate}%。这些视频总共被额外观看了{total_rewatches}次,"
- f"平均每个重复观看的视频被看了{avg_watches_per_video}次。"
- )
- else:
- insights["rewatch_overview"] = f"在你观看的{total_videos}个视频中,暂时还没有重复观看的视频。"
-
- # 最多观看视频洞察
- most_watched = watch_count_data.get("most_watched_videos", [])
- if most_watched:
- top_videos = most_watched[:3] # 取前三
- top_video = top_videos[0]
-
- # 计算平均重看间隔(天)
- avg_interval_days = round(top_video.get('avg_interval', 0) / (24 * 3600), 1)
-
- if avg_interval_days > 0:
- insights["most_watched_videos"] = (
- f"你最喜欢的视频是{top_video.get('author_name', '未知作者')}的《{top_video.get('title', '未知视频')}》,"
- f"共观看了{top_video.get('watch_count', 0)}次,平均每{avg_interval_days}天就会重看一次。"
- )
- else:
- insights["most_watched_videos"] = (
- f"你最喜欢的视频是{top_video.get('author_name', '未知作者')}的《{top_video.get('title', '未知视频')}》,"
- f"共观看了{top_video.get('watch_count', 0)}次。"
- )
-
- if len(top_videos) > 1:
- other_favorites = [
- f"{v.get('author_name', '未知作者')}的《{v.get('title', '未知视频')}》({v.get('watch_count', 0)}次)"
- for v in top_videos[1:3]
- ]
- insights["most_watched_videos"] += f"紧随其后的是{' 和 '.join(other_favorites)}。"
-
- # 重复观看视频时长分布洞察
- duration_dist = watch_count_data.get("duration_distribution", {})
- if duration_dist:
- total_rewatched = sum(duration_dist.values())
- if total_rewatched > 0:
- duration_percentages = {
- k: round(v/total_rewatched * 100, 1)
- for k, v in duration_dist.items()
- }
- sorted_durations = sorted(
- duration_percentages.items(),
- key=lambda x: x[1],
- reverse=True
- )
-
- insights["duration_preference"] = (
- f"在重复观看的视频中,{sorted_durations[0][0]}最多,占比{sorted_durations[0][1]}%。"
- f"其次是{sorted_durations[1][0]}({sorted_durations[1][1]}%),"
- f"而{sorted_durations[2][0]}占比{sorted_durations[2][1]}%。"
- f"这表明你在重复观看时更偏好{sorted_durations[0][0].replace('视频', '')}的内容。"
- )
-
- # 重复观看分区分布洞察
- tag_dist = watch_count_data.get("tag_distribution", {})
- if tag_dist:
- total_tags = sum(tag_dist.values())
- if total_tags > 0:
- top_tags = sorted(tag_dist.items(), key=lambda x: x[1], reverse=True)[:3]
-
- tag_insights = []
- for tag, count in top_tags:
- percentage = round(count/total_tags * 100, 1)
- tag_insights.append(f"{tag}({count}个视频, {percentage}%)")
-
- insights["tag_preference"] = (
- f"你最常重复观看的内容类型是{tag_insights[0]}。"
- f"紧随其后的是{' 和 '.join(tag_insights[1:])}。"
- )
-
- # 生成总体观看行为总结
- if rewatched_videos > 0:
- insights["behavior_summary"] = (
- f"总的来说,你是一位{_get_rewatch_habit_description(rewatch_rate)}。"
- f"你特别喜欢重复观看{_get_preferred_content_type(tag_dist, duration_dist)}的内容。"
- )
- else:
- insights["behavior_summary"] = "总的来说,你喜欢探索新的内容,很少重复观看同一个视频。"
-
- except Exception as e:
- print(f"Error generating watch count insights: {str(e)}")
- insights["basic_watch_count"] = "暂时无法生成详细的重复观看分析。"
-
- return insights
-
-def _get_rewatch_habit_description(rewatch_rate: float) -> str:
- """根据重复观看率描述用户习惯"""
- if rewatch_rate < 2:
- return "喜欢探索新内容的观众"
- elif rewatch_rate < 5:
- return "对特定内容会重复观看的观众"
- else:
- return "经常重复观看喜欢内容的忠实观众"
-
-def _get_preferred_content_type(tag_dist: dict, duration_dist: dict) -> str:
- """根据分区和时长分布描述用户偏好"""
- if not tag_dist or not duration_dist:
- return "多样化"
-
- top_tag = max(tag_dist.items(), key=lambda x: x[1])[0]
- top_duration = max(duration_dist.items(), key=lambda x: x[1])[0]
-
- return f"{top_duration.replace('视频', '')}的{top_tag}"
-
-def get_available_years():
- """获取数据库中所有可用的年份"""
- conn = get_db()
- try:
- cursor = conn.cursor()
- cursor.execute("""
- SELECT name FROM sqlite_master
- WHERE type='table' AND name LIKE 'bilibili_history_%'
- ORDER BY name DESC
- """)
-
- years = []
- for (table_name,) in cursor.fetchall():
- try:
- year = int(table_name.split('_')[-1])
- years.append(year)
- except (ValueError, IndexError):
- continue
-
- return sorted(years, reverse=True)
- except sqlite3.Error as e:
- print(f"获取年份列表时发生错误: {e}")
- return []
- finally:
- if conn:
- conn.close()
-
-def validate_year_and_get_table(year: Optional[int]) -> tuple:
- """验证年份并返回表名和可用年份列表
-
- Args:
- year: 要验证的年份,None表示使用最新年份
-
- Returns:
- tuple: (table_name, target_year, available_years) 或 (None, None, error_response)
- """
- # 获取可用年份列表
- available_years = get_available_years()
- if not available_years:
- error_response = {
- "status": "error",
- "message": "未找到任何历史记录数据"
- }
- return None, None, error_response
-
- # 如果未指定年份,使用最新的年份;如果指定年份不存在,则自动回退到最新可用年份
- if year is None:
- target_year = available_years[0]
- elif year in available_years:
- target_year = year
- else:
- target_year = available_years[0]
-
- table_name = f"bilibili_history_{target_year}"
- return table_name, target_year, available_years
-
-@router.get("/monthly-stats", summary="获取月度观看统计分析")
-async def get_monthly_stats(
- year: Optional[int] = Query(None, description="要分析的年份,不传则使用当前年份"),
- use_cache: bool = Query(True, description="是否使用缓存,默认为True。如果为False则重新分析数据")
-):
- """获取月度观看统计分析
-
- Args:
- year: 要分析的年份,不传则使用当前年份
- use_cache: 是否使用缓存,默认为True。如果为False则重新分析数据
-
- Returns:
- dict: 包含月度观看统计分析的数据
- """
- # 验证年份并获取表名
- table_name, target_year, available_years = validate_year_and_get_table(year)
- if table_name is None:
- return available_years # 这里是错误响应
-
- conn = get_db()
- try:
- cursor = conn.cursor()
-
- # 如果启用缓存,尝试从缓存获取
- if use_cache:
- from .title_pattern_discovery import pattern_cache
- cached_response = pattern_cache.get_cached_patterns(table_name, 'monthly_stats')
- if cached_response:
- print(f"从缓存获取 {target_year} 年的月度统计分析数据")
- return cached_response
-
- print(f"开始分析 {target_year} 年的月度观看统计数据")
-
- # 月度观看统计
- cursor.execute(f"""
- SELECT
- strftime('%Y-%m', datetime(view_at + 28800, 'unixepoch')) as month,
- COUNT(*) as view_count
- FROM {table_name}
- GROUP BY month
- ORDER BY month
- """)
- monthly_stats = {row[0]: row[1] for row in cursor.fetchall()}
-
- # 计算总视频数和活跃天数
- cursor.execute(f"SELECT COUNT(*) FROM {table_name}")
- total_videos = cursor.fetchone()[0]
-
- cursor.execute(f"""
- SELECT COUNT(DISTINCT strftime('%Y-%m-%d', datetime(view_at + 28800, 'unixepoch')))
- FROM {table_name}
- """)
- active_days = cursor.fetchone()[0]
-
- # 计算平均每日观看数
- avg_daily_videos = round(total_videos / active_days, 1) if active_days > 0 else 0
-
- # 生成月度洞察
- monthly_insights = {}
-
- # 添加总体活动洞察
- if total_videos > 0 and active_days > 0:
- monthly_insights['overall_activity'] = f"今年以来,你在B站观看了{total_videos}个视频,平均每天观看{avg_daily_videos}个视频"
-
- if monthly_stats:
- max_month = max(monthly_stats.items(), key=lambda x: x[1])
- min_month = min(monthly_stats.items(), key=lambda x: x[1])
-
- # 计算月度趋势
- months = sorted(monthly_stats.keys())
- month_trend = ""
- if len(months) >= 2:
- first_month_count = monthly_stats[months[0]]
- last_month_count = monthly_stats[months[-1]]
- if last_month_count > first_month_count * 1.2:
- month_trend = "你在B站观看视频的热情正在逐月增长,看来你越来越喜欢B站了呢!"
- elif last_month_count < first_month_count * 0.8:
- month_trend = "最近你在B站的活跃度有所下降,可能是工作或学习变得更忙了吧。"
- else:
- month_trend = "你在B站的活跃度保持得很稳定,看来已经养成了良好的观看习惯。"
-
- monthly_insights['monthly_pattern'] = f"在{max_month[0]}月,你观看了{max_month[1]}个视频,是你最活跃的月份;而在{min_month[0]}月,观看量为{min_month[1]}个。{month_trend}"
-
- # 构建响应
- response = {
- "status": "success",
- "data": {
- "monthly_stats": monthly_stats,
- "total_videos": total_videos,
- "active_days": active_days,
- "avg_daily_videos": avg_daily_videos,
- "insights": monthly_insights,
- "year": target_year,
- "available_years": available_years
- }
- }
-
- # 更新缓存
- from .title_pattern_discovery import pattern_cache
- print(f"更新 {target_year} 年的月度统计分析数据缓存")
- pattern_cache.cache_patterns(table_name, 'monthly_stats', response)
-
- return response
-
- except Exception as e:
- raise HTTPException(status_code=500, detail=str(e))
- finally:
- if conn:
- conn.close()
-
-@router.get("/weekly-stats", summary="获取周度观看统计分析")
-async def get_weekly_stats(
- year: Optional[int] = Query(None, description="要分析的年份,不传则使用当前年份"),
- use_cache: bool = Query(True, description="是否使用缓存,默认为True。如果为False则重新分析数据")
-):
- """获取周度观看统计分析
-
- Args:
- year: 要分析的年份,不传则使用当前年份
- use_cache: 是否使用缓存,默认为True。如果为False则重新分析数据
-
- Returns:
- dict: 包含周度观看统计分析的数据
- """
- # 验证年份并获取表名
- table_name, target_year, available_years = validate_year_and_get_table(year)
- if table_name is None:
- return available_years # 这里是错误响应
-
- conn = get_db()
- try:
- cursor = conn.cursor()
-
- # 如果启用缓存,尝试从缓存获取
- if use_cache:
- from .title_pattern_discovery import pattern_cache
- cached_response = pattern_cache.get_cached_patterns(table_name, 'weekly_stats')
- if cached_response:
- print(f"从缓存获取 {target_year} 年的周度统计分析数据")
- return cached_response
-
- print(f"开始分析 {target_year} 年的周度观看统计数据")
-
- # 计算活跃天数(用于洞察生成)
- cursor.execute(f"""
- SELECT COUNT(DISTINCT strftime('%Y-%m-%d', datetime(view_at + 28800, 'unixepoch'))) as active_days
- FROM {table_name}
- """)
- active_days = cursor.fetchone()[0] or 0
-
- # 每周观看分布(0=周日,1-6=周一至周六)
- weekday_mapping = {'0': '周日', '1': '周一', '2': '周二', '3': '周三',
- '4': '周四', '5': '周五', '6': '周六'}
- # 初始化所有星期的默认值为0
- weekly_stats = {day: 0 for day in weekday_mapping.values()}
- cursor.execute(f"""
- SELECT
- strftime('%w', datetime(view_at + 28800, 'unixepoch')) as weekday,
- COUNT(*) as view_count
- FROM {table_name}
- GROUP BY weekday
- ORDER BY weekday
- """)
- # 更新有数据的星期的值
- for row in cursor.fetchall():
- weekly_stats[weekday_mapping[row[0]]] = row[1]
-
- # 季节性观看模式分析
- cursor.execute(f"""
- SELECT
- CASE
- WHEN CAST(strftime('%m', datetime(view_at + 28800, 'unixepoch')) AS INTEGER) IN (1,2,3) THEN '春季'
- WHEN CAST(strftime('%m', datetime(view_at + 28800, 'unixepoch')) AS INTEGER) IN (4,5,6) THEN '夏季'
- WHEN CAST(strftime('%m', datetime(view_at + 28800, 'unixepoch')) AS INTEGER) IN (7,8,9) THEN '秋季'
- WHEN CAST(strftime('%m', datetime(view_at + 28800, 'unixepoch')) AS INTEGER) IN (10,11,12) THEN '冬季'
- END as season,
- COUNT(*) as view_count,
- AVG(CASE WHEN progress = -1 THEN duration ELSE progress END) as avg_duration
- FROM {table_name}
- WHERE CAST(strftime('%m', datetime(view_at + 28800, 'unixepoch')) AS INTEGER) BETWEEN 1 AND 12
- GROUP BY season
- """)
- seasonal_patterns = {row[0]: {'view_count': row[1], 'avg_duration': row[2]} for row in cursor.fetchall()}
-
- # 生成周度统计洞察
- weekly_insights = {}
- if weekly_stats and active_days > 0:
- max_weekday = max(weekly_stats.items(), key=lambda x: x[1])
- min_weekday = min(weekly_stats.items(), key=lambda x: x[1])
-
- # 计算工作日和周末的平均值
- workday_avg = sum(weekly_stats[day] for day in ['周一', '周二', '周三', '周四', '周五']) / 5
- weekend_avg = sum(weekly_stats[day] for day in ['周六', '周日']) / 2
-
- if weekend_avg > workday_avg * 1.5:
- week_pattern = "你是一位周末党,倾向于在周末集中补番或观看视频。"
- elif workday_avg > weekend_avg:
- week_pattern = "工作日反而是你观看视频的主要时间,也许是通过B站来缓解工作压力?"
- else:
- week_pattern = "你的观看时间分布很均衡,不管是工作日还是周末都保持着适度的观看习惯。"
-
- weekly_insights['weekly_pattern'] = f"{week_pattern}其中{max_weekday[0]}是你最喜欢刷B站的日子,平均会看{round(max_weekday[1]/active_days*7, 1)}个视频;而{min_weekday[0]}的观看量最少。"
-
- # 构建响应
- response = {
- "status": "success",
- "data": {
- "weekly_stats": weekly_stats,
- "seasonal_patterns": seasonal_patterns,
- "insights": weekly_insights,
- "year": target_year,
- "available_years": available_years
- }
- }
-
- # 更新缓存
- from .title_pattern_discovery import pattern_cache
- print(f"更新 {target_year} 年的周度统计分析数据缓存")
- pattern_cache.cache_patterns(table_name, 'weekly_stats', response)
-
- return response
-
- except Exception as e:
- raise HTTPException(status_code=500, detail=str(e))
- finally:
- if conn:
- conn.close()
-
-@router.get("/time-slots", summary="获取时段观看分析")
-async def get_time_slots(
- year: Optional[int] = Query(None, description="要分析的年份,不传则使用当前年份"),
- use_cache: bool = Query(True, description="是否使用缓存,默认为True。如果为False则重新分析数据")
-):
- """获取时段观看分析
-
- Args:
- year: 要分析的年份,不传则使用当前年份
- use_cache: 是否使用缓存,默认为True。如果为False则重新分析数据
-
- Returns:
- dict: 包含时段观看分析的数据
- """
- # 验证年份并获取表名
- table_name, target_year, available_years = validate_year_and_get_table(year)
- if table_name is None:
- return available_years # 这里是错误响应
-
- conn = get_db()
- try:
- cursor = conn.cursor()
-
- # 如果启用缓存,尝试从缓存获取
- if use_cache:
- from .title_pattern_discovery import pattern_cache
- cached_response = pattern_cache.get_cached_patterns(table_name, 'time_slots')
- if cached_response:
- print(f"从缓存获取 {target_year} 年的时段分析数据")
- return cached_response
-
- print(f"开始分析 {target_year} 年的时段观看数据")
-
- # 每日时段分布(按小时统计)
- cursor.execute(f"""
- SELECT
- strftime('%H', datetime(view_at + 28800, 'unixepoch')) as hour,
- COUNT(*) as view_count
- FROM {table_name}
- GROUP BY hour
- ORDER BY hour
- """)
- daily_time_slots = {f"{int(row[0])}时": row[1] for row in cursor.fetchall()}
-
- # 最活跃时段TOP5
- cursor.execute(f"""
- SELECT
- strftime('%H', datetime(view_at + 28800, 'unixepoch')) as hour,
- COUNT(*) as view_count
- FROM {table_name}
- GROUP BY hour
- ORDER BY view_count DESC
- LIMIT 5
- """)
- peak_hours = [{
- "hour": f"{int(row[0])}时",
- "view_count": row[1]
- } for row in cursor.fetchall()]
-
- # 时间投入分析 - 使用已有的函数
- time_investment = analyze_time_investment(cursor, table_name)
-
- # 单日最大观看记录
- cursor.execute(f"""
- SELECT
- date(datetime(view_at + 28800, 'unixepoch')) as view_date,
- COUNT(*) as video_count
- FROM {table_name}
- GROUP BY view_date
- ORDER BY video_count DESC
- LIMIT 1
- """)
- max_daily_record = cursor.fetchone()
- max_daily_record = {
- 'date': max_daily_record[0],
- 'video_count': max_daily_record[1]
- }
-
- # 生成时段分析洞察
- time_slot_insights = {}
- if daily_time_slots and peak_hours:
- # 将一天分为几个时间段
- morning = sum(daily_time_slots.get(f"{i}时", 0) for i in range(5, 12))
- afternoon = sum(daily_time_slots.get(f"{i}时", 0) for i in range(12, 18))
- evening = sum(daily_time_slots.get(f"{i}时", 0) for i in range(18, 23))
- night = sum(daily_time_slots.get(f"{i}时", 0) for i in range(23, 24)) + sum(daily_time_slots.get(f"{i}时", 0) for i in range(0, 5))
-
- time_slots = [
- ("清晨和上午", morning),
- ("下午", afternoon),
- ("傍晚和晚上", evening),
- ("深夜", night)
- ]
- primary_slot = max(time_slots, key=lambda x: x[1])
-
- if primary_slot[0] == "深夜":
- time_advice = "熬夜看视频可能会影响健康,建议调整作息哦!"
- else:
- time_advice = "这个时间段的观看习惯很好,既不影响作息,也能享受视频带来的乐趣。"
-
- # 获取最高峰时段
- top_hour = peak_hours[0]["hour"] if peak_hours else "未知"
-
- time_slot_insights['time_preference'] = f"你最喜欢在{primary_slot[0]}观看B站视频,特别是{top_hour}达到观看高峰。{time_advice}"
-
- # 生成单日观看记录洞察
- if max_daily_record:
- time_slot_insights['daily_record'] = f"在{max_daily_record['date']}这一天,你创下了单日观看{max_daily_record['video_count']}个视频的记录!这可能是一个特别的日子,也许是在追番、学习或者在家放松的一天。"
-
- # 构建响应
- response = {
- "status": "success",
- "data": {
- "daily_time_slots": daily_time_slots,
- "peak_hours": peak_hours,
- "time_investment": time_investment,
- "max_daily_record": max_daily_record,
- "insights": time_slot_insights,
- "year": target_year,
- "available_years": available_years
- }
- }
-
- # 更新缓存
- from .title_pattern_discovery import pattern_cache
- print(f"更新 {target_year} 年的时段分析数据缓存")
- pattern_cache.cache_patterns(table_name, 'time_slots', response)
-
- return response
-
- except Exception as e:
- raise HTTPException(status_code=500, detail=str(e))
- finally:
- if conn:
- conn.close()
-
-@router.get("/continuity", summary="获取观看连续性分析")
-async def get_viewing_continuity(
- year: Optional[int] = Query(None, description="要分析的年份,不传则使用当前年份"),
- use_cache: bool = Query(True, description="是否使用缓存,默认为True。如果为False则重新分析数据")
-):
- """获取观看连续性分析
-
- Args:
- year: 要分析的年份,不传则使用当前年份
- use_cache: 是否使用缓存,默认为True。如果为False则重新分析数据
-
- Returns:
- dict: 包含观看连续性分析的数据
- """
- # 验证年份并获取表名
- table_name, target_year, available_years = validate_year_and_get_table(year)
- if table_name is None:
- return available_years # 这里是错误响应
-
- conn = get_db()
- try:
- cursor = conn.cursor()
-
- # 如果启用缓存,尝试从缓存获取
- if use_cache:
- from .title_pattern_discovery import pattern_cache
- cached_response = pattern_cache.get_cached_patterns(table_name, 'viewing_continuity')
- if cached_response:
- print(f"从缓存获取 {target_year} 年的观看连续性分析数据")
- return cached_response
-
- print(f"开始分析 {target_year} 年的观看连续性数据")
-
- # 分析观看连续性
- viewing_continuity = analyze_viewing_continuity(cursor, table_name)
-
- # 生成连续性洞察
- continuity_insights = generate_continuity_insights(viewing_continuity)
-
- # 构建响应
- response = {
- "status": "success",
- "data": {
- "viewing_continuity": viewing_continuity,
- "insights": continuity_insights,
- "year": target_year,
- "available_years": available_years
- }
- }
-
- # 更新缓存
- from .title_pattern_discovery import pattern_cache
- print(f"更新 {target_year} 年的观看连续性分析数据缓存")
- pattern_cache.cache_patterns(table_name, 'viewing_continuity', response)
-
- return response
-
- except Exception as e:
- raise HTTPException(status_code=500, detail=str(e))
- finally:
- if conn:
- conn.close()
-
-def analyze_viewing_details(cursor, table_name: str) -> dict:
- """分析更详细的观看行为,包括设备、总观看时长等
-
- Args:
- cursor: 数据库游标
- table_name: 表名
-
- Returns:
- dict: 详细观看行为分析结果
- """
- # 1. 计算总观看时长(根据progress字段)
- cursor.execute(f"""
- SELECT SUM(CASE WHEN progress = -1 THEN duration ELSE progress END) as total_watch_seconds
- FROM {table_name}
- WHERE progress IS NOT NULL
- """)
- total_seconds = cursor.fetchone()[0] or 0
- total_hours = round(total_seconds / 3600, 1)
-
- # 2. 计算观看B站的总天数
- cursor.execute(f"""
- SELECT COUNT(DISTINCT strftime('%Y-%m-%d', datetime(view_at + 28800, 'unixepoch'))) as total_days
- FROM {table_name}
- """)
- total_days = cursor.fetchone()[0] or 0
-
- # 3. 分析分区观看数据前10
- cursor.execute(f"""
- SELECT
- main_category,
- COUNT(*) as view_count,
- SUM(CASE WHEN progress = -1 THEN duration ELSE progress END) as total_progress
- FROM {table_name}
- WHERE main_category IS NOT NULL AND main_category != ''
- GROUP BY main_category
- ORDER BY view_count DESC
- LIMIT 10
- """)
- category_stats = [
- {
- "category": row[0],
- "view_count": row[1],
- "watch_hours": round((row[2] or 0) / 3600, 1)
- } for row in cursor.fetchall()
- ]
-
- # 4. 年度挚爱UP主
- cursor.execute(f"""
- SELECT
- author_mid,
- author_name,
- COUNT(*) as view_count,
- SUM(CASE WHEN progress = -1 THEN duration ELSE progress END) as total_progress
- FROM {table_name}
- WHERE author_mid IS NOT NULL
- GROUP BY author_mid
- ORDER BY view_count DESC
- LIMIT 10
- """)
- favorite_up_stats = [
- {
- "mid": row[0],
- "name": row[1],
- "view_count": row[2],
- "watch_hours": round((row[3] or 0) / 3600, 1)
- } for row in cursor.fetchall()
- ]
-
- # 5. 寻找深夜观看记录
- # 第一步:创建临时表存储深夜观看记录
- cursor.execute(f"""
- CREATE TEMPORARY TABLE IF NOT EXISTS temp_night_views AS
- SELECT
- view_at,
- author_name,
- title,
- strftime('%H', datetime(view_at + 28800, 'unixepoch')) as hour,
- strftime('%M', datetime(view_at + 28800, 'unixepoch')) as minute,
- -- 将凌晨时间(00:00-05:00)的日期调整为前一天
- CASE
- WHEN strftime('%H', datetime(view_at + 28800, 'unixepoch')) < '05' THEN
- date(datetime(view_at + 28800 - 86400, 'unixepoch'))
- ELSE
- date(datetime(view_at + 28800, 'unixepoch'))
- END as adjusted_date,
- -- 计算小时+分钟的浮点数时间
- CASE
- WHEN strftime('%H', datetime(view_at + 28800, 'unixepoch')) < '05' THEN
- CAST(strftime('%H', datetime(view_at + 28800, 'unixepoch')) AS REAL) + 24
- ELSE
- CAST(strftime('%H', datetime(view_at + 28800, 'unixepoch')) AS REAL)
- END + CAST(strftime('%M', datetime(view_at + 28800, 'unixepoch')) AS REAL)/100.0 as hour_with_minute
- FROM {table_name}
- WHERE
- strftime('%H', datetime(view_at + 28800, 'unixepoch')) >= '23' OR
- strftime('%H', datetime(view_at + 28800, 'unixepoch')) < '05'
- """)
-
- # 第二步:创建临时表存储每天最晚的观看时间
- cursor.execute("""
- CREATE TEMPORARY TABLE IF NOT EXISTS temp_latest_per_day AS
- SELECT
- adjusted_date,
- MAX(hour_with_minute) as latest_hour_with_minute
- FROM temp_night_views
- GROUP BY adjusted_date
- """)
-
- # 第三步:查询每天最晚的观看记录
- cursor.execute("""
- SELECT
- t.adjusted_date as date,
- strftime('%H:%M', datetime(t.view_at + 28800, 'unixepoch')) as time,
- t.author_name,
- t.title,
- t.hour,
- t.minute,
- t.hour_with_minute
- FROM temp_night_views t
- JOIN temp_latest_per_day l ON
- t.adjusted_date = l.adjusted_date AND
- t.hour_with_minute = l.latest_hour_with_minute
- ORDER BY t.hour_with_minute DESC
- LIMIT 10
- """)
-
- late_night_views = [
- {
- "date": row[0],
- "time": row[1],
- "author": row[2],
- "title": row[3],
- "hour": int(row[4]),
- "minute": row[5],
- "hour_with_minute": float(row[6])
- } for row in cursor.fetchall()
- ]
-
- # 清理临时表
- cursor.execute("DROP TABLE IF EXISTS temp_night_views")
- cursor.execute("DROP TABLE IF EXISTS temp_latest_per_day")
-
- # 6. 各时间段的活跃天数百分比
- cursor.execute(f"""
- SELECT
- CASE
- WHEN strftime('%H', datetime(view_at + 28800, 'unixepoch')) BETWEEN '05' AND '11' THEN '上午'
- WHEN strftime('%H', datetime(view_at + 28800, 'unixepoch')) BETWEEN '12' AND '17' THEN '下午'
- WHEN strftime('%H', datetime(view_at + 28800, 'unixepoch')) BETWEEN '18' AND '22' THEN '晚上'
- ELSE '深夜'
- END as time_slot,
- COUNT(DISTINCT strftime('%Y-%m-%d', datetime(view_at + 28800, 'unixepoch'))) as active_days
- FROM {table_name}
- GROUP BY time_slot
- """)
- time_slot_days = {}
- for row in cursor.fetchall():
- time_slot_days[row[0]] = {
- "days": row[1],
- "percentage": round(row[1] / total_days * 100, 1) if total_days > 0 else 0
- }
-
- # 7. 查询最常用的设备信息(如果有)
- cursor.execute(f"""
- SELECT
- CASE
- WHEN dt IN (1, 3, 5, 7) THEN '手机'
- WHEN dt = 2 THEN '网页'
- WHEN dt IN (4, 6) THEN '平板'
- WHEN dt = 33 THEN '电视'
- ELSE '其他'
- END as platform,
- COUNT(*) as count
- FROM {table_name}
- GROUP BY platform
- ORDER BY count DESC
- LIMIT 3
- """)
- devices = [{"name": row[0], "count": row[1]} for row in cursor.fetchall()]
-
- return {
- "total_watch_hours": total_hours,
- "total_days": total_days,
- "top_categories": category_stats,
- "favorite_up_users": favorite_up_stats,
- "late_night_views": late_night_views,
- "time_slot_activity": time_slot_days,
- "devices": devices
- }
-
-def generate_viewing_report(viewing_details: dict) -> dict:
- """根据观看数据生成综合报告和亮点
-
- Args:
- viewing_details: 观看详细数据
-
- Returns:
- dict: 包含各种总结语句的报告
- """
- report = {}
-
- # 1. 总观看时长和天数总结
- report["total_summary"] = f"和B站共度的{viewing_details['total_days']}天里,你观看超过{viewing_details['total_watch_hours']}小时的内容"
-
- # 2. 时间段访问情况
- time_slots = viewing_details["time_slot_activity"]
- max_slot = max(time_slots.items(), key=lambda x: x[1]["percentage"]) if time_slots else None
-
- if max_slot:
- report["time_slot_summary"] = f"{max_slot[0]}时段访问B站天数超过{max_slot[1]['percentage']}%"
-
- # 3. 深夜观看记录
- if viewing_details["late_night_views"]:
- # late_night_views已按照最晚时间排序,首条记录是最晚的
- latest_view = viewing_details["late_night_views"][0]
- report["late_night_summary"] = f"{latest_view['date']}你迟迟不肯入睡,{latest_view['time']}还在看{latest_view['author']}的《{latest_view['title']}》"
-
- # 4. 分区观看总结
- if viewing_details["top_categories"]:
- top_category = viewing_details["top_categories"][0]
- report["category_summary"] = f"你最喜欢的分区是{top_category['category']},共观看{top_category['view_count']}个视频,时长{top_category['watch_hours']}小时"
-
- # 5. 年度挚爱UP总结
- if viewing_details["favorite_up_users"]:
- top_up = viewing_details["favorite_up_users"][0]
- report["up_summary"] = f"年度挚爱UP主是{top_up['name']},共观看{top_up['view_count']}个视频,时长{top_up['watch_hours']}小时"
-
- # 6. 设备使用总结
- if viewing_details["devices"]:
- top_device = viewing_details["devices"][0]
- report["device_summary"] = f"你最常用的观看设备是{top_device['name']},共使用{top_device['count']}次"
-
- return report
-
-@router.get("/viewing/", summary="获取观看行为数据分析")
-async def get_viewing_details(
- year: Optional[int] = Query(None, description="要分析的年份,不传则使用当前年份"),
- use_cache: bool = Query(True, description="是否使用缓存,默认为True。如果为False则重新分析数据")
-):
- """获取观看行为数据分析
-
- Args:
- year: 要分析的年份,不传则使用当前年份
- use_cache: 是否使用缓存,默认为True。如果为False则重新分析数据
-
- Returns:
- dict: 包含观看行为分析的详细数据和总结报告
- """
- # 验证年份并获取表名
- table_name, target_year, available_years = validate_year_and_get_table(year)
- if table_name is None:
- return available_years # 这里是错误响应
-
- conn = get_db()
- try:
- cursor = conn.cursor()
-
- # 如果启用缓存,尝试从缓存获取完整响应
- if use_cache:
- from .title_pattern_discovery import pattern_cache
- cached_response = pattern_cache.get_cached_patterns(table_name, 'viewing_details')
- if cached_response:
- print(f"从缓存获取 {target_year} 年的观看行为分析数据")
- return cached_response
-
- print(f"开始分析 {target_year} 年的观看行为数据")
-
- # 获取详细观看数据
- viewing_details = analyze_viewing_details(cursor, table_name)
-
- # 生成综合报告
- viewing_report = generate_viewing_report(viewing_details)
-
- # 构建完整响应
- response = {
- "status": "success",
- "data": {
- "details": viewing_details,
- "report": viewing_report,
- "year": target_year,
- "available_years": available_years
- }
- }
-
- # 无论是否启用缓存,都更新缓存数据
- from .title_pattern_discovery import pattern_cache
- print(f"更新 {target_year} 年的观看行为分析数据缓存")
- pattern_cache.cache_patterns(table_name, 'viewing_details', response)
-
- return response
-
- except Exception as e:
- raise HTTPException(status_code=500, detail=str(e))
-
-@router.get("/watch-counts", summary="获取重复观看分析")
-async def get_viewing_watch_counts(
- year: Optional[int] = Query(None, description="要分析的年份,不传则使用当前年份"),
- use_cache: bool = Query(True, description="是否使用缓存,默认为True。如果为False则重新分析数据")
-):
- """获取用户重复观看分析
-
- Args:
- year: 要分析的年份,不传则使用当前年份
- use_cache: 是否使用缓存,默认为True。如果为False则重新分析数据
-
- Returns:
- dict: 包含重复观看分析结果的响应
- """
- # 验证年份并获取表名
- table_name, target_year, available_years = validate_year_and_get_table(year)
- if table_name is None:
- return available_years # 这里是错误响应
-
- conn = get_db()
- try:
- cursor = conn.cursor()
-
- # 如果启用缓存,尝试从缓存获取
- if use_cache:
- from .title_pattern_discovery import pattern_cache
- cached_response = pattern_cache.get_cached_patterns(table_name, 'watch_counts')
- if cached_response:
- print(f"从缓存获取 {target_year} 年的重复观看分析数据")
- return cached_response
-
- print(f"开始分析 {target_year} 年的重复观看数据")
-
- # 获取重复观看分析数据
- watch_count_data = analyze_video_watch_counts(cursor, table_name)
-
- # 生成重复观看洞察
- watch_count_insights = generate_watch_count_insights(watch_count_data)
-
- # 构建响应
- response = {
- "status": "success",
- "data": {
- "watch_counts": watch_count_data,
- "insights": watch_count_insights,
- "year": target_year,
- "available_years": available_years
- }
- }
-
- # 更新缓存
- from .title_pattern_discovery import pattern_cache
- print(f"更新 {target_year} 年的重复观看分析数据缓存")
- pattern_cache.cache_patterns(table_name, 'watch_counts', response)
-
- return response
-
- except Exception as e:
- raise HTTPException(status_code=500, detail=str(e))
- finally:
- if conn:
- conn.close()
-
-@router.get("/completion-rates", summary="获取视频完成率分析")
-async def get_viewing_completion_rates(
- year: Optional[int] = Query(None, description="要分析的年份,不传则使用当前年份"),
- use_cache: bool = Query(True, description="是否使用缓存,默认为True。如果为False则重新分析数据")
-):
- """获取用户视频完成率分析
-
- Args:
- year: 要分析的年份,不传则使用当前年份
- use_cache: 是否使用缓存,默认为True。如果为False则重新分析数据
-
- Returns:
- dict: 包含视频完成率分析结果的响应
- """
- # 验证年份并获取表名
- table_name, target_year, available_years = validate_year_and_get_table(year)
- if table_name is None:
- return available_years # 这里是错误响应
-
- conn = get_db()
- try:
- cursor = conn.cursor()
-
- # 如果启用缓存,尝试从缓存获取
- if use_cache:
- from .title_pattern_discovery import pattern_cache
- cached_response = pattern_cache.get_cached_patterns(table_name, 'completion_rates')
- if cached_response:
- print(f"从缓存获取 {target_year} 年的视频完成率分析数据")
- return cached_response
-
- print(f"开始分析 {target_year} 年的视频完成率数据")
-
- # 获取视频完成率分析数据
- completion_data = analyze_completion_rates(cursor, table_name)
-
- # 生成完成率洞察
- completion_insights = generate_completion_insights(completion_data)
-
- # 构建响应
- response = {
- "status": "success",
- "data": {
- "completion_rates": completion_data,
- "insights": completion_insights,
- "year": target_year,
- "available_years": available_years
- }
- }
-
- # 更新缓存
- from .title_pattern_discovery import pattern_cache
- print(f"更新 {target_year} 年的视频完成率分析数据缓存")
- pattern_cache.cache_patterns(table_name, 'completion_rates', response)
-
- return response
-
- except Exception as e:
- raise HTTPException(status_code=500, detail=str(e))
- finally:
- if conn:
- conn.close()
-
-def analyze_author_completion_rates(cursor, table_name: str) -> dict:
- """专门分析UP主完成率数据,使用智能综合评分算法"""
- # 获取表结构
- cursor.execute(f"PRAGMA table_info({table_name})")
- columns = {col[1]: idx for idx, col in enumerate(cursor.fetchall())}
-
- # 确保必要的列存在
- required_columns = ['duration', 'progress', 'author_name', 'author_mid']
- for col in required_columns:
- if col not in columns:
- raise ValueError(f"Required column '{col}' not found in table {table_name}")
-
- # 获取所有历史记录
- cursor.execute(f"SELECT * FROM {table_name}")
- histories = cursor.fetchall()
-
- author_stats = {}
-
- for history in histories:
- # 获取并转换数据类型
- try:
- duration = float(history[columns['duration']]) if history[columns['duration']] else 0
- progress = float(history[columns['progress']]) if history[columns['progress']] else 0
- author_name = history[columns['author_name']]
- author_mid = history[columns['author_mid']]
- except (ValueError, TypeError):
- continue
-
- # 计算完成率
- if progress == -1:
- completion_rate = 100
- else:
- completion_rate = (progress / duration * 100) if duration > 0 else 0
-
- # UP主统计
- if author_name and author_mid:
- if author_name not in author_stats:
- author_stats[author_name] = {
- "author_mid": author_mid,
- "video_count": 0,
- "total_completion": 0,
- "fully_watched": 0
- }
- stats = author_stats[author_name]
- stats["video_count"] += 1
- stats["total_completion"] += completion_rate
- if completion_rate >= 90:
- stats["fully_watched"] += 1
-
- # 计算UP主平均完成率和完整观看率,并按观看数量筛选
- filtered_authors = {}
- for name, stats in author_stats.items():
- if stats["video_count"] >= 5: # 只保留观看数量>=5的UP主
- stats["average_completion_rate"] = round(stats["total_completion"] / stats["video_count"], 2)
- stats["fully_watched_rate"] = round(stats["fully_watched"] / stats["video_count"] * 100, 2)
- filtered_authors[name] = stats
-
- # 使用新的智能评分算法
- scored_authors = calculate_comprehensive_author_scores(filtered_authors)
-
- return {
- "most_watched_authors": scored_authors["most_watched_authors"],
- "highest_completion_authors": scored_authors["highest_completion_authors"],
- "most_valuable_authors": scored_authors["most_valuable_authors"],
- "potential_authors": scored_authors["potential_authors"]
- }
-
-def calculate_comprehensive_author_scores(authors_data: dict) -> dict:
- """计算UP主综合评分并分类"""
- import math
-
- if not authors_data:
- return {
- "most_watched_authors": {},
- "highest_completion_authors": {},
- "most_valuable_authors": {},
- "potential_authors": {}
- }
-
- # 计算观看数量的最大值和最小值,用于标准化
- view_counts = [stats["video_count"] for stats in authors_data.values()]
- max_views = max(view_counts)
- min_views = min(view_counts)
- view_range = max_views - min_views if max_views > min_views else 1
-
- # 为每个UP主计算综合评分
- scored_authors = {}
- for name, stats in authors_data.items():
- # 1. 观看数量标准化 (0-100)
- normalized_views = (stats["video_count"] - min_views) / view_range * 100
-
- # 2. 置信度计算 (避免小样本偏差)
- confidence = min(1.0, stats["video_count"] / 20)
-
- # 3. 综合评分计算
- # 权重: 观看数量25%, 完成率50%, 完整观看率25%
- comprehensive_score = (
- normalized_views * 0.25 +
- stats["average_completion_rate"] * 0.5 +
- stats["fully_watched_rate"] * 0.25
- ) * confidence
-
- # 4. 计算特殊指标
- # 忠诚度指标:观看数量 * 完成率的平方根
- loyalty_score = stats["video_count"] * math.sqrt(stats["average_completion_rate"] / 100)
-
- # 质量指标:完成率和完整观看率的加权平均
- quality_score = stats["average_completion_rate"] * 0.7 + stats["fully_watched_rate"] * 0.3
-
- scored_authors[name] = {
- **stats,
- "comprehensive_score": round(comprehensive_score, 2),
- "loyalty_score": round(loyalty_score, 2),
- "quality_score": round(quality_score, 2),
- "confidence": round(confidence, 2),
- "normalized_views": round(normalized_views, 2)
- }
-
- # 按不同维度排序分类
- # 1. 观看次数最多的UP主 (传统排序)
- most_watched_authors = dict(sorted(
- scored_authors.items(),
- key=lambda x: x[1]["video_count"],
- reverse=True
- )[:10])
-
- # 2. 完成率最高的UP主 (传统排序)
- highest_completion_authors = dict(sorted(
- scored_authors.items(),
- key=lambda x: x[1]["average_completion_rate"],
- reverse=True
- )[:10])
-
- # 3. 最有价值UP主 (综合评分最高)
- most_valuable_authors = dict(sorted(
- scored_authors.items(),
- key=lambda x: x[1]["comprehensive_score"],
- reverse=True
- )[:10])
-
- # 4. 潜力UP主 (高质量但观看数量不是最多的)
- potential_authors = {}
- for name, stats in scored_authors.items():
- # 筛选条件:质量评分>85,但观看数量不在前3
- if (stats["quality_score"] > 85 and
- stats["video_count"] < sorted(view_counts, reverse=True)[min(2, len(view_counts)-1)]):
- potential_authors[name] = stats
-
- # 潜力UP主按质量评分排序,取前5
- potential_authors = dict(sorted(
- potential_authors.items(),
- key=lambda x: x[1]["quality_score"],
- reverse=True
- )[:5])
-
- return {
- "most_watched_authors": most_watched_authors,
- "highest_completion_authors": highest_completion_authors,
- "most_valuable_authors": most_valuable_authors,
- "potential_authors": potential_authors
- }
-
-def generate_author_completion_insights(author_data: dict) -> dict:
- """生成UP主完成率相关的智能洞察"""
- insights = {}
-
- try:
- # 1. 最有价值UP主洞察(综合评分最高)
- most_valuable = author_data.get("most_valuable_authors", {})
- if most_valuable:
- top_valuable = next(iter(most_valuable.items()), None)
- if top_valuable:
- name, stats = top_valuable
- insights["most_valuable_author"] = (
- f"综合来看,{name}是你最有价值的UP主,观看了{stats.get('video_count', 0)}个视频,"
- f"平均完成率高达{stats.get('average_completion_rate', 0)}%,"
- f"完整观看率{stats.get('fully_watched_rate', 0)}%,综合评分{stats.get('comprehensive_score', 0)}分。"
- )
-
- # 2. 观看最多UP主洞察(如果与最有价值UP主不同)
- most_watched = author_data.get("most_watched_authors", {})
- if most_watched:
- top_watched = next(iter(most_watched.items()), None)
- if top_watched and (not most_valuable or top_watched[0] != next(iter(most_valuable.keys()))):
- name, stats = top_watched
- insights["most_watched_author"] = (
- f"你观看最多的UP主是{name},观看了{stats.get('video_count', 0)}个视频,"
- f"平均完成率为{stats.get('average_completion_rate', 0)}%,是你的喜爱观看对象。"
- )
-
- # 3. 生成综合观看行为分析
- if most_valuable:
- total_authors = len(author_data.get("most_watched_authors", {}))
- insights["viewing_behavior_summary"] = (
- f"在你经常观看的{total_authors}位UP主中,你展现出了很好的内容鉴赏能力,"
- f"特别偏爱高质量内容,对喜欢的UP主有很高的完成度和喜爱度。"
- )
-
- except Exception as e:
- print(f"Error generating author completion insights: {str(e)}")
- insights["basic_author"] = "暂时无法生成详细的UP主完成率分析。"
-
- return insights
-
-@router.get("/author-completion", summary="获取UP主完成率分析")
-async def get_viewing_author_completion(
- year: Optional[int] = Query(None, description="要分析的年份,不传则使用当前年份"),
- use_cache: bool = Query(True, description="是否使用缓存,默认为True。如果为False则重新分析数据")
-):
- """获取UP主完成率分析
-
- Args:
- year: 要分析的年份,不传则使用当前年份
- use_cache: 是否使用缓存,默认为True。如果为False则重新分析数据
-
- Returns:
- dict: 包含UP主完成率分析结果的响应
- """
- # 验证年份并获取表名
- table_name, target_year, available_years = validate_year_and_get_table(year)
- if table_name is None:
- return available_years # 这里是错误响应
-
- conn = get_db()
- try:
- cursor = conn.cursor()
-
- # 如果启用缓存,尝试从缓存获取
- if use_cache:
- from .title_pattern_discovery import pattern_cache
- cached_response = pattern_cache.get_cached_patterns(table_name, 'author_completion')
- if cached_response:
- print(f"从缓存获取 {target_year} 年的UP主完成率分析数据")
- return cached_response
-
- print(f"开始分析 {target_year} 年的UP主完成率数据")
-
- # 获取UP主完成率分析数据
- author_data = analyze_author_completion_rates(cursor, table_name)
-
- # 生成UP主完成率洞察
- author_insights = generate_author_completion_insights(author_data)
-
- # 构建响应
- response = {
- "status": "success",
- "data": {
- "completion_rates": author_data,
- "insights": author_insights,
- "year": target_year,
- "available_years": available_years
- }
- }
-
- # 更新缓存
- from .title_pattern_discovery import pattern_cache
- print(f"更新 {target_year} 年的UP主完成率分析数据缓存")
- pattern_cache.cache_patterns(table_name, 'author_completion', response)
-
- return response
-
- except Exception as e:
- raise HTTPException(status_code=500, detail=str(e))
- finally:
- if conn:
- conn.close()
-
-def analyze_tag_analysis(cursor, table_name: str) -> dict:
- """专门分析标签数据,包括分布和完成率"""
- # 获取表结构
- cursor.execute(f"PRAGMA table_info({table_name})")
- columns = {col[1]: idx for idx, col in enumerate(cursor.fetchall())}
-
- # 确保必要的列存在
- required_columns = ['duration', 'progress', 'tag_name']
- for col in required_columns:
- if col not in columns:
- raise ValueError(f"Required column '{col}' not found in table {table_name}")
-
- # 获取所有历史记录
- cursor.execute(f"SELECT * FROM {table_name}")
- histories = cursor.fetchall()
-
- tag_stats = {}
- tag_distribution = {}
-
- for history in histories:
- # 获取并转换数据类型
- try:
- duration = float(history[columns['duration']]) if history[columns['duration']] else 0
- progress = float(history[columns['progress']]) if history[columns['progress']] else 0
- tag_name = history[columns['tag_name']]
- except (ValueError, TypeError):
- continue
-
- # 计算完成率
- if progress == -1:
- completion_rate = 100
- else:
- completion_rate = (progress / duration * 100) if duration > 0 else 0
-
- # 标签分布统计
- if tag_name:
- tag_distribution[tag_name] = tag_distribution.get(tag_name, 0) + 1
-
- # 标签完成率统计
- if tag_name not in tag_stats:
- tag_stats[tag_name] = {
- "video_count": 0,
- "total_completion": 0,
- "fully_watched": 0
- }
- stats = tag_stats[tag_name]
- stats["video_count"] += 1
- stats["total_completion"] += completion_rate
- if completion_rate >= 90:
- stats["fully_watched"] += 1
-
- # 计算标签平均完成率和完整观看率,并按观看数量筛选
- filtered_tags = {}
- for tag, stats in tag_stats.items():
- if stats["video_count"] >= 5: # 只保留视频数量>=5的标签
- stats["average_completion_rate"] = round(stats["total_completion"] / stats["video_count"], 2)
- stats["fully_watched_rate"] = round(stats["fully_watched"] / stats["video_count"] * 100, 2)
- filtered_tags[tag] = stats
-
- # 获取完成率最高的标签
- top_completion_tags = dict(sorted(
- filtered_tags.items(),
- key=lambda x: x[1]["average_completion_rate"],
- reverse=True
- )[:10])
-
- # 获取观看最多的标签
- top_watched_tags = dict(sorted(
- tag_distribution.items(),
- key=lambda x: x[1],
- reverse=True
- )[:10])
-
- return {
- "tag_distribution": top_watched_tags,
- "tag_completion_rates": top_completion_tags
- }
-
-def generate_tag_analysis_insights(tag_data: dict) -> dict:
- """生成标签分析相关的洞察"""
- insights = {}
-
- try:
- # 标签偏好洞察
- tag_distribution = tag_data.get("tag_distribution", {})
- if tag_distribution:
- top_tag = next(iter(tag_distribution.items()), None)
- if top_tag:
- insights["tag_preference"] = (
- f"你最喜欢观看{top_tag[0]}分区的视频,共观看了{top_tag[1]}个视频。"
- )
-
- # 标签完成率洞察
- tag_completion = tag_data.get("tag_completion_rates", {})
- if tag_completion:
- top_completion = next(iter(tag_completion.items()), None)
- if top_completion:
- insights["tag_completion"] = (
- f"在经常观看的分区中,你对{top_completion[0]}分区的视频最感兴趣,"
- f"平均完成率达到{top_completion[1].get('average_completion_rate', 0)}%,"
- f"观看过{top_completion[1].get('video_count', 0)}个该分区的视频。"
- )
-
- except Exception as e:
- print(f"Error generating tag analysis insights: {str(e)}")
- insights["basic_tag"] = "暂时无法生成详细的标签分析。"
-
- return insights
-
-@router.get("/tag-analysis", summary="获取标签分析")
-async def get_viewing_tag_analysis(
- year: Optional[int] = Query(None, description="要分析的年份,不传则使用当前年份"),
- use_cache: bool = Query(True, description="是否使用缓存,默认为True。如果为False则重新分析数据")
-):
- """获取标签分析
-
- Args:
- year: 要分析的年份,不传则使用当前年份
- use_cache: 是否使用缓存,默认为True。如果为False则重新分析数据
-
- Returns:
- dict: 包含标签分析结果的响应
- """
- # 验证年份并获取表名
- table_name, target_year, available_years = validate_year_and_get_table(year)
- if table_name is None:
- return available_years # 这里是错误响应
-
- conn = get_db()
- try:
- cursor = conn.cursor()
-
- # 如果启用缓存,尝试从缓存获取
- if use_cache:
- from .title_pattern_discovery import pattern_cache
- cached_response = pattern_cache.get_cached_patterns(table_name, 'tag_analysis')
- if cached_response:
- print(f"从缓存获取 {target_year} 年的标签分析数据")
- return cached_response
-
- print(f"开始分析 {target_year} 年的标签数据")
-
- # 获取标签分析数据
- tag_data = analyze_tag_analysis(cursor, table_name)
-
- # 生成标签分析洞察
- tag_insights = generate_tag_analysis_insights(tag_data)
-
- # 构建响应
- response = {
- "status": "success",
- "data": {
- "watch_counts": {"tag_distribution": tag_data["tag_distribution"]},
- "completion_rates": {"tag_completion_rates": tag_data["tag_completion_rates"]},
- "insights": tag_insights,
- "year": target_year,
- "available_years": available_years
- }
- }
-
- # 更新缓存
- from .title_pattern_discovery import pattern_cache
- print(f"更新 {target_year} 年的标签分析数据缓存")
- pattern_cache.cache_patterns(table_name, 'tag_analysis', response)
-
- return response
-
- except Exception as e:
- raise HTTPException(status_code=500, detail=str(e))
- finally:
- if conn:
- conn.close()
-
-def analyze_duration_analysis(cursor, table_name: str) -> dict:
- """专门分析视频时长数据"""
- # 获取表结构
- cursor.execute(f"PRAGMA table_info({table_name})")
- columns = {col[1]: idx for idx, col in enumerate(cursor.fetchall())}
-
- # 确保必要的列存在
- required_columns = ['duration', 'view_at']
- for col in required_columns:
- if col not in columns:
- raise ValueError(f"Required column '{col}' not found in table {table_name}")
-
- # 获取所有历史记录
- cursor.execute(f"SELECT * FROM {table_name}")
- histories = cursor.fetchall()
-
- print(f"Debug: 总共获取到 {len(histories)} 条历史记录")
- if len(histories) > 0:
- print(f"Debug: 第一条记录示例: {histories[0]}")
- print(f"Debug: 列映射: {columns}")
-
- # 时段分类
- time_periods = {
- '凌晨': {'start': 0, 'end': 6},
- '上午': {'start': 6, 'end': 12},
- '下午': {'start': 12, 'end': 18},
- '晚上': {'start': 18, 'end': 24}
- }
-
- # 初始化时长相关性数据
- duration_correlation = {}
- for period in time_periods.keys():
- duration_correlation[period] = {
- '短视频': {'video_count': 0, 'total_duration': 0, 'avg_duration': 0},
- '中等视频': {'video_count': 0, 'total_duration': 0, 'avg_duration': 0},
- '长视频': {'video_count': 0, 'total_duration': 0, 'avg_duration': 0}
- }
-
- processed_count = 0
- valid_count = 0
-
- for history in histories:
- processed_count += 1
- try:
- duration = float(history[columns['duration']]) if history[columns['duration']] else 0
- view_at = history[columns['view_at']]
-
- if not view_at or duration <= 0:
- if processed_count <= 5: # 只打印前5条的调试信息
- print(f"Debug: 跳过记录 {processed_count}: view_at={view_at}, duration={duration}")
- continue
-
- # 解析观看时间 - view_at 是 Unix 时间戳
- from datetime import datetime
- try:
- # view_at 是 Unix 时间戳,需要转换为 datetime 对象
- view_time = datetime.fromtimestamp(int(view_at))
- hour = view_time.hour
- except (ValueError, TypeError, OSError):
- continue
-
- # 确定时段
- period = None
- for p, time_range in time_periods.items():
- if time_range['start'] <= hour < time_range['end']:
- period = p
- break
-
- if not period:
- continue
-
- # 确定时长类型
- if duration < 300: # 5分钟以下
- duration_type = '短视频'
- elif duration < 1200: # 20分钟以下
- duration_type = '中等视频'
- else:
- duration_type = '长视频'
-
- # 更新统计
- stats = duration_correlation[period][duration_type]
- stats['video_count'] += 1
- stats['total_duration'] += duration
- valid_count += 1
-
- if valid_count <= 5: # 只打印前5条有效记录的调试信息
- print(f"Debug: 有效记录 {valid_count}: period={period}, duration_type={duration_type}, duration={duration}")
-
- except (ValueError, TypeError):
- if processed_count <= 5:
- print(f"Debug: 数据转换失败,记录 {processed_count}")
- continue
-
- # 计算平均时长
- for period in duration_correlation:
- for duration_type in duration_correlation[period]:
- stats = duration_correlation[period][duration_type]
- if stats['video_count'] > 0:
- stats['avg_duration'] = stats['total_duration'] / stats['video_count']
-
- print(f"Debug: 处理完成 - 总记录数: {processed_count}, 有效记录数: {valid_count}")
- print(f"Debug: 最终统计结果: {duration_correlation}")
-
- return duration_correlation
-
-def generate_duration_analysis_insights(duration_data: dict) -> dict:
- """生成视频时长分析相关的洞察"""
- insights = {}
-
- try:
- # 计算总体时长偏好
- total_counts = {'短视频': 0, '中等视频': 0, '长视频': 0}
-
- for period in duration_data:
- for duration_type in duration_data[period]:
- total_counts[duration_type] += duration_data[period][duration_type]['video_count']
-
- if sum(total_counts.values()) > 0:
- # 找出最喜欢的时长类型
- preferred_type = max(total_counts.items(), key=lambda x: x[1])
- total_videos = sum(total_counts.values())
- preference_rate = round(preferred_type[1] / total_videos * 100, 1)
-
- # 找出最活跃的时段和对应的时长偏好
- max_period_count = 0
- max_period = None
- max_period_type = None
-
- for period in duration_data:
- for duration_type in duration_data[period]:
- count = duration_data[period][duration_type]['video_count']
- if count > max_period_count:
- max_period_count = count
- max_period = period
- max_period_type = duration_type
-
- insights["duration_preference"] = (
- f"你最喜欢观看{preferred_type[0]},占总观看量的{preference_rate}%。"
- f"特别是在{max_period}时段,你更偏向于观看{max_period_type}。"
- )
-
- except Exception as e:
- print(f"Error generating duration analysis insights: {str(e)}")
- insights["basic_duration"] = "暂时无法生成详细的时长分析。"
-
- return insights
-
-@router.get("/duration-analysis", summary="获取视频时长分析")
-async def get_viewing_duration_analysis(
- year: Optional[int] = Query(None, description="要分析的年份,不传则使用当前年份"),
- use_cache: bool = Query(True, description="是否使用缓存,默认为True。如果为False则重新分析数据")
-):
- """获取视频时长分析
-
- Args:
- year: 要分析的年份,不传则使用当前年份
- use_cache: 是否使用缓存,默认为True。如果为False则重新分析数据
-
- Returns:
- dict: 包含视频时长分析结果的响应
- """
- # 验证年份并获取表名
- table_name, target_year, available_years = validate_year_and_get_table(year)
- if table_name is None:
- return available_years # 这里是错误响应
-
- conn = get_db()
- try:
- cursor = conn.cursor()
-
- # 如果启用缓存,尝试从缓存获取
- if use_cache:
- from .title_pattern_discovery import pattern_cache
- cached_response = pattern_cache.get_cached_patterns(table_name, 'duration_analysis')
- if cached_response:
- print(f"从缓存获取 {target_year} 年的视频时长分析数据")
- return cached_response
-
- print(f"开始分析 {target_year} 年的视频时长数据")
-
- # 获取视频时长分析数据
- duration_data = analyze_duration_analysis(cursor, table_name)
-
- # 生成时长分析洞察
- duration_insights = generate_duration_analysis_insights(duration_data)
-
- # 构建响应
- response = {
- "status": "success",
- "data": {
- "duration_correlation": duration_data,
- "insights": duration_insights,
- "year": target_year,
- "available_years": available_years
- }
- }
-
- # 更新缓存
- from .title_pattern_discovery import pattern_cache
- print(f"更新 {target_year} 年的视频时长分析数据缓存")
- pattern_cache.cache_patterns(table_name, 'duration_analysis', response)
-
- return response
-
- except Exception as e:
- raise HTTPException(status_code=500, detail=str(e))
- finally:
- if conn:
- conn.close()
-
-
-def collect_annual_summary_data(cursor, table_name: str, target_year: int) -> Dict[str, Any]:
- """
- 收集年度总结的所有统计数据
-
- Args:
- cursor: 数据库游标
- table_name: 表名
- target_year: 目标年份
-
- Returns:
- Dict[str, Any]: 包含所有统计数据的字典
- """
-
- summary_data = {
- "year": target_year,
- "generated_at": datetime.now().isoformat(),
- "statistics": {},
- "insights": {}
- }
-
- try:
- print(f"开始收集 {target_year} 年的年度总结数据...")
-
- monthly_stats = analyze_monthly_stats(cursor, table_name)
- summary_data["statistics"]["monthly"] = monthly_stats
-
- weekly_stats = analyze_weekly_stats(cursor, table_name)
- summary_data["statistics"]["weekly"] = weekly_stats
-
- time_slots = analyze_time_slots(cursor, table_name)
- summary_data["statistics"]["time_slots"] = time_slots
-
- viewing_continuity = analyze_viewing_continuity(cursor, table_name)
- summary_data["statistics"]["viewing_continuity"] = viewing_continuity
-
- viewing_details = analyze_viewing_details(cursor, table_name)
- summary_data["statistics"]["viewing_details"] = viewing_details
-
- watch_counts = analyze_video_watch_counts(cursor, table_name)
- summary_data["statistics"]["watch_counts"] = watch_counts
-
- completion_rates = analyze_completion_rates(cursor, table_name)
- summary_data["statistics"]["completion_rates"] = completion_rates
-
- author_completion = analyze_author_completion_rates(cursor, table_name)
- summary_data["statistics"]["author_completion"] = author_completion
-
- tag_analysis = analyze_tag_analysis(cursor, table_name)
- summary_data["statistics"]["tag_analysis"] = tag_analysis
-
- duration_analysis = analyze_duration_analysis(cursor, table_name)
- summary_data["statistics"]["duration_analysis"] = duration_analysis
-
- try:
- from .interaction_records import build_interaction_insights, collect_interaction_summary
-
- interaction_summary = collect_interaction_summary(target_year)
- summary_data["statistics"]["interactions"] = interaction_summary
- summary_data["insights"]["interactions"] = build_interaction_insights(interaction_summary)
- except Exception as interaction_error:
- print(f"收集互动记录统计时出错: {str(interaction_error)}")
- summary_data["statistics"]["interactions"] = {
- "year": target_year,
- "totals": {"total_records": 0, "unique_videos": 0, "supplement_videos": 0},
- "source_counts": {"favorite": 0, "like": 0, "coin": 0},
- "error": str(interaction_error),
- }
-
- summary_data["insights"]["monthly"] = generate_monthly_insights(monthly_stats)
- summary_data["insights"]["weekly"] = generate_weekly_insights(weekly_stats)
- summary_data["insights"]["time_slots"] = generate_time_slot_insights(time_slots)
- summary_data["insights"]["continuity"] = generate_continuity_insights(viewing_continuity)
- summary_data["insights"]["viewing_details"] = generate_viewing_report(viewing_details)
- summary_data["insights"]["watch_counts"] = generate_watch_count_insights(watch_counts)
- summary_data["insights"]["completion_rates"] = generate_completion_insights(completion_rates)
- summary_data["insights"]["author_completion"] = generate_author_completion_insights(author_completion)
- summary_data["insights"]["tag_analysis"] = generate_tag_analysis_insights(tag_analysis)
- summary_data["insights"]["duration_analysis"] = generate_duration_analysis_insights(duration_analysis)
-
- print(f"成功收集 {target_year} 年的年度总结数据")
-
- except Exception as e:
- print(f"收集年度总结数据时出错: {str(e)}")
- raise
-
- return summary_data
-
-
-def analyze_monthly_stats(cursor, table_name: str) -> Dict[str, Any]:
- """分析月度观看统计"""
- cursor.execute(f"""
- SELECT
- strftime('%Y-%m', datetime(view_at + 28800, 'unixepoch')) as month,
- COUNT(*) as view_count
- FROM {table_name}
- GROUP BY month
- ORDER BY month
- """)
- monthly_stats = {row[0]: row[1] for row in cursor.fetchall()}
-
- cursor.execute(f"SELECT COUNT(*) FROM {table_name}")
- total_videos = cursor.fetchone()[0]
-
- cursor.execute(f"""
- SELECT COUNT(DISTINCT strftime('%Y-%m-%d', datetime(view_at + 28800, 'unixepoch')))
- FROM {table_name}
- """)
- active_days = cursor.fetchone()[0] or 0
-
- avg_daily_videos = round(total_videos / active_days, 1) if active_days > 0 else 0
-
- return {
- "monthly_stats": monthly_stats,
- "total_videos": total_videos,
- "active_days": active_days,
- "avg_daily_videos": avg_daily_videos
- }
-
-
-def generate_monthly_insights(monthly_data: Dict[str, Any]) -> Dict[str, str]:
- """生成月度统计洞察"""
- insights = {}
-
- monthly_stats = monthly_data.get("monthly_stats", {})
- total_videos = monthly_data.get("total_videos", 0)
- active_days = monthly_data.get("active_days", 0)
- avg_daily_videos = monthly_data.get("avg_daily_videos", 0)
-
- if total_videos > 0 and active_days > 0:
- insights['overall_activity'] = f"今年以来,你在B站观看了{total_videos}个视频,平均每天观看{avg_daily_videos}个视频"
-
- if monthly_stats:
- max_month = max(monthly_stats.items(), key=lambda x: x[1])
- min_month = min(monthly_stats.items(), key=lambda x: x[1])
-
- months = sorted(monthly_stats.keys())
- month_trend = ""
- if len(months) >= 2:
- first_month_count = monthly_stats[months[0]]
- last_month_count = monthly_stats[months[-1]]
- if last_month_count > first_month_count * 1.2:
- month_trend = "你在B站观看视频的热情正在逐月增长,看来你越来越喜欢B站了呢!"
- elif last_month_count < first_month_count * 0.8:
- month_trend = "最近你在B站的活跃度有所下降,可能是工作或学习变得更忙了吧。"
- else:
- month_trend = "你在B站的活跃度保持得很稳定,看来已经养成了良好的观看习惯。"
-
- insights['monthly_pattern'] = f"在{max_month[0]}月,你观看了{max_month[1]}个视频,是你最活跃的月份;而在{min_month[0]}月,观看量为{min_month[1]}个。{month_trend}"
-
- return insights
-
-
-def analyze_weekly_stats(cursor, table_name: str) -> Dict[str, Any]:
- """分析周度观看统计"""
- weekday_mapping = {'0': '周日', '1': '周一', '2': '周二', '3': '周三',
- '4': '周四', '5': '周五', '6': '周六'}
- weekly_stats = {day: 0 for day in weekday_mapping.values()}
-
- cursor.execute(f"""
- SELECT
- strftime('%w', datetime(view_at + 28800, 'unixepoch')) as weekday,
- COUNT(*) as view_count
- FROM {table_name}
- GROUP BY weekday
- ORDER BY weekday
- """)
- for row in cursor.fetchall():
- weekly_stats[weekday_mapping[row[0]]] = row[1]
-
- cursor.execute(f"""
- SELECT
- CASE
- WHEN CAST(strftime('%m', datetime(view_at + 28800, 'unixepoch')) AS INTEGER) IN (1,2,3) THEN '春季'
- WHEN CAST(strftime('%m', datetime(view_at + 28800, 'unixepoch')) AS INTEGER) IN (4,5,6) THEN '夏季'
- WHEN CAST(strftime('%m', datetime(view_at + 28800, 'unixepoch')) AS INTEGER) IN (7,8,9) THEN '秋季'
- WHEN CAST(strftime('%m', datetime(view_at + 28800, 'unixepoch')) AS INTEGER) IN (10,11,12) THEN '冬季'
- END as season,
- COUNT(*) as view_count,
- AVG(CASE WHEN progress = -1 THEN duration ELSE progress END) as avg_duration
- FROM {table_name}
- WHERE CAST(strftime('%m', datetime(view_at + 28800, 'unixepoch')) AS INTEGER) BETWEEN 1 AND 12
- GROUP BY season
- """)
- seasonal_patterns = {row[0]: {'view_count': row[1], 'avg_duration': row[2]} for row in cursor.fetchall()}
-
- cursor.execute(f"""
- SELECT COUNT(DISTINCT strftime('%Y-%m-%d', datetime(view_at + 28800, 'unixepoch'))) as active_days
- FROM {table_name}
- """)
- active_days = cursor.fetchone()[0] or 0
-
- return {
- "weekly_stats": weekly_stats,
- "seasonal_patterns": seasonal_patterns,
- "active_days": active_days
- }
-
-
-def generate_weekly_insights(weekly_data: Dict[str, Any]) -> Dict[str, str]:
- """生成周度统计洞察"""
- insights = {}
-
- weekly_stats = weekly_data.get("weekly_stats", {})
- active_days = weekly_data.get("active_days", 0)
-
- if weekly_stats and active_days > 0:
- max_weekday = max(weekly_stats.items(), key=lambda x: x[1])
- min_weekday = min(weekly_stats.items(), key=lambda x: x[1])
-
- workday_avg = sum(weekly_stats[day] for day in ['周一', '周二', '周三', '周四', '周五']) / 5
- weekend_avg = sum(weekly_stats[day] for day in ['周六', '周日']) / 2
-
- if weekend_avg > workday_avg * 1.5:
- week_pattern = "你是一位周末党,倾向于在周末集中补番或观看视频。"
- elif workday_avg > weekend_avg:
- week_pattern = "工作日反而是你观看视频的主要时间,也许是通过B站来缓解工作压力?"
- else:
- week_pattern = "你的观看时间分布很均衡,不管是工作日还是周末都保持着适度的观看习惯。"
-
- insights['weekly_pattern'] = f"{week_pattern}其中{max_weekday[0]}是你最喜欢刷B站的日子,平均会看{round(max_weekday[1]/active_days*7, 1)}个视频;而{min_weekday[0]}的观看量最少。"
-
- return insights
-
-
-def analyze_time_slots(cursor, table_name: str) -> Dict[str, Any]:
- """分析时段观看统计"""
- cursor.execute(f"""
- SELECT
- strftime('%H', datetime(view_at + 28800, 'unixepoch')) as hour,
- COUNT(*) as view_count
- FROM {table_name}
- GROUP BY hour
- ORDER BY hour
- """)
- daily_time_slots = {f"{int(row[0])}时": row[1] for row in cursor.fetchall()}
-
- cursor.execute(f"""
- SELECT
- strftime('%H', datetime(view_at + 28800, 'unixepoch')) as hour,
- COUNT(*) as view_count
- FROM {table_name}
- GROUP BY hour
- ORDER BY view_count DESC
- LIMIT 5
- """)
- peak_hours = [{
- "hour": f"{int(row[0])}时",
- "view_count": row[1]
- } for row in cursor.fetchall()]
-
- time_investment = analyze_time_investment(cursor, table_name)
-
- cursor.execute(f"""
- SELECT
- date(datetime(view_at + 28800, 'unixepoch')) as view_date,
- COUNT(*) as video_count
- FROM {table_name}
- GROUP BY view_date
- ORDER BY video_count DESC
- LIMIT 1
- """)
- max_daily_record = cursor.fetchone()
- max_daily_record = {
- 'date': max_daily_record[0],
- 'video_count': max_daily_record[1]
- } if max_daily_record else None
-
- return {
- "daily_time_slots": daily_time_slots,
- "peak_hours": peak_hours,
- "time_investment": time_investment,
- "max_daily_record": max_daily_record
- }
-
-
-def generate_time_slot_insights(time_slot_data: Dict[str, Any]) -> Dict[str, str]:
- """生成时段分析洞察"""
- insights = {}
-
- daily_time_slots = time_slot_data.get("daily_time_slots", {})
- peak_hours = time_slot_data.get("peak_hours", [])
- max_daily_record = time_slot_data.get("max_daily_record")
-
- if daily_time_slots and peak_hours:
- morning = sum(daily_time_slots.get(f"{i}时", 0) for i in range(5, 12))
- afternoon = sum(daily_time_slots.get(f"{i}时", 0) for i in range(12, 18))
- evening = sum(daily_time_slots.get(f"{i}时", 0) for i in range(18, 23))
- night = sum(daily_time_slots.get(f"{i}时", 0) for i in range(23, 24)) + sum(daily_time_slots.get(f"{i}时", 0) for i in range(0, 5))
-
- time_slots = [
- ("清晨和上午", morning),
- ("下午", afternoon),
- ("傍晚和晚上", evening),
- ("深夜", night)
- ]
- primary_slot = max(time_slots, key=lambda x: x[1])
-
- if primary_slot[0] == "深夜":
- time_advice = "熬夜看视频可能会影响健康,建议调整作息哦!"
- else:
- time_advice = "这个时间段的观看习惯很好,既不影响作息,也能享受视频带来的乐趣。"
-
- top_hour = peak_hours[0]["hour"] if peak_hours else "未知"
-
- insights['time_preference'] = f"你最喜欢在{primary_slot[0]}观看B站视频,特别是{top_hour}达到观看高峰。{time_advice}"
-
- if max_daily_record:
- insights['daily_record'] = f"在{max_daily_record['date']}这一天,你创下了单日观看{max_daily_record['video_count']}个视频的记录!这可能是一个特别的日子,也许是在追番、学习或者在家放松的一天。"
-
- return insights
-
-
-def save_annual_summary_to_json(summary_data: Dict[str, Any], year: int) -> str:
- """
- 将年度总结保存为 JSON 文件
-
- Args:
- summary_data: 年度总结数据
- year: 年份
-
- Returns:
- str: 保存的文件路径
- """
- output_dir = get_output_path('annual_summary')
- os.makedirs(output_dir, exist_ok=True)
-
- filename = f"annual_summary_{year}.json"
- filepath = os.path.join(output_dir, filename)
-
- with open(filepath, 'w', encoding='utf-8') as f:
- json.dump(summary_data, f, ensure_ascii=False, indent=2, default=str)
-
- print(f"年度总结 JSON 已保存到: {filepath}")
- return filepath
-
-
-@router.get("/annual-summary/json", summary="获取年度总结 JSON 数据")
-async def get_annual_summary_json(
- year: Optional[int] = Query(None, description="要分析的年份,不传则使用最新可用年份"),
- use_cache: bool = Query(True, description="是否使用缓存,默认为True"),
- save_to_file: bool = Query(False, description="是否同时保存到文件,默认为False")
-):
- """
- 获取年度总结的完整 JSON 数据,包含所有统计指标
-
- Args:
- year: 要分析的年份,不传则使用最新可用年份
- use_cache: 是否使用缓存
- save_to_file: 是否同时保存到文件
-
- Returns:
- dict: 包含完整年度总结数据的响应
- """
- table_name, target_year, available_years = validate_year_and_get_table(year)
- if table_name is None:
- return available_years
-
- conn = get_db()
- try:
- cursor = conn.cursor()
-
- if use_cache:
- from .title_pattern_discovery import pattern_cache
- cached_response = pattern_cache.get_cached_patterns(table_name, 'annual_summary_json')
- if cached_response:
- print(f"从缓存获取 {target_year} 年的年度总结 JSON 数据")
- return cached_response
-
- print(f"开始生成 {target_year} 年的年度总结 JSON 数据")
-
- summary_data = collect_annual_summary_data(cursor, table_name, target_year)
-
- response = {
- "status": "success",
- "data": summary_data,
- "year": target_year,
- "available_years": available_years
- }
-
- if save_to_file:
- filepath = save_annual_summary_to_json(summary_data, target_year)
- response["saved_file"] = filepath
-
- from .title_pattern_discovery import pattern_cache
- print(f"更新 {target_year} 年的年度总结 JSON 数据缓存")
- pattern_cache.cache_patterns(table_name, 'annual_summary_json', response)
-
- return response
-
- except Exception as e:
- raise HTTPException(status_code=500, detail=str(e))
- finally:
- if conn:
- conn.close()
-
-
-@router.post("/annual-summary/export", summary="导出年度总结为 JSON 文件")
-async def export_annual_summary_json(
- year: Optional[int] = Query(None, description="要分析的年份,不传则使用最新可用年份"),
- use_cache: bool = Query(True, description="是否使用缓存,默认为True")
-):
- """
- 导出年度总结为 JSON 文件并返回文件路径
-
- Args:
- year: 要分析的年份,不传则使用最新可用年份
- use_cache: 是否使用缓存
-
- Returns:
- dict: 包含导出结果的响应
- """
- table_name, target_year, available_years = validate_year_and_get_table(year)
- if table_name is None:
- return available_years
-
- conn = get_db()
- try:
- cursor = conn.cursor()
-
- print(f"开始导出 {target_year} 年的年度总结 JSON 文件")
-
- summary_data = collect_annual_summary_data(cursor, table_name, target_year)
-
- filepath = save_annual_summary_to_json(summary_data, target_year)
-
- return {
- "status": "success",
- "message": f"年度总结已成功导出",
- "year": target_year,
- "available_years": available_years,
- "file_path": filepath,
- "file_name": os.path.basename(filepath)
- }
-
- except Exception as e:
- raise HTTPException(status_code=500, detail=str(e))
- finally:
- if conn:
- conn.close()
diff --git a/scripts/analyze_bilibili_history.py b/scripts/analyze_bilibili_history.py
deleted file mode 100644
index 1fcfa21..0000000
--- a/scripts/analyze_bilibili_history.py
+++ /dev/null
@@ -1,462 +0,0 @@
-import json
-import os
-from collections import defaultdict
-from datetime import datetime
-import sqlite3
-
-from scripts.utils import load_config, get_output_path
-
-config = load_config()
-
-def get_db():
- """获取数据库连接"""
- db_path = get_output_path(config['db_file'])
- return sqlite3.connect(db_path)
-
-def get_current_year():
- """获取当前年份"""
- return datetime.now().year
-
-def load_history_from_db():
- """从数据库加载历史记录数据"""
- conn = get_db()
- try:
- cursor = conn.cursor()
- current_year = get_current_year()
- table_name = f"bilibili_history_{current_year}"
-
- # 检查表是否存在
- cursor.execute(f"""
- SELECT name FROM sqlite_master
- WHERE type='table' AND name=?
- """, (table_name,))
-
- if not cursor.fetchone():
- print(f"表 {table_name} 不存在")
- return []
-
- # 查询所有记录
- cursor.execute(f"SELECT view_at FROM {table_name}")
- return cursor.fetchall()
-
- except sqlite3.Error as e:
- print(f"数据库错误: {e}")
- return []
- finally:
- conn.close()
-
-def calculate_video_counts(history_data):
- """统计每天和每月的视频观看数量"""
- current_year = datetime.now().year
- daily_count = defaultdict(int)
- monthly_count = defaultdict(int)
-
- for (view_at,) in history_data:
- view_time = datetime.fromtimestamp(view_at)
- if view_time.year != current_year:
- continue
-
- date_str = view_time.strftime('%Y-%m-%d')
- month_str = view_time.strftime('%Y-%m')
- daily_count[date_str] += 1
- monthly_count[month_str] += 1
-
- return daily_count, monthly_count
-
-def save_daily_count_to_json(daily_count, year):
- """保存每天的观看数量到 JSON 文件"""
- output_file = get_output_path(f'daily_count_{year}.json')
- os.makedirs(os.path.dirname(output_file), exist_ok=True)
- with open(output_file, 'w', encoding='utf-8') as f:
- json.dump(daily_count, f, ensure_ascii=False, indent=4)
- print(f"每天观看数量已保存到 {output_file}")
- return output_file
-
-def analyze_history_by_params(date_str=None, start_date=None, end_date=None):
- """根据参数分析历史数据
-
- Args:
- date_str: 指定日期,格式为YYYY-MM-DD
- start_date: 起始日期,格式为YYYY-MM-DD
- end_date: 结束日期,格式为YYYY-MM-DD
- """
- conn = get_db()
- try:
- cursor = conn.cursor()
- current_year = get_current_year()
- table_name = f"bilibili_history_{current_year}"
-
- # 构建基础查询
- query = f"SELECT view_at FROM {table_name} WHERE 1=1"
- params = []
-
- # 处理日期条件
- if date_str:
- start_timestamp = int(datetime.strptime(date_str, '%Y-%m-%d').timestamp())
- end_timestamp = start_timestamp + 86400 # 加一天
- query += " AND view_at >= ? AND view_at < ?"
- params.extend([start_timestamp, end_timestamp])
- elif start_date or end_date:
- if start_date:
- start_timestamp = int(datetime.strptime(start_date, '%Y-%m-%d').timestamp())
- query += " AND view_at >= ?"
- params.append(start_timestamp)
- if end_date:
- end_timestamp = int(datetime.strptime(end_date, '%Y-%m-%d').timestamp()) + 86400
- query += " AND view_at < ?"
- params.append(end_timestamp)
-
- # 执行查询
- cursor.execute(query, params)
- history_data = cursor.fetchall()
-
- # 计算统计数据
- daily_count = defaultdict(int)
- monthly_count = defaultdict(int)
-
- for (view_at,) in history_data:
- view_time = datetime.fromtimestamp(view_at)
- current_date = view_time.strftime('%Y-%m-%d')
- month_str = view_time.strftime('%Y-%m')
- daily_count[current_date] += 1
- monthly_count[month_str] += 1
-
- result = {}
-
- # 如果指定了具体日期,返回该日期的观看数量
- if date_str:
- count = daily_count.get(date_str, 0)
- result["date_count"] = {
- "date": date_str,
- "count": count
- }
-
- # 如果指定了日期范围,返回该范围内的数据
- if start_date or end_date:
- total_count = sum(daily_count.values())
- result["date_range"] = {
- "start_date": start_date or "无限制",
- "end_date": end_date or "无限制",
- "total_count": total_count,
- "daily_counts": dict(daily_count)
- }
-
- return result
-
- except sqlite3.Error as e:
- print(f"数据库错误: {e}")
- return {"error": f"数据库错误: {e}"}
- finally:
- conn.close()
-
-def get_daily_counts(year=None):
- """获取每日观看数量"""
- conn = get_db()
- try:
- cursor = conn.cursor()
- table_name = f"bilibili_history_{year}" if year else None
-
- if not table_name:
- # 获取所有年份的表
- cursor.execute("""
- SELECT name FROM sqlite_master
- WHERE type='table' AND name LIKE 'bilibili_history_%'
- """)
- tables = cursor.fetchall()
- if not tables:
- return {"error": "未找到任何历史记录数据"}
-
- # 合并所有年份的数据
- daily_count = {}
- for (table,) in tables:
- # 按日期统计观看数量
- cursor.execute(f"""
- SELECT
- strftime('%Y-%m-%d', datetime(view_at, 'unixepoch')) as date,
- COUNT(*) as count
- FROM {table}
- GROUP BY date
- ORDER BY date
- """)
-
- for row in cursor.fetchall():
- date, count = row
- if date in daily_count:
- daily_count[date] += count
- else:
- daily_count[date] = count
- else:
- # 查询指定年份的数据
- cursor.execute(f"""
- SELECT
- strftime('%Y-%m-%d', datetime(view_at, 'unixepoch')) as date,
- COUNT(*) as count
- FROM {table_name}
- GROUP BY date
- ORDER BY date
- """)
-
- daily_count = {row[0]: row[1] for row in cursor.fetchall()}
-
- # 保存到JSON文件
- try:
- if year:
- output_file = save_daily_count_to_json(daily_count, year)
- else:
- # 按年份拆分数据并保存
- daily_count_by_year = {}
- for date, count in daily_count.items():
- year = date.split('-')[0]
- if year not in daily_count_by_year:
- daily_count_by_year[year] = {}
- daily_count_by_year[year][date] = count
-
- # 保存每年的数据到单独的文件
- for year, data in daily_count_by_year.items():
- output_file = save_daily_count_to_json(data, year)
- print(f"数据已保存到: {output_file}")
- except Exception as e:
- print(f"保存JSON文件时出错: {e}")
- return {"error": f"保存JSON文件时出错: {e}"}
-
- return daily_count
-
- except sqlite3.Error as e:
- print(f"数据库错误: {e}")
- return {"error": f"数据库错误: {e}"}
- finally:
- conn.close()
-
-def get_monthly_counts(year=None):
- """获取每月观看数量"""
- conn = get_db()
- try:
- cursor = conn.cursor()
- table_name = f"bilibili_history_{year}" if year else None
-
- if not table_name:
- # 获取所有年份的表
- cursor.execute("""
- SELECT name FROM sqlite_master
- WHERE type='table' AND name LIKE 'bilibili_history_%'
- """)
- tables = cursor.fetchall()
- if not tables:
- return {"error": "未找到任何历史记录数据"}
-
- # 合并所有年份的数据
- monthly_count = {}
- for (table,) in tables:
- cursor.execute(f"""
- SELECT
- strftime('%Y-%m', datetime(view_at, 'unixepoch')) as month,
- COUNT(*) as count
- FROM {table}
- GROUP BY month
- ORDER BY month
- """)
-
- for row in cursor.fetchall():
- month, count = row
- if month in monthly_count:
- monthly_count[month] += count
- else:
- monthly_count[month] = count
- else:
- cursor.execute(f"""
- SELECT
- strftime('%Y-%m', datetime(view_at, 'unixepoch')) as month,
- COUNT(*) as count
- FROM {table_name}
- GROUP BY month
- ORDER BY month
- """)
-
- monthly_count = {row[0]: row[1] for row in cursor.fetchall()}
-
- return monthly_count
-
- except sqlite3.Error as e:
- print(f"数据库错误: {e}")
- return {"error": f"数据库错误: {e}"}
- finally:
- conn.close()
-
-def get_available_years():
- """获取可用的年份列表"""
- conn = get_db()
- try:
- cursor = conn.cursor()
- cursor.execute("""
- SELECT name FROM sqlite_master
- WHERE type='table' AND name LIKE 'bilibili_history_%'
- """)
- tables = cursor.fetchall()
- years = []
- for (table_name,) in tables:
- try:
- year = int(table_name.split('_')[-1])
- years.append(year)
- except (ValueError, IndexError):
- continue
- return sorted(years, reverse=True)
- except sqlite3.Error as e:
- print(f"数据库错误: {e}")
- return []
- finally:
- conn.close()
-
-def get_daily_and_monthly_counts(target_year=None):
- """获取每日和每月的观看数量统计
-
- Args:
- target_year: 要分析的年份,不传则分析所有年份
- """
- current_time = datetime.now().strftime("%Y-%m-%d %H:%M:%S")
- print(f"========== 运行时间: {current_time} ==========")
-
- conn = get_db()
- try:
- cursor = conn.cursor()
-
- # 获取所有可用年份
- available_years = get_available_years()
- if not available_years:
- return {"error": "未找到任何历史记录数据"}
-
- # 如果指定了年份,检查是否可用
- if target_year is not None:
- if target_year not in available_years:
- return {"error": f"未找到 {target_year} 年的历史记录数据"}
- years_to_analyze = [target_year]
- else:
- years_to_analyze = available_years
-
- daily_count = {}
- monthly_count = {}
- total_count = 0
-
- # 新增: 时长统计
- daily_watch_seconds = {}
- monthly_watch_seconds = {}
- total_watch_seconds = 0
-
- # 分析每个年份的数据
- for year in years_to_analyze:
- table_name = f"bilibili_history_{year}"
-
- # 获取每日观看数量,使用localtime进行时区转换
- cursor.execute(f"""
- SELECT
- strftime('%Y-%m-%d', datetime(view_at, 'unixepoch', 'localtime')) as date,
- COUNT(*) as count
- FROM {table_name}
- GROUP BY date
- ORDER BY date
- """)
- year_daily_count = {row[0]: row[1] for row in cursor.fetchall()}
- daily_count.update(year_daily_count)
-
- # 获取每日观看总时长(秒),使用localtime进行时区转换
- cursor.execute(f"""
- SELECT
- strftime('%Y-%m-%d', datetime(view_at, 'unixepoch', 'localtime')) as date,
- SUM(
- CASE
- WHEN progress = -1 THEN duration
- WHEN progress IS NULL THEN 0
- WHEN progress >= 0 THEN CASE WHEN progress > duration THEN duration ELSE progress END
- ELSE 0
- END
- ) as seconds
- FROM {table_name}
- GROUP BY date
- ORDER BY date
- """)
- year_daily_watch = {row[0]: int(row[1] or 0) for row in cursor.fetchall()}
- daily_watch_seconds.update(year_daily_watch)
- total_watch_seconds += sum(year_daily_watch.values())
-
- # 获取每月观看数量,使用localtime进行时区转换
- cursor.execute(f"""
- SELECT
- strftime('%Y-%m', datetime(view_at, 'unixepoch', 'localtime')) as month,
- COUNT(*) as count
- FROM {table_name}
- GROUP BY month
- ORDER BY month
- """)
- year_monthly_count = {row[0]: row[1] for row in cursor.fetchall()}
- monthly_count.update(year_monthly_count)
-
- # 获取每月观看总时长(秒),使用localtime进行时区转换
- cursor.execute(f"""
- SELECT
- strftime('%Y-%m', datetime(view_at, 'unixepoch', 'localtime')) as month,
- SUM(
- CASE
- WHEN progress = -1 THEN duration
- WHEN progress IS NULL THEN 0
- WHEN progress >= 0 THEN CASE WHEN progress > duration THEN duration ELSE progress END
- ELSE 0
- END
- ) as seconds
- FROM {table_name}
- GROUP BY month
- ORDER BY month
- """)
- year_monthly_watch = {row[0]: int(row[1] or 0) for row in cursor.fetchall()}
- monthly_watch_seconds.update(year_monthly_watch)
-
- # 计算该年份的总数
- total_count += sum(year_daily_count.values())
-
- # 输出每月的视频观看统计
- print(f"\n{year}年每月观看视频数量:")
- for month, count in sorted(year_monthly_count.items()):
- print(f"{month}: {count} 个视频")
-
- # 保存每日观看数量到JSON文件
- try:
- if target_year:
- output_file = save_daily_count_to_json(daily_count, target_year)
- print(f"每日观看数量已保存到: {output_file}")
- else:
- # 按年份拆分数据并保存
- daily_count_by_year = {}
- for date, count in daily_count.items():
- year = date.split('-')[0]
- if year not in daily_count_by_year:
- daily_count_by_year[year] = {}
- daily_count_by_year[year][date] = count
-
- # 保存每年的数据到单独的文件
- for year, data in daily_count_by_year.items():
- output_file = save_daily_count_to_json(data, year)
- print(f"{year}年每日观看数量已保存到: {output_file}")
- except Exception as e:
- print(f"保存JSON文件时出错: {e}")
-
- return {
- "daily_count": daily_count,
- "monthly_count": monthly_count,
- "total_count": total_count,
- "daily_watch_seconds": daily_watch_seconds,
- "monthly_watch_seconds": monthly_watch_seconds,
- "total_watch_seconds": total_watch_seconds
- }
-
- except sqlite3.Error as e:
- print(f"数据库错误: {e}")
- return {"error": f"数据库错误: {e}"}
- finally:
- if conn:
- conn.close()
-
-# 如果该脚本直接运行,则调用 main()
-if __name__ == '__main__':
- result = get_daily_and_monthly_counts()
- if "error" in result:
- print(f"错误: {result['error']}")
- else:
- print("\n分析完成!")
diff --git a/scripts/apprise_notify.py b/scripts/apprise_notify.py
deleted file mode 100644
index 4d46334..0000000
--- a/scripts/apprise_notify.py
+++ /dev/null
@@ -1,136 +0,0 @@
-import asyncio
-from typing import Dict, Optional
-from loguru import logger
-
-try:
- import apprise
-except ImportError:
- apprise = None
-
-from scripts.utils import load_config
-
-
-def _get_apprise_config() -> dict:
- """从配置文件读取 Apprise 配置"""
- config = load_config()
- return config.get('apprise', {})
-
-
-def _get_apprise_urls() -> list[str]:
- """获取启用的 Apprise URL 列表"""
- apprise_config = _get_apprise_config()
- if not apprise_config.get('enabled', False):
- return []
- urls = apprise_config.get('urls', [])
- return [str(u).strip() for u in urls if str(u).strip()]
-
-
-async def send_apprise_notification(
- title: str,
- body: str,
- urls: Optional[list[str]] = None
-) -> Dict:
- """
- 通过 Apprise 发送通知
-
- Args:
- title: 通知标题
- body: 通知内容
- urls: 可选,直接指定URL列表(用于测试)
-
- Returns:
- {
- "status": "success"|"partial"|"error"|"skipped",
- "message": "...",
- "summary": {"total": 0, "success": 0, "failed": 0},
- "results": []
- }
- """
- target_urls = urls or _get_apprise_urls()
-
- if not target_urls:
- return {
- "status": "skipped",
- "message": "未配置Apprise推送地址",
- "summary": {"total": 0, "success": 0, "failed": 0},
- "results": []
- }
-
- if apprise is None:
- return {
- "status": "error",
- "message": "未安装apprise库,请运行: pip install apprise",
- "summary": {"total": len(target_urls), "success": 0, "failed": len(target_urls)},
- "results": []
- }
-
- def _notify_one(url: str) -> Dict:
- notifier = apprise.Apprise()
- notifier.add(url)
- try:
- success = bool(notifier.notify(title=title, body=body))
- return {
- "url": url,
- "status": "success" if success else "error",
- "message": "发送成功" if success else "发送失败,请检查地址是否正确"
- }
- except Exception as e:
- return {
- "url": url,
- "status": "error",
- "message": f"发送异常: {str(e)}"
- }
-
- try:
- logger.info(f"Apprise 开始发送,共 {len(target_urls)} 个地址")
- results = []
- success_count = 0
- failed_count = 0
-
- for url in target_urls:
- result = await asyncio.to_thread(_notify_one, url)
- results.append(result)
- if result['status'] == 'success':
- success_count += 1
- logger.info(f"Apprise 推送成功: {url}")
- else:
- failed_count += 1
- logger.warning(f"Apprise 推送失败: {url} - {result['message']}")
-
- total = len(results)
- summary = {"total": total, "success": success_count, "failed": failed_count}
-
- if success_count == total:
- status = "success"
- message = f"Apprise推送发送成功({success_count}/{total})"
- elif success_count > 0:
- status = "partial"
- message = f"Apprise推送部分成功(成功 {success_count} 条,失败 {failed_count} 条)"
- else:
- status = "error"
- message = "Apprise推送全部失败,请检查地址是否正确"
-
- logger.info(f"Apprise 发送结果: 成功 {success_count} 条,失败 {failed_count} 条")
- return {
- "status": status,
- "message": message,
- "summary": summary,
- "results": results
- }
- except Exception as e:
- logger.exception(f"Apprise 推送异常: {str(e)}")
- return {
- "status": "error",
- "message": f"Apprise推送异常: {str(e)}",
- "summary": {"total": len(target_urls), "success": 0, "failed": len(target_urls)},
- "results": []
- }
-
-
-async def test_apprise_urls(urls: list[str]) -> Dict:
- """测试指定的Apprise URL列表"""
- return await send_apprise_notification(
- title="Bilibili历史记录 - 测试推送",
- body="这是一条测试通知,用于验证Apprise配置是否有效。",
- urls=urls
- )
diff --git a/scripts/bilibili_history.py b/scripts/bilibili_history.py
index e1a0990..8ce8b85 100644
--- a/scripts/bilibili_history.py
+++ b/scripts/bilibili_history.py
@@ -1,40 +1,18 @@
+import asyncio
import json
import logging
import os
-import time
-import sqlite3
-import asyncio
-import concurrent.futures
-import random
-import string
-from datetime import datetime, timedelta
+from datetime import datetime
+
import requests
-from scripts.utils import load_config, get_base_path, get_output_path
-# 导入获取视频详情的函数
-from routers.download import get_video_info
+from scripts.utils import get_output_path, load_config
-config = load_config()
def load_cookie():
- """从配置文件读取 SESSDATA"""
- print("\n=== 读取 Cookie 配置 ===")
- # 重新加载配置文件,确保获取最新的SESSDATA
- current_config = load_config()
- print(f"配置内容: {current_config}")
- sessdata = current_config.get('SESSDATA', '')
- if not sessdata:
- print("警告: 配置文件中未找到 SESSDATA")
- return ''
-
- # 移除可能存在的引号
- sessdata = sessdata.strip('"')
- if not sessdata:
- print("警告: SESSDATA 为空")
- return ''
-
- print(f"获取到的 SESSDATA: {sessdata}")
- return sessdata
+ """从配置文件读取 SESSDATA。"""
+ return load_config().get("SESSDATA", "").strip('"')
+
def find_latest_local_history(base_folder='history_by_date'):
"""查找本地最新的历史记录"""
@@ -134,1594 +112,69 @@ def save_history(history_data, base_folder='history_by_date'):
json.dump(daily_data, f, ensure_ascii=False, indent=4)
logging.info(f"历史记录保存完成,共保存了{saved_count}条新记录。")
- return {"status": "success", "message": f"历史记录获取成功", "data": history_data}
-
-def save_video_details(video_data):
- """将视频详细信息保存到新数据库"""
- try:
- # 设置数据库路径
- db_path = get_output_path("video_library.db")
- print(f"视频库数据库路径: {db_path}")
-
- # 创建连接
- conn = sqlite3.connect(db_path)
- cursor = conn.cursor()
-
- # 如果不存在,创建主表
- cursor.execute('''
- CREATE TABLE IF NOT EXISTS video_details (
- id INTEGER PRIMARY KEY,
- bvid TEXT UNIQUE,
- aid INTEGER,
- videos INTEGER,
- tid INTEGER,
- tid_v2 INTEGER,
- tname TEXT,
- tname_v2 TEXT,
- copyright INTEGER,
- pic TEXT,
- title TEXT,
- pubdate INTEGER,
- ctime INTEGER,
- desc TEXT,
- state INTEGER,
- duration INTEGER,
-
- -- rights信息
- rights_bp INTEGER,
- rights_elec INTEGER,
- rights_download INTEGER,
- rights_movie INTEGER,
- rights_pay INTEGER,
- rights_hd5 INTEGER,
- rights_no_reprint INTEGER,
- rights_autoplay INTEGER,
- rights_ugc_pay INTEGER,
- rights_is_cooperation INTEGER,
- rights_ugc_pay_preview INTEGER,
- rights_no_background INTEGER,
- rights_clean_mode INTEGER,
- rights_is_stein_gate INTEGER,
- rights_is_360 INTEGER,
- rights_no_share INTEGER,
- rights_arc_pay INTEGER,
- rights_free_watch INTEGER,
-
- -- owner信息
- owner_mid INTEGER,
- owner_name TEXT,
- owner_face TEXT,
-
- -- stat信息
- stat_view INTEGER,
- stat_danmaku INTEGER,
- stat_reply INTEGER,
- stat_favorite INTEGER,
- stat_coin INTEGER,
- stat_share INTEGER,
- stat_now_rank INTEGER,
- stat_his_rank INTEGER,
- stat_like INTEGER,
- stat_dislike INTEGER,
-
- -- argue_info
- argue_msg TEXT,
- argue_type INTEGER,
- argue_link TEXT,
-
- -- 其他信息
- dynamic TEXT,
- cid INTEGER,
- dimension_width INTEGER,
- dimension_height INTEGER,
- dimension_rotate INTEGER,
- teenage_mode INTEGER,
- is_chargeable_season INTEGER,
- is_story INTEGER,
- is_upower_exclusive INTEGER,
- is_upower_play INTEGER,
- is_upower_preview INTEGER,
- is_upower_exclusive_with_qa INTEGER,
- no_cache INTEGER,
-
- -- 字幕信息
- subtitle_allow_submit INTEGER,
-
- -- 标签信息
- label_type INTEGER,
-
- -- 季节信息
- is_season_display INTEGER,
-
- -- 点赞信息
- like_icon TEXT,
-
- -- 其他布尔信息
- need_jump_bv INTEGER,
- disable_show_up_info INTEGER,
- is_story_play INTEGER,
- is_view_self INTEGER,
-
- -- 添加时间
- add_time INTEGER
- )
- ''')
-
- # 创建视频分P表
- cursor.execute('''
- CREATE TABLE IF NOT EXISTS video_pages (
- id INTEGER PRIMARY KEY,
- video_bvid TEXT,
- cid INTEGER,
- page INTEGER,
- from_source TEXT,
- part TEXT,
- duration INTEGER,
- vid TEXT,
- weblink TEXT,
- dimension_width INTEGER,
- dimension_height INTEGER,
- dimension_rotate INTEGER,
- first_frame TEXT,
- ctime INTEGER,
- FOREIGN KEY (video_bvid) REFERENCES video_details (bvid)
- )
- ''')
-
- # 创建视频staff表
- cursor.execute('''
- CREATE TABLE IF NOT EXISTS video_staff (
- id INTEGER PRIMARY KEY,
- video_bvid TEXT,
- mid INTEGER,
- title TEXT,
- name TEXT,
- face TEXT,
- vip_type INTEGER,
- vip_status INTEGER,
- official_role INTEGER,
- official_title TEXT,
- official_desc TEXT,
- follower INTEGER,
- FOREIGN KEY (video_bvid) REFERENCES video_details (bvid)
- )
- ''')
-
- # 创建字幕表
- cursor.execute('''
- CREATE TABLE IF NOT EXISTS video_subtitles (
- id INTEGER PRIMARY KEY,
- video_bvid TEXT,
- subtitle_id TEXT,
- lan TEXT,
- lan_doc TEXT,
- is_lock INTEGER,
- subtitle_url TEXT,
- type INTEGER,
- ai_type INTEGER,
- ai_status INTEGER,
- FOREIGN KEY (video_bvid) REFERENCES video_details (bvid)
- )
- ''')
-
- # 创建荣誉列表表
- cursor.execute('''
- CREATE TABLE IF NOT EXISTS video_honors (
- id INTEGER PRIMARY KEY,
- video_bvid TEXT,
- aid INTEGER,
- type INTEGER,
- desc TEXT,
- weekly_recommend_num INTEGER,
- FOREIGN KEY (video_bvid) REFERENCES video_details (bvid)
- )
- ''')
-
- # 检查是否已存在相同的视频
- cursor.execute("SELECT id FROM video_details WHERE bvid = ?", (video_data['bvid'],))
- existing = cursor.fetchone()
-
- current_time = int(time.time())
- bvid = video_data.get('bvid', '')
-
- # 准备数据
- video_info = {}
-
- # 基本信息
- video_info['bvid'] = bvid
- video_info['aid'] = video_data.get('aid', 0)
- video_info['videos'] = video_data.get('videos', 0)
- video_info['tid'] = video_data.get('tid', 0)
- video_info['tid_v2'] = video_data.get('tid_v2', 0)
- video_info['tname'] = video_data.get('tname', '')
- video_info['tname_v2'] = video_data.get('tname_v2', '')
- video_info['copyright'] = video_data.get('copyright', 0)
- video_info['pic'] = video_data.get('pic', '')
- video_info['title'] = video_data.get('title', '')
- video_info['pubdate'] = video_data.get('pubdate', 0)
- video_info['ctime'] = video_data.get('ctime', 0)
- video_info['desc'] = video_data.get('desc', '')
- video_info['state'] = video_data.get('state', 0)
- video_info['duration'] = video_data.get('duration', 0)
-
- # rights信息
- rights = video_data.get('rights', {})
- video_info['rights_bp'] = rights.get('bp', 0)
- video_info['rights_elec'] = rights.get('elec', 0)
- video_info['rights_download'] = rights.get('download', 0)
- video_info['rights_movie'] = rights.get('movie', 0)
- video_info['rights_pay'] = rights.get('pay', 0)
- video_info['rights_hd5'] = rights.get('hd5', 0)
- video_info['rights_no_reprint'] = rights.get('no_reprint', 0)
- video_info['rights_autoplay'] = rights.get('autoplay', 0)
- video_info['rights_ugc_pay'] = rights.get('ugc_pay', 0)
- video_info['rights_is_cooperation'] = rights.get('is_cooperation', 0)
- video_info['rights_ugc_pay_preview'] = rights.get('ugc_pay_preview', 0)
- video_info['rights_no_background'] = rights.get('no_background', 0)
- video_info['rights_clean_mode'] = rights.get('clean_mode', 0)
- video_info['rights_is_stein_gate'] = rights.get('is_stein_gate', 0)
- video_info['rights_is_360'] = rights.get('is_360', 0)
- video_info['rights_no_share'] = rights.get('no_share', 0)
- video_info['rights_arc_pay'] = rights.get('arc_pay', 0)
- video_info['rights_free_watch'] = rights.get('free_watch', 0)
-
- # owner信息
- owner = video_data.get('owner', {})
- video_info['owner_mid'] = owner.get('mid', 0)
- video_info['owner_name'] = owner.get('name', '')
- video_info['owner_face'] = owner.get('face', '')
-
- # stat信息
- stat = video_data.get('stat', {})
- video_info['stat_view'] = stat.get('view', 0)
- video_info['stat_danmaku'] = stat.get('danmaku', 0)
- video_info['stat_reply'] = stat.get('reply', 0)
- video_info['stat_favorite'] = stat.get('favorite', 0)
- video_info['stat_coin'] = stat.get('coin', 0)
- video_info['stat_share'] = stat.get('share', 0)
- video_info['stat_now_rank'] = stat.get('now_rank', 0)
- video_info['stat_his_rank'] = stat.get('his_rank', 0)
- video_info['stat_like'] = stat.get('like', 0)
- video_info['stat_dislike'] = stat.get('dislike', 0)
-
- # argue_info
- argue_info = video_data.get('argue_info', {})
- video_info['argue_msg'] = argue_info.get('argue_msg', '')
- video_info['argue_type'] = argue_info.get('argue_type', 0)
- video_info['argue_link'] = argue_info.get('argue_link', '')
-
- # dynamic
- video_info['dynamic'] = video_data.get('dynamic', '')
- video_info['cid'] = video_data.get('cid', 0)
-
- # dimension
- dimension = video_data.get('dimension', {})
- video_info['dimension_width'] = dimension.get('width', 0)
- video_info['dimension_height'] = dimension.get('height', 0)
- video_info['dimension_rotate'] = dimension.get('rotate', 0)
-
- # 其他标志位
- video_info['teenage_mode'] = video_data.get('teenage_mode', 0)
- video_info['is_chargeable_season'] = 1 if video_data.get('is_chargeable_season', False) else 0
- video_info['is_story'] = 1 if video_data.get('is_story', False) else 0
- video_info['is_upower_exclusive'] = 1 if video_data.get('is_upower_exclusive', False) else 0
- video_info['is_upower_play'] = 1 if video_data.get('is_upower_play', False) else 0
- video_info['is_upower_preview'] = 1 if video_data.get('is_upower_preview', False) else 0
- video_info['is_upower_exclusive_with_qa'] = 1 if video_data.get('is_upower_exclusive_with_qa', False) else 0
- video_info['no_cache'] = 1 if video_data.get('no_cache', False) else 0
-
- # 字幕信息
- subtitle = video_data.get('subtitle', {})
- video_info['subtitle_allow_submit'] = 1 if subtitle.get('allow_submit', False) else 0
-
- # 标签信息
- label = video_data.get('label', {})
- video_info['label_type'] = label.get('type', 0)
-
- # 季节信息
- video_info['is_season_display'] = 1 if video_data.get('is_season_display', False) else 0
-
- # 点赞信息
- video_info['like_icon'] = video_data.get('like_icon', '')
-
- # 其他布尔信息
- video_info['need_jump_bv'] = 1 if video_data.get('need_jump_bv', False) else 0
- video_info['disable_show_up_info'] = 1 if video_data.get('disable_show_up_info', False) else 0
- video_info['is_story_play'] = video_data.get('is_story_play', 0)
- video_info['is_view_self'] = 1 if video_data.get('is_view_self', False) else 0
-
- # 添加时间
- video_info['add_time'] = current_time
-
- if existing:
- # 构建更新语句
- update_fields = []
- update_values = []
-
- for key, value in video_info.items():
- if key != 'bvid': # 不更新主键bvid
- update_fields.append(f"{key} = ?")
- update_values.append(value)
-
- # 添加WHERE条件的值
- update_values.append(video_info['bvid'])
-
- # 执行更新
- cursor.execute(
- f"UPDATE video_details SET {', '.join(update_fields)} WHERE bvid = ?",
- update_values
- )
- print(f"已更新视频信息: {video_info['title']} (BV号: {video_info['bvid']})")
-
- # 删除相关的子表数据,以便重新插入
- cursor.execute("DELETE FROM video_pages WHERE video_bvid = ?", (bvid,))
- cursor.execute("DELETE FROM video_staff WHERE video_bvid = ?", (bvid,))
- cursor.execute("DELETE FROM video_subtitles WHERE video_bvid = ?", (bvid,))
- cursor.execute("DELETE FROM video_honors WHERE video_bvid = ?", (bvid,))
- else:
- # 构建插入语句
- columns = list(video_info.keys())
- placeholders = ['?'] * len(columns)
- values = [video_info[key] for key in columns]
-
- # 执行插入
- cursor.execute(
- f"INSERT INTO video_details ({', '.join(columns)}) VALUES ({', '.join(placeholders)})",
- values
- )
- print(f"已添加新视频到库: {video_info['title']} (BV号: {video_info['bvid']})")
-
- # 插入分P信息
- pages = video_data.get('pages', [])
- for page in pages:
- page_dimension = page.get('dimension', {})
- cursor.execute('''
- INSERT INTO video_pages (
- video_bvid, cid, page, from_source, part, duration, vid, weblink,
- dimension_width, dimension_height, dimension_rotate, first_frame, ctime
- ) VALUES (?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?)
- ''', (
- bvid,
- page.get('cid', 0),
- page.get('page', 0),
- page.get('from', ''),
- page.get('part', ''),
- page.get('duration', 0),
- page.get('vid', ''),
- page.get('weblink', ''),
- page_dimension.get('width', 0),
- page_dimension.get('height', 0),
- page_dimension.get('rotate', 0),
- page.get('first_frame', ''),
- page.get('ctime', 0)
- ))
-
- # 插入staff信息
- staff_list = video_data.get('staff', [])
- for staff in staff_list:
- vip = staff.get('vip', {})
- official = staff.get('official', {})
- cursor.execute('''
- INSERT INTO video_staff (
- video_bvid, mid, title, name, face,
- vip_type, vip_status, official_role, official_title, official_desc, follower
- ) VALUES (?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?)
- ''', (
- bvid,
- staff.get('mid', 0),
- staff.get('title', ''),
- staff.get('name', ''),
- staff.get('face', ''),
- vip.get('type', 0),
- vip.get('status', 0),
- official.get('role', 0),
- official.get('title', ''),
- official.get('desc', ''),
- staff.get('follower', 0)
- ))
-
- # 插入字幕信息
- subtitle_list = subtitle.get('list', [])
- for sub in subtitle_list:
- cursor.execute('''
- INSERT INTO video_subtitles (
- video_bvid, subtitle_id, lan, lan_doc, is_lock,
- subtitle_url, type, ai_type, ai_status
- ) VALUES (?, ?, ?, ?, ?, ?, ?, ?, ?)
- ''', (
- bvid,
- sub.get('id_str', ''),
- sub.get('lan', ''),
- sub.get('lan_doc', ''),
- 1 if sub.get('is_lock', False) else 0,
- sub.get('subtitle_url', ''),
- sub.get('type', 0),
- sub.get('ai_type', 0),
- sub.get('ai_status', 0)
- ))
-
- # 插入荣誉信息
- honor_reply = video_data.get('honor_reply', {})
- honor_list = honor_reply.get('honor', [])
- for honor in honor_list:
- cursor.execute('''
- INSERT INTO video_honors (
- video_bvid, aid, type, desc, weekly_recommend_num
- ) VALUES (?, ?, ?, ?, ?)
- ''', (
- bvid,
- honor.get('aid', 0),
- honor.get('type', 0),
- honor.get('desc', ''),
- honor.get('weekly_recommend_num', 0)
- ))
-
- conn.commit()
- return True
- except Exception as e:
- print(f"保存视频详情时出错: {e}")
- import traceback
- print(traceback.format_exc())
- if 'conn' in locals() and conn:
- conn.rollback()
- return False
- finally:
- if 'conn' in locals() and conn:
- conn.close()
-
-# 添加一个函数,用于检查视频是否已经存在于视频库中
-def is_video_exists(bvid):
- """检查视频是否已经存在于视频库中"""
- try:
- db_path = get_output_path("video_library.db")
- conn = sqlite3.connect(db_path)
- cursor = conn.cursor()
-
- cursor.execute("SELECT id FROM video_details WHERE bvid = ?", (bvid,))
- result = cursor.fetchone()
-
- conn.close()
- return result is not None
- except Exception as e:
- print(f"检查视频是否存在时出错: {e}")
- return False
-
-def create_invalid_videos_table():
- """创建记录失效视频的数据库表"""
- try:
- db_path = get_output_path("video_library.db")
- conn = sqlite3.connect(db_path)
- cursor = conn.cursor()
-
- # 创建失效视频表
- cursor.execute('''
- CREATE TABLE IF NOT EXISTS invalid_videos (
- id INTEGER PRIMARY KEY,
- bvid TEXT UNIQUE,
- error_type TEXT,
- error_code INTEGER,
- error_message TEXT,
- raw_response TEXT,
- first_check_time INTEGER,
- last_check_time INTEGER,
- check_count INTEGER DEFAULT 1
- )
- ''')
-
- conn.commit()
- conn.close()
- print("成功创建或更新失效视频表")
- return True
- except Exception as e:
- print(f"创建失效视频表时出错: {e}")
- return False
-
-def save_invalid_video(video_result):
- """保存失效视频记录到数据库"""
- try:
- # 获取视频信息
- bvid = getattr(video_result, 'bvid', None)
- if not bvid:
- print("无法保存失效视频记录:缺少BV号")
- return False
-
- error_type = getattr(video_result, 'error_type', 'unknown')
- error_code = getattr(video_result, 'error_code', None)
- error_message = getattr(video_result, 'message', '')
- raw_response = getattr(video_result, 'raw_response', None)
-
- # 如果raw_response是字典,转换为JSON字符串
- if isinstance(raw_response, dict):
- raw_response = json.dumps(raw_response, ensure_ascii=False)
- elif raw_response is None:
- raw_response = ""
-
- current_time = int(time.time())
-
- # 连接数据库
- db_path = get_output_path("video_library.db")
- conn = sqlite3.connect(db_path)
- cursor = conn.cursor()
-
- # 确保表存在
- create_invalid_videos_table()
-
- # 检查是否已存在记录
- cursor.execute("SELECT check_count, first_check_time FROM invalid_videos WHERE bvid = ?", (bvid,))
- existing = cursor.fetchone()
-
- if existing:
- # 更新现有记录
- check_count = existing[0] + 1
- first_check_time = existing[1]
-
- cursor.execute('''
- UPDATE invalid_videos
- SET error_type = ?,
- error_code = ?,
- error_message = ?,
- raw_response = ?,
- last_check_time = ?,
- check_count = ?
- WHERE bvid = ?
- ''', (error_type, error_code, error_message, raw_response, current_time, check_count, bvid))
-
- print(f"更新失效视频记录: {bvid}, 错误类型: {error_type}, 检查次数: {check_count}")
- else:
- # 插入新记录
- cursor.execute('''
- INSERT INTO invalid_videos
- (bvid, error_type, error_code, error_message, raw_response, first_check_time, last_check_time)
- VALUES (?, ?, ?, ?, ?, ?, ?)
- ''', (bvid, error_type, error_code, error_message, raw_response, current_time, current_time))
-
- print(f"添加新失效视频记录: {bvid}, 错误类型: {error_type}")
-
- conn.commit()
- conn.close()
- return True
- except Exception as e:
- print(f"保存失效视频记录时出错: {e}")
- import traceback
- print(traceback.format_exc())
- return False
+ return {"status": "success", "message": "历史记录获取成功", "data": {"new_records_count": saved_count}}
-def check_invalid_video(bvid):
- """检查视频是否已在失效视频表中"""
- try:
- db_path = get_output_path("video_library.db")
- conn = sqlite3.connect(db_path)
- cursor = conn.cursor()
-
- cursor.execute("SELECT id, error_type, last_check_time FROM invalid_videos WHERE bvid = ?", (bvid,))
- result = cursor.fetchone()
-
- conn.close()
-
- if result:
- # 如果在失效表中找到,返回错误类型和最后检查时间
- return {
- "is_invalid": True,
- "error_type": result[1],
- "last_check_time": result[2]
- }
- return {"is_invalid": False}
- except Exception as e:
- print(f"检查失效视频时出错: {e}")
- return {"is_invalid": False}
-# 修改get_video_info_sync函数,在JSON解析错误时保存并打印原始响应内容,并确保将这类错误也添加到失效表中
-def get_video_info_sync(bvid, sessdata, skip_exists=False, use_sessdata=True):
- """同步版本的获取视频详情函数,供多线程使用"""
- # 如果需要跳过已存在的视频,则先检查
- if skip_exists and is_video_exists(bvid):
- print(f"视频 {bvid} 已存在于数据库中,跳过获取")
- return None
-
- # 检查是否已知失效视频
- invalid_check = check_invalid_video(bvid)
- if invalid_check["is_invalid"]:
- print(f"视频 {bvid} 已知失效,类型: {invalid_check['error_type']},最后检查时间: {datetime.fromtimestamp(invalid_check['last_check_time'])}")
- return type('ErrorResponse', (), {
- 'status': 'error',
- 'message': f"已知失效视频 (类型: {invalid_check['error_type']})",
- 'data': None,
- 'bvid': bvid,
- 'error_type': invalid_check['error_type'],
- 'error_code': None,
- 'raw_response': None,
- 'is_known_invalid': True
- })
-
- # 随机延迟0.5-2秒,使请求看起来更像人类行为
- delay = 0.5 + random.random() * 1.5
- time.sleep(delay)
-
- # 生成随机的buvid和其他cookie值
- buvid3 = ''.join(random.choices(string.ascii_letters + string.digits, k=32))
- buvid4 = ''.join(random.choices(string.ascii_letters + string.digits, k=32))
- b_nut = str(int(time.time() * 1000))
-
- # 随机化User-Agent
- user_agents = [
- 'Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/91.0.4472.124 Safari/537.36',
- 'Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/92.0.4515.159 Safari/537.36',
- 'Mozilla/5.0 (Windows NT 10.0; Win64; x64; rv:90.0) Gecko/20100101 Firefox/90.0',
- 'Mozilla/5.0 (Macintosh; Intel Mac OS X 10_15_7) AppleWebKit/605.1.15 (KHTML, like Gecko) Version/14.1.1 Safari/605.1.15',
- 'Mozilla/5.0 (Macintosh; Intel Mac OS X 10_15_7) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/92.0.4515.131 Safari/537.36',
- 'Mozilla/5.0 (X11; Linux x86_64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/92.0.4515.107 Safari/537.36'
- ]
- user_agent = random.choice(user_agents)
-
- # 构建更完整的请求头
+async def fetch_and_compare_history(cookie, latest_date):
+ """按游标获取历史记录,增量获取保留本地最新日期内的记录。"""
+ url = "https://api.bilibili.com/x/web-interface/history/cursor"
headers = {
- 'User-Agent': user_agent,
- 'Referer': f'https://www.bilibili.com/video/{bvid}',
- 'Accept': 'application/json, text/plain, */*',
- 'Accept-Language': 'zh-CN,zh;q=0.9,en;q=0.8',
- 'Accept-Encoding': 'gzip, deflate, br',
- 'Connection': 'keep-alive',
- 'Origin': 'https://www.bilibili.com',
- 'Sec-Fetch-Site': 'same-site',
- 'Sec-Fetch-Mode': 'cors',
- 'Sec-Fetch-Dest': 'empty',
- 'Sec-Ch-Ua': '"Chromium";v="92", " Not A;Brand";v="99", "Google Chrome";v="92"',
- 'Sec-Ch-Ua-Mobile': '?0',
- 'Cookie': f'buvid3={buvid3}; buvid4={buvid4}; b_nut={b_nut}; bsource=search_google; _uuid=D{buvid3}-{b_nut}-{buvid4}'
+ "Cookie": f"SESSDATA={cookie}",
+ "User-Agent": "Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/91.0.4472.124 Safari/537.36",
+ "Referer": "https://www.bilibili.com",
+ "Origin": "https://www.bilibili.com",
+ "Accept": "application/json, text/plain, */*",
}
-
- # 如果存在SESSDATA并且需要使用,加入到Cookie中
- if sessdata and use_sessdata:
- headers['Cookie'] += f'; SESSDATA={sessdata}'
-
- # 使用指数退避策略进行重试
- max_retries = 3
- last_response_text = None
- last_error = None
-
- for retry in range(max_retries):
- try:
- # 直接使用同步请求,避免事件循环嵌套问题
- url = f"https://api.bilibili.com/x/web-interface/view?bvid={bvid}"
- response = requests.get(url, headers=headers, timeout=20)
-
- # 保存原始响应文本,以便错误时打印
- last_response_text = response.text
-
- # 检查响应状态码
- if response.status_code == 412:
- print(f"获取视频 {bvid} 的详情被服务器拒绝(412),等待后重试...")
- print(f"原始响应: {last_response_text[:500]}...") # 打印部分响应内容
- # 412错误时使用更长的指数退避延迟
- retry_delay = (4 ** retry) + random.uniform(1, 5)
- time.sleep(retry_delay)
- continue
-
- # 如果是其他错误状态码
- if response.status_code != 200:
- print(f"获取视频 {bvid} 的详情失败,HTTP状态码: {response.status_code}")
- print(f"原始响应: {last_response_text[:500]}...") # 打印部分响应内容
- return type('ErrorResponse', (), {
- 'status': 'error',
- 'message': f'HTTP错误 {response.status_code}: {response.reason}',
- 'data': None,
- 'bvid': bvid,
- 'error_type': 'http_error',
- 'error_code': response.status_code,
- 'raw_response': last_response_text
- })
-
- # 尝试解析JSON响应
- try:
- data = response.json()
- except json.JSONDecodeError as json_err:
- print(f"获取视频 {bvid} 时出现JSON解析错误: {str(json_err)}")
- print(f"原始响应内容: {last_response_text[:500]}...") # 打印部分响应以便分析
-
- # 将解析错误作为失效视频处理
- error_response = type('ErrorResponse', (), {
- 'status': 'error',
- 'message': f'JSON解析错误: {str(json_err)}',
- 'data': None,
- 'bvid': bvid,
- 'error_type': 'parse_error',
- 'error_code': None,
- 'raw_response': last_response_text
- })
-
- # 保存到失效视频表
- save_invalid_video(error_response)
-
- return error_response
-
- # 打印失效视频的响应数据,用于分析
- if data.get('code') != 0:
- print(f"视频 {bvid} 失效,B站返回数据: {json.dumps(data, ensure_ascii=False)}")
-
- # 检查API错误码
- if data.get('code') != 0:
- error_code = data.get('code')
- error_msg = data.get('message', '未知错误')
-
- # 特定错误码的处理
- if error_code == -404:
- print(f"获取视频 {bvid} 的详情失败: 视频不存在或已被删除")
- return type('ErrorResponse', (), {
- 'status': 'error',
- 'message': f'视频不存在或已被删除 (错误码: -404)',
- 'data': None,
- 'bvid': bvid,
- 'error_type': 'not_found',
- 'error_code': error_code,
- 'raw_response': data
- })
- elif error_code == 62002:
- print(f"获取视频 {bvid} 的详情失败: 视频已设为私有或被隐藏")
- return type('ErrorResponse', (), {
- 'status': 'error',
- 'message': f'视频已设为私有或被隐藏 (错误码: 62002)',
- 'data': None,
- 'bvid': bvid,
- 'error_type': 'invisible',
- 'error_code': error_code,
- 'raw_response': data
- })
- else:
- print(f"获取视频 {bvid} 的详情失败: API错误 {error_code}: {error_msg}")
- return type('ErrorResponse', (), {
- 'status': 'error',
- 'message': f'API错误 {error_code}: {error_msg}',
- 'data': None,
- 'bvid': bvid,
- 'error_type': 'api_error',
- 'error_code': error_code,
- 'raw_response': data
- })
-
- # 成功获取数据
- return type('SuccessResponse', (), {
- 'status': 'success',
- 'message': '获取视频信息成功',
- 'data': data.get('data', {}),
- 'bvid': bvid
- })
-
- except requests.exceptions.RequestException as e:
- # 请求异常,使用指数退避策略
- last_error = str(e)
- retry_delay = (2 ** retry) + random.uniform(0.5, 2)
- print(f"获取视频 {bvid} 时出错: {e},{retry+1}/{max_retries}次重试,等待{retry_delay:.2f}秒")
- if last_response_text:
- print(f"上次响应内容: {last_response_text[:500]}...")
- time.sleep(retry_delay)
- except Exception as e:
- # 其他异常
- last_error = str(e)
- retry_delay = (2 ** retry) + random.uniform(0.5, 2)
- print(f"处理视频 {bvid} 时出错: {e},{retry+1}/{max_retries}次重试,等待{retry_delay:.2f}秒")
- if last_response_text:
- print(f"上次响应内容: {last_response_text[:500]}...")
- time.sleep(retry_delay)
-
- # 所有重试都失败后,创建通用错误响应
- error_response = type('ErrorResponse', (), {
- 'status': 'error',
- 'message': f'获取视频 {bvid} 详情失败,已重试 {max_retries} 次: {last_error}',
- 'data': None,
- 'bvid': bvid,
- 'error_type': 'retry_exceeded',
- 'error_code': None,
- 'raw_response': last_response_text
- })
-
- # 将重试失败的也加入失效表,但标记为临时错误类型
- if 'Expecting value' in str(last_error):
- error_response.error_type = 'parse_error'
- # 保存到失效视频表
- save_invalid_video(error_response)
-
- return error_response
-
-# 批量保存视频详情,修改以处理失效视频
-def batch_save_video_details(video_details_list):
- """批量保存多个视频的详情"""
- success_count = 0
- fail_count = 0
- skipped_count = 0
- invalid_count = 0
-
- # 错误类型统计
- error_stats = {
- "404_not_found": 0, # 视频不存在或已删除
- "62002_invisible": 0, # 视频已设为私有或被隐藏
- "412_banned": 0, # 请求被禁止/拒绝
- "decode_error": 0, # 解码错误
- "parse_error": 0, # JSON解析错误
- "empty_data": 0, # 数据为空
- "save_error": 0, # 保存过程出错
- "other_error": 0 # 其他错误
- }
-
- # 确保失效视频表已创建
- create_invalid_videos_table()
-
- for video_data in video_details_list:
- if video_data is None:
- # 跳过的视频,不计入成功或失败
- skipped_count += 1
- continue
-
- # 处理各种失败情况
- if not hasattr(video_data, 'status') or video_data.status != "success":
- fail_count += 1
-
- # 获取错误信息
- error_msg = getattr(video_data, 'message', '未知错误') if hasattr(video_data, 'message') else '未知错误'
-
- # 错误类型统计
- if '404' in error_msg or '视频不存在' in error_msg:
- error_stats["404_not_found"] += 1
- elif '62002' in error_msg or '稿件不可见' in error_msg:
- error_stats["62002_invisible"] += 1
- elif '412' in error_msg or 'request was banned' in error_msg:
- error_stats["412_banned"] += 1
- elif 'decode' in error_msg or '解码' in error_msg:
- error_stats["decode_error"] += 1
- elif 'parse_error' in error_msg or 'JSON解析错误' in error_msg:
- error_stats["parse_error"] += 1
- else:
- error_stats["other_error"] += 1
-
- # 对于失效视频,保存到失效表中
- if hasattr(video_data, 'error_type'):
- error_type = getattr(video_data, 'error_type')
- # 永久性错误类型,应保存到失效表
- permanent_error_types = ['not_found', 'invisible', 'api_error', 'parse_error']
-
- if error_type in permanent_error_types:
- # 视频的永久性错误,将其保存到失效视频表
- saved = save_invalid_video(video_data)
- if saved:
- invalid_count += 1
- print(f"已将视频 {getattr(video_data, 'bvid', '未知')} 的错误信息保存到失效表,错误类型: {error_type}")
-
- print(f"跳过保存视频详情:获取数据失败 - {error_msg}")
- continue
-
- if not hasattr(video_data, 'data') or not video_data.data:
- fail_count += 1
- error_stats["empty_data"] += 1
- print("跳过保存视频详情:数据为空")
- continue
-
- # 尝试保存视频详情
- try:
- bvid = video_data.data.get('bvid', '未知BV号')
- title = video_data.data.get('title', '未知标题')
-
- result = save_video_details(video_data.data)
- if result:
- success_count += 1
- print(f"成功保存视频: {title} ({bvid})")
- else:
- fail_count += 1
- error_stats["save_error"] += 1
- print(f"保存视频详情失败: {bvid}")
- except Exception as e:
- fail_count += 1
- error_stats["save_error"] += 1
- print(f"保存视频详情时发生异常: {str(e)}")
-
- # 打印统计信息
- print(f"\n=== 批量保存完成 ===")
- print(f"成功:{success_count},失败:{fail_count},失效视频:{invalid_count},跳过:{skipped_count}")
-
- # 输出错误类型统计
- if fail_count > 0:
- print("\n错误类型统计:")
- for error_type, count in error_stats.items():
- if count > 0:
- print(f"- {error_type}: {count}次")
-
- return {
- "success": success_count,
- "fail": fail_count,
- "invalid": invalid_count,
- "skipped": skipped_count,
- "error_stats": error_stats
- }
-
-async def fetch_and_compare_history(cookie, latest_date, skip_exists=False, process_video_details=False):
- """
- 获取历史记录并与本地最新记录对比
-
- Args:
- cookie: 用户cookie中的SESSDATA
- latest_date: 本地最新的记录日期,格式为YYYY-MM-DD
- skip_exists: 是否跳过已存在的记录
- process_video_details: 是否同时获取视频详情,默认为False
-
- Returns:
- dict: 新的历史记录,按日期分组
- """
- api_url = "https://api.bilibili.com/x/v2/history"
-
- print("\n=== API 请求信息 ===")
- print(f"使用的 Cookie: {cookie}")
-
- url = 'https://api.bilibili.com/x/web-interface/history/cursor'
-
- # 添加更多必要的 cookie 字段
- headers = {
- 'Cookie': f"SESSDATA={cookie}; buvid3=random_string; b_nut=1234567890; buvid4=random_string",
- 'User-Agent': 'Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/91.0.4472.124 Safari/537.36',
- 'Referer': 'https://www.bilibili.com',
- 'Origin': 'https://www.bilibili.com',
- 'Accept': 'application/json, text/plain, */*',
- 'Connection': 'keep-alive'
- }
- print(f"请求头: {headers}")
-
- params = {
- 'ps': 30,
- 'max': '',
- 'view_at': '',
- 'business': '',
- }
-
- # 测试 API 连接
- response = requests.get(url, headers=headers, params=params)
- print(f"\n=== API 响应信息 ===")
- print(f"状态码: {response.status_code}")
- try:
- response_data = response.json()
- if response_data.get('code') == -101:
- print("Cookie 已失效,请更新 SESSDATA")
- return []
- except:
- print(f"响应内容: {response.text}")
-
- all_new_data = []
- all_video_ids = [] # 存储所有需要获取详情的视频ID
- page_count = 0
- last_view_at = None # 记录最后一条数据的时间
- empty_page_count = 0 # 记录连续空页面的次数
- max_empty_pages = 3 # 最大允许的连续空页面次数
-
- if latest_date:
- # 直接使用最新日期的时间戳作为停止条件
- cutoff_timestamp = int(datetime.combine(latest_date, datetime.min.time()).timestamp())
- print(f"设置停止条件:view_at <= {cutoff_timestamp} ({latest_date})")
- else:
- cutoff_timestamp = 0
- print("没有本地数据,抓取所有可用的历史记录。")
+ params = {"ps": 30, "max": "", "view_at": "", "business": ""}
+ cutoff_timestamp = (
+ int(datetime.combine(latest_date, datetime.min.time()).timestamp())
+ if latest_date else 0
+ )
+ new_history = []
while True:
- page_count += 1
- print(f"发送请求获取数据... (第{page_count}页)")
response = requests.get(url, headers=headers, params=params)
-
- if response.status_code == 200:
- try:
- data = response.json()
- if data['code'] != 0:
- print(f"API请求失败,错误码: {data['code']}, 错误信息: {data['message']}")
- break
-
- if 'data' in data and 'list' in data['data']:
- fetched_list = data['data']['list']
- print(f"获取到{len(fetched_list)}条记录,进行对比...")
-
- # 如果获取到0条记录,检查是否是因为到达了最后一页
- if len(fetched_list) == 0:
- empty_page_count += 1
- print(f"连续获取到空页面 {empty_page_count}/{max_empty_pages}")
-
- if empty_page_count >= max_empty_pages:
- print(f"连续{max_empty_pages}次获取到空页面,停止请求。")
- break
-
- if 'cursor' in data['data']:
- # 检查新的游标时间是否大于最后一条记录的时间
- new_view_at = data['data']['cursor']['view_at']
- current_max = data['data']['cursor']['max']
-
- # 如果游标被重置(max变为0或很小的值),说明已经到达末尾
- if current_max == 0 or (last_view_at and current_max < 1000000):
- print(f"检测到游标重置(max={current_max}),停止请求。")
- break
-
- if last_view_at and new_view_at >= last_view_at:
- print(f"检测到重复数据(当前游标时间 {new_view_at} >= 最后记录时间 {last_view_at}),停止请求。")
- break
-
- params['max'] = current_max
- params['view_at'] = new_view_at
- print(f"获取到空页,尝试继续请求。游标更新:max={params['max']}, view_at={params['view_at']}")
- continue
- else:
- print("没有更多数据,停止请求。")
- break
- else:
- # 重置空页面计数
- empty_page_count = 0
-
- # 更新最后一条记录的时间
- if fetched_list:
- last_view_at = fetched_list[-1]['view_at']
- print(f"更新最后记录时间: {last_view_at}")
-
- # 收集所有视频ID,先不进行API调用
- for entry in fetched_list:
- print(f"标题: {entry['title']}, 观看时间: {datetime.fromtimestamp(entry['view_at'])}")
-
- # 从历史记录获取 bvid
- bvid = entry['history'].get('bvid', '')
- if bvid:
- all_video_ids.append(bvid)
-
- new_entries = []
- should_stop = False
-
- for entry in fetched_list:
- view_at = entry['view_at']
- if view_at > cutoff_timestamp:
- new_entries.append(entry)
- else:
- should_stop = True
-
- if new_entries:
- all_new_data.extend(new_entries)
- print(f"找到{len(new_entries)}条新记录。")
-
- if should_stop:
- print("达到停止条件,停止请求。")
- break
-
- if 'cursor' in data['data']:
- current_max = data['data']['cursor']['max']
- params['max'] = current_max
- params['view_at'] = data['data']['cursor']['view_at']
- print(f"请求游标更新:max={params['max']}, view_at={params['view_at']}")
- else:
- print("未能获取游标信息,停止请求。")
- break
-
- await asyncio.sleep(1)
- else:
- print("没有更多的数据或数据结构错误。")
- break
-
- except json.JSONDecodeError:
- print("JSON Decode Error: 无法解析服务器响应")
- break
- else:
- print(f"请求失败,状态码: {response.status_code}")
+ response.raise_for_status()
+ result = response.json()
+ if result.get("code") != 0:
+ raise ValueError(result.get("message", "获取历史记录失败"))
+
+ data = result["data"]
+ records = data["list"]
+ if not records:
break
- # 完成历史记录获取后,使用多线程获取视频详情
- if all_video_ids and process_video_details:
- print(f"\n=== 多线程获取视频详情 ===")
- print(f"总共有 {len(all_video_ids)} 个视频需要获取详情")
-
- # 去重
- unique_video_ids = list(set(all_video_ids))
- print(f"去重后有 {len(unique_video_ids)} 个不同的视频")
-
- # 使用线程池并行获取视频详情 - 增加最大线程数到30
- max_workers = min(30, len(unique_video_ids)) # 最多30个线程
- print(f"使用 {max_workers} 个线程并行获取视频详情")
-
- # 分批处理,避免一次性创建太多线程
- batch_size = 30 # 增加批处理数量
- results = []
-
- for i in range(0, len(unique_video_ids), batch_size):
- batch = unique_video_ids[i:i+batch_size]
- print(f"处理第 {i//batch_size + 1} 批,共 {len(batch)} 个视频")
-
- with concurrent.futures.ThreadPoolExecutor(max_workers=max_workers) as executor:
- # 将每个视频ID分配给线程池,添加skip_exists参数
- future_to_bvid = {
- executor.submit(get_video_info_sync, bvid, cookie, skip_exists): bvid
- for bvid in batch
- }
-
- for future in concurrent.futures.as_completed(future_to_bvid):
- bvid = future_to_bvid[future]
- try:
- result = future.result()
- if result is None: # 跳过的视频
- continue
- if result.status == "success":
- results.append(result)
- print(f"成功获取视频 {bvid} 的详情: {result.data.get('title', '')}")
- else:
- print(f"获取视频 {bvid} 的详情失败: {result.message}")
- except Exception as e:
- print(f"处理视频 {bvid} 时出错: {e}")
-
- # 每批处理完后,批量保存到数据库
- if results:
- print(f"开始批量保存第 {i//batch_size + 1} 批视频详情...")
- batch_result = batch_save_video_details(results)
- total_success = batch_result["success"]
- total_fail = batch_result["fail"]
-
- # 合并错误统计
- if "error_stats" in batch_result:
- for error_type, count in batch_result["error_stats"].items():
- if error_type not in error_stats:
- error_stats[error_type] = 0
- error_stats[error_type] += count
-
- print(f"批次完成: 成功 {batch_result['success']},失败 {batch_result['fail']}")
- results = [] # 清空结果列表,准备下一批
-
- # 批次之间稍微暂停,减轻服务器压力
- time.sleep(1) # 减少暂停时间
- elif all_video_ids:
- print(f"\n跳过视频详情获取 (process_video_details={process_video_details})")
- print(f"如需获取视频详情,请使用/fetch/video-details-stats和/fetch/fetch-video-details接口")
-
- return all_new_data
-
-async def fetch_history(output_dir: str = "history_by_date", skip_exists: bool = False, process_video_details: bool = False) -> dict:
- """主函数:获取B站历史记录并同时获取视频详细信息存入视频库"""
- try:
- # 重新加载配置文件,确保获取最新的SESSDATA
- current_config = load_config()
-
- # 修改这里:直接使用 output_dir 而不是拼接 output 路径
- full_output_dir = get_output_path(output_dir) # 这里 get_output_path 已经会添加 output 前缀
-
- print("\n=== 路径信息 ===")
- print(f"输出目录: {full_output_dir}")
- print(f"目录存在: {os.path.exists(full_output_dir)}")
-
- cookie = current_config.get('SESSDATA', '')
- if not cookie:
- return {"status": "error", "message": "未找到SESSDATA配置"}
+ new_history.extend(record for record in records if record["view_at"] >= cutoff_timestamp)
+ if any(record["view_at"] < cutoff_timestamp for record in records):
+ break
- latest_date = find_latest_local_history(output_dir) # 传入相对路径
- # 由于fetch_and_compare_history现在是异步函数,需要使用await调用
- new_history = await fetch_and_compare_history(cookie, latest_date, skip_exists, process_video_details)
+ cursor = data.get("cursor")
+ if not cursor or not cursor.get("max"):
+ break
+ params["max"] = cursor["max"]
+ params["view_at"] = cursor["view_at"]
+ await asyncio.sleep(1)
- result = {"status": "success", "message": "没有新记录需要更新", "data": {}}
- if new_history:
- save_result = save_history(new_history, output_dir) # 传入相对路径
- result = save_result
-
- # 如果需要处理视频详情
- if process_video_details and save_result["status"] == "success":
- print("\n=== 开始处理新记录的视频详情 ===")
-
- # 获取所有新记录的bvid
- new_bvids = []
- for date, records in new_history.items():
- for record in records:
- if record.get("bvid"):
- new_bvids.append(record["bvid"])
-
- print(f"新记录中包含 {len(new_bvids)} 个视频ID")
-
- # 调用获取视频详情的函数
- if new_bvids:
- video_details_result = await fetch_video_details_only(specific_videos=new_bvids)
- result["video_details_result"] = video_details_result
-
- if video_details_result.get("status") == "success":
- print("成功获取新记录的视频详情")
- else:
- print(f"获取新记录的视频详情时出错: {video_details_result.get('message', '未知错误')}")
- else:
- print("无新视频需要获取详情")
- result["video_details_result"] = {
- "status": "success",
- "message": "no new videos",
- "data": {}
- }
-
- return result
+ return new_history
- except Exception as e:
- logging.error(f"获取历史记录时发生错误: {e}")
- import traceback
- logging.error(traceback.format_exc())
- return {"status": "error", "message": str(e)}
-# 新增: 批量获取历史记录中的视频详情但不重新获取历史记录
-async def fetch_video_details_only(max_videos: int = 0, specific_videos: list = None, use_sessdata: bool = True) -> dict:
- """
- 从历史记录中获取视频ID,批量获取视频详情
-
- Args:
- max_videos: 本次最多处理的视频数量,0表示不限制
- specific_videos: 指定要获取的视频ID列表,如果提供则优先使用这个列表
- use_sessdata: 是否使用SESSDATA进行认证,默认为True
- """
+async def fetch_history(skip_exists: bool = True) -> dict:
+ """获取B站历史记录并按日期保存JSON。"""
try:
- # 确保参数是合法整数
- if max_videos is None:
- max_videos = 0
-
- print("\n=== 开始批量获取视频详情 ===")
-
- # 获取cookie
- current_config = load_config()
- cookie = current_config.get('SESSDATA', '')
+ cookie = load_cookie()
if not cookie:
- return {"status": "error", "message": "未找到SESSDATA配置"}
-
- # 如果没有指定视频列表,则自动获取待处理视频
- if not specific_videos:
- # 获取统计数据,包含待获取视频列表
- stats = await get_video_details_stats()
- if stats["status"] != "success":
- return stats
-
- # 获取待处理视频列表
- videos_to_fetch = stats["data"]["pending_videos"]
- total_videos_to_fetch = len(videos_to_fetch)
-
- if total_videos_to_fetch == 0:
- return {"status": "success", "message": "所有历史记录的视频详情都已获取", "data": {"skipped": True, "processed": 0}}
- else:
- # 使用指定的视频列表
- videos_to_fetch = specific_videos
- total_videos_to_fetch = len(videos_to_fetch)
- print(f"使用指定的视频列表,共 {total_videos_to_fetch} 个视频")
-
- # 限制每次处理的视频数量
- if max_videos > 0 and len(videos_to_fetch) > max_videos:
- print(f"限制处理的视频数量为 {max_videos} 个(总共 {total_videos_to_fetch} 个待处理)")
- videos_to_fetch = videos_to_fetch[:max_videos]
-
- print(f"本次将处理 {len(videos_to_fetch)} 个视频")
-
- # 降低并发线程数,避免过高并发导致412错误
- max_workers = min(15, len(videos_to_fetch)) # 最大15个线程
- total_success = 0
- total_fail = 0
- skipped_invalid_count = 0
-
- # 初始化错误统计
- error_stats = {
- "404_not_found": 0, # 视频不存在或已删除
- "62002_invisible": 0, # 视频已设为私有或被隐藏
- "412_banned": 0, # 请求被禁止/拒绝
- "decode_error": 0, # 解码错误
- "parse_error": 0, # JSON解析错误
- "empty_data": 0, # 数据为空
- "save_error": 0, # 保存过程出错
- "other_error": 0 # 其他错误
- }
-
- # 存储错误视频信息
- error_videos = []
-
- # 分批处理,进一步减小每批的大小
- batch_size = 20 # 确保每批最多20个
-
- # 随机打乱视频顺序,避免按顺序请求被检测
- random.shuffle(videos_to_fetch)
-
- start_time = time.time()
-
- for i in range(0, len(videos_to_fetch), batch_size):
- batch = videos_to_fetch[i:i+batch_size]
- batch_num = i//batch_size + 1
- total_batches = (len(videos_to_fetch)-1)//batch_size + 1
- print(f"处理第 {batch_num}/{total_batches} 批,共 {len(batch)} 个视频")
-
- results = []
- batch_success = 0
- batch_fail = 0
- batch_skipped = 0
-
- with concurrent.futures.ThreadPoolExecutor(max_workers=max_workers) as executor:
- future_to_bvid = {
- executor.submit(get_video_info_sync, bvid, cookie, False, use_sessdata): bvid
- for bvid in batch
- }
-
- for future in concurrent.futures.as_completed(future_to_bvid):
- bvid = future_to_bvid[future]
- try:
- result = future.result()
-
- # 检查是否为已知失效视频
- if result and hasattr(result, 'is_known_invalid') and result.is_known_invalid:
- batch_skipped += 1
- skipped_invalid_count += 1
- print(f"跳过已知失效视频 {bvid}")
- continue
-
- if result and result.status == "success":
- results.append(result)
- batch_success += 1
- print(f"成功获取视频 {bvid} 的详情: {result.data.get('title', '')}")
- else:
- batch_fail += 1
- error_msg = result.message if result and hasattr(result, 'message') else "未知错误"
- error_type = result.error_type if result and hasattr(result, 'error_type') else "unknown"
- print(f"获取视频 {bvid} 的详情失败: {error_msg}, 类型: {error_type}")
-
- # 添加到错误视频列表
- error_videos.append({
- "bvid": bvid,
- "error_type": error_type,
- "error_message": error_msg
- })
- except Exception as e:
- batch_fail += 1
- print(f"处理视频 {bvid} 时出错: {e}")
- # 添加到错误视频列表
- error_videos.append({
- "bvid": bvid,
- "error_type": "exception",
- "error_message": str(e)
- })
-
- # 批量保存结果
- if results:
- batch_result = batch_save_video_details(results)
- total_success += batch_result["success"]
- total_fail += batch_result["fail"] + (batch_fail - batch_result.get("invalid", 0))
-
- # 合并错误统计
- if "error_stats" in batch_result:
- for error_type, count in batch_result["error_stats"].items():
- if error_type in error_stats:
- error_stats[error_type] += count
-
- print(f"批次完成: 成功 {batch_result['success']},失败 {batch_result['fail']},跳过 {batch_skipped}")
- else:
- print(f"批次完成: 没有成功获取的视频,跳过 {batch_skipped}")
- total_fail += batch_fail
-
- # 计算进度
- processed_videos = i + len(batch)
- progress_percentage = (processed_videos / len(videos_to_fetch)) * 100
- elapsed_time = time.time() - start_time
-
- print(f"进度: {processed_videos}/{len(videos_to_fetch)} ({progress_percentage:.2f}%),耗时: {elapsed_time:.2f}秒")
-
- # 批次之间暂停时间增加并随机化
- batch_delay = 3 + random.random() * 4 # 3-7秒随机延迟
- print(f"批次间暂停 {batch_delay:.2f} 秒...")
- time.sleep(batch_delay)
-
- # 如果失败太多,提前停止
- if total_fail > 5 * total_success and total_fail > 10:
- print(f"失败过多 (成功:{total_success},失败:{total_fail}),提前停止任务")
- break
-
- # 计算总耗时
- total_elapsed_time = time.time() - start_time
-
- # 打印最终错误统计
- if total_fail > 0:
- print("\n=== 错误类型统计 ===")
- for error_type, count in error_stats.items():
- if count > 0:
- percentage = (count/total_fail*100) if total_fail > 0 else 0
- print(f"- {error_type}: {count}次 ({percentage:.1f}%)")
-
- # 获取剩余未处理的视频数量
- remaining_videos = total_videos_to_fetch - len(videos_to_fetch)
-
- # 如果使用的是指定视频列表,则不考虑剩余视频
- if specific_videos:
- remaining_videos = 0
-
- # 返回处理结果
- return {
- "status": "success",
- "message": f"批量获取视频详情完成,成功: {total_success},失败: {total_fail},跳过: {skipped_invalid_count}",
- "data": {
- "total_videos": total_videos_to_fetch,
- "processed_videos": len(videos_to_fetch),
- "success_count": total_success,
- "fail_count": total_fail,
- "skipped_invalid_count": skipped_invalid_count,
- "remaining_videos": remaining_videos,
- "elapsed_time": total_elapsed_time,
- "error_stats": error_stats,
- "error_videos": error_videos[:20] # 只返回前20个错误,避免响应过大
- }
- }
-
- except Exception as e:
- error_msg = f"批量获取视频详情时出错: {str(e)}"
- print(error_msg)
- import traceback
- print(traceback.format_exc())
- return {"status": "error", "message": error_msg}
+ return {"status": "error", "message": "未找到SESSDATA配置,请先登录"}
-async def get_invalid_videos_from_db(page=1, limit=50, error_type=None):
- """从数据库中获取失效视频列表"""
- try:
- # 连接数据库
- db_path = get_output_path("video_library.db")
- conn = sqlite3.connect(db_path)
- conn.row_factory = sqlite3.Row # 启用字典游标
- cursor = conn.cursor()
-
- # 构建查询条件
- query_params = []
- where_clause = ""
-
- if error_type:
- where_clause = "WHERE error_type = ?"
- query_params.append(error_type)
-
- # 获取总数
- count_sql = f"""
- SELECT COUNT(*) as total FROM invalid_videos {where_clause}
- """
- cursor.execute(count_sql, query_params)
- total = cursor.fetchone()["total"]
-
- # 计算分页
- offset = (page - 1) * limit
-
- # 查询当前页数据
- select_sql = f"""
- SELECT
- id, bvid, error_type, error_code, error_message,
- first_check_time, last_check_time, check_count
- FROM invalid_videos
- {where_clause}
- ORDER BY last_check_time DESC
- LIMIT ? OFFSET ?
- """
-
- query_params.extend([limit, offset])
- cursor.execute(select_sql, query_params)
-
- rows = cursor.fetchall()
-
- # 转换为列表
- items = []
- for row in rows:
- items.append(dict(row))
-
- conn.close()
-
- # 返回分页结果
- return {
- "total": total,
- "page": page,
- "limit": limit,
- "has_more": total > page * limit,
- "items": items
- }
- except Exception as e:
- print(f"获取失效视频列表失败: {e}")
- import traceback
- print(traceback.format_exc())
- raise e
-
-## 新增: 获取视频详情统计数据
-async def get_video_details_stats() -> dict:
- """
- 获取视频详情的统计数据
- 返回历史记录总数、已获取视频数、失效视频数、未获取视频数等信息
- """
- try:
- print("\n=== 获取视频详情统计数据 ===")
-
- # 查询数据库中已有的历史记录,但尚未获取详情的视频
- history_db_path = get_output_path("bilibili_history.db")
- video_db_path = get_output_path("video_library.db")
-
- # 查询历史记录数据库中的所有bvid
- conn_history = sqlite3.connect(history_db_path)
- cursor_history = conn_history.cursor()
-
- print("查询历史记录数据库中的视频ID...")
-
- # 首先获取所有年份的表
- cursor_history.execute("""
- SELECT name FROM sqlite_master
- WHERE type='table' AND name LIKE 'bilibili_history_%'
- """)
-
- history_tables = cursor_history.fetchall()
-
- if not history_tables:
- return {"status": "error", "message": "未找到历史记录表", "data": None}
-
- print(f"找到以下历史记录表: {[table[0] for table in history_tables]}")
-
- # 构建查询所有年份表的UNION查询
- all_bvids = []
- for table in history_tables:
- table_name = table[0]
- cursor_history.execute(f"""
- SELECT DISTINCT bvid FROM {table_name}
- WHERE bvid IS NOT NULL AND bvid != ''
- """)
- bvids = [row[0] for row in cursor_history.fetchall()]
- all_bvids = list(set(all_bvids + bvids))
- print(f"从表 {table_name} 中找到 {len(bvids)} 个视频ID")
-
- conn_history.close()
-
- total_history_videos = len(all_bvids)
- print(f"历史记录数据库中总共找到 {total_history_videos} 个不同的视频ID")
-
- # 查询视频库中已有的bvid
- conn_video = sqlite3.connect(video_db_path)
- cursor_video = conn_video.cursor()
-
- # 获取已存储详情的视频ID
- try:
- cursor_video.execute("SELECT bvid FROM video_details")
- existing_bvids = {row[0] for row in cursor_video.fetchall()}
- existing_videos_count = len(existing_bvids)
- except sqlite3.OperationalError:
- # 如果表不存在
- existing_bvids = set()
- existing_videos_count = 0
-
- # 获取失效视频ID
- try:
- cursor_video.execute("SELECT bvid FROM invalid_videos")
- invalid_bvids = {row[0] for row in cursor_video.fetchall()}
- invalid_videos_count = len(invalid_bvids)
- except sqlite3.OperationalError:
- # 如果表不存在
- invalid_bvids = set()
- invalid_videos_count = 0
-
- # 按错误类型统计失效视频
- error_type_stats = {}
- try:
- cursor_video.execute("""
- SELECT error_type, COUNT(*) as count
- FROM invalid_videos
- GROUP BY error_type
- """)
- for row in cursor_video.fetchall():
- error_type_stats[row[0]] = row[1]
- except sqlite3.OperationalError:
- # 如果表不存在
- pass
-
- conn_video.close()
-
- # 找出需要获取详情的视频ID (排除已获取和已知失效的)
- videos_to_fetch = [bvid for bvid in all_bvids if bvid not in existing_bvids and bvid not in invalid_bvids]
- pending_videos_count = len(videos_to_fetch)
-
- print(f"\n=== 视频详情统计 ===")
- print(f"历史记录总视频数: {total_history_videos}")
- print(f"已获取详情视频数: {existing_videos_count}")
- print(f"已知失效视频数: {invalid_videos_count}")
- print(f"待获取视频数: {pending_videos_count}")
-
- completion_percentage = ((existing_videos_count + invalid_videos_count) / total_history_videos) * 100 if total_history_videos > 0 else 0
-
- # 返回统计结果
+ latest_date = find_latest_local_history() if skip_exists else None
+ records = await fetch_and_compare_history(cookie, latest_date)
+ os.makedirs(get_output_path("history_by_date"), exist_ok=True)
+ if records:
+ return save_history(records)
return {
"status": "success",
- "message": "成功获取视频详情统计数据",
- "data": {
- "total_history_videos": total_history_videos, # 历史记录总视频数
- "existing_videos_count": existing_videos_count, # 已获取详情的视频数
- "invalid_videos_count": invalid_videos_count, # 已知失效的视频数
- "pending_videos_count": pending_videos_count, # 待获取的视频数
- "completion_percentage": round(completion_percentage, 2), # 完成百分比
- "error_type_stats": error_type_stats, # 失效视频类型统计
- "pending_videos": videos_to_fetch # 待获取的视频ID列表
- }
+ "message": "没有新记录需要更新",
+ "data": {"new_records_count": 0},
}
-
- except Exception as e:
- error_msg = f"获取视频详情统计数据时出错: {str(e)}"
- print(error_msg)
- import traceback
- print(traceback.format_exc())
- return {"status": "error", "message": error_msg, "data": None}
+ except Exception as error:
+ logging.error("获取历史记录失败: %s", error)
+ return {"status": "error", "message": f"获取历史记录失败: {error}"}
diff --git a/scripts/check_data_integrity.py b/scripts/check_data_integrity.py
deleted file mode 100644
index 1eed3cc..0000000
--- a/scripts/check_data_integrity.py
+++ /dev/null
@@ -1,363 +0,0 @@
-import json
-import logging
-import os
-import sqlite3
-from datetime import datetime
-
-# 配置日志
-# 确保输出目录存在
-os.makedirs("output/check", exist_ok=True)
-
-# 设置自定义的日志格式化器,以正确处理中文字符
-class EncodingFormatter(logging.Formatter):
- def format(self, record):
- msg = super().format(record)
- # 确保返回的是原始字符串,不会被转义
- if isinstance(msg, str):
- return msg
- else:
- return str(msg)
-
-# 配置日志处理程序
-formatter = EncodingFormatter('%(asctime)s - %(levelname)s - %(message)s')
-file_handler = logging.FileHandler("output/check/data_integrity_check.log", mode='a', encoding='utf-8')
-file_handler.setFormatter(formatter)
-
-console_handler = logging.StreamHandler()
-console_handler.setFormatter(formatter)
-
-logger = logging.getLogger(__name__)
-logger.setLevel(logging.INFO)
-logger.handlers = [] # 清除可能存在的处理程序
-logger.addHandler(file_handler)
-logger.addHandler(console_handler)
-logger.propagate = False # 防止日志消息传播到根日志器
-
-
-def get_json_files(json_root_path):
- """获取所有JSON文件的路径"""
- json_files = []
-
- for year_dir in os.listdir(json_root_path):
- year_path = os.path.join(json_root_path, year_dir)
- if not os.path.isdir(year_path) or not year_dir.isdigit():
- continue
-
- for month_dir in os.listdir(year_path):
- month_path = os.path.join(year_path, month_dir)
- if not os.path.isdir(month_path) or not month_dir.isdigit():
- continue
-
- for day_file in os.listdir(month_path):
- if not day_file.endswith('.json'):
- continue
-
- day_path = os.path.join(month_path, day_file)
- json_files.append({
- 'path': day_path,
- 'year': int(year_dir),
- 'month': int(month_dir),
- 'day': int(day_file.split('.')[0])
- })
-
- return json_files
-
-
-def count_records_in_json_file(file_path):
- """统计JSON文件中的记录数量,并返回所有记录标题"""
- try:
- with open(file_path, 'r', encoding='utf-8') as f:
- data = json.load(f)
- titles = [item.get('title', '未知标题') for item in data]
- return len(data), titles
- except Exception as e:
- logger.error(f"读取JSON文件 {file_path} 时出错: {e}")
- return 0, []
-
-
-def get_db_tables(db_path):
- """获取数据库中的所有表名"""
- try:
- conn = sqlite3.connect(db_path)
- cursor = conn.cursor()
- cursor.execute("SELECT name FROM sqlite_master WHERE type='table';")
- tables = [row[0] for row in cursor.fetchall()]
- conn.close()
- return tables
- except Exception as e:
- logger.error(f"获取数据库表时出错: {e}")
- return []
-
-
-def count_records_in_db_table(db_path, table_name):
- """统计数据库表中的记录数量"""
- try:
- conn = sqlite3.connect(db_path)
- cursor = conn.cursor()
- cursor.execute(f"SELECT COUNT(*) FROM {table_name}")
- count = cursor.fetchone()[0]
- conn.close()
- return count
- except Exception as e:
- logger.error(f"统计表 {table_name} 记录数时出错: {e}")
- return 0
-
-
-def get_records_by_date(db_path, table_name, year, month, day):
- """获取某一天的数据库记录"""
- try:
- # 计算目标日期的时间戳范围
- start_date = datetime(year, month, day).timestamp()
- end_date = datetime(year, month, day, 23, 59, 59).timestamp()
-
- conn = sqlite3.connect(db_path)
- cursor = conn.cursor()
- cursor.execute(f"SELECT title, view_at FROM {table_name} WHERE view_at >= ? AND view_at <= ?",
- (start_date, end_date))
- records = cursor.fetchall()
- titles = [record[0] for record in records]
- conn.close()
- return len(records), titles
- except Exception as e:
- logger.error(f"获取{year}年{month}月{day}日的记录时出错: {e}")
- return 0, []
-
-
-def check_data_integrity(db_path=None, json_root_path=None):
- """检查数据完整性"""
- # 配置路径
- if db_path is None:
- db_path = os.path.join('output', 'bilibili_history.db')
- if json_root_path is None:
- json_root_path = os.path.join('output', 'history_by_date')
-
- logger.info("开始数据完整性检查...")
- logger.info(f"数据库路径: {db_path}")
- logger.info(f"JSON文件路径: {json_root_path}")
-
- # 创建输出目录
- output_dir = os.path.join("output", "check")
- os.makedirs(output_dir, exist_ok=True)
-
- results = {
- "total_json_files": 0,
- "total_json_records": 0,
- "total_db_records": 0,
- "db_tables": [],
- "missing_records": [],
- "extra_records": []
- }
-
- # 获取数据库表
- tables = get_db_tables(db_path)
- results["db_tables"] = tables
- logger.info(f"数据库包含以下表: {', '.join(tables)}")
-
- # 获取历史表(以bilibili_history_开头的表)
- history_tables = [table for table in tables if table.startswith('bilibili_history_')]
-
- # 遍历所有JSON文件
- json_files = get_json_files(json_root_path)
- results["total_json_files"] = len(json_files)
- logger.info(f"找到 {len(json_files)} 个JSON文件")
-
- all_json_records = 0
- all_db_records = 0
-
- for file_info in json_files:
- file_path = file_info['path']
- year = file_info['year']
- month = file_info['month']
- day = file_info['day']
-
- # 统计JSON文件中的记录
- json_count, json_titles = count_records_in_json_file(file_path)
- all_json_records += json_count
-
- if json_count == 0:
- logger.warning(f"JSON文件为空: {file_path}")
- continue
-
- # 查找对应年份的数据库表
- table_name = f"bilibili_history_{year}"
- if table_name not in history_tables:
- logger.error(f"数据库中缺少表 {table_name}")
- results["missing_records"].append({
- "year": year,
- "month": month,
- "day": day,
- "missing_count": json_count,
- "missing_titles": json_titles,
- "reason": f"数据库中缺少表 {table_name}"
- })
- continue
-
- # 获取数据库中对应日期的记录
- db_count, db_titles = get_records_by_date(db_path, table_name, year, month, day)
- all_db_records += db_count
-
- # 比较记录数量
- if json_count > db_count:
- missing_count = json_count - db_count
- # 找出缺少的标题
- missing_titles = [title for title in json_titles if title not in db_titles]
-
- results["missing_records"].append({
- "year": year,
- "month": month,
- "day": day,
- "missing_count": missing_count,
- "missing_titles": missing_titles[:10] if len(missing_titles) > 10 else missing_titles, # 最多显示10个
- "reason": "数据库记录少于JSON文件"
- })
- logger.warning(f"{year}年{month}月{day}日 - 数据库中缺少 {missing_count} 条记录")
-
- elif json_count < db_count:
- extra_count = db_count - json_count
- # 找出多余的标题
- extra_titles = [title for title in db_titles if title not in json_titles]
-
- results["extra_records"].append({
- "year": year,
- "month": month,
- "day": day,
- "extra_count": extra_count,
- "extra_titles": extra_titles[:10] if len(extra_titles) > 10 else extra_titles, # 最多显示10个
- "reason": "数据库记录多于JSON文件"
- })
- logger.warning(f"{year}年{month}月{day}日 - 数据库中多出 {extra_count} 条记录")
-
- # 统计总记录数
- results["total_json_records"] = all_json_records
- results["total_db_records"] = all_db_records
-
- for table in history_tables:
- table_count = count_records_in_db_table(db_path, table)
- logger.info(f"表 {table} 中有 {table_count} 条记录")
-
- if all_json_records > all_db_records:
- logger.error(f"总缺少记录数: {all_json_records - all_db_records}")
- elif all_json_records < all_db_records:
- logger.error(f"总多余记录数: {all_db_records - all_json_records}")
- else:
- logger.info("JSON文件和数据库中的记录数量完全匹配")
-
- # 保存结果到JSON文件
- result_file = os.path.join(output_dir, "data_integrity_results.json")
- with open(result_file, 'w', encoding='utf-8') as f:
- json.dump(results, f, ensure_ascii=False, indent=4)
-
- logger.info(f"检查完成,结果已保存到 {result_file}")
-
- # 生成报告
- report_file = generate_report(results)
-
- return {
- "success": True,
- "result_file": result_file,
- "report_file": report_file,
- "total_json_files": results["total_json_files"],
- "total_json_records": results["total_json_records"],
- "total_db_records": results["total_db_records"],
- "missing_records_count": len(results["missing_records"]),
- "extra_records_count": len(results["extra_records"]),
- "difference": all_json_records - all_db_records
- }
-
-
-def generate_report(results):
- """生成报告"""
- # 创建输出目录
- output_dir = os.path.join("output", "check")
- os.makedirs(output_dir, exist_ok=True)
-
- report = ["# 数据完整性检查报告\n"]
-
- # 基本信息
- report.append(f"## 基本信息\n")
- report.append(f"* 检查时间: {datetime.now().strftime('%Y-%m-%d %H:%M:%S')}")
- report.append(f"* JSON文件总数: {results['total_json_files']}")
- report.append(f"* JSON记录总数: {results['total_json_records']}")
- report.append(f"* 数据库记录总数: {results['total_db_records']}")
- report.append(f"* 数据库表: {', '.join(results['db_tables'])}\n")
-
- # 总体差异
- diff = results['total_json_records'] - results['total_db_records']
- if diff > 0:
- report.append(f"## 总体情况: 数据库缺少 {diff} 条记录\n")
- elif diff < 0:
- report.append(f"## 总体情况: 数据库多出 {-diff} 条记录\n")
- else:
- report.append(f"## 总体情况: 数据库和JSON文件记录数一致\n")
-
- # 缺少的记录
- if results["missing_records"]:
- report.append(f"## 缺少的记录 (共 {len(results['missing_records'])} 天)\n")
- for item in results["missing_records"]:
- report.append(f"### {item['year']}年{item['month']}月{item['day']}日 - 缺少 {item['missing_count']} 条记录")
- report.append(f"原因: {item['reason']}")
- if item['missing_titles']:
- report.append("缺少的标题示例:")
- for title in item['missing_titles']:
- report.append(f"* {title}")
- report.append("")
-
- # 多余的记录
- if results["extra_records"]:
- report.append(f"## 多余的记录 (共 {len(results['extra_records'])} 天)\n")
- for item in results["extra_records"]:
- report.append(f"### {item['year']}年{item['month']}月{item['day']}日 - 多出 {item['extra_count']} 条记录")
- report.append(f"原因: {item['reason']}")
- if item['extra_titles']:
- report.append("多余的标题示例:")
- for title in item['extra_titles']:
- report.append(f"* {title}")
- report.append("")
-
- # 保存报告
- report_file = os.path.join(output_dir, "data_integrity_report.md")
- with open(report_file, 'w', encoding='utf-8') as f:
- f.write('\n'.join(report))
-
- logger.info(f"报告已保存到 {report_file}")
- return report_file
-
-
-def main():
- db_path = os.path.join('output', 'bilibili_history.db')
- json_root_path = os.path.join('output', 'history_by_date')
-
- print("=" * 50)
- print("开始检查数据完整性...")
- print(f"数据库路径: {db_path}")
- print(f"JSON文件路径: {json_root_path}")
- print("=" * 50)
-
- if not os.path.exists(db_path):
- print(f"错误: 数据库文件不存在: {db_path}")
- return
-
- if not os.path.exists(json_root_path):
- print(f"错误: JSON文件目录不存在: {json_root_path}")
- return
-
- results = check_data_integrity(db_path, json_root_path)
-
- print("\n" + "=" * 50)
- print(f"检查完成! 详细结果已保存到 {results['report_file']}")
- print("=" * 50)
-
- # 简要报告
- diff = results['difference']
- if diff > 0:
- print(f"数据库总共缺少 {diff} 条记录")
- if results["missing_records_count"] > 0:
- print(f"\n缺少记录的日期数: {results['missing_records_count']}")
- elif diff < 0:
- print(f"数据库总共多出 {-diff} 条记录")
- else:
- print("数据库和JSON文件记录数一致")
-
-
-if __name__ == "__main__":
- main()
diff --git a/scripts/clean_data.py b/scripts/clean_data.py
deleted file mode 100644
index eb199cf..0000000
--- a/scripts/clean_data.py
+++ /dev/null
@@ -1,57 +0,0 @@
-import json
-import os
-
-from scripts.utils import load_config, get_base_path, get_output_path
-
-config = load_config()
-
-def clean_history_data():
- full_input_folder = get_output_path('history_by_date')
- full_output_folder = get_output_path('cleaned_history_by_date')
-
- if not os.path.exists(full_input_folder):
- print(f"输入文件夹 '{full_input_folder}' 不存在。")
- return {"status": "error", "message": f"输入文件夹 '{full_input_folder}' 不存在。"}
-
- cleaned_files = 0
- for year in os.listdir(full_input_folder):
- year_path = os.path.join(full_input_folder, year)
- if os.path.isdir(year_path) and year.isdigit():
- for month in os.listdir(year_path):
- month_path = os.path.join(year_path, month)
- if os.path.isdir(month_path) and month.isdigit():
- for day_file in os.listdir(month_path):
- if day_file.endswith('.json'):
- input_file = os.path.join(month_path, day_file)
- output_file = os.path.join(full_output_folder, year, month, day_file)
-
- # 确保输出目录存在
- os.makedirs(os.path.dirname(output_file), exist_ok=True)
-
- with open(input_file, 'r', encoding='utf-8') as f:
- data = json.load(f)
-
- # 清理数据
- cleaned_data = clean_data(data, config['fields_to_remove'])
-
- # 保存清理后的数据
- with open(output_file, 'w', encoding='utf-8') as f:
- json.dump(cleaned_data, f, ensure_ascii=False, indent=4)
-
- cleaned_files += 1
-
- message = f"数据清理完成。共处理 {cleaned_files} 个文件。"
- return {"status": "success", "message": message}
-
-def clean_data(data, fields_to_remove):
- cleaned_data = []
- for item in data:
- cleaned_item = {key: value for key, value in item.items() if key not in fields_to_remove}
- if 'history' in item:
- cleaned_item['history'] = {key: value for key, value in item['history'].items() if key not in fields_to_remove}
- cleaned_data.append(cleaned_item)
- return cleaned_data
-
-if __name__ == "__main__":
- result = clean_history_data()
- print(result["message"])
diff --git a/scripts/comment_fetcher.py b/scripts/comment_fetcher.py
deleted file mode 100644
index 0416af0..0000000
--- a/scripts/comment_fetcher.py
+++ /dev/null
@@ -1,384 +0,0 @@
-import json
-import os
-import sqlite3
-import time
-from datetime import datetime
-from typing import Dict, List
-
-import requests
-
-
-def create_comments_table(connection):
- """创建评论表"""
- create_table_sql = """
- CREATE TABLE IF NOT EXISTS comments (
- rpid TEXT PRIMARY KEY,
- uid TEXT NOT NULL,
- message TEXT NOT NULL,
- time INTEGER NOT NULL,
- rank INTEGER NOT NULL,
- rootid TEXT,
- parentid TEXT,
- oid TEXT NOT NULL,
- type INTEGER NOT NULL,
- fetch_time INTEGER NOT NULL
- );
- """
-
- create_indexes = [
- "CREATE INDEX IF NOT EXISTS idx_comments_uid ON comments (uid);",
- "CREATE INDEX IF NOT EXISTS idx_comments_time ON comments (time);",
- "CREATE INDEX IF NOT EXISTS idx_comments_fetch_time ON comments (fetch_time);"
- ]
-
- # 创建用户表
- create_users_table_sql = """
- CREATE TABLE IF NOT EXISTS comment_users (
- uid TEXT PRIMARY KEY,
- first_fetch_time INTEGER NOT NULL,
- last_fetch_time INTEGER NOT NULL
- );
- """
-
- try:
- cursor = connection.cursor()
- cursor.execute(create_table_sql)
-
- # 创建索引
- for index_sql in create_indexes:
- cursor.execute(index_sql)
-
- # 创建用户表
- cursor.execute(create_users_table_sql)
-
- connection.commit()
- print("评论表和用户表创建成功")
- except Exception as e:
- print(f"创建表时发生错误: {e}")
- raise
-
-def check_user_exists(connection, uid: str) -> bool:
- """检查用户是否存在于用户表中"""
- query = "SELECT 1 FROM comment_users WHERE uid = ?"
- cursor = connection.cursor()
- cursor.execute(query, (uid,))
- return cursor.fetchone() is not None
-
-def update_user_record(connection, uid: str):
- """更新或插入用户记录"""
- current_time = int(time.time())
-
- # 先检查用户是否存在
- if check_user_exists(connection, uid):
- # 更新最后获取时间
- update_sql = """
- UPDATE comment_users
- SET last_fetch_time = ?
- WHERE uid = ?
- """
- connection.cursor().execute(update_sql, (current_time, uid))
- else:
- # 插入新用户记录
- insert_sql = """
- INSERT INTO comment_users (uid, first_fetch_time, last_fetch_time)
- VALUES (?, ?, ?)
- """
- connection.cursor().execute(insert_sql, (uid, current_time, current_time))
-
- connection.commit()
- print(f"用户记录 {uid} 已更新")
-
-def fetch_comments(uid: str, mode: str = "0", keyword: str = "") -> List[Dict]:
- """获取用户评论数据"""
- base_url = "https://api.aicu.cc/api/v3/search/getreply"
- all_replies = []
- page = 1
- page_size = 500 # 使用最大页面大小
-
- while True:
- params = {
- "uid": uid,
- "pn": str(page),
- "ps": str(page_size),
- "mode": mode,
- "keyword": keyword
- }
-
- try:
- response = requests.get(base_url, params=params)
- response.raise_for_status()
- data = response.json()
-
- if data["code"] != 0:
- print(f"API返回错误: {data['message']}")
- break
-
- replies = data["data"]["replies"]
- if not replies:
- break
-
- all_replies.extend(replies)
-
- if data["data"]["cursor"]["is_end"]:
- break
-
- page += 1
- time.sleep(1) # 添加延迟避免请求过快
-
- except Exception as e:
- print(f"获取评论数据时发生错误: {e}")
- break
-
- return all_replies
-
-def save_comments_to_file(uid: str, comments: List[Dict]):
- """保存评论数据到JSON文件"""
- timestamp = int(time.time())
- output_dir = os.path.join("output", "comment", uid)
- os.makedirs(output_dir, exist_ok=True)
-
- file_path = os.path.join(output_dir, f"{timestamp}.json")
- with open(file_path, "w", encoding="utf-8") as f:
- json.dump(comments, f, ensure_ascii=False, indent=2)
- print(f"评论数据已保存到: {file_path}")
-
- return file_path
-
-def create_connection():
- """创建SQLite数据库连接"""
- try:
- db_path = os.path.join("output", "database")
- os.makedirs(db_path, exist_ok=True)
- db_file = os.path.join(db_path, "bilibili_comments.db")
-
- conn = sqlite3.connect(db_file)
- print(f"成功连接到评论数据库: {db_file}")
- return conn
- except sqlite3.Error as e:
- print(f"连接数据库时发生错误: {e}")
- raise
-
-def insert_comments_to_db(connection, comments: List[Dict], uid: str):
- """将评论数据插入到数据库"""
- insert_sql = """
- INSERT OR REPLACE INTO comments (
- rpid, uid, message, time, rank, rootid, parentid, oid, type, fetch_time
- ) VALUES (?, ?, ?, ?, ?, ?, ?, ?, ?, ?)
- """
-
- fetch_time = int(time.time())
- data_to_insert = []
-
- for comment in comments:
- parent = comment.get("parent", {})
- dyn = comment.get("dyn", {})
-
- record = (
- comment["rpid"],
- uid,
- comment["message"],
- comment["time"],
- comment["rank"],
- parent.get("rootid"),
- parent.get("parentid"),
- str(dyn.get("oid", 0)), # 转换为字符串
- dyn.get("type", 0),
- fetch_time
- )
- data_to_insert.append(record)
-
- if data_to_insert:
- cursor = connection.cursor()
- try:
- cursor.executemany(insert_sql, data_to_insert)
- connection.commit()
- print(f"成功插入 {len(data_to_insert)} 条评论数据")
- except sqlite3.Error as e:
- connection.rollback()
- print(f"插入数据时发生错误: {e}")
-
-def fetch_and_save_comments(uid: str, mode: str = "0", keyword: str = ""):
- """获取并保存用户评论数据"""
- # 获取评论数据
- comments = fetch_comments(uid, mode, keyword)
-
- # 创建数据库连接
- connection = create_connection()
- try:
- create_comments_table(connection)
-
- # 无论是否获取到评论,都更新用户记录
- update_user_record(connection, uid)
-
- if not comments:
- print("未获取到评论数据")
- return {
- "message": "未获取到评论数据",
- "total_count": 0,
- "latest_comment_time": None
- }
-
- # 保存到文件
- save_comments_to_file(uid, comments)
-
- # 保存到数据库
- insert_comments_to_db(connection, comments, uid)
- finally:
- connection.close()
-
- # 获取最新评论时间(第一条数据的时间)
- latest_time = comments[0]["time"]
- # 转换为北京时间
- latest_time_str = datetime.fromtimestamp(latest_time).strftime("%Y-%m-%d %H:%M:%S")
-
- return {
- "message": "评论数据获取成功",
- "total_count": len(comments),
- "latest_comment_time": latest_time_str
- }
-
-def query_comments(connection, uid: str, page: int = 1, page_size: int = 20,
- comment_type: str = "all", keyword: str = "", comment_type_filter: int = None) -> Dict:
- """
- 查询用户评论数据
-
- Args:
- connection: 数据库连接
- uid: 用户ID
- page: 页码,从1开始
- page_size: 每页数量
- comment_type: 评论类型,可选值:all(全部), root(一级评论), reply(二级评论)
- keyword: 关键词,用于模糊匹配评论内容
- comment_type_filter: 评论类型筛选(type字段),例如:1(视频评论),17(动态评论)等
-
- Returns:
- dict: 包含评论列表和总数的字典
- """
- # 构建基础查询条件
- conditions = ["uid = ?"]
- params = [uid]
-
- # 添加评论类型条件
- if comment_type == "root":
- conditions.append("parentid IS NULL")
- elif comment_type == "reply":
- conditions.append("parentid IS NOT NULL")
-
- # 添加评论类型筛选条件
- if comment_type_filter is not None:
- conditions.append("type = ?")
- params.append(comment_type_filter)
-
- # 添加关键词条件
- if keyword:
- conditions.append("message LIKE ?")
- params.append(f"%{keyword}%")
-
- # 构建WHERE子句
- where_clause = " AND ".join(conditions)
-
- # 计算总数
- count_sql = f"""
- SELECT COUNT(*) FROM comments WHERE {where_clause}
- """
- cursor = connection.cursor()
- cursor.execute(count_sql, params)
- total_count = cursor.fetchone()[0]
-
- # 计算偏移量
- offset = (page - 1) * page_size
-
- # 构建查询SQL
- query_sql = f"""
- SELECT rpid, uid, message, time, rank, rootid, parentid, oid, type, fetch_time
- FROM comments
- WHERE {where_clause}
- ORDER BY time DESC
- LIMIT ? OFFSET ?
- """
-
- # 添加分页参数
- params.extend([page_size, offset])
-
- # 执行查询
- cursor.execute(query_sql, params)
- rows = cursor.fetchall()
-
- # 转换结果为字典列表
- comments = []
- for row in rows:
- comment = {
- "rpid": row[0],
- "uid": row[1],
- "message": row[2],
- "time": row[3],
- "rank": row[4],
- "rootid": row[5],
- "parentid": row[6],
- "oid": row[7], # 已经是字符串了
- "type": row[8],
- "fetch_time": row[9]
- }
- # 转换时间戳为可读时间(直接转换,不需要加8小时)
- comment["time_str"] = datetime.fromtimestamp(comment["time"]).strftime("%Y-%m-%d %H:%M:%S")
- comment["fetch_time_str"] = datetime.fromtimestamp(comment["fetch_time"]).strftime("%Y-%m-%d %H:%M:%S")
- comments.append(comment)
-
- return {
- "total": total_count,
- "page": page,
- "page_size": page_size,
- "total_pages": (total_count + page_size - 1) // page_size,
- "comments": comments
- }
-
-def get_user_comments(uid: str, page: int = 1, page_size: int = 20,
- comment_type: str = "all", keyword: str = "", comment_type_filter: int = None) -> Dict:
- """
- 获取用户评论,如果用户不存在则先获取数据
-
- Args:
- uid: 用户ID
- page: 页码,从1开始
- page_size: 每页数量
- comment_type: 评论类型,可选值:all(全部), root(一级评论), reply(二级评论)
- keyword: 关键词,用于模糊匹配评论内容
- comment_type_filter: 评论类型筛选(type字段),例如:1(视频评论),17(动态评论)等
-
- Returns:
- dict: 包含评论列表和总数的字典
- """
- connection = create_connection()
- try:
- create_comments_table(connection)
-
- # 检查用户是否存在
- if not check_user_exists(connection, uid):
- print(f"用户 {uid} 不存在,先获取数据")
- connection.close() # 先关闭当前连接
-
- # 获取用户评论数据
- fetch_and_save_comments(uid)
-
- # 重新连接数据库
- connection = create_connection()
-
- # 查询评论数据
- result = query_comments(
- connection=connection,
- uid=uid,
- page=page,
- page_size=page_size,
- comment_type=comment_type,
- keyword=keyword,
- comment_type_filter=comment_type_filter
- )
- return result
- finally:
- connection.close()
-
-if __name__ == "__main__":
- # 示例使用
- uid = "17497789" # 替换为实际的用户ID
- result = get_user_comments(uid)
- print(f"获取结果: {result}")
\ No newline at end of file
diff --git a/scripts/dynamic_db.py b/scripts/dynamic_db.py
deleted file mode 100644
index d8a5ef9..0000000
--- a/scripts/dynamic_db.py
+++ /dev/null
@@ -1,608 +0,0 @@
-import os
-import json
-import sqlite3
-from datetime import datetime
-from typing import Iterable, Optional, Tuple, Dict, Any, List
-from loguru import logger
-
-from scripts.utils import get_database_path
-from scripts.dynamic_media import collect_image_urls
-
-
-def _get_db_path() -> str:
- """获取动态数据数据库路径"""
- return get_database_path('bilibili_dynamic.db')
-
-
-def _ensure_schema(conn: sqlite3.Connection) -> None:
- """确保动态相关表结构存在"""
- cursor = conn.cursor()
-
-
-
- # 规范化主表:核心信息
- cursor.execute(
- """
- CREATE TABLE IF NOT EXISTS dynamic_core (
- host_mid TEXT NOT NULL,
- id_str TEXT NOT NULL,
- type TEXT,
- visible INTEGER,
- publish_ts INTEGER,
- comment_id_str TEXT,
- comment_type INTEGER,
- rid_str TEXT,
- txt TEXT,
- author_name TEXT,
- bvid TEXT,
- title TEXT,
- cover TEXT,
- desc TEXT,
- article_title TEXT,
- article_covers TEXT,
- opus_title TEXT,
- opus_summary_text TEXT,
- media_locals TEXT,
- media_count INTEGER,
- live_media_locals TEXT,
- live_media_count INTEGER,
- fetch_time INTEGER NOT NULL,
- PRIMARY KEY (host_mid, id_str)
- )
- """
- )
-
- # media_urls 字段移除:不需要旧数据迁移
- cursor.execute(
- """
- CREATE INDEX IF NOT EXISTS idx_dynamic_core_publish_ts
- ON dynamic_core(publish_ts)
- """
- )
-
- # 作者信息
- cursor.execute(
- """
- CREATE TABLE IF NOT EXISTS dynamic_author (
- host_mid TEXT NOT NULL,
- id_str TEXT NOT NULL,
- author_mid TEXT,
- author_name TEXT,
- face TEXT,
- PRIMARY KEY (host_mid, id_str)
- )
- """
- )
-
- # 统计信息
- cursor.execute(
- """
- CREATE TABLE IF NOT EXISTS dynamic_stat (
- host_mid TEXT NOT NULL,
- id_str TEXT NOT NULL,
- like_count INTEGER,
- comment_count INTEGER,
- repost_count INTEGER,
- view_count INTEGER,
- PRIMARY KEY (host_mid, id_str)
- )
- """
- )
-
-
- # 话题
- cursor.execute(
- """
- CREATE TABLE IF NOT EXISTS dynamic_topic (
- host_mid TEXT NOT NULL,
- id_str TEXT NOT NULL,
- topic_name TEXT,
- jump_url TEXT,
- PRIMARY KEY (host_mid, id_str)
- )
- """
- )
-
-
-
-
- # major: 图文(opus)
- cursor.execute(
- """
- CREATE TABLE IF NOT EXISTS major_opus_pics (
- host_mid TEXT NOT NULL,
- id_str TEXT NOT NULL,
- idx INTEGER NOT NULL,
- url TEXT NOT NULL,
- PRIMARY KEY (host_mid, id_str, idx)
- )
- """
- )
-
- # major: archive 跳转URL列表(逐条展开)
- cursor.execute(
- """
- CREATE TABLE IF NOT EXISTS major_archive_jump_urls (
- host_mid TEXT NOT NULL,
- id_str TEXT NOT NULL,
- idx INTEGER NOT NULL,
- url TEXT NOT NULL,
- PRIMARY KEY (host_mid, id_str, idx)
- )
- """
- )
-
- conn.commit()
-
-
-def get_connection() -> sqlite3.Connection:
- """获取数据库连接(并自动创建表结构)"""
- db_path = _get_db_path()
- os.makedirs(os.path.dirname(db_path), exist_ok=True)
- conn = sqlite3.connect(db_path)
- _ensure_schema(conn)
- return conn
-
-
-
-
-
-
-
-
-def dynamic_core_exists(conn: sqlite3.Connection, host_mid: int, id_str: str) -> bool:
- """判断某条动态是否已存在于核心表中"""
- cursor = conn.cursor()
- cursor.execute(
- """
- SELECT 1 FROM dynamic_core WHERE host_mid = ? AND id_str = ? LIMIT 1
- """,
- (str(host_mid), str(id_str)),
- )
- return cursor.fetchone() is not None
-
-
-def _to_int(value: Any) -> Optional[int]:
- try:
- if value is None:
- return None
- return int(value)
- except Exception:
- return None
-
-
-def save_normalized_dynamic_item(conn: sqlite3.Connection, host_mid: int, item: Dict[str, Any]) -> None:
- """将动态条目按多表结构保存/更新
-
- - 核心信息 dynamic_core
- - 作者 dynamic_author
- - 统计 dynamic_stat
- - 正文 dynamic_desc
- - 话题 dynamic_topic
- - major 分类型:archive / draw / article / opus
- """
- cursor = conn.cursor()
- fetch_time = int(datetime.now().timestamp())
- logger.debug(f"normalize.begin host_mid={host_mid}")
-
- basic = item.get("basic", {}) if isinstance(item, dict) else {}
- modules_raw = item.get("modules")
- # 兼容 modules 既可能为对象也可能为数组
- module_author = {}
- module_stat = {}
- module_dynamic = {}
- if isinstance(modules_raw, dict):
- module_author = modules_raw.get("module_author", {})
- module_stat = modules_raw.get("module_stat", {})
- module_dynamic = modules_raw.get("module_dynamic", {})
- elif isinstance(modules_raw, list):
- for mod in modules_raw:
- if not isinstance(mod, dict):
- continue
- mtype = mod.get("module_type")
- # 新版结构将内容放在同级键名里,例如 {"module_author": {...}, "module_type": "MODULE_TYPE_AUTHOR"}
- if mtype == "MODULE_TYPE_AUTHOR" and not module_author:
- module_author = mod.get("module_author", {})
- elif mtype == "MODULE_TYPE_STAT" and not module_stat:
- module_stat = mod.get("module_stat", {})
- elif mtype == "MODULE_TYPE_DYNAMIC" and not module_dynamic:
- module_dynamic = mod.get("module_dynamic", {})
-
- id_str = (
- item.get("id_str")
- or basic.get("id_str")
- or str(item.get("id"))
- )
- if not id_str:
- logger.warning("normalize.skip: missing id_str")
- return
- logger.debug(f"normalize.id id_str={id_str}")
-
- # 核心信息
- publish_ts = _to_int(module_author.get("pub_ts"))
- comment_id_str = basic.get("comment_id_str")
- comment_type = _to_int(basic.get("comment_type"))
- rid_str = basic.get("rid_str")
- visible = item.get("visible")
-
- # 作者名/头像URL
- author_name = module_author.get("name") or module_author.get("uname")
- avatar = module_author.get("avatar")
- if isinstance(avatar, dict):
- fl = avatar.get("fallback_layers", {})
- layers = fl.get("layers") if isinstance(fl, dict) else None
- if isinstance(layers, list):
- for layer in layers:
- if not isinstance(layer, dict):
- continue
- res = layer.get("resource", {})
- if isinstance(res, dict):
- res_img = res.get("res_image", {})
- if isinstance(res_img, dict):
- img_src = res_img.get("image_src", {})
- if isinstance(img_src, dict):
- remote = img_src.get("remote", {})
- if isinstance(remote, dict) and remote.get("url"):
- author_face_url = remote.get("url")
- break
-
- # 文本
- txt = None
- desc_obj = module_dynamic.get("desc") if isinstance(module_dynamic, dict) else None
- if isinstance(desc_obj, dict):
- txt = desc_obj.get("text")
- elif isinstance(desc_obj, str):
- txt = desc_obj
- if not txt and isinstance(modules_raw, list):
- for mod in modules_raw:
- if isinstance(mod, dict) and isinstance(mod.get("module_desc"), dict):
- txt = mod.get("module_desc", {}).get("text")
- if txt:
- break
-
- # 媒体信息不再从单独表中获取,直接设置为空
- media_locals_joined = None
- media_count = 0
-
- # 提取 archive、article 和 opus 信息到核心表
- archive_bvid = None
- archive_title = None
- archive_cover = None
- archive_desc = None
- article_title = None
- article_covers = None
- opus_title = None
- opus_summary_text = None
- major = module_dynamic.get("major") if isinstance(module_dynamic, dict) else None
- if isinstance(major, dict):
- if isinstance(major.get("archive"), dict):
- arc = major["archive"]
- archive_bvid = arc.get("bvid")
- archive_title = arc.get("title")
- archive_cover = arc.get("cover")
- archive_desc = arc.get("desc")
- if isinstance(major.get("article"), dict):
- ar = major["article"]
- article_title = ar.get("title")
- covers = ar.get("covers") if isinstance(ar, dict) else None
- if isinstance(covers, list) and covers:
- import json
- article_covers = json.dumps(covers)
- if isinstance(major.get("opus"), dict):
- opus = major["opus"]
- opus_title = opus.get("title")
- summary = opus.get("summary")
- if isinstance(summary, dict):
- opus_summary_text = summary.get("text")
-
- logger.info(f"normalize.core.upsert begin host_mid={host_mid} id_str={id_str} media_count={media_count}")
- cursor.execute(
- """
- INSERT INTO dynamic_core (host_mid, id_str, type, visible, publish_ts, comment_id_str, comment_type, rid_str,
- txt, author_name, bvid, title, cover, desc, article_title, article_covers,
- opus_title, opus_summary_text, media_locals, media_count, live_media_locals, live_media_count,
- fetch_time)
- VALUES (?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?)
- ON CONFLICT(host_mid, id_str) DO UPDATE SET
- type = excluded.type,
- visible = excluded.visible,
- publish_ts = excluded.publish_ts,
- comment_id_str = excluded.comment_id_str,
- comment_type = excluded.comment_type,
- rid_str = excluded.rid_str,
- txt = excluded.txt,
- author_name = excluded.author_name,
- bvid = excluded.bvid,
- title = excluded.title,
- cover = excluded.cover,
- desc = excluded.desc,
- article_title = excluded.article_title,
- article_covers = excluded.article_covers,
- opus_title = excluded.opus_title,
- opus_summary_text = excluded.opus_summary_text,
- media_locals = excluded.media_locals,
- media_count = excluded.media_count,
- live_media_locals = excluded.live_media_locals,
- live_media_count = excluded.live_media_count,
- fetch_time = excluded.fetch_time
- """,
- (
- str(host_mid),
- str(id_str),
- item.get("type"),
- 1 if visible else 0 if visible is not None else None,
- publish_ts,
- comment_id_str,
- comment_type,
- rid_str,
- txt,
- author_name,
- archive_bvid,
- archive_title,
- archive_cover,
- archive_desc if isinstance(archive_desc, str) else None,
- article_title,
- article_covers,
- opus_title,
- opus_summary_text,
- media_locals_joined,
- media_count,
- None, # live_media_locals - 暂时设为None,稍后在路由中处理
- 0, # live_media_count - 暂时设为0
- fetch_time,
- ),
- )
- logger.info(f"normalize.core.saved host_mid={host_mid} id_str={id_str}")
-
- # 作者
- author_mid = module_author.get("mid") or module_author.get("id")
- author_name = module_author.get("name") or module_author.get("uname")
- face = module_author.get("face")
- cursor.execute(
- """
- INSERT INTO dynamic_author (host_mid, id_str, author_mid, author_name, face)
- VALUES (?, ?, ?, ?, ?)
- ON CONFLICT(host_mid, id_str) DO UPDATE SET
- author_mid = excluded.author_mid,
- author_name = excluded.author_name,
- face = excluded.face
- """,
- (
- str(host_mid),
- str(id_str),
- str(author_mid) if author_mid is not None else None,
- author_name,
- face,
- ),
- )
-
- # 统计
- like_count = _to_int(
- module_stat.get("like") if isinstance(module_stat.get("like"), (int, str)) else (module_stat.get("like", {}).get("count") if isinstance(module_stat.get("like"), dict) else None)
- )
- comment_count = _to_int(
- module_stat.get("comment") if isinstance(module_stat.get("comment"), (int, str)) else (module_stat.get("comment", {}).get("count") if isinstance(module_stat.get("comment"), dict) else None)
- )
- repost_count = _to_int(
- module_stat.get("repost") if isinstance(module_stat.get("repost"), (int, str)) else (module_stat.get("forward", {}).get("count") if isinstance(module_stat.get("forward"), dict) else None)
- )
- view_count = _to_int(
- module_stat.get("view") if isinstance(module_stat.get("view"), (int, str)) else (module_stat.get("view", {}).get("count") if isinstance(module_stat.get("view"), dict) else None)
- )
- cursor.execute(
- """
- INSERT INTO dynamic_stat (host_mid, id_str, like_count, comment_count, repost_count, view_count)
- VALUES (?, ?, ?, ?, ?, ?)
- ON CONFLICT(host_mid, id_str) DO UPDATE SET
- like_count = excluded.like_count,
- comment_count = excluded.comment_count,
- repost_count = excluded.repost_count,
- view_count = excluded.view_count
- """,
- (
- str(host_mid),
- str(id_str),
- like_count,
- comment_count,
- repost_count,
- view_count,
- ),
- )
-
-
- conn.commit()
-
-
-def list_hosts_with_stats(
- conn: sqlite3.Connection,
- limit: int = 50,
- offset: int = 0,
-) -> List[Dict[str, Any]]:
- """列出数据库中已有动态的UP(host_mid)及统计信息。
-
- 返回字段:host_mid, item_count, core_count, last_publish_ts, last_fetch_time
- """
- cursor = conn.cursor()
- logger.debug(f"db.list_hosts_with_stats begin limit={limit} offset={offset}")
- rows = cursor.execute(
- (
- """
- SELECT dc.host_mid AS host_mid,
- COUNT(*) AS item_count,
- COUNT(*) AS core_count,
- MAX(dc.publish_ts) AS last_publish_ts,
- MAX(dc.fetch_time) AS last_fetch_time
- FROM dynamic_core AS dc
- GROUP BY dc.host_mid
- ORDER BY (MAX(dc.publish_ts) IS NULL) ASC, MAX(dc.publish_ts) DESC, COUNT(*) DESC
- LIMIT ? OFFSET ?
- """
- ),
- (limit, offset),
- ).fetchall()
-
- results: List[Dict[str, Any]] = []
- for r in rows:
- host_mid, item_count, core_count, last_publish_ts, last_fetch_time = r
- results.append(
- {
- "host_mid": str(host_mid) if host_mid is not None else None,
- "item_count": int(item_count) if item_count is not None else 0,
- "core_count": int(core_count) if core_count is not None else 0,
- "last_publish_ts": int(last_publish_ts) if last_publish_ts is not None else None,
- "last_fetch_time": int(last_fetch_time) if last_fetch_time is not None else None,
- }
- )
- logger.debug(f"db.list_hosts_with_stats done count={len(results)}")
- return results
-
-
-def list_dynamics_for_host(
- conn: sqlite3.Connection,
- host_mid: int,
- limit: int = 20,
- offset: int = 0,
-) -> Dict[str, Any]:
- """列出指定UP的动态,优先从 dynamic_core 读取;若无则回退到 dynamic_items。
-
- 返回:
- {
- "source": "core" | "items",
- "total": int,
- "items": [ { id_str, type, visible, publish_ts, txt, author_name, media_count, media_urls, media_locals, fetch_time } ]
- }
- """
- cursor = conn.cursor()
- host_mid_str = str(host_mid)
-
- # 统计 core 数量
- core_total_row = cursor.execute(
- "SELECT COUNT(*) FROM dynamic_core WHERE host_mid = ?",
- (host_mid_str,),
- ).fetchone()
- core_total = int(core_total_row[0]) if core_total_row and core_total_row[0] is not None else 0
-
- if core_total > 0:
- rows = cursor.execute(
- (
- """
- SELECT host_mid, id_str, type, visible, publish_ts, comment_id_str, comment_type, rid_str,
- txt, author_name, bvid, title, cover, desc, article_title, article_covers,
- opus_title, opus_summary_text, media_locals, media_count, live_media_locals, live_media_count, fetch_time
- FROM dynamic_core
- WHERE host_mid = ?
- ORDER BY (publish_ts IS NULL) ASC, publish_ts DESC, fetch_time DESC
- LIMIT ? OFFSET ?
- """
- ),
- (host_mid_str, limit, offset),
- ).fetchall()
- items: List[Dict[str, Any]] = []
- for r in rows:
- (
- _host_mid,
- id_str,
- dynamic_type,
- visible,
- publish_ts,
- comment_id_str,
- comment_type,
- rid_str,
- txt,
- author_name,
- bvid,
- title,
- cover,
- desc,
- article_title,
- article_covers,
- opus_title,
- opus_summary_text,
- media_locals,
- media_count,
- live_media_locals,
- live_media_count,
- fetch_time,
- ) = r
- items.append(
- {
- "host_mid": str(_host_mid) if _host_mid is not None else host_mid_str,
- "id_str": str(id_str) if id_str is not None else None,
- "type": dynamic_type,
- "visible": int(visible) if visible is not None else None,
- "publish_ts": int(publish_ts) if publish_ts is not None else None,
- "comment_id_str": comment_id_str,
- "comment_type": int(comment_type) if comment_type is not None else None,
- "rid_str": rid_str,
- "txt": txt,
- "author_name": author_name,
- "bvid": bvid,
- "title": title,
- "cover": cover,
- "desc": desc,
- "article_title": article_title,
- "article_covers": article_covers,
- "opus_title": opus_title,
- "opus_summary_text": opus_summary_text,
- "media_locals": media_locals,
- "media_count": int(media_count) if media_count is not None else None,
- "live_media_locals": live_media_locals,
- "live_media_count": int(live_media_count) if live_media_count is not None else None,
- "fetch_time": int(fetch_time) if fetch_time is not None else None,
- }
- )
- return {"source": "core", "total": core_total, "items": items}
-
- # 如果没有core数据,返回空结果
- return {"source": "core", "total": 0, "items": []}
-
-
-
-
-def purge_host(conn: sqlite3.Connection, host_mid: int) -> Dict[str, int]:
- """按 host_mid 删除与动态相关的所有数据库内容。
-
- 删除范围:
- - dynamic_core
- - dynamic_author
- - dynamic_stat
- - dynamic_topic
- - major_opus_pics
- - major_archive_jump_urls
-
- Returns:
- Dict[str, int]: 各表删除数量与总数统计,如 {"dynamic_core": 10, ..., "total": 42}
- """
- cursor = conn.cursor()
- host_mid_str = str(host_mid)
- # 为避开潜在的外键约束问题(虽然当前表未启用约束),从“子表”到“主表”的顺序删除
- tables = [
- "major_archive_jump_urls",
- "major_opus_pics",
- "dynamic_topic",
- "dynamic_stat",
- "dynamic_author",
- "dynamic_core",
- ]
-
- stats: Dict[str, int] = {}
- total = 0
- for t in tables:
- try:
- cursor.execute(f"DELETE FROM {t} WHERE host_mid = ?", (host_mid_str,))
- # sqlite3 rowcount 返回本次操作影响的行数;若不可用则置 0
- affected = cursor.rowcount if cursor.rowcount is not None else 0
- stats[t] = affected
- total += affected
- except Exception as e:
- # 不中断整个清理,记录警告并继续
- logger.warning(f"purge_host: delete from {t} failed: {e}")
- stats[t] = 0
-
- try:
- conn.commit()
- except Exception as e:
- logger.warning(f"purge_host: commit failed: {e}")
-
- stats["total"] = total
- return stats
\ No newline at end of file
diff --git a/scripts/dynamic_media.py b/scripts/dynamic_media.py
deleted file mode 100644
index 9d04da9..0000000
--- a/scripts/dynamic_media.py
+++ /dev/null
@@ -1,339 +0,0 @@
-import asyncio
-import hashlib
-import os
-from typing import Dict, Iterable, List, Set, Tuple, Any
-from urllib.parse import urlparse
-
-import aiohttp
-import aiofiles
-
-
-def _looks_like_image_url(url: str) -> bool:
- if not isinstance(url, str):
- return False
- if not url.startswith("http://") and not url.startswith("https://"):
- return False
- lower = url.lower()
- if any(ext in lower for ext in [".jpg", ".jpeg", ".png", ".gif", ".webp"]):
- return True
- # 常见B站图片CDN路径包含 /bfs/,即便未带扩展名
- if "/bfs/" in lower:
- return True
- return False
-
-
-def _walk_collect_urls(obj: Any, path: List[str], collector: Set[str]) -> None:
- """递归遍历对象并按上下文收集图片URL,排除标签、头像、头像框(pendant)和表情相关图片"""
- # 路径关键字,用于排除
- path_lower = [p.lower() for p in path]
-
- def is_label_context() -> bool:
- return any(p == "label" for p in path_lower)
-
- def is_avatar_context() -> bool:
- return any(p in ("avatar", "face", "avatar_subscript_url") for p in path_lower)
-
- def is_decorate_card_context() -> bool:
- return any(p in ("decorate", "decorate_card", "decoration_card") for p in path_lower)
-
- def is_pendant_context() -> bool:
- # 头像框字段:module_author.pendant.*(仅在 pendant/pendent 上下文才判定)
- return any(p in ("pendant", "pendent") for p in path_lower)
-
- def is_interaction_context() -> bool:
- return any(p == "module_interaction" for p in path_lower)
-
- def is_emoji_context() -> bool:
- """检查是否是表情上下文"""
- if isinstance(obj, dict):
- # 检查是否是表情节点
- if obj.get("type") == "RICH_TEXT_NODE_TYPE_EMOJI":
- return True
- # 检查是否在表情数据结构中
- if "emoji" in obj and isinstance(obj["emoji"], dict):
- emoji_data = obj["emoji"]
- if "icon_url" in emoji_data and "text" in emoji_data:
- return True
- return False
-
- # 如果当前路径已经落在 label、avatar、pendant、表情或其它不需要区域,直接不收集其下任何URL
- if (
- is_label_context()
- or is_avatar_context()
- or is_pendant_context()
- or is_decorate_card_context()
- or is_interaction_context()
- or is_emoji_context()
- ):
- return
-
- if isinstance(obj, dict):
- for k, v in obj.items():
- # 对于已知的标签字段,跳过
- k_lower = str(k).lower()
- if k_lower in (
- "img_label_uri_hans",
- "img_label_uri_hans_static",
- "img_label_uri_hant",
- "img_label_uri_hant_static",
- "label_theme",
- ):
- continue
-
- _walk_collect_urls(v, path + [str(k)], collector)
- elif isinstance(obj, list):
- for idx, v in enumerate(obj):
- _walk_collect_urls(v, path + [str(idx)], collector)
- elif isinstance(obj, str):
- s = obj
- if _looks_like_image_url(s):
- # 额外基于URL路径排除头像与头像框类
- low = s.lower()
- # 头像
- if "/bfs/face/" in low or "/face/" in low:
- return
- # 头像框(pendant)常见路径:/bfs/garb/item/
- if "/bfs/garb/item/" in low:
- return
- # 其它图片加入集合
- collector.add(s)
-
-
-def collect_image_urls(dynamic_item: Dict) -> List[str]:
- """从动态条目中抽取图片类URL(包含视频封面),排除标签图片与头像图片"""
- urls: Set[str] = set()
- _walk_collect_urls(dynamic_item, [], urls)
- return list(urls)
-
-
-def collect_live_media_urls(dynamic_item: Dict) -> List[Tuple[str, str]]:
- """从动态条目中抽取实况媒体URL,返回(image_url, video_url)的元组列表"""
- live_media: List[Tuple[str, str]] = []
-
- def _extract_live_media(obj: Any, path: List[str]) -> None:
- if isinstance(obj, dict):
- # 检查是否包含live_url字段
- if "live_url" in obj and "url" in obj:
- image_url = obj.get("url")
- live_url = obj.get("live_url")
- if image_url and live_url and live_url != "null":
- live_media.append((image_url, live_url))
-
- for k, v in obj.items():
- _extract_live_media(v, path + [str(k)])
- elif isinstance(obj, list):
- for i, item in enumerate(obj):
- _extract_live_media(item, path + [str(i)])
-
- _extract_live_media(dynamic_item, [])
- return live_media
-
-
-def collect_emoji_urls(dynamic_item: Dict) -> List[Tuple[str, str]]:
- """从动态条目中抽取表情URL,返回(emoji_url, emoji_text)的元组列表"""
- emoji_list: List[Tuple[str, str]] = []
-
- def _extract_emojis(obj: Any, path: List[str]) -> None:
- # 路径上下文:忽略互动区(module_interaction)的热评表情
- path_lower = [p.lower() for p in path]
- if any(p == "module_interaction" for p in path_lower):
- return
- if isinstance(obj, dict):
- # 检查是否是表情节点
- if (obj.get("type") == "RICH_TEXT_NODE_TYPE_EMOJI" and
- "emoji" in obj and isinstance(obj["emoji"], dict)):
- emoji_data = obj["emoji"]
- icon_url = emoji_data.get("icon_url")
- text = emoji_data.get("text", "")
- if icon_url and text:
- # 去掉文本中的方括号
- clean_text = text.strip("[]")
- if clean_text:
- emoji_list.append((icon_url, clean_text))
-
- for k, v in obj.items():
- _extract_emojis(v, path + [str(k)])
- elif isinstance(obj, list):
- for i, item in enumerate(obj):
- _extract_emojis(item, path + [str(i)])
-
- _extract_emojis(dynamic_item, [])
- return emoji_list
-
-
-def _guess_extension(url: str) -> str:
- path = urlparse(url).path
- _, ext = os.path.splitext(path)
- ext = (ext or "").lower()
- if ext in [".jpg", ".jpeg", ".png", ".gif", ".webp"]:
- return ext
- return ".jpg"
-
-
-def _hash_name(url: str) -> str:
- return hashlib.md5(url.encode("utf-8")).hexdigest()
-
-
-def predict_image_path(url: str, save_dir: str) -> str:
- """基于链接原始文件名预测保存路径(不依赖下载结果)"""
- os.makedirs(save_dir, exist_ok=True)
- path = urlparse(url).path
- base = os.path.basename(path)
- if not base:
- base = _hash_name(url) + _guess_extension(url)
- # 确保有扩展名
- root, ext = os.path.splitext(base)
- if not ext:
- base = f"{base}{_guess_extension(url)}"
- return os.path.join(save_dir, base)
-
-
-async def _download_one(session: aiohttp.ClientSession, url: str, save_dir: str) -> Tuple[str, str, bool]:
- os.makedirs(save_dir, exist_ok=True)
- save_path = predict_image_path(url, save_dir)
-
- try:
- async with session.get(url, timeout=aiohttp.ClientTimeout(total=20)) as resp:
- if resp.status != 200:
- return url, save_path, False
- content_type = resp.headers.get("content-type", "").lower()
- if "image" not in content_type:
- return url, save_path, False
- data = await resp.read()
- async with aiofiles.open(save_path, "wb") as f:
- await f.write(data)
- return url, save_path, True
- except Exception:
- return url, save_path, False
-
-
-async def download_images(urls: Iterable[str], save_dir: str, concurrency: int = 6) -> List[Tuple[str, str, bool]]:
- unique_urls = list(dict.fromkeys(urls))
- if not unique_urls:
- return []
-
- sem = asyncio.Semaphore(concurrency)
-
- async with aiohttp.ClientSession(headers={
- 'User-Agent': 'Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/130.0.0.0 Safari/537.36',
- 'Referer': 'https://www.bilibili.com/'
- }) as session:
- async def bound(u: str):
- async with sem:
- return await _download_one(session, u, save_dir)
-
- tasks = [bound(u) for u in unique_urls]
- results = await asyncio.gather(*tasks, return_exceptions=False)
- return results
-
-
-async def _download_live_media(session: aiohttp.ClientSession, image_url: str, video_url: str, save_dir: str) -> Tuple[str, str, str, str, bool]:
- """下载实况媒体(图片和视频),返回(image_url, video_url, image_path, video_path, success)"""
- os.makedirs(save_dir, exist_ok=True)
-
- # 生成文件名
- image_name = _hash_name(image_url) + _guess_extension(image_url)
- video_name = _hash_name(video_url) + ".mp4" # live视频通常是mp4格式
-
- image_path = os.path.join(save_dir, image_name)
- video_path = os.path.join(save_dir, video_name)
-
- try:
- # 下载图片
- image_success = False
- if not os.path.exists(image_path):
- async with session.get(image_url) as resp:
- if resp.status == 200:
- data = await resp.read()
- async with aiofiles.open(image_path, "wb") as f:
- await f.write(data)
- image_success = True
- else:
- image_success = True
-
- # 下载视频
- video_success = False
- if not os.path.exists(video_path):
- async with session.get(video_url) as resp:
- if resp.status == 200:
- data = await resp.read()
- async with aiofiles.open(video_path, "wb") as f:
- await f.write(data)
- video_success = True
- else:
- video_success = True
-
- return image_url, video_url, image_path, video_path, (image_success and video_success)
- except Exception:
- return image_url, video_url, image_path, video_path, False
-
-
-async def download_live_media(live_media_pairs: List[Tuple[str, str]], save_dir: str, concurrency: int = 3) -> List[Tuple[str, str, str, str, bool]]:
- """下载实况媒体列表,返回下载结果"""
- if not live_media_pairs:
- return []
-
- sem = asyncio.Semaphore(concurrency)
-
- async with aiohttp.ClientSession(headers={
- 'User-Agent': 'Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/130.0.0.0 Safari/537.36',
- 'Referer': 'https://www.bilibili.com/'
- }) as session:
- async def bound(pair: Tuple[str, str]):
- async with sem:
- image_url, video_url = pair
- return await _download_live_media(session, image_url, video_url, save_dir)
-
- tasks = [bound(pair) for pair in live_media_pairs]
- results = await asyncio.gather(*tasks, return_exceptions=False)
- return results
-
-
-async def _download_emoji(session: aiohttp.ClientSession, emoji_url: str, emoji_text: str, save_dir: str) -> Tuple[str, str, bool]:
- """下载单个表情,返回(emoji_url, emoji_path, success)"""
- os.makedirs(save_dir, exist_ok=True)
-
- # 使用表情文本作为文件名,并添加.png扩展名
- # 清理文件名中的非法字符
- import re
- safe_name = re.sub(r'[<>:"/\\|?*]', '_', emoji_text)
- emoji_name = f"{safe_name}.png"
- emoji_path = os.path.join(save_dir, emoji_name)
-
- try:
- if not os.path.exists(emoji_path):
- async with session.get(emoji_url) as resp:
- if resp.status == 200:
- data = await resp.read()
- async with aiofiles.open(emoji_path, "wb") as f:
- await f.write(data)
- return emoji_url, emoji_path, True
- else:
- return emoji_url, emoji_path, True
- except Exception:
- pass
-
- return emoji_url, emoji_path, False
-
-
-async def download_emojis(emoji_pairs: List[Tuple[str, str]], save_dir: str, concurrency: int = 6) -> List[Tuple[str, str, bool]]:
- """下载表情列表,返回下载结果"""
- if not emoji_pairs:
- return []
-
- sem = asyncio.Semaphore(concurrency)
-
- async with aiohttp.ClientSession(headers={
- 'User-Agent': 'Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/130.0.0.0 Safari/537.36',
- 'Referer': 'https://www.bilibili.com/'
- }) as session:
- async def bound(pair: Tuple[str, str]):
- async with sem:
- emoji_url, emoji_text = pair
- return await _download_emoji(session, emoji_url, emoji_text, save_dir)
-
- tasks = [bound(pair) for pair in emoji_pairs]
- results = await asyncio.gather(*tasks, return_exceptions=False)
- return results
-
-
diff --git a/scripts/export_to_excel.py b/scripts/export_to_excel.py
deleted file mode 100644
index 6bcd5dd..0000000
--- a/scripts/export_to_excel.py
+++ /dev/null
@@ -1,200 +0,0 @@
-import json
-import logging
-import os
-import sqlite3
-import traceback
-from datetime import datetime
-
-import pandas as pd
-from openpyxl.utils import get_column_letter
-
-from scripts.utils import load_config, get_output_path
-
-config = load_config()
-
-# 配置日志记录
-logging.basicConfig(level=logging.INFO)
-logger = logging.getLogger(__name__)
-
-def create_connection(db_file):
- """创建一个到SQLite数据库的连接"""
- if not os.path.exists(db_file):
- logger.error(f"数据库文件 {db_file} 不存在。")
- return None
-
- conn = None
- try:
- conn = sqlite3.connect(db_file)
- logger.info(f"成功连接到SQLite数据库: {db_file}")
- except sqlite3.Error as e:
- logger.error(f"连接SQLite数据库时出错: {e}")
- return conn
-
-def get_current_year():
- return datetime.now().year
-
-def safe_json_loads(value):
- try:
- if value is None or value == 'null':
- return []
- return json.loads(value)
- except json.JSONDecodeError:
- logger.warning(f"JSON解析错误,值为: {value}")
- return []
- except Exception as e:
- logger.error(f"处理JSON时发生未知错误: {e}, 值为: {value}")
- return []
-
-def export_bilibili_history(year=None, month=None, start_date=None, end_date=None):
- """导出B站历史记录到Excel文件
-
- Args:
- year: 要导出的年份,如果不指定则使用当前年份
- month: 要导出的月份(1-12),如果指定则只导出该月数据
- start_date: 开始日期,格式为'YYYY-MM-DD',如果指定则从该日期开始导出
- end_date: 结束日期,格式为'YYYY-MM-DD',如果指定则导出到该日期为止
- """
- full_db_file = get_output_path(config['db_file'])
- target_year = year if year is not None else get_current_year()
-
- # 构建文件名
- filename_parts = ['bilibili_history']
- if year is not None:
- filename_parts.append(str(target_year))
- if month is not None:
- filename_parts.append(f"{month:02d}月")
- if start_date and end_date:
- filename_parts.append(f"{start_date}至{end_date}")
- elif start_date:
- filename_parts.append(f"从{start_date}开始")
- elif end_date:
- filename_parts.append(f"至{end_date}")
-
- excel_file = get_output_path(f'{"_".join(filename_parts)}.xlsx')
-
- conn = create_connection(full_db_file)
- if conn is None:
- return {"status": "error", "message": f"无法连接到数据库 {full_db_file}。数据库文件可能不存在。"}
-
- try:
- # 如果指定了日期范围,需要确定要查询的年份表
- years_to_query = [target_year]
-
- # 如果指定了日期范围,可能需要查询多个年份的表
- if start_date or end_date:
- # 获取开始和结束年份
- start_year = int(start_date.split('-')[0]) if start_date else target_year
- end_year = int(end_date.split('-')[0]) if end_date else target_year
-
- # 确保年份范围有效
- start_year = max(2000, min(start_year, datetime.now().year))
- end_year = max(2000, min(end_year, datetime.now().year))
-
- # 生成要查询的年份列表
- years_to_query = list(range(start_year, end_year + 1))
- logger.info(f"将查询以下年份的表: {years_to_query}")
-
- # 获取所有存在的表
- cursor = conn.cursor()
- cursor.execute("SELECT name FROM sqlite_master WHERE type='table' AND name LIKE 'bilibili_history_%'")
- existing_tables = [row[0] for row in cursor.fetchall()]
- logger.info(f"存在的表: {existing_tables}")
-
- # 过滤出实际存在的表
- tables_to_query = [f"bilibili_history_{year}" for year in years_to_query if f"bilibili_history_{year}" in existing_tables]
-
- if not tables_to_query:
- return {"status": "error", "message": f"没有找到符合条件的数据表。"}
-
- logger.info(f"将查询以下表: {tables_to_query}")
-
- # 准备查询条件
- conditions = []
- params = []
-
- # 如果指定了月份,添加月份筛选条件
- if month is not None:
- conditions.append("strftime('%m', datetime(view_at, 'unixepoch', 'localtime')) = ?")
- params.append(f"{month:02d}")
-
- # 如果指定了开始日期,添加开始日期筛选条件
- if start_date:
- conditions.append("date(view_at, 'unixepoch', 'localtime') >= ?")
- params.append(start_date)
-
- # 如果指定了结束日期,添加结束日期筛选条件
- if end_date:
- conditions.append("date(view_at, 'unixepoch', 'localtime') <= ?")
- params.append(end_date)
-
- # 准备查询条件字符串
- condition_str = ""
- if conditions:
- condition_str = " WHERE " + " AND ".join(conditions)
-
- # 从所有表中查询数据
- all_data = []
- for table in tables_to_query:
- query = f"SELECT * FROM {table}{condition_str}"
-
- # 打印调试信息
- logger.info(f"执行SQL查询: {query}")
- logger.info(f"参数: {params}")
-
- # 使用params参数执行查询
- table_df = pd.read_sql_query(query, conn, params=params)
- if not table_df.empty:
- all_data.append(table_df)
- logger.info(f"从表 {table} 中获取了 {len(table_df)} 条数据")
-
- # 合并所有表的数据
- if all_data:
- df = pd.concat(all_data, ignore_index=True)
- logger.info(f"合并后共有 {len(df)} 条数据")
- else:
- df = pd.DataFrame()
-
- if df.empty:
- return {"status": "error", "message": f"没有找到符合条件的数据。"}
-
- # 将 JSON 字符串转换为列表,处理 null 值
- if 'covers' in df.columns:
- df['covers'] = df['covers'].apply(safe_json_loads)
-
- # 清理列名,移除非法字符并确保列名有效
- df.columns = df.columns.str.replace(r'[^\w\s]', '', regex=True).str.strip()
- df.columns = [f"Column_{i}" if not col or not col[0].isalpha() else col for i, col in enumerate(df.columns)]
-
- # 导出到Excel
- with pd.ExcelWriter(excel_file, engine='openpyxl') as writer:
- df.to_excel(writer, index=False, sheet_name='BilibiliHistory')
-
- # 调整列宽
- worksheet = writer.sheets['BilibiliHistory']
- for idx, col in enumerate(df.columns):
- series = df[col]
- max_len = max((
- series.astype(str).map(len).max(), # 最长的值
- len(str(col)) # 列名长度
- )) + 1 # 为了美观增加一个字符的宽度
- worksheet.column_dimensions[get_column_letter(idx + 1)].width = max_len
-
- logger.info(f"数据已成功导出到 {excel_file}")
- return {"status": "success", "message": f"数据已成功导出到 {excel_file}"}
-
- except Exception as e:
- logger.error(f"导出数据时发生错误: {e}")
- traceback.print_exc()
- return {"status": "error", "message": f"导出数据时发生错误: {e}"}
-
- finally:
- if conn:
- conn.close()
-
-# 如果该脚本直接运行,则调用导出函数
-if __name__ == '__main__':
- result = export_bilibili_history()
- if result["status"] == "success":
- print(result["message"])
- else:
- print(f"错误: {result['message']}")
diff --git a/scripts/heatmap_visualizer.py b/scripts/heatmap_visualizer.py
deleted file mode 100644
index 8fa1251..0000000
--- a/scripts/heatmap_visualizer.py
+++ /dev/null
@@ -1,230 +0,0 @@
-import calendar
-import json
-import os
-import re
-from datetime import datetime, timedelta
-
-from jinja2 import Environment, FileSystemLoader
-from pyecharts import options as opts
-from pyecharts.charts import Calendar
-from pyecharts.commons.utils import JsCode
-
-from scripts.utils import load_config, get_output_path, get_config_path
-
-# 设置周的起始日为星期一
-calendar.setfirstweekday(calendar.MONDAY)
-
-config = load_config()
-
-class HeatmapVisualizer:
- def __init__(self):
- # 从配置文件加载配置
- self.config = load_config()
- self.heatmap_config = self.config.get('heatmap', {})
-
- # 使用配置文件中的路径
- self.template_file = get_config_path(self.heatmap_config.get('template_file', 'template.html'))
- self.output_dir = get_output_path(self.heatmap_config.get('output_dir', 'heatmap'))
- self.base_folder = get_output_path('')
-
- # 从配置中获取图表尺寸
- self.chart_width = self.heatmap_config.get('chart', {}).get('width', '1000px')
- self.chart_height = self.heatmap_config.get('chart', {}).get('height', '200px')
-
- # 从配置中获取颜色配置
- self.color_pieces = self.heatmap_config.get('colors', {}).get('pieces', [
- {"min": 1, "max": 10, "color": "#FFECF1"},
- {"min": 11, "max": 50, "color": "#FFB3CA"},
- {"min": 51, "max": 100, "color": "#FF8CB0"},
- {"min": 101, "max": 200, "color": "#FF6699"},
- {"min": 201, "max": 9999, "color": "#E84B85"},
- ])
-
- self.charts = []
- self.data = {}
-
- # 打印路径信息
- print("\n=== 热力图路径信息 ===")
- print(f"模板文件路径: {self.template_file}")
- print(f"输出目录: {self.output_dir}")
- print(f"基础文件夹: {self.base_folder}")
- print(f"模板文件存在: {os.path.exists(self.template_file)}")
- if os.path.exists(os.path.dirname(self.template_file)):
- print(f"模板目录内容: {os.listdir(os.path.dirname(self.template_file))}")
- print("=====================\n")
-
- if not os.path.exists(self.output_dir):
- os.makedirs(self.output_dir)
- self.years = self.detect_years()
-
- def detect_years(self):
- """
- 扫描 base_folder 文件夹,检测所有符合 daily_count_XXXX.json 格式的文件,并提取年份。
- """
- pattern = re.compile(r'daily_count_(\d{4})\.json$')
- years = []
- if not os.path.exists(self.base_folder):
- print(f"文件夹 {self.base_folder} 不存在。")
- return years
-
- for filename in os.listdir(self.base_folder):
- match = pattern.match(filename)
- if match:
- year = int(match.group(1))
- years.append(year)
-
- years = sorted(years) # 按年份排序
- if not years:
- print(f"在文件夹 {self.base_folder} 中未找到符合格式的 JSON 文件。")
- else:
- print(f"检测到年份: {years}")
- return years
-
- def load_data(self, year):
- """加载指定年份的 JSON 数据"""
- data_file = os.path.join(self.base_folder, f'daily_count_{year}.json')
- try:
- with open(data_file, 'r', encoding='utf-8') as f:
- daily_count = json.load(f)
- return daily_count
- except FileNotFoundError:
- print(f"文件 {data_file} 不存在,请检查文件路径。")
- return {}
-
- def plot_calendar_heatmaps(self):
- """生成热力图"""
- for year in self.years:
- daily_count = self.load_data(year)
- if not daily_count:
- print(f"跳过年份 {year},因为没有找到相关数据或数据为空。")
- continue
- self.data[year] = daily_count
- try:
- chart_html = self.create_calendar_chart(year, daily_count)
- if chart_html:
- self.charts.append({
- 'year': year,
- 'chart_html': chart_html
- })
- except ValueError as e:
- print(f"处理年份 {year} 时出错: {e}")
- continue
-
- if not self.charts:
- print("没有可生成的热力图。")
- return {"status": "error", "message": "没有可生成的热力图。"}
-
- env = Environment(loader=FileSystemLoader(os.path.dirname(self.template_file)))
- try:
- template = env.get_template(os.path.basename(self.template_file))
- except Exception as e:
- error_message = f"加载模板文件 {self.template_file} 时出错: {str(e)}"
- print(error_message)
- return {"status": "error", "message": error_message}
-
- rendered_html = template.render(
- title=self.heatmap_config.get('title', "Bilibili 每年每日视频观看热力图"),
- charts=self.charts
- )
-
- output_file = os.path.join(self.output_dir, "heatmap_comparison.html")
- try:
- with open(output_file, 'w', encoding='utf-8') as f:
- f.write(rendered_html)
- success_message = f"热力图已保存为 {output_file}"
- return {"status": "success", "message": success_message}
- except Exception as e:
- error_message = f"保存 HTML 文件时出错: {e}"
- print(error_message)
- return {"status": "error", "message": error_message}
-
- def create_calendar_chart(self, year, daily_count):
- """创建日历热力图"""
- date_range = self.generate_date_range(daily_count)
- if not date_range:
- print(f"年份 {year} 的日期范围生成失败。")
- return ""
-
- data = self.prepare_data_for_calendar(date_range, daily_count)
-
- calendar_range = [f"{year}-01-01", f"{year}-12-31"]
-
- calendar_chart = (
- Calendar(init_opts=opts.InitOpts(width=self.chart_width, height=self.chart_height))
- .add(
- series_name="观看数量",
- yaxis_data=data,
- calendar_opts=opts.CalendarOpts(
- range_=calendar_range,
- daylabel_opts=opts.CalendarDayLabelOpts(name_map="cn"),
- monthlabel_opts=opts.CalendarMonthLabelOpts(name_map="cn"),
- cell_size=[15, 15],
- itemstyle_opts=opts.ItemStyleOpts(
- border_width=0.5,
- border_color="#ccc",
- color="#ffffff",
- ),
- splitline_opts=opts.SplitLineOpts(is_show=False)
- ),
- )
- .set_global_opts(
- visualmap_opts=opts.VisualMapOpts(
- max_=100,
- min_=1,
- orient="horizontal",
- is_piecewise=True,
- pieces=self.color_pieces,
- pos_top="top",
- textstyle_opts=opts.TextStyleOpts(color="#FF6699"),
- ),
- tooltip_opts=opts.TooltipOpts(
- is_show=True,
- formatter=JsCode(
- """
- function(params) {
- var date = params.value[0];
- var count = params.value[1];
- return date + ' : ' + count + '个视频';
- }
- """
- )
- )
- )
- )
-
- return calendar_chart.render_embed()
-
- def generate_date_range(self, daily_count):
- """生成日期范围"""
- if not daily_count:
- return []
-
- try:
- all_dates = [datetime.strptime(date, '%Y-%m-%d') for date in daily_count.keys()]
- except ValueError as e:
- print(f"日期格式错误: {e}")
- return []
-
- min_date, max_date = min(all_dates), max(all_dates)
-
- if min_date.year != max_date.year:
- raise ValueError("数据中包含多个年份,请确保数据只包含一个年份。")
-
- year = min_date.year
- num_days = (datetime(year, 12, 31) - datetime(year, 1, 1)).days + 1
- return [datetime(year, 1, 1) + timedelta(days=i) for i in range(num_days)]
-
- def prepare_data_for_calendar(self, date_range, daily_count):
- """准备日历数据"""
- return [
- [date.strftime('%Y-%m-%d'), daily_count.get(date.strftime('%Y-%m-%d'), 0)]
- for date in date_range
- ]
-
-def generate_heatmap():
- visualizer = HeatmapVisualizer()
- return visualizer.plot_calendar_heatmaps()
-
-if __name__ == "__main__":
- result = generate_heatmap()
- print(result["message"])
diff --git a/scripts/image_downloader.py b/scripts/image_downloader.py
deleted file mode 100644
index 1ce070d..0000000
--- a/scripts/image_downloader.py
+++ /dev/null
@@ -1,1105 +0,0 @@
-import os
-import sys
-
-# 添加项目根目录到Python路径
-project_root = os.path.dirname(os.path.dirname(os.path.abspath(__file__)))
-sys.path.insert(0, project_root)
-
-import json
-import time
-import hashlib
-import random
-import threading
-import sqlite3
-from datetime import datetime
-from queue import Queue, Empty
-from typing import Optional, Dict, List, Tuple
-from urllib.parse import urlparse
-
-import requests
-from requests.adapters import HTTPAdapter
-from urllib3.util.retry import Retry
-
-from scripts.utils import get_output_path, load_config
-
-config = load_config()
-
-class DownloadStatusDB:
- def __init__(self):
- self.db_path = get_output_path('image_downloads.db')
- self.lock = threading.Lock()
- self._init_db()
-
- def _get_table_name(self, type: str, year: int) -> str:
- """获取表名
-
- Args:
- type: 图片类型 (cover 或 avatar)
- year: 年份
-
- Returns:
- str: 表名,格式为 images_{type}_{year}
- """
- return f"images_{type}s_{year}"
-
- def _create_table(self, cursor: sqlite3.Cursor, table_name: str):
- """创建表结构"""
- cursor.execute(f"""
- CREATE TABLE IF NOT EXISTS {table_name} (
- hash TEXT PRIMARY KEY,
- url TEXT NOT NULL,
- path TEXT NOT NULL,
- downloaded BOOLEAN DEFAULT 0,
- timestamp INTEGER NOT NULL,
- error TEXT
- )
- """)
-
- # 创建索引
- cursor.execute(f"""
- CREATE INDEX IF NOT EXISTS idx_{table_name}_downloaded
- ON {table_name}(downloaded)
- """)
- cursor.execute(f"""
- CREATE INDEX IF NOT EXISTS idx_{table_name}_timestamp
- ON {table_name}(timestamp)
- """)
-
- def _init_db(self):
- """初始化数据库表结构"""
- with self.lock:
- conn = sqlite3.connect(self.db_path)
- try:
- cursor = conn.cursor()
-
- # 获取现有的表
- cursor.execute("""
- SELECT name FROM sqlite_master
- WHERE type='table' AND name LIKE 'images_%'
- """)
- existing_tables = {row[0] for row in cursor.fetchall()}
-
- # 如果存在旧的单表,迁移数据
- if 'image_downloads' in existing_tables:
- print("检测到旧的单表结构,开始迁移数据...")
- self._migrate_from_single_table(cursor)
- cursor.execute("DROP TABLE image_downloads")
- print("旧表迁移完成并删除")
-
- conn.commit()
- finally:
- conn.close()
-
- def _migrate_from_single_table(self, cursor: sqlite3.Cursor):
- """从旧的单表结构迁移数据到新的分表结构"""
- # 获取所有数据
- cursor.execute("""
- SELECT hash, type, url, path, downloaded, timestamp, error, year
- FROM image_downloads
- """)
- rows = cursor.fetchall()
-
- # 按年份和类型分组数据
- data_by_table = {}
- for row in rows:
- hash_value, type_name, url, path, downloaded, timestamp, error, year = row
- if not year: # 如果没有年份信息,跳过
- continue
-
- table_name = self._get_table_name(type_name, year)
- if table_name not in data_by_table:
- data_by_table[table_name] = []
- data_by_table[table_name].append(
- (hash_value, url, path, downloaded, timestamp, error)
- )
-
- # 创建新表并插入数据
- for table_name, table_data in data_by_table.items():
- self._create_table(cursor, table_name)
- cursor.executemany(f"""
- INSERT OR REPLACE INTO {table_name}
- (hash, url, path, downloaded, timestamp, error)
- VALUES (?, ?, ?, ?, ?, ?)
- """, table_data)
-
- def update_status(self, hash_value: str, type: str, url: str, path: str,
- downloaded: bool, error: str = None, year: int = None):
- """更新下载状态"""
- if not year:
- print(f"警告:缺少年份信息,无法更新状态")
- return
-
- with self.lock:
- conn = sqlite3.connect(self.db_path)
- try:
- cursor = conn.cursor()
- table_name = self._get_table_name(type, year)
-
- # 确保表存在
- self._create_table(cursor, table_name)
-
- # 更新状态
- cursor.execute(f"""
- INSERT OR REPLACE INTO {table_name}
- (hash, url, path, downloaded, timestamp, error)
- VALUES (?, ?, ?, ?, ?, ?)
- """, (hash_value, url, path, downloaded, int(time.time()), error))
-
- conn.commit()
- finally:
- conn.close()
-
- def get_status(self, hash_value: str) -> Optional[Dict]:
- """获取指定hash的下载状态"""
- with self.lock:
- conn = sqlite3.connect(self.db_path)
- try:
- cursor = conn.cursor()
-
- # 查询所有年份的表
- cursor.execute("""
- SELECT name FROM sqlite_master
- WHERE type='table' AND name LIKE 'images_%'
- """)
-
- for (table_name,) in cursor.fetchall():
- cursor.execute(f"""
- SELECT url, path, downloaded, timestamp, error
- FROM {table_name}
- WHERE hash = ?
- """, (hash_value,))
-
- row = cursor.fetchone()
- if row:
- return {
- 'url': row[0],
- 'path': row[1],
- 'downloaded': bool(row[2]),
- 'timestamp': row[3],
- 'error': row[4]
- }
- return None
- finally:
- conn.close()
-
- def get_stats(self) -> Dict:
- """获取下载统计信息"""
- print("\n=== 数据库统计信息 ===")
- with self.lock:
- conn = sqlite3.connect(self.db_path)
- try:
- cursor = conn.cursor()
- stats = {
- 'covers': {'total': 0, 'downloaded': 0, 'failed': 0},
- 'avatars': {'total': 0, 'downloaded': 0, 'failed': 0}
- }
-
- # 获取所有年份的表
- cursor.execute("""
- SELECT name FROM sqlite_master
- WHERE type='table' AND name LIKE 'images_%'
- """)
-
- print("查询所有图片相关的表...")
- for (table_name,) in cursor.fetchall():
- print(f"\n处理表: {table_name}")
- # 从表名解析类型
- if 'covers' in table_name:
- type_name = 'covers'
- elif 'avatars' in table_name:
- type_name = 'avatars'
- else:
- print(f"跳过不相关的表: {table_name}")
- continue
-
- # 获取统计信息
- cursor.execute(f"""
- SELECT
- COUNT(*) as total,
- SUM(CASE WHEN downloaded = 1 THEN 1 ELSE 0 END) as downloaded,
- SUM(CASE WHEN downloaded = 0 AND error IS NOT NULL THEN 1 ELSE 0 END) as failed
- FROM {table_name}
- """)
-
- row = cursor.fetchone()
- if row:
- print(f"{type_name} 统计结果:")
- print(f"- 总数: {row[0] or 0}")
- print(f"- 已下载: {row[1] or 0}")
- print(f"- 失败: {row[2] or 0}")
-
- stats[type_name]['total'] += row[0] or 0
- stats[type_name]['downloaded'] += row[1] or 0
- stats[type_name]['failed'] += row[2] or 0
-
- # 获取最近下载时间
- cursor.execute(f"""
- SELECT MAX(timestamp)
- FROM {table_name}
- WHERE downloaded = 1
- """)
-
- last_download = cursor.fetchone()[0]
- if last_download:
- current_last = stats[type_name].get('last_download', 0)
- stats[type_name]['last_download'] = max(current_last, last_download)
- print(f"最近下载时间: {datetime.fromtimestamp(stats[type_name]['last_download'])}")
-
-
- return stats
- finally:
- conn.close()
-
- def clear_all(self):
- """清空所有下载状态"""
- with self.lock:
- conn = sqlite3.connect(self.db_path)
- try:
- cursor = conn.cursor()
-
- # 获取所有图片相关的表
- cursor.execute("""
- SELECT name FROM sqlite_master
- WHERE type='table' AND name LIKE 'images_%'
- """)
-
- # 删除所有表
- for (table_name,) in cursor.fetchall():
- cursor.execute(f"DROP TABLE {table_name}")
-
- conn.commit()
- finally:
- conn.close()
-
- def get_failed_downloads(self, type: str, year: int) -> List[Dict]:
- """获取失败的下载记录
-
- Args:
- type: 图片类型 (cover 或 avatar)
- year: 年份
-
- Returns:
- List[Dict]: 失败记录列表
- """
- with self.lock:
- conn = sqlite3.connect(self.db_path)
- try:
- cursor = conn.cursor()
- table_name = self._get_table_name(type, year)
-
- cursor.execute(f"""
- SELECT hash, url, path, timestamp, error
- FROM {table_name}
- WHERE downloaded = 0 AND error IS NOT NULL
- """)
-
- return [{
- 'hash': row[0],
- 'url': row[1],
- 'path': row[2],
- 'timestamp': row[3],
- 'error': row[4]
- } for row in cursor.fetchall()]
- finally:
- conn.close()
-
-class ImageDownloader:
- _instance = None
- _lock = threading.Lock()
-
- def __new__(cls):
- with cls._lock:
- if cls._instance is None:
- cls._instance = super(ImageDownloader, cls).__new__(cls)
- # 将初始化移到这里,确保只执行一次
- cls._instance._initialize()
- return cls._instance
-
- def _initialize(self):
- """初始化实例属性"""
- if hasattr(self, '_initialized'):
- return
-
- print("\n=== 初始化图片下载器 ===")
- self.session = self._create_session()
- self.download_queue = Queue()
- self.lock = threading.Lock()
- self.is_downloading = False
-
- # 初始化数据库
- self.db = DownloadStatusDB()
-
- # 总下载数量跟踪
- self.total_covers_to_download = 0
- self.total_avatars_to_download = 0
-
- # 添加初始total值的存储
- self.initial_covers_total = 0
- self.initial_avatars_total = 0
-
- # 确保目录存在
- self.base_path = get_output_path('images')
- self.covers_path = os.path.join(self.base_path, 'covers')
- self.avatars_path = os.path.join(self.base_path, 'avatars')
- self.orphaned_covers_path = os.path.join(self.base_path, 'orphaned_covers')
- self.orphaned_avatars_path = os.path.join(self.base_path, 'orphaned_avatars')
-
- os.makedirs(self.covers_path, exist_ok=True)
- os.makedirs(self.avatars_path, exist_ok=True)
- os.makedirs(self.orphaned_covers_path, exist_ok=True)
- os.makedirs(self.orphaned_avatars_path, exist_ok=True)
-
- print("初始化图片下载器完成")
- print(f"图片保存基础路径: {self.base_path}")
- print(f"封面保存路径: {self.covers_path}")
- print(f"头像保存路径: {self.avatars_path}")
- print(f"孤立封面保存路径: {self.orphaned_covers_path}")
- print(f"孤立头像保存路径: {self.orphaned_avatars_path}")
-
- self._initialized = True
-
- def __init__(self):
- """空的初始化方法,实际初始化在_initialize中完成"""
- pass
-
- def _create_session(self) -> requests.Session:
- """创建请求会话,配置重试策略和请求头"""
- session = requests.Session()
-
- # 配置重试策略
- retry_strategy = Retry(
- total=3,
- backoff_factor=0.5,
- status_forcelist=[500, 502, 503, 504]
- )
- adapter = HTTPAdapter(max_retries=retry_strategy)
- session.mount("http://", adapter)
- session.mount("https://", adapter)
-
- # 设置请求头
- session.headers.update({
- 'User-Agent': 'Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/91.0.4472.124 Safari/537.36',
- 'Referer': 'https://www.bilibili.com'
- })
-
- print("创建请求会话完成,已配置重试策略和请求头")
- return session
-
- def _get_file_hash(self, url: str) -> str:
- """获取URL的哈希值作为文件名"""
- return hashlib.md5(url.encode()).hexdigest()
-
- def _get_file_extension(self, url: str) -> str:
- """从URL中获取文件扩展名"""
- path = urlparse(url).path
- ext = os.path.splitext(path)[1].lower()
-
- # 如果URL中没有扩展名,从Content-Type中获取
- if not ext:
- try:
- response = self.session.head(url, timeout=5)
- content_type = response.headers.get('content-type', '')
- if 'gif' in content_type:
- return '.gif'
- elif 'png' in content_type:
- return '.png'
- elif 'jpeg' in content_type or 'jpg' in content_type:
- return '.jpg'
- elif 'webp' in content_type:
- return '.webp'
- except Exception as e:
- print(f"获取Content-Type失败: {str(e)}")
-
- return ext if ext else '.jpg'
-
- def _download_image(self, url: str, save_path: str, use_sessdata: bool = True) -> bool:
- """下载单个图片
-
- Args:
- url: 图片URL
- save_path: 保存路径
- use_sessdata: 是否使用SESSDATA(对于公开内容如视频封面和头像,可以不使用SESSDATA)
-
- Returns:
- bool: 下载是否成功
- """
- try:
- # 如果不使用SESSDATA,移除URL中可能包含的SESSDATA参数
- if not use_sessdata and '?' in url:
- # 移除URL中的所有参数,保留纯净的图片URL
- url = url.split('?')[0]
- print(f"不使用SESSDATA,处理后的URL: {url}")
-
- print(f"\n开始下载图片: {url}")
- print(f"保存路径: {save_path}")
-
- # 随机延迟
- delay = random.uniform(2, 5)
- print(f"随机延迟 {delay:.2f} 秒")
- time.sleep(delay)
-
- response = self.session.get(url, timeout=10)
- response.raise_for_status()
-
- # 检查是否是图片
- content_type = response.headers.get('content-type', '')
- print(f"响应Content-Type: {content_type}")
-
- if not content_type.startswith('image/'):
- print(f"警告:URL {url} 返回的不是图片({content_type})")
- return False
-
- # 特殊处理GIF图片
- if 'gif' in content_type.lower():
- print("检测到GIF图片,使用二进制模式保存")
- with open(save_path, 'wb') as f:
- f.write(response.content)
- if not save_path.lower().endswith('.gif'):
- new_path = os.path.splitext(save_path)[0] + '.gif'
- os.rename(save_path, new_path)
- print(f"重命名文件为GIF格式: {new_path}")
- return True
-
- # 保存其他类型的图片
- with open(save_path, 'wb') as f:
- f.write(response.content)
-
- file_size = os.path.getsize(save_path)
- print(f"图片下载成功,文件大小: {file_size/1024:.2f}KB")
- return True
-
- except Exception as e:
- print(f"下载图片失败 {url}")
- print(f"错误类型: {type(e).__name__}")
- print(f"错误信息: {str(e)}")
- if isinstance(e, requests.exceptions.RequestException):
- print(f"请求异常详情: {e.response.status_code if e.response else '无响应'}")
- return False
-
- def _get_cover_path(self, url: str, year: int = None) -> str:
- """获取封面图片的保存路径,使用哈希值组织目录结构"""
- file_hash = self._get_file_hash(url)
- ext = self._get_file_extension(url)
- sub_dir = file_hash[:2] # 使用哈希的前两位作为子目录
- save_dir = os.path.join(self.covers_path, str(year), sub_dir) if year else os.path.join(self.covers_path, sub_dir)
- os.makedirs(save_dir, exist_ok=True)
- return os.path.join(save_dir, f"{file_hash}{ext}")
-
- def _get_avatar_path(self, url: str, year: int = None) -> str:
- """获取头像图片的保存路径"""
- file_hash = self._get_file_hash(url)
- ext = self._get_file_extension(url)
- sub_dir = file_hash[:2] # 使用哈希的前两位作为子目录
- save_dir = os.path.join(self.avatars_path, str(year), sub_dir) if year else os.path.join(self.avatars_path, sub_dir)
- os.makedirs(save_dir, exist_ok=True)
- return os.path.join(save_dir, f"{file_hash}{ext}")
-
- def download_worker(self):
- """下载工作线程"""
- thread_name = threading.current_thread().name
- print(f"\n=== 线程 {thread_name} 开始工作 ===")
-
- while True:
- try:
- # 使用超时获取任务,避免永久阻塞
- try:
- task = self.download_queue.get(timeout=1)
- except Empty:
- # 如果队列为空且下载已完成,退出线程
- if not self.is_downloading:
- print(f"线程 {thread_name} 检测到下载完成标志,退出")
- break
- continue
-
- if task is None:
- print(f"线程 {thread_name} 收到停止信号,退出")
- break
-
- url, save_path, is_cover, hash_value, year, use_sessdata = task
- print(f"\n=== 线程 {thread_name} 处理下载任务 ===")
- print(f"URL: {url}")
- print(f"保存路径: {save_path}")
- print(f"类型: {'封面' if is_cover else '头像'}")
- print(f"年份: {year}")
- print(f"使用SESSDATA: {use_sessdata}")
-
- try:
- # 检查是否已下载
- status = self.db.get_status(hash_value)
- if status and status['downloaded']:
- print(f"跳过已下载的图片: {url}")
- self.download_queue.task_done()
- continue
-
- # 确保目录存在
- save_dir = os.path.dirname(save_path)
- os.makedirs(save_dir, exist_ok=True)
-
- # 下载图片
- print("开始下载图片...")
- success = self._download_image(url, save_path, use_sessdata)
- print(f"下载结果: {'成功' if success else '失败'}")
-
- # 更新状态
- print("更新下载状态...")
- self.db.update_status(
- hash_value=hash_value,
- type='cover' if is_cover else 'avatar',
- url=url,
- path=save_path,
- downloaded=success,
- error=None if success else "Download failed",
- year=year
- )
-
- except Exception as e:
- print(f"\n处理下载任务时出错:")
- print(f"URL: {url}")
- print(f"错误类型: {type(e).__name__}")
- print(f"错误信息: {str(e)}")
- print("错误堆栈:")
- import traceback
- print(traceback.format_exc())
-
- # 记录错误状态
- self.db.update_status(
- hash_value=hash_value,
- type='cover' if is_cover else 'avatar',
- url=url,
- path=save_path,
- downloaded=False,
- error=str(e),
- year=year
- )
-
- finally:
- # 无论成功与否,都标记任务完成
- self.download_queue.task_done()
- print("任务已标记为完成")
-
- except Exception as e:
- print(f"\n下载工作线程发生错误:")
- print(f"错误类型: {type(e).__name__}")
- print(f"错误信息: {str(e)}")
- print("错误堆栈:")
- import traceback
- print(traceback.format_exc())
-
- def start_download(self, year: Optional[int] = None, use_sessdata: bool = True):
- """开始下载指定年份的图片
-
- Args:
- year: 指定年份,不指定则下载所有年份
- use_sessdata: 是否在下载图片时使用SESSDATA
- """
- try:
- print(f"\n{'='*50}")
- print(f"开始下载图片 - {datetime.now().strftime('%Y-%m-%d %H:%M:%S')}")
- print(f"目标年份: {'所有年份' if year is None else year}")
- print(f"使用SESSDATA: {use_sessdata}")
-
- # 重置总下载数量
- with self.lock:
- self.total_covers_to_download = 0
- self.total_avatars_to_download = 0
-
- # 设置下载状态标志
- self.is_downloading = True
-
- # 获取要处理的年份列表
- if year:
- years = [year]
- else:
- years = get_available_years()
-
- if not years:
- print("错误:未找到任何可用年份")
- raise ValueError("未找到任何可用年份")
-
- print(f"将处理以下年份: {years}")
-
- # 获取当前已下载的数量
- current_stats = self.db.get_stats()
- current_covers_downloaded = current_stats['covers']['downloaded']
- current_avatars_downloaded = current_stats['avatars']['downloaded']
-
- # 预先计算总下载数量
- total_cover_urls = []
- total_avatar_urls = []
- for year in years:
- cover_urls, avatar_urls = self._preprocess_year_data(year)
- total_cover_urls.extend(cover_urls)
- total_avatar_urls.extend(avatar_urls)
-
- # 过滤出需要下载的新URL
- new_cover_urls = self._filter_new_urls(total_cover_urls, True)
- new_avatar_urls = self._filter_new_urls(total_avatar_urls, False)
-
- # 更新总下载数量
- with self.lock:
- self.total_covers_to_download = len(new_cover_urls)
- self.total_avatars_to_download = len(new_avatar_urls)
-
- # 保存初始total值 = 当前已下载 + 计划下载
- self.initial_covers_total = current_covers_downloaded + self.total_covers_to_download
- self.initial_avatars_total = current_avatars_downloaded + self.total_avatars_to_download
- print(f"\n保存初始total值:")
- print(f"- 封面: {self.initial_covers_total} (已下载: {current_covers_downloaded} + 计划: {self.total_covers_to_download})")
- print(f"- 头像: {self.initial_avatars_total} (已下载: {current_avatars_downloaded} + 计划: {self.total_avatars_to_download})")
-
- print(f"\n总计需要下载的图片:")
- print(f"封面: {self.total_covers_to_download}/{len(total_cover_urls)} 个")
- print(f"头像: {self.total_avatars_to_download}/{len(total_avatar_urls)} 个")
-
- # 如果没有需要下载的图片,直接返回
- if self.total_covers_to_download == 0 and self.total_avatars_to_download == 0:
- print("\n没有新的图片需要下载,任务完成")
- self.is_downloading = False
- return
-
- # 创建下载线程池
- num_threads = 20 # 增加到20个线程
- print(f"\n=== 创建下载线程池 ===")
- print(f"启动 {num_threads} 个下载线程")
- print(f"每个线程随机延迟: 2-5秒")
- print(f"预计最大并发下载数: {num_threads}")
- print("========================\n")
-
- threads = []
- for i in range(num_threads):
- t = threading.Thread(target=self.download_worker, name=f"DownloadWorker-{i+1}")
- t.daemon = True # 设置为守护线程
- t.start()
- threads.append(t)
- print(f"线程 DownloadWorker-{i+1} 已启动")
-
- # 处理每个年份的数据
- total_processed = 0
- for year in years:
- print(f"\n=== 处理 {year} 年数据 ===")
- # 预处理年份数据
- cover_urls, avatar_urls = self._preprocess_year_data(year)
-
- # 过滤出需要下载的新URL
- year_new_cover_urls = self._filter_new_urls(cover_urls, True)
- year_new_avatar_urls = self._filter_new_urls(avatar_urls, False)
-
- print(f"\n{year}年需要下载的图片:")
- print(f"封面: {len(year_new_cover_urls)}/{len(cover_urls)} 个")
- print(f"头像: {len(year_new_avatar_urls)}/{len(avatar_urls)} 个")
-
- # 添加下载任务
- for url in year_new_cover_urls:
- save_path = self._get_cover_path(url, year)
- hash_value = self._get_file_hash(url)
- self.download_queue.put((
- url,
- save_path,
- True,
- hash_value,
- year,
- use_sessdata
- ))
-
- for url in year_new_avatar_urls:
- save_path = self._get_avatar_path(url, year)
- hash_value = self._get_file_hash(url)
- self.download_queue.put((
- url,
- save_path,
- False,
- hash_value,
- year,
- use_sessdata
- ))
-
- total_processed += len(year_new_cover_urls) + len(year_new_avatar_urls)
-
- # 等待队列处理完毕,但设置超时避免永久阻塞
- print("\n等待当前年份下载任务完成...")
- while not self.download_queue.empty():
- try:
- self.download_queue.join()
- except Exception as e:
- print(f"等待任务完成时出错: {str(e)}")
- break
-
- print("\n所有数据处理完成,正在停止下载线程...")
-
- # 停止工作线程
- self.is_downloading = False
- for _ in threads:
- self.download_queue.put(None)
-
- # 等待线程结束,但设置超时
- for t in threads:
- t.join(timeout=5)
-
- # 确保状态标记为已完成
- self.is_downloading = False
-
- print("\n=== 下载统计 ===")
- stats = self.get_download_stats()
- print(f"封面图片:")
- print(f"- 总数: {stats['covers']['total']}")
- print(f"- 已下载: {stats['covers']['downloaded']}")
- print(f"- 失败: {stats['covers']['failed']}")
- print(f"\n头像图片:")
- print(f"- 总数: {stats['avatars']['total']}")
- print(f"- 已下载: {stats['avatars']['downloaded']}")
- print(f"- 失败: {stats['avatars']['failed']}")
-
- print(f"\n下载任务完成 - {datetime.now().strftime('%Y-%m-%d %H:%M:%S')}")
- print(f"总处理记录数: {total_processed}")
- print('='*50)
-
- except Exception as e:
- print("\n下载过程发生错误:")
- print(f"错误类型: {type(e).__name__}")
- print(f"错误信息: {str(e)}")
- import traceback
- print("错误堆栈:")
- print(traceback.format_exc())
- finally:
- # 确保无论发生什么情况,状态都会设置为已完成
- print("\n结束下载任务,设置状态为已完成")
- self.is_downloading = False
-
- # 如果下载已完成且所有图片都已下载,重置计数器
- if self.total_covers_to_download == 0 and self.total_avatars_to_download == 0:
- print("下载已完成,重置计数器")
- self.initial_covers_total = 0
- self.initial_avatars_total = 0
-
- if 'conn' in locals():
- conn.close()
- print("数据库连接已关闭")
-
- def get_download_stats(self) -> Dict:
- """获取下载统计信息"""
- print("\n=== 获取下载统计 ===")
-
- # 从数据库获取统计信息
- print("从数据库获取统计信息...")
- stats = self.db.get_stats()
-
- # 如果没有正在下载,计算潜在的下载数量
- if not self.is_downloading:
- print("\n计算潜在的下载数量...")
- # 获取所有年份
- years = get_available_years()
- if years:
- # 收集所有URL
- total_cover_urls = []
- total_avatar_urls = []
- for year in years:
- cover_urls, avatar_urls = self._preprocess_year_data(year)
- total_cover_urls.extend(cover_urls)
- total_avatar_urls.extend(avatar_urls)
-
- # 过滤出需要下载的新URL
- new_cover_urls = self._filter_new_urls(total_cover_urls, True)
- new_avatar_urls = self._filter_new_urls(total_avatar_urls, False)
-
- # 更新总下载数量
- self.total_covers_to_download = len(new_cover_urls)
- self.total_avatars_to_download = len(new_avatar_urls)
-
- # 更新初始total值 - 仅在非下载状态下
- self.initial_covers_total = stats['covers']['downloaded'] + self.total_covers_to_download
- self.initial_avatars_total = stats['avatars']['downloaded'] + self.total_avatars_to_download
-
- print(f"潜在下载数量:")
- print(f"- 封面: {self.total_covers_to_download}")
- print(f"- 头像: {self.total_avatars_to_download}")
-
- print(f"更新初始total值:")
- print(f"- 封面: {self.initial_covers_total}")
- print(f"- 头像: {self.initial_avatars_total}")
- else:
- # 如果正在下载,根据初始total和当前下载量计算待下载数量
- # 初始total应该保持不变,只调整total_planned
- self.total_covers_to_download = max(0, self.initial_covers_total - stats['covers']['downloaded'])
- self.total_avatars_to_download = max(0, self.initial_avatars_total - stats['avatars']['downloaded'])
-
- print(f"下载进度:")
- print(f"- 封面: 已下载 {stats['covers']['downloaded']}/{self.initial_covers_total},剩余 {self.total_covers_to_download}")
- print(f"- 头像: 已下载 {stats['avatars']['downloaded']}/{self.initial_avatars_total},剩余 {self.total_avatars_to_download}")
-
- # 检查下载是否实际已完成
- if (self.total_covers_to_download == 0 and self.total_avatars_to_download == 0 and
- stats['covers']['downloaded'] == self.initial_covers_total and
- stats['avatars']['downloaded'] == self.initial_avatars_total):
- print("\n检测到所有图片已下载完成,自动设置下载状态为已完成")
- self.is_downloading = False
-
- # 更新统计信息
- # 对于下载状态,使用初始固定total值
- # 对于非下载状态,使用downloaded + total_planned
- if self.is_downloading:
- stats['covers']['total'] = self.initial_covers_total
- stats['avatars']['total'] = self.initial_avatars_total
- else:
- stats['covers']['total'] = stats['covers']['downloaded'] + self.total_covers_to_download
- stats['avatars']['total'] = stats['avatars']['downloaded'] + self.total_avatars_to_download
-
- print(f"最终统计结果:")
- print(f"- 封面总数: {stats['covers']['total']}")
- print(f"- 封面已下载: {stats['covers']['downloaded']}")
- print(f"- 封面待下载: {self.total_covers_to_download}")
- print(f"- 头像总数: {stats['avatars']['total']}")
- print(f"- 头像已下载: {stats['avatars']['downloaded']}")
- print(f"- 头像待下载: {self.total_avatars_to_download}")
- print(f"- 下载状态: {'正在下载' if self.is_downloading else '已完成'}")
-
- # 添加总下载数量信息
- stats['covers']['total_planned'] = self.total_covers_to_download
- stats['avatars']['total_planned'] = self.total_avatars_to_download
-
- # 添加其他信息
- stats.update({
- 'last_update': int(time.time()),
- 'is_downloading': self.is_downloading
- })
-
-
- return stats
-
- def clear_all_images(self):
- """清空所有图片和下载状态"""
- try:
- print("\n开始清空所有图片和下载状态...")
-
- # 停止当前下载任务(如果有)
- self.is_downloading = False
- self.download_queue = Queue()
-
- # 清空数据库
- self.db.clear_all()
-
- # 删除所有图片文件夹中的文件
- def remove_files_in_dir(directory):
- if os.path.exists(directory):
- for root, dirs, files in os.walk(directory, topdown=False):
- for name in files:
- try:
- file_path = os.path.join(root, name)
- os.remove(file_path)
- except Exception as e:
- print(f"删除文件失败: {file_path} - {str(e)}")
- for name in dirs:
- try:
- dir_path = os.path.join(root, name)
- os.rmdir(dir_path)
- except Exception as e:
- print(f"删除文件夹失败: {dir_path} - {str(e)}")
-
- # 清空各个图片目录
- remove_files_in_dir(self.covers_path)
- remove_files_in_dir(self.avatars_path)
- remove_files_in_dir(self.orphaned_covers_path)
- remove_files_in_dir(self.orphaned_avatars_path)
-
- # 重新创建基础目录
- os.makedirs(self.covers_path, exist_ok=True)
- os.makedirs(self.avatars_path, exist_ok=True)
- os.makedirs(self.orphaned_covers_path, exist_ok=True)
- os.makedirs(self.orphaned_avatars_path, exist_ok=True)
-
- print("\n清空操作完成!")
- print(f"- 图片保存基础路径: {self.base_path}")
- print(f"- 封面保存路径: {self.covers_path}")
- print(f"- 头像保存路径: {self.avatars_path}")
- print(f"- 孤立封面保存路径: {self.orphaned_covers_path}")
- print(f"- 孤立头像保存路径: {self.orphaned_avatars_path}")
-
- return True
-
- except Exception as e:
- print(f"\n清空过程发生错误:")
- print(f"错误类型: {type(e).__name__}")
- print(f"错误信息: {str(e)}")
- import traceback
- print("错误堆栈:")
- print(traceback.format_exc())
- return False
-
- def _preprocess_year_data(self, year: int) -> Tuple[List[str], List[str]]:
- """预处理指定年份的数据,获取需要下载的图片URL
-
- Args:
- year: 要处理的年份
-
- Returns:
- Tuple[List[str], List[str]]: 封面URL列表和头像URL列表
- """
- print(f"\n=== 预处理 {year} 年数据 ===")
-
- conn = get_db()
- try:
- cursor = conn.cursor()
- table_name = f"bilibili_history_{year}"
-
- # 获取封面URL和头像URL,明确包含covers字段
- cursor.execute(f"""
- SELECT DISTINCT cover, covers, author_face
- FROM {table_name}
- WHERE cover IS NOT NULL OR covers IS NOT NULL OR author_face IS NOT NULL
- """)
-
- cover_urls = set()
- avatar_urls = set()
-
- for row in cursor.fetchall():
- cover, covers_json, avatar = row
-
- # 处理封面URL
- if cover:
- cover_urls.add(cover)
-
- # 处理JSON格式的covers字段
- if covers_json:
- try:
- # 先检查covers_json是否已经是JSON对象
- if isinstance(covers_json, str):
- covers = json.loads(covers_json)
- else:
- covers = covers_json
-
- # 如果covers是列表,添加所有URL
- if isinstance(covers, list):
- for url in covers:
- if url and isinstance(url, str):
- cover_urls.add(url)
- # 如果covers是字典,提取其中的所有URL
- elif isinstance(covers, dict):
- for key, value in covers.items():
- if isinstance(value, str) and ('http://' in value or 'https://' in value):
- cover_urls.add(value)
- except (json.JSONDecodeError, TypeError) as e:
- print(f"解析covers字段失败: {e} - 值: {covers_json}")
-
- # 处理头像URL
- if avatar:
- avatar_urls.add(avatar)
-
- print(f"找到 {len(cover_urls)} 个封面URL")
- print(f"找到 {len(avatar_urls)} 个头像URL")
-
- return list(cover_urls), list(avatar_urls)
-
- except sqlite3.Error as e:
- print(f"数据库错误: {str(e)}")
- return [], []
- finally:
- conn.close()
-
- def _filter_new_urls(self, urls: List[str], is_cover: bool) -> List[str]:
- """过滤出需要下载的新URL
-
- Args:
- urls: URL列表
- is_cover: 是否是封面图片
-
- Returns:
- List[str]: 需要下载的URL列表
- """
- new_urls = []
- for url in urls:
- if not url: # 跳过空URL
- continue
-
- # 计算URL的哈希值
- hash_value = self._get_file_hash(url)
-
- # 检查是否已下载
- status = self.db.get_status(hash_value)
- if not status or not status['downloaded']:
- new_urls.append(url)
-
- return new_urls
-
- def stop_download(self):
- """停止当前下载任务"""
- print("\n=== 正在停止下载任务 ===")
-
- # 设置停止标志
- self.is_downloading = False
-
- # 重置下载相关的初始值
- self.total_covers_to_download = 0
- self.total_avatars_to_download = 0
- self.initial_covers_total = 0
- self.initial_avatars_total = 0
-
- # 清空下载队列
- while not self.download_queue.empty():
- try:
- self.download_queue.get_nowait()
- self.download_queue.task_done()
- except Empty:
- break
-
- print("已清空下载队列")
- print("等待现有下载任务完成...")
- print("注意:已开始的下载会继续完成")
- print("======================\n")
-
- return {
- "status": "success",
- "message": "下载任务已停止",
- "stats": self.get_download_stats()
- }
-
-def get_db():
- """获取数据库连接"""
- db_path = get_output_path(config['db_file'])
- return sqlite3.connect(db_path)
-
-def get_available_years() -> List[int]:
- """获取可用的年份列表"""
- conn = get_db()
- try:
- cursor = conn.cursor()
- cursor.execute("""
- SELECT name FROM sqlite_master
- WHERE type='table' AND name LIKE 'bilibili_history_%'
- """)
- tables = cursor.fetchall()
- years = []
- for (table_name,) in tables:
- try:
- year = int(table_name.split('_')[-1])
- years.append(year)
- except (ValueError, IndexError):
- continue
- return sorted(years, reverse=True)
- finally:
- if conn:
- conn.close()
-
-if __name__ == '__main__':
- try:
- print("\n=== 开始图片下载任务 ===")
- print("初始化下载器...")
- downloader = ImageDownloader()
-
- print("\n下载2025年的图片...")
- downloader.start_download(2025)
-
- print("\n获取下载统计...")
- stats = downloader.get_download_stats()
- print("\n下载统计:")
- print(f"封面图片: 总数 {stats['covers']['total']}, "
- f"已下载 {stats['covers']['downloaded']}, "
- f"失败 {stats['covers']['failed']}")
- print(f"头像图片: 总数 {stats['avatars']['total']}, "
- f"已下载 {stats['avatars']['downloaded']}, "
- f"失败 {stats['avatars']['failed']}")
- except Exception as e:
- print("\n程序执行出错:")
- print(f"错误类型: {type(e).__name__}")
- print(f"错误信息: {str(e)}")
- import traceback
- print("错误堆栈:")
- print(traceback.format_exc())
\ No newline at end of file
diff --git a/scripts/import_database.py b/scripts/import_database.py
deleted file mode 100644
index 2a9558e..0000000
--- a/scripts/import_database.py
+++ /dev/null
@@ -1,394 +0,0 @@
-import pymysql
-import json
-import os
-import time
-import threading
-from datetime import datetime
-import sys
-
-from config.sql_statements_mysql import *
-from scripts.utils import load_config, get_base_path, get_output_path
-
-config = load_config()
-base_path = get_base_path()
-
-# 加载分类映射
-def load_categories():
- """从 categories.json 文件中加载分类信息"""
- try:
- # 获取基础路径
- if getattr(sys, 'frozen', False):
- # 如果是打包后的exe运行,配置文件在_internal目录中
- base_path = os.path.dirname(sys.executable)
- categories_path = os.path.join(base_path, '_internal', 'config', 'categories.json')
- else:
- # 如果是直接运行python脚本
- base_path = os.path.dirname(os.path.dirname(os.path.abspath(__file__)))
- categories_path = os.path.join(base_path, 'config', 'categories.json')
-
- print(f"\n=== 分类配置信息 ===")
- print(f"基础路径: {base_path}")
- print(f"配置文件路径: {categories_path}")
- print(f"配置文件存在: {os.path.exists(categories_path)}")
-
- # 如果配置文件不存在,尝试其他可能的位置
- if not os.path.exists(categories_path):
- alternative_paths = [
- os.path.join(base_path, 'config', 'categories.json'),
- os.path.join(os.getcwd(), 'config', 'categories.json'),
- os.path.join(base_path, '_internal', 'config', 'categories.json'),
- ]
- print("\n尝试其他可能的配置文件位置:")
- for alt_path in alternative_paths:
- print(f"检查: {alt_path} - {'存在' if os.path.exists(alt_path) else '不存在'}")
- if os.path.exists(alt_path):
- categories_path = alt_path
- break
-
- if not os.path.exists(categories_path):
- raise FileNotFoundError(f"找不到分类配置文件: {categories_path}")
-
- with open(categories_path, 'r', encoding='utf-8') as f:
- categories = json.load(f)
- print(f"成功加载分类配置")
- return categories['duplicated_tags'], categories['unique_tag_to_main']
- except Exception as e:
- print(f"加载分类配置时发生错误: {e}")
- raise
-
-duplicated_tags, unique_tag_to_main = load_categories()
-
-# 雪花算法生成器类
-class SnowflakeIDGenerator:
- def __init__(self, machine_id=1, datacenter_id=1):
- self.lock = threading.Lock()
- self.machine_id = machine_id & 0x3FF # 10 位
- self.datacenter_id = datacenter_id & 0x3FF # 10 位
- self.sequence = 0
- self.last_timestamp = -1
- self.epoch = 1609459200000 # 2021-01-01 00:00:00 UTC 以毫秒为单位
-
- def _current_millis(self):
- return int(time.time() * 1000)
-
- def get_id(self):
- with self.lock:
- timestamp = self._current_millis()
-
- if timestamp < self.last_timestamp:
- raise Exception("时钟向后移动。拒绝生成 id。")
-
- if timestamp == self.last_timestamp:
- self.sequence = (self.sequence + 1) & 0xFFF # 12 bits
- if self.sequence == 0:
- # 等待下一秒
- while timestamp <= self.last_timestamp:
- timestamp = self._current_millis()
- else:
- self.sequence = 0
-
- self.last_timestamp = timestamp
-
- # 生成64位ID
- id = ((timestamp - self.epoch) << 22) | (self.datacenter_id << 12) | self.sequence
- return id
-
-# 初始化雪花ID生成器
-id_generator = SnowflakeIDGenerator(machine_id=1, datacenter_id=1)
-
-# 获取当前年份和上一年份
-def get_years():
- current_year = datetime.now().year
- previous_year = current_year - 1
- return current_year, previous_year
-
-# 连接到 MySQL 数据库,并在必要时创建数据库
-def connect_to_db():
- try:
- # 首先连接到 MySQL,不指定数据库
- connection = pymysql.connect(
- host=os.getenv('DB_HOST', 'localhost'),
- port=int(os.getenv('DB_PORT', 3306)),
- user=os.getenv('DB_USER', 'root'),
- password=os.getenv('DB_PASSWORD', '123456789'),
- charset='utf8mb4',
- cursorclass=pymysql.cursors.DictCursor,
- autocommit=True
- )
- with connection.cursor() as cursor:
- # 列出所有数据库
- cursor.execute("SHOW DATABASES;")
- databases = cursor.fetchall()
-
- # 检查数据库是否存在
- db_name = os.getenv('DB_NAME', 'bilibilihistory')
- print(f"使用的数据库名称是: {db_name}")
- cursor.execute(SHOW_DATABASES, (db_name,))
- result = cursor.fetchone()
- if not result:
- # 创建数据库
- cursor.execute(CREATE_DATABASE.format(db_name=db_name))
- print(f"数据库 '{db_name}' 已创建。")
- else:
- print(f"数据库 '{db_name}' 已存在。")
- connection.close()
-
- # 重新连接到刚创建或已存在的数据库
- connection = pymysql.connect(
- host=os.getenv('DB_HOST', 'localhost'),
- port=int(os.getenv('DB_PORT', 3306)),
- user=os.getenv('DB_USER', 'root'),
- password=os.getenv('DB_PASSWORD', '123456789'),
- db=db_name,
- charset='utf8mb4',
- cursorclass=pymysql.cursors.DictCursor
- )
-
- # 再次列出当前连接的数据库
- with connection.cursor() as cursor:
- cursor.execute(SELECT_DATABASE)
- current_db = cursor.fetchone()['current_db']
- print(f"当前连接的数据库是: {current_db}")
-
- return connection
- except Exception as e:
- print(f"连接到数据库时发生错误: {e}")
- raise
-
-# 创建新年份的表,如果不存在
-def create_new_year_table(connection, new_table, reference_table):
- try:
- with connection.cursor() as cursor:
- # 检查新表是否存在
- cursor.execute(SHOW_TABLES, (connection.db, new_table))
- if cursor.fetchone()['COUNT(*)'] == 0:
- # 检查参考表是否存在
- cursor.execute(SHOW_TABLES, (connection.db, reference_table))
- if cursor.fetchone()['COUNT(*)'] == 0:
- # 如果参考表不存在,使用默认的 CREATE TABLE 语句
- create_table_sql = CREATE_TABLE_DEFAULT.format(table=new_table)
- else:
- # 如果参考表存在,复制参考表的结构
- create_table_sql = CREATE_TABLE_LIKE.format(new_table=new_table, reference_table=reference_table)
- cursor.execute(create_table_sql)
- connection.commit()
- base_structure = "默认结构" if "CREATE TABLE" in create_table_sql else reference_table
- print(f"已创建新表: {new_table},基于表: {base_structure}")
- else:
- print(f"表 {new_table} 已存在,无需创建。")
- except Exception as e:
- connection.rollback()
- print(f"创建新表时发生错误: {e}")
- raise
-
-# 批量插入数据到 MySQL,支持事务回滚
-def batch_insert_data(connection, insert_sql, data_chunk):
- try:
- with connection.cursor() as cursor:
- cursor.executemany(insert_sql, data_chunk)
- connection.commit()
- return len(data_chunk)
- except Exception as e:
- connection.rollback()
- print(f" 插入数据时发生错误: {e}")
- return 0
-
-# 从 JSON 文件导入数据
-def import_data_from_json(connection, insert_sql, file_path, batch_size=1000):
- with open(file_path, 'r', encoding='utf-8') as f:
- try:
- data = json.load(f)
- except json.JSONDecodeError as e:
- print(f"JSON 解码错误在文件 {file_path}: {e}")
- return 0
- except Exception as e:
- print(f"读取文件 {file_path} 时发生错误: {e}")
- return 0
-
- total_inserted = 0
-
- try:
- # 构建要插入的数据列表,并生成唯一的id
- new_data = []
- for index, item in enumerate(data, start=1):
- main_category = None
- history = item.get('history', {})
- business = history.get('business', '')
-
- # 始终获取 tag_name,即使 business 不是 'archive'
- tag_name = item.get('tag_name', '').strip()
-
- if business == 'archive':
- if tag_name in unique_tag_to_main:
- main_category = unique_tag_to_main[tag_name]
- elif tag_name in duplicated_tags:
- main_category = '待定'
- else:
- main_category = '待定'
- # 如果 business 不为 'archive',main_category 保持为 None
-
- record = {
- "id": id_generator.get_id(), # 生成唯一ID
- "title": item.get('title', ''),
- "long_title": item.get('long_title', ''),
- "cover": item.get('cover', ''),
- "covers": json.dumps(item.get('covers', [])),
- "uri": item.get('uri', ''),
- "oid": history.get('oid', 0),
- "epid": history.get('epid', 0),
- "bvid": history.get('bvid', ''),
- "page": history.get('page', 1),
- "cid": history.get('cid', 0),
- "part": history.get('part', ''),
- "business": business,
- "dt": history.get('dt', 0),
- "videos": item.get('videos', 1),
- "author_name": item.get('author_name', ''),
- "author_face": item.get('author_face', ''),
- "author_mid": item.get('author_mid', 0),
- "view_at": item.get('view_at', 0),
- "progress": item.get('progress', 0),
- "badge": item.get('badge', ''),
- "show_title": item.get('show_title', ''),
- "duration": item.get('duration', 0),
- "current": item.get('current', ''),
- "total": item.get('total', 0),
- "new_desc": item.get('new_desc', ''),
- "is_finish": item.get('is_finish', 0),
- "is_fav": item.get('is_fav', 0),
- "kid": item.get('kid', 0),
- "tag_name": tag_name, # 确保 tag_name 被赋值
- "live_status": item.get('live_status', 0),
- "main_category": main_category # 设置主分区
- }
- new_data.append(record)
-
- # 分批插入数据
- for i in range(0, len(new_data), batch_size):
- batch_chunk = new_data[i:i + batch_size]
- inserted_count = batch_insert_data(connection, insert_sql, batch_chunk)
- total_inserted += inserted_count
-
- return total_inserted
-
- except Exception as e:
- print(f"处理数据时发生错误: {e}")
- return 0
-
-# 读取标记文件,返回上次导入的日期和文件名
-def get_last_imported_file():
- file_path = get_output_path(config['log_file'])
- if not os.path.exists(file_path):
- return None, None
- with open(file_path, 'r', encoding='utf-8') as f:
- try:
- data = json.load(f)
- return data.get('last_imported_date'), data.get('last_imported_file')
- except json.JSONDecodeError:
- print("标记文件格式错误,无法解析。")
- return None, None
-
-# 更新标记文件,记录本次导入的日期和文件名
-def update_last_imported_file(last_imported_date, last_imported_file):
- file_path = get_output_path(config['log_file'])
- data = {
- 'last_imported_date': last_imported_date,
- 'last_imported_file': last_imported_file
- }
- with open(file_path, 'w', encoding='utf-8') as f:
- json.dump(data, f, ensure_ascii=False, indent=4)
-
-# 遍历所有按日期分割的文件并导入数据
-def import_all_history_files():
- base_path = get_base_path()
- full_data_folder = os.path.join(base_path, 'output/history_by_date') # 修改为新的路径
- log_file = os.path.join(base_path, config['log_file'])
-
- total_inserted = 0
- file_insert_counts = {}
-
- print(f"开始遍历并导入文件夹 '{full_data_folder}' 中的数据...")
-
- if not os.path.exists(full_data_folder):
- print(f"本地文件夹 '{full_data_folder}' 不存在,无法加载数据。")
- return {"status": "error", "message": f"本地文件夹 '{full_data_folder}' 不存在,无法加载数据。"}
-
- # 获取当前年份和上一年份
- current_year, previous_year = get_years()
- new_table = f"bilibili_history_{current_year}"
- reference_table = f"bilibili_history_{previous_year}"
-
- connection = connect_to_db()
- try:
- # 创建新年份的表,如果不存在
- create_new_year_table(connection, new_table, reference_table)
-
- # 定义动态的 INSERT SQL 语句
- insert_sql = INSERT_DATA.format(table=new_table)
-
- # 读取上次导入的文件日期和文件名
- last_imported_date, last_imported_file = get_last_imported_file()
- print(f"上次导入的日期: {last_imported_date}, 文件: {last_imported_file}")
-
- # 遍历按日期分割的文件夹
- for year in sorted(os.listdir(full_data_folder)):
- year_path = os.path.join(full_data_folder, year)
- if os.path.isdir(year_path) and year.isdigit():
- for month in sorted(os.listdir(year_path)):
- month_path = os.path.join(year_path, month)
- if os.path.isdir(month_path) and month.isdigit():
- for day_file in sorted(os.listdir(month_path)):
- if day_file.endswith('.json'):
- day_path = os.path.join(month_path, day_file)
-
- # 获取当前文件的日期
- day = ''.join(filter(str.isdigit, day_file))[:2] # 提取前两位数字作为日
- if len(day) != 2:
- print(f"无法解析文件名中的日期: {day_file},跳过文件。")
- continue
- file_date = f"{year}-{month.zfill(2)}-{day.zfill(2)}"
-
- # 如果当前文件日期和上次相同,继续检查文件名顺序
- if last_imported_date:
- if file_date < last_imported_date:
- print(f"跳过文件 {day_path},日期 {file_date} 在上次导入日期之前。")
- continue
- elif file_date == last_imported_date and day_file <= last_imported_file:
- print(f"跳过文件 {day_path},文件名 {day_file} 在上次导入文件之前或相同。")
- continue
-
- # 开始导入文件
- inserted_count = import_data_from_json(connection, insert_sql, day_path)
- total_inserted += inserted_count
- file_insert_counts[day_path] = inserted_count
-
- # 更新标记文件
- update_last_imported_file(file_date, day_file)
-
- # 输出每个文件的插入条数
- print("\n每个文件的插入记录:")
- for file, count in file_insert_counts.items():
- print(f"{file}: 插入或更新了 {count} 条数据")
-
- # 输出总插入条数
- print(f"\n所有文件均已导入数据库,总共插入或更新了 {total_inserted} 条数据。")
-
- except Exception as e:
- print(f"导入过程中发生错误: {e}")
-
- finally:
- connection.close()
-
- return {"status": "success", "message": f"所有文件均已导入数据库,总共插入或更新了 {total_inserted} 条数据。"}
-
-# 供外部调用的接口
-def import_history():
- return import_all_history_files()
-
-# 如果该脚本直接运行,则调用 import_all_history_files()
-if __name__ == '__main__':
- result = import_all_history_files()
- if result["status"] == "success":
- print(result["message"])
- else:
- print(f"错误: {result['message']}")
diff --git a/scripts/import_sqlite.py b/scripts/import_sqlite.py
index 8ced862..8291a33 100644
--- a/scripts/import_sqlite.py
+++ b/scripts/import_sqlite.py
@@ -7,7 +7,7 @@
from datetime import datetime
from config.sql_statements_sqlite import CREATE_TABLE_DEFAULT, CREATE_INDEXES, INSERT_DATA
-from scripts.utils import load_config, get_base_path, get_output_path
+from scripts.utils import get_config_path, get_output_path, load_config
config = load_config()
@@ -15,16 +15,10 @@
logging.basicConfig(level=logging.INFO)
logger = logging.getLogger(__name__)
-IS_SCRIPT_RUN = True
-
-def get_base_path():
- return os.path.dirname(os.path.dirname(os.path.abspath(__file__))) if IS_SCRIPT_RUN else os.getcwd()
-
# 定义读取分类信息的函数
def load_categories(config_path=None):
if config_path is None:
- base_path = get_base_path()
- config_path = os.path.join(base_path, 'config', 'categories.json')
+ config_path = get_config_path('categories.json')
"""从 categories.json 文件中加载分类信息"""
try:
with open(config_path, 'r', encoding='utf-8') as f:
@@ -74,11 +68,6 @@ def get_id(self):
id_generator = SnowflakeIDGenerator(machine_id=1, datacenter_id=1)
-def get_years():
- current_year = datetime.now().year
- previous_year = current_year - 1
- return current_year, previous_year
-
def create_connection(db_file):
"""创建数据库连接"""
try:
@@ -128,23 +117,9 @@ def batch_insert_data(conn, table_name, data_batch):
except sqlite3.Error as e:
logger.error(f"插入数据时发生错误: {e}")
conn.rollback()
- return 0
-
-def get_last_import_time():
- """获取上次导入时间"""
- try:
- last_import_file = os.path.join(get_output_path(), 'last_import.json')
- if os.path.exists(last_import_file):
- with open(last_import_file, 'r', encoding='utf-8') as f:
- data = json.load(f)
- return data.get('last_import_time', 0)
- logger.info("未找到last_import.json文件,将导入所有数据")
- return 0
- except Exception as e:
- logger.error(f"读取上次导入时间失败: {e}")
- return 0
+ raise
-def import_data_from_json(conn, table_name, file_path, last_import_time=0, batch_size=1000, sync_deleted=False):
+def import_data_from_json(conn, table_name, file_path, last_import_time=0, batch_size=1000):
"""从JSON文件导入数据"""
try:
# 尝试不同的编码方式读取
@@ -164,12 +139,12 @@ def import_data_from_json(conn, table_name, file_path, last_import_time=0, batch
total_inserted = 0
# 按年份分组数据
data_by_year = {}
- has_new_records = False
# 获取现有记录的bvid和view_at组合
cursor = conn.cursor()
existing_records = set()
- for year in range(datetime.now().year - 1, datetime.now().year + 1):
+ years = {datetime.fromtimestamp(item['view_at']).year for item in data if item.get('view_at')}
+ for year in years:
table = f"bilibili_history_{year}"
if table_exists(conn, table):
cursor.execute(f"SELECT bvid, view_at FROM {table}")
@@ -177,19 +152,8 @@ def import_data_from_json(conn, table_name, file_path, last_import_time=0, batch
# 获取已删除的记录
deleted_records = set()
- if not sync_deleted:
- # 确保删除记录表存在
- cursor.execute("""
- CREATE TABLE IF NOT EXISTS deleted_history (
- id INTEGER PRIMARY KEY,
- bvid TEXT NOT NULL,
- view_at INTEGER NOT NULL,
- delete_time INTEGER NOT NULL,
- UNIQUE(bvid, view_at)
- )
- """)
-
- # 获取已删除的记录
+ if table_exists(conn, 'deleted_history'):
+ # 保留已有记录的删除标记,导入时不恢复这些记录。
cursor.execute("SELECT bvid, view_at FROM deleted_history")
deleted_records = set((bvid, view_at) for bvid, view_at in cursor.fetchall())
logger.info(f"已加载 {len(deleted_records)} 条已删除的记录")
@@ -214,11 +178,10 @@ def import_data_from_json(conn, table_name, file_path, last_import_time=0, batch
continue
# 如果不同步已删除的记录,则跳过已删除的记录
- if not sync_deleted and (bvid, view_at) in deleted_records:
+ if (bvid, view_at) in deleted_records:
logger.debug(f"跳过已删除的记录: {item.get('title')} - {datetime.fromtimestamp(view_at)}")
continue
- has_new_records = True
year = datetime.fromtimestamp(view_at).year
if year not in data_by_year:
data_by_year[year] = []
@@ -301,7 +264,7 @@ def import_data_from_json(conn, table_name, file_path, last_import_time=0, batch
except sqlite3.Error as e:
logger.error(f"导入数据时发生错误: {e}")
- return 0
+ raise
def save_last_import_record(file_path, timestamp):
"""保存最后导入记录"""
@@ -324,7 +287,7 @@ def get_last_import_record():
return json.load(f)
return None
-def import_all_history_files(sync_deleted=False):
+def import_all_history_files(incremental=True):
"""导入所有历史记录文件"""
current_time = datetime.now().strftime("%Y-%m-%d %H:%M:%S")
logger.info(f"========== 运行时间: {current_time} ==========")
@@ -344,7 +307,7 @@ def import_all_history_files(sync_deleted=False):
return {"status": "error", "message": message}
# 获取最后导入记录
- last_record = get_last_import_record()
+ last_record = get_last_import_record() if incremental else None
last_import_time = last_record['last_import_time'] if last_record else 0
if last_record:
@@ -409,7 +372,7 @@ def import_all_history_files(sync_deleted=False):
logger.error(f"读取文件 {day_path} 时出错: {e}")
continue
- inserted_count = import_data_from_json(conn, "bilibili_history", day_path, last_import_time, sync_deleted=sync_deleted)
+ inserted_count = import_data_from_json(conn, "bilibili_history", day_path, last_import_time)
if inserted_count > 0:
total_files += 1
total_records += inserted_count
diff --git a/scripts/init_categories.py b/scripts/init_categories.py
deleted file mode 100644
index e64b51f..0000000
--- a/scripts/init_categories.py
+++ /dev/null
@@ -1,223 +0,0 @@
-import sqlite3
-from scripts.utils import get_output_path, load_config
-
-def init_categories():
- """初始化视频分类表"""
- config = load_config()
- db_path = get_output_path(config['db_file'])
-
- conn = sqlite3.connect(db_path)
- cursor = conn.cursor()
-
- try:
- # 创建视频分类表
- cursor.execute('''
- CREATE TABLE IF NOT EXISTS video_categories (
- id INTEGER PRIMARY KEY AUTOINCREMENT,
- main_category TEXT NOT NULL,
- sub_category TEXT NOT NULL,
- alias TEXT NOT NULL,
- tid INTEGER NOT NULL,
- image TEXT
- )
- ''')
-
- # 插入数据
- categories_data = [
- ('动画', '动画', 'douga', 1, 'https://socialsisteryi.github.io/bilibili-API-collect/assets/douga-551968c9.svg'),
- ('动画', 'MAD·AMV', 'mad', 24, 'https://socialsisteryi.github.io/bilibili-API-collect/assets/douga-551968c9.svg' ),
- ('动画', 'MMD·3D', 'mmd', 25, 'https://socialsisteryi.github.io/bilibili-API-collect/assets/douga-551968c9.svg'),
- ('动画', '短片·手书', 'handdrawn', 47, 'https://socialsisteryi.github.io/bilibili-API-collect/assets/douga-551968c9.svg'),
- ('动画', '配音', 'voice', 257, 'https://socialsisteryi.github.io/bilibili-API-collect/assets/douga-551968c9.svg'),
- ('动画', '手办·模玩', 'garage_kit', 210, 'https://socialsisteryi.github.io/bilibili-API-collect/assets/douga-551968c9.svg'),
- ('动画', '特摄', 'tokusatsu', 86, 'https://socialsisteryi.github.io/bilibili-API-collect/assets/douga-551968c9.svg'),
- ('动画', '动漫杂谈', 'acgntalks', 253, 'https://socialsisteryi.github.io/bilibili-API-collect/assets/douga-551968c9.svg'),
- ('动画', '综合', 'other', 27, 'https://socialsisteryi.github.io/bilibili-API-collect/assets/douga-551968c9.svg'),
-
- ('番剧', '番剧', 'anime', 13,'https://socialsisteryi.github.io/bilibili-API-collect/assets/anime-b33a4df8.svg'),
- ('番剧', '资讯', 'information', 51,'https://socialsisteryi.github.io/bilibili-API-collect/assets/anime-b33a4df8.svg'),
- ('番剧', '官方延伸', 'offical', 152,'https://socialsisteryi.github.io/bilibili-API-collect/assets/anime-b33a4df8.svg'),
- ('番剧', '完结动画', 'finish', 32,'https://socialsisteryi.github.io/bilibili-API-collect/assets/anime-b33a4df8.svg'),
- ('番剧', '连载动画', 'serial', 33,'https://socialsisteryi.github.io/bilibili-API-collect/assets/anime-b33a4df8.svg'),
-
- ('国创', '国创', 'guochuang', 167,'https://socialsisteryi.github.io/bilibili-API-collect/assets/guochuang-2887858d.svg'),
- ('国创', '国产动画', 'chinese', 153,'https://socialsisteryi.github.io/bilibili-API-collect/assets/guochuang-2887858d.svg'),
- ('国创', '国产原创相关', 'original', 168,'https://socialsisteryi.github.io/bilibili-API-collect/assets/guochuang-2887858d.svg'),
- ('国创', '布袋戏', 'puppetry', 169,'https://socialsisteryi.github.io/bilibili-API-collect/assets/guochuang-2887858d.svg'),
- ('国创', '资讯', 'information', 170,'https://socialsisteryi.github.io/bilibili-API-collect/assets/guochuang-2887858d.svg'),
- ('国创', '动态漫·广播剧', 'motioncomic', 195,'https://socialsisteryi.github.io/bilibili-API-collect/assets/guochuang-2887858d.svg'),
-
- ('音乐', '音乐', 'music', 3,'https://socialsisteryi.github.io/bilibili-API-collect/assets/music-1d6aa097.svg'),
- ('音乐', '原创音乐', 'original', 28,'https://socialsisteryi.github.io/bilibili-API-collect/assets/music-1d6aa097.svg'),
- ('音乐', '翻唱', 'cover', 31,'https://socialsisteryi.github.io/bilibili-API-collect/assets/music-1d6aa097.svg'),
- ('音乐', 'VOCALOID·UTAU', 'vocaloid', 30,'https://socialsisteryi.github.io/bilibili-API-collect/assets/music-1d6aa097.svg'),
- ('音乐', '演奏', 'perform', 59,'https://socialsisteryi.github.io/bilibili-API-collect/assets/music-1d6aa097.svg'),
- ('音乐', 'MV', 'mv', 193,'https://socialsisteryi.github.io/bilibili-API-collect/assets/music-1d6aa097.svg'),
- ('音乐', '音乐现场', 'live', 29,'https://socialsisteryi.github.io/bilibili-API-collect/assets/music-1d6aa097.svg'),
- ('音乐', '音乐综合', 'other', 130,'https://socialsisteryi.github.io/bilibili-API-collect/assets/music-1d6aa097.svg'),
- ('音乐', '乐评盘点', 'commentary', 243,'https://socialsisteryi.github.io/bilibili-API-collect/assets/music-1d6aa097.svg'),
- ('音乐', '音乐教学', 'tutorial', 244,'https://socialsisteryi.github.io/bilibili-API-collect/assets/music-1d6aa097.svg'),
-
- ('舞蹈', '舞蹈', 'dance', 129,'https://socialsisteryi.github.io/bilibili-API-collect/assets/dance-26e4156b.svg'),
- ('舞蹈', '宅舞', 'otaku', 20,'https://socialsisteryi.github.io/bilibili-API-collect/assets/dance-26e4156b.svg'),
- ('舞蹈', '舞蹈综合', 'three_d', 154,'https://socialsisteryi.github.io/bilibili-API-collect/assets/dance-26e4156b.svg'),
- ('舞蹈', '舞蹈教程', 'demo', 156,'https://socialsisteryi.github.io/bilibili-API-collect/assets/dance-26e4156b.svg'),
- ('舞蹈', '街舞', 'hiphop', 198,'https://socialsisteryi.github.io/bilibili-API-collect/assets/dance-26e4156b.svg'),
- ('舞蹈', '明星舞蹈', 'star', 199,'https://socialsisteryi.github.io/bilibili-API-collect/assets/dance-26e4156b.svg'),
- ('舞蹈', '国风舞蹈', 'china', 200,'https://socialsisteryi.github.io/bilibili-API-collect/assets/dance-26e4156b.svg'),
- ('舞蹈', '手势·网红舞', 'gestures', 255,'https://socialsisteryi.github.io/bilibili-API-collect/assets/dance-26e4156b.svg'),
-
- ('游戏', '游戏', 'game', 4,'https://socialsisteryi.github.io/bilibili-API-collect/assets/game-158a0730.svg'),
- ('游戏', '单机游戏', 'stand_alone', 17,'https://socialsisteryi.github.io/bilibili-API-collect/assets/game-158a0730.svg'),
- ('游戏', '电子竞技', 'esports', 171,'https://socialsisteryi.github.io/bilibili-API-collect/assets/game-158a0730.svg'),
- ('游戏', '手机游戏', 'mobile', 172,'https://socialsisteryi.github.io/bilibili-API-collect/assets/game-158a0730.svg'),
- ('游戏', '网络游戏', 'online', 65,'https://socialsisteryi.github.io/bilibili-API-collect/assets/game-158a0730.svg'),
- ('游戏', '桌游棋牌', 'board', 173,'https://socialsisteryi.github.io/bilibili-API-collect/assets/game-158a0730.svg'),
- ('游戏', 'GMV', 'gmv', 121,'https://socialsisteryi.github.io/bilibili-API-collect/assets/game-158a0730.svg'),
- ('游戏', '音游', 'music', 136,'https://socialsisteryi.github.io/bilibili-API-collect/assets/game-158a0730.svg'),
- ('游戏', 'Mugen', 'mugen', 19,'https://socialsisteryi.github.io/bilibili-API-collect/assets/game-158a0730.svg'),
-
- ('知识', '知识', 'knowledge', 36,'https://socialsisteryi.github.io/bilibili-API-collect/assets/knowledge-65fd8dce.svg'),
- ('知识', '科学科普', 'science', 201,'https://socialsisteryi.github.io/bilibili-API-collect/assets/knowledge-65fd8dce.svg'),
- ('知识', '社科·法律·心理', 'social_science', 124,'https://socialsisteryi.github.io/bilibili-API-collect/assets/knowledge-65fd8dce.svg'),
- ('知识', '人文历史', 'humanity_history', 228,'https://socialsisteryi.github.io/bilibili-API-collect/assets/knowledge-65fd8dce.svg'),
- ('知识', '财经商业', 'business', 207,'https://socialsisteryi.github.io/bilibili-API-collect/assets/knowledge-65fd8dce.svg'),
- ('知识', '校园学习', 'campus', 208,'https://socialsisteryi.github.io/bilibili-API-collect/assets/knowledge-65fd8dce.svg'),
- ('知识', '职业职场', 'career', 209,'https://socialsisteryi.github.io/bilibili-API-collect/assets/knowledge-65fd8dce.svg'),
- ('知识', '设计·创意', 'design', 229,'https://socialsisteryi.github.io/bilibili-API-collect/assets/knowledge-65fd8dce.svg'),
- ('知识', '野生技术协会', 'skill', 122,'https://socialsisteryi.github.io/bilibili-API-collect/assets/knowledge-65fd8dce.svg'),
-
-
- ('科技', '科技', 'tech', 188,'https://socialsisteryi.github.io/bilibili-API-collect/assets/tech-8f2eb72e.svg'),
- ('科技', '数码', 'digital', 95,'https://socialsisteryi.github.io/bilibili-API-collect/assets/tech-8f2eb72e.svg'),
- ('科技', '软件应用', 'application', 230,'https://socialsisteryi.github.io/bilibili-API-collect/assets/tech-8f2eb72e.svg'),
- ('科技', '计算机技术', 'computer_tech', 231,'https://socialsisteryi.github.io/bilibili-API-collect/assets/tech-8f2eb72e.svg'),
- ('科技', '科工机械', 'industry', 232,'https://socialsisteryi.github.io/bilibili-API-collect/assets/tech-8f2eb72e.svg'),
- ('科技', '极客DIY', 'diy', 233,'https://socialsisteryi.github.io/bilibili-API-collect/assets/tech-8f2eb72e.svg'),
-
-
- ('运动', '运动', 'sports', 234,'https://socialsisteryi.github.io/bilibili-API-collect/assets/sports-bfc825f3.svg'),
- ('运动', '篮球', 'basketball', 235,'https://socialsisteryi.github.io/bilibili-API-collect/assets/sports-bfc825f3.svg'),
- ('运动', '足球', 'football', 249,'https://socialsisteryi.github.io/bilibili-API-collect/assets/sports-bfc825f3.svg'),
- ('运动', '健身', 'aerobics', 164,'https://socialsisteryi.github.io/bilibili-API-collect/assets/sports-bfc825f3.svg'),
- ('运动', '竞技体育', 'athletic', 236,'https://socialsisteryi.github.io/bilibili-API-collect/assets/sports-bfc825f3.svg'),
- ('运动', '运动文化', 'culture', 237,'https://socialsisteryi.github.io/bilibili-API-collect/assets/sports-bfc825f3.svg'),
- ('运动', '运动综合', 'comprehensive', 238,'https://socialsisteryi.github.io/bilibili-API-collect/assets/sports-bfc825f3.svg'),
-
-
- ('汽车', '汽车', 'car', 223,'https://socialsisteryi.github.io/bilibili-API-collect/assets/car-c766485c.svg'),
- ('汽车', '汽车知识科普', 'knowledge', 258,'https://socialsisteryi.github.io/bilibili-API-collect/assets/car-c766485c.svg'),
- ('汽车', '赛车', 'racing', 245,'https://socialsisteryi.github.io/bilibili-API-collect/assets/car-c766485c.svg'),
- ('汽车', '改装玩车', 'modifiedvehicle', 246,'https://socialsisteryi.github.io/bilibili-API-collect/assets/car-c766485c.svg'),
- ('汽车', '新能源汽车', 'newenergyvehicle', 247,'https://socialsisteryi.github.io/bilibili-API-collect/assets/car-c766485c.svg'),
- ('汽车', '房车', 'touringcar', 248,'https://socialsisteryi.github.io/bilibili-API-collect/assets/car-c766485c.svg'),
- ('汽车', '摩托车', 'motorcycle', 240,'https://socialsisteryi.github.io/bilibili-API-collect/assets/car-c766485c.svg'),
- ('汽车', '购车攻略', 'strategy', 227,'https://socialsisteryi.github.io/bilibili-API-collect/assets/car-c766485c.svg'),
- ('汽车', '汽车生活', 'life', 176,'https://socialsisteryi.github.io/bilibili-API-collect/assets/car-c766485c.svg'),
-
-
- ('生活', '生活', 'life', 160,'https://socialsisteryi.github.io/bilibili-API-collect/assets/life-1f4a6ef5.svg'),
- ('生活', '搞笑', 'funny', 138,'https://socialsisteryi.github.io/bilibili-API-collect/assets/life-1f4a6ef5.svg'),
- ('生活', '出行', 'travel', 250,'https://socialsisteryi.github.io/bilibili-API-collect/assets/life-1f4a6ef5.svg'),
- ('生活', '三农', 'rurallife', 251,'https://socialsisteryi.github.io/bilibili-API-collect/assets/life-1f4a6ef5.svg'),
- ('生活', '家居房产', 'home', 239,'https://socialsisteryi.github.io/bilibili-API-collect/assets/life-1f4a6ef5.svg'),
- ('生活', '手工', 'handmake', 161,'https://socialsisteryi.github.io/bilibili-API-collect/assets/life-1f4a6ef5.svg'),
- ('生活', '绘画', 'painting', 162,'https://socialsisteryi.github.io/bilibili-API-collect/assets/life-1f4a6ef5.svg'),
- ('生活', '日常', 'daily', 21,'https://socialsisteryi.github.io/bilibili-API-collect/assets/life-1f4a6ef5.svg'),
- ('生活', '亲子', 'parenting', 254,'https://socialsisteryi.github.io/bilibili-API-collect/assets/life-1f4a6ef5.svg'),
-
-
- ('美食', '美食', 'food', 211,'https://socialsisteryi.github.io/bilibili-API-collect/assets/food-5883d8d8.svg'),
- ('美食', '美食制作', 'make', 76,'https://socialsisteryi.github.io/bilibili-API-collect/assets/food-5883d8d8.svg'),
- ('美食', '美食侦探', 'detective', 212,'https://socialsisteryi.github.io/bilibili-API-collect/assets/food-5883d8d8.svg'),
- ('美食', '美食测评', 'measurement', 213,'https://socialsisteryi.github.io/bilibili-API-collect/assets/food-5883d8d8.svg'),
- ('美食', '田园美食', 'rural', 214,'https://socialsisteryi.github.io/bilibili-API-collect/assets/food-5883d8d8.svg'),
- ('美食', '美食记录', 'record', 215,'https://socialsisteryi.github.io/bilibili-API-collect/assets/food-5883d8d8.svg'),
-
-
- ('动物圈', '动物圈', 'animal', 217,'https://socialsisteryi.github.io/bilibili-API-collect/assets/animal-95ff87f2.svg'),
- ('动物圈', '喵星人', 'cat', 218,'https://socialsisteryi.github.io/bilibili-API-collect/assets/animal-95ff87f2.svg'),
- ('动物圈', '汪星人', 'dog', 219,'https://socialsisteryi.github.io/bilibili-API-collect/assets/animal-95ff87f2.svg'),
- ('动物圈', '动物二创', 'second_edition', 220,'https://socialsisteryi.github.io/bilibili-API-collect/assets/animal-95ff87f2.svg'),
- ('动物圈', '野生动物', 'wild_animal', 221,'https://socialsisteryi.github.io/bilibili-API-collect/assets/animal-95ff87f2.svg'),
- ('动物圈', '小宠异宠', 'reptiles', 222,'https://socialsisteryi.github.io/bilibili-API-collect/assets/animal-95ff87f2.svg'),
- ('动物圈', '动物综合', 'animal_composite', 75,'https://socialsisteryi.github.io/bilibili-API-collect/assets/animal-95ff87f2.svg'),
-
-
- ('鬼畜', '鬼畜', 'kichiku', 119,'https://socialsisteryi.github.io/bilibili-API-collect/assets/kichiku-8f960ae2.svg'),
- ('鬼畜', '鬼畜调教', 'guide', 22,'https://socialsisteryi.github.io/bilibili-API-collect/assets/kichiku-8f960ae2.svg'),
- ('鬼畜', '音MAD', 'mad', 26,'https://socialsisteryi.github.io/bilibili-API-collect/assets/kichiku-8f960ae2.svg'),
- ('鬼畜', '人力VOCALOID', 'manual_vocaloid', 126,'https://socialsisteryi.github.io/bilibili-API-collect/assets/kichiku-8f960ae2.svg'),
- ('鬼畜', '鬼畜剧场', 'theatre', 216,'https://socialsisteryi.github.io/bilibili-API-collect/assets/kichiku-8f960ae2.svg'),
- ('鬼畜', '教程演示', 'course', 127,'https://socialsisteryi.github.io/bilibili-API-collect/assets/kichiku-8f960ae2.svg'),
-
-
- ('时尚', '时尚', 'fashion', 155,'https://socialsisteryi.github.io/bilibili-API-collect/assets/fashion-773241bb.svg'),
- ('时尚', '美妆护肤', 'makeup', 157,'https://socialsisteryi.github.io/bilibili-API-collect/assets/fashion-773241bb.svg'),
- ('时尚', '仿妆cos', 'cos', 252,'https://socialsisteryi.github.io/bilibili-API-collect/assets/fashion-773241bb.svg'),
- ('时尚', '穿搭', 'clothing', 158,'https://socialsisteryi.github.io/bilibili-API-collect/assets/fashion-773241bb.svg'),
- ('时尚', '时尚潮流', 'catwalk', 159,'https://socialsisteryi.github.io/bilibili-API-collect/assets/fashion-773241bb.svg'),
-
-
- ('资讯', '资讯', 'information', 202,'https://socialsisteryi.github.io/bilibili-API-collect/assets/information-d98c5ed0.svg'),
- ('资讯', '热点', 'hotspot', 203,'https://socialsisteryi.github.io/bilibili-API-collect/assets/information-d98c5ed0.svg'),
- ('资讯', '环球', 'global', 204,'https://socialsisteryi.github.io/bilibili-API-collect/assets/information-d98c5ed0.svg'),
- ('资讯', '社会', 'social', 205,'https://socialsisteryi.github.io/bilibili-API-collect/assets/information-d98c5ed0.svg'),
- ('资讯', '综合', 'multiple', 206,'https://socialsisteryi.github.io/bilibili-API-collect/assets/information-d98c5ed0.svg'),
-
-
- ('娱乐', '娱乐', 'ent', 5,'https://socialsisteryi.github.io/bilibili-API-collect/assets/ent-ed6247e0.svg'),
- ('娱乐', '综艺', 'variety', 71,'https://socialsisteryi.github.io/bilibili-API-collect/assets/ent-ed6247e0.svg'),
- ('娱乐', '娱乐杂谈', 'talker', 241,'https://socialsisteryi.github.io/bilibili-API-collect/assets/ent-ed6247e0.svg'),
- ('娱乐', '粉丝创作', 'fans', 242,'https://socialsisteryi.github.io/bilibili-API-collect/assets/ent-ed6247e0.svg'),
- ('娱乐', '明星综合', 'celebrity', 137,'https://socialsisteryi.github.io/bilibili-API-collect/assets/ent-ed6247e0.svg'),
-
-
- ('影视', '影视', 'cinephile', 181,'https://socialsisteryi.github.io/bilibili-API-collect/assets/cinephile-c8d74b94.svg'),
- ('影视', '影视杂谈', 'cinecism', 182,'https://socialsisteryi.github.io/bilibili-API-collect/assets/cinephile-c8d74b94.svg'),
- ('影视', '影视剪辑', 'montage', 183,'https://socialsisteryi.github.io/bilibili-API-collect/assets/cinephile-c8d74b94.svg'),
- ('影视', '小剧场', 'shortfilm', 85,'https://socialsisteryi.github.io/bilibili-API-collect/assets/cinephile-c8d74b94.svg'),
- ('影视', '预告·资讯', 'trailer_info', 184,'https://socialsisteryi.github.io/bilibili-API-collect/assets/cinephile-c8d74b94.svg'),
- ('影视', '短片', 'shortfilm', 256,'https://socialsisteryi.github.io/bilibili-API-collect/assets/cinephile-c8d74b94.svg'),
-
-
- ('纪录片', '纪录片', 'documentary', 177,'https://socialsisteryi.github.io/bilibili-API-collect/assets/documentary-2c550e67.svg'),
- ('纪录片', '人文·历史', 'history', 37,'https://socialsisteryi.github.io/bilibili-API-collect/assets/documentary-2c550e67.svg'),
- ('纪录片', '科学·探索·自然', 'science', 178,'https://socialsisteryi.github.io/bilibili-API-collect/assets/documentary-2c550e67.svg'),
- ('纪录片', '军事', 'military', 179,'https://socialsisteryi.github.io/bilibili-API-collect/assets/documentary-2c550e67.svg'),
- ('纪录片', '社会·美食·旅行', 'travel', 180,'https://socialsisteryi.github.io/bilibili-API-collect/assets/documentary-2c550e67.svg'),
-
-
- ('电影', '电影', 'movie', 23,'https://socialsisteryi.github.io/bilibili-API-collect/assets/movie-693cc994.svg'),
- ('电影', '华语电影', 'chinese', 147,'https://socialsisteryi.github.io/bilibili-API-collect/assets/movie-693cc994.svg'),
- ('电影', '欧美电影', 'west', 145,'https://socialsisteryi.github.io/bilibili-API-collect/assets/movie-693cc994.svg'),
- ('电影', '日本电影', 'japan', 146,'https://socialsisteryi.github.io/bilibili-API-collect/assets/movie-693cc994.svg'),
- ('电影', '其他国家', 'movie', 83,'https://socialsisteryi.github.io/bilibili-API-collect/assets/movie-693cc994.svg'),
-
-
- ('电视剧', '电视剧', 'tv', 11,'https://socialsisteryi.github.io/bilibili-API-collect/assets/teleplay-1f3272a8.svg'),
- ('电视剧', '国产剧', 'mainland', 185,'https://socialsisteryi.github.io/bilibili-API-collect/assets/teleplay-1f3272a8.svg'),
- ('电视剧', '海外剧', 'overseas', 187,'https://socialsisteryi.github.io/bilibili-API-collect/assets/teleplay-1f3272a8.svg'),
-
- ]
-
- # 先清空表
- cursor.execute('DELETE FROM video_categories')
-
- # 插入所有数据
- cursor.executemany('''
- INSERT INTO video_categories (main_category, sub_category, alias, tid, image)
- VALUES (?, ?, ?, ?, ?)
- ''', categories_data)
-
- conn.commit()
- print("视频分类表初始化成功!")
-
- except sqlite3.Error as e:
- print(f"数据库错误: {e}")
- conn.rollback()
- finally:
- conn.close()
-
-if __name__ == '__main__':
- init_categories()
\ No newline at end of file
diff --git a/scripts/popular_videos.py b/scripts/popular_videos.py
deleted file mode 100644
index c3b311c..0000000
--- a/scripts/popular_videos.py
+++ /dev/null
@@ -1,1303 +0,0 @@
-#!/usr/bin/env python
-# -*- coding: utf-8 -*-
-"""
-bilibili_popular_videos.py - 获取B站热门视频列表
-
-该脚本用于获取哔哩哔哩当前热门视频列表,使用了WBI签名验证
-可以作为API接口导入到其他模块中使用
-"""
-
-import json
-import os
-import time
-import random
-import sqlite3
-from datetime import datetime
-from typing import Dict, Any, List, Optional, Tuple
-
-import requests
-
-from scripts.wbi_sign import get_wbi_sign
-from scripts.utils import get_output_path, get_database_path
-
-# API 地址
-POPULAR_API = "https://api.bilibili.com/x/web-interface/popular"
-
-def get_db_connection(year=None):
- """
- 获取数据库连接,支持按年切分数据库
-
- Args:
- year: 指定年份,如果为None则使用当前年份
-
- Returns:
- SQLite数据库连接
- """
- # 如果未指定年份,使用当前年份
- if year is None:
- year = datetime.now().year
-
- # 构建基于年份的数据库路径
- db_filename = f"bilibili_popular_{year}.db"
- db_path = get_database_path(db_filename)
- conn = sqlite3.connect(db_path)
-
- # 创建表
- create_tables(conn)
-
- print(f"已连接到{year}年的数据库: {db_path}")
- return conn
-
-# 获取当前年份的数据库连接
-def get_current_db_connection():
- """获取当前年份的数据库连接"""
- current_year = datetime.now().year
- return get_db_connection(current_year)
-
-# 获取所有年份的数据库列表
-def get_all_year_dbs():
- """获取所有年份的数据库列表"""
- db_dir = os.path.dirname(get_database_path(""))
- db_files = [f for f in os.listdir(db_dir) if f.startswith("bilibili_popular_") and f.endswith(".db")]
- years = []
-
- for db_file in db_files:
- try:
- year = int(db_file.replace("bilibili_popular_", "").replace(".db", ""))
- years.append(year)
- except ValueError:
- continue
-
- return sorted(years)
-
-# 获取多年数据库连接
-def get_multi_year_connections(start_year=None, end_year=None):
- """获取多年数据库连接"""
- if start_year is None or end_year is None:
- years = get_all_year_dbs()
- if not years:
- # 如果没有找到数据库,返回当前年份
- return {datetime.now().year: get_current_db_connection()}
- else:
- years = range(start_year, end_year + 1)
-
- connections = {}
- for year in years:
- try:
- connections[year] = get_db_connection(year)
- except Exception as e:
- print(f"连接{year}年数据库出错: {e}")
-
- return connections
-
-def create_tables(conn):
- """创建数据库表"""
- cursor = conn.cursor()
-
- # 创建热门视频表
- cursor.execute('''
- CREATE TABLE IF NOT EXISTS popular_videos (
- id INTEGER PRIMARY KEY AUTOINCREMENT,
- aid TEXT,
- bvid TEXT,
- title TEXT,
- pubdate INTEGER,
- ctime INTEGER,
- desc TEXT,
- videos INTEGER,
- tid INTEGER,
- tname TEXT,
- copyright INTEGER,
- pic TEXT,
- duration INTEGER,
- owner_mid INTEGER,
- owner_name TEXT,
- owner_face TEXT,
- view_count INTEGER,
- danmaku_count INTEGER,
- reply_count INTEGER,
- favorite_count INTEGER,
- coin_count INTEGER,
- share_count INTEGER,
- like_count INTEGER,
- dynamic TEXT,
- cid TEXT,
-
- /* 展开dimension字段 */
- dimension_width INTEGER,
- dimension_height INTEGER,
- dimension_rotate INTEGER,
-
- short_link TEXT,
- first_frame TEXT,
- pub_location TEXT,
- cover43 TEXT,
- tidv2 INTEGER,
- tnamev2 TEXT,
- pid_v2 INTEGER,
- pid_name_v2 TEXT,
- season_type INTEGER,
- is_ogv INTEGER,
-
- /* 展开rights字段 */
- rights_bp INTEGER,
- rights_elec INTEGER,
- rights_download INTEGER,
- rights_movie INTEGER,
- rights_pay INTEGER,
- rights_hd5 INTEGER,
- rights_no_reprint INTEGER,
- rights_autoplay INTEGER,
- rights_ugc_pay INTEGER,
- rights_is_cooperation INTEGER,
- rights_ugc_pay_preview INTEGER,
- rights_no_background INTEGER,
- rights_arc_pay INTEGER,
- rights_pay_free_watch INTEGER,
-
- /* 展开stat字段 */
- stat_view INTEGER,
- stat_danmaku INTEGER,
- stat_reply INTEGER,
- stat_favorite INTEGER,
- stat_coin INTEGER,
- stat_share INTEGER,
- stat_now_rank INTEGER,
- stat_his_rank INTEGER,
- stat_like INTEGER,
- stat_dislike INTEGER,
- stat_vv INTEGER,
- stat_fav_g INTEGER,
- stat_like_g INTEGER,
-
- /* 展开rcmd_reason字段 */
- rcmd_reason_content TEXT,
- rcmd_reason_corner_mark INTEGER,
-
- ogv_info TEXT,
- ai_rcmd TEXT,
- fetch_time INTEGER,
- UNIQUE(aid, bvid, fetch_time)
- )
- ''')
-
- # 创建抓取记录表
- cursor.execute('''
- CREATE TABLE IF NOT EXISTS fetch_records (
- id INTEGER PRIMARY KEY AUTOINCREMENT,
- fetch_time INTEGER,
- total_fetched INTEGER,
- pages_fetched INTEGER,
- success INTEGER,
- failed_to_save INTEGER DEFAULT 0,
- duplicates_skipped INTEGER DEFAULT 0
- )
- ''')
-
- # 创建视频热门跟踪表
- cursor.execute('''
- CREATE TABLE IF NOT EXISTS popular_video_tracking (
- id INTEGER PRIMARY KEY AUTOINCREMENT,
- aid TEXT,
- bvid TEXT,
- title TEXT,
- first_seen INTEGER, -- 首次出现时间
- last_seen INTEGER, -- 最后一次出现时间
- is_active INTEGER, -- 是否仍在热门列表
- total_duration INTEGER, -- 累计在热门列表的时间(秒)
- highest_rank INTEGER, -- 历史最高排名
- lowest_rank INTEGER, -- 历史最低排名
- appearances INTEGER DEFAULT 1, -- 出现次数
- UNIQUE(aid, bvid)
- )
- ''')
-
- conn.commit()
-
-def insert_video_to_db(conn, video: Dict[str, Any], fetch_time: int, rank: int = 0, auto_commit: bool = False):
- """
- 将视频信息插入数据库
-
- Args:
- conn: 数据库连接
- video: 视频数据
- fetch_time: 抓取时间戳
- rank: 视频排名
- auto_commit: 是否自动提交事务,默认为False,用于批量插入时由外部控制事务
- """
- cursor = conn.cursor()
-
- # 提取嵌套数据
- owner = video.get('owner', {})
- stat = video.get('stat', {})
- dimension = video.get('dimension', {})
- rcmd_reason = video.get('rcmd_reason', {})
- rights = video.get('rights', {})
-
- try:
- # 插入到主视频表
- # 计算参数数量
- values = (
- video.get('aid'),
- video.get('bvid'),
- video.get('title'),
- video.get('pubdate'),
- video.get('ctime'),
- video.get('desc'),
- video.get('videos'),
- video.get('tid'),
- video.get('tname'),
- video.get('copyright'),
- video.get('pic'),
- video.get('duration'),
- owner.get('mid'),
- owner.get('name'),
- owner.get('face'),
- stat.get('view'),
- stat.get('danmaku'),
- stat.get('reply'),
- stat.get('favorite'),
- stat.get('coin'),
- stat.get('share'),
- stat.get('like'),
- video.get('dynamic'),
- video.get('cid'),
- # dimension字段展开
- dimension.get('width'),
- dimension.get('height'),
- dimension.get('rotate'),
- video.get('short_link_v2'), # 使用short_link_v2作为short_link列的值
- video.get('first_frame'),
- video.get('pub_location'),
- video.get('cover43'),
- video.get('tidv2'),
- video.get('tnamev2'),
- video.get('pid_v2'),
- video.get('pid_name_v2'),
- video.get('season_type'),
- 1 if video.get('is_ogv') else 0,
- # rights字段展开
- rights.get('bp'),
- rights.get('elec'),
- rights.get('download'),
- rights.get('movie'),
- rights.get('pay'),
- rights.get('hd5'),
- rights.get('no_reprint'),
- rights.get('autoplay'),
- rights.get('ugc_pay'),
- rights.get('is_cooperation'),
- rights.get('ugc_pay_preview'),
- rights.get('no_background'),
- rights.get('arc_pay'),
- rights.get('pay_free_watch'),
- # stat字段展开
- stat.get('view'),
- stat.get('danmaku'),
- stat.get('reply'),
- stat.get('favorite'),
- stat.get('coin'),
- stat.get('share'),
- stat.get('now_rank'),
- stat.get('his_rank'),
- stat.get('like'),
- stat.get('dislike'),
- stat.get('vv'),
- stat.get('fav_g'),
- stat.get('like_g'),
- # rcmd_reason字段展开
- rcmd_reason.get('content'),
- rcmd_reason.get('corner_mark'),
- # 其他字段
- json.dumps(video.get('ogv_info', {}), ensure_ascii=False) if video.get('ogv_info') else None,
- json.dumps(video.get('ai_rcmd', {}), ensure_ascii=False) if video.get('ai_rcmd') else None,
- fetch_time
- )
-
- cursor.execute('''
- INSERT OR REPLACE INTO popular_videos (
- aid, bvid, title, pubdate, ctime, desc, videos, tid, tname, copyright,
- pic, duration, owner_mid, owner_name, owner_face, view_count, danmaku_count,
- reply_count, favorite_count, coin_count, share_count, like_count, dynamic,
- cid,
- dimension_width, dimension_height, dimension_rotate,
- short_link, first_frame, pub_location, cover43, tidv2,
- tnamev2, pid_v2, pid_name_v2, season_type, is_ogv,
- rights_bp, rights_elec, rights_download, rights_movie, rights_pay,
- rights_hd5, rights_no_reprint, rights_autoplay, rights_ugc_pay,
- rights_is_cooperation, rights_ugc_pay_preview, rights_no_background,
- rights_arc_pay, rights_pay_free_watch,
- stat_view, stat_danmaku, stat_reply, stat_favorite, stat_coin,
- stat_share, stat_now_rank, stat_his_rank, stat_like, stat_dislike,
- stat_vv, stat_fav_g, stat_like_g,
- rcmd_reason_content, rcmd_reason_corner_mark,
- ogv_info, ai_rcmd, fetch_time
- ) VALUES ({})
- '''.format(', '.join(['?'] * len(values))), values)
-
- # 更新跟踪表
- update_tracking_info(conn, video, fetch_time, rank)
-
- # 只有在auto_commit为True时才提交事务
- if auto_commit:
- conn.commit()
-
- except sqlite3.Error as e:
- print(f"插入数据库时出错: {e}")
- # 如果auto_commit为True,则回滚操作
- if auto_commit:
- conn.rollback()
- raise
-
-def update_tracking_info(conn, video: Dict[str, Any], fetch_time: int, rank: int = 0, auto_commit: bool = False):
- """
- 更新视频热门跟踪信息
-
- Args:
- conn: 数据库连接
- video: 视频数据
- fetch_time: 抓取时间戳
- rank: 视频排名
- auto_commit: 是否自动提交事务,默认为False,用于批量插入时由外部控制事务
- """
- cursor = conn.cursor()
-
- aid = video.get('aid')
- bvid = video.get('bvid')
- title = video.get('title')
-
- try:
- # 检查视频是否已存在于跟踪表中
- cursor.execute(
- "SELECT first_seen, last_seen, is_active, highest_rank, lowest_rank, appearances FROM popular_video_tracking WHERE aid = ? AND bvid = ?",
- (aid, bvid)
- )
- result = cursor.fetchone()
-
- if result:
- # 视频已存在,更新信息
- first_seen, last_seen, is_active, highest_rank, lowest_rank, appearances = result
-
- # 更新最后一次出现时间、出现次数和活跃状态
- if last_seen < fetch_time:
- cursor.execute(
- "UPDATE popular_video_tracking SET last_seen = ?, is_active = 1, appearances = appearances + 1 WHERE aid = ? AND bvid = ?",
- (fetch_time, aid, bvid)
- )
-
- # 更新排名记录
- if rank > 0:
- if highest_rank is None or rank < highest_rank:
- cursor.execute(
- "UPDATE popular_video_tracking SET highest_rank = ? WHERE aid = ? AND bvid = ?",
- (rank, aid, bvid)
- )
- if lowest_rank is None or rank > lowest_rank:
- cursor.execute(
- "UPDATE popular_video_tracking SET lowest_rank = ? WHERE aid = ? AND bvid = ?",
- (rank, aid, bvid)
- )
- else:
- # 新视频,插入记录
- cursor.execute('''
- INSERT INTO popular_video_tracking (
- aid, bvid, title, first_seen, last_seen, is_active,
- total_duration, highest_rank, lowest_rank, appearances
- ) VALUES (?, ?, ?, ?, ?, ?, ?, ?, ?, ?)
- ''', (
- aid, bvid, title, fetch_time, fetch_time, 1,
- 0, rank if rank > 0 else None, rank if rank > 0 else None, 1
- ))
-
- # 只有在auto_commit为True时才提交事务
- if auto_commit:
- conn.commit()
-
- except sqlite3.Error as e:
- print(f"更新跟踪信息时出错: {e}")
- # 如果auto_commit为True,则回滚操作
- if auto_commit:
- conn.rollback()
- raise
-
-def update_inactive_videos(conn, fetch_time: int):
- """
- 更新不再在热门列表中的视频状态
-
- Args:
- conn: 数据库连接
- fetch_time: 当前抓取时间戳
- """
- cursor = conn.cursor()
-
- try:
- # 查找所有活跃但在当前抓取中未出现的视频
- cursor.execute('''
- SELECT aid, bvid, last_seen FROM popular_video_tracking
- WHERE is_active = 1 AND last_seen < ?
- ''', (fetch_time,))
-
- inactive_videos = cursor.fetchall()
-
- # 更新这些视频的状态
- for aid, bvid, last_seen in inactive_videos:
- total_duration = fetch_time - last_seen
-
- cursor.execute('''
- UPDATE popular_video_tracking
- SET is_active = 0, total_duration = total_duration + ?
- WHERE aid = ? AND bvid = ?
- ''', (total_duration, aid, bvid))
-
- return len(inactive_videos)
- except sqlite3.Error as e:
- print(f"更新非活跃视频时出错: {e}")
- return 0
-
-def save_fetch_record(conn, fetch_time: int, total_fetched: int, pages_fetched: int, success: bool, failed: int = 0, duplicates: int = 0):
- """
- 保存抓取记录
-
- Args:
- conn: 数据库连接
- fetch_time: 抓取时间戳
- total_fetched: 总共抓取的视频数
- pages_fetched: 抓取的页数
- success: 是否成功
- failed: 保存失败的数量
- duplicates: 重复跳过的数量
- """
- cursor = conn.cursor()
-
- try:
- cursor.execute('''
- INSERT INTO fetch_records (fetch_time, total_fetched, pages_fetched, success, failed_to_save, duplicates_skipped)
- VALUES (?, ?, ?, ?, ?, ?)
- ''', (
- fetch_time,
- total_fetched,
- pages_fetched,
- 1 if success else 0,
- failed,
- duplicates
- ))
- conn.commit()
- except sqlite3.Error as e:
- print(f"保存抓取记录时出错: {e}")
- conn.rollback()
-
-def get_popular_videos(page_num: int = 1, page_size: int = 20) -> Dict[str, Any]:
- """
- 获取B站当前热门视频列表
-
- Args:
- page_num: 页码,默认为1
- page_size: 每页视频数量,默认为20
-
- Returns:
- Dict[str, Any]: 热门视频列表数据
- """
- # 基础参数
- params = {
- "ps": page_size,
- "pn": page_num,
- "web_location": "333.934" # 网页位置参数
- }
-
- # 添加 WBI 签名
- signed_params = get_wbi_sign(params)
-
- # 请求头
- headers = {
- "User-Agent": "Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/91.0.4472.124 Safari/537.36",
- "Referer": "https://www.bilibili.com/",
- "Accept": "application/json, text/plain, */*",
- "Accept-Language": "zh-CN,zh;q=0.9,en;q=0.8",
- "Origin": "https://www.bilibili.com"
- }
-
- try:
- # 发送请求
- response = requests.get(
- POPULAR_API,
- params=signed_params,
- headers=headers,
- timeout=30
- )
- response.raise_for_status()
-
- # 解析响应数据
- data = response.json()
-
- return data
- except requests.RequestException as e:
- print(f"网络请求失败: {e}")
- return {"code": -1, "message": f"网络请求失败: {e}", "ttl": 0, "data": None}
- except json.JSONDecodeError as e:
- print(f"解析JSON数据失败: {e}")
- return {"code": -1, "message": f"解析JSON数据失败: {e}", "ttl": 0, "data": None}
- except Exception as e:
- print(f"获取热门视频列表失败: {e}")
- return {"code": -1, "message": f"获取热门视频列表失败: {e}", "ttl": 0, "data": None}
-
-def get_all_popular_videos(
- page_size: int = 20,
- max_pages: int = 100,
- save_to_db: bool = True,
- progress_callback = None
-) -> Tuple[List[Dict[str, Any]], bool, Dict[str, Any]]:
- """
- 获取B站所有热门视频,直到没有更多数据为止
-
- Args:
- page_size: 每页视频数量,默认为20
- max_pages: 最大获取页数,防止无限循环,默认为100
- save_to_db: 是否保存到数据库,默认为True
- progress_callback: 进度回调函数,可选。接受当前进度(百分比)、状态消息、当前页码和总页数作为参数
-
- Returns:
- Tuple[List[Dict[str, Any]], bool, Dict[str, Any]]:
- - 所有热门视频列表
- - 是否成功获取完所有数据
- - 抓取统计信息
- """
- all_videos = []
- total_items = 0
- page_num = 1
- has_more = True
- conn = None
- fetch_time = int(time.time())
- failed_count = 0
- duplicate_count = 0
- inactive_count = 0
- # 用于收集所有要保存的视频数据
- videos_to_save = []
-
- try:
- # 如果需要保存到数据库,建立连接
- if save_to_db:
- conn = get_current_db_connection()
-
- while has_more and page_num <= max_pages:
- print(f"正在获取第 {page_num} 页数据...")
-
- # 报告进度(如果提供了回调函数)
- estimated_progress = min(95, int((page_num / max_pages) * 100))
- if progress_callback:
- progress_callback(
- estimated_progress,
- f"正在获取第 {page_num} 页数据...",
- page_num,
- max_pages
- )
-
- # 随机延迟,模拟人类行为
- delay = random.uniform(3.0, 7.0)
- print(f"等待 {delay:.2f} 秒...")
- time.sleep(delay)
-
- # 获取当前页数据
- data = get_popular_videos(page_num=page_num, page_size=page_size)
-
- # 检查是否成功
- if data["code"] != 0 or not data.get("data"):
- print(f"获取第 {page_num} 页数据失败: {data.get('message', '未知错误')}")
-
- # 报告错误(如果提供了回调函数)
- if progress_callback:
- progress_callback(
- estimated_progress,
- f"获取第 {page_num} 页数据失败: {data.get('message', '未知错误')}",
- page_num,
- max_pages,
- success=False
- )
-
- # 保存抓取记录
- if save_to_db and conn:
- save_fetch_record(conn, fetch_time, len(all_videos), page_num - 1, False, failed_count, duplicate_count)
-
- fetch_stats = {
- "status": "error",
- "message": data.get('message', '未知错误'),
- "pages_fetched": page_num - 1,
- "total_items": total_items,
- "saved_successfully": len(all_videos),
- "failed_to_save": failed_count,
- "duplicates_skipped": duplicate_count,
- "fetch_time": datetime.fromtimestamp(fetch_time).strftime("%Y-%m-%d %H:%M:%S")
- }
-
- return all_videos, False, fetch_stats
-
- # 提取视频列表
- video_list = data["data"].get("list", [])
- if video_list:
- total_items += len(video_list)
-
- # 收集视频数据,但不立即写入数据库
- if save_to_db:
- for index, video in enumerate(video_list):
- # 计算当前视频的排名
- rank = (page_num - 1) * page_size + index + 1
- # 将视频和排名信息添加到待保存列表
- videos_to_save.append((video, rank))
-
- # 提取视频信息并添加到总列表中
- videos = extract_video_info(data)
- all_videos.extend(videos)
-
- # 输出当前获取进度
- print(f"已获取 {len(all_videos)} 个视频")
-
- # 报告进度(如果提供了回调函数)
- if progress_callback:
- progress_callback(
- estimated_progress,
- f"已获取 {len(all_videos)} 个视频",
- page_num,
- max_pages
- )
-
- # 检查是否还有更多数据
- has_more = not data.get("data", {}).get("no_more", True)
-
- # 准备获取下一页
- if has_more:
- page_num += 1
- else:
- print("已获取全部热门视频数据")
-
- # 报告进度(如果提供了回调函数)
- if progress_callback:
- progress_callback(
- 95,
- "已获取全部热门视频数据,正在处理...",
- page_num,
- page_num
- )
-
- # 一次性批量保存所有视频数据到数据库
- if save_to_db and conn and videos_to_save:
- print(f"开始一次性保存 {len(videos_to_save)} 个视频到数据库...")
-
- # 报告进度(如果提供了回调函数)
- if progress_callback:
- progress_callback(
- 96,
- f"正在保存 {len(videos_to_save)} 个视频到数据库...",
- page_num,
- page_num
- )
-
- # 开始事务
- conn.execute("BEGIN TRANSACTION")
-
- try:
- cursor = conn.cursor()
- for video, rank in videos_to_save:
- try:
- # 检查是否已存在相同视频记录
- cursor.execute(
- "SELECT 1 FROM popular_videos WHERE aid = ? AND bvid = ? AND fetch_time = ?",
- (video.get('aid'), video.get('bvid'), fetch_time)
- )
- exists = cursor.fetchone() is not None
-
- if exists:
- duplicate_count += 1
- print(f"跳过重复视频: {video.get('bvid')} - {video.get('title')}")
- else:
- # 插入视频数据,不自动提交事务
- insert_video_to_db(conn, video, fetch_time, rank, auto_commit=False)
- except Exception as e:
- failed_count += 1
- print(f"保存视频 {video.get('bvid')} 时出错: {e}")
-
- # 提交事务
- conn.execute("COMMIT")
- print(f"成功保存 {len(videos_to_save) - failed_count - duplicate_count} 个视频到数据库")
-
- except Exception as e:
- # 回滚事务
- conn.execute("ROLLBACK")
- print(f"批量保存视频时出错,已回滚: {e}")
- failed_count = len(videos_to_save)
-
- # 报告进度(如果提供了回调函数)
- if progress_callback:
- progress_callback(
- 97,
- f"已保存 {len(videos_to_save) - failed_count - duplicate_count} 个视频到数据库",
- page_num,
- page_num
- )
-
- # 更新不再活跃的视频
- if save_to_db and conn:
- inactive_count = update_inactive_videos(conn, fetch_time)
- print(f"已更新 {inactive_count} 个不再活跃的视频")
-
- # 报告进度(如果提供了回调函数)
- if progress_callback:
- progress_callback(
- 98,
- f"已更新 {inactive_count} 个不再活跃的视频",
- max_pages,
- max_pages
- )
-
- # 保存抓取记录
- if save_to_db and conn:
- save_fetch_record(conn, fetch_time, len(all_videos), page_num - 1, True, failed_count, duplicate_count)
-
- fetch_stats = {
- "status": "success",
- "total_videos": len(all_videos),
- "fetch_stats": {
- "pages_fetched": page_num - 1,
- "total_items": total_items,
- "saved_successfully": len(all_videos) - failed_count - duplicate_count,
- "failed_to_save": failed_count,
- "duplicates_skipped": duplicate_count,
- "inactive_updated": inactive_count,
- "fetch_time": datetime.fromtimestamp(fetch_time).strftime("%Y-%m-%d %H:%M:%S")
- }
- }
-
- # 报告完成(如果提供了回调函数)
- if progress_callback:
- progress_callback(
- 100,
- "热门视频获取完成",
- max_pages,
- max_pages,
- success=True
- )
-
- return all_videos, True, fetch_stats
-
- except Exception as e:
- print(f"获取所有热门视频时出错: {e}")
-
- # 报告错误(如果提供了回调函数)
- if progress_callback:
- progress_callback(
- min(95, int((page_num / max_pages) * 100)),
- f"获取热门视频时出错: {str(e)}",
- page_num,
- max_pages,
- success=False
- )
-
- # 保存抓取记录
- if save_to_db and conn:
- save_fetch_record(conn, fetch_time, len(all_videos), page_num - 1, False, failed_count, duplicate_count)
-
- fetch_stats = {
- "status": "error",
- "message": str(e),
- "pages_fetched": page_num - 1,
- "total_items": total_items,
- "saved_successfully": len(all_videos) - failed_count - duplicate_count,
- "failed_to_save": failed_count,
- "duplicates_skipped": duplicate_count,
- "fetch_time": datetime.fromtimestamp(fetch_time).strftime("%Y-%m-%d %H:%M:%S")
- }
-
- return all_videos, False, fetch_stats
- finally:
- # 关闭数据库连接
- if conn:
- conn.close()
-
-def extract_video_info(data: Dict[str, Any]) -> List[Dict[str, Any]]:
- """
- 从返回的数据中提取视频基本信息
-
- Args:
- data: API返回的数据
-
- Returns:
- List[Dict[str, Any]]: 视频信息列表
- """
- if data["code"] != 0 or not data.get("data") or not data["data"].get("list"):
- return []
-
- videos = []
- for video in data["data"]["list"]:
- videos.append({
- "aid": video.get("aid"),
- "bvid": video.get("bvid"),
- "title": video.get("title"),
- "author": video.get("owner", {}).get("name"),
- "mid": video.get("owner", {}).get("mid"),
- "play": video.get("stat", {}).get("view"),
- "favorite": video.get("stat", {}).get("favorite"),
- "coin": video.get("stat", {}).get("coin"),
- "share": video.get("stat", {}).get("share"),
- "like": video.get("stat", {}).get("like"),
- "duration": video.get("duration"),
- "pubdate": video.get("pubdate"),
- "description": video.get("desc"),
- "tname": video.get("tname"),
- "short_link": video.get("short_link_v2")
- })
-
- return videos
-
-def print_popular_videos(video_list: List[Dict[str, Any]], max_display: int = None) -> None:
- """
- 打印视频信息
-
- Args:
- video_list: 视频信息列表
- max_display: 最大显示数量,默认为None,表示显示所有视频
- """
- if not video_list:
- print("未获取到视频信息")
- return
-
- # 如果指定了最大显示数量,则限制显示
- if max_display is not None and max_display > 0:
- display_list = video_list[:max_display]
- print(f"\n共获取到 {len(video_list)} 个热门视频,显示前 {len(display_list)} 个:")
- else:
- display_list = video_list
- print(f"\n共获取到 {len(video_list)} 个热门视频:")
-
- print("-" * 80)
-
- for i, video in enumerate(display_list, 1):
- try:
- # 格式化时间
- pubdate = time.strftime("%Y-%m-%d %H:%M:%S", time.localtime(video.get("pubdate", 0)))
-
- # 格式化播放量
- play_count = video.get("play", 0)
- if play_count and play_count > 10000:
- play_count = f"{play_count / 10000:.1f}万"
-
- print(f"{i}. {video.get('title')}")
- print(f" UP主: {video.get('author')} (UID: {video.get('mid')})")
- print(f" 播放: {play_count} | 点赞: {video.get('like')} | 投币: {video.get('coin')} | 收藏: {video.get('favorite')}")
- print(f" BV号: {video.get('bvid')} | 分区: {video.get('tname')} | 发布时间: {pubdate}")
- print(f" 链接: {video.get('short_link')}")
- print("-" * 80)
- except Exception as e:
- print(f"打印视频信息时出错: {e}")
- continue
-
-def query_recent_videos(limit: int = 20) -> List[Dict[str, Any]]:
- """
- 从数据库查询最近获取的视频
-
- Args:
- limit: 限制返回的数量
-
- Returns:
- List[Dict[str, Any]]: 视频信息列表
- """
- conn = None
- try:
- conn = get_current_db_connection()
- cursor = conn.cursor()
-
- # 获取最新一次抓取的时间
- cursor.execute('''
- SELECT MAX(fetch_time) FROM fetch_records WHERE success = 1
- ''')
- result = cursor.fetchone()
-
- if not result or not result[0]:
- return []
-
- latest_fetch_time = result[0]
-
- # 查询这次抓取的视频
- cursor.execute('''
- SELECT
- aid, bvid, title, pubdate, owner_mid, owner_name,
- view_count, favorite_count, coin_count, share_count, like_count,
- duration, tname, short_link
- FROM popular_videos
- WHERE fetch_time = ?
- ORDER BY view_count DESC
- LIMIT ?
- ''', (latest_fetch_time, limit))
-
- rows = cursor.fetchall()
-
- videos = []
- for row in rows:
- videos.append({
- "aid": row[0],
- "bvid": row[1],
- "title": row[2],
- "pubdate": row[3],
- "mid": row[4],
- "author": row[5],
- "play": row[6],
- "favorite": row[7],
- "coin": row[8],
- "share": row[9],
- "like": row[10],
- "duration": row[11],
- "tname": row[12],
- "short_link": row[13]
- })
-
- return videos
- except sqlite3.Error as e:
- print(f"查询数据库时出错: {e}")
- return []
- finally:
- if conn:
- conn.close()
-
-def get_fetch_history(limit: int = 10) -> List[Dict[str, Any]]:
- """
- 获取抓取历史记录
-
- Args:
- limit: 限制返回的数量
-
- Returns:
- List[Dict[str, Any]]: 抓取历史列表
- """
- connections = {}
- history = []
-
- try:
- # 获取所有年份的数据库连接
- connections = get_multi_year_connections()
-
- # 从每个年份的数据库中查询抓取历史
- for year, conn in connections.items():
- cursor = conn.cursor()
- cursor.execute('''
- SELECT fetch_time, total_fetched, pages_fetched, success
- FROM fetch_records
- ORDER BY fetch_time DESC
- LIMIT ?
- ''', (limit,))
-
- rows = cursor.fetchall()
- for row in rows:
- fetch_time = row[0]
- history.append({
- "fetch_time": fetch_time,
- "fetch_time_str": datetime.fromtimestamp(fetch_time).strftime("%Y-%m-%d %H:%M:%S"),
- "total_fetched": row[1],
- "pages_fetched": row[2],
- "success": bool(row[3]),
- "year": year
- })
-
- # 按照fetch_time降序排序
- history.sort(key=lambda x: x["fetch_time"], reverse=True)
-
- # 限制返回数量
- return history[:limit]
- except sqlite3.Error as e:
- print(f"查询抓取历史时出错: {e}")
- return []
- finally:
- for conn in connections.values():
- if conn:
- conn.close()
-
-def get_video_tracking_stats(limit: int = 20) -> List[Dict[str, Any]]:
- """
- 获取视频热门跟踪统计,修复重复视频问题
-
- Args:
- limit: 限制返回的数量
-
- Returns:
- List[Dict[str, Any]]: 视频热门统计信息(去重后)
- """
- connections = {}
- stats_dict = {} # 使用字典存储结果,以bvid为键避免重复
-
- try:
- # 获取所有年份的数据库连接
- connections = get_multi_year_connections()
-
- for year, conn in connections.items():
- cursor = conn.cursor()
-
- # 修改查询,使用DISTINCT消除重复,并确保只选择最新的记录
- cursor.execute('''
- WITH RankedVideos AS (
- SELECT
- t.aid, t.bvid, t.title, t.first_seen, t.last_seen,
- t.is_active, t.total_duration, t.highest_rank,
- t.lowest_rank, t.appearances,
- p.owner_name,
- ROW_NUMBER() OVER (PARTITION BY t.bvid ORDER BY t.last_seen DESC) as rn
- FROM popular_video_tracking t
- LEFT JOIN popular_videos p ON t.bvid = p.bvid
- ORDER BY
- CASE WHEN t.is_active = 1 THEN (? - t.first_seen) + t.total_duration
- ELSE t.total_duration END DESC
- )
- SELECT * FROM RankedVideos WHERE rn = 1
- LIMIT ?
- ''', (int(time.time()), limit))
-
- rows = cursor.fetchall()
-
- for row in rows:
- bvid = row[1] # 获取视频bvid
-
- # 如果该视频已经添加过(可能来自其他年份的数据库),则跳过
- if bvid in stats_dict:
- continue
-
- first_seen_date = datetime.fromtimestamp(row[3]).strftime("%Y-%m-%d %H:%M:%S")
- last_seen_date = datetime.fromtimestamp(row[4]).strftime("%Y-%m-%d %H:%M:%S")
-
- # 计算持续时间显示
- total_seconds = row[6]
- if row[5] == 1: # 如果仍然活跃,加上当前时间差
- total_seconds += (int(time.time()) - row[4])
-
- days = total_seconds // (24 * 3600)
- hours = (total_seconds % (24 * 3600)) // 3600
- minutes = (total_seconds % 3600) // 60
- duration_str = ""
- if days > 0:
- duration_str += f"{days}天"
- if hours > 0 or days > 0:
- duration_str += f"{hours}小时"
- duration_str += f"{minutes}分钟"
-
- stats_dict[bvid] = {
- "aid": row[0],
- "bvid": bvid,
- "title": row[2],
- "first_seen": row[3],
- "first_seen_str": first_seen_date,
- "last_seen": row[4],
- "last_seen_str": last_seen_date,
- "is_active": bool(row[5]),
- "total_duration": row[6],
- "duration_str": duration_str,
- "highest_rank": row[7],
- "lowest_rank": row[8],
- "appearances": row[9],
- "author": row[10]
- }
-
- # 将字典值转为列表并排序(按total_duration降序)
- stats = list(stats_dict.values())
- stats.sort(key=lambda x: x["total_duration"], reverse=True)
-
- # 限制返回数量
- return stats[:limit]
-
- except sqlite3.Error as e:
- print(f"查询视频跟踪统计时出错: {e}")
- return []
- finally:
- for conn in connections.values():
- if conn:
- conn.close()
-
-def cleanup_inactive_video_records(year: Optional[int] = None):
- """
- 清理已经不在热门列表的视频数据,只保留首条和末条记录
-
- 此函数执行以下操作:
- 1. 找出所有已经不在热门列表的视频(is_active=0)
- 2. 对每个视频,保留其第一条和最后一条记录
- 3. 删除该视频的所有中间记录
-
- Args:
- year: 指定清理的年份;不传则清理所有年份数据库
-
- Returns:
- dict: 清理统计信息
- """
- connections = {}
- stats = {
- "processed_videos": 0,
- "deleted_records": 0,
- "error_count": 0,
- "year_stats": {}
- }
-
- try:
- # 获取数据库连接(支持按年清理)
- if year is None:
- connections = get_multi_year_connections()
- else:
- db_filename = f"bilibili_popular_{year}.db"
- db_path = get_database_path(db_filename)
- if not os.path.exists(db_path):
- raise FileNotFoundError(f"未找到{year}年的热门视频数据库文件: {db_path}")
- connections = {year: get_db_connection(year)}
-
- for db_year, conn in connections.items():
- year_stats = {
- "processed_videos": 0,
- "deleted_records": 0
- }
-
- cursor = conn.cursor()
- cursor.execute("BEGIN TRANSACTION")
-
- try:
- # 1. 查找所有已经不在热门列表的视频
- cursor.execute("""
- SELECT bvid
- FROM popular_video_tracking
- WHERE is_active = 0
- """)
-
- inactive_videos = [row[0] for row in cursor.fetchall()]
-
- print(f"{db_year}年数据库中找到 {len(inactive_videos)} 个不活跃视频")
-
- for bvid in inactive_videos:
- # 2. 获取该视频的所有记录时间戳,按时间排序
- cursor.execute("""
- SELECT fetch_time
- FROM popular_videos
- WHERE bvid = ?
- ORDER BY fetch_time
- """, (bvid,))
-
- fetch_times = [row[0] for row in cursor.fetchall()]
-
- if len(fetch_times) <= 2:
- # 如果只有两条或更少记录,不需要清理
- continue
-
- # 3. 保留第一条和最后一条记录,删除中间记录
- first_time = fetch_times[0]
- last_time = fetch_times[-1]
-
- # 构建要删除的时间列表(排除首尾)
- times_to_delete = fetch_times[1:-1]
-
- # 将时间列表转换为IN子句可用的格式
- placeholders = ','.join(['?'] * len(times_to_delete))
-
- # 4. 执行删除
- cursor.execute(f"""
- DELETE FROM popular_videos
- WHERE bvid = ? AND fetch_time IN ({placeholders})
- """, [bvid] + times_to_delete)
-
- deleted_count = cursor.rowcount
-
- # 6. 更新统计信息
- year_stats["processed_videos"] += 1
- year_stats["deleted_records"] += deleted_count
-
- # 7. 输出清理信息
- if deleted_count > 0:
- print(f"清理视频 {bvid}: 删除了 {deleted_count} 条记录,保留首条({first_time})和末条({last_time})记录")
-
- # 提交事务
- cursor.execute("COMMIT")
-
- # 更新总统计信息
- stats["processed_videos"] += year_stats["processed_videos"]
- stats["deleted_records"] += year_stats["deleted_records"]
- stats["year_stats"][db_year] = year_stats
-
- except Exception as e:
- # 发生错误,回滚事务
- cursor.execute("ROLLBACK")
- print(f"{db_year}年数据清理时出错: {e}")
- stats["error_count"] += 1
- stats["year_stats"][db_year] = {"error": str(e)}
-
- print(f"数据清理完成: 处理了 {stats['processed_videos']} 个视频,删除了 {stats['deleted_records']} 条记录")
-
- # 执行VACUUM操作回收空间
- for db_year, conn in connections.items():
- try:
- print(f"正在对{db_year}年数据库执行VACUUM操作...")
- conn.execute("VACUUM")
- print(f"{db_year}年数据库VACUUM操作完成")
- except Exception as e:
- print(f"{db_year}年数据库VACUUM操作失败: {e}")
-
- return stats
-
- except Exception as e:
- print(f"执行数据清理时出错: {e}")
- stats["error"] = str(e)
- return stats
- finally:
- # 关闭所有数据库连接
- for conn in connections.values():
- if conn:
- conn.close()
-
-def schedule_daily_cleanup():
- """
- 设置每日数据清理定时任务,应在应用启动时调用此函数
- """
- import threading
- import schedule
- import time
-
- def run_cleanup():
- print(f"===== 开始执行每日数据清理,时间: {datetime.now().strftime('%Y-%m-%d %H:%M:%S')} =====")
- stats = cleanup_inactive_video_records()
- print(f"===== 每日数据清理完成,时间: {datetime.now().strftime('%Y-%m-%d %H:%M:%S')} =====")
- print(f"清理统计: {stats}")
-
- def run_scheduler():
- # 设置每天凌晨3点执行清理
- schedule.every().day.at("03:00").do(run_cleanup)
-
- while True:
- schedule.run_pending()
- time.sleep(60) # 每分钟检查一次
-
- # 创建并启动调度器线程
- scheduler_thread = threading.Thread(target=run_scheduler)
- scheduler_thread.daemon = True # 设为守护线程,主程序退出时自动结束
- scheduler_thread.start()
-
- print("已设置每日数据清理定时任务,将在每天凌晨3点执行")
-
- # 也可以提供一个立即执行的选项
- return scheduler_thread
-
-def main() -> None:
- """主函数"""
- try:
- print("正在获取B站热门视频列表...")
-
- # 默认获取所有热门视频
- videos, success, fetch_stats = get_all_popular_videos(page_size=20)
-
- if success and videos:
- # 只显示前20个视频
- print_popular_videos(videos, max_display=20)
-
- # 提示用户是否要显示所有视频
- if len(videos) > 20:
- choice = input("\n是否显示所有获取到的视频?(y/n): ")
- if choice.lower() == 'y':
- print_popular_videos(videos)
-
- elif not videos:
- print("未获取到任何视频数据")
-
- except KeyboardInterrupt:
- print("\n程序已被用户中断")
- except Exception as e:
- print(f"程序执行出错: {e}")
- finally:
- print("\n程序执行完毕")
-
-if __name__ == "__main__":
- main()
diff --git a/scripts/scheduler.py b/scripts/scheduler.py
deleted file mode 100644
index 0def947..0000000
--- a/scripts/scheduler.py
+++ /dev/null
@@ -1,170 +0,0 @@
-import logging
-import time
-from datetime import datetime
-from pathlib import Path
-
-import requests
-import schedule
-import yaml
-
-# 配置日志
-logging.basicConfig(
- level=logging.INFO,
- format='%(asctime)s - %(levelname)s - %(message)s',
- handlers=[
- logging.FileHandler('scheduler.log', encoding='utf-8'),
- logging.StreamHandler()
- ]
-)
-
-class TaskScheduler:
- def __init__(self, config_path=None):
- # 设置配置文件路径
- if config_path is None:
- from scripts.utils import get_config_path
- config_path = get_config_path('scheduler_config.yaml')
-
- self.config_path = config_path
- self.load_config()
- self.task_chains = {}
- self._init_task_status()
- self.base_url = "http://localhost:8899"
- self.tasks = {}
- self.start_time = datetime.now()
- logging.info(f"调度器初始化完成,启动时间: {self.start_time}")
-
- def load_config(self):
- """加载调度配置"""
- try:
- with open(self.config_path, 'r', encoding='utf-8') as f:
- config = yaml.safe_load(f)
- self.base_url = config.get('base_url', self.base_url)
- self.tasks = config.get('tasks', {})
- logging.info(f"成功加载配置文件: {self.config_path}")
- logging.info(f"已配置的任务: {list(self.tasks.keys())}")
- except Exception as e:
- logging.error(f"加载配置文件失败: {e}")
-
- def execute_task(self, task_name):
- """执行指定任务"""
- if task_name not in self.tasks:
- logging.error(f"未找到任务: {task_name}")
- return
-
- task = self.tasks[task_name]
- url = f"{self.base_url}{task['endpoint']}"
- method = task.get('method', 'GET').upper()
- params = task.get('params', {})
-
- try:
- logging.info(f"开始执行任务: {task_name}")
- logging.info(f"请求: {method} {url}")
- logging.info(f"参数: {params}")
-
- if method == 'GET':
- response = requests.get(url, params=params)
- elif method == 'POST':
- response = requests.post(url, json=params)
- else:
- logging.error(f"不支持的HTTP方法: {method}")
- return
-
- if response.status_code == 200:
- logging.info(f"任务 {task_name} 执行成功")
- logging.info(f"响应: {response.json()}")
- else:
- logging.error(f"任务 {task_name} 执行失败: {response.status_code}")
- logging.error(f"错误信息: {response.text}")
-
- except Exception as e:
- logging.error(f"执行任务 {task_name} 时发生错误: {e}")
-
- def schedule_tasks(self):
- """设置所有任务的调度"""
- for task_name, task in self.tasks.items():
- if 'schedule' in task:
- schedule_info = task['schedule']
- schedule_type = schedule_info.get('type')
-
- if schedule_type == 'daily':
- time_str = schedule_info.get('time', '00:00')
- schedule.every().day.at(time_str).do(self.execute_task, task_name)
- logging.info(f"已设置每日 {time_str} 执行任务: {task_name}")
-
- elif schedule_type == 'interval':
- interval = schedule_info.get('interval', 1)
- unit = schedule_info.get('unit', 'hours')
-
- if unit == 'minutes':
- schedule.every(interval).minutes.do(self.execute_task, task_name)
- elif unit == 'hours':
- schedule.every(interval).hours.do(self.execute_task, task_name)
- elif unit == 'days':
- schedule.every(interval).days.do(self.execute_task, task_name)
- elif unit == 'months':
- schedule.every(interval).months.do(self.execute_task, task_name)
- elif unit == 'years':
- schedule.every(interval).years.do(self.execute_task, task_name)
-
- logging.info(f"已设置每 {interval} {unit} 执行任务: {task_name}")
-
- def run(self):
- """运行调度器"""
- self.schedule_tasks()
- logging.info("调度器已启动,等待执行任务...")
-
- while True:
- try:
- schedule.run_pending()
- time.sleep(1)
- except Exception as e:
- logging.error(f"调度器运行错误: {e}")
- time.sleep(60) # 发生错误时等待1分钟后继续
-
-def create_default_config():
- """创建默认配置文件"""
- default_config = {
- 'base_url': 'http://localhost:8000',
- 'tasks': {
- 'fetch_history': {
- 'name': '获取历史记录',
- 'endpoint': '/fetch/bili-history',
- 'method': 'GET',
- 'params': {},
- 'schedule': {
- 'type': 'daily',
- 'time': '00:00'
- }
- },
- 'clean_data': {
- 'name': '清理数据',
- 'endpoint': '/clean/data',
- 'method': 'POST',
- 'params': {},
- 'schedule': {
- 'type': 'interval',
- 'interval': 12,
- 'unit': 'hours'
- }
- }
- }
- }
-
- config_dir = Path('config')
- config_dir.mkdir(exist_ok=True)
- config_path = config_dir / 'scheduler_config.yaml'
-
- if not config_path.exists():
- with open(config_path, 'w', encoding='utf-8') as f:
- yaml.dump(default_config, f, allow_unicode=True, sort_keys=False)
- logging.info(f"已创建默认配置文件: {config_path}")
-
- return config_path
-
-if __name__ == '__main__':
- # 确保配置文件存在
- config_path = create_default_config()
-
- # 创建并运行调度器
- scheduler = TaskScheduler(config_path)
- scheduler.run()
\ No newline at end of file
diff --git a/scripts/scheduler_db.py b/scripts/scheduler_db.py
deleted file mode 100644
index 517b251..0000000
--- a/scripts/scheduler_db.py
+++ /dev/null
@@ -1,530 +0,0 @@
-import json
-import os
-import sqlite3
-from datetime import datetime
-from typing import List, Dict, Optional
-
-from loguru import logger
-
-from scripts.utils import get_base_path, setup_logger
-
-# 确保日志系统已初始化
-setup_logger()
-
-class SchedulerDB:
- """计划任务数据库管理类"""
-
- _instance = None
-
- @classmethod
- def get_instance(cls) -> 'SchedulerDB':
- """获取单例实例"""
- if not cls._instance:
- cls._instance = cls()
- return cls._instance
-
- def __init__(self):
- """初始化数据库连接"""
- if SchedulerDB._instance is not None:
- return
-
- base_path = get_base_path()
- self.db_dir = os.path.join(base_path, 'output', 'database')
- os.makedirs(self.db_dir, exist_ok=True)
-
- self.db_path = os.path.join(self.db_dir, 'scheduler.db')
- self.conn = sqlite3.connect(self.db_path, check_same_thread=False)
- self.conn.row_factory = sqlite3.Row
-
- # 创建所需的表
- self._create_tables()
-
- def _create_tables(self):
- """创建所需的数据库表"""
- cursor = self.conn.cursor()
-
- # 任务状态表 - 存储每个任务的最新状态
- cursor.execute('''
- CREATE TABLE IF NOT EXISTS task_status (
- task_id TEXT PRIMARY KEY,
- name TEXT,
- last_run_time TEXT,
- next_run_time TEXT,
- last_status TEXT,
- enabled INTEGER DEFAULT 1,
- total_runs INTEGER DEFAULT 0,
- success_runs INTEGER DEFAULT 0,
- fail_runs INTEGER DEFAULT 0,
- avg_duration REAL DEFAULT 0,
- last_error TEXT,
- last_modified TEXT,
- priority INTEGER DEFAULT 0,
- tags TEXT,
- extra_data TEXT
- )
- ''')
-
- # 任务执行历史表 - 存储每次执行的详细信息
- cursor.execute('''
- CREATE TABLE IF NOT EXISTS task_history (
- id INTEGER PRIMARY KEY AUTOINCREMENT,
- task_id TEXT,
- start_time TEXT,
- end_time TEXT,
- duration REAL,
- status TEXT,
- error_message TEXT,
- triggered_by TEXT,
- output TEXT,
- FOREIGN KEY (task_id) REFERENCES task_status (task_id)
- )
- ''')
-
- # 依赖任务执行记录表 - 记录任务链的执行情况
- cursor.execute('''
- CREATE TABLE IF NOT EXISTS task_chain_execution (
- id INTEGER PRIMARY KEY AUTOINCREMENT,
- chain_id TEXT,
- start_task_id TEXT,
- start_time TEXT,
- end_time TEXT,
- status TEXT,
- tasks_executed TEXT,
- tasks_succeeded TEXT,
- tasks_failed TEXT
- )
- ''')
-
- self.conn.commit()
-
- def get_all_task_status(self) -> List[Dict]:
- """获取所有任务的状态"""
- cursor = self.conn.cursor()
- cursor.execute('''
- SELECT * FROM task_status
- ''')
-
- rows = cursor.fetchall()
- result = []
-
- for row in rows:
- task_data = dict(row)
- # 处理JSON字段
- if task_data.get('extra_data'):
- try:
- task_data['extra_data'] = json.loads(task_data['extra_data'])
- except:
- task_data['extra_data'] = {}
-
- if task_data.get('tags'):
- try:
- task_data['tags'] = json.loads(task_data['tags'])
- except:
- task_data['tags'] = []
-
- result.append(task_data)
-
- return result
-
- def get_task_status(self, task_id: str) -> Optional[Dict]:
- """获取特定任务的状态"""
- cursor = self.conn.cursor()
- cursor.execute('''
- SELECT * FROM task_status WHERE task_id = ?
- ''', (task_id,))
-
- row = cursor.fetchone()
- if not row:
- return None
-
- task_data = dict(row)
- # 处理JSON字段
- if task_data.get('extra_data'):
- try:
- task_data['extra_data'] = json.loads(task_data['extra_data'])
- except:
- task_data['extra_data'] = {}
-
- if task_data.get('tags'):
- try:
- task_data['tags'] = json.loads(task_data['tags'])
- except:
- task_data['tags'] = []
-
- return task_data
-
- def update_task_status(self, task_id: str, data: Dict) -> bool:
- """更新任务状态"""
- try:
- task_status = self.get_task_status(task_id)
- cursor = self.conn.cursor()
-
- # 检查task_status表是否有last_modified列
- cursor.execute("PRAGMA table_info(task_status)")
- columns = cursor.fetchall()
- has_last_modified = any(col[1] == 'last_modified' for col in columns)
-
- if task_status:
- # 任务存在,更新
- fields = []
- values = []
-
- for key, value in data.items():
- # 确保列存在于表中
- if key == 'last_modified' and not has_last_modified:
- continue
-
- fields.append(f"{key} = ?")
-
- # 处理特殊字段
- if key in ['extra_data', 'tags'] and value is not None:
- values.append(json.dumps(value, ensure_ascii=False))
- else:
- values.append(value)
-
- # 如果表中有last_modified列,才添加最后修改时间
- if has_last_modified:
- fields.append("last_modified = ?")
- values.append(datetime.now().isoformat())
-
- # 添加任务ID
- values.append(task_id)
-
- query = f'''
- UPDATE task_status SET {", ".join(fields)} WHERE task_id = ?
- '''
-
- cursor.execute(query, values)
- else:
- # 任务不存在,创建新任务
- fields = ['task_id']
- placeholders = ['?']
- values = [task_id]
-
- for key, value in data.items():
- # 确保列存在于表中
- if key == 'last_modified' and not has_last_modified:
- continue
-
- fields.append(key)
- placeholders.append('?')
-
- # 处理特殊字段
- if key in ['extra_data', 'tags'] and value is not None:
- values.append(json.dumps(value, ensure_ascii=False))
- else:
- values.append(value)
-
- # 如果表中有last_modified列,才添加最后修改时间
- if has_last_modified:
- fields.append("last_modified")
- placeholders.append("?")
- values.append(datetime.now().isoformat())
-
- query = f'''
- INSERT INTO task_status ({", ".join(fields)})
- VALUES ({", ".join(placeholders)})
- '''
-
- cursor.execute(query, values)
-
- self.conn.commit()
- return True
- except Exception as e:
- logger.error(f"更新任务状态失败: {str(e)}")
- return False
-
- def record_task_execution(self, task_id: str,
- start_time: str,
- end_time: Optional[str] = None,
- duration: Optional[float] = None,
- status: str = "success",
- error_message: Optional[str] = None,
- triggered_by: Optional[str] = None,
- output: Optional[str] = None) -> int:
- """记录任务执行"""
- try:
- cursor = self.conn.cursor()
-
- # 如果提供了开始时间和结束时间,但没有提供持续时间,尝试计算
- if start_time and end_time and duration is None:
- try:
- # 尝试解析时间字符串为datetime对象
- start_dt = datetime.fromisoformat(start_time)
- end_dt = datetime.fromisoformat(end_time)
- duration = (end_dt - start_dt).total_seconds()
- except Exception as e:
- logger.warning(f"计算任务持续时间失败: {str(e)}")
-
- # 插入执行记录
- cursor.execute('''
- INSERT INTO task_history
- (task_id, start_time, end_time, duration, status, error_message, triggered_by, output)
- VALUES (?, ?, ?, ?, ?, ?, ?, ?)
- ''', (
- task_id,
- start_time,
- end_time,
- duration,
- status,
- error_message,
- triggered_by,
- output
- ))
-
- history_id = cursor.lastrowid
-
- # 更新任务状态
- task_status = self.get_task_status(task_id) or {}
-
- # 基本更新字段
- update_data = {
- 'last_run_time': start_time,
- 'last_status': status
- }
-
- # 计数更新
- total_runs = task_status.get('total_runs', 0) + 1
- update_data['total_runs'] = total_runs
-
- if status == 'success':
- success_runs = task_status.get('success_runs', 0) + 1
- update_data['success_runs'] = success_runs
- elif status == 'fail':
- fail_runs = task_status.get('fail_runs', 0) + 1
- update_data['fail_runs'] = fail_runs
- update_data['last_error'] = error_message
-
- # 更新平均执行时间
- if duration is not None:
- old_avg = float(task_status.get('avg_duration', 0))
- if old_avg == 0:
- update_data['avg_duration'] = duration
- else:
- # 使用移动平均值
- update_data['avg_duration'] = (old_avg * (total_runs - 1) + duration) / total_runs
-
- # 应用更新
- self.update_task_status(task_id, update_data)
-
- self.conn.commit()
- return history_id
- except Exception as e:
- logger.error(f"记录任务执行失败: {str(e)}")
- return -1
-
- def get_task_execution_history(self, task_id: str, limit: int = 10) -> List[Dict]:
- """获取任务执行历史"""
- cursor = self.conn.cursor()
- cursor.execute('''
- SELECT * FROM task_history
- WHERE task_id = ?
- ORDER BY start_time DESC
- LIMIT ?
- ''', (task_id, limit))
-
- rows = cursor.fetchall()
- return [dict(row) for row in rows]
-
- def get_recent_task_executions(self, limit: int = 20) -> List[Dict]:
- """获取最近的任务执行记录"""
- cursor = self.conn.cursor()
- cursor.execute('''
- SELECT h.*, s.name
- FROM task_history h
- LEFT JOIN task_status s ON h.task_id = s.task_id
- ORDER BY h.start_time DESC
- LIMIT ?
- ''', (limit,))
-
- rows = cursor.fetchall()
- return [dict(row) for row in rows]
-
- def record_chain_execution(self, chain_id: str, start_task_id: str,
- tasks_executed: List[str], tasks_succeeded: List[str],
- tasks_failed: List[str], status: str,
- start_time: datetime, end_time: Optional[datetime] = None) -> int:
- """记录任务链执行"""
- try:
- cursor = self.conn.cursor()
-
- cursor.execute('''
- INSERT INTO task_chain_execution
- (chain_id, start_task_id, start_time, end_time, status, tasks_executed, tasks_succeeded, tasks_failed)
- VALUES (?, ?, ?, ?, ?, ?, ?, ?)
- ''', (
- chain_id,
- start_task_id,
- start_time.isoformat(),
- end_time.isoformat() if end_time else None,
- status,
- json.dumps(tasks_executed, ensure_ascii=False),
- json.dumps(tasks_succeeded, ensure_ascii=False),
- json.dumps(tasks_failed, ensure_ascii=False)
- ))
-
- chain_id = cursor.lastrowid
- self.conn.commit()
- return chain_id
- except Exception as e:
- logger.error(f"记录任务链执行失败: {str(e)}")
- return -1
-
- def get_chain_execution_history(self, limit: int = 10) -> List[Dict]:
- """获取任务链执行历史"""
- cursor = self.conn.cursor()
- cursor.execute('''
- SELECT * FROM task_chain_execution
- ORDER BY start_time DESC
- LIMIT ?
- ''', (limit,))
-
- rows = cursor.fetchall()
- result = []
-
- for row in rows:
- chain_data = dict(row)
- # 解析JSON字段
- for field in ['tasks_executed', 'tasks_succeeded', 'tasks_failed']:
- if chain_data.get(field):
- try:
- chain_data[field] = json.loads(chain_data[field])
- except:
- chain_data[field] = []
-
- result.append(chain_data)
-
- return result
-
- def set_task_next_run(self, task_id: str, next_run_time: datetime) -> bool:
- """设置任务的下次执行时间"""
- try:
- self.update_task_status(task_id, {
- 'next_run_time': next_run_time.isoformat()
- })
- return True
- except Exception as e:
- logger.error(f"设置任务下次执行时间失败: {str(e)}")
- return False
-
- def enable_task(self, task_id: str, enabled: bool = True) -> bool:
- """启用或禁用任务"""
- try:
- self.update_task_status(task_id, {
- 'enabled': 1 if enabled else 0
- })
- return True
- except Exception as e:
- logger.error(f"{'启用' if enabled else '禁用'}任务失败: {str(e)}")
- return False
-
- def set_task_priority(self, task_id: str, priority: int) -> bool:
- """设置任务优先级"""
- try:
- self.update_task_status(task_id, {
- 'priority': priority
- })
- return True
- except Exception as e:
- logger.error(f"设置任务优先级失败: {str(e)}")
- return False
-
- def add_task_tags(self, task_id: str, tags: List[str]) -> bool:
- """添加任务标签"""
- try:
- task_status = self.get_task_status(task_id)
- if not task_status:
- return False
-
- current_tags = task_status.get('tags', [])
- if not isinstance(current_tags, list):
- current_tags = []
-
- # 添加新标签
- for tag in tags:
- if tag not in current_tags:
- current_tags.append(tag)
-
- self.update_task_status(task_id, {
- 'tags': current_tags
- })
- return True
- except Exception as e:
- logger.error(f"添加任务标签失败: {str(e)}")
- return False
-
- def remove_task_tags(self, task_id: str, tags: List[str]) -> bool:
- """移除任务标签"""
- try:
- task_status = self.get_task_status(task_id)
- if not task_status:
- return False
-
- current_tags = task_status.get('tags', [])
- if not isinstance(current_tags, list):
- current_tags = []
-
- # 移除标签
- current_tags = [tag for tag in current_tags if tag not in tags]
-
- self.update_task_status(task_id, {
- 'tags': current_tags
- })
- return True
- except Exception as e:
- logger.error(f"移除任务标签失败: {str(e)}")
- return False
-
- def record_chain_execution_start(self, chain_id: str, start_task_id: str, start_time: str) -> int:
- """记录任务链开始执行"""
- try:
- cursor = self.conn.cursor()
-
- cursor.execute('''
- INSERT INTO task_chain_execution
- (chain_id, start_task_id, start_time, status)
- VALUES (?, ?, ?, ?)
- ''', (
- chain_id,
- start_task_id,
- start_time,
- 'running'
- ))
-
- execution_id = cursor.lastrowid
- self.conn.commit()
- return execution_id
- except Exception as e:
- logger.error(f"记录任务链开始执行失败: {str(e)}")
- return -1
-
- def record_chain_execution_end(self, chain_id: str, end_time: str, status: str,
- tasks_executed: int, tasks_succeeded: int, tasks_failed: int) -> bool:
- """记录任务链执行完成"""
- try:
- cursor = self.conn.cursor()
-
- cursor.execute('''
- UPDATE task_chain_execution
- SET end_time = ?, status = ?,
- tasks_executed = ?, tasks_succeeded = ?, tasks_failed = ?
- WHERE chain_id = ?
- ''', (
- end_time,
- status,
- tasks_executed,
- tasks_succeeded,
- tasks_failed,
- chain_id
- ))
-
- self.conn.commit()
- return cursor.rowcount > 0
- except Exception as e:
- logger.error(f"记录任务链执行完成失败: {str(e)}")
- return False
-
- def close(self):
- """关闭数据库连接"""
- if self.conn:
- self.conn.close()
\ No newline at end of file
diff --git a/scripts/scheduler_db_enhanced.py b/scripts/scheduler_db_enhanced.py
deleted file mode 100644
index 1531087..0000000
--- a/scripts/scheduler_db_enhanced.py
+++ /dev/null
@@ -1,1718 +0,0 @@
-import calendar
-import json
-import os
-import sqlite3
-import threading
-from datetime import datetime, timedelta
-from typing import List, Dict, Optional
-
-import yaml
-from loguru import logger
-
-from scripts.scheduler_db import SchedulerDB
-from scripts.utils import setup_logger
-
-# 确保日志系统已初始化
-setup_logger()
-
-class EnhancedSchedulerDB(SchedulerDB):
- """增强版调度器数据库管理类,支持主次任务关系"""
-
- _instance = None
- _lock = threading.Lock()
-
- @classmethod
- def get_instance(cls) -> 'EnhancedSchedulerDB':
- """获取单例实例"""
- if not cls._instance:
- with cls._lock:
- if not cls._instance:
- cls._instance = cls()
- return cls._instance
-
- def __init__(self):
- """初始化数据库连接"""
- if hasattr(self, '_initialized'):
- return
-
- # 确保输出目录存在
- self.db_dir = os.path.join('output', 'database')
- os.makedirs(self.db_dir, exist_ok=True)
-
- self.db_path = os.path.join(self.db_dir, 'scheduler.db')
- os.makedirs(os.path.dirname(self.db_path), exist_ok=True)
-
- # 连接数据库并设置时区为 UTC+8
- self.conn = sqlite3.connect(self.db_path)
- self.conn.execute("PRAGMA timezone='+08:00'")
- cursor = self.conn.cursor()
- cursor.execute("SELECT datetime('now', 'localtime')")
- self.conn.row_factory = sqlite3.Row
-
- # 如果数据库尚未初始化,则执行初始化操作
- cursor.execute("SELECT name FROM sqlite_master WHERE type='table'")
- tables = cursor.fetchall()
-
- if not tables:
- # 创建新的表结构
- self._create_tables()
-
- # 从配置文件导入初始数据
- self._import_config_data()
-
- self._initialized = True
-
- def _drop_all_tables(self):
- """删除所有现有表"""
- cursor = self.conn.cursor()
- cursor.execute("SELECT name FROM sqlite_master WHERE type='table'")
- tables = cursor.fetchall()
-
- for table in tables:
- if table[0] not in ['sqlite_sequence']: # 保留系统表
- cursor.execute(f"DROP TABLE IF EXISTS {table[0]}")
-
- self.conn.commit()
-
- def _create_tables(self):
- """创建新的表结构"""
- cursor = self.conn.cursor()
-
- # 主任务表
- cursor.execute('''
- CREATE TABLE IF NOT EXISTS main_tasks (
- task_id TEXT PRIMARY KEY,
- name TEXT NOT NULL,
- endpoint TEXT NOT NULL,
- method TEXT DEFAULT 'GET',
- params TEXT,
- schedule_type TEXT NOT NULL,
- schedule_time TEXT,
- schedule_delay INTEGER,
- interval_value INTEGER,
- interval_unit TEXT,
- enabled INTEGER DEFAULT 1,
- task_type TEXT DEFAULT 'main',
- created_at TIMESTAMP DEFAULT (datetime('now', 'localtime')),
- last_modified TIMESTAMP DEFAULT (datetime('now', 'localtime'))
- )
- ''')
-
- # 子任务表
- cursor.execute('''
- CREATE TABLE IF NOT EXISTS sub_tasks (
- task_id TEXT PRIMARY KEY,
- parent_id TEXT NOT NULL,
- name TEXT NOT NULL,
- sequence_number INTEGER NOT NULL,
- endpoint TEXT NOT NULL,
- method TEXT DEFAULT 'GET',
- params TEXT,
- schedule_type TEXT DEFAULT 'daily',
- enabled INTEGER DEFAULT 1,
- created_at TIMESTAMP DEFAULT (datetime('now', 'localtime')),
- last_modified TIMESTAMP DEFAULT (datetime('now', 'localtime')),
- FOREIGN KEY (parent_id) REFERENCES main_tasks(task_id) ON DELETE CASCADE
- )
- ''')
-
- # 任务状态表
- cursor.execute('''
- CREATE TABLE IF NOT EXISTS task_status (
- task_id TEXT PRIMARY KEY,
- last_run_time TEXT,
- next_run_time TEXT,
- last_status TEXT,
- total_runs INTEGER DEFAULT 0,
- success_runs INTEGER DEFAULT 0,
- fail_runs INTEGER DEFAULT 0,
- avg_duration REAL DEFAULT 0,
- last_error TEXT,
- tags TEXT,
- success_rate REAL DEFAULT 0,
- FOREIGN KEY (task_id) REFERENCES main_tasks(task_id) ON DELETE CASCADE
- )
- ''')
-
- # 子任务状态表
- cursor.execute('''
- CREATE TABLE IF NOT EXISTS sub_task_status (
- task_id TEXT PRIMARY KEY,
- last_run_time TEXT,
- next_run_time TEXT,
- last_status TEXT,
- total_runs INTEGER DEFAULT 0,
- success_runs INTEGER DEFAULT 0,
- fail_runs INTEGER DEFAULT 0,
- avg_duration REAL DEFAULT 0,
- last_error TEXT,
- tags TEXT,
- success_rate REAL DEFAULT 0,
- FOREIGN KEY (task_id) REFERENCES sub_tasks(task_id) ON DELETE CASCADE
- )
- ''')
-
- # 任务执行历史表
- cursor.execute('''
- CREATE TABLE IF NOT EXISTS task_executions (
- id INTEGER PRIMARY KEY AUTOINCREMENT,
- task_id TEXT NOT NULL,
- start_time TEXT NOT NULL,
- end_time TEXT,
- duration REAL,
- status TEXT NOT NULL,
- error_message TEXT,
- output TEXT,
- triggered_by TEXT,
- next_run_time TEXT,
- created_at TIMESTAMP DEFAULT (datetime('now', 'localtime')),
- FOREIGN KEY (task_id) REFERENCES main_tasks(task_id) ON DELETE CASCADE
- )
- ''')
-
- # 子任务执行历史表
- cursor.execute('''
- CREATE TABLE IF NOT EXISTS sub_task_executions (
- id INTEGER PRIMARY KEY AUTOINCREMENT,
- task_id TEXT NOT NULL,
- start_time TEXT NOT NULL,
- end_time TEXT,
- duration REAL,
- status TEXT NOT NULL,
- error_message TEXT,
- output TEXT,
- triggered_by TEXT,
- next_run_time TEXT,
- created_at TIMESTAMP DEFAULT (datetime('now', 'localtime')),
- FOREIGN KEY (task_id) REFERENCES sub_tasks(task_id) ON DELETE CASCADE
- )
- ''')
-
- # 任务依赖关系表 - 移除外键约束
- cursor.execute('''
- CREATE TABLE IF NOT EXISTS task_dependencies (
- id INTEGER PRIMARY KEY AUTOINCREMENT,
- task_id TEXT NOT NULL,
- depends_on TEXT NOT NULL,
- created_at TIMESTAMP DEFAULT (datetime('now', 'localtime')),
- UNIQUE(task_id, depends_on)
- )
- ''')
-
- self.conn.commit()
-
- def _import_config_data(self):
- """从配置文件导入初始数据"""
- try:
- from scripts.utils import get_config_path
- config_path = get_config_path('scheduler_config.yaml')
-
- if not os.path.exists(config_path):
- print(f"配置文件不存在: {config_path}")
- return
-
- with open(config_path, 'r', encoding='utf-8') as f:
- config = yaml.safe_load(f)
-
- if not config or 'tasks' not in config:
- print("配置文件中没有任务数据")
- return
-
- cursor = self.conn.cursor()
-
- # 首先找出所有主任务(没有依赖的任务)
- main_tasks = {}
- sub_tasks = {}
-
- for task_id, task_data in config['tasks'].items():
- if not task_data.get('requires'): # 没有依赖的是主任务
- main_tasks[task_id] = task_data
- else:
- sub_tasks[task_id] = task_data
-
- print(f"找到 {len(main_tasks)} 个主任务和 {len(sub_tasks)} 个子任务")
-
- # 导入主任务
- for task_id, task_data in main_tasks.items():
- schedule_info = task_data.get('schedule', {})
-
- # 处理interval类型任务的特殊字段
- interval_value = None
- interval_unit = None
- schedule_type = schedule_info.get('type', 'daily')
-
- if schedule_type == 'interval':
- # 优先使用interval_value和interval_unit,其次使用value和unit
- interval_value = schedule_info.get('interval_value', schedule_info.get('value'))
- interval_unit = schedule_info.get('interval_unit', schedule_info.get('unit'))
- print(f"任务 {task_id}: 间隔值 = {interval_value}, 间隔单位 = {interval_unit}")
-
- # 插入主任务
- cursor.execute("""
- INSERT INTO main_tasks (
- task_id, name, endpoint, method, params, schedule_type,
- schedule_time, schedule_delay, interval_value, interval_unit,
- enabled, task_type, last_modified
- ) VALUES (?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?)
- """, (
- task_id,
- task_data.get('name', task_id),
- task_data.get('endpoint', ''),
- task_data.get('method', 'GET'),
- json.dumps(task_data.get('params', {})),
- schedule_type,
- schedule_info.get('time'),
- schedule_info.get('delay'),
- interval_value,
- interval_unit,
- task_data.get('enabled', 1),
- 'main',
- datetime.now().isoformat()
- ))
-
- # 初始化任务状态
- cursor.execute('''
- INSERT INTO task_status (task_id, tags)
- VALUES (?, ?)
- ''', (task_id, json.dumps(task_data.get('tags', []))))
-
- # 导入子任务
- sequence_counter = {} # 用于记录每个主任务的子任务序号
-
- for task_id, task_data in sub_tasks.items():
- # 找到父任务
- parent_id = self._find_root_task(task_id, config['tasks'])
- if not parent_id:
- print(f"警告: 无法找到任务 {task_id} 的父任务")
- continue
-
- # 初始化序号计数器
- if parent_id not in sequence_counter:
- sequence_counter[parent_id] = 1
-
- schedule_info = task_data.get('schedule', {})
- sub_task = {
- 'task_id': task_id,
- 'parent_id': parent_id,
- 'name': task_data.get('name', task_id),
- 'sequence_number': sequence_counter[parent_id],
- 'endpoint': task_data.get('endpoint', ''),
- 'method': task_data.get('method', 'GET'),
- 'params': json.dumps(task_data.get('params', {})),
- 'schedule_type': schedule_info.get('type', 'daily'), # 修改这里,默认为daily
- 'enabled': 1
- }
-
- # 插入子任务
- cursor.execute('''
- INSERT INTO sub_tasks (
- task_id, parent_id, name, sequence_number,
- endpoint, method, params, schedule_type, enabled
- ) VALUES (
- :task_id, :parent_id, :name, :sequence_number,
- :endpoint, :method, :params, :schedule_type, :enabled
- )
- ''', sub_task)
-
- # 初始化子任务状态
- cursor.execute('''
- INSERT INTO sub_task_status (task_id, tags)
- VALUES (?, ?)
- ''', (task_id, json.dumps(task_data.get('tags', []))))
-
- # 更新序号计数器
- sequence_counter[parent_id] += 1
-
- # 添加依赖关系
- for depends_on in task_data.get('requires', []):
- cursor.execute('''
- INSERT INTO task_dependencies (task_id, depends_on)
- VALUES (?, ?)
- ''', (task_id, depends_on))
-
- self.conn.commit()
- print("成功导入配置数据")
-
- except Exception as e:
- print(f"导入配置数据时出错: {str(e)}")
- self.conn.rollback()
-
- def _find_root_task(self, task_id: str, tasks: dict) -> str:
- """递归查找任务链的根任务(主任务)"""
- task_data = tasks.get(task_id)
- if not task_data or not task_data.get('requires'):
- return task_id
- return self._find_root_task(task_data['requires'][0], tasks)
-
- def close(self):
- """关闭数据库连接"""
- if hasattr(self, 'conn'):
- self.conn.close()
-
- # =================== 主任务管理 ===================
-
- def get_all_main_tasks(self) -> List[Dict]:
- """获取所有主任务"""
- cursor = self.conn.cursor()
- cursor.execute('''
- SELECT m.*,
- ts.last_run_time, ts.next_run_time, ts.last_status,
- ts.total_runs, ts.success_runs, ts.fail_runs,
- ts.avg_duration, ts.last_error, ts.tags,
- ts.success_rate,
- m.created_at as created_at_local,
- m.last_modified as last_modified_local
- FROM main_tasks m
- LEFT JOIN task_status ts ON m.task_id = ts.task_id
- ''')
-
- rows = cursor.fetchall()
- result = []
-
- for row in rows:
- task_data = dict(row)
- # 处理JSON字段
- if task_data.get('params'):
- try:
- task_data['params'] = json.loads(task_data['params'])
- except:
- task_data['params'] = {}
-
- if task_data.get('tags'):
- try:
- task_data['tags'] = json.loads(task_data['tags'])
- except:
- task_data['tags'] = []
-
- # 使用本地时间替换原始时间
- task_data['created_at'] = task_data.pop('created_at_local')
- task_data['last_modified'] = task_data.pop('last_modified_local')
-
- # 确保 task_type 字段存在
- if 'task_type' not in task_data:
- task_data['task_type'] = 'main'
-
- # 获取子任务
- task_data['sub_tasks'] = self.get_sub_tasks(task_data['task_id'])
-
- result.append(task_data)
-
- return result
-
- def get_main_task_by_id(self, task_id: str) -> Optional[Dict]:
- """获取指定ID的主任务"""
- cursor = self.conn.cursor()
- cursor.execute('''
- SELECT m.*, ts.last_run_time, ts.next_run_time, ts.last_status,
- ts.total_runs, ts.success_runs, ts.fail_runs,
- ts.avg_duration, ts.last_error, ts.success_rate,
- m.created_at as created_at_local,
- m.last_modified as last_modified_local
- FROM main_tasks m
- LEFT JOIN task_status ts ON m.task_id = ts.task_id
- WHERE m.task_id = ?
- ''', (task_id,))
-
- row = cursor.fetchone()
- if not row:
- return None
-
- task_data = dict(row)
- # 处理JSON字段
- if task_data.get('params'):
- try:
- task_data['params'] = json.loads(task_data['params'])
- except:
- task_data['params'] = {}
-
- if task_data.get('tags'):
- try:
- task_data['tags'] = json.loads(task_data['tags'])
- except:
- task_data['tags'] = []
-
- # 使用本地时间替换原始时间
- task_data['created_at'] = task_data.pop('created_at_local')
- task_data['last_modified'] = task_data.pop('last_modified_local')
-
- return task_data
-
- def create_main_task(self, task_id: str, task_data: Dict) -> bool:
- """创建新的主任务"""
- try:
- cursor = self.conn.cursor()
-
- # 检查任务ID是否已存在
- cursor.execute("SELECT COUNT(*) FROM main_tasks WHERE task_id = ?", (task_id,))
- if cursor.fetchone()[0] > 0:
- logger.error(f"任务ID '{task_id}' 已存在")
- return False
-
- # 准备任务数据
- params = task_data.get('params', {})
-
- # 如果是发送邮件任务,确保params包含必要的内容
- if task_data.get('endpoint') == '/log/send-email' and not params:
- params = {
- "content": None,
- "mode": "simple",
- "subject": "B站历史记录日报 - {current_time}"
- }
- logger.info(f"为发送邮件任务 '{task_id}' 自动添加默认参数")
-
- params_json = json.dumps(params) if params else None
- tags = json.dumps(task_data.get('tags', [])) if task_data.get('tags') else '[]'
-
- # 处理interval类型任务的特殊字段
- interval_value = None
- interval_unit = None
- if task_data.get('schedule_type') == 'interval':
- interval_value = task_data.get('interval_value', task_data.get('interval'))
- interval_unit = task_data.get('interval_unit', task_data.get('unit'))
- logger.info(f"设置间隔执行任务: 每 {interval_value} {interval_unit}")
-
- # 插入主任务
- cursor.execute("""
- INSERT INTO main_tasks (
- task_id, name, endpoint, method, params, schedule_type,
- schedule_time, schedule_delay, interval_value, interval_unit,
- enabled, task_type, last_modified
- ) VALUES (?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?, ?)
- """, (
- task_id,
- task_data.get('name', task_id),
- task_data.get('endpoint', ''),
- task_data.get('method', 'GET'),
- params_json,
- task_data.get('schedule_type', 'daily'),
- task_data.get('schedule_time'),
- task_data.get('schedule_delay'),
- interval_value,
- interval_unit,
- task_data.get('enabled', 1),
- 'main',
- datetime.now().isoformat()
- ))
-
- # 初始化任务状态
- cursor.execute('''
- INSERT INTO task_status (task_id, tags)
- VALUES (?, ?)
- ''', (task_id, tags))
-
- self.conn.commit()
- logger.info(f"成功创建主任务 '{task_id}'")
- return True
- except Exception as e:
- self.conn.rollback()
- logger.error(f"创建主任务失败: {str(e)}")
- return False
-
- def update_main_task(self, task_id: str, task_data: Dict) -> bool:
- """更新主任务信息"""
- try:
- cursor = self.conn.cursor()
-
- # 检查任务是否存在且为主任务
- cursor.execute("SELECT COUNT(*) FROM main_tasks WHERE task_id = ?", (task_id,))
- if cursor.fetchone()[0] == 0:
- logger.error(f"主任务 '{task_id}' 不存在")
- return False
-
- # 准备更新字段
- fields = []
- values = []
-
- for key, value in task_data.items():
- if key in ['name', 'endpoint', 'method', 'schedule_type', 'schedule_time',
- 'schedule_delay', 'enabled']:
- fields.append(f"{key} = ?")
- values.append(value)
- elif key == 'interval_value' or key == 'interval':
- fields.append("interval_value = ?")
- values.append(value)
- elif key == 'interval_unit' or key == 'unit':
- fields.append("interval_unit = ?")
- values.append(value)
- elif key == 'params':
- # 如果是发送邮件任务,确保params包含必要的内容
- if 'endpoint' in task_data and task_data['endpoint'] == '/log/send-email':
- if not value:
- value = {
- "content": None,
- "mode": "simple",
- "subject": "B站历史记录日报 - {current_time}"
- }
- logger.info(f"为发送邮件任务 '{task_id}' 自动添加默认参数")
- fields.append("params = ?")
- values.append(json.dumps(value))
- elif key == 'tags':
- # 更新任务状态表中的标签
- try:
- cursor.execute("""
- UPDATE task_status
- SET tags = ?
- WHERE task_id = ?
- """, (json.dumps(value), task_id))
- except Exception as e:
- logger.error(f"更新任务标签失败: {str(e)}")
-
- # 添加最后修改时间
- fields.append("last_modified = ?")
- values.append(datetime.now().isoformat())
-
- # 添加任务ID
- values.append(task_id)
-
- if fields:
- # 构建更新SQL
- sql = f"UPDATE main_tasks SET {', '.join(fields)} WHERE task_id = ?"
- cursor.execute(sql, values)
-
- self.conn.commit()
- logger.info(f"成功更新主任务 '{task_id}'")
- return True
- else:
- logger.warning(f"没有提供有效的更新字段")
- return False
-
- except Exception as e:
- self.conn.rollback()
- logger.error(f"更新主任务失败: {str(e)}")
- return False
-
- def delete_main_task(self, task_id: str) -> bool:
- """删除主任务及其所有子任务"""
- try:
- cursor = self.conn.cursor()
-
- # 检查任务是否存在且为主任务
- cursor.execute("SELECT COUNT(*) FROM main_tasks WHERE task_id = ?", (task_id,))
- if cursor.fetchone()[0] == 0:
- logger.error(f"主任务 '{task_id}' 不存在")
- return False
-
- # 开启事务
- self.conn.execute("BEGIN TRANSACTION")
-
- # 获取所有子任务ID
- cursor.execute("SELECT task_id FROM sub_tasks WHERE parent_id = ?", (task_id,))
- subtask_ids = [row[0] for row in cursor.fetchall()]
-
- # 删除子任务依赖
- for subtask_id in subtask_ids:
- cursor.execute("DELETE FROM task_dependencies WHERE task_id = ? OR depends_on = ?",
- (subtask_id, subtask_id))
-
- # 删除子任务状态
- for subtask_id in subtask_ids:
- cursor.execute("DELETE FROM sub_task_status WHERE task_id = ?", (subtask_id,))
-
- # 删除子任务执行历史记录
- for subtask_id in subtask_ids:
- cursor.execute("DELETE FROM sub_task_executions WHERE task_id = ?", (subtask_id,))
-
- # 删除子任务
- cursor.execute("DELETE FROM sub_tasks WHERE parent_id = ?", (task_id,))
-
- # 删除主任务依赖
- cursor.execute("DELETE FROM task_dependencies WHERE task_id = ? OR depends_on = ?",
- (task_id, task_id))
-
- # 删除主任务状态
- cursor.execute("DELETE FROM task_status WHERE task_id = ?", (task_id,))
-
- # 删除主任务执行历史记录
- cursor.execute("DELETE FROM task_executions WHERE task_id = ?", (task_id,))
-
- # 删除主任务
- cursor.execute("DELETE FROM main_tasks WHERE task_id = ?", (task_id,))
-
- self.conn.commit()
- logger.info(f"成功删除主任务 '{task_id}' 及其子任务")
- return True
- except Exception as e:
- self.conn.rollback()
- logger.error(f"删除主任务失败: {str(e)}")
- return False
-
- # =================== 子任务管理 ===================
-
- def get_sub_tasks(self, parent_id: str) -> List[Dict]:
- """获取指定主任务的所有子任务"""
- cursor = self.conn.cursor()
- cursor.execute('''
- SELECT s.*,
- sts.last_run_time, sts.next_run_time, sts.last_status,
- sts.total_runs, sts.success_runs, sts.fail_runs,
- sts.avg_duration, sts.last_error, sts.tags,
- sts.success_rate,
- s.created_at as created_at_local,
- s.last_modified as last_modified_local,
- td.depends_on
- FROM sub_tasks s
- LEFT JOIN sub_task_status sts ON s.task_id = sts.task_id
- LEFT JOIN task_dependencies td ON s.task_id = td.task_id
- WHERE s.parent_id = ?
- ORDER BY s.sequence_number
- ''', (parent_id,))
-
- rows = cursor.fetchall()
- result = []
-
- for row in rows:
- task_data = dict(row)
- # 处理JSON字段
- if task_data.get('params'):
- try:
- task_data['params'] = json.loads(task_data['params'])
- except:
- task_data['params'] = {}
-
- if task_data.get('tags'):
- try:
- task_data['tags'] = json.loads(task_data['tags'])
- except:
- task_data['tags'] = []
-
- # 使用本地时间替换原始时间
- task_data['created_at'] = task_data.pop('created_at_local')
- task_data['last_modified'] = task_data.pop('last_modified_local')
-
- # 获取依赖任务信息
- cursor.execute('''
- SELECT td.depends_on, COALESCE(mt.name, st.name) as depends_on_name
- FROM task_dependencies td
- LEFT JOIN main_tasks mt ON td.depends_on = mt.task_id
- LEFT JOIN sub_tasks st ON td.depends_on = st.task_id
- WHERE td.task_id = ?
- ''', (task_data['task_id'],))
-
- dependencies = cursor.fetchall()
- if dependencies:
- task_data['depends_on'] = {
- 'task_id': dependencies[0][0],
- 'name': dependencies[0][1]
- }
-
- result.append(task_data)
-
- return result
-
- def get_subtask_by_id(self, task_id: str) -> Optional[Dict]:
- """获取指定ID的子任务"""
- cursor = self.conn.cursor()
- cursor.execute('''
- SELECT s.*,
- sts.last_run_time, sts.next_run_time, sts.last_status,
- sts.total_runs, sts.success_runs, sts.fail_runs,
- sts.avg_duration, sts.last_error, sts.tags,
- sts.success_rate,
- s.created_at as created_at_local,
- s.last_modified as last_modified_local,
- td.depends_on
- FROM sub_tasks s
- LEFT JOIN sub_task_status sts ON s.task_id = sts.task_id
- LEFT JOIN task_dependencies td ON s.task_id = td.task_id
- WHERE s.task_id = ?
- ''', (task_id,))
-
- row = cursor.fetchone()
- if not row:
- return None
-
- task_data = dict(row)
- # 处理JSON字段
- if task_data.get('params'):
- try:
- task_data['params'] = json.loads(task_data['params'])
- except:
- task_data['params'] = {}
-
- if task_data.get('tags'):
- try:
- task_data['tags'] = json.loads(task_data['tags'])
- except:
- task_data['tags'] = []
-
- # 使用本地时间替换原始时间
- task_data['created_at'] = task_data.pop('created_at_local')
- task_data['last_modified'] = task_data.pop('last_modified_local')
-
- # 获取依赖任务信息
- cursor.execute('''
- SELECT td.depends_on, COALESCE(mt.name, st.name) as depends_on_name
- FROM task_dependencies td
- LEFT JOIN main_tasks mt ON td.depends_on = mt.task_id
- LEFT JOIN sub_tasks st ON td.depends_on = st.task_id
- WHERE td.task_id = ?
- ''', (task_id,))
-
- dependencies = cursor.fetchall()
- if dependencies:
- task_data['depends_on'] = {
- 'task_id': dependencies[0][0],
- 'name': dependencies[0][1]
- }
-
- return task_data
-
- def get_sub_task(self, parent_id: str, task_id: str) -> Optional[Dict]:
- """获取指定主任务下的特定子任务"""
- cursor = self.conn.cursor()
- cursor.execute('''
- SELECT s.*,
- sts.last_run_time, sts.next_run_time, sts.last_status,
- sts.total_runs, sts.success_runs, sts.fail_runs,
- sts.avg_duration, sts.last_error, sts.tags,
- sts.success_rate,
- s.created_at as created_at_local,
- s.last_modified as last_modified_local,
- td.depends_on
- FROM sub_tasks s
- LEFT JOIN sub_task_status sts ON s.task_id = sts.task_id
- LEFT JOIN task_dependencies td ON s.task_id = td.task_id
- WHERE s.task_id = ? AND s.parent_id = ?
- ''', (task_id, parent_id))
-
- row = cursor.fetchone()
- if not row:
- return None
-
- task_data = dict(row)
- # 处理JSON字段
- if task_data.get('params'):
- try:
- task_data['params'] = json.loads(task_data['params'])
- except:
- task_data['params'] = {}
-
- if task_data.get('tags'):
- try:
- task_data['tags'] = json.loads(task_data['tags'])
- except:
- task_data['tags'] = []
-
- # 使用本地时间替换原始时间
- task_data['created_at'] = task_data.pop('created_at_local')
- task_data['last_modified'] = task_data.pop('last_modified_local')
-
- # 获取依赖任务信息
- cursor.execute('''
- SELECT td.depends_on, COALESCE(mt.name, st.name) as depends_on_name
- FROM task_dependencies td
- LEFT JOIN main_tasks mt ON td.depends_on = mt.task_id
- LEFT JOIN sub_tasks st ON td.depends_on = st.task_id
- WHERE td.task_id = ?
- ''', (task_id,))
-
- dependencies = cursor.fetchall()
- if dependencies:
- task_data['depends_on'] = {
- 'task_id': dependencies[0][0],
- 'name': dependencies[0][1]
- }
-
- return task_data
-
- def create_sub_task(self, parent_id: str, task_data: Dict) -> bool:
- """创建新的子任务"""
- try:
- cursor = self.conn.cursor()
- logger.info(f"开始创建子任务,父任务ID: {parent_id}")
- logger.info(f"任务数据: {json.dumps(task_data, ensure_ascii=False)}")
-
- # 检查父任务是否存在
- cursor.execute("SELECT COUNT(*) FROM main_tasks WHERE task_id = ?", (parent_id,))
- if cursor.fetchone()[0] == 0:
- logger.error(f"父任务 '{parent_id}' 不存在")
- return False
-
- # 获取当前最大序号
- cursor.execute("""
- SELECT COALESCE(MAX(sequence_number), 0)
- FROM sub_tasks
- WHERE parent_id = ?
- """, (parent_id,))
- max_sequence = cursor.fetchone()[0]
- logger.info(f"当前最大序号: {max_sequence}")
-
- # 准备任务数据
- task_id = task_data.get('task_id')
- if not task_id:
- logger.error("未提供子任务ID")
- return False
-
- # 检查任务ID是否已存在
- cursor.execute("""
- SELECT COUNT(*) FROM sub_tasks WHERE task_id = ?
- """, (task_id,))
- if cursor.fetchone()[0] > 0:
- logger.error(f"子任务ID '{task_id}' 已存在")
- return False
-
- params = task_data.get('params', {})
-
- # 如果是发送邮件任务,确保params包含必要的内容
- if task_data.get('endpoint') == '/log/send-email' and not params:
- params = {
- "content": None,
- "mode": "simple",
- "subject": "B站历史记录日报 - {current_time}"
- }
- logger.info(f"为发送邮件子任务 '{task_id}' 自动添加默认参数")
-
- params_json = json.dumps(params) if params else None
- tags = json.dumps(task_data.get('tags', [])) if task_data.get('tags') else '[]'
-
- # 插入子任务
- logger.info(f"开始插入子任务记录: {task_id}")
- cursor.execute("""
- INSERT INTO sub_tasks (
- task_id, parent_id, name, sequence_number,
- endpoint, method, params, schedule_type, enabled
- ) VALUES (?, ?, ?, ?, ?, ?, ?, ?, ?)
- """, (
- task_id,
- parent_id,
- task_data.get('name', task_id),
- max_sequence + 1,
- task_data.get('endpoint', ''),
- task_data.get('method', 'GET'),
- params_json,
- task_data.get('schedule_type', 'daily'),
- task_data.get('enabled', 1)
- ))
- logger.info("子任务记录插入成功")
-
- # 初始化子任务状态
- logger.info(f"开始初始化子任务状态: {task_id}")
- cursor.execute('''
- INSERT INTO sub_task_status (task_id, tags)
- VALUES (?, ?)
- ''', (task_id, tags))
- logger.info("子任务状态初始化成功")
-
- # 处理依赖关系
- if 'depends_on' in task_data:
- logger.info(f"发现依赖关系配置: {json.dumps(task_data.get('depends_on', {}), ensure_ascii=False)}")
- if task_data['depends_on'] and isinstance(task_data['depends_on'], dict):
- depends_on_id = task_data['depends_on'].get('task_id')
- logger.info(f"依赖任务ID: {depends_on_id}")
- if depends_on_id:
- try:
- logger.info(f"开始插入依赖关系: {task_id} -> {depends_on_id}")
- cursor.execute("""
- INSERT INTO task_dependencies (task_id, depends_on)
- VALUES (?, ?)
- """, (task_id, depends_on_id))
- logger.info("依赖关系插入成功")
- except Exception as e:
- logger.error(f"插入依赖关系时出错: {str(e)}")
- raise
- else:
- logger.warning("依赖关系数据格式不正确")
- else:
- logger.info("没有依赖关系需要处理")
-
- self.conn.commit()
- logger.info(f"成功创建子任务 '{task_id}'")
- return True
-
- except Exception as e:
- self.conn.rollback()
- logger.error(f"创建子任务失败: {str(e)}")
- return False
-
- def update_subtask(self, task_id: str, task_data: Dict) -> bool:
- """更新子任务信息"""
- try:
- cursor = self.conn.cursor()
-
- # 检查任务是否存在且为子任务
- cursor.execute("SELECT COUNT(*) FROM sub_tasks WHERE task_id = ?", (task_id,))
- if cursor.fetchone()[0] == 0:
- logger.error(f"子任务 '{task_id}' 不存在")
- return False
-
- # 准备更新字段
- fields = []
- values = []
-
- for key, value in task_data.items():
- if key in ['name', 'endpoint', 'method', 'schedule_type', 'enabled']:
- fields.append(f"{key} = ?")
- values.append(value)
- elif key == 'params':
- # 如果是发送邮件任务,确保params包含必要的内容
- if 'endpoint' in task_data and task_data['endpoint'] == '/log/send-email':
- if not value:
- value = {
- "content": None,
- "mode": "simple",
- "subject": "B站历史记录日报 - {current_time}"
- }
- logger.info(f"为发送邮件子任务 '{task_id}' 自动添加默认参数")
- fields.append("params = ?")
- values.append(json.dumps(value))
- elif key == 'tags':
- # 更新子任务状态表中的标签
- try:
- cursor.execute("""
- UPDATE sub_task_status
- SET tags = ?
- WHERE task_id = ?
- """, (json.dumps(value), task_id))
- except Exception as e:
- logger.error(f"更新子任务标签失败: {str(e)}")
-
- # 添加最后修改时间
- fields.append("last_modified = ?")
- values.append(datetime.now().isoformat())
-
- # 更新依赖关系
- if 'depends_on' in task_data:
- # 删除现有依赖
- cursor.execute("DELETE FROM task_dependencies WHERE task_id = ?", (task_id,))
-
- # 添加新依赖
- if task_data['depends_on'] and isinstance(task_data['depends_on'], dict):
- depends_on_id = task_data['depends_on'].get('task_id')
- if depends_on_id:
- try:
- cursor.execute("""
- INSERT INTO task_dependencies (task_id, depends_on)
- VALUES (?, ?)
- """, (task_id, depends_on_id))
- except Exception as e:
- logger.error(f"更新依赖关系失败: {str(e)}")
-
- # 添加任务ID
- values.append(task_id)
-
- if fields:
- # 构建更新SQL
- sql = f"UPDATE sub_tasks SET {', '.join(fields)} WHERE task_id = ?"
- cursor.execute(sql, values)
-
- self.conn.commit()
- logger.info(f"成功更新子任务 '{task_id}'")
- return True
- else:
- logger.warning(f"没有提供有效的更新字段")
- return False
-
- except Exception as e:
- self.conn.rollback()
- logger.error(f"更新子任务失败: {str(e)}")
- return False
-
- def delete_subtask(self, task_id: str, parent_id: str = None) -> bool:
- """删除子任务,可选指定父任务ID以确保只删除特定主任务下的子任务"""
- try:
- cursor = self.conn.cursor()
-
- # 检查任务是否存在且为子任务
- if parent_id:
- cursor.execute("SELECT COUNT(*) FROM sub_tasks WHERE task_id = ? AND parent_id = ?", (task_id, parent_id))
- else:
- cursor.execute("SELECT COUNT(*) FROM sub_tasks WHERE task_id = ?", (task_id,))
-
- if cursor.fetchone()[0] == 0:
- logger.error(f"子任务 '{task_id}' 不存在" + (f" 或不属于主任务 '{parent_id}'" if parent_id else ""))
- return False
-
- # 开启事务
- self.conn.execute("BEGIN TRANSACTION")
-
- # 删除依赖关系
- cursor.execute("DELETE FROM task_dependencies WHERE task_id = ? OR depends_on = ?",
- (task_id, task_id))
-
- # 删除子任务状态
- cursor.execute("DELETE FROM sub_task_status WHERE task_id = ?", (task_id,))
-
- # 删除子任务执行历史记录
- cursor.execute("DELETE FROM sub_task_executions WHERE task_id = ?", (task_id,))
-
- # 删除子任务
- if parent_id:
- cursor.execute("DELETE FROM sub_tasks WHERE task_id = ? AND parent_id = ?", (task_id, parent_id))
- else:
- cursor.execute("DELETE FROM sub_tasks WHERE task_id = ?", (task_id,))
-
- # 重新排序剩余子任务
- # 如果提供了parent_id,只重新排序该主任务下的子任务
- if parent_id:
- cursor.execute("""
- SELECT task_id, sequence_number
- FROM sub_tasks
- WHERE parent_id = ?
- ORDER BY sequence_number
- """, (parent_id,))
- subtasks = cursor.fetchall()
-
- # 更新序号
- for i, task in enumerate(subtasks, 1):
- if task[1] != i: # 如果序号不匹配才更新
- cursor.execute("""
- UPDATE sub_tasks SET sequence_number = ? WHERE task_id = ?
- """, (i, task[0]))
- else:
- # 按父任务分组重新排序所有子任务
- cursor.execute("""
- SELECT task_id, parent_id, sequence_number
- FROM sub_tasks
- ORDER BY parent_id, sequence_number
- """)
- subtasks = cursor.fetchall()
-
- # 按父任务分组
- subtasks_by_parent = {}
- for subtask in subtasks:
- if subtask[1] not in subtasks_by_parent:
- subtasks_by_parent[subtask[1]] = []
- subtasks_by_parent[subtask[1]].append(subtask)
-
- # 更新序号
- for parent_id, tasks in subtasks_by_parent.items():
- for i, task in enumerate(tasks, 1):
- if task[2] != i: # 如果序号不匹配才更新
- cursor.execute("""
- UPDATE sub_tasks SET sequence_number = ? WHERE task_id = ?
- """, (i, task[0]))
-
- self.conn.commit()
- logger.info(f"成功删除子任务 '{task_id}'" + (f" (主任务: {parent_id})" if parent_id else ""))
- return True
- except Exception as e:
- self.conn.rollback()
- logger.error(f"删除子任务失败: {str(e)}")
- return False
-
- def delete_sub_task(self, parent_id: str, task_id: str) -> bool:
- """删除指定主任务下的特定子任务,确保ID相同时不会错删除主任务"""
- return self.delete_subtask(task_id, parent_id)
-
- def reorder_subtasks(self, parent_id: str, task_order: List[str]) -> bool:
- """重新排序子任务"""
- try:
- cursor = self.conn.cursor()
-
- # 检查主任务是否存在
- cursor.execute("SELECT COUNT(*) FROM main_tasks WHERE task_id = ?", (parent_id,))
- if cursor.fetchone()[0] == 0:
- logger.error(f"主任务 '{parent_id}' 不存在")
- return False
-
- # 获取所有子任务
- cursor.execute("""
- SELECT task_id FROM sub_tasks WHERE parent_id = ?
- """, (parent_id,))
- existing_subtasks = [row[0] for row in cursor.fetchall()]
-
- # 验证输入的任务列表
- if set(task_order) != set(existing_subtasks):
- logger.error(f"提供的任务列表与实际子任务不匹配")
- return False
-
- # 更新序号
- for i, task_id in enumerate(task_order, 1):
- cursor.execute("""
- UPDATE sub_tasks SET sequence_number = ? WHERE task_id = ?
- """, (i, task_id))
-
- self.conn.commit()
- logger.info(f"成功重排主任务 '{parent_id}' 的子任务顺序")
- return True
- except Exception as e:
- self.conn.rollback()
- logger.error(f"重排子任务顺序失败: {str(e)}")
- return False
-
- def is_main_task(self, task_id: str) -> bool:
- """检查指定任务是否为主任务"""
- cursor = self.conn.cursor()
- cursor.execute("SELECT COUNT(*) FROM main_tasks WHERE task_id = ?", (task_id,))
- row = cursor.fetchone()
- return row and row[0] > 0
-
- def get_task_execution_history_enhanced(
- self,
- task_id: str,
- include_subtasks: bool = True,
- conditions: dict = None,
- page: int = 1,
- page_size: int = 20
- ) -> Dict:
- """获取任务的执行历史(增强版)"""
- cursor = self.conn.cursor()
- params = []
- where_clauses = []
-
- # 基础查询
- if self.is_main_task(task_id):
- # 主任务查询
- base_query = """
- SELECT te.*, mt.name as task_name, 'main' as task_type, NULL as parent_id
- FROM task_executions te
- LEFT JOIN main_tasks mt ON te.task_id = mt.task_id
- """
- where_clauses.append("te.task_id = ?")
- params.append(task_id)
-
- if include_subtasks:
- # 添加子任务历史
- base_query = """
- SELECT te.*, mt.name as task_name, 'main' as task_type, NULL as parent_id
- FROM task_executions te
- LEFT JOIN main_tasks mt ON te.task_id = mt.task_id
- WHERE te.task_id = ?
- UNION ALL
- SELECT ste.*, st.name as task_name, 'sub' as task_type, st.parent_id
- FROM sub_task_executions ste
- LEFT JOIN sub_tasks st ON ste.task_id = st.task_id
- WHERE st.parent_id = ?
- """
- params = [task_id, task_id] # 重置参数列表
- else:
- # 子任务查询
- base_query = """
- SELECT ste.*, st.name as task_name, 'sub' as task_type, st.parent_id
- FROM sub_task_executions ste
- LEFT JOIN sub_tasks st ON ste.task_id = st.task_id
- """
- where_clauses.append("ste.task_id = ?")
- params.append(task_id)
-
- # 添加条件过滤
- if conditions:
- if conditions.get('status'):
- where_clauses.append("status = ?")
- params.append(conditions['status'])
- if conditions.get('start_date'):
- where_clauses.append("start_time >= ?")
- params.append(conditions['start_date'])
- if conditions.get('end_date'):
- where_clauses.append("start_time <= ?")
- params.append(conditions['end_date'])
-
- # 构建完整查询
- if not include_subtasks or not self.is_main_task(task_id):
- # 如果不包含子任务或者是子任务查询,使用 WHERE 子句
- where_clause = " AND ".join(where_clauses) if where_clauses else "1=1"
- final_query = f"{base_query} WHERE {where_clause}"
- else:
- # 如果是包含子任务的主任务查询,base_query 已经包含了完整的查询条件
- final_query = base_query
-
- # 获取总记录数
- count_query = f"SELECT COUNT(*) FROM ({final_query})"
- cursor.execute(count_query, params)
- total_count = cursor.fetchone()[0]
-
- # 添加分页和排序
- final_query = f"""
- {final_query}
- ORDER BY start_time DESC
- LIMIT ? OFFSET ?
- """
- params.extend([page_size, (page - 1) * page_size])
-
- # 执行查询
- cursor.execute(final_query, params)
- rows = cursor.fetchall()
-
- # 处理结果
- records = []
- for row in rows:
- record = dict(row)
- # 处理输出字段(如果存在)
- if record.get('output'):
- try:
- record['output'] = json.loads(record['output'])
- except:
- pass
- records.append(record)
-
- return {
- 'records': records,
- 'total': total_count
- }
-
- def get_task_dependencies(self, task_id: str) -> List[str]:
- """获取任务的依赖项"""
- cursor = self.conn.cursor()
- cursor.execute("""
- SELECT depends_on FROM task_dependencies WHERE task_id = ?
- """, (task_id,))
- return [row[0] for row in cursor.fetchall()]
-
- def record_task_execution_enhanced(self,
- task_id: str,
- start_time: str,
- end_time: str = None,
- duration: float = None,
- status: str = "success",
- error_message: str = None,
- triggered_by: str = None,
- output: str = None,
- parent_execution_id: int = None,
- next_run_time: str = None) -> int:
- """记录任务执行(增强版)"""
- try:
- cursor = self.conn.cursor()
-
- # 如果提供了开始时间和结束时间,但没有提供持续时间,尝试计算
- if start_time and end_time and duration is None:
- try:
- start_dt = datetime.fromisoformat(start_time)
- end_dt = datetime.fromisoformat(end_time)
- duration = (end_dt - start_dt).total_seconds()
- except Exception as e:
- logger.warning(f"计算任务持续时间失败: {str(e)}")
-
- # 确定任务类型(主任务或子任务)
- is_sub_task = not self.is_main_task(task_id)
-
- # 获取任务配置以确定下次执行时间
- task_config = None
- if is_sub_task:
- task_config = self.get_subtask_by_id(task_id)
- else:
- task_config = self.get_main_task_by_id(task_id)
-
- # 如果没有提供 next_run_time,则计算它
- if next_run_time is None:
- schedule_type = task_config.get('schedule_type') if task_config else None
-
- # 只有主任务时才计算下次执行时间
- if not is_sub_task:
- if schedule_type == 'daily':
- schedule_time = task_config.get('schedule_time')
- if schedule_time:
- try:
- current_dt = datetime.fromisoformat(start_time)
- schedule_parts = schedule_time.split(':')
- next_dt = current_dt.replace(
- hour=int(schedule_parts[0]),
- minute=int(schedule_parts[1]),
- second=0,
- microsecond=0
- )
-
- # 如果当前时间已经过了今天的调度时间,设置为明天
- if current_dt >= next_dt:
- next_dt = next_dt + timedelta(days=1)
-
- next_run_time = next_dt.strftime('%Y-%m-%d %H:%M:%S')
- logger.info(f"计算得到下次执行时间: {next_run_time}")
- except Exception as e:
- logger.error(f"计算下次执行时间失败: {str(e)}")
- next_run_time = None
- elif schedule_type == 'interval':
- # 处理间隔任务
- interval_value = task_config.get('interval_value')
- interval_unit = task_config.get('interval_unit')
-
- if interval_value and interval_unit:
- try:
- current_dt = datetime.fromisoformat(start_time if end_time is None else end_time)
-
- # 根据间隔值和单位计算下次执行时间
- if interval_unit == 'minutes':
- next_dt = current_dt + timedelta(minutes=interval_value)
- elif interval_unit == 'hours':
- next_dt = current_dt + timedelta(hours=interval_value)
- elif interval_unit == 'days':
- next_dt = current_dt + timedelta(days=interval_value)
- elif interval_unit == 'weeks':
- next_dt = current_dt + timedelta(weeks=interval_value)
- elif interval_unit == 'months':
- # 手动计算月份
- year = current_dt.year
- month = current_dt.month + interval_value
-
- # 处理月份溢出
- while month > 12:
- month -= 12
- year += 1
-
- # 处理月份天数问题(例如,1月31日 + 1个月)
- day = min(current_dt.day, calendar.monthrange(year, month)[1])
-
- next_dt = current_dt.replace(year=year, month=month, day=day)
- elif interval_unit == 'years':
- # 处理闰年问题
- year = current_dt.year + interval_value
- month = current_dt.month
- day = min(current_dt.day, calendar.monthrange(year, month)[1])
-
- next_dt = current_dt.replace(year=year, day=day)
- else:
- logger.warning(f"不支持的间隔单位: {interval_unit}")
- next_dt = None
-
- if next_dt:
- next_run_time = next_dt.strftime('%Y-%m-%d %H:%M:%S')
- logger.info(f"计算得到间隔任务下次执行时间: {next_run_time},间隔: {interval_value} {interval_unit}")
- except Exception as e:
- logger.error(f"计算间隔任务下次执行时间失败: {str(e)}")
- next_run_time = None
-
- # 根据任务类型选择表
- table_name = "sub_task_executions" if is_sub_task else "task_executions"
- status_table = "sub_task_status" if is_sub_task else "task_status"
-
- # 构建插入语句
- fields = ["task_id", "start_time", "end_time", "duration",
- "status", "error_message", "triggered_by", "output"]
- values = [task_id, start_time, end_time, duration,
- status, error_message, triggered_by, output]
-
- if next_run_time is not None:
- fields.append("next_run_time")
- values.append(next_run_time)
-
- # 如果提供了父执行ID,添加到字段列表
- if parent_execution_id is not None:
- fields.append("parent_execution_id")
- values.append(parent_execution_id)
-
- # 构建SQL语句
- placeholders = ["?" for _ in values]
- sql = f"""
- INSERT INTO {table_name}
- ({', '.join(fields)})
- VALUES ({', '.join(placeholders)})
- """
-
- # 执行插入
- cursor.execute(sql, values)
- execution_id = cursor.lastrowid
-
- # 更新任务状态
- # 先获取当前状态以计算成功率和平均执行时间
- cursor.execute(f'''
- SELECT total_runs, success_runs, fail_runs, avg_duration
- FROM {status_table}
- WHERE task_id = ?
- ''', (task_id,))
- current_stats = cursor.fetchone()
-
- if current_stats:
- total_runs = current_stats[0] + 1
- success_runs = current_stats[1] + (1 if status == 'success' else 0)
- fail_runs = current_stats[2] + (1 if status != 'success' else 0)
- success_rate = (success_runs / total_runs) * 100 if total_runs > 0 else 0
-
- # 计算新的平均执行时间
- current_avg_duration = current_stats[3] or 0
- if duration is not None:
- avg_duration = ((current_avg_duration * (total_runs - 1)) + duration) / total_runs
- else:
- avg_duration = current_avg_duration
-
- cursor.execute(f'''
- UPDATE {status_table}
- SET last_run_time = ?,
- next_run_time = ?,
- last_status = ?,
- last_error = ?,
- total_runs = ?,
- success_runs = ?,
- fail_runs = ?,
- success_rate = ?,
- avg_duration = ?
- WHERE task_id = ?
- ''', (
- start_time,
- next_run_time,
- status,
- error_message,
- total_runs,
- success_runs,
- fail_runs,
- success_rate,
- avg_duration,
- task_id
- ))
- else:
- # 如果没有状态记录,创建一个新的
- cursor.execute(f'''
- INSERT INTO {status_table}
- (task_id, last_run_time, next_run_time, last_status, last_error,
- total_runs, success_runs, fail_runs, success_rate, avg_duration)
- VALUES (?, ?, ?, ?, ?, 1, ?, ?, ?, ?)
- ''', (
- task_id,
- start_time,
- next_run_time,
- status,
- error_message,
- 1 if status == 'success' else 0,
- 1 if status != 'success' else 0,
- 100 if status == 'success' else 0,
- duration or 0
- ))
-
- self.conn.commit()
- return execution_id
-
- except Exception as e:
- self.conn.rollback()
- logger.error(f"记录任务执行失败: {str(e)}")
- return -1
-
- def _calculate_next_run_time(self, task_data: Dict) -> Optional[datetime]:
- """计算下次执行时间"""
- schedule_type = task_data.get('schedule_type')
- if not schedule_type:
- return None
-
- now = datetime.now()
-
- if schedule_type == 'daily':
- schedule_time = task_data.get('schedule_time')
- if not schedule_time:
- return None
- hour, minute = map(int, schedule_time.split(':'))
- next_run = now.replace(hour=hour, minute=minute, second=0, microsecond=0)
- if next_run <= now:
- next_run += timedelta(days=1)
-
- elif schedule_type == 'interval':
- # 优先使用interval_value和interval_unit字段,如果不存在则尝试使用interval和unit字段
- interval_value = task_data.get('interval_value', task_data.get('interval'))
- interval_unit = task_data.get('interval_unit', task_data.get('unit'))
-
- if not interval_value:
- logger.error(f"间隔任务缺少间隔值: {task_data}")
- return None
-
- if not interval_unit:
- logger.error(f"间隔任务缺少间隔单位: {task_data}")
- return None
-
- logger.info(f"计算间隔任务下次执行时间: 间隔值={interval_value}, 单位={interval_unit}")
-
- if interval_value and interval_unit:
- try:
- now = datetime.now()
-
- # 根据间隔值和单位计算下次执行时间
- if interval_unit == 'minutes':
- next_dt = now + timedelta(minutes=interval_value)
- elif interval_unit == 'hours':
- next_dt = now + timedelta(hours=interval_value)
- elif interval_unit == 'days':
- next_dt = now + timedelta(days=interval_value)
- elif interval_unit == 'weeks':
- next_dt = now + timedelta(weeks=interval_value)
- elif interval_unit == 'months':
- # 手动计算月份
- year = now.year
- month = now.month + interval_value
-
- # 处理月份溢出
- while month > 12:
- month -= 12
- year += 1
-
- # 处理月份天数问题
- day = min(now.day, calendar.monthrange(year, month)[1])
-
- next_dt = now.replace(year=year, month=month, day=day)
- elif interval_unit == 'years':
- # 处理闰年问题
- year = now.year + interval_value
- month = now.month
- day = min(now.day, calendar.monthrange(year, month)[1])
-
- next_dt = now.replace(year=year, day=day)
- else:
- logger.warning(f"不支持的间隔单位: {interval_unit}")
- return None
-
- next_run_time = next_dt.strftime('%Y-%m-%d %H:%M:%S')
- logger.info(f"计算得到间隔任务下次执行时间: {next_run_time},间隔: {interval_value} {interval_unit}")
- return next_dt
- except Exception as e:
- logger.error(f"计算间隔任务下次执行时间失败: {str(e)}")
- return None
- else:
- logger.error(f"间隔任务缺少必要参数: interval_value={interval_value}, interval_unit={interval_unit}")
- return None
- elif schedule_type == 'once':
- delay = task_data.get('delay', 0)
- next_run = now + timedelta(seconds=delay)
-
- else:
- return None
-
- return next_run
-
- def update_next_execution_time(self, task_id: str, next_run_time: Optional[str] = None):
- """
- 更新任务的下次执行时间
-
- Args:
- task_id: 任务ID
- next_run_time: 下次执行时间,如果为None则自动计算
-
- Returns:
- bool: 更新是否成功
- """
- try:
- # 确定任务类型(主任务或子任务)
- is_sub_task = not self.is_main_task(task_id)
-
- # 如果是子任务,不处理下次执行时间
- if is_sub_task:
- logger.warning(f"子任务 {task_id} 不支持更新下次执行时间")
- return False
-
- # 获取任务配置
- task_config = self.get_main_task_by_id(task_id)
- if not task_config:
- logger.error(f"任务 {task_id} 不存在")
- return False
-
- # 如果没有提供 next_run_time,则计算它
- if next_run_time is None:
- schedule_type = task_config.get('schedule_type')
-
- if schedule_type == 'daily':
- schedule_time = task_config.get('schedule_time')
- if schedule_time:
- try:
- now = datetime.now()
- schedule_parts = schedule_time.split(':')
- next_dt = now.replace(
- hour=int(schedule_parts[0]),
- minute=int(schedule_parts[1]),
- second=0,
- microsecond=0
- )
-
- # 如果当前时间已经过了今天的调度时间,设置为明天
- if now >= next_dt:
- next_dt = next_dt + timedelta(days=1)
-
- next_run_time = next_dt.strftime('%Y-%m-%d %H:%M:%S')
- logger.info(f"计算得到下次执行时间: {next_run_time}")
- except Exception as e:
- logger.error(f"计算下次执行时间失败: {str(e)}")
- return False
-
- elif schedule_type == 'interval':
- # 处理间隔任务
- interval_value = task_config.get('interval_value')
- interval_unit = task_config.get('interval_unit')
-
- # 如果interval_value和interval_unit不存在,尝试使用旧的字段名
- if interval_value is None:
- interval_value = task_config.get('interval')
- logger.info(f"使用旧的interval字段: {interval_value}")
-
- if interval_unit is None:
- interval_unit = task_config.get('unit')
- logger.info(f"使用旧的unit字段: {interval_unit}")
-
- logger.info(f"准备计算间隔任务时间: 任务={task_id}, 间隔值={interval_value}, 单位={interval_unit}")
-
- if interval_value and interval_unit:
- try:
- now = datetime.now()
-
- # 根据间隔值和单位计算下次执行时间
- if interval_unit == 'minutes':
- next_dt = now + timedelta(minutes=interval_value)
- elif interval_unit == 'hours':
- next_dt = now + timedelta(hours=interval_value)
- elif interval_unit == 'days':
- next_dt = now + timedelta(days=interval_value)
- elif interval_unit == 'weeks':
- next_dt = now + timedelta(weeks=interval_value)
- elif interval_unit == 'months':
- # 手动计算月份
- year = now.year
- month = now.month + interval_value
-
- # 处理月份溢出
- while month > 12:
- month -= 12
- year += 1
-
- # 处理月份天数问题
- day = min(now.day, calendar.monthrange(year, month)[1])
-
- next_dt = now.replace(year=year, month=month, day=day)
- elif interval_unit == 'years':
- # 处理闰年问题
- year = now.year + interval_value
- month = now.month
- day = min(now.day, calendar.monthrange(year, month)[1])
-
- next_dt = now.replace(year=year, day=day)
- else:
- logger.warning(f"不支持的间隔单位: {interval_unit}")
- return False
-
- next_run_time = next_dt.strftime('%Y-%m-%d %H:%M:%S')
- logger.info(f"计算得到间隔任务下次执行时间: {next_run_time},间隔: {interval_value} {interval_unit}")
- except Exception as e:
- logger.error(f"计算间隔任务下次执行时间失败: {str(e)}")
- return False
- else:
- logger.error(f"间隔任务缺少必要参数: interval_value={interval_value}, interval_unit={interval_unit}")
- return False
- else:
- logger.warning(f"任务 {task_id} 的计划类型 {schedule_type} 不支持自动计算下次执行时间")
- return False
-
- # 更新数据库中的下次执行时间
- cursor = self.conn.cursor()
- cursor.execute('''
- UPDATE task_status
- SET next_run_time = ?
- WHERE task_id = ?
- ''', (next_run_time, task_id))
-
- # 如果没有状态记录,创建一个新的
- if cursor.rowcount == 0:
- cursor.execute('''
- INSERT INTO task_status
- (task_id, next_run_time)
- VALUES (?, ?)
- ''', (task_id, next_run_time))
-
- self.conn.commit()
- logger.info(f"成功更新任务 {task_id} 的下次执行时间: {next_run_time}")
- return True
-
- except Exception as e:
- self.conn.rollback()
- logger.error(f"更新任务下次执行时间失败: {str(e)}")
- return False
-
- def load_config(self):
- """加载调度器配置"""
- try:
- from scripts.utils import get_config_path
- config_path = get_config_path('scheduler_config.yaml')
-
- if not os.path.exists(config_path):
- return False
-
- with open(config_path, 'r', encoding='utf-8') as f:
- config = yaml.safe_load(f)
-
- if 'tasks' not in config:
- return False
-
- self.config = config
- return True
- except Exception as e:
- logger.error(f"加载配置文件失败: {e}")
- return False
\ No newline at end of file
diff --git a/scripts/scheduler_manager.py b/scripts/scheduler_manager.py
deleted file mode 100644
index 6198943..0000000
--- a/scripts/scheduler_manager.py
+++ /dev/null
@@ -1,1525 +0,0 @@
-import asyncio
-import calendar
-import os
-import threading
-import traceback
-from datetime import datetime, timedelta
-from typing import Optional, List
-
-import httpx
-import schedule
-import yaml
-from loguru import logger
-
-from scripts.scheduler_db_enhanced import EnhancedSchedulerDB # 修改为导入增强版数据库
-from scripts.utils import get_base_path, load_config, get_config_path, setup_logger
-
-# 确保日志系统已初始化
-setup_logger()
-
-class SchedulerManager:
- _instance = None
- _lock = threading.Lock() # 添加线程锁
-
- @classmethod
- def get_instance(cls, app=None) -> 'SchedulerManager':
- """获取 SchedulerManager 的单例实例"""
- if not cls._instance:
- with cls._lock: # 使用线程锁确保线程安全
- if not cls._instance: # 双重检查
- if app is None:
- raise ValueError("First initialization requires app instance")
- cls._instance = cls(app)
- return cls._instance
-
- def __init__(self, app):
- """初始化调度管理器"""
- # 防止重复初始化
- if hasattr(self, '_initialized'): # 检查是否已初始化
- return
-
- self.app = app
- self.tasks = {}
- self.daily_tasks = {}
- self.task_chains = {} # 通过依赖关系构建的任务链
- self.scheduler = None
- self.task_status = {}
- self.chain_status = {}
- self.is_running = False
- self.log_capture = None
- self.current_log_file = None
-
- # 从config.yaml读取服务器配置
- config = load_config()
- server_config = config.get('server', {})
- bind_host = server_config.get('host', '0.0.0.0')
- port = server_config.get('port', 8899)
-
- # 根据服务器配置构建base_url
- #
- # 注意: 0.0.0.0/:: 是“监听所有网卡”的绑定地址,不能作为客户端连接目标。
- # 调度器的内部HTTP调用应使用本机回环地址,否则会出现 `All connection attempts failed`。
- connect_host = (bind_host or "").strip()
- if not connect_host or connect_host in {"0.0.0.0", "::", "0:0:0:0:0:0:0:0"}:
- connect_host = "127.0.0.1"
-
- ssl_enabled = bool(server_config.get('ssl_enabled', False))
- ssl_certfile = server_config.get('ssl_certfile')
- ssl_keyfile = server_config.get('ssl_keyfile')
- scheme = "https" if (ssl_enabled and ssl_certfile and ssl_keyfile) else "http"
-
- url_host = connect_host
- if ":" in url_host and not url_host.startswith("["):
- url_host = f"[{url_host}]"
-
- self.base_url = f"{scheme}://{url_host}:{port}"
- print(f"从主配置文件读取服务器监听地址: {bind_host}:{port}")
- if connect_host != bind_host:
- print(f"检测到监听地址为 {bind_host},调度器内部请求将使用 {connect_host} (本机回环)")
- print(f"设置base_url为: {self.base_url}")
-
- # 获取增强版数据库实例
- self.db = EnhancedSchedulerDB.get_instance()
-
- # 加载调度器配置(不再从这里获取base_url)
- self.load_scheduler_config()
- self._initialized = True # 标记为已初始化
-
- def load_scheduler_config(self):
- """加载调度器配置"""
- try:
- config_file = get_config_path('scheduler_config.yaml')
-
- if not os.path.exists(config_file):
- logger.warning(f"调度器配置文件不存在: {config_file}")
- return
-
- with open(config_file, 'r', encoding='utf-8') as f:
- config = yaml.safe_load(f)
-
- # 处理错误处理配置
- if 'error_handling' in config:
- self.notify_on_failure = config['error_handling'].get('notify_on_failure', True)
- self.stop_on_failure = config['error_handling'].get('stop_on_failure', True)
-
- # 处理调度器配置
- if 'scheduler' in config:
- scheduler_config = config['scheduler']
- self.log_level = scheduler_config.get('log_level', 'INFO')
- if 'retry' in scheduler_config:
- self.retry_delay = scheduler_config['retry'].get('delay', 60)
- self.max_retry_attempts = scheduler_config['retry'].get('max_attempts', 3)
-
- # 清空现有任务
- self.tasks = {}
-
- # 检查数据库是否已初始化(通过检查是否有任何主任务)
- main_tasks = self.db.get_all_main_tasks()
-
- if not main_tasks and 'tasks' in config:
- # 数据库未初始化,从配置文件加载
- logger.info("数据库未初始化,从配置文件加载任务")
- for task_id, task_config in config['tasks'].items():
- # 创建新任务
- task_name = task_config.get('name', task_id)
- endpoint = task_config.get('endpoint', '')
- method = task_config.get('method', 'GET')
- params = task_config.get('params', {})
-
- # 获取调度配置
- schedule_config = task_config.get('schedule', {})
- schedule_type = schedule_config.get('type', 'daily')
- schedule_time = schedule_config.get('time') if schedule_type == 'daily' else None
- schedule_delay = schedule_config.get('delay') if schedule_type == 'once' else None
-
- # 获取interval类型的特殊配置
- interval_value = None
- interval_unit = None
- if schedule_type == 'interval':
- # 优先使用interval_value和interval_unit,其次使用value和unit
- interval_value = schedule_config.get('interval_value', schedule_config.get('value'))
- interval_unit = schedule_config.get('interval_unit', schedule_config.get('unit'))
- print(f"从配置文件读取间隔任务: {task_id}, 间隔值={interval_value}, 单位={interval_unit}")
-
- # 判断是否为主任务或子任务
- task_type = 'main' # 默认为主任务
- parent_id = None
- sequence_number = None
-
- # 获取依赖项
- requires = task_config.get('requires', [])
-
- # 将任务保存到数据库
- task_data = {
- 'name': task_name,
- 'endpoint': endpoint,
- 'method': method,
- 'params': params,
- 'task_type': task_type,
- 'parent_id': parent_id,
- 'sequence_number': sequence_number,
- 'schedule_type': schedule_type,
- 'schedule_time': schedule_time,
- 'schedule_delay': schedule_delay,
- 'interval_value': interval_value,
- 'interval_unit': interval_unit,
- 'enabled': True
- }
-
- self.db.create_main_task(task_id, task_data)
-
- # 添加依赖关系
- for dep in requires:
- self.db.add_task_dependency(task_id, dep)
- else:
- # 数据库已初始化,直接从数据库加载
- logger.info("从数据库加载任务")
- for task_data in main_tasks:
- task_id = task_data['task_id']
- self.tasks[task_id] = task_data
-
- # 合并配置文件中新定义但数据库不存在的任务(便于新增任务生效)
- try:
- if 'tasks' in config:
- existing_ids = {t['task_id'] for t in main_tasks}
- for new_task_id, task_cfg in config['tasks'].items():
- if new_task_id in existing_ids:
- continue
- # 解析调度配置
- schedule_cfg = task_cfg.get('schedule', {})
- schedule_type = schedule_cfg.get('type', 'daily')
- schedule_time = schedule_cfg.get('time') if schedule_type == 'daily' else None
- schedule_delay = schedule_cfg.get('delay') if schedule_type == 'once' else None
- interval_value = None
- interval_unit = None
- if schedule_type == 'interval':
- interval_value = schedule_cfg.get('interval_value', schedule_cfg.get('value'))
- interval_unit = schedule_cfg.get('interval_unit', schedule_cfg.get('unit'))
-
- merged_task_data = {
- 'name': task_cfg.get('name', new_task_id),
- 'endpoint': task_cfg.get('endpoint', ''),
- 'method': task_cfg.get('method', 'GET'),
- 'params': task_cfg.get('params', {}),
- 'task_type': 'main',
- 'parent_id': None,
- 'sequence_number': None,
- 'schedule_type': schedule_type,
- 'schedule_time': schedule_time,
- 'schedule_delay': schedule_delay,
- 'interval_value': interval_value,
- 'interval_unit': interval_unit,
- 'enabled': True
- }
- self.db.create_main_task(new_task_id, merged_task_data)
- self.tasks[new_task_id] = merged_task_data
-
- # 写入依赖关系
- for dep in task_cfg.get('requires', []):
- self.db.add_task_dependency(new_task_id, dep)
-
- logger.info("已合并配置文件中的新增任务到数据库")
- except Exception as merge_ex:
- logger.warning(f"合并配置任务时出错(忽略): {merge_ex}")
-
- # 应用 config.yaml 中的登录监控覆盖(开关与间隔)
- try:
- main_cfg = load_config()
- monitor_cfg = (main_cfg.get('server') or {}).get('login_monitor') or {}
- monitor_enabled = bool(monitor_cfg.get('enabled', True))
- monitor_interval = int(monitor_cfg.get('interval_minutes', 10))
- task_id = 'sessdata_health_check'
-
- base_task = {
- 'name': 'SESSDATA健康检查',
- 'endpoint': '/login/check-and-notify',
- 'method': 'GET',
- 'params': {},
- 'task_type': 'main',
- 'parent_id': None,
- 'sequence_number': None,
- 'schedule_type': 'interval',
- 'schedule_time': None,
- 'schedule_delay': None,
- 'interval_value': monitor_interval,
- 'interval_unit': 'minutes',
- 'enabled': 1 if monitor_enabled else 0
- }
-
- if task_id in self.tasks:
- self.tasks[task_id].update({
- 'schedule_type': 'interval',
- 'schedule_time': None,
- 'interval_value': monitor_interval,
- 'interval_unit': 'minutes',
- 'enabled': 1 if monitor_enabled else 0
- })
- try:
- self.db.update_main_task(task_id, {
- 'schedule_type': 'interval',
- 'schedule_time': None,
- 'interval_value': monitor_interval,
- 'interval_unit': 'minutes',
- 'enabled': 1 if monitor_enabled else 0
- })
- except Exception:
- pass
- else:
- if monitor_enabled:
- self.db.create_main_task(task_id, base_task)
- self.tasks[task_id] = base_task
- logger.info("已根据配置创建登录监控任务 sessdata_health_check")
- except Exception as e:
- logger.warning(f"应用登录监控覆盖失败(忽略): {e}")
-
- # 构建任务链
- self._build_task_chains()
-
- # 设置每日任务
- self._setup_daily_tasks()
-
- logger.info(f"成功加载 {len(self.tasks)} 个任务,{len(self.daily_tasks)} 个每日任务,{len(self.task_chains)} 个任务链")
-
- self._initialized = True
- except Exception as e:
- logger.error(f"加载调度器配置失败: {str(e)}")
- traceback_str = traceback.format_exc()
- logger.debug(f"错误详情: {traceback_str}")
-
- def _init_task_status_in_db(self):
- """初始化数据库中的任务状态记录"""
- for task_id, task in self.tasks.items():
- # 检查任务是否已在数据库中存在
- task_status = self.db.get_task_status(task_id)
- if not task_status:
- # 新任务,添加到数据库
- self.db.update_task_status(task_id, {
- 'name': task.get('name', task_id),
- 'enabled': 1
- })
-
- def _build_task_chains(self):
- """构建任务链(基于增强版数据库)"""
- task_chains = {}
-
- # 从数据库获取所有任务依赖关系
- for task_id in self.tasks:
- # 获取任务依赖项
- dependencies = self.db.get_task_dependencies(task_id)
-
- # 如果有依赖,就把当前任务添加到它们的后续任务中
- for dep in dependencies:
- if dep not in task_chains:
- task_chains[dep] = []
- if task_id not in task_chains[dep]:
- task_chains[dep].append(task_id)
-
- self.task_chains = task_chains
- logger.info(f"构建了 {len(task_chains)} 个任务链")
-
- # 输出每个任务链的详情
- for source, targets in task_chains.items():
- logger.info(f"任务链: {source} -> {', '.join(targets)}")
-
- def _setup_daily_tasks(self):
- """设置每日任务的调度"""
- now = datetime.now()
-
- # 先清除所有现有的调度任务
- schedule.clear()
- schedule.jobs.clear()
-
- # 重置所有任务的状态
- self.task_status.clear()
-
- # 创建一个同步的执行函数
- def sync_execute_task(task_name):
- try:
- loop = asyncio.get_running_loop()
- except RuntimeError:
- loop = asyncio.new_event_loop()
- asyncio.set_event_loop(loop)
-
- try:
- task = loop.create_task(self.execute_task_chain(task_name))
- loop.run_until_complete(asyncio.gather(task))
- except Exception as e:
- print(f"执行任务时发生错误: {str(e)}")
- finally:
- if loop and not loop.is_running():
- loop.close()
-
- for task_name, task in self.tasks.items():
- if task.get('schedule_type') == 'daily':
- # 从数据库获取任务的启用状态
- task_data = self.db.get_main_task_by_id(task_name)
- is_enabled = bool(task_data.get('enabled', False)) if task_data else False
-
- # 只调度启用的任务
- if is_enabled:
- schedule_time = task.get('schedule_time')
- if not schedule_time:
- print(f"警告: 任务 {task_name} 没有设置调度时间")
- continue
-
- # 计算下次执行时间
- next_run = self._calculate_next_run_time(schedule_time)
- if next_run:
- next_run_str = next_run.strftime('%Y-%m-%d %H:%M:%S')
- self.db.update_task_status(task_name, {'next_run_time': next_run_str})
-
- try:
- job = schedule.every().day.at(schedule_time).do(sync_execute_task, task_name)
- print(f"已设置任务 {task_name} 的调度时间: {schedule_time}")
- except Exception as e:
- print(f"设置任务调度失败: {str(e)}")
-
- def add_main_task(self, task_id, task_data):
- """添加主任务"""
- # 检查是否已存在同名主任务
- if self.db.is_main_task(task_id):
- logger.warning(f"主任务 {task_id} 已存在,无法添加")
- return False
-
- result = self.db.create_main_task(task_id, task_data)
- if result:
- # 更新内存中的任务集合
- task = self.db.get_main_task_by_id(task_id)
- if task:
- self.tasks[task_id] = task
-
- # 如果是每日任务,更新每日任务集合
- if task.get('schedule_type') == 'daily':
- self._setup_daily_tasks()
-
- logger.info(f"成功添加主任务: {task_id}")
- return True
-
- return False
-
- def add_sub_task(self, parent_id, task_id, sub_task_data):
- """添加子任务"""
- if not self.db.is_main_task(parent_id):
- logger.warning(f"父任务 {parent_id} 不存在或不是主任务,无法添加子任务")
- return False
-
- # 确保子任务数据中包含task_id
- if 'task_id' not in sub_task_data:
- sub_task_data['task_id'] = task_id
-
- result = self.db.create_sub_task(parent_id, sub_task_data)
- if result:
- logger.info(f"成功为主任务 {parent_id} 添加子任务 {task_id}")
- return True
-
- return False
-
- def update_task_dependencies(self, task_id, dependencies):
- """更新任务依赖关系"""
- # 首先移除现有依赖
- self.db.remove_all_task_dependencies(task_id)
-
- # 添加新依赖
- for dep in dependencies:
- self.db.add_task_dependency(task_id, dep)
-
- # 重新构建任务链
- self._build_task_chains()
-
- logger.info(f"成功更新任务 {task_id} 的依赖关系: {dependencies}")
- return True
-
- async def execute_task(self, task_id: str) -> bool:
- """执行单个任务"""
- print(f"\n=== 执行任务: {task_id} ===")
- print(f"当前时间: {datetime.now().strftime('%Y-%m-%d %H:%M:%S')}")
-
- try:
- # 检查任务是否存在
- if task_id not in self.tasks:
- print(f"错误: 任务 {task_id} 不存在")
- return False
-
- task = self.tasks[task_id]
- print(f"开始执行任务: {task['name']}")
-
- # 创建后台任务并等待其完成
- task_result = await self.execute_task_chain(task_id)
-
- print(f"任务 {task_id} 执行完成")
- return task_result
-
- except Exception as e:
- print(f"执行任务时发生错误: {str(e)}")
- return False
-
- async def execute_task_chain(self, task_id: str) -> bool:
- """执行任务链,包括主任务及其子任务"""
- print(f"\n=== 执行任务链: {task_id} ===")
- print(f"当前时间: {datetime.now().strftime('%Y-%m-%d %H:%M:%S')}")
-
- try:
- # 检查任务是否存在
- if task_id not in self.tasks:
- print(f"错误: 任务 {task_id} 不存在")
- return False
-
- # 检查主任务是否启用
- task_data = self.db.get_main_task_by_id(task_id)
- if not task_data or not task_data.get('enabled', False):
- print(f"主任务 {task_id} 已禁用,跳过执行")
- return False
-
- # 获取任务链
- task_chain = self._build_chain_from_task(task_id)
- if not task_chain:
- print(f"错误: 无法构建任务 {task_id} 的执行链")
- return False
-
- print(f"任务链: {' -> '.join(task_chain)}")
-
- # 依次执行任务链中的每个任务
- for chain_task_id in task_chain:
- print(f"\n执行链中的任务: {chain_task_id}")
-
- # 设置当前正在执行的任务链
- self.current_chain = task_id
-
- # 如果是主任务,先执行主任务,再执行其子任务
- if self.db.is_main_task(chain_task_id):
- # 检查主任务是否启用
- main_task_data = self.db.get_main_task_by_id(chain_task_id)
- if not main_task_data or not main_task_data.get('enabled', False):
- print(f"主任务 {chain_task_id} 已禁用,跳过执行")
- continue
-
- # 执行主任务
- success = await self._execute_single_task(chain_task_id)
- if not success:
- print(f"主任务 {chain_task_id} 执行失败")
- return False
-
- # 获取子任务列表
- sub_tasks = self.db.get_sub_tasks(chain_task_id)
- if sub_tasks:
- print(f"\n开始执行主任务 {chain_task_id} 的子任务")
- # 按sequence_number排序子任务
- sub_tasks.sort(key=lambda x: x.get('sequence_number', 0))
-
- # 依次执行子任务
- for sub_task in sub_tasks:
- sub_task_id = sub_task['task_id']
- # 检查子任务是否启用
- if sub_task.get('enabled', False):
- print(f"\n执行子任务: {sub_task_id}")
- sub_success = await self._execute_single_task(sub_task_id, is_sub_task=True)
- if not sub_success:
- print(f"子任务 {sub_task_id} 执行失败")
- # 记录子任务失败但继续执行其他子任务
- continue
- else:
- print(f"子任务 {sub_task_id} 已禁用,跳过执行")
- continue
- else:
- # 执行普通任务
- success = await self._execute_single_task(chain_task_id)
- if not success:
- print(f"任务 {chain_task_id} 执行失败")
- return False
-
- print(f"\n任务链执行完成: {task_id}")
- return True
-
- except Exception as e:
- print(f"执行任务链时发生错误: {str(e)}")
- return False
- finally:
- # 清除当前任务链标记
- self.current_chain = None
-
- def find_next_task(self, current_task: str) -> Optional[str]:
- """查找下一个要执行的任务"""
- for task_name, task in self.tasks.items():
- if 'requires' in task and current_task in task['requires']:
- return task_name
- return None
-
- def schedule_tasks(self):
- """设置任务调度"""
- print("\n=== 开始设置任务调度 ===")
- now = datetime.now()
- print(f"当前时间: {now.strftime('%Y-%m-%d %H:%M:%S')}")
-
- # 先清除所有现有的调度任务
- schedule.clear()
- schedule.jobs.clear() # 确保完全清除所有任务
- print("已清除所有现有调度任务")
-
- # 重置所有任务的状态
- self.task_status.clear()
- print(f"当前已配置的任务: {list(self.tasks.keys())}")
-
- # 创建一个同步的执行函数
- def sync_execute_task(task_name):
- print(f"\n=== 调度器触发任务执行 ===")
- print(f"当前时间: {datetime.now().strftime('%Y-%m-%d %H:%M:%S')}")
- print(f"任务名称: {task_name}")
-
- # 获取或创建事件循环
- try:
- loop = asyncio.get_event_loop()
- except RuntimeError:
- loop = asyncio.new_event_loop()
- asyncio.set_event_loop(loop)
-
- # 在事件循环中执行异步任务
- try:
- # 创建任务并等待其完成
- task = loop.create_task(self.execute_task_chain(task_name))
- loop.run_until_complete(asyncio.gather(task))
- except Exception as e:
- print(f"执行任务时发生错误: {str(e)}")
- finally:
- # 如果我们创建了新的事件循环,需要关闭它
- if loop and not loop.is_running():
- loop.close()
-
- for task_name, task in self.tasks.items():
- print(f"\n--- 处理任务: {task_name} ---")
-
- # 打印任务详细信息
- print(f"任务配置: {task}")
-
- if task.get('schedule_type') == 'daily':
- # 获取任务的启用状态
- task_status = self.db.get_task_status(task_name)
- is_enabled = True
- if task_status and 'enabled' in task_status:
- is_enabled = bool(task_status['enabled'])
- print(f"任务状态: {'启用' if is_enabled else '禁用'}")
-
- # 只调度启用的任务
- if is_enabled:
- schedule_time = task.get('schedule_time')
- if not schedule_time:
- print(f"警告: 任务 {task_name} 没有设置调度时间")
- continue
-
- print(f"调度时间: {schedule_time}")
-
- # 计算下次执行时间
- next_run = self._calculate_next_run_time(schedule_time)
- if next_run:
- next_run_str = next_run.strftime('%Y-%m-%d %H:%M:%S')
- self.db.update_task_status(task_name, {'next_run_time': next_run_str})
- print(f"计算的下次执行时间: {next_run_str}")
- time_diff = (next_run - now).total_seconds() / 60
- print(f"距离现在: {time_diff:.1f} 分钟")
-
- # 使用schedule库设置任务
- try:
- # 确保时间格式正确
- if ':' not in schedule_time or len(schedule_time.split(':')) != 2:
- raise ValueError(f"时间格式不正确: {schedule_time}, 应为 HH:MM 格式")
-
- print(f"正在设置schedule任务...")
- # 使用同步函数包装异步执行
- job = schedule.every().day.at(schedule_time).do(
- sync_execute_task, task_name
- )
-
- # 验证任务是否已正确设置
- if job in schedule.jobs:
- print(f"任务已成功添加到调度队列")
- print(f"任务详情: {job}")
- if hasattr(job, 'next_run'):
- print(f"Schedule库计算的下次执行时间: {job.next_run.strftime('%Y-%m-%d %H:%M:%S')}")
- else:
- print(f"警告: 任务可能未成功添加到调度队列")
- except Exception as e:
- print(f"设置任务调度失败: {str(e)}")
- else:
- print(f"警告: 无法计算下次执行时间")
- else:
- print(f"任务已禁用,跳过调度")
- elif task.get('schedule_type') == 'once':
- # 检查任务是否已执行过
- task_status = self.db.get_task_status(task_name)
- if task_status and task_status.get('last_run_time'):
- print(f"一次性任务 {task_name} 已执行过,跳过")
- continue
-
- delay = task.get('schedule_delay', 0)
- print(f"设置一次性任务: {task_name}, {delay}秒后执行")
-
- # 使用同步函数包装异步执行
- def delayed_sync_execute(task_name, delay):
- import time
- print(f"等待{delay}秒后执行任务: {task_name}")
- time.sleep(delay)
- sync_execute_task(task_name)
-
- # 在新线程中执行延迟任务
- import threading
- thread = threading.Thread(
- target=delayed_sync_execute,
- args=(task_name, delay)
- )
- thread.daemon = True
- thread.start()
- elif task.get('schedule_type') == 'interval':
- # 获取任务的启用状态
- task_status = self.db.get_task_status(task_name)
- is_enabled = task.get('enabled', True)
- if task_status and 'enabled' in task_status:
- is_enabled = bool(task_status['enabled'])
- print(f"任务状态: {'启用' if is_enabled else '禁用'}")
-
- # 只调度启用的任务
- if is_enabled:
- interval_value = task.get('interval_value')
- interval_unit = task.get('interval_unit')
-
- if not interval_value or not interval_unit:
- print(f"警告: 任务 {task_name} 没有设置有效的间隔值或单位")
- continue
-
- print(f"间隔设置: 每 {interval_value} {interval_unit}")
-
- # 使用schedule库设置任务
- try:
- print(f"正在设置interval调度任务...")
-
- # 根据interval_unit选择合适的调度方法
- job = None
- if interval_unit == 'minutes':
- job = schedule.every(interval_value).minutes.do(sync_execute_task, task_name)
- elif interval_unit == 'hours':
- job = schedule.every(interval_value).hours.do(sync_execute_task, task_name)
- elif interval_unit == 'days':
- job = schedule.every(interval_value).days.do(sync_execute_task, task_name)
- elif interval_unit == 'weeks':
- job = schedule.every(interval_value).weeks.do(sync_execute_task, task_name)
- else:
- print(f"警告: 不支持的间隔单位: {interval_unit}")
- continue
-
- # 验证任务是否已正确设置
- if job in schedule.jobs:
- print(f"间隔任务已成功添加到调度队列")
- print(f"任务详情: {job}")
- if hasattr(job, 'next_run'):
- next_run = job.next_run
- print(f"Schedule库计算的下次执行时间: {next_run.strftime('%Y-%m-%d %H:%M:%S')}")
-
- # 更新数据库中的下次执行时间
- next_run_str = next_run.strftime('%Y-%m-%d %H:%M:%S')
- self.db.update_task_status(task_name, {'next_run_time': next_run_str})
-
- # 计算距离现在的时间
- time_diff = (next_run - now).total_seconds() / 60
- print(f"距离现在: {time_diff:.1f} 分钟")
- else:
- print(f"警告: 间隔任务可能未成功添加到调度队列")
- except Exception as e:
- print(f"设置间隔任务调度失败: {str(e)}")
- import traceback
- traceback.print_exc()
- else:
- print(f"间隔任务已禁用,跳过调度")
-
- # 打印最终的调度状态
- print("\n=== 当前调度状态 ===")
- if not schedule.jobs:
- print("没有已调度的任务")
- else:
- for job in schedule.jobs:
- print(f"- {job}")
- if hasattr(job, 'next_run') and job.next_run:
- time_diff = (job.next_run - now).total_seconds() / 60
- print(f" 下次执行时间: {job.next_run.strftime('%Y-%m-%d %H:%M:%S')}")
- print(f" 距离现在: {time_diff:.1f} 分钟")
-
- print("\n=== 任务调度设置完成 ===")
-
- def _calculate_next_run_time(self, time_str, allow_today=True):
- """计算下次执行时间"""
- try:
- hour, minute = map(int, time_str.split(':'))
- now = datetime.now()
- today_run_time = now.replace(hour=hour, minute=minute, second=0, microsecond=0)
- time_diff_minutes = (today_run_time - now).total_seconds() / 60
-
- if time_diff_minutes > 0:
- next_run = today_run_time
- else:
- from datetime import timedelta
- next_run = today_run_time + timedelta(days=1)
-
- return next_run
- except Exception as e:
- error_msg = f"计算下次执行时间失败: {str(e)}"
- logger.error(error_msg, exception=e)
- return None
-
- async def run_scheduler(self):
- """运行调度器"""
- print(f"\n=== 开始运行调度器 [{datetime.now().strftime('%Y-%m-%d %H:%M:%S')}] ===")
-
- # 重新加载配置并设置任务
- self.load_scheduler_config()
- schedule.clear()
- schedule.jobs.clear()
- self.task_status.clear()
- self.chain_status.clear()
- self.schedule_tasks()
-
- # 打印初始调度状态
- if schedule.jobs:
- print("\n当前已调度的任务:")
- for job in schedule.jobs:
- if hasattr(job, 'next_run') and job.next_run:
- print(f"- {job}")
- print(f" 下次执行时间: {job.next_run.strftime('%Y-%m-%d %H:%M:%S')}")
- else:
- print("\n没有已调度的任务")
-
- self.is_running = True
- last_check_minute = -1
-
- while self.is_running:
- try:
- now = datetime.now()
- current_minute = now.minute
-
- # 每分钟检查一次任务状态
- if current_minute != last_check_minute:
- last_check_minute = current_minute
- # 运行到期的任务
- schedule.run_pending()
-
- # 等待1秒
- await asyncio.sleep(1)
- except Exception as e:
- error_msg = f"调度器运行错误: {str(e)}"
- print(f"\n!!! 调度器错误: {error_msg}")
- logger.error(error_msg, exception=e)
-
- await asyncio.sleep(60) # 出错后等待60秒再重试
- self.reload_scheduler()
-
- def stop_scheduler(self):
- """停止调度器"""
- self.is_running = False
-
- # 关闭数据库连接
- if hasattr(self, 'db'):
- self.db.close()
-
- def reload_scheduler(self):
- """重新加载调度配置"""
- print("\n=== 重新加载调度配置 ===")
- print(f"当前时间: {datetime.now().strftime('%Y-%m-%d %H:%M:%S')}")
-
- # 清除所有现有的调度任务
- schedule.clear()
- schedule.jobs.clear() # 确保完全清除所有任务
- print("已清除所有现有调度任务")
-
- # 清除内部状态
- self.task_status.clear()
- self.chain_status.clear()
-
- # 重新加载配置
- self.load_scheduler_config()
-
- # 重新设置调度
- self.schedule_tasks()
-
- # 打印当前的调度状态
- print("\n当前调度状态:")
- for job in schedule.jobs:
- print(f"- {job}")
- if hasattr(job, 'next_run') and job.next_run:
- time_diff = (job.next_run - datetime.now()).total_seconds() / 60
- print(f" 下次执行时间: {job.next_run.strftime('%Y-%m-%d %H:%M:%S')}")
- print(f" 距离现在: {time_diff:.1f} 分钟")
-
- print("\n调度配置重新加载完成")
-
- def update_task_enabled_status(self, task_id: str, enabled: bool):
- """更新任务的启用状态并重新加载调度配置"""
- if task_id not in self.tasks:
- return False
-
- # 更新数据库中的任务状态
- self.db.update_task_status(task_id, {'enabled': 1 if enabled else 0})
-
- # 重新加载调度配置
- self.reload_scheduler()
-
- return True
-
- def update_task_schedule_time(self, task_id: str, new_time: str):
- """更新任务的调度时间"""
- print(f"\n=== 更新任务调度时间 ===")
- print(f"任务ID: {task_id}")
- print(f"新的调度时间: {new_time}")
-
- try:
- # 1. 检查任务是否存在
- if task_id not in self.tasks:
- print(f"错误: 任务 {task_id} 不存在")
- return False
-
- # 2. 验证时间格式
- try:
- datetime.strptime(new_time, "%H:%M")
- except ValueError:
- print(f"错误: 无效的时间格式 {new_time},应为 HH:MM")
- return False
-
- # 3. 更新内存中的任务配置
- print("更新内存中的任务配置...")
- self.tasks[task_id]['schedule']['time'] = new_time
-
- # 4. 保存到配置文件
- print("保存配置到文件...")
- self._save_config_to_file()
-
- # 5. 停止当前调度器
- print("停止当前调度器...")
- old_running = self.is_running
- self.is_running = False
- schedule.clear()
- schedule.jobs.clear()
-
- # 6. 重新加载配置
- print("重新加载配置...")
- self.load_scheduler_config()
-
- # 7. 重新设置所有任务的调度
- print("重新设置任务调度...")
- self.schedule_tasks()
-
- # 8. 恢复调度器状态
- print("恢复调度器状态...")
- self.is_running = old_running
-
- # 9. 检查新任务是否已正确设置
- print("\n=== 检查新的调度设置 ===")
- found = False
- now = datetime.now()
- for job in schedule.jobs:
- if task_id in str(job):
- found = True
- next_run = job.next_run
- time_diff = (next_run - now).total_seconds() / 60
- print(f"找到任务: {job}")
- print(f"下次执行时间: {next_run.strftime('%Y-%m-%d %H:%M:%S')}")
- print(f"距离现在: {time_diff:.1f} 分钟")
-
- if not found:
- print(f"警告: 未找到任务 {task_id} 的新调度设置")
- return False
-
- print("\n任务调度时间更新成功")
- return True
-
- except Exception as e:
- print(f"更新任务调度时间时发生错误: {str(e)}")
- return False
-
- def _save_config_to_file(self):
- """保存配置到文件"""
- try:
- # 使用utils中的公共函数获取配置文件路径
- config_path = get_config_path('scheduler_config.yaml')
-
- # 先读取现有配置,以保留其他设置
- with open(config_path, 'r', encoding='utf-8') as f:
- config = yaml.safe_load(f)
-
- # 更新任务配置
- config['tasks'] = self.tasks
-
- # 写回文件
- with open(config_path, 'w', encoding='utf-8') as f:
- yaml.dump(config, f, allow_unicode=True, default_flow_style=False)
-
- print(f"配置已保存到: {config_path}")
- return True
- except Exception as e:
- logger.error(f"保存配置文件失败: {str(e)}")
- raise
-
- def sync_execute_task(self, task_name):
- """同步执行任务的包装函数"""
- print(f"\n=== 同步执行任务: {task_name} ===")
- print(f"当前时间: {datetime.now().strftime('%Y-%m-%d %H:%M:%S')}")
-
- try:
- # 获取当前事件循环,如果没有则创建新的
- try:
- loop = asyncio.get_running_loop()
- except RuntimeError:
- loop = asyncio.new_event_loop()
- asyncio.set_event_loop(loop)
- should_close_loop = True
- else:
- should_close_loop = False
-
- # 在事件循环中执行任务
- try:
- # 创建任务并等待其完成
- if loop.is_running():
- try:
- # 如果循环已经在运行,使用asyncio.run_coroutine_threadsafe
- future = asyncio.run_coroutine_threadsafe(
- self.execute_task_chain(task_name),
- loop
- )
- result = future.result()
- except RuntimeError as re:
- # 处理"This event loop is already running"错误
- if "This event loop is already running" in str(re):
- print(f"执行任务时发生事件循环错误: {str(re)},任务将被跳过")
- # 记录错误
- self._record_task_failure(
- task_name,
- datetime.now().strftime('%Y-%m-%d %H:%M:%S'),
- f"事件循环错误: {str(re)}",
- "scheduler"
- )
- return False
- else:
- raise # 重新引发其他RuntimeError
- else:
- # 如果循环未运行,正常执行
- task = asyncio.ensure_future(self.execute_task_chain(task_name), loop=loop)
- result = loop.run_until_complete(task)
- return result
- finally:
- # 只关闭我们创建的事件循环
- if should_close_loop and not loop.is_running():
- loop.close()
- except Exception as e:
- print(f"执行任务时发生错误: {str(e)}")
- return False
-
- async def _execute_single_task(self, task_id: str, is_sub_task: bool = False) -> bool:
- """执行单个任务(主任务或子任务)"""
- print(f"\n=== 执行{'子' if is_sub_task else ''}任务: {task_id} ===")
-
- start_time = datetime.now()
- start_time_str = start_time.strftime('%Y-%m-%d %H:%M:%S')
- triggered_by = "manual" if not hasattr(self, 'current_chain') else f"chain:{self.current_chain}"
-
- try:
- task = None
- if is_sub_task:
- task = self.db.get_subtask_by_id(task_id)
- else:
- task = self.tasks.get(task_id)
-
- if not task:
- print(f"错误: {'子' if is_sub_task else ''}任务 {task_id} 不存在")
- self._record_task_failure(task_id, start_time_str, "任务不存在", triggered_by)
- return False
-
- # 确保base_url有协议前缀
- base_url = self.base_url
- if not base_url.startswith(('http://', 'https://')):
- base_url = f"http://{base_url}"
- print(f"警告: base_url未包含协议前缀,已自动添加http://前缀")
-
- # 构建完整URL
- endpoint = task['endpoint']
- if endpoint.startswith('/'):
- url = f"{base_url}{endpoint}"
- else:
- url = f"{base_url}/{endpoint}"
-
- print(f"请求URL: {url}")
- method = task.get('method', 'GET').upper()
- params = task.get('params', {})
- timeout = task.get('timeout', 300)
-
- # 强制将所有调度任务设置为内部API调用类型
- task['task_type'] = 'internal_api'
-
- # 从配置中获取API密钥
- try:
- config = load_config()
- api_security = config.get('server', {}).get('api_security', {})
- api_enabled = api_security.get('enabled', False)
- api_key = api_security.get('api_key', '')
-
- logger.info(f"API安全状态: enabled={api_enabled}, API密钥长度: {len(api_key) if api_key else 0}")
- print(f"API安全状态: enabled={api_enabled}, API密钥长度: {len(api_key) if api_key else 0}")
-
- # 检查任务类型是否是内部API调用
- task_type = task.get('task_type', '')
- logger.info(f"任务 {task_id} 类型: {task_type}")
- print(f"任务 {task_id} 类型: {task_type}")
-
- if task_type == 'internal_api':
- # 内部API调用不需要验证API密钥
- logger.info(f"任务 {task_id} 是内部API调用,跳过API密钥验证")
- print(f"任务 {task_id} 是内部API调用,跳过API密钥验证")
- headers = {'X-Internal-Call': 'true'}
- elif api_security.get('enabled', False):
- # 普通任务,添加API密钥
- api_key = api_security.get('api_key', '')
- headers = {'X-API-Key': api_key}
- logger.info(f"任务 {task_id} 已添加API密钥到请求头,密钥长度: {len(api_key)}")
- print(f"任务 {task_id} 已添加API密钥到请求头,密钥长度: {len(api_key)}")
- else:
- # API安全验证未启用
- headers = {}
- logger.info(f"API安全验证未启用,不添加API密钥")
- print(f"API安全验证未启用,不添加API密钥")
- except Exception as e:
- logger.error(f"获取API密钥失败: {str(e)}")
- print(f"获取API密钥失败: {str(e)}")
- headers = {}
-
- async with httpx.AsyncClient(timeout=timeout) as client:
- if method == 'GET':
- response = await client.get(url, params=params, headers=headers)
- else:
- response = await client.post(url, json=params, headers=headers)
-
- end_time = datetime.now()
- end_time_str = end_time.strftime('%Y-%m-%d %H:%M:%S')
- duration = (end_time - start_time).total_seconds()
-
- if response.status_code == 200:
- result = response.json()
- if result.get("status") == "success":
- print(f"任务 {task_id} 执行成功")
- self.task_status[task_id] = True
- self.db.record_task_execution_enhanced(
- task_id=task_id,
- start_time=start_time_str,
- end_time=end_time_str,
- duration=duration,
- status="success",
- triggered_by=triggered_by,
- output=str(result)
- )
- return True
- else:
- error_msg = result.get('message', '未知错误')
- print(f"任务 {task_id} 执行失败: {error_msg}")
- self._record_task_failure(task_id, start_time_str, error_msg, triggered_by)
- return False
- else:
- error_msg = f"请求失败: {response.status_code}"
- print(f"任务 {task_id} 请求失败: {response.status_code}")
- self._record_task_failure(task_id, start_time_str, error_msg, triggered_by)
- return False
-
- except Exception as e:
- error_msg = str(e)
- print(f"执行任务时发生错误: {error_msg}")
- self._record_task_failure(task_id, start_time_str, error_msg, triggered_by)
- return False
-
- def _record_task_failure(self, task_id, start_time_str, error_msg, triggered_by):
- """记录任务失败信息"""
- end_time = datetime.now()
- end_time_str = end_time.strftime('%Y-%m-%d %H:%M:%S')
- duration = (datetime.strptime(end_time_str, '%Y-%m-%d %H:%M:%S') -
- datetime.strptime(start_time_str, '%Y-%m-%d %H:%M:%S')).total_seconds()
-
- self.task_status[task_id] = False
- self.db.record_task_execution_enhanced(
- task_id=task_id,
- start_time=start_time_str,
- end_time=end_time_str,
- duration=duration,
- status="fail",
- error_message=error_msg,
- triggered_by=triggered_by
- )
-
- def _build_chain_from_task(self, task_id: str) -> List[str]:
- """根据任务ID构建执行链
-
- Args:
- task_id: 任务ID
-
- Returns:
- List[str]: 任务执行顺序列表
- """
- print(f"构建任务 {task_id} 的执行链")
-
- try:
- # 如果任务不存在,返回空列表
- if task_id not in self.tasks:
- print(f"任务 {task_id} 不存在")
- return []
-
- # 获取任务的依赖项
- dependencies = self.db.get_task_dependencies(task_id)
- print(f"任务 {task_id} 的依赖项: {dependencies}")
-
- # 如果没有依赖,只返回当前任务
- if not dependencies:
- print(f"任务 {task_id} 没有依赖项,返回单任务链")
- return [task_id]
-
- # 构建完整的执行链
- execution_chain = []
-
- # 首先添加所有依赖任务
- for dep in dependencies:
- # 递归构建依赖任务的执行链
- dep_chain = self._build_chain_from_task(dep)
- # 添加未包含的任务
- for task in dep_chain:
- if task not in execution_chain:
- execution_chain.append(task)
-
- # 最后添加当前任务
- if task_id not in execution_chain:
- execution_chain.append(task_id)
-
- print(f"任务 {task_id} 的执行链: {' -> '.join(execution_chain)}")
- return execution_chain
-
- except Exception as e:
- print(f"构建任务链时发生错误: {str(e)}")
- return [task_id] # 出错时至少返回当前任务
-
- def delete_main_task(self, task_id: str) -> bool:
- """删除主任务"""
- if task_id not in self.tasks:
- logger.warning(f"任务 {task_id} 不存在")
- return False
-
- result = self.db.delete_main_task(task_id)
- if result:
- # 从内存中删除任务
- self.tasks.pop(task_id, None)
- # 如果是每日任务,也从每日任务集合中删除
- self.daily_tasks.pop(task_id, None)
- # 重新构建任务链
- self._build_task_chains()
- logger.info(f"成功删除主任务: {task_id}")
- return True
-
- return False
-
- def _check_scheduled_tasks(self):
- """检查所有计划任务,执行到期的任务"""
- try:
- cursor = self.db.conn.cursor()
-
- # 获取所有启用的主任务
- cursor.execute("""
- SELECT task_id, name, endpoint, method, params, schedule_type,
- schedule_time, schedule_delay, interval_value, interval_unit,
- last_executed, last_status
- FROM main_tasks
- WHERE enabled = 1 AND task_type = 'main'
- """)
-
- tasks = cursor.fetchall()
- current_time = datetime.now()
-
- for task in tasks:
- task_id, name, endpoint, method, params, schedule_type, schedule_time, schedule_delay, interval_value, interval_unit, last_executed, last_status = task
-
- should_execute = False
-
- # 解析上次执行时间
- if last_executed:
- try:
- last_exec_time = datetime.fromisoformat(last_executed)
- except ValueError:
- last_exec_time = None
- else:
- last_exec_time = None
-
- # 检查是否应该执行
- if schedule_type == 'daily':
- # 每日任务
- if schedule_time and not self._is_executed_today(task_id):
- scheduled_time = self._parse_schedule_time(schedule_time)
- if scheduled_time and current_time.time() >= scheduled_time:
- should_execute = True
- logger.info(f"每日任务 '{task_id}' 达到执行时间 {schedule_time}")
-
- elif schedule_type == 'once':
- # 一次性任务
- if not last_executed and schedule_delay is not None:
- # 任务还未执行且设置了延迟
- creation_time = self._get_task_creation_time(task_id)
- if creation_time:
- scheduled_time = creation_time + timedelta(seconds=schedule_delay)
- if current_time >= scheduled_time:
- should_execute = True
- logger.info(f"一次性任务 '{task_id}' 达到执行时间")
-
- elif schedule_type == 'interval':
- # 间隔执行任务
- if interval_value is not None and interval_unit and last_exec_time:
- # 计算下次执行时间
- next_exec_time = self._calculate_next_interval_execution(
- last_exec_time, interval_value, interval_unit
- )
- if current_time >= next_exec_time:
- should_execute = True
- logger.info(f"间隔任务 '{task_id}' 达到执行时间 (每 {interval_value} {interval_unit})")
- elif interval_value is not None and interval_unit and not last_exec_time:
- # 间隔任务还未执行过,查看是否设置了初始延迟
- if schedule_delay is not None:
- creation_time = self._get_task_creation_time(task_id)
- if creation_time:
- scheduled_time = creation_time + timedelta(seconds=schedule_delay)
- if current_time >= scheduled_time:
- should_execute = True
- logger.info(f"间隔任务 '{task_id}' 首次执行 (每 {interval_value} {interval_unit})")
- else:
- # 获取任务创建时间,从创建时间开始计算第一次执行时间
- creation_time = self._get_task_creation_time(task_id)
- if creation_time:
- # 使用创建时间作为基准计算下次执行时间
- next_exec_time = self._calculate_next_interval_execution(
- creation_time, interval_value, interval_unit
- )
- if current_time >= next_exec_time:
- should_execute = True
- logger.info(f"间隔任务 '{task_id}' 首次执行时间到达 (每 {interval_value} {interval_unit})")
- else:
- logger.info(f"间隔任务 '{task_id}' 等待首次执行时间 {next_exec_time}")
-
- # 执行任务
- if should_execute:
- thread = threading.Thread(
- target=self._execute_task_wrapper,
- args=(task_id, name, endpoint, method, params),
- daemon=True
- )
- thread.start()
-
- return True
-
- except Exception as e:
- logger.error(f"检查计划任务出错: {str(e)}")
- return False
-
- def _calculate_next_interval_execution(self, last_exec_time, interval_value, interval_unit):
- """计算间隔任务的下次执行时间"""
- if not isinstance(interval_value, int) or interval_value <= 0:
- logger.warning(f"无效的间隔值: {interval_value}")
- return datetime.max # 返回一个极远的未来时间,防止任务被执行
-
- try:
- if interval_unit == 'minutes':
- return last_exec_time + timedelta(minutes=interval_value)
- elif interval_unit == 'hours':
- return last_exec_time + timedelta(hours=interval_value)
- elif interval_unit == 'days':
- return last_exec_time + timedelta(days=interval_value)
- elif interval_unit == 'weeks':
- return last_exec_time + timedelta(weeks=interval_value)
- elif interval_unit == 'months':
- # Python的timedelta没有months,手动计算
- year = last_exec_time.year
- month = last_exec_time.month + interval_value
-
- # 处理月份溢出
- while month > 12:
- month -= 12
- year += 1
-
- # 处理月份天数问题(例如,1月31日 + 1个月)
- day = min(last_exec_time.day, calendar.monthrange(year, month)[1])
-
- return last_exec_time.replace(year=year, month=month, day=day)
- elif interval_unit == 'years':
- # 处理闰年问题
- year = last_exec_time.year + interval_value
- month = last_exec_time.month
- day = min(last_exec_time.day, calendar.monthrange(year, month)[1])
-
- return last_exec_time.replace(year=year, day=day)
- else:
- logger.warning(f"不支持的间隔单位: {interval_unit}")
- return datetime.max
-
- except Exception as e:
- logger.error(f"计算下次执行时间出错: {str(e)}")
- return datetime.max
-
- def _get_task_creation_time(self, task_id: str) -> Optional[datetime]:
- """获取任务的创建时间"""
- try:
- cursor = self.db.conn.cursor()
- cursor.execute("SELECT created_at FROM main_tasks WHERE task_id = ?", (task_id,))
- row = cursor.fetchone()
-
- if row and row[0]:
- try:
- # 尝试解析ISO格式的时间字符串
- return datetime.fromisoformat(row[0].replace('Z', '+00:00'))
- except ValueError:
- # 如果不是ISO格式,尝试其他格式
- formats = [
- '%Y-%m-%d %H:%M:%S',
- '%Y-%m-%dT%H:%M:%S',
- '%Y-%m-%d %H:%M:%S.%f'
- ]
-
- for fmt in formats:
- try:
- return datetime.strptime(row[0], fmt)
- except ValueError:
- continue
-
- # 如果所有格式都不匹配,记录错误并返回当前时间
- logger.error(f"无法解析任务 {task_id} 的创建时间: {row[0]}")
- return datetime.now()
- else:
- logger.warning(f"未找到任务 {task_id} 的创建时间,使用当前时间")
- return datetime.now()
-
- except Exception as e:
- logger.error(f"获取任务创建时间出错: {str(e)}")
- return datetime.now()
-
- def _execute_task_wrapper(self, task_id, name, endpoint, method, params):
- """执行任务并更新下次执行时间(针对计划任务)"""
- print(f"\n=== 执行计划任务: {task_id} ===")
- print(f"当前时间: {datetime.now().strftime('%Y-%m-%d %H:%M:%S')}")
- print(f"任务名称: {name}")
- print(f"接口: {method} {endpoint}")
-
- try:
- # 记录任务开始执行
- start_time = datetime.now()
- start_time_str = start_time.strftime('%Y-%m-%d %H:%M:%S')
-
- # 获取任务配置,特别是计划类型
- task_config = self.db.get_main_task_by_id(task_id)
- if not task_config:
- print(f"错误: 任务 {task_id} 不存在")
- return
-
- schedule_type = task_config.get('schedule_type')
-
- # 执行任务
- try:
- # 使用异步方式执行任务
- loop = asyncio.new_event_loop()
- asyncio.set_event_loop(loop)
- task = loop.create_task(self.execute_task_chain(task_id))
- result = loop.run_until_complete(asyncio.gather(task))[0]
- loop.close()
-
- # 记录执行结果
- end_time = datetime.now()
- end_time_str = end_time.strftime('%Y-%m-%d %H:%M:%S')
- duration = (end_time - start_time).total_seconds()
-
- # 为interval类型的任务计算下次执行时间
- next_run_time = None
- if schedule_type == 'interval':
- interval_value = task_config.get('interval_value')
- interval_unit = task_config.get('interval_unit')
-
- if interval_value and interval_unit:
- try:
- # 使用end_time计算下次执行时间
- next_exec_time = self._calculate_next_interval_execution(
- end_time, interval_value, interval_unit
- )
- next_run_time = next_exec_time.strftime('%Y-%m-%d %H:%M:%S')
- logger.info(f"计算得到间隔任务下次执行时间: {next_run_time}")
-
- # 更新数据库中的下次执行时间
- self.db.update_task_status(task_id, {'next_run_time': next_run_time})
- print(f"已更新任务 {task_id} 的下次执行时间: {next_run_time}")
- except Exception as e:
- logger.error(f"计算间隔任务下次执行时间失败: {str(e)}")
-
- print(f"任务执行{'成功' if result else '失败'}")
-
- # 记录成功的执行结果
- if result:
- self.db.record_task_execution_enhanced(
- task_id=task_id,
- start_time=start_time_str,
- end_time=end_time_str,
- duration=duration,
- status="success",
- triggered_by="scheduler",
- next_run_time=next_run_time
- )
- else:
- self.db.record_task_execution_enhanced(
- task_id=task_id,
- start_time=start_time_str,
- end_time=end_time_str,
- duration=duration,
- status="fail",
- error_message="任务执行失败",
- triggered_by="scheduler",
- next_run_time=next_run_time
- )
-
- except Exception as e:
- error_msg = str(e)
- print(f"执行任务时出错: {error_msg}")
- traceback.print_exc()
-
- # 记录执行失败
- end_time = datetime.now()
- end_time_str = end_time.strftime('%Y-%m-%d %H:%M:%S')
- duration = (end_time - start_time).total_seconds()
-
- self.db.record_task_execution_enhanced(
- task_id=task_id,
- start_time=start_time_str,
- end_time=end_time_str,
- duration=duration,
- status="fail",
- error_message=error_msg,
- triggered_by="scheduler"
- )
-
- except Exception as e:
- print(f"执行任务包装器出错: {str(e)}")
- traceback.print_exc()
-
-async def send_error_notification(error_message):
- """发送错误通知邮件"""
- from scripts.send_log_email import send_email
- from scripts.apprise_notify import send_apprise_notification
-
- # 直接使用send_email函数,它会自动从配置文件加载邮件设置
-
- subject = "Bilibili历史记录分析任务执行出错"
- body = f"""
- 执行时间: {datetime.now().strftime('%Y-%m-%d %H:%M:%S')}
- 错误信息: {error_message}
- """
-
- try:
- await send_email(
- subject=subject,
- content=body
- )
- except Exception as e:
- print(f"发送错误通知邮件失败: {e}")
- logger.error(f"发送错误通知邮件失败: {e}", exception=e)
-
- try:
- apprise_result = await send_apprise_notification(title=subject, body=body)
- logger.info(f"任务错误 Apprise 通知结果: {apprise_result['message']}")
- except Exception as e:
- print(f"发送Apprise推送失败: {e}")
- logger.error(f"发送Apprise推送失败: {e}", exception=e)
diff --git a/scripts/send_log_email.py b/scripts/send_log_email.py
deleted file mode 100644
index 483bc19..0000000
--- a/scripts/send_log_email.py
+++ /dev/null
@@ -1,230 +0,0 @@
-import os
-import smtplib
-from datetime import datetime
-from email.header import Header
-from email.mime.multipart import MIMEMultipart
-from email.mime.text import MIMEText
-from typing import Optional, Dict
-
-from loguru import logger
-
-from scripts.utils import load_config, setup_logger, get_logs_path
-
-# 确保日志系统已初始化
-setup_logger()
-
-
-def get_task_execution_logs() -> str:
- """
- 获取最近一次计划任务执行期间的完整日志内容
-
- 从当前日志文件中查找最近一次任务执行的日志,
- 包含从任务开始到文件结尾的所有日志内容。
-
- Returns:
- str: 最近一次计划任务执行的完整日志内容,如果没有找到则返回提示信息
- """
- # 获取当前日志文件路径
- log_file = get_logs_path()
-
- # 检查日志文件是否存在
- if not os.path.exists(log_file):
- return "今日暂无日志记录"
-
- with open(log_file, 'r', encoding='utf-8') as f:
- log_lines = f.readlines()
-
- # 如果日志为空
- if not log_lines:
- return "今日暂无日志记录"
-
- # 查找最近一次计划任务执行的开始位置
- start_index = -1
- end_index = len(log_lines) # 默认到文件末尾
-
- # 计划任务开始的标记
- task_start_markers = [
- "=== 执行任务链:", # 主任务链开始
- "=== 执行任务:", # 单个任务开始
- "=== 调度器触发任务执行" # 调度器触发的任务
- ]
-
- # 从后向前查找最近的任务执行开始标记
- for i in range(len(log_lines) - 1, -1, -1):
- line = log_lines[i]
- if any(marker in line for marker in task_start_markers):
- start_index = i
- break
-
- # 如果找不到任务执行开始标记,则返回提示信息
- if start_index == -1:
- return "未找到任务执行记录"
-
- # 提取任务执行期间的日志 - 从开始标记一直到文件结束
- task_logs = log_lines[start_index:end_index]
- return "".join(task_logs)
-
-
-async def send_email(subject: str, content: Optional[str] = None, to_email: Optional[str] = None) -> Dict:
- """
- 发送邮件
-
- Args:
- subject: 邮件主题
- content: 邮件内容,如果为None则发送当天的任务执行日志
- to_email: 收件人邮箱,如果为None则使用配置文件中的默认收件人
-
- Returns:
- dict: 发送结果,包含status和message
- """
- logger.info(f"准备发送邮件: {subject}")
- try:
- config = load_config()
- email_config = config.get('email', {})
- smtp_server = email_config.get('smtp_server', 'smtp.qq.com')
- smtp_port = email_config.get('smtp_port', 587)
- sender_email = email_config.get('sender')
- auth_username = email_config.get('auth_username') or email_config.get('username') or sender_email
- sender_password = email_config.get('password')
- receiver_email = to_email or email_config.get('receiver')
-
- if not all([sender_email, sender_password, receiver_email]):
- logger.error("邮件配置不完整,请检查配置文件")
- raise ValueError("邮件配置不完整,请检查配置文件")
-
- # 如果没有提供内容,则获取任务执行期间的日志
- if content is None:
- content = get_task_execution_logs()
-
- # 格式化主题(替换时间占位符)
- current_time = datetime.now().strftime("%Y-%m-%d %H:%M:%S")
- subject = subject.format(current_time=current_time)
-
- # 创建邮件对象
- message = MIMEMultipart()
- message['From'] = Header(sender_email)
- message['To'] = Header(receiver_email)
- message['Subject'] = Header(subject)
-
- # 添加邮件内容
- message.attach(MIMEText(content, 'plain', 'utf-8'))
-
- # 连接SMTP服务器并发送
- server = None
- email_sent = False
-
- try:
- # 不使用 with 语句,以便更好地控制异常处理流程
- # 支持本地邮件服务和mailrise转发,自动检测SSL支持
- server = smtplib.SMTP(smtp_server, smtp_port, timeout=30)
-
- # 自动检测是否支持STARTTLS
- use_starttls = False
- try:
- # 先尝试使用STARTTLS(适用于QQ邮箱等标准SMTP服务)
- server.starttls()
- use_starttls = True
- logger.info("STARTTLS连接成功")
- except smtplib.SMTPNotSupportedError:
- # 如果服务器不支持STARTTLS(如本地mailrise),继续使用明文连接
- logger.info("服务器不支持STARTTLS,使用明文连接")
- except Exception as e:
- # 如果STARTTLS失败,尝试明文连接
- logger.warning(f"STARTTLS失败,尝试明文连接: {str(e)}")
-
- # 智能认证:先尝试认证,失败则判断是否需要认证
- try:
- # 直接尝试登录认证(适用于大部分标准SMTP服务器)
- server.login(auth_username, sender_password)
- logger.info("身份认证成功")
-
- except smtplib.SMTPNotSupportedError:
- # 服务器明确不支持认证
- logger.info("服务器不支持身份认证,跳过认证步骤")
-
- except smtplib.SMTPAuthenticationError as e:
- # 认证失败,可能是凭据错误或其他问题
- logger.error(f"身份认证失败: {str(e)}")
- raise Exception(f"身份认证失败: {str(e)}")
-
- except Exception as e:
- # 检查是否是"需要认证"的错误
- error_str = str(e).lower()
- if any(keyword in error_str for keyword in ['auth', 'authentication', 'login', 'need ehlo']):
- # 明确要求认证的错误,不应该跳过
- logger.error(f"服务器要求身份认证但认证失败: {str(e)}")
- raise Exception(f"服务器要求身份认证: {str(e)}")
- else:
- # 其他类型错误,可能是不需要认证的服务器
- logger.warning(f"认证过程出错,尝试无认证方式: {str(e)}")
-
- server.send_message(message)
- email_sent = True # 标记邮件已成功发送
-
- # 邮件发送成功后立即关闭连接
- server.quit()
-
- except smtplib.SMTPException as e:
- raise Exception(f"SMTP错误: {str(e)}")
- except TimeoutError:
- raise Exception("SMTP服务器连接超时")
- except Exception as e:
- # 如果发生任何异常,尝试安全关闭连接
- if server:
- try:
- server.quit()
- except:
- # 忽略关闭连接时的任何异常,因为主要异常更重要
- pass
- raise e
-
- # 如果执行到这里,说明邮件发送成功且连接正常关闭
- logger.info(f"邮件发送成功: {subject}")
- return {"status": "success", "message": "邮件发送成功"}
-
- except Exception as e:
- error_msg = f"邮件发送失败: {str(e)}"
- logger.error(f"邮件发送失败: {str(e)}")
-
- # 检查特定的错误情况,如 \x00\x00\x00,这可能表示邮件实际已发送
- if "\\x00\\x00\\x00" in str(e):
- logger.info("邮件可能已成功发送(出现特殊错误码但通常不影响邮件传递)")
- return {"status": "success", "message": "邮件可能已成功发送(出现特殊错误码但通常不影响邮件传递)"}
-
- return {"status": "error", "message": error_msg}
-
-def get_today_logs():
- """
- 获取今日全部日志内容
-
- 从当前日志文件获取所有日志行
-
- Returns:
- list: 今日的全部日志行
- """
- # 获取当前日志文件路径
- log_file = get_logs_path()
- logs = []
-
- # 检查今天的日志文件
- if os.path.exists(log_file):
- with open(log_file, 'r', encoding='utf-8') as f:
- logs = f.read().splitlines()
-
- return logs
-
-# 测试代码
-if __name__ == '__main__':
- import asyncio
-
- async def test_send():
- try:
- await send_email(
- subject="测试日志邮件",
- content=None # 测试发送当天的日志
- )
- print("测试邮件发送成功")
- except Exception as e:
- print(f"测试邮件发送失败: {e}")
-
- asyncio.run(test_send())
diff --git a/scripts/sync_db_json.py b/scripts/sync_db_json.py
deleted file mode 100644
index dc9cf73..0000000
--- a/scripts/sync_db_json.py
+++ /dev/null
@@ -1,474 +0,0 @@
-import json
-import logging
-import os
-import shutil
-import sqlite3
-from datetime import datetime
-
-# 配置日志
-# 确保输出目录存在
-os.makedirs("output/check", exist_ok=True)
-
-# 设置自定义的日志格式化器,以正确处理中文字符
-class EncodingFormatter(logging.Formatter):
- def format(self, record):
- msg = super().format(record)
- # 确保返回的是原始字符串,不会被转义
- if isinstance(msg, str):
- return msg
- else:
- return str(msg)
-
-# 配置日志处理程序
-formatter = EncodingFormatter('%(asctime)s - %(levelname)s - %(message)s')
-file_handler = logging.FileHandler("output/check/sync_db_json.log", mode='a', encoding='utf-8')
-file_handler.setFormatter(formatter)
-
-console_handler = logging.StreamHandler()
-console_handler.setFormatter(formatter)
-
-logger = logging.getLogger(__name__)
-logger.setLevel(logging.INFO)
-logger.handlers = [] # 清除可能存在的处理程序
-logger.addHandler(file_handler)
-logger.addHandler(console_handler)
-logger.propagate = False # 防止日志消息传播到根日志器
-
-
-def get_json_files(json_root_path):
- """获取所有JSON文件的路径"""
- json_files = []
-
- for year_dir in os.listdir(json_root_path):
- year_path = os.path.join(json_root_path, year_dir)
- if not os.path.isdir(year_path) or not year_dir.isdigit():
- continue
-
- for month_dir in os.listdir(year_path):
- month_path = os.path.join(year_path, month_dir)
- if not os.path.isdir(month_path) or not month_dir.isdigit():
- continue
-
- for day_file in os.listdir(month_path):
- if not day_file.endswith('.json'):
- continue
-
- day_path = os.path.join(month_path, day_file)
- json_files.append({
- 'path': day_path,
- 'year': int(year_dir),
- 'month': int(month_dir),
- 'day': int(day_file.split('.')[0])
- })
-
- return json_files
-
-
-def get_db_tables(db_path):
- """获取数据库中的所有表名"""
- try:
- conn = sqlite3.connect(db_path)
- cursor = conn.cursor()
- cursor.execute("SELECT name FROM sqlite_master WHERE type='table';")
- tables = [row[0] for row in cursor.fetchall()]
- conn.close()
- return tables
- except Exception as e:
- logger.error(f"获取数据库表时出错: {e}")
- return []
-
-
-def load_json_file(file_path):
- """读取JSON文件"""
- try:
- with open(file_path, 'r', encoding='utf-8') as f:
- return json.load(f)
- except Exception as e:
- logger.error(f"读取JSON文件 {file_path} 时出错: {e}")
- return []
-
-
-def save_json_file(file_path, data):
- """保存JSON文件"""
- try:
- # 确保目录存在
- os.makedirs(os.path.dirname(file_path), exist_ok=True)
-
- # 备份原文件(如果存在)
- if os.path.exists(file_path):
- backup_dir = os.path.join('output', 'check', 'backups')
- os.makedirs(backup_dir, exist_ok=True)
-
- file_name = os.path.basename(file_path)
- backup_path = os.path.join(backup_dir, f"{datetime.now().strftime('%Y%m%d%H%M%S')}_{file_name}")
- shutil.copy2(file_path, backup_path)
- logger.info(f"原文件已备份到 {backup_path}")
-
- # 保存新文件
- with open(file_path, 'w', encoding='utf-8') as f:
- json.dump(data, f, ensure_ascii=False, indent=4)
- logger.info(f"数据已保存到 {file_path}")
- return True
- except Exception as e:
- logger.error(f"保存JSON文件 {file_path} 时出错: {e}")
- return False
-
-
-def get_records_from_db(db_path, year, month, day):
- """从db中获取某天的所有记录并转换成JSON格式"""
- try:
- # 计算目标日期的时间戳范围
- start_date = datetime(year, month, day).timestamp()
- end_date = datetime(year, month, day, 23, 59, 59).timestamp()
-
- conn = sqlite3.connect(db_path)
- conn.row_factory = sqlite3.Row # 将结果转换为字典格式
- cursor = conn.cursor()
-
- # 获取当天所有记录
- table_name = f"bilibili_history_{year}"
- cursor.execute(f"""
- SELECT * FROM {table_name}
- WHERE view_at >= ? AND view_at <= ?
- ORDER BY view_at DESC
- """, (start_date, end_date))
-
- records = cursor.fetchall()
- records_list = [dict(record) for record in records]
- conn.close()
-
- # 将数据库记录转换为JSON格式
- json_records = []
- for record in records_list:
- json_record = {
- "title": record["title"],
- "long_title": record["long_title"],
- "cover": record["cover"],
- "covers": json.loads(record["covers"]) if record["covers"] else None,
- "uri": record["uri"],
- "history": {
- "oid": record["oid"],
- "epid": record["epid"],
- "bvid": record["bvid"],
- "page": record["page"],
- "cid": record["cid"],
- "part": record["part"],
- "business": record["business"],
- "dt": record["dt"]
- },
- "videos": record["videos"],
- "author_name": record["author_name"],
- "author_face": record["author_face"],
- "author_mid": record["author_mid"],
- "view_at": record["view_at"],
- "progress": record["progress"],
- "badge": record["badge"],
- "show_title": record["show_title"],
- "duration": record["duration"],
- "current": record["current"],
- "total": record["total"],
- "new_desc": record["new_desc"],
- "is_finish": record["is_finish"],
- "is_fav": record["is_fav"],
- "kid": record["kid"],
- "tag_name": record["tag_name"],
- "live_status": record["live_status"]
- }
- json_records.append(json_record)
-
- logger.info(f"从数据库中获取了 {len(json_records)} 条 {year}年{month}月{day}日的记录")
- return json_records
-
- except Exception as e:
- logger.error(f"从数据库获取记录时出错: {e}")
- return []
-
-
-def import_records_to_db(db_path, records, year):
- """将记录导入到数据库"""
- if not records:
- return 0
-
- try:
- conn = sqlite3.connect(db_path)
- cursor = conn.cursor()
-
- # 检查表是否存在
- table_name = f"bilibili_history_{year}"
- cursor.execute("SELECT name FROM sqlite_master WHERE type='table' AND name=?", (table_name,))
- if not cursor.fetchone():
- logger.error(f"数据库表 {table_name} 不存在")
- conn.close()
- return 0
-
- # 获取表结构
- cursor.execute(f"PRAGMA table_info({table_name})")
- columns = [column[1] for column in cursor.fetchall()]
-
- imported_count = 0
- for record in records:
- # 检查记录是否已存在
- view_at = record.get('view_at', 0)
- bvid = record.get('history', {}).get('bvid', '')
-
- cursor.execute(f"SELECT id FROM {table_name} WHERE view_at = ? AND bvid = ?", (view_at, bvid))
- if cursor.fetchone():
- logger.debug(f"记录已存在: {record.get('title')} ({bvid}, {view_at})")
- continue
-
- # 构建导入数据
- data = {
- "id": None, # 自增字段
- "title": record.get('title', ''),
- "long_title": record.get('long_title', ''),
- "cover": record.get('cover', ''),
- "covers": json.dumps(record.get('covers', [])),
- "uri": record.get('uri', ''),
- "oid": record.get('history', {}).get('oid', 0),
- "epid": record.get('history', {}).get('epid', 0),
- "bvid": record.get('history', {}).get('bvid', ''),
- "page": record.get('history', {}).get('page', 1),
- "cid": record.get('history', {}).get('cid', 0),
- "part": record.get('history', {}).get('part', ''),
- "business": record.get('history', {}).get('business', ''),
- "dt": record.get('history', {}).get('dt', 0),
- "videos": record.get('videos', 1),
- "author_name": record.get('author_name', ''),
- "author_face": record.get('author_face', ''),
- "author_mid": record.get('author_mid', 0),
- "view_at": view_at,
- "progress": record.get('progress', 0),
- "badge": record.get('badge', ''),
- "show_title": record.get('show_title', ''),
- "duration": record.get('duration', 0),
- "current": record.get('current', ''),
- "total": record.get('total', 0),
- "new_desc": record.get('new_desc', ''),
- "is_finish": record.get('is_finish', 0),
- "is_fav": record.get('is_fav', 0),
- "kid": record.get('kid', 0),
- "tag_name": record.get('tag_name', ''),
- "live_status": record.get('live_status', 0),
- "main_category": None # 默认为Null
- }
-
- # 生成SQL语句
- valid_columns = [col for col in data.keys() if col in columns]
- placeholders = ', '.join(['?' for _ in valid_columns])
- sql = f"INSERT INTO {table_name} ({', '.join(valid_columns)}) VALUES ({placeholders})"
-
- # 导入数据
- values = [data[col] for col in valid_columns]
- cursor.execute(sql, values)
- imported_count += 1
-
- conn.commit()
- conn.close()
- logger.info(f"成功导入 {imported_count} 条记录到表 {table_name}")
- return imported_count
-
- except Exception as e:
- logger.error(f"导入记录到数据库时出错: {e}")
- return 0
-
-
-def sync_json_to_db(db_path, json_root_path):
- """将JSON文件中的记录导入到数据库"""
- json_files = get_json_files(json_root_path)
- total_imported = 0
- synced_days = []
-
- for json_file in json_files:
- year, month, day = json_file['year'], json_file['month'], json_file['day']
- file_path = json_file['path']
-
- # 读取JSON文件
- json_records = load_json_file(file_path)
- if not json_records:
- continue
-
- # 导入记录到数据库
- imported_count = import_records_to_db(db_path, json_records, year)
- total_imported += imported_count
-
- if imported_count > 0:
- # 记录已导入的日期和标题信息
- imported_titles = [record.get('title', '未知标题') for record in json_records[:10]] # 最多记录10个标题
- synced_days.append({
- "date": f"{year}-{month:02d}-{day:02d}",
- "imported_count": imported_count,
- "source": "json_to_db",
- "titles": imported_titles if len(imported_titles) <= 10 else imported_titles[:10]
- })
- logger.info(f"从 {file_path} 导入了 {imported_count} 条记录到数据库")
-
- return total_imported, synced_days
-
-
-def sync_db_to_json(db_path, json_root_path):
- """将数据库中的记录导入到JSON文件"""
- # 获取数据库中的表名
- db_tables = get_db_tables(db_path)
- history_tables = [table for table in db_tables if table.startswith('bilibili_history_')]
-
- total_restored = 0
- synced_days = []
-
- # 获取JSON文件列表
- json_files = get_json_files(json_root_path)
- json_file_dict = {}
-
- # 构建日期的路径到文件的映射制式
- for file_info in json_files:
- key = f"{file_info['year']}-{file_info['month']}-{file_info['day']}"
- json_file_dict[key] = file_info['path']
-
- # 遍历数据库中的表
- for table in history_tables:
- year = int(table.split('_')[-1])
-
- try:
- conn = sqlite3.connect(db_path)
- cursor = conn.cursor()
-
- # 获取表中的不同日期的记录
- cursor.execute(f"""
- SELECT strftime('%Y-%m-%d', datetime(view_at, 'unixepoch')) as date_str,
- strftime('%Y', datetime(view_at, 'unixepoch')) as year,
- strftime('%m', datetime(view_at, 'unixepoch')) as month,
- strftime('%d', datetime(view_at, 'unixepoch')) as day
- FROM {table}
- GROUP BY date_str
- ORDER BY date_str
- """)
- dates = cursor.fetchall()
- conn.close()
-
- for date in dates:
- date_str, db_year, db_month, db_day = date
- db_year, db_month, db_day = int(db_year), int(db_month), int(db_day)
-
- # 构建日期的路径
- json_path = json_file_dict.get(date_str)
- if not json_path:
- # 如果日期的路径不存在,创建JSON文件
- json_path = os.path.join(json_root_path, str(db_year), f"{db_month:02d}", f"{db_day:02d}.json")
-
- # 从数据库中获取日期的记录
- db_records = get_records_from_db(db_path, db_year, db_month, db_day)
-
- # 如果日期的JSON文件存在,合成记录
- if os.path.exists(json_path):
- json_records = load_json_file(json_path)
-
- # 判除重复的记录
- existing_keys = set((record.get('view_at', 0), record.get('history', {}).get('bvid', ''))
- for record in json_records)
-
- # 获取数据库中的新记录
- new_records = []
- for db_record in db_records:
- key = (db_record.get('view_at', 0), db_record.get('history', {}).get('bvid', ''))
- if key not in existing_keys:
- new_records.append(db_record)
- existing_keys.add(key)
-
- # 合成记录
- if new_records:
- combined_records = json_records + new_records
- # 按时间进行排列
- combined_records.sort(key=lambda x: x.get('view_at', 0), reverse=True)
- if save_json_file(json_path, combined_records):
- # 记录同步信息
- titles = [record.get('title', '未知标题') for record in new_records[:10]]
- synced_days.append({
- "date": f"{db_year}-{db_month:02d}-{db_day:02d}",
- "imported_count": len(new_records),
- "source": "db_to_json",
- "titles": titles if len(titles) <= 10 else titles[:10]
- })
- logger.info(f"已新增 {json_path} 了 {len(new_records)} 条记录")
- total_restored += len(new_records)
- else:
- # 日期的JSON文件不存在,创建JSON文件
- if db_records and save_json_file(json_path, db_records):
- # 记录同步信息
- titles = [record.get('title', '未知标题') for record in db_records[:10]]
- synced_days.append({
- "date": f"{db_year}-{db_month:02d}-{db_day:02d}",
- "imported_count": len(db_records),
- "source": "db_to_json",
- "titles": titles if len(titles) <= 10 else titles[:10]
- })
- logger.info(f"已创建 {json_path} 了 {len(db_records)} 条记录")
- total_restored += len(db_records)
-
- except Exception as e:
- logger.error(f"将 {year} 年的数据库中的记录导入JSON文件时出错: {e}")
-
- return total_restored, synced_days
-
-
-def sync_data(db_path=None, json_root_path=None):
- """同步数据库和JSON文件的接口函数"""
- # 配置路径
- if db_path is None:
- db_path = os.path.join('output', 'bilibili_history.db')
- if json_root_path is None:
- json_root_path = os.path.join('output', 'history_by_date')
-
- # 创建,计算路径
- output_dir = os.path.join('output', 'check')
- os.makedirs(output_dir, exist_ok=True)
-
- logger.info("===== 开始同步数据库和不同的JSON文件 =====")
- logger.info(f"数据库路径: {db_path}")
- logger.info(f"JSON文件路径: {json_root_path}")
-
- # 1. 将JSON文件中的记录导入到数据库
- json_to_db_count, json_to_db_days = sync_json_to_db(db_path, json_root_path)
- logger.info(f"从JSON文件中获取了 {json_to_db_count} 条记录导入到数据库")
-
- # 2. 将数据库中的记录导入到JSON文件
- db_to_json_count, db_to_json_days = sync_db_to_json(db_path, json_root_path)
- logger.info(f"从数据库中获取了 {db_to_json_count} 条记录导入到JSON文件")
-
- # 合并同步天数信息
- all_synced_days = json_to_db_days + db_to_json_days
-
- # 按日期排序
- all_synced_days.sort(key=lambda x: x['date'], reverse=True)
-
- logger.info("===== 同步成功。 =====")
- logger.info(f"总条记录: 从JSON文件导入到数据库 {json_to_db_count} 条,从数据库导入到JSON文件 {db_to_json_count} 条")
-
- # 保存同步结果到JSON文件
- sync_result_file = os.path.join(output_dir, "sync_result.json")
- sync_result = {
- "success": True,
- "json_to_db_count": json_to_db_count,
- "db_to_json_count": db_to_json_count,
- "total_synced": json_to_db_count + db_to_json_count,
- "synced_days": all_synced_days,
- "timestamp": datetime.now().isoformat()
- }
-
- with open(sync_result_file, 'w', encoding='utf-8') as f:
- json.dump(sync_result, f, ensure_ascii=False, indent=4)
-
- logger.info(f"同步结果已保存到 {sync_result_file}")
-
- return sync_result
-
-
-def main():
- # 配置路径
- db_path = os.path.join('output', 'bilibili_history.db')
- json_root_path = os.path.join('output', 'history_by_date')
-
- sync_result = sync_data(db_path, json_root_path)
- print(f"同步完成,总共同步 {sync_result['total_synced']} 条记录")
-
-
-if __name__ == '__main__':
- main()
diff --git a/scripts/task_manager.py b/scripts/task_manager.py
deleted file mode 100644
index cb5dd99..0000000
--- a/scripts/task_manager.py
+++ /dev/null
@@ -1,238 +0,0 @@
-import os
-import sqlite3
-import sys
-import argparse
-from datetime import datetime
-
-def get_db_connection():
- """获取数据库连接"""
- # 使用相对路径,假设脚本在项目根目录或scripts目录下运行
- script_dir = os.path.dirname(os.path.abspath(__file__))
- project_root = os.path.dirname(script_dir) if os.path.basename(script_dir) == 'scripts' else script_dir
-
- db_path = os.path.join(project_root, 'output', 'database', 'scheduler.db')
-
- if not os.path.exists(db_path):
- print(f"错误: 数据库文件不存在: {db_path}")
- sys.exit(1)
-
- conn = sqlite3.connect(db_path)
- conn.row_factory = sqlite3.Row
- return conn
-
-def list_tasks():
- """列出所有任务及其状态"""
- conn = get_db_connection()
- cursor = conn.cursor()
-
- cursor.execute("""
- SELECT t.task_id, t.name, t.task_type, t.enabled, t.schedule_type, t.schedule_time,
- t.last_run_time, t.next_run_time, t.last_status,
- (SELECT GROUP_CONCAT(depends_on, ', ') FROM task_dependencies WHERE task_id = t.task_id) as dependencies
- FROM tasks t
- ORDER BY
- CASE t.task_type WHEN 'main' THEN 0 ELSE 1 END,
- t.parent_id,
- t.sequence_number
- """)
-
- tasks = cursor.fetchall()
-
- print("\n=== 任务列表 ===")
- print(f"总计 {len(tasks)} 个任务\n")
-
- # 打印所有主任务和它们的子任务
- main_tasks = [t for t in tasks if t['task_type'] == 'main']
- for main_task in main_tasks:
- print(f"【{main_task['task_id']}】({main_task['name']}) - " +
- f"{'启用' if main_task['enabled'] else '禁用'}")
- print(f" 类型: 主任务, 调度: {main_task['schedule_type']}")
-
- if main_task['schedule_time']:
- print(f" 执行时间: {main_task['schedule_time']}")
-
- print(f" 上次执行: {main_task['last_run_time'] or '未执行'}")
- print(f" 下次执行: {main_task['next_run_time'] or '未计划'}")
- print(f" 上次状态: {main_task['last_status'] or '未知'}")
-
- # 获取这个主任务的子任务
- sub_tasks = [t for t in tasks if t['task_type'] == 'sub' and t['dependencies'] and main_task['task_id'] in t['dependencies']]
-
- if sub_tasks:
- print("\n 子任务:")
- for idx, sub_task in enumerate(sub_tasks, 1):
- print(f" {idx}. {sub_task['task_id']} ({sub_task['name']}) - " +
- f"{'启用' if sub_task['enabled'] else '禁用'}")
-
- # 添加一个空行分隔不同的主任务
- print()
-
- conn.close()
-
-def enable_task(task_id, enable=True):
- """启用或禁用任务"""
- conn = get_db_connection()
- cursor = conn.cursor()
-
- # 检查任务是否存在
- cursor.execute("SELECT task_id, name, task_type, enabled FROM tasks WHERE task_id = ?", (task_id,))
- task = cursor.fetchone()
-
- if not task:
- print(f"错误: 任务 '{task_id}' 不存在")
- conn.close()
- return False
-
- current_status = bool(task['enabled'])
- if current_status == enable:
- print(f"任务 '{task_id}' 已经{'启用' if enable else '禁用'},无需更改")
- conn.close()
- return True
-
- # 更新任务状态
- now = datetime.now().isoformat()
- cursor.execute("""
- UPDATE tasks
- SET enabled = ?, last_modified = ?
- WHERE task_id = ?
- """, (1 if enable else 0, now, task_id))
-
- conn.commit()
- conn.close()
-
- print(f"任务 '{task_id}' ({task['name']}) 已{'启用' if enable else '禁用'}")
- return True
-
-def get_task_details(task_id):
- """获取任务详情"""
- conn = get_db_connection()
- cursor = conn.cursor()
-
- # 查询任务基本信息
- cursor.execute("""
- SELECT * FROM tasks WHERE task_id = ?
- """, (task_id,))
-
- task = cursor.fetchone()
-
- if not task:
- print(f"错误: 任务 '{task_id}' 不存在")
- conn.close()
- return False
-
- print(f"\n=== 任务详情: {task_id} ===")
- print(f"名称: {task['name']}")
- print(f"类型: {'主任务' if task['task_type'] == 'main' else '子任务'}")
- print(f"状态: {'启用' if task['enabled'] else '禁用'}")
- print(f"接口: {task['method']} {task['endpoint']}")
- print(f"调度类型: {task['schedule_type']}")
-
- if task['schedule_time']:
- print(f"调度时间: {task['schedule_time']}")
-
- if task['schedule_delay']:
- print(f"延迟时间: {task['schedule_delay']}秒")
-
- print(f"上次执行: {task['last_run_time'] or '未执行'}")
- print(f"下次执行: {task['next_run_time'] or '未计划'}")
- print(f"执行状态: {task['last_status'] or '未知'}")
- print(f"总执行次数: {task['total_runs']}")
- print(f"成功次数: {task['success_runs']}")
- print(f"失败次数: {task['fail_runs']}")
-
- if task['last_error']:
- print(f"最近错误: {task['last_error']}")
-
- # 查询依赖关系
- cursor.execute("""
- SELECT depends_on FROM task_dependencies WHERE task_id = ?
- """, (task_id,))
-
- dependencies = [row['depends_on'] for row in cursor.fetchall()]
-
- if dependencies:
- print(f"\n依赖任务: {', '.join(dependencies)}")
-
- # 查询被依赖关系
- cursor.execute("""
- SELECT task_id FROM task_dependencies WHERE depends_on = ?
- """, (task_id,))
-
- dependent_tasks = [row['task_id'] for row in cursor.fetchall()]
-
- if dependent_tasks:
- print(f"被依赖任务: {', '.join(dependent_tasks)}")
-
- # 如果是主任务,查询子任务
- if task['task_type'] == 'main':
- cursor.execute("""
- SELECT task_id, name, enabled, sequence_number
- FROM tasks
- WHERE parent_id = ?
- ORDER BY sequence_number
- """, (task_id,))
-
- subtasks = cursor.fetchall()
-
- if subtasks:
- print("\n子任务:")
- for idx, subtask in enumerate(subtasks, 1):
- print(f" {idx}. {subtask['task_id']} ({subtask['name']}) - " +
- f"{'启用' if subtask['enabled'] else '禁用'}")
-
- # 获取最近的执行记录
- cursor.execute("""
- SELECT * FROM task_executions
- WHERE task_id = ?
- ORDER BY start_time DESC
- LIMIT 5
- """, (task_id,))
-
- executions = cursor.fetchall()
-
- if executions:
- print("\n最近执行记录:")
- for idx, exec_record in enumerate(executions, 1):
- print(f" {idx}. 时间: {exec_record['start_time']}")
- print(f" 状态: {exec_record['status']}")
- print(f" 耗时: {exec_record['duration']}秒")
- if exec_record['error_message']:
- print(f" 错误: {exec_record['error_message']}")
-
- conn.close()
- return True
-
-def main():
- parser = argparse.ArgumentParser(description='任务管理工具')
- subparsers = parser.add_subparsers(dest='command', help='命令')
-
- # 列出所有任务
- list_parser = subparsers.add_parser('list', help='列出所有任务')
-
- # 启用任务
- enable_parser = subparsers.add_parser('enable', help='启用任务')
- enable_parser.add_argument('task_id', help='任务ID')
-
- # 禁用任务
- disable_parser = subparsers.add_parser('disable', help='禁用任务')
- disable_parser.add_argument('task_id', help='任务ID')
-
- # 获取任务详情
- details_parser = subparsers.add_parser('details', help='获取任务详情')
- details_parser.add_argument('task_id', help='任务ID')
-
- args = parser.parse_args()
-
- if args.command == 'list':
- list_tasks()
- elif args.command == 'enable':
- enable_task(args.task_id, True)
- elif args.command == 'disable':
- enable_task(args.task_id, False)
- elif args.command == 'details':
- get_task_details(args.task_id)
- else:
- parser.print_help()
-
-if __name__ == "__main__":
- main()
\ No newline at end of file
diff --git a/scripts/utils.py b/scripts/utils.py
index ddf7a75..c3387a4 100644
--- a/scripts/utils.py
+++ b/scripts/utils.py
@@ -1,5 +1,4 @@
import os
-import sqlite3
import sys
from datetime import datetime
from typing import Dict, Any
@@ -46,7 +45,7 @@ def setup_logger(log_level: str = "INFO") -> Dict:
logger.remove()
# 配置全局上下文信息
- logger.configure(extra={"app_name": "BilibiliHistoryFetcher", "version": "1.7.0"})
+ logger.configure(extra={"app_name": "HistoryHub", "version": "1.7.2"})
# 添加控制台处理器(仅INFO级别以上,只显示消息,无时间戳等)
logger.add(
@@ -163,14 +162,6 @@ def load_config() -> Dict[str, Any]:
with open(config_path, 'r', encoding='utf-8') as f:
config = yaml.safe_load(f)
- # 验证邮件配置
- email_config = config.get('email', {})
- required_fields = ['smtp_server', 'smtp_port', 'sender', 'password', 'receiver']
- missing_fields = [field for field in required_fields if not email_config.get(field)]
-
- if missing_fields:
- raise ValueError(f"邮件配置缺少必要字段: {', '.join(missing_fields)}")
-
return config
except Exception as e:
logger.error(f"加载配置文件失败: {str(e)}")
@@ -201,59 +192,3 @@ def get_output_path(*paths: str) -> str:
os.makedirs(os.path.dirname(full_path), exist_ok=True)
return full_path
-
-def get_database_path(*paths: str) -> str:
- """
- 获取数据库文件路径
- Args:
- *paths: 路径片段
- Returns:
- 完整的数据库路径
- """
- # 总是使用exe所在目录(或项目根目录)作为基础路径
- base_path = get_base_path()
-
- # 基础数据库目录
- database_dir = os.path.join(base_path, 'output', 'database')
-
- # 创建基础数据库目录
- if not os.path.exists(database_dir):
- os.makedirs(database_dir)
-
- # 组合完整路径
- full_path = os.path.join(database_dir, *paths)
-
- # 确保父目录存在
- parent_dir = os.path.dirname(full_path)
- if parent_dir != database_dir: # 避免重复创建database_dir
- os.makedirs(parent_dir, exist_ok=True)
-
- return full_path
-
-def get_logs_path() -> str:
- """
- 获取当前日期的日志文件路径
-
- 根据当前日期动态生成日志文件路径,与setup_logger函数中的动态路径格式保持一致
-
- Returns:
- str: 当前日期对应的日志文件路径
- """
- current_time = datetime.now()
- year = str(current_time.year)
- month = f"{current_time.month:02d}"
- day = f"{current_time.day:02d}"
-
- # 构建与setup_logger中动态路径格式一致的路径
- log_path = f"output/logs/{year}/{month}/{day}/{day}.log"
-
- # 确保日志目录存在
- log_dir = os.path.dirname(log_path)
- os.makedirs(log_dir, exist_ok=True)
-
- return log_path
-
-def get_db():
- """获取数据库连接"""
- db_path = get_database_path('bilibili_history.db')
- return sqlite3.connect(db_path)
diff --git a/scripts/wbi_sign.py b/scripts/wbi_sign.py
deleted file mode 100644
index f1312c1..0000000
--- a/scripts/wbi_sign.py
+++ /dev/null
@@ -1,190 +0,0 @@
-import hashlib
-import json
-import time
-import urllib.parse
-from typing import Dict, Any
-
-import requests
-
-# 混淆用的字符表
-MIXIN_KEY_ENC_TAB = [
- 46, 47, 18, 2, 53, 8, 23, 32, 15, 50, 10, 31, 58, 3, 45, 35, 27, 43, 5, 49,
- 33, 9, 42, 19, 29, 28, 14, 39, 12, 38, 41, 13, 37, 48, 7, 16, 24, 55, 40,
- 61, 26, 17, 0, 1, 60, 51, 30, 4, 22, 25, 54, 21, 56, 59, 6, 63, 57, 62, 11,
- 36, 20, 34, 44, 52
-]
-
-# 缓存的WBI密钥
-_cached_wbi_keys = {
- "img_key": "",
- "sub_key": "",
- "time": 0
-}
-
-def get_mixin_key(orig: str) -> str:
- """
- 对 imgKey 和 subKey 进行字符顺序打乱编码
- 取MIXIN_KEY_ENC_TAB中的前32个字符
- """
- mixed_key = ""
- for i in MIXIN_KEY_ENC_TAB:
- if i < len(orig):
- mixed_key += orig[i]
- return mixed_key[:32]
-
-def fetch_wbi_keys() -> Dict[str, str]:
- """
- 获取最新的 WBI 签名密钥
- """
- global _cached_wbi_keys
-
- # 检查缓存是否过期(1小时)
- current_time = int(time.time())
- if _cached_wbi_keys["time"] > 0 and current_time - _cached_wbi_keys["time"] < 3600:
- return {
- "img_key": _cached_wbi_keys["img_key"],
- "sub_key": _cached_wbi_keys["sub_key"]
- }
-
- try:
- # 从配置中读取SESSDATA
- from scripts.utils import load_config
- config = load_config()
- sessdata = config.get('SESSDATA', '')
-
- # 设置请求头,解决412错误,添加Cookie认证
- headers = {
- "User-Agent": "Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/91.0.4472.124 Safari/537.36",
- "Referer": "https://www.bilibili.com/"
- }
-
- # 如果有SESSDATA,添加到Cookie
- if sessdata:
- headers["Cookie"] = f"SESSDATA={sessdata}"
-
- # 从B站首页获取最新的 wbi_img 和 wbi_sub
- resp = requests.get(
- "https://api.bilibili.com/x/web-interface/nav",
- headers=headers,
- timeout=10
- )
- resp.raise_for_status()
- json_content = resp.json()
-
- if json_content["code"] != 0:
- raise Exception(f"获取WBI密钥失败: {json_content['message']}")
-
- img_url = json_content["data"]["wbi_img"]["img_url"]
- sub_url = json_content["data"]["wbi_img"]["sub_url"]
-
- img_key = img_url.split("/")[-1].split(".")[0]
- sub_key = sub_url.split("/")[-1].split(".")[0]
-
- # 更新缓存
- _cached_wbi_keys = {
- "img_key": img_key,
- "sub_key": sub_key,
- "time": current_time
- }
-
- return {
- "img_key": img_key,
- "sub_key": sub_key
- }
- except Exception as e:
- print(f"获取WBI密钥时出错: {e}")
- # 如果有缓存,返回缓存的密钥
- if _cached_wbi_keys["img_key"] and _cached_wbi_keys["sub_key"]:
- return {
- "img_key": _cached_wbi_keys["img_key"],
- "sub_key": _cached_wbi_keys["sub_key"]
- }
- # 否则返回空值
- return {"img_key": "", "sub_key": ""}
-
-def get_wbi_sign(params: Dict[str, Any]) -> Dict[str, Any]:
- """
- 对参数进行 WBI 签名
- """
- # 获取 WBI 密钥
- keys = fetch_wbi_keys()
- img_key, sub_key = keys["img_key"], keys["sub_key"]
-
- # 如果获取密钥失败,返回原始参数
- if not img_key or not sub_key:
- print("获取WBI密钥失败,返回未签名的参数")
- return params
-
- # 返回签名后的参数
- return enc_wbi(params, img_key, sub_key)
-
-def enc_wbi(params: Dict[str, Any], img_key: str, sub_key: str) -> Dict[str, Any]:
- """
- 为请求参数进行 wbi 签名
- """
- # 合并密钥并进行混淆
- mixin_key = get_mixin_key(img_key + sub_key)
-
- # 添加 wts 参数(当前时间戳)
- params_with_wts = dict(params)
- curr_time = int(time.time())
- params_with_wts["wts"] = curr_time
-
- # 按照参数名排序
- params_sorted = dict(sorted(params_with_wts.items()))
-
- # 过滤 value 中的 "!'()*" 字符
- filtered_params = {}
- for k, v in params_sorted.items():
- filtered_value = str(v)
- for char in "!'()*":
- filtered_value = filtered_value.replace(char, '')
- filtered_params[k] = filtered_value
-
- # 构造待签名的字符串
- query = urllib.parse.urlencode(filtered_params)
-
- # 计算 w_rid
- w_rid = hashlib.md5((query + mixin_key).encode()).hexdigest()
-
- # 添加签名参数
- result_params = dict(params)
- result_params["wts"] = curr_time
- result_params["w_rid"] = w_rid
-
- return result_params
-
-# 测试函数
-if __name__ == "__main__":
- # 测试参数
- test_params = {
- "bvid": "BV1L94y1H7CV",
- "cid": 1335073288,
- "up_mid": 297242063
- }
-
- # 获取签名后的参数
- signed_params = get_wbi_sign(test_params)
-
- print("原始参数:", test_params)
- print("签名后的参数:", signed_params)
-
- # 测试请求
- url = "https://api.bilibili.com/x/web-interface/view/conclusion/get"
-
- # 添加请求头
- headers = {
- "User-Agent": "Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/91.0.4472.124 Safari/537.36",
- "Referer": "https://www.bilibili.com/"
- }
-
- response = requests.get(url, params=signed_params, headers=headers)
-
- print("\n请求URL:", response.url)
- print("响应状态码:", response.status_code)
-
- try:
- data = response.json()
- print("响应内容:", json.dumps(data, ensure_ascii=False, indent=2))
- except:
- print("响应内容解析失败:", response.text)
\ No newline at end of file
diff --git a/scripts/yutto_runner.py b/scripts/yutto_runner.py
deleted file mode 100644
index 2cd7fbb..0000000
--- a/scripts/yutto_runner.py
+++ /dev/null
@@ -1,57 +0,0 @@
-import asyncio
-import io
-import sys
-from typing import AsyncGenerator
-
-from yutto.__main__ import main as _YUTTO_MAIN
-
-class _AsyncWriter(io.StringIO):
- """自定义的 StringIO:每次 write 时立即通过 Queue 推送到事件循环"""
- def __init__(self, queue: asyncio.Queue[str | None], loop: asyncio.AbstractEventLoop):
- super().__init__()
- self._queue = queue
- self._loop = loop
-
- def write(self, s: str) -> int:
- """重写 write,每写一次就把内容丢到 Queue"""
- if s:
- self._loop.call_soon_threadsafe(self._queue.put_nowait, s)
- return len(s)
-
-
-async def run_yutto(argv: list[str]) -> AsyncGenerator[str, None]:
- """在当前进程内执行 yutto CLI,实时产出 SSE 数据"""
- loop = asyncio.get_running_loop()
- queue: asyncio.Queue[str | None] = asyncio.Queue()
-
- # 临时接管 stdout / stderr
- stdout_backup, stderr_backup = sys.stdout, sys.stderr
- sys.stdout = _AsyncWriter(queue, loop)
- sys.stderr = _AsyncWriter(queue, loop)
-
- # 在线程池执行同步的 yutto.main
- def _worker():
- # 伪装 sys.argv
- argv_backup = sys.argv
- sys.argv = ["yutto", *argv, '--no-color']
- try:
- _YUTTO_MAIN() # 进入 yutto 的主函数
- except SystemExit: # yutto 内部可能调用 sys.exit()
- pass
- finally:
- sys.argv = argv_backup
- # 通知协程:任务结束
- loop.call_soon_threadsafe(queue.put_nowait, None)
-
- # 把 _worker 丢进默认线程池,避免阻塞事件循环
- loop.run_in_executor(None, _worker)
-
- # 异步迭代 queue,并包装成 SSE
- while True:
- line = await queue.get()
- if line is None: # 收到结束标记
- break
- yield f"data: {line.rstrip()}\n\n"
-
- # 恢复 stdout / stderr
- sys.stdout, sys.stderr = stdout_backup, stderr_backup
diff --git a/skills/bilibili-history-mcp/SKILL.md b/skills/bilibili-history-mcp/SKILL.md
deleted file mode 100644
index cafb03b..0000000
--- a/skills/bilibili-history-mcp/SKILL.md
+++ /dev/null
@@ -1,27 +0,0 @@
----
-name: bilibili-history-mcp
-description: Use when an AI client needs to read BilibiliHistoryFetcher data through its read-only LAN MCP server without loading the full project context.
----
-
-# Bilibili History MCP
-
-Use the project's MCP server instead of reading files directly when the user asks for local Bilibili history, yearly reports, viewing analytics, interaction records, video details, scheduler status, or data health.
-
-## Start Here
-
-1. Read `bili://project/overview`.
-2. Read `bili://project/data-status`.
-3. Read `bili://project/tool-guide` only when choosing a tool is unclear.
-
-## Tool Rules
-
-- Prefer summary tools before record tools.
-- Always paginate record tools; keep `size` small unless the user asks for bulk analysis.
-- Use `query_history_records` for browsing and `search_history_records` for keyword lookup.
-- Use `get_annual_summary`, `get_viewing_analytics`, and `get_title_analytics` for analysis.
-- Use `query_interaction_records` only after `get_interaction_summary` when details are needed.
-- Do not ask for write operations; this MCP intentionally does not expose sync, fetch, download, delete, login, reset, or config update.
-
-## Privacy
-
-The MCP is LAN HTTP with Bearer Token auth. Treat returned watch history as private user data. Do not request secrets such as SESSDATA, bili_jct, email passwords, or config tokens.
diff --git a/tests/test_send_log_email.py b/tests/test_send_log_email.py
deleted file mode 100644
index 27be161..0000000
--- a/tests/test_send_log_email.py
+++ /dev/null
@@ -1,81 +0,0 @@
-import asyncio
-import smtplib
-import unittest
-from unittest.mock import patch
-
-import scripts.send_log_email as email_mod
-from routers.email_config import update_yaml_field
-
-
-class FakeSMTP:
- login_calls = []
-
- def __init__(self, server, port, timeout=30):
- self.server = server
- self.port = port
- self.timeout = timeout
-
- def starttls(self):
- return None
-
- def login(self, username, password):
- self.__class__.login_calls.append((username, password))
-
- def send_message(self, message):
- self.message = message
-
- def quit(self):
- return None
-
-
-class SendEmailAuthUsernameTests(unittest.TestCase):
- def setUp(self):
- FakeSMTP.login_calls = []
-
- def run_send_email_with_config(self, email_config):
- config = {"email": email_config}
- with patch.object(email_mod.smtplib, "SMTP", FakeSMTP), patch.object(email_mod, "load_config", lambda: config):
- return asyncio.run(email_mod.send_email("test", "body"))
-
- def test_uses_configured_auth_username_when_present(self):
- result = self.run_send_email_with_config(
- {
- "smtp_server": "smtp.example.test",
- "smtp_port": 587,
- "sender": "from@example.com",
- "auth_username": "smtp-auth-user",
- "password": "secret",
- "receiver": "to@example.com",
- }
- )
-
- self.assertEqual(result["status"], "success")
- self.assertEqual(FakeSMTP.login_calls, [("smtp-auth-user", "secret")])
-
- def test_falls_back_to_sender_for_qq_style_config(self):
- result = self.run_send_email_with_config(
- {
- "smtp_server": "smtp.qq.com",
- "smtp_port": 587,
- "sender": "user@qq.com",
- "password": "authorization-code",
- "receiver": "to@example.com",
- }
- )
-
- self.assertEqual(result["status"], "success")
- self.assertEqual(FakeSMTP.login_calls, [("user@qq.com", "authorization-code")])
-
-
-class EmailConfigYamlUpdateTests(unittest.TestCase):
- def test_inserts_missing_nested_email_field(self):
- content = """email:\n smtp_server: smtp.qq.com\n smtp_port: 587\n sender: \"user@qq.com\"\n password: \"secret\"\n receiver: \"to@example.com\"\n\nlog_folder: logs\n"""
-
- updated = update_yaml_field(content, ["email", "auth_username"], '"smtp-auth-user"')
-
- self.assertIn(' auth_username: "smtp-auth-user"', updated)
- self.assertLess(updated.index(" auth_username:"), updated.index("log_folder:"))
-
-
-if __name__ == "__main__":
- unittest.main()
diff --git a/uv.lock b/uv.lock
index 83d4212..0bfea2b 100644
--- a/uv.lock
+++ b/uv.lock
@@ -1,5 +1,5 @@
version = 1
-revision = 3
+revision = 2
requires-python = ">=3.10"
resolution-markers = [
"python_full_version >= '3.12'",
@@ -7,118 +7,6 @@ resolution-markers = [
"python_full_version < '3.11'",
]
-[[package]]
-name = "aiofiles"
-version = "24.1.0"
-source = { registry = "https://pypi.org/simple" }
-sdist = { url = "https://files.pythonhosted.org/packages/0b/03/a88171e277e8caa88a4c77808c20ebb04ba74cc4681bf1e9416c862de237/aiofiles-24.1.0.tar.gz", hash = "sha256:22a075c9e5a3810f0c2e48f3008c94d68c65d763b9b03857924c99e57355166c", size = 30247, upload-time = "2024-06-24T11:02:03.584Z" }
-wheels = [
- { url = "https://files.pythonhosted.org/packages/a5/45/30bb92d442636f570cb5651bc661f52b610e2eec3f891a5dc3a4c3667db0/aiofiles-24.1.0-py3-none-any.whl", hash = "sha256:b4ec55f4195e3eb5d7abd1bf7e061763e864dd4954231fb8539a0ef8bb8260e5", size = 15896, upload-time = "2024-06-24T11:02:01.529Z" },
-]
-
-[[package]]
-name = "aiohappyeyeballs"
-version = "2.6.1"
-source = { registry = "https://pypi.org/simple" }
-sdist = { url = "https://files.pythonhosted.org/packages/26/30/f84a107a9c4331c14b2b586036f40965c128aa4fee4dda5d3d51cb14ad54/aiohappyeyeballs-2.6.1.tar.gz", hash = "sha256:c3f9d0113123803ccadfdf3f0faa505bc78e6a72d1cc4806cbd719826e943558", size = 22760, upload-time = "2025-03-12T01:42:48.764Z" }
-wheels = [
- { url = "https://files.pythonhosted.org/packages/0f/15/5bf3b99495fb160b63f95972b81750f18f7f4e02ad051373b669d17d44f2/aiohappyeyeballs-2.6.1-py3-none-any.whl", hash = "sha256:f349ba8f4b75cb25c99c5c2d84e997e485204d2902a9597802b0371f09331fb8", size = 15265, upload-time = "2025-03-12T01:42:47.083Z" },
-]
-
-[[package]]
-name = "aiohttp"
-version = "3.11.16"
-source = { registry = "https://pypi.org/simple" }
-dependencies = [
- { name = "aiohappyeyeballs" },
- { name = "aiosignal" },
- { name = "async-timeout", marker = "python_full_version < '3.11'" },
- { name = "attrs" },
- { name = "frozenlist" },
- { name = "multidict" },
- { name = "propcache" },
- { name = "yarl" },
-]
-sdist = { url = "https://files.pythonhosted.org/packages/f1/d9/1c4721d143e14af753f2bf5e3b681883e1f24b592c0482df6fa6e33597fa/aiohttp-3.11.16.tar.gz", hash = "sha256:16f8a2c9538c14a557b4d309ed4d0a7c60f0253e8ed7b6c9a2859a7582f8b1b8", size = 7676826, upload-time = "2025-04-02T02:17:44.74Z" }
-wheels = [
- { url = "https://files.pythonhosted.org/packages/b8/21/6bd4cb580a323b64cda3b11fcb3f68deba77568e97806727a858de57349d/aiohttp-3.11.16-cp310-cp310-macosx_10_9_universal2.whl", hash = "sha256:fb46bb0f24813e6cede6cc07b1961d4b04f331f7112a23b5e21f567da4ee50aa", size = 708259, upload-time = "2025-04-02T02:15:15.439Z" },
- { url = "https://files.pythonhosted.org/packages/96/8c/7b4b9debe90ffc31931b85ee8612a5c83f34d8fdc6d90ee3eb27b43639e4/aiohttp-3.11.16-cp310-cp310-macosx_10_9_x86_64.whl", hash = "sha256:54eb3aead72a5c19fad07219acd882c1643a1027fbcdefac9b502c267242f955", size = 468886, upload-time = "2025-04-02T02:15:17.025Z" },
- { url = "https://files.pythonhosted.org/packages/13/da/a7fcd68e62acacf0a1930060afd2c970826f989265893082b6fb9eb25cb5/aiohttp-3.11.16-cp310-cp310-macosx_11_0_arm64.whl", hash = "sha256:38bea84ee4fe24ebcc8edeb7b54bf20f06fd53ce4d2cc8b74344c5b9620597fd", size = 455846, upload-time = "2025-04-02T02:15:18.662Z" },
- { url = "https://files.pythonhosted.org/packages/5d/12/b73d9423253f4c872d276a3771decb0722cb5f962352593bd617445977ba/aiohttp-3.11.16-cp310-cp310-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:d0666afbe984f6933fe72cd1f1c3560d8c55880a0bdd728ad774006eb4241ecd", size = 1587183, upload-time = "2025-04-02T02:15:20.048Z" },
- { url = "https://files.pythonhosted.org/packages/75/d3/291b57d54719d996e6cb8c1db8b13d01bdb24dca90434815ac7e6a70393f/aiohttp-3.11.16-cp310-cp310-manylinux_2_17_ppc64le.manylinux2014_ppc64le.whl", hash = "sha256:7ba92a2d9ace559a0a14b03d87f47e021e4fa7681dc6970ebbc7b447c7d4b7cd", size = 1634937, upload-time = "2025-04-02T02:15:22.156Z" },
- { url = "https://files.pythonhosted.org/packages/be/85/4229eba92b433173065b0b459ab677ca11ead4a179f76ccfe55d8738b188/aiohttp-3.11.16-cp310-cp310-manylinux_2_17_s390x.manylinux2014_s390x.whl", hash = "sha256:3ad1d59fd7114e6a08c4814983bb498f391c699f3c78712770077518cae63ff7", size = 1667980, upload-time = "2025-04-02T02:15:23.843Z" },
- { url = "https://files.pythonhosted.org/packages/2b/0d/d2423936962e3c711fafd5bb9172a99e6b07dd63e086515aa957d8a991fd/aiohttp-3.11.16-cp310-cp310-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:98b88a2bf26965f2015a771381624dd4b0839034b70d406dc74fd8be4cc053e3", size = 1590365, upload-time = "2025-04-02T02:15:25.809Z" },
- { url = "https://files.pythonhosted.org/packages/ea/93/04209affc20834982c1ef4214b1afc07743667998a9975d69413e9c1e1c1/aiohttp-3.11.16-cp310-cp310-manylinux_2_5_i686.manylinux1_i686.manylinux_2_17_i686.manylinux2014_i686.whl", hash = "sha256:576f5ca28d1b3276026f7df3ec841ae460e0fc3aac2a47cbf72eabcfc0f102e1", size = 1547614, upload-time = "2025-04-02T02:15:27.544Z" },
- { url = "https://files.pythonhosted.org/packages/f6/fb/194ad4e4cae98023ae19556e576347f402ce159e80d74cc0713d460c4a39/aiohttp-3.11.16-cp310-cp310-musllinux_1_2_aarch64.whl", hash = "sha256:a2a450bcce4931b295fc0848f384834c3f9b00edfc2150baafb4488c27953de6", size = 1532815, upload-time = "2025-04-02T02:15:28.985Z" },
- { url = "https://files.pythonhosted.org/packages/33/6d/a4da7adbac90188bf1228c73b6768a607dd279c146721a9ff7dcb75c5ac6/aiohttp-3.11.16-cp310-cp310-musllinux_1_2_armv7l.whl", hash = "sha256:37dcee4906454ae377be5937ab2a66a9a88377b11dd7c072df7a7c142b63c37c", size = 1559005, upload-time = "2025-04-02T02:15:30.406Z" },
- { url = "https://files.pythonhosted.org/packages/7e/88/2fa9fbfd23fc16cb2cfdd1f290343e085e7e327438041e9c6aa0208a854d/aiohttp-3.11.16-cp310-cp310-musllinux_1_2_i686.whl", hash = "sha256:4d0c970c0d602b1017e2067ff3b7dac41c98fef4f7472ec2ea26fd8a4e8c2149", size = 1535231, upload-time = "2025-04-02T02:15:32.468Z" },
- { url = "https://files.pythonhosted.org/packages/f5/8f/9623cd2558e3e182d02dcda8b480643e1c48a0550a86e3050210e98dba27/aiohttp-3.11.16-cp310-cp310-musllinux_1_2_ppc64le.whl", hash = "sha256:004511d3413737700835e949433536a2fe95a7d0297edd911a1e9705c5b5ea43", size = 1609985, upload-time = "2025-04-02T02:15:33.899Z" },
- { url = "https://files.pythonhosted.org/packages/f8/a2/53a8d1bfc67130710f1c8091f623cdefe7f85cd5d09e14637ed2ed6e1a6d/aiohttp-3.11.16-cp310-cp310-musllinux_1_2_s390x.whl", hash = "sha256:c15b2271c44da77ee9d822552201180779e5e942f3a71fb74e026bf6172ff287", size = 1628842, upload-time = "2025-04-02T02:15:35.396Z" },
- { url = "https://files.pythonhosted.org/packages/49/3a/35fb43d07489573c6c1f8c6a3e6c657196124a63223705b7feeddaea06f1/aiohttp-3.11.16-cp310-cp310-musllinux_1_2_x86_64.whl", hash = "sha256:ad9509ffb2396483ceacb1eee9134724443ee45b92141105a4645857244aecc8", size = 1566929, upload-time = "2025-04-02T02:15:36.863Z" },
- { url = "https://files.pythonhosted.org/packages/d5/82/bb3f4f2cc7677e790ba4c040db7dd8445c234a810ef893a858e217647d38/aiohttp-3.11.16-cp310-cp310-win32.whl", hash = "sha256:634d96869be6c4dc232fc503e03e40c42d32cfaa51712aee181e922e61d74814", size = 416935, upload-time = "2025-04-02T02:15:38.337Z" },
- { url = "https://files.pythonhosted.org/packages/df/ad/a64db1c18063569d6dff474c46a7d4de7ab85ff55e2a35839b149b1850ea/aiohttp-3.11.16-cp310-cp310-win_amd64.whl", hash = "sha256:938f756c2b9374bbcc262a37eea521d8a0e6458162f2a9c26329cc87fdf06534", size = 442168, upload-time = "2025-04-02T02:15:39.757Z" },
- { url = "https://files.pythonhosted.org/packages/b1/98/be30539cd84260d9f3ea1936d50445e25aa6029a4cb9707f3b64cfd710f7/aiohttp-3.11.16-cp311-cp311-macosx_10_9_universal2.whl", hash = "sha256:8cb0688a8d81c63d716e867d59a9ccc389e97ac7037ebef904c2b89334407180", size = 708664, upload-time = "2025-04-02T02:15:41.433Z" },
- { url = "https://files.pythonhosted.org/packages/e6/27/d51116ce18bdfdea7a2244b55ad38d7b01a4298af55765eed7e8431f013d/aiohttp-3.11.16-cp311-cp311-macosx_10_9_x86_64.whl", hash = "sha256:0ad1fb47da60ae1ddfb316f0ff16d1f3b8e844d1a1e154641928ea0583d486ed", size = 468953, upload-time = "2025-04-02T02:15:43.118Z" },
- { url = "https://files.pythonhosted.org/packages/34/23/eedf80ec42865ea5355b46265a2433134138eff9a4fea17e1348530fa4ae/aiohttp-3.11.16-cp311-cp311-macosx_11_0_arm64.whl", hash = "sha256:df7db76400bf46ec6a0a73192b14c8295bdb9812053f4fe53f4e789f3ea66bbb", size = 456065, upload-time = "2025-04-02T02:15:44.994Z" },
- { url = "https://files.pythonhosted.org/packages/36/23/4a5b1ef6cff994936bf96d981dd817b487d9db755457a0d1c2939920d620/aiohttp-3.11.16-cp311-cp311-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:cc3a145479a76ad0ed646434d09216d33d08eef0d8c9a11f5ae5cdc37caa3540", size = 1687976, upload-time = "2025-04-02T02:15:46.632Z" },
- { url = "https://files.pythonhosted.org/packages/d0/5d/c7474b4c3069bb35276d54c82997dff4f7575e4b73f0a7b1b08a39ece1eb/aiohttp-3.11.16-cp311-cp311-manylinux_2_17_ppc64le.manylinux2014_ppc64le.whl", hash = "sha256:d007aa39a52d62373bd23428ba4a2546eed0e7643d7bf2e41ddcefd54519842c", size = 1752711, upload-time = "2025-04-02T02:15:48.276Z" },
- { url = "https://files.pythonhosted.org/packages/64/4c/ee416987b6729558f2eb1b727c60196580aafdb141e83bd78bb031d1c000/aiohttp-3.11.16-cp311-cp311-manylinux_2_17_s390x.manylinux2014_s390x.whl", hash = "sha256:f6ddd90d9fb4b501c97a4458f1c1720e42432c26cb76d28177c5b5ad4e332601", size = 1791305, upload-time = "2025-04-02T02:15:49.965Z" },
- { url = "https://files.pythonhosted.org/packages/58/28/3e1e1884070b95f1f69c473a1995852a6f8516670bb1c29d6cb2dbb73e1c/aiohttp-3.11.16-cp311-cp311-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:0a2f451849e6b39e5c226803dcacfa9c7133e9825dcefd2f4e837a2ec5a3bb98", size = 1674499, upload-time = "2025-04-02T02:15:51.718Z" },
- { url = "https://files.pythonhosted.org/packages/ad/55/a032b32fa80a662d25d9eb170ed1e2c2be239304ca114ec66c89dc40f37f/aiohttp-3.11.16-cp311-cp311-manylinux_2_5_i686.manylinux1_i686.manylinux_2_17_i686.manylinux2014_i686.whl", hash = "sha256:8df6612df74409080575dca38a5237282865408016e65636a76a2eb9348c2567", size = 1622313, upload-time = "2025-04-02T02:15:53.377Z" },
- { url = "https://files.pythonhosted.org/packages/b1/df/ca775605f72abbda4e4746e793c408c84373ca2c6ce7a106a09f853f1e89/aiohttp-3.11.16-cp311-cp311-musllinux_1_2_aarch64.whl", hash = "sha256:78e6e23b954644737e385befa0deb20233e2dfddf95dd11e9db752bdd2a294d3", size = 1658274, upload-time = "2025-04-02T02:15:55.035Z" },
- { url = "https://files.pythonhosted.org/packages/cc/6c/21c45b66124df5b4b0ab638271ecd8c6402b702977120cb4d5be6408e15d/aiohttp-3.11.16-cp311-cp311-musllinux_1_2_armv7l.whl", hash = "sha256:696ef00e8a1f0cec5e30640e64eca75d8e777933d1438f4facc9c0cdf288a810", size = 1666704, upload-time = "2025-04-02T02:15:56.581Z" },
- { url = "https://files.pythonhosted.org/packages/1d/e2/7d92adc03e3458edd18a21da2575ab84e58f16b1672ae98529e4eeee45ab/aiohttp-3.11.16-cp311-cp311-musllinux_1_2_i686.whl", hash = "sha256:e3538bc9fe1b902bef51372462e3d7c96fce2b566642512138a480b7adc9d508", size = 1652815, upload-time = "2025-04-02T02:15:58.126Z" },
- { url = "https://files.pythonhosted.org/packages/3a/52/7549573cd654ad651e3c5786ec3946d8f0ee379023e22deb503ff856b16c/aiohttp-3.11.16-cp311-cp311-musllinux_1_2_ppc64le.whl", hash = "sha256:3ab3367bb7f61ad18793fea2ef71f2d181c528c87948638366bf1de26e239183", size = 1735669, upload-time = "2025-04-02T02:16:00.313Z" },
- { url = "https://files.pythonhosted.org/packages/d5/54/dcd24a23c7a5a2922123e07a296a5f79ea87ce605f531be068415c326de6/aiohttp-3.11.16-cp311-cp311-musllinux_1_2_s390x.whl", hash = "sha256:56a3443aca82abda0e07be2e1ecb76a050714faf2be84256dae291182ba59049", size = 1760422, upload-time = "2025-04-02T02:16:02.233Z" },
- { url = "https://files.pythonhosted.org/packages/a7/53/87327fe982fa310944e1450e97bf7b2a28015263771931372a1dfe682c58/aiohttp-3.11.16-cp311-cp311-musllinux_1_2_x86_64.whl", hash = "sha256:61c721764e41af907c9d16b6daa05a458f066015abd35923051be8705108ed17", size = 1694457, upload-time = "2025-04-02T02:16:04.233Z" },
- { url = "https://files.pythonhosted.org/packages/ce/6d/c5ccf41059267bcf89853d3db9d8d217dacf0a04f4086cb6bf278323011f/aiohttp-3.11.16-cp311-cp311-win32.whl", hash = "sha256:3e061b09f6fa42997cf627307f220315e313ece74907d35776ec4373ed718b86", size = 416817, upload-time = "2025-04-02T02:16:06.268Z" },
- { url = "https://files.pythonhosted.org/packages/e7/dd/01f6fe028e054ef4f909c9d63e3a2399e77021bb2e1bb51d56ca8b543989/aiohttp-3.11.16-cp311-cp311-win_amd64.whl", hash = "sha256:745f1ed5e2c687baefc3c5e7b4304e91bf3e2f32834d07baaee243e349624b24", size = 442986, upload-time = "2025-04-02T02:16:07.712Z" },
- { url = "https://files.pythonhosted.org/packages/db/38/100d01cbc60553743baf0fba658cb125f8ad674a8a771f765cdc155a890d/aiohttp-3.11.16-cp312-cp312-macosx_10_13_universal2.whl", hash = "sha256:911a6e91d08bb2c72938bc17f0a2d97864c531536b7832abee6429d5296e5b27", size = 704881, upload-time = "2025-04-02T02:16:09.26Z" },
- { url = "https://files.pythonhosted.org/packages/21/ed/b4102bb6245e36591209e29f03fe87e7956e54cb604ee12e20f7eb47f994/aiohttp-3.11.16-cp312-cp312-macosx_10_13_x86_64.whl", hash = "sha256:6ac13b71761e49d5f9e4d05d33683bbafef753e876e8e5a7ef26e937dd766713", size = 464564, upload-time = "2025-04-02T02:16:10.781Z" },
- { url = "https://files.pythonhosted.org/packages/3b/e1/a9ab6c47b62ecee080eeb33acd5352b40ecad08fb2d0779bcc6739271745/aiohttp-3.11.16-cp312-cp312-macosx_11_0_arm64.whl", hash = "sha256:fd36c119c5d6551bce374fcb5c19269638f8d09862445f85a5a48596fd59f4bb", size = 456548, upload-time = "2025-04-02T02:16:12.764Z" },
- { url = "https://files.pythonhosted.org/packages/80/ad/216c6f71bdff2becce6c8776f0aa32cb0fa5d83008d13b49c3208d2e4016/aiohttp-3.11.16-cp312-cp312-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:d489d9778522fbd0f8d6a5c6e48e3514f11be81cb0a5954bdda06f7e1594b321", size = 1691749, upload-time = "2025-04-02T02:16:14.304Z" },
- { url = "https://files.pythonhosted.org/packages/bd/ea/7df7bcd3f4e734301605f686ffc87993f2d51b7acb6bcc9b980af223f297/aiohttp-3.11.16-cp312-cp312-manylinux_2_17_ppc64le.manylinux2014_ppc64le.whl", hash = "sha256:69a2cbd61788d26f8f1e626e188044834f37f6ae3f937bd9f08b65fc9d7e514e", size = 1736874, upload-time = "2025-04-02T02:16:16.538Z" },
- { url = "https://files.pythonhosted.org/packages/51/41/c7724b9c87a29b7cfd1202ec6446bae8524a751473d25e2ff438bc9a02bf/aiohttp-3.11.16-cp312-cp312-manylinux_2_17_s390x.manylinux2014_s390x.whl", hash = "sha256:cd464ba806e27ee24a91362ba3621bfc39dbbb8b79f2e1340201615197370f7c", size = 1786885, upload-time = "2025-04-02T02:16:18.268Z" },
- { url = "https://files.pythonhosted.org/packages/86/b3/f61f8492fa6569fa87927ad35a40c159408862f7e8e70deaaead349e2fba/aiohttp-3.11.16-cp312-cp312-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:1ce63ae04719513dd2651202352a2beb9f67f55cb8490c40f056cea3c5c355ce", size = 1698059, upload-time = "2025-04-02T02:16:20.234Z" },
- { url = "https://files.pythonhosted.org/packages/ce/be/7097cf860a9ce8bbb0e8960704e12869e111abcd3fbd245153373079ccec/aiohttp-3.11.16-cp312-cp312-manylinux_2_5_i686.manylinux1_i686.manylinux_2_17_i686.manylinux2014_i686.whl", hash = "sha256:09b00dd520d88eac9d1768439a59ab3d145065c91a8fab97f900d1b5f802895e", size = 1626527, upload-time = "2025-04-02T02:16:22.092Z" },
- { url = "https://files.pythonhosted.org/packages/1d/1d/aaa841c340e8c143a8d53a1f644c2a2961c58cfa26e7b398d6bf75cf5d23/aiohttp-3.11.16-cp312-cp312-musllinux_1_2_aarch64.whl", hash = "sha256:7f6428fee52d2bcf96a8aa7b62095b190ee341ab0e6b1bcf50c615d7966fd45b", size = 1644036, upload-time = "2025-04-02T02:16:23.707Z" },
- { url = "https://files.pythonhosted.org/packages/2c/88/59d870f76e9345e2b149f158074e78db457985c2b4da713038d9da3020a8/aiohttp-3.11.16-cp312-cp312-musllinux_1_2_armv7l.whl", hash = "sha256:13ceac2c5cdcc3f64b9015710221ddf81c900c5febc505dbd8f810e770011540", size = 1685270, upload-time = "2025-04-02T02:16:25.874Z" },
- { url = "https://files.pythonhosted.org/packages/2b/b1/c6686948d4c79c3745595efc469a9f8a43cab3c7efc0b5991be65d9e8cb8/aiohttp-3.11.16-cp312-cp312-musllinux_1_2_i686.whl", hash = "sha256:fadbb8f1d4140825069db3fedbbb843290fd5f5bc0a5dbd7eaf81d91bf1b003b", size = 1650852, upload-time = "2025-04-02T02:16:27.556Z" },
- { url = "https://files.pythonhosted.org/packages/fe/94/3e42a6916fd3441721941e0f1b8438e1ce2a4c49af0e28e0d3c950c9b3c9/aiohttp-3.11.16-cp312-cp312-musllinux_1_2_ppc64le.whl", hash = "sha256:6a792ce34b999fbe04a7a71a90c74f10c57ae4c51f65461a411faa70e154154e", size = 1704481, upload-time = "2025-04-02T02:16:29.573Z" },
- { url = "https://files.pythonhosted.org/packages/b1/6d/6ab5854ff59b27075c7a8c610597d2b6c38945f9a1284ee8758bc3720ff6/aiohttp-3.11.16-cp312-cp312-musllinux_1_2_s390x.whl", hash = "sha256:f4065145bf69de124accdd17ea5f4dc770da0a6a6e440c53f6e0a8c27b3e635c", size = 1735370, upload-time = "2025-04-02T02:16:31.191Z" },
- { url = "https://files.pythonhosted.org/packages/73/2a/08a68eec3c99a6659067d271d7553e4d490a0828d588e1daa3970dc2b771/aiohttp-3.11.16-cp312-cp312-musllinux_1_2_x86_64.whl", hash = "sha256:fa73e8c2656a3653ae6c307b3f4e878a21f87859a9afab228280ddccd7369d71", size = 1697619, upload-time = "2025-04-02T02:16:32.873Z" },
- { url = "https://files.pythonhosted.org/packages/61/d5/fea8dbbfb0cd68fbb56f0ae913270a79422d9a41da442a624febf72d2aaf/aiohttp-3.11.16-cp312-cp312-win32.whl", hash = "sha256:f244b8e541f414664889e2c87cac11a07b918cb4b540c36f7ada7bfa76571ea2", size = 411710, upload-time = "2025-04-02T02:16:34.525Z" },
- { url = "https://files.pythonhosted.org/packages/33/fb/41cde15fbe51365024550bf77b95a4fc84ef41365705c946da0421f0e1e0/aiohttp-3.11.16-cp312-cp312-win_amd64.whl", hash = "sha256:23a15727fbfccab973343b6d1b7181bfb0b4aa7ae280f36fd2f90f5476805682", size = 438012, upload-time = "2025-04-02T02:16:36.103Z" },
- { url = "https://files.pythonhosted.org/packages/52/52/7c712b2d9fb4d5e5fd6d12f9ab76e52baddfee71e3c8203ca7a7559d7f51/aiohttp-3.11.16-cp313-cp313-macosx_10_13_universal2.whl", hash = "sha256:a3814760a1a700f3cfd2f977249f1032301d0a12c92aba74605cfa6ce9f78489", size = 698005, upload-time = "2025-04-02T02:16:37.923Z" },
- { url = "https://files.pythonhosted.org/packages/51/3e/61057814f7247666d43ac538abcd6335b022869ade2602dab9bf33f607d2/aiohttp-3.11.16-cp313-cp313-macosx_10_13_x86_64.whl", hash = "sha256:9b751a6306f330801665ae69270a8a3993654a85569b3469662efaad6cf5cc50", size = 461106, upload-time = "2025-04-02T02:16:39.961Z" },
- { url = "https://files.pythonhosted.org/packages/4f/85/6b79fb0ea6e913d596d5b949edc2402b20803f51b1a59e1bbc5bb7ba7569/aiohttp-3.11.16-cp313-cp313-macosx_11_0_arm64.whl", hash = "sha256:ad497f38a0d6c329cb621774788583ee12321863cd4bd9feee1effd60f2ad133", size = 453394, upload-time = "2025-04-02T02:16:41.562Z" },
- { url = "https://files.pythonhosted.org/packages/4b/04/e1bb3fcfbd2c26753932c759593a32299aff8625eaa0bf8ff7d9c0c34a36/aiohttp-3.11.16-cp313-cp313-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:ca37057625693d097543bd88076ceebeb248291df9d6ca8481349efc0b05dcd0", size = 1666643, upload-time = "2025-04-02T02:16:43.62Z" },
- { url = "https://files.pythonhosted.org/packages/0e/27/97bc0fdd1f439b8f060beb3ba8fb47b908dc170280090801158381ad7942/aiohttp-3.11.16-cp313-cp313-manylinux_2_17_ppc64le.manylinux2014_ppc64le.whl", hash = "sha256:a5abcbba9f4b463a45c8ca8b7720891200658f6f46894f79517e6cd11f3405ca", size = 1721948, upload-time = "2025-04-02T02:16:45.617Z" },
- { url = "https://files.pythonhosted.org/packages/2c/4f/bc4c5119e75c05ef15c5670ef1563bbe25d4ed4893b76c57b0184d815e8b/aiohttp-3.11.16-cp313-cp313-manylinux_2_17_s390x.manylinux2014_s390x.whl", hash = "sha256:f420bfe862fb357a6d76f2065447ef6f484bc489292ac91e29bc65d2d7a2c84d", size = 1774454, upload-time = "2025-04-02T02:16:48.562Z" },
- { url = "https://files.pythonhosted.org/packages/73/5b/54b42b2150bb26fdf795464aa55ceb1a49c85f84e98e6896d211eabc6670/aiohttp-3.11.16-cp313-cp313-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:58ede86453a6cf2d6ce40ef0ca15481677a66950e73b0a788917916f7e35a0bb", size = 1677785, upload-time = "2025-04-02T02:16:50.367Z" },
- { url = "https://files.pythonhosted.org/packages/10/ee/a0fe68916d3f82eae199b8535624cf07a9c0a0958c7a76e56dd21140487a/aiohttp-3.11.16-cp313-cp313-manylinux_2_5_i686.manylinux1_i686.manylinux_2_17_i686.manylinux2014_i686.whl", hash = "sha256:6fdec0213244c39973674ca2a7f5435bf74369e7d4e104d6c7473c81c9bcc8c4", size = 1608456, upload-time = "2025-04-02T02:16:52.158Z" },
- { url = "https://files.pythonhosted.org/packages/8b/48/83afd779242b7cf7e1ceed2ff624a86d3221e17798061cf9a79e0b246077/aiohttp-3.11.16-cp313-cp313-musllinux_1_2_aarch64.whl", hash = "sha256:72b1b03fb4655c1960403c131740755ec19c5898c82abd3961c364c2afd59fe7", size = 1622424, upload-time = "2025-04-02T02:16:54.386Z" },
- { url = "https://files.pythonhosted.org/packages/6f/27/452f1d5fca1f516f9f731539b7f5faa9e9d3bf8a3a6c3cd7c4b031f20cbd/aiohttp-3.11.16-cp313-cp313-musllinux_1_2_armv7l.whl", hash = "sha256:780df0d837276276226a1ff803f8d0fa5f8996c479aeef52eb040179f3156cbd", size = 1660943, upload-time = "2025-04-02T02:16:56.887Z" },
- { url = "https://files.pythonhosted.org/packages/d6/e1/5c7d63143b8d00c83b958b9e78e7048c4a69903c760c1e329bf02bac57a1/aiohttp-3.11.16-cp313-cp313-musllinux_1_2_i686.whl", hash = "sha256:ecdb8173e6c7aa09eee342ac62e193e6904923bd232e76b4157ac0bfa670609f", size = 1622797, upload-time = "2025-04-02T02:16:58.676Z" },
- { url = "https://files.pythonhosted.org/packages/46/9e/2ac29cca2746ee8e449e73cd2fcb3d454467393ec03a269d50e49af743f1/aiohttp-3.11.16-cp313-cp313-musllinux_1_2_ppc64le.whl", hash = "sha256:a6db7458ab89c7d80bc1f4e930cc9df6edee2200127cfa6f6e080cf619eddfbd", size = 1687162, upload-time = "2025-04-02T02:17:01.076Z" },
- { url = "https://files.pythonhosted.org/packages/ad/6b/eaa6768e02edebaf37d77f4ffb74dd55f5cbcbb6a0dbf798ccec7b0ac23b/aiohttp-3.11.16-cp313-cp313-musllinux_1_2_s390x.whl", hash = "sha256:2540ddc83cc724b13d1838026f6a5ad178510953302a49e6d647f6e1de82bc34", size = 1718518, upload-time = "2025-04-02T02:17:03.388Z" },
- { url = "https://files.pythonhosted.org/packages/e5/18/dda87cbad29472a51fa058d6d8257dfce168289adaeb358b86bd93af3b20/aiohttp-3.11.16-cp313-cp313-musllinux_1_2_x86_64.whl", hash = "sha256:3b4e6db8dc4879015b9955778cfb9881897339c8fab7b3676f8433f849425913", size = 1675254, upload-time = "2025-04-02T02:17:05.579Z" },
- { url = "https://files.pythonhosted.org/packages/32/d9/d2fb08c614df401d92c12fcbc60e6e879608d5e8909ef75c5ad8d4ad8aa7/aiohttp-3.11.16-cp313-cp313-win32.whl", hash = "sha256:493910ceb2764f792db4dc6e8e4b375dae1b08f72e18e8f10f18b34ca17d0979", size = 410698, upload-time = "2025-04-02T02:17:07.499Z" },
- { url = "https://files.pythonhosted.org/packages/ce/ed/853e36d5a33c24544cfa46585895547de152dfef0b5c79fa675f6e4b7b87/aiohttp-3.11.16-cp313-cp313-win_amd64.whl", hash = "sha256:42864e70a248f5f6a49fdaf417d9bc62d6e4d8ee9695b24c5916cb4bb666c802", size = 436395, upload-time = "2025-04-02T02:17:09.566Z" },
-]
-
-[[package]]
-name = "aiosignal"
-version = "1.3.2"
-source = { registry = "https://pypi.org/simple" }
-dependencies = [
- { name = "frozenlist" },
-]
-sdist = { url = "https://files.pythonhosted.org/packages/ba/b5/6d55e80f6d8a08ce22b982eafa278d823b541c925f11ee774b0b9c43473d/aiosignal-1.3.2.tar.gz", hash = "sha256:a8c255c66fafb1e499c9351d0bf32ff2d8a0321595ebac3b93713656d2436f54", size = 19424, upload-time = "2024-12-13T17:10:40.86Z" }
-wheels = [
- { url = "https://files.pythonhosted.org/packages/ec/6a/bc7e17a3e87a2985d3e8f4da4cd0f481060eb78fb08596c42be62c90a4d9/aiosignal-1.3.2-py2.py3-none-any.whl", hash = "sha256:45cde58e409a301715980c2b01d0c28bdde3770d8290b5eb2173759d9acb31a5", size = 7597, upload-time = "2024-12-13T17:10:38.469Z" },
-]
-
[[package]]
name = "altgraph"
version = "0.17.4"
@@ -128,15 +16,6 @@ wheels = [
{ url = "https://files.pythonhosted.org/packages/4d/3f/3bc3f1d83f6e4a7fcb834d3720544ca597590425be5ba9db032b2bf322a2/altgraph-0.17.4-py2.py3-none-any.whl", hash = "sha256:642743b4750de17e655e6711601b077bc6598dbfa3ba5fa2b2a35ce12b508dff", size = 21212, upload-time = "2023-09-25T09:04:50.691Z" },
]
-[[package]]
-name = "annotated-doc"
-version = "0.0.4"
-source = { registry = "https://pypi.org/simple" }
-sdist = { url = "https://files.pythonhosted.org/packages/57/ba/046ceea27344560984e26a590f90bc7f4a75b06701f653222458922b558c/annotated_doc-0.0.4.tar.gz", hash = "sha256:fbcda96e87e9c92ad167c2e53839e57503ecfda18804ea28102353485033faa4", size = 7288, upload-time = "2025-11-10T22:07:42.062Z" }
-wheels = [
- { url = "https://files.pythonhosted.org/packages/1e/d3/26bf1008eb3d2daa8ef4cacc7f3bfdc11818d111f7e2d0201bc6e3b49d45/annotated_doc-0.0.4-py3-none-any.whl", hash = "sha256:571ac1dc6991c450b25a9c2d84a3705e2ae7a53467b5d111c24fa8baabbed320", size = 5303, upload-time = "2025-11-10T22:07:40.673Z" },
-]
-
[[package]]
name = "annotated-types"
version = "0.7.0"
@@ -161,147 +40,6 @@ wheels = [
{ url = "https://files.pythonhosted.org/packages/a1/ee/48ca1a7c89ffec8b6a0c5d02b89c305671d5ffd8d3c94acf8b8c408575bb/anyio-4.9.0-py3-none-any.whl", hash = "sha256:9f76d541cad6e36af7beb62e978876f3b41e3e04f2c1fbf0884604c0a9c4d93c", size = 100916, upload-time = "2025-03-17T00:02:52.713Z" },
]
-[[package]]
-name = "apprise"
-version = "1.11.0"
-source = { registry = "https://pypi.org/simple" }
-dependencies = [
- { name = "certifi" },
- { name = "click" },
- { name = "markdown" },
- { name = "pyyaml" },
- { name = "requests" },
- { name = "requests-oauthlib" },
- { name = "tzdata", marker = "sys_platform == 'win32'" },
-]
-sdist = { url = "https://files.pythonhosted.org/packages/a8/f8/83f4e2aaaa0342dc67f783bf84427d9ff5cfa4ecde3a52d9b587740a91ee/apprise-1.11.0.tar.gz", hash = "sha256:3b1e6f5365b302d1fae270c0c8007958e54224b9b7808acec69006ea27f5b8a2", size = 2337248, upload-time = "2026-05-29T17:52:29.198Z" }
-wheels = [
- { url = "https://files.pythonhosted.org/packages/5e/79/1483693160917522703708e45b4045946d86be634b8af2c2ac9f361f8fa3/apprise-1.11.0-py3-none-any.whl", hash = "sha256:6abc6d9f8dddedfe14b2918c3553146894ac6e3dad401deaf854b20b4c455d38", size = 1712975, upload-time = "2026-05-29T17:52:26.645Z" },
-]
-
-[[package]]
-name = "async-timeout"
-version = "5.0.1"
-source = { registry = "https://pypi.org/simple" }
-sdist = { url = "https://files.pythonhosted.org/packages/a5/ae/136395dfbfe00dfc94da3f3e136d0b13f394cba8f4841120e34226265780/async_timeout-5.0.1.tar.gz", hash = "sha256:d9321a7a3d5a6a5e187e824d2fa0793ce379a202935782d555d6e9d2735677d3", size = 9274, upload-time = "2024-11-06T16:41:39.6Z" }
-wheels = [
- { url = "https://files.pythonhosted.org/packages/fe/ba/e2081de779ca30d473f21f5b30e0e737c438205440784c7dfc81efc2b029/async_timeout-5.0.1-py3-none-any.whl", hash = "sha256:39e3809566ff85354557ec2398b55e096c8364bacac9405a7a1fa429e77fe76c", size = 6233, upload-time = "2024-11-06T16:41:37.9Z" },
-]
-
-[[package]]
-name = "attrs"
-version = "25.3.0"
-source = { registry = "https://pypi.org/simple" }
-sdist = { url = "https://files.pythonhosted.org/packages/5a/b0/1367933a8532ee6ff8d63537de4f1177af4bff9f3e829baf7331f595bb24/attrs-25.3.0.tar.gz", hash = "sha256:75d7cefc7fb576747b2c81b4442d4d4a1ce0900973527c011d1030fd3bf4af1b", size = 812032, upload-time = "2025-03-13T11:10:22.779Z" }
-wheels = [
- { url = "https://files.pythonhosted.org/packages/77/06/bb80f5f86020c4551da315d78b3ab75e8228f89f0162f2c3a819e407941a/attrs-25.3.0-py3-none-any.whl", hash = "sha256:427318ce031701fea540783410126f03899a97ffc6f61596ad581ac2e40e3bc3", size = 63815, upload-time = "2025-03-13T11:10:21.14Z" },
-]
-
-[[package]]
-name = "biliass"
-version = "2.2.0"
-source = { registry = "https://pypi.org/simple" }
-sdist = { url = "https://files.pythonhosted.org/packages/c1/f5/0982ed1a34a9a780f360d9a3f559a861dda889b886ced4d2043cc7003fc2/biliass-2.2.0.tar.gz", hash = "sha256:94328ebc52e641516cd32d22c1fa6f2d6a5a648c8f0494802d691bb3e8175d4e", size = 31055, upload-time = "2024-12-15T13:09:28Z" }
-wheels = [
- { url = "https://files.pythonhosted.org/packages/3a/d2/861645bd31b9d92060b225ee524a29c4584aadeb55917c0068cc52a157d5/biliass-2.2.0-cp313-cp313t-macosx_10_12_x86_64.whl", hash = "sha256:64964a6af3dd45ae534b4622ca95f883ad880ceadf5bb57c15464740c24f9402", size = 889351, upload-time = "2024-12-15T13:08:22.559Z" },
- { url = "https://files.pythonhosted.org/packages/79/0f/25cc8eb37a945a35b8cde012cebf3915e9d7135d2153ae25925ef5582bfc/biliass-2.2.0-cp313-cp313t-macosx_11_0_arm64.whl", hash = "sha256:7fc28cdb22a0b138dc0486732c776b88d1e8c0e0bf10234fb4ff93029bcbee71", size = 848386, upload-time = "2024-12-15T13:08:27.038Z" },
- { url = "https://files.pythonhosted.org/packages/5e/f2/97567d4f3414685fbfd244e5579ac5fc326defad74e9b53ef25109d69356/biliass-2.2.0-cp313-cp313t-manylinux_2_12_i686.manylinux2010_i686.whl", hash = "sha256:d28570a7fabc2e7787f7465b82f818b103ec9fde68b29033a070c6981eb3a579", size = 942998, upload-time = "2024-12-15T13:08:29.724Z" },
- { url = "https://files.pythonhosted.org/packages/37/0b/5f4565690af61be1829b3ad31e92fe3438744abffe49475999416c305ea4/biliass-2.2.0-cp313-cp313t-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:457b7e0d117a4b995ce492d4f00ff3dbf9f8bff10b6d10c3e6296adc936492a0", size = 921196, upload-time = "2024-12-15T13:08:32.43Z" },
- { url = "https://files.pythonhosted.org/packages/aa/0b/14751c1971779ec09f8acdbcb4f4af6556f2e8824a5d5e8748379f8793ad/biliass-2.2.0-cp313-cp313t-manylinux_2_17_armv7l.manylinux2014_armv7l.whl", hash = "sha256:9ea84d6c2b4c33827d38492c0f18f630cba012ad17d3c233ce9cb806f6656747", size = 915903, upload-time = "2024-12-15T13:08:35.617Z" },
- { url = "https://files.pythonhosted.org/packages/1f/0f/1f19282a1676130443b0e430b6c9a4f8f301713d73e14252f3cd5634a21e/biliass-2.2.0-cp313-cp313t-manylinux_2_17_ppc64le.manylinux2014_ppc64le.whl", hash = "sha256:8a72e6b418afb27fbecabbfc5068944e46d6f15e1b446dbf6feb086f162e7122", size = 981930, upload-time = "2024-12-15T13:08:38.434Z" },
- { url = "https://files.pythonhosted.org/packages/a3/05/18245df7d4722595ff5236ce74daf7d68999f335eb7f27b465be4dbc0453/biliass-2.2.0-cp313-cp313t-manylinux_2_17_s390x.manylinux2014_s390x.whl", hash = "sha256:e657f9780f2f34c30e0342cee960689cd047d3321c91bc2c62b5a9a52d19fc1b", size = 1017596, upload-time = "2024-12-15T13:08:40.098Z" },
- { url = "https://files.pythonhosted.org/packages/35/d0/6c8646e64f8b62bc9abbd960b8db5d31f329860befce0f095a595374a08f/biliass-2.2.0-cp313-cp313t-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:e91fba8fbf139db91c53b6f57fb7ef1111587b275ae87822d39c471da8722c82", size = 960580, upload-time = "2024-12-15T13:08:42.857Z" },
- { url = "https://files.pythonhosted.org/packages/f7/ab/1ed875106a517b6e317c3d0a537e96301e758b549b6b51461ede6bd345b7/biliass-2.2.0-cp313-cp313t-musllinux_1_2_aarch64.whl", hash = "sha256:89f2f72bcfe042ec217ea4062c57f0d78c0abfa75ee2d9c9f816942eda4a11d8", size = 1097540, upload-time = "2024-12-15T13:08:44.373Z" },
- { url = "https://files.pythonhosted.org/packages/83/17/8534c461f1f2fea7d07cee98c3c44e9552751bb48a3cb6240b55e0bdc85d/biliass-2.2.0-cp313-cp313t-musllinux_1_2_armv7l.whl", hash = "sha256:4d2aa4fb4ecc809f3f78cccc050872deb6ff95649b50ccc73d9a2b3fb59cb153", size = 1177746, upload-time = "2024-12-15T13:08:45.853Z" },
- { url = "https://files.pythonhosted.org/packages/4a/67/8d7de08ca37e2b3f483ddb9f9c1a8bc88cd1522ebe01ab57d297859a0c89/biliass-2.2.0-cp313-cp313t-musllinux_1_2_i686.whl", hash = "sha256:72bd3a934683e2704da55f403a349e0d2f43923a57b05bd21f0ed3bd6672cf25", size = 1104365, upload-time = "2024-12-15T13:08:47.585Z" },
- { url = "https://files.pythonhosted.org/packages/b8/47/fc037b458671451aede8bbd7a0f4f2a909a69613e849e21f82e7f68280f3/biliass-2.2.0-cp313-cp313t-musllinux_1_2_x86_64.whl", hash = "sha256:e7ac064e7822f14ff500ae3da675388c0484fc7d10cf81ffeda2a675b68b82e6", size = 1130452, upload-time = "2024-12-15T13:08:49.081Z" },
- { url = "https://files.pythonhosted.org/packages/b6/e7/5bdd43ba36945ebe20d311fc92b23298d62ba8f5700a440346b76b39e584/biliass-2.2.0-cp313-cp313t-win32.whl", hash = "sha256:bfc102cca0ba0111739bb5e8923077b5610b939a0e4b50e57e367d4a1a035e4d", size = 683876, upload-time = "2024-12-15T13:08:51.812Z" },
- { url = "https://files.pythonhosted.org/packages/fe/26/22638cbcd9246589a8287fa773dcb88b78235e9821a18c4f74c36cfcadd7/biliass-2.2.0-cp313-cp313t-win_amd64.whl", hash = "sha256:f3f5869db4950421ca32bbb4f6cafbb753b47c761981ae83d5c2f582a4a734ad", size = 747042, upload-time = "2024-12-15T13:08:53.19Z" },
- { url = "https://files.pythonhosted.org/packages/82/1f/a759d5e36e89d2a791c59e2943e7133281aeee1c3a1f58a0982b43b3076c/biliass-2.2.0-cp39-abi3-macosx_10_12_x86_64.whl", hash = "sha256:3b260e7226414d12481d208f04f1270e7fa1ed02421375b715f59ccada6d61ff", size = 889306, upload-time = "2024-12-15T13:08:54.651Z" },
- { url = "https://files.pythonhosted.org/packages/72/09/57c8dc2d21f4e7b6db2821c6a4685f4e22fe3c9825f5cf78cd805767ccc5/biliass-2.2.0-cp39-abi3-macosx_11_0_arm64.whl", hash = "sha256:400b166c6f4a3c4b4f906944982a9274778528e61ca4eeccbb4957e732d3a51a", size = 848344, upload-time = "2024-12-15T13:08:59.121Z" },
- { url = "https://files.pythonhosted.org/packages/bb/53/039657ddbc0c2f279feca8daf762172f4a931105bf5771faf984200ea169/biliass-2.2.0-cp39-abi3-manylinux_2_12_i686.manylinux2010_i686.whl", hash = "sha256:e6e177c3512453f0ccf73f372ae17ff9e0690c8b5a158a65b82ceaae8e3a4f45", size = 942934, upload-time = "2024-12-15T13:09:00.765Z" },
- { url = "https://files.pythonhosted.org/packages/4f/7e/5f2dd5561734a7445d58140f76fd48e1843fc4533eef65ed91e2f61107fb/biliass-2.2.0-cp39-abi3-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:eff756c2e1efd5f6806f295ee1133c12741912b19d0eca31892990380d838b0b", size = 921124, upload-time = "2024-12-15T13:09:02.317Z" },
- { url = "https://files.pythonhosted.org/packages/fe/7a/242d3dab439c841914cb10b1b00a4363e3ce2bd80a8794a52391264f8a7f/biliass-2.2.0-cp39-abi3-manylinux_2_17_armv7l.manylinux2014_armv7l.whl", hash = "sha256:5ef0133c8ff809aac6fd2f7e5fdfaba11442d3efe9459abb30139ed6e8041316", size = 915825, upload-time = "2024-12-15T13:09:03.842Z" },
- { url = "https://files.pythonhosted.org/packages/92/e7/36c1d7f4593c0b5efbcba618992a4ef85eb4747ec29adfac8224d32a5f66/biliass-2.2.0-cp39-abi3-manylinux_2_17_ppc64le.manylinux2014_ppc64le.whl", hash = "sha256:dd9214384b67b2a624338f178af8a21b7b51639daf574cee2c2d7637a428bc00", size = 981847, upload-time = "2024-12-15T13:09:05.364Z" },
- { url = "https://files.pythonhosted.org/packages/02/4b/0808c5baa2e9a18b83976af5ba2de94c19aadb626fb0e2914765c7208f88/biliass-2.2.0-cp39-abi3-manylinux_2_17_s390x.manylinux2014_s390x.whl", hash = "sha256:aaa4cada04ccd6cff1d6ea358dcc92a93f25f01c0cee092a9585bf787695ca48", size = 1017528, upload-time = "2024-12-15T13:09:09.357Z" },
- { url = "https://files.pythonhosted.org/packages/fc/24/efcdd85549a8cdbe6a2f29c00003424017669fe061d7a775b4a3e7b6f5da/biliass-2.2.0-cp39-abi3-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:2b145f699a4f1a22a6cc032a2be0fc69ef8d7af68f03ca963d80d1236e3bc03e", size = 960511, upload-time = "2024-12-15T13:09:13.651Z" },
- { url = "https://files.pythonhosted.org/packages/6f/6e/1699b6fd4f1b7fb474e68952f16a374ae49b39ffb90a2b75b2230a570dfd/biliass-2.2.0-cp39-abi3-musllinux_1_2_aarch64.whl", hash = "sha256:44a18acc54a718ab87832e8aa07a30b81520c73427b773cd5900056b52cc5565", size = 1097460, upload-time = "2024-12-15T13:09:16.461Z" },
- { url = "https://files.pythonhosted.org/packages/5b/ba/88dd0b5e7eb923eaa37be7c95c633972e972c58cde83b7729fb063798673/biliass-2.2.0-cp39-abi3-musllinux_1_2_armv7l.whl", hash = "sha256:b1cec532ad4c146defc4b23adb24eaf0c190c616942b07b1964e70e5b8ebf7a6", size = 1177662, upload-time = "2024-12-15T13:09:17.964Z" },
- { url = "https://files.pythonhosted.org/packages/06/f1/71a3310171807161457ec60c3d967f099003392582a27c1ff211f3218126/biliass-2.2.0-cp39-abi3-musllinux_1_2_i686.whl", hash = "sha256:06a2b3c9986670be9ee25b07e978e282b7f7c1fc953cd79bfe1c119960434750", size = 1104291, upload-time = "2024-12-15T13:09:19.397Z" },
- { url = "https://files.pythonhosted.org/packages/fa/07/9e1a91c731f023a6d8bd116475b0ecde02f3e3037654a6f82bcc8391a627/biliass-2.2.0-cp39-abi3-musllinux_1_2_x86_64.whl", hash = "sha256:b06430e977defd3712f0116e031238841fe76a4f53a49c1a4e12263351c6aa6c", size = 1130374, upload-time = "2024-12-15T13:09:20.955Z" },
- { url = "https://files.pythonhosted.org/packages/01/64/f689da729a0a7febb2523a22022a4e7733d8c34f3fee427181a99b42cf31/biliass-2.2.0-cp39-abi3-win32.whl", hash = "sha256:9dbb636f69b7b4e5784df23ac7265ba4904090af6f51214ad0dcaee3e6eb3f15", size = 686605, upload-time = "2024-12-15T13:09:23.979Z" },
- { url = "https://files.pythonhosted.org/packages/e1/fe/f57f7c8c6a40dc2c392eea31ddf3da584aaf2d0d2c239bb6d2df44a29972/biliass-2.2.0-cp39-abi3-win_amd64.whl", hash = "sha256:e0a657abe5535a482e133e0a8a6884b2a375a174fc7e7cd54a82bd9fd8223384", size = 751513, upload-time = "2024-12-15T13:09:25.415Z" },
-]
-
-[[package]]
-name = "historyhub"
-version = "1.7.2"
-source = { virtual = "." }
-dependencies = [
- { name = "aiohttp" },
- { name = "apprise" },
- { name = "email-validator" },
- { name = "fastapi" },
- { name = "httpx" },
- { name = "jieba" },
- { name = "jinja2" },
- { name = "loguru" },
- { name = "mcp", extra = ["cli"] },
- { name = "numpy" },
- { name = "openpyxl" },
- { name = "pandas" },
- { name = "pillow" },
- { name = "psutil" },
- { name = "pydantic" },
- { name = "pyecharts" },
- { name = "pyinstaller" },
- { name = "pymysql" },
- { name = "python-dateutil" },
- { name = "pyyaml" },
- { name = "qrcode" },
- { name = "requests" },
- { name = "schedule" },
- { name = "scikit-learn" },
- { name = "snownlp" },
- { name = "tqdm" },
- { name = "urllib3" },
- { name = "uvicorn" },
- { name = "yutto" },
-]
-
-[package.metadata]
-requires-dist = [
- { name = "aiohttp", specifier = "~=3.11.13" },
- { name = "apprise", specifier = ">=1.11.0" },
- { name = "email-validator", specifier = ">=2.1.0" },
- { name = "fastapi", specifier = "~=0.115.8" },
- { name = "httpx", specifier = "~=0.28.1" },
- { name = "jieba", specifier = "~=0.42.1" },
- { name = "jinja2", specifier = "~=3.1.5" },
- { name = "loguru", specifier = ">=0.7.2" },
- { name = "mcp", extras = ["cli"], specifier = ">=1.27.2" },
- { name = "numpy", specifier = "~=1.26.4" },
- { name = "openpyxl", specifier = "~=3.1.5" },
- { name = "pandas", specifier = "~=2.2.3" },
- { name = "pillow", specifier = "~=10.2.0" },
- { name = "psutil", specifier = ">=5.9.0" },
- { name = "pydantic", specifier = ">=2.11,<3" },
- { name = "pyecharts", specifier = "~=2.0.8" },
- { name = "pyinstaller", specifier = ">=6.12.0" },
- { name = "pymysql", specifier = "~=1.1.1" },
- { name = "python-dateutil", specifier = ">=2.8.2" },
- { name = "pyyaml", specifier = "~=6.0.2" },
- { name = "qrcode", specifier = "~=8.0" },
- { name = "requests", specifier = "~=2.32.3" },
- { name = "schedule", specifier = "~=1.2.2" },
- { name = "scikit-learn", specifier = "~=1.5.2" },
- { name = "snownlp", specifier = "~=0.12.3" },
- { name = "tqdm", specifier = ">=4.66.0" },
- { name = "urllib3", specifier = "~=2.3.0" },
- { name = "uvicorn", specifier = "~=0.32.1" },
- { name = "yutto", specifier = "~=2.0.0" },
-]
-
[[package]]
name = "certifi"
version = "2025.1.31"
@@ -311,88 +49,6 @@ wheels = [
{ url = "https://files.pythonhosted.org/packages/38/fc/bce832fd4fd99766c04d1ee0eead6b0ec6486fb100ae5e74c1d91292b982/certifi-2025.1.31-py3-none-any.whl", hash = "sha256:ca78db4565a652026a4db2bcdf68f2fb589ea80d0be70e03929ed730746b84fe", size = 166393, upload-time = "2025-01-31T02:16:45.015Z" },
]
-[[package]]
-name = "cffi"
-version = "2.0.0"
-source = { registry = "https://pypi.org/simple" }
-dependencies = [
- { name = "pycparser", marker = "implementation_name != 'PyPy'" },
-]
-sdist = { url = "https://files.pythonhosted.org/packages/eb/56/b1ba7935a17738ae8453301356628e8147c79dbb825bcbc73dc7401f9846/cffi-2.0.0.tar.gz", hash = "sha256:44d1b5909021139fe36001ae048dbdde8214afa20200eda0f64c068cac5d5529", size = 523588, upload-time = "2025-09-08T23:24:04.541Z" }
-wheels = [
- { url = "https://files.pythonhosted.org/packages/93/d7/516d984057745a6cd96575eea814fe1edd6646ee6efd552fb7b0921dec83/cffi-2.0.0-cp310-cp310-macosx_10_13_x86_64.whl", hash = "sha256:0cf2d91ecc3fcc0625c2c530fe004f82c110405f101548512cce44322fa8ac44", size = 184283, upload-time = "2025-09-08T23:22:08.01Z" },
- { url = "https://files.pythonhosted.org/packages/9e/84/ad6a0b408daa859246f57c03efd28e5dd1b33c21737c2db84cae8c237aa5/cffi-2.0.0-cp310-cp310-macosx_11_0_arm64.whl", hash = "sha256:f73b96c41e3b2adedc34a7356e64c8eb96e03a3782b535e043a986276ce12a49", size = 180504, upload-time = "2025-09-08T23:22:10.637Z" },
- { url = "https://files.pythonhosted.org/packages/50/bd/b1a6362b80628111e6653c961f987faa55262b4002fcec42308cad1db680/cffi-2.0.0-cp310-cp310-manylinux1_i686.manylinux2014_i686.manylinux_2_17_i686.manylinux_2_5_i686.whl", hash = "sha256:53f77cbe57044e88bbd5ed26ac1d0514d2acf0591dd6bb02a3ae37f76811b80c", size = 208811, upload-time = "2025-09-08T23:22:12.267Z" },
- { url = "https://files.pythonhosted.org/packages/4f/27/6933a8b2562d7bd1fb595074cf99cc81fc3789f6a6c05cdabb46284a3188/cffi-2.0.0-cp310-cp310-manylinux2014_aarch64.manylinux_2_17_aarch64.whl", hash = "sha256:3e837e369566884707ddaf85fc1744b47575005c0a229de3327f8f9a20f4efeb", size = 216402, upload-time = "2025-09-08T23:22:13.455Z" },
- { url = "https://files.pythonhosted.org/packages/05/eb/b86f2a2645b62adcfff53b0dd97e8dfafb5c8aa864bd0d9a2c2049a0d551/cffi-2.0.0-cp310-cp310-manylinux2014_ppc64le.manylinux_2_17_ppc64le.whl", hash = "sha256:5eda85d6d1879e692d546a078b44251cdd08dd1cfb98dfb77b670c97cee49ea0", size = 203217, upload-time = "2025-09-08T23:22:14.596Z" },
- { url = "https://files.pythonhosted.org/packages/9f/e0/6cbe77a53acf5acc7c08cc186c9928864bd7c005f9efd0d126884858a5fe/cffi-2.0.0-cp310-cp310-manylinux2014_s390x.manylinux_2_17_s390x.whl", hash = "sha256:9332088d75dc3241c702d852d4671613136d90fa6881da7d770a483fd05248b4", size = 203079, upload-time = "2025-09-08T23:22:15.769Z" },
- { url = "https://files.pythonhosted.org/packages/98/29/9b366e70e243eb3d14a5cb488dfd3a0b6b2f1fb001a203f653b93ccfac88/cffi-2.0.0-cp310-cp310-manylinux2014_x86_64.manylinux_2_17_x86_64.whl", hash = "sha256:fc7de24befaeae77ba923797c7c87834c73648a05a4bde34b3b7e5588973a453", size = 216475, upload-time = "2025-09-08T23:22:17.427Z" },
- { url = "https://files.pythonhosted.org/packages/21/7a/13b24e70d2f90a322f2900c5d8e1f14fa7e2a6b3332b7309ba7b2ba51a5a/cffi-2.0.0-cp310-cp310-musllinux_1_2_aarch64.whl", hash = "sha256:cf364028c016c03078a23b503f02058f1814320a56ad535686f90565636a9495", size = 218829, upload-time = "2025-09-08T23:22:19.069Z" },
- { url = "https://files.pythonhosted.org/packages/60/99/c9dc110974c59cc981b1f5b66e1d8af8af764e00f0293266824d9c4254bc/cffi-2.0.0-cp310-cp310-musllinux_1_2_i686.whl", hash = "sha256:e11e82b744887154b182fd3e7e8512418446501191994dbf9c9fc1f32cc8efd5", size = 211211, upload-time = "2025-09-08T23:22:20.588Z" },
- { url = "https://files.pythonhosted.org/packages/49/72/ff2d12dbf21aca1b32a40ed792ee6b40f6dc3a9cf1644bd7ef6e95e0ac5e/cffi-2.0.0-cp310-cp310-musllinux_1_2_x86_64.whl", hash = "sha256:8ea985900c5c95ce9db1745f7933eeef5d314f0565b27625d9a10ec9881e1bfb", size = 218036, upload-time = "2025-09-08T23:22:22.143Z" },
- { url = "https://files.pythonhosted.org/packages/e2/cc/027d7fb82e58c48ea717149b03bcadcbdc293553edb283af792bd4bcbb3f/cffi-2.0.0-cp310-cp310-win32.whl", hash = "sha256:1f72fb8906754ac8a2cc3f9f5aaa298070652a0ffae577e0ea9bd480dc3c931a", size = 172184, upload-time = "2025-09-08T23:22:23.328Z" },
- { url = "https://files.pythonhosted.org/packages/33/fa/072dd15ae27fbb4e06b437eb6e944e75b068deb09e2a2826039e49ee2045/cffi-2.0.0-cp310-cp310-win_amd64.whl", hash = "sha256:b18a3ed7d5b3bd8d9ef7a8cb226502c6bf8308df1525e1cc676c3680e7176739", size = 182790, upload-time = "2025-09-08T23:22:24.752Z" },
- { url = "https://files.pythonhosted.org/packages/12/4a/3dfd5f7850cbf0d06dc84ba9aa00db766b52ca38d8b86e3a38314d52498c/cffi-2.0.0-cp311-cp311-macosx_10_13_x86_64.whl", hash = "sha256:b4c854ef3adc177950a8dfc81a86f5115d2abd545751a304c5bcf2c2c7283cfe", size = 184344, upload-time = "2025-09-08T23:22:26.456Z" },
- { url = "https://files.pythonhosted.org/packages/4f/8b/f0e4c441227ba756aafbe78f117485b25bb26b1c059d01f137fa6d14896b/cffi-2.0.0-cp311-cp311-macosx_11_0_arm64.whl", hash = "sha256:2de9a304e27f7596cd03d16f1b7c72219bd944e99cc52b84d0145aefb07cbd3c", size = 180560, upload-time = "2025-09-08T23:22:28.197Z" },
- { url = "https://files.pythonhosted.org/packages/b1/b7/1200d354378ef52ec227395d95c2576330fd22a869f7a70e88e1447eb234/cffi-2.0.0-cp311-cp311-manylinux1_i686.manylinux2014_i686.manylinux_2_17_i686.manylinux_2_5_i686.whl", hash = "sha256:baf5215e0ab74c16e2dd324e8ec067ef59e41125d3eade2b863d294fd5035c92", size = 209613, upload-time = "2025-09-08T23:22:29.475Z" },
- { url = "https://files.pythonhosted.org/packages/b8/56/6033f5e86e8cc9bb629f0077ba71679508bdf54a9a5e112a3c0b91870332/cffi-2.0.0-cp311-cp311-manylinux2014_aarch64.manylinux_2_17_aarch64.whl", hash = "sha256:730cacb21e1bdff3ce90babf007d0a0917cc3e6492f336c2f0134101e0944f93", size = 216476, upload-time = "2025-09-08T23:22:31.063Z" },
- { url = "https://files.pythonhosted.org/packages/dc/7f/55fecd70f7ece178db2f26128ec41430d8720f2d12ca97bf8f0a628207d5/cffi-2.0.0-cp311-cp311-manylinux2014_ppc64le.manylinux_2_17_ppc64le.whl", hash = "sha256:6824f87845e3396029f3820c206e459ccc91760e8fa24422f8b0c3d1731cbec5", size = 203374, upload-time = "2025-09-08T23:22:32.507Z" },
- { url = "https://files.pythonhosted.org/packages/84/ef/a7b77c8bdc0f77adc3b46888f1ad54be8f3b7821697a7b89126e829e676a/cffi-2.0.0-cp311-cp311-manylinux2014_s390x.manylinux_2_17_s390x.whl", hash = "sha256:9de40a7b0323d889cf8d23d1ef214f565ab154443c42737dfe52ff82cf857664", size = 202597, upload-time = "2025-09-08T23:22:34.132Z" },
- { url = "https://files.pythonhosted.org/packages/d7/91/500d892b2bf36529a75b77958edfcd5ad8e2ce4064ce2ecfeab2125d72d1/cffi-2.0.0-cp311-cp311-manylinux2014_x86_64.manylinux_2_17_x86_64.whl", hash = "sha256:8941aaadaf67246224cee8c3803777eed332a19d909b47e29c9842ef1e79ac26", size = 215574, upload-time = "2025-09-08T23:22:35.443Z" },
- { url = "https://files.pythonhosted.org/packages/44/64/58f6255b62b101093d5df22dcb752596066c7e89dd725e0afaed242a61be/cffi-2.0.0-cp311-cp311-musllinux_1_2_aarch64.whl", hash = "sha256:a05d0c237b3349096d3981b727493e22147f934b20f6f125a3eba8f994bec4a9", size = 218971, upload-time = "2025-09-08T23:22:36.805Z" },
- { url = "https://files.pythonhosted.org/packages/ab/49/fa72cebe2fd8a55fbe14956f9970fe8eb1ac59e5df042f603ef7c8ba0adc/cffi-2.0.0-cp311-cp311-musllinux_1_2_i686.whl", hash = "sha256:94698a9c5f91f9d138526b48fe26a199609544591f859c870d477351dc7b2414", size = 211972, upload-time = "2025-09-08T23:22:38.436Z" },
- { url = "https://files.pythonhosted.org/packages/0b/28/dd0967a76aab36731b6ebfe64dec4e981aff7e0608f60c2d46b46982607d/cffi-2.0.0-cp311-cp311-musllinux_1_2_x86_64.whl", hash = "sha256:5fed36fccc0612a53f1d4d9a816b50a36702c28a2aa880cb8a122b3466638743", size = 217078, upload-time = "2025-09-08T23:22:39.776Z" },
- { url = "https://files.pythonhosted.org/packages/2b/c0/015b25184413d7ab0a410775fdb4a50fca20f5589b5dab1dbbfa3baad8ce/cffi-2.0.0-cp311-cp311-win32.whl", hash = "sha256:c649e3a33450ec82378822b3dad03cc228b8f5963c0c12fc3b1e0ab940f768a5", size = 172076, upload-time = "2025-09-08T23:22:40.95Z" },
- { url = "https://files.pythonhosted.org/packages/ae/8f/dc5531155e7070361eb1b7e4c1a9d896d0cb21c49f807a6c03fd63fc877e/cffi-2.0.0-cp311-cp311-win_amd64.whl", hash = "sha256:66f011380d0e49ed280c789fbd08ff0d40968ee7b665575489afa95c98196ab5", size = 182820, upload-time = "2025-09-08T23:22:42.463Z" },
- { url = "https://files.pythonhosted.org/packages/95/5c/1b493356429f9aecfd56bc171285a4c4ac8697f76e9bbbbb105e537853a1/cffi-2.0.0-cp311-cp311-win_arm64.whl", hash = "sha256:c6638687455baf640e37344fe26d37c404db8b80d037c3d29f58fe8d1c3b194d", size = 177635, upload-time = "2025-09-08T23:22:43.623Z" },
- { url = "https://files.pythonhosted.org/packages/ea/47/4f61023ea636104d4f16ab488e268b93008c3d0bb76893b1b31db1f96802/cffi-2.0.0-cp312-cp312-macosx_10_13_x86_64.whl", hash = "sha256:6d02d6655b0e54f54c4ef0b94eb6be0607b70853c45ce98bd278dc7de718be5d", size = 185271, upload-time = "2025-09-08T23:22:44.795Z" },
- { url = "https://files.pythonhosted.org/packages/df/a2/781b623f57358e360d62cdd7a8c681f074a71d445418a776eef0aadb4ab4/cffi-2.0.0-cp312-cp312-macosx_11_0_arm64.whl", hash = "sha256:8eca2a813c1cb7ad4fb74d368c2ffbbb4789d377ee5bb8df98373c2cc0dee76c", size = 181048, upload-time = "2025-09-08T23:22:45.938Z" },
- { url = "https://files.pythonhosted.org/packages/ff/df/a4f0fbd47331ceeba3d37c2e51e9dfc9722498becbeec2bd8bc856c9538a/cffi-2.0.0-cp312-cp312-manylinux1_i686.manylinux2014_i686.manylinux_2_17_i686.manylinux_2_5_i686.whl", hash = "sha256:21d1152871b019407d8ac3985f6775c079416c282e431a4da6afe7aefd2bccbe", size = 212529, upload-time = "2025-09-08T23:22:47.349Z" },
- { url = "https://files.pythonhosted.org/packages/d5/72/12b5f8d3865bf0f87cf1404d8c374e7487dcf097a1c91c436e72e6badd83/cffi-2.0.0-cp312-cp312-manylinux2014_aarch64.manylinux_2_17_aarch64.whl", hash = "sha256:b21e08af67b8a103c71a250401c78d5e0893beff75e28c53c98f4de42f774062", size = 220097, upload-time = "2025-09-08T23:22:48.677Z" },
- { url = "https://files.pythonhosted.org/packages/c2/95/7a135d52a50dfa7c882ab0ac17e8dc11cec9d55d2c18dda414c051c5e69e/cffi-2.0.0-cp312-cp312-manylinux2014_ppc64le.manylinux_2_17_ppc64le.whl", hash = "sha256:1e3a615586f05fc4065a8b22b8152f0c1b00cdbc60596d187c2a74f9e3036e4e", size = 207983, upload-time = "2025-09-08T23:22:50.06Z" },
- { url = "https://files.pythonhosted.org/packages/3a/c8/15cb9ada8895957ea171c62dc78ff3e99159ee7adb13c0123c001a2546c1/cffi-2.0.0-cp312-cp312-manylinux2014_s390x.manylinux_2_17_s390x.whl", hash = "sha256:81afed14892743bbe14dacb9e36d9e0e504cd204e0b165062c488942b9718037", size = 206519, upload-time = "2025-09-08T23:22:51.364Z" },
- { url = "https://files.pythonhosted.org/packages/78/2d/7fa73dfa841b5ac06c7b8855cfc18622132e365f5b81d02230333ff26e9e/cffi-2.0.0-cp312-cp312-manylinux2014_x86_64.manylinux_2_17_x86_64.whl", hash = "sha256:3e17ed538242334bf70832644a32a7aae3d83b57567f9fd60a26257e992b79ba", size = 219572, upload-time = "2025-09-08T23:22:52.902Z" },
- { url = "https://files.pythonhosted.org/packages/07/e0/267e57e387b4ca276b90f0434ff88b2c2241ad72b16d31836adddfd6031b/cffi-2.0.0-cp312-cp312-musllinux_1_2_aarch64.whl", hash = "sha256:3925dd22fa2b7699ed2617149842d2e6adde22b262fcbfada50e3d195e4b3a94", size = 222963, upload-time = "2025-09-08T23:22:54.518Z" },
- { url = "https://files.pythonhosted.org/packages/b6/75/1f2747525e06f53efbd878f4d03bac5b859cbc11c633d0fb81432d98a795/cffi-2.0.0-cp312-cp312-musllinux_1_2_x86_64.whl", hash = "sha256:2c8f814d84194c9ea681642fd164267891702542f028a15fc97d4674b6206187", size = 221361, upload-time = "2025-09-08T23:22:55.867Z" },
- { url = "https://files.pythonhosted.org/packages/7b/2b/2b6435f76bfeb6bbf055596976da087377ede68df465419d192acf00c437/cffi-2.0.0-cp312-cp312-win32.whl", hash = "sha256:da902562c3e9c550df360bfa53c035b2f241fed6d9aef119048073680ace4a18", size = 172932, upload-time = "2025-09-08T23:22:57.188Z" },
- { url = "https://files.pythonhosted.org/packages/f8/ed/13bd4418627013bec4ed6e54283b1959cf6db888048c7cf4b4c3b5b36002/cffi-2.0.0-cp312-cp312-win_amd64.whl", hash = "sha256:da68248800ad6320861f129cd9c1bf96ca849a2771a59e0344e88681905916f5", size = 183557, upload-time = "2025-09-08T23:22:58.351Z" },
- { url = "https://files.pythonhosted.org/packages/95/31/9f7f93ad2f8eff1dbc1c3656d7ca5bfd8fb52c9d786b4dcf19b2d02217fa/cffi-2.0.0-cp312-cp312-win_arm64.whl", hash = "sha256:4671d9dd5ec934cb9a73e7ee9676f9362aba54f7f34910956b84d727b0d73fb6", size = 177762, upload-time = "2025-09-08T23:22:59.668Z" },
- { url = "https://files.pythonhosted.org/packages/4b/8d/a0a47a0c9e413a658623d014e91e74a50cdd2c423f7ccfd44086ef767f90/cffi-2.0.0-cp313-cp313-macosx_10_13_x86_64.whl", hash = "sha256:00bdf7acc5f795150faa6957054fbbca2439db2f775ce831222b66f192f03beb", size = 185230, upload-time = "2025-09-08T23:23:00.879Z" },
- { url = "https://files.pythonhosted.org/packages/4a/d2/a6c0296814556c68ee32009d9c2ad4f85f2707cdecfd7727951ec228005d/cffi-2.0.0-cp313-cp313-macosx_11_0_arm64.whl", hash = "sha256:45d5e886156860dc35862657e1494b9bae8dfa63bf56796f2fb56e1679fc0bca", size = 181043, upload-time = "2025-09-08T23:23:02.231Z" },
- { url = "https://files.pythonhosted.org/packages/b0/1e/d22cc63332bd59b06481ceaac49d6c507598642e2230f201649058a7e704/cffi-2.0.0-cp313-cp313-manylinux1_i686.manylinux2014_i686.manylinux_2_17_i686.manylinux_2_5_i686.whl", hash = "sha256:07b271772c100085dd28b74fa0cd81c8fb1a3ba18b21e03d7c27f3436a10606b", size = 212446, upload-time = "2025-09-08T23:23:03.472Z" },
- { url = "https://files.pythonhosted.org/packages/a9/f5/a2c23eb03b61a0b8747f211eb716446c826ad66818ddc7810cc2cc19b3f2/cffi-2.0.0-cp313-cp313-manylinux2014_aarch64.manylinux_2_17_aarch64.whl", hash = "sha256:d48a880098c96020b02d5a1f7d9251308510ce8858940e6fa99ece33f610838b", size = 220101, upload-time = "2025-09-08T23:23:04.792Z" },
- { url = "https://files.pythonhosted.org/packages/f2/7f/e6647792fc5850d634695bc0e6ab4111ae88e89981d35ac269956605feba/cffi-2.0.0-cp313-cp313-manylinux2014_ppc64le.manylinux_2_17_ppc64le.whl", hash = "sha256:f93fd8e5c8c0a4aa1f424d6173f14a892044054871c771f8566e4008eaa359d2", size = 207948, upload-time = "2025-09-08T23:23:06.127Z" },
- { url = "https://files.pythonhosted.org/packages/cb/1e/a5a1bd6f1fb30f22573f76533de12a00bf274abcdc55c8edab639078abb6/cffi-2.0.0-cp313-cp313-manylinux2014_s390x.manylinux_2_17_s390x.whl", hash = "sha256:dd4f05f54a52fb558f1ba9f528228066954fee3ebe629fc1660d874d040ae5a3", size = 206422, upload-time = "2025-09-08T23:23:07.753Z" },
- { url = "https://files.pythonhosted.org/packages/98/df/0a1755e750013a2081e863e7cd37e0cdd02664372c754e5560099eb7aa44/cffi-2.0.0-cp313-cp313-manylinux2014_x86_64.manylinux_2_17_x86_64.whl", hash = "sha256:c8d3b5532fc71b7a77c09192b4a5a200ea992702734a2e9279a37f2478236f26", size = 219499, upload-time = "2025-09-08T23:23:09.648Z" },
- { url = "https://files.pythonhosted.org/packages/50/e1/a969e687fcf9ea58e6e2a928ad5e2dd88cc12f6f0ab477e9971f2309b57c/cffi-2.0.0-cp313-cp313-musllinux_1_2_aarch64.whl", hash = "sha256:d9b29c1f0ae438d5ee9acb31cadee00a58c46cc9c0b2f9038c6b0b3470877a8c", size = 222928, upload-time = "2025-09-08T23:23:10.928Z" },
- { url = "https://files.pythonhosted.org/packages/36/54/0362578dd2c9e557a28ac77698ed67323ed5b9775ca9d3fe73fe191bb5d8/cffi-2.0.0-cp313-cp313-musllinux_1_2_x86_64.whl", hash = "sha256:6d50360be4546678fc1b79ffe7a66265e28667840010348dd69a314145807a1b", size = 221302, upload-time = "2025-09-08T23:23:12.42Z" },
- { url = "https://files.pythonhosted.org/packages/eb/6d/bf9bda840d5f1dfdbf0feca87fbdb64a918a69bca42cfa0ba7b137c48cb8/cffi-2.0.0-cp313-cp313-win32.whl", hash = "sha256:74a03b9698e198d47562765773b4a8309919089150a0bb17d829ad7b44b60d27", size = 172909, upload-time = "2025-09-08T23:23:14.32Z" },
- { url = "https://files.pythonhosted.org/packages/37/18/6519e1ee6f5a1e579e04b9ddb6f1676c17368a7aba48299c3759bbc3c8b3/cffi-2.0.0-cp313-cp313-win_amd64.whl", hash = "sha256:19f705ada2530c1167abacb171925dd886168931e0a7b78f5bffcae5c6b5be75", size = 183402, upload-time = "2025-09-08T23:23:15.535Z" },
- { url = "https://files.pythonhosted.org/packages/cb/0e/02ceeec9a7d6ee63bb596121c2c8e9b3a9e150936f4fbef6ca1943e6137c/cffi-2.0.0-cp313-cp313-win_arm64.whl", hash = "sha256:256f80b80ca3853f90c21b23ee78cd008713787b1b1e93eae9f3d6a7134abd91", size = 177780, upload-time = "2025-09-08T23:23:16.761Z" },
- { url = "https://files.pythonhosted.org/packages/92/c4/3ce07396253a83250ee98564f8d7e9789fab8e58858f35d07a9a2c78de9f/cffi-2.0.0-cp314-cp314-macosx_10_13_x86_64.whl", hash = "sha256:fc33c5141b55ed366cfaad382df24fe7dcbc686de5be719b207bb248e3053dc5", size = 185320, upload-time = "2025-09-08T23:23:18.087Z" },
- { url = "https://files.pythonhosted.org/packages/59/dd/27e9fa567a23931c838c6b02d0764611c62290062a6d4e8ff7863daf9730/cffi-2.0.0-cp314-cp314-macosx_11_0_arm64.whl", hash = "sha256:c654de545946e0db659b3400168c9ad31b5d29593291482c43e3564effbcee13", size = 181487, upload-time = "2025-09-08T23:23:19.622Z" },
- { url = "https://files.pythonhosted.org/packages/d6/43/0e822876f87ea8a4ef95442c3d766a06a51fc5298823f884ef87aaad168c/cffi-2.0.0-cp314-cp314-manylinux2014_aarch64.manylinux_2_17_aarch64.whl", hash = "sha256:24b6f81f1983e6df8db3adc38562c83f7d4a0c36162885ec7f7b77c7dcbec97b", size = 220049, upload-time = "2025-09-08T23:23:20.853Z" },
- { url = "https://files.pythonhosted.org/packages/b4/89/76799151d9c2d2d1ead63c2429da9ea9d7aac304603de0c6e8764e6e8e70/cffi-2.0.0-cp314-cp314-manylinux2014_ppc64le.manylinux_2_17_ppc64le.whl", hash = "sha256:12873ca6cb9b0f0d3a0da705d6086fe911591737a59f28b7936bdfed27c0d47c", size = 207793, upload-time = "2025-09-08T23:23:22.08Z" },
- { url = "https://files.pythonhosted.org/packages/bb/dd/3465b14bb9e24ee24cb88c9e3730f6de63111fffe513492bf8c808a3547e/cffi-2.0.0-cp314-cp314-manylinux2014_s390x.manylinux_2_17_s390x.whl", hash = "sha256:d9b97165e8aed9272a6bb17c01e3cc5871a594a446ebedc996e2397a1c1ea8ef", size = 206300, upload-time = "2025-09-08T23:23:23.314Z" },
- { url = "https://files.pythonhosted.org/packages/47/d9/d83e293854571c877a92da46fdec39158f8d7e68da75bf73581225d28e90/cffi-2.0.0-cp314-cp314-manylinux2014_x86_64.manylinux_2_17_x86_64.whl", hash = "sha256:afb8db5439b81cf9c9d0c80404b60c3cc9c3add93e114dcae767f1477cb53775", size = 219244, upload-time = "2025-09-08T23:23:24.541Z" },
- { url = "https://files.pythonhosted.org/packages/2b/0f/1f177e3683aead2bb00f7679a16451d302c436b5cbf2505f0ea8146ef59e/cffi-2.0.0-cp314-cp314-musllinux_1_2_aarch64.whl", hash = "sha256:737fe7d37e1a1bffe70bd5754ea763a62a066dc5913ca57e957824b72a85e205", size = 222828, upload-time = "2025-09-08T23:23:26.143Z" },
- { url = "https://files.pythonhosted.org/packages/c6/0f/cafacebd4b040e3119dcb32fed8bdef8dfe94da653155f9d0b9dc660166e/cffi-2.0.0-cp314-cp314-musllinux_1_2_x86_64.whl", hash = "sha256:38100abb9d1b1435bc4cc340bb4489635dc2f0da7456590877030c9b3d40b0c1", size = 220926, upload-time = "2025-09-08T23:23:27.873Z" },
- { url = "https://files.pythonhosted.org/packages/3e/aa/df335faa45b395396fcbc03de2dfcab242cd61a9900e914fe682a59170b1/cffi-2.0.0-cp314-cp314-win32.whl", hash = "sha256:087067fa8953339c723661eda6b54bc98c5625757ea62e95eb4898ad5e776e9f", size = 175328, upload-time = "2025-09-08T23:23:44.61Z" },
- { url = "https://files.pythonhosted.org/packages/bb/92/882c2d30831744296ce713f0feb4c1cd30f346ef747b530b5318715cc367/cffi-2.0.0-cp314-cp314-win_amd64.whl", hash = "sha256:203a48d1fb583fc7d78a4c6655692963b860a417c0528492a6bc21f1aaefab25", size = 185650, upload-time = "2025-09-08T23:23:45.848Z" },
- { url = "https://files.pythonhosted.org/packages/9f/2c/98ece204b9d35a7366b5b2c6539c350313ca13932143e79dc133ba757104/cffi-2.0.0-cp314-cp314-win_arm64.whl", hash = "sha256:dbd5c7a25a7cb98f5ca55d258b103a2054f859a46ae11aaf23134f9cc0d356ad", size = 180687, upload-time = "2025-09-08T23:23:47.105Z" },
- { url = "https://files.pythonhosted.org/packages/3e/61/c768e4d548bfa607abcda77423448df8c471f25dbe64fb2ef6d555eae006/cffi-2.0.0-cp314-cp314t-macosx_10_13_x86_64.whl", hash = "sha256:9a67fc9e8eb39039280526379fb3a70023d77caec1852002b4da7e8b270c4dd9", size = 188773, upload-time = "2025-09-08T23:23:29.347Z" },
- { url = "https://files.pythonhosted.org/packages/2c/ea/5f76bce7cf6fcd0ab1a1058b5af899bfbef198bea4d5686da88471ea0336/cffi-2.0.0-cp314-cp314t-macosx_11_0_arm64.whl", hash = "sha256:7a66c7204d8869299919db4d5069a82f1561581af12b11b3c9f48c584eb8743d", size = 185013, upload-time = "2025-09-08T23:23:30.63Z" },
- { url = "https://files.pythonhosted.org/packages/be/b4/c56878d0d1755cf9caa54ba71e5d049479c52f9e4afc230f06822162ab2f/cffi-2.0.0-cp314-cp314t-manylinux2014_aarch64.manylinux_2_17_aarch64.whl", hash = "sha256:7cc09976e8b56f8cebd752f7113ad07752461f48a58cbba644139015ac24954c", size = 221593, upload-time = "2025-09-08T23:23:31.91Z" },
- { url = "https://files.pythonhosted.org/packages/e0/0d/eb704606dfe8033e7128df5e90fee946bbcb64a04fcdaa97321309004000/cffi-2.0.0-cp314-cp314t-manylinux2014_ppc64le.manylinux_2_17_ppc64le.whl", hash = "sha256:92b68146a71df78564e4ef48af17551a5ddd142e5190cdf2c5624d0c3ff5b2e8", size = 209354, upload-time = "2025-09-08T23:23:33.214Z" },
- { url = "https://files.pythonhosted.org/packages/d8/19/3c435d727b368ca475fb8742ab97c9cb13a0de600ce86f62eab7fa3eea60/cffi-2.0.0-cp314-cp314t-manylinux2014_s390x.manylinux_2_17_s390x.whl", hash = "sha256:b1e74d11748e7e98e2f426ab176d4ed720a64412b6a15054378afdb71e0f37dc", size = 208480, upload-time = "2025-09-08T23:23:34.495Z" },
- { url = "https://files.pythonhosted.org/packages/d0/44/681604464ed9541673e486521497406fadcc15b5217c3e326b061696899a/cffi-2.0.0-cp314-cp314t-manylinux2014_x86_64.manylinux_2_17_x86_64.whl", hash = "sha256:28a3a209b96630bca57cce802da70c266eb08c6e97e5afd61a75611ee6c64592", size = 221584, upload-time = "2025-09-08T23:23:36.096Z" },
- { url = "https://files.pythonhosted.org/packages/25/8e/342a504ff018a2825d395d44d63a767dd8ebc927ebda557fecdaca3ac33a/cffi-2.0.0-cp314-cp314t-musllinux_1_2_aarch64.whl", hash = "sha256:7553fb2090d71822f02c629afe6042c299edf91ba1bf94951165613553984512", size = 224443, upload-time = "2025-09-08T23:23:37.328Z" },
- { url = "https://files.pythonhosted.org/packages/e1/5e/b666bacbbc60fbf415ba9988324a132c9a7a0448a9a8f125074671c0f2c3/cffi-2.0.0-cp314-cp314t-musllinux_1_2_x86_64.whl", hash = "sha256:6c6c373cfc5c83a975506110d17457138c8c63016b563cc9ed6e056a82f13ce4", size = 223437, upload-time = "2025-09-08T23:23:38.945Z" },
- { url = "https://files.pythonhosted.org/packages/a0/1d/ec1a60bd1a10daa292d3cd6bb0b359a81607154fb8165f3ec95fe003b85c/cffi-2.0.0-cp314-cp314t-win32.whl", hash = "sha256:1fc9ea04857caf665289b7a75923f2c6ed559b8298a1b8c49e59f7dd95c8481e", size = 180487, upload-time = "2025-09-08T23:23:40.423Z" },
- { url = "https://files.pythonhosted.org/packages/bf/41/4c1168c74fac325c0c8156f04b6749c8b6a8f405bbf91413ba088359f60d/cffi-2.0.0-cp314-cp314t-win_amd64.whl", hash = "sha256:d68b6cef7827e8641e8ef16f4494edda8b36104d79773a334beaa1e3521430f6", size = 191726, upload-time = "2025-09-08T23:23:41.742Z" },
- { url = "https://files.pythonhosted.org/packages/ae/3a/dbeec9d1ee0844c679f6bb5d6ad4e9f198b1224f4e7a32825f47f6192b0c/cffi-2.0.0-cp314-cp314t-win_arm64.whl", hash = "sha256:0a1527a803f0a659de1af2e1fd700213caba79377e27e4693648c2923da066f9", size = 184195, upload-time = "2025-09-08T23:23:43.004Z" },
-]
-
[[package]]
name = "charset-normalizer"
version = "3.4.1"
@@ -475,106 +131,6 @@ wheels = [
{ url = "https://files.pythonhosted.org/packages/d1/d6/3965ed04c63042e047cb6a3e6ed1a63a35087b6a609aa3a15ed8ac56c221/colorama-0.4.6-py2.py3-none-any.whl", hash = "sha256:4f1d9991f5acc0ca119f9d443620b77f9d6b33703e51011c16baf57afb285fc6", size = 25335, upload-time = "2022-10-25T02:36:20.889Z" },
]
-[[package]]
-name = "cryptography"
-version = "48.0.1"
-source = { registry = "https://pypi.org/simple" }
-dependencies = [
- { name = "cffi", marker = "platform_python_implementation != 'PyPy'" },
- { name = "typing-extensions", marker = "python_full_version < '3.11'" },
-]
-sdist = { url = "https://files.pythonhosted.org/packages/12/45/870e7f4bef50e5f53b9f51d4428aee5290eedf58ba443f16b1ebb7ab8e66/cryptography-48.0.1.tar.gz", hash = "sha256:266f4ee051abb2f725b74ef8072b521ce1feacf685a3364fa6a6b45548db791a", size = 832989, upload-time = "2026-06-09T22:32:31.8Z" }
-wheels = [
- { url = "https://files.pythonhosted.org/packages/1b/bc/ee4137cbbe105652c0ee4252792b78fc8e7afa4b8e61d9d5dc05a7f45731/cryptography-48.0.1-cp311-abi3-macosx_10_9_universal2.whl", hash = "sha256:3e4a1a3232eef2e6c732827d5722db29a0cc8b27af2a4d865b094cf954be9ca1", size = 8008324, upload-time = "2026-06-09T22:31:00.702Z" },
- { url = "https://files.pythonhosted.org/packages/d5/85/6379d42181bfc713094f081360fc5784d6c816b599d45e7f082502d173ce/cryptography-48.0.1-cp311-abi3-manylinux2014_aarch64.manylinux_2_17_aarch64.whl", hash = "sha256:32143b24adb918f078134e1e230f1eb8cc04886b92c28b5f0041aaf3e5699225", size = 4696243, upload-time = "2026-06-09T22:32:33.446Z" },
- { url = "https://files.pythonhosted.org/packages/9c/87/c85d147b53323c7eb4d850920c8901377323c2a0ff8d79c262d4fee89aa2/cryptography-48.0.1-cp311-abi3-manylinux2014_x86_64.manylinux_2_17_x86_64.whl", hash = "sha256:f0d27a5696721ef7a672b8c810f6aded391058e0b9486e63e6d93baf765da691", size = 4713235, upload-time = "2026-06-09T22:31:40.141Z" },
- { url = "https://files.pythonhosted.org/packages/79/58/67cbf8cf1ee7c54b439ca07bbecf8362c07afc11a3724fea70f745784add/cryptography-48.0.1-cp311-abi3-manylinux_2_28_aarch64.whl", hash = "sha256:eb86ce1af36fe65041b6db9a8bb064ee621a7e5fded0f80d475ec243477cd242", size = 4702323, upload-time = "2026-06-09T22:31:42.191Z" },
- { url = "https://files.pythonhosted.org/packages/89/c6/24266ac10c47f6cd2a865f4446062b466da1d1f10b27189eac00e61bf0c9/cryptography-48.0.1-cp311-abi3-manylinux_2_28_ppc64le.whl", hash = "sha256:b024e784ad6c077ee0147b35ea9cbfc1e34e1fd4c1dcca214c2794d73a12df08", size = 5300085, upload-time = "2026-06-09T22:31:58.703Z" },
- { url = "https://files.pythonhosted.org/packages/d2/bb/cc4b78784f97efc8c5874c2a9743708d172be6663024b34a0467885ae0c8/cryptography-48.0.1-cp311-abi3-manylinux_2_28_x86_64.whl", hash = "sha256:3752f2dbc8f07a30aad2932c986cea495b03bb554887828225da104f732852b6", size = 4746137, upload-time = "2026-06-09T22:31:31.01Z" },
- { url = "https://files.pythonhosted.org/packages/1f/52/0c44de3f5267f8fbe8e835138017522a333436166e406f0db9b9e6e3033f/cryptography-48.0.1-cp311-abi3-manylinux_2_31_armv7l.whl", hash = "sha256:bd81490cd5801d755cf97bb68ac191f14b708470b1c7cf4580f669b9c9264cd8", size = 4333867, upload-time = "2026-06-09T22:32:28.096Z" },
- { url = "https://files.pythonhosted.org/packages/9a/2e/772d7adbfa931537bc401640b7cac9976bff689bda187833e5d63b428e49/cryptography-48.0.1-cp311-abi3-manylinux_2_34_aarch64.whl", hash = "sha256:66fd0771e7b9c6dcd44cf1120690d2338d16d72795cf40cae2786a39eba65429", size = 4701805, upload-time = "2026-06-09T22:31:38.284Z" },
- { url = "https://files.pythonhosted.org/packages/f8/a3/b06844f303873493c963caf581c04df31c7035e0c1b0f02c4814d319ec80/cryptography-48.0.1-cp311-abi3-manylinux_2_34_ppc64le.whl", hash = "sha256:3fd2ca57062b241c856670b073487d2e86c4637937ca5601e48f97bf8e11fc8f", size = 5258461, upload-time = "2026-06-09T22:31:04.187Z" },
- { url = "https://files.pythonhosted.org/packages/9f/13/8b765e2e12b07c74941caadb9d1c8fdc006c4dfbf2b8f2d610519758954d/cryptography-48.0.1-cp311-abi3-manylinux_2_34_x86_64.whl", hash = "sha256:0ee6ea481db1ab889cba043ec1eda17bb9c1ea79db6722f779c3667f9f70322f", size = 4745488, upload-time = "2026-06-09T22:32:30.07Z" },
- { url = "https://files.pythonhosted.org/packages/2e/aa/48972bce55049b32a94f4907eda4d75fa385aad8a39506cc2fc72196ecf0/cryptography-48.0.1-cp311-abi3-musllinux_1_2_aarch64.whl", hash = "sha256:f2ceef93cb096aa3c4cc4b5c94ca6131f9196d28c64d6111533402a9b2054d41", size = 4830256, upload-time = "2026-06-09T22:31:43.868Z" },
- { url = "https://files.pythonhosted.org/packages/47/a2/e5079a032fb85cf6005046ca92bbd78b0c82dad2b5751ab8c311659da06f/cryptography-48.0.1-cp311-abi3-musllinux_1_2_x86_64.whl", hash = "sha256:9bd3f92d76217892b15df84ca256c2c113d386fdda7a7d8691aeeced976507c6", size = 4979117, upload-time = "2026-06-09T22:31:05.845Z" },
- { url = "https://files.pythonhosted.org/packages/b7/a0/8f50cae9c74e718ed769d63ed5c74bd0ea830c9550a74629cebd1b9c7bc7/cryptography-48.0.1-cp311-abi3-win32.whl", hash = "sha256:b9a32b876490d66c8bcc9963ef220199569748434ab01a9d6aaeabf88e7f5158", size = 3304154, upload-time = "2026-06-09T22:32:16.845Z" },
- { url = "https://files.pythonhosted.org/packages/c5/69/0572c77dbace6fef72f33755bd52ea399c71367250d366237f8691826b9e/cryptography-48.0.1-cp311-abi3-win_amd64.whl", hash = "sha256:39489bfca54c7a1f6b297efcd8bc608ab92d16c4ca631b0cad4da46724588b24", size = 3817138, upload-time = "2026-06-09T22:32:00.388Z" },
- { url = "https://files.pythonhosted.org/packages/42/06/3e768b4c3bc78201583fa35a0e18f640dd782ff41afba88f8545481a8874/cryptography-48.0.1-cp314-cp314t-macosx_10_9_universal2.whl", hash = "sha256:f817adc181390bd54f2f700107a7419040fb7c1bdf2fc26f36551a06a68c3345", size = 7989830, upload-time = "2026-06-09T22:31:07.8Z" },
- { url = "https://files.pythonhosted.org/packages/8a/13/6476736484b94041110c8340a3eb63962fea4975baea8cb4a512adb44d4d/cryptography-48.0.1-cp314-cp314t-manylinux2014_aarch64.manylinux_2_17_aarch64.whl", hash = "sha256:d5d30989c6917b478b5817902e85fddaea2261efa8648383d965381ccb9e1ac4", size = 4689201, upload-time = "2026-06-09T22:31:09.745Z" },
- { url = "https://files.pythonhosted.org/packages/79/62/65a87f34d2a431546e2509b85d55e8c90df86d668f6731da64d538512ac2/cryptography-48.0.1-cp314-cp314t-manylinux2014_x86_64.manylinux_2_17_x86_64.whl", hash = "sha256:df637c05205ea7c1d7fbcbe54bbfea648a52951155f997af13d895d0ecc96991", size = 4702822, upload-time = "2026-06-09T22:32:24.409Z" },
- { url = "https://files.pythonhosted.org/packages/7f/59/810b5204b0a9b10f4b6bc06bd551a8b609803cd931806bc3b71884b225e5/cryptography-48.0.1-cp314-cp314t-manylinux_2_28_aarch64.whl", hash = "sha256:869c3b8a53bfe27147832df48b32adadf558249d50e76cb3769d40e986b13265", size = 4694875, upload-time = "2026-06-09T22:32:08.737Z" },
- { url = "https://files.pythonhosted.org/packages/24/dc/d8ca05ffea724eec6d232ea6f18e74c269eb6bdfdcc9bfba689790d1325f/cryptography-48.0.1-cp314-cp314t-manylinux_2_28_ppc64le.whl", hash = "sha256:e361afba8918070d376df76f408a4f67fec0ee9cff81a99e48fe9a233ef59e17", size = 5290385, upload-time = "2026-06-09T22:31:15.212Z" },
- { url = "https://files.pythonhosted.org/packages/03/8c/3be6cb4da181f5bb6c19cf560c2359d60644a6b5fc5b57854e528f47b296/cryptography-48.0.1-cp314-cp314t-manylinux_2_28_x86_64.whl", hash = "sha256:d069066deead00ac7f090be101be875a06855908f7ec004c27b8fefb4acfb411", size = 4737082, upload-time = "2026-06-09T22:32:22.66Z" },
- { url = "https://files.pythonhosted.org/packages/aa/f6/d5f60a5a1434dbfd949e227fd0065d194c7e6b6ac526b17f5c06152b8231/cryptography-48.0.1-cp314-cp314t-manylinux_2_31_armv7l.whl", hash = "sha256:09f73a725d582cef64b91281a322cd798d14a33b2b6f2b7ad9531dc336d84c02", size = 4325328, upload-time = "2026-06-09T22:32:10.777Z" },
- { url = "https://files.pythonhosted.org/packages/17/b7/ba75dd947a14b6ad907b01ae8f6b5b348cdd1b48142f0063dee9e20c1d9d/cryptography-48.0.1-cp314-cp314t-manylinux_2_34_aarch64.whl", hash = "sha256:15254441469dd6bf027039453288e2072124f8b6603563f5d759e1c9b69273fa", size = 4694530, upload-time = "2026-06-09T22:31:53.105Z" },
- { url = "https://files.pythonhosted.org/packages/62/29/50d6b9e8aff12d8b67afaeb3569335e32dc83a5723e3bbded24fdac9f809/cryptography-48.0.1-cp314-cp314t-manylinux_2_34_ppc64le.whl", hash = "sha256:8ace4507d1e6533c125f4fac754f8bb8b6a74c08e92179dabd7e16571a3efbf3", size = 5245046, upload-time = "2026-06-09T22:31:25.774Z" },
- { url = "https://files.pythonhosted.org/packages/9f/04/618f4115cfc0add0838c82507aa18a346089428da8653ad38b3ff36f5cb3/cryptography-48.0.1-cp314-cp314t-manylinux_2_34_x86_64.whl", hash = "sha256:b4e391975f038e66432328639620a4aff2d307513b004f1ca06d6225bced815c", size = 4736660, upload-time = "2026-06-09T22:32:12.676Z" },
- { url = "https://files.pythonhosted.org/packages/24/9c/06e062462a0de28a3b3911322eded4c16deb9f441b1b7575d3dc59488ab5/cryptography-48.0.1-cp314-cp314t-musllinux_1_2_aarch64.whl", hash = "sha256:42fcd8e26fe555d9b3577a135f5091fefa0aa4e99129c23fb56787a1bd4ada72", size = 4822229, upload-time = "2026-06-09T22:31:17.062Z" },
- { url = "https://files.pythonhosted.org/packages/f4/be/0561971eaaee4b8a0e7d5113c536921063ab91aaf23278ac374eaf881e11/cryptography-48.0.1-cp314-cp314t-musllinux_1_2_x86_64.whl", hash = "sha256:c1400da5e32a43253392277eac7490a60e497d810a63dd5608d71bbd7af507c9", size = 4966364, upload-time = "2026-06-09T22:31:32.842Z" },
- { url = "https://files.pythonhosted.org/packages/a4/27/728c77876f12b000820b69ae490f3c4083775e79e07827e9e60be07ad209/cryptography-48.0.1-cp314-cp314t-win32.whl", hash = "sha256:0df56b056bc17c1b7d6821dfa65216e62bd232d8ab05eb3db44e71d235651471", size = 3278498, upload-time = "2026-06-09T22:31:29.154Z" },
- { url = "https://files.pythonhosted.org/packages/06/e3/79a612c6d7b1e6ee0edd43633d53035bec2cfb78c82b76f7864f39e36f34/cryptography-48.0.1-cp314-cp314t-win_amd64.whl", hash = "sha256:9de21387aa95e2a895823d0745b430bed4f33503ba9ab5e0b5311f33e37d66d2", size = 3798790, upload-time = "2026-06-09T22:31:56.697Z" },
- { url = "https://files.pythonhosted.org/packages/ca/6c/00fa2a95997164c8b2072ce327c23d4ab20809ccc323ea5fab91e53a4bba/cryptography-48.0.1-cp39-abi3-macosx_10_9_universal2.whl", hash = "sha256:4fdc69f8e4316bcf0c8c8ec1f26f285d12e8142d88d96c876a59a03be3f6ae67", size = 7987408, upload-time = "2026-06-09T22:32:20.777Z" },
- { url = "https://files.pythonhosted.org/packages/b0/d9/45f309a7e4e5f3f8f121d6d3be9e94024a7726ec598d6e08ae04edb2f04d/cryptography-48.0.1-cp39-abi3-manylinux2014_aarch64.manylinux_2_17_aarch64.whl", hash = "sha256:48fe40804d4caa2288f24e70ca8c64c42dd826da0ad7e4f1b41b2128d679e6c8", size = 4690196, upload-time = "2026-06-09T22:31:54.74Z" },
- { url = "https://files.pythonhosted.org/packages/5f/9f/a1bc8bcc798811b8527eb374bbccf30a3f3e806829d967118222bf1125eb/cryptography-48.0.1-cp39-abi3-manylinux2014_x86_64.manylinux_2_17_x86_64.whl", hash = "sha256:86be3b1b0b6bf09482fb50a979c508d2950ed95f5621ec77f4e385962006b83a", size = 4696782, upload-time = "2026-06-09T22:31:45.615Z" },
- { url = "https://files.pythonhosted.org/packages/66/c2/81a4fb4e4373c500bb526bc337ac5719dd31dd15b970b84a238168c6aa08/cryptography-48.0.1-cp39-abi3-manylinux_2_28_aarch64.whl", hash = "sha256:4ab0a343c807bbcd90c971cd1ecf072937cd01847a9e002bef88fb47ac6be577", size = 4696618, upload-time = "2026-06-09T22:31:11.564Z" },
- { url = "https://files.pythonhosted.org/packages/e5/0b/aa68b221dde92d09cb29a024ede17550ee21e77a404e59fc093c82bb51e1/cryptography-48.0.1-cp39-abi3-manylinux_2_28_ppc64le.whl", hash = "sha256:9621de99d2da096006b629979efd8ae7eb2d8b822488d0c89ee4000c306c59b1", size = 5289970, upload-time = "2026-06-09T22:31:20.368Z" },
- { url = "https://files.pythonhosted.org/packages/78/13/fba657f958d2af66ea959a4ba01212632089249d34af1ae48054136344d7/cryptography-48.0.1-cp39-abi3-manylinux_2_28_x86_64.whl", hash = "sha256:88c852a0ae366e262e5a1744b685e6a433dc8788dd2a277e418bf4904203609d", size = 4731873, upload-time = "2026-06-09T22:31:22.253Z" },
- { url = "https://files.pythonhosted.org/packages/4c/4c/9a964756d24a26b3e34dfcb16f961b89838786e6700b635b0d1e3adff4b6/cryptography-48.0.1-cp39-abi3-manylinux_2_31_armv7l.whl", hash = "sha256:43c5835e2cb98c8733d86f57d6fc879b613f5c3478607281c3e36daffc6dd8a6", size = 4330804, upload-time = "2026-06-09T22:31:36.56Z" },
- { url = "https://files.pythonhosted.org/packages/4b/0f/a10f3a6eb12950a10e3a874070283aa2dd5875b2bfd15fad8a3e17b3f13e/cryptography-48.0.1-cp39-abi3-manylinux_2_34_aarch64.whl", hash = "sha256:fe0180af5bf9236518a087e35bf2d9a347d5f5f51e63c579d683ddff424e3d46", size = 4696217, upload-time = "2026-06-09T22:31:13.351Z" },
- { url = "https://files.pythonhosted.org/packages/f3/6f/5cd12f951165ea73ef85266775d97e4c763b2474ccfd816dd69d3a18d6f8/cryptography-48.0.1-cp39-abi3-manylinux_2_34_ppc64le.whl", hash = "sha256:b7a2d1a937a738a881737cec135a38bb61470589b17515b9f73f571d0ae10401", size = 5245252, upload-time = "2026-06-09T22:32:02.193Z" },
- { url = "https://files.pythonhosted.org/packages/68/ab/8aaa12e4516ec4464033ab79b6f3b592bd5a92102467c4ace8a0d970203f/cryptography-48.0.1-cp39-abi3-manylinux_2_34_x86_64.whl", hash = "sha256:b74ca3b8e5ecdd833bf6a002ca41b4793bb27fb8f1c06ffaf2643c9e9140e31b", size = 4731388, upload-time = "2026-06-09T22:32:04.019Z" },
- { url = "https://files.pythonhosted.org/packages/1b/24/50027ea4dca85ec1f40688f3c24fb32ccacd520583c9592c3cc95628e6fb/cryptography-48.0.1-cp39-abi3-musllinux_1_2_aarch64.whl", hash = "sha256:2c37f2461406063b417837f5f3daab668652acd82423efcd7f0a9f04be972de1", size = 4824186, upload-time = "2026-06-09T22:32:18.707Z" },
- { url = "https://files.pythonhosted.org/packages/52/41/04cb5eb17085ade6f50cc611fb657df6a0f5885350de8764ece89c050197/cryptography-48.0.1-cp39-abi3-musllinux_1_2_x86_64.whl", hash = "sha256:86fe77abb1bd87afb251d4d02ada7ecf53a32cee9b67d976abb2e45a13297475", size = 4964539, upload-time = "2026-06-09T22:31:18.793Z" },
- { url = "https://files.pythonhosted.org/packages/36/bf/ed70785c496e89d7e73b7cda2d21f2447fd6d4e821714b8d04ff217fed92/cryptography-48.0.1-cp39-abi3-win32.whl", hash = "sha256:6b2c0c3e6ccf3ade7750f836ef3ee36eea250cc467d45c256895573ac08cc6f1", size = 3282307, upload-time = "2026-06-09T22:30:53.162Z" },
- { url = "https://files.pythonhosted.org/packages/b3/ff/371ea7d252656ee1eb6d83eeeef3d1d0c6baf1d6497687d081ea03814670/cryptography-48.0.1-cp39-abi3-win_amd64.whl", hash = "sha256:9a49ca6c81417f6a5edb50375a60cccdd70fa0a91a5211829dbea74eba94d2ac", size = 3793408, upload-time = "2026-06-09T22:32:15.191Z" },
- { url = "https://files.pythonhosted.org/packages/a9/d3/eb4e394e587341fdad09a09101fa76478ead3a78b0ad63e55c22f0d75c02/cryptography-48.0.1-pp311-pypy311_pp73-macosx_11_0_arm64.whl", hash = "sha256:08a597acce1ff37f347400087776599e2348a3a8bc53b44120e463cd274efe4a", size = 3951747, upload-time = "2026-06-09T22:31:23.871Z" },
- { url = "https://files.pythonhosted.org/packages/e0/4a/3f43451b4f858bfceaaaffc649e6e787e8d4fb332a1d443af39ab02cc8f1/cryptography-48.0.1-pp311-pypy311_pp73-manylinux_2_28_aarch64.whl", hash = "sha256:735824ec41b7f74a7c45fb1591349333e4c696cb6c044e5f46356e560143e4cd", size = 4641226, upload-time = "2026-06-09T22:31:02.532Z" },
- { url = "https://files.pythonhosted.org/packages/73/4e/855584c2c23b09e4ce2d3b9c30e983e679cd60b068c513c6bbdb91e11782/cryptography-48.0.1-pp311-pypy311_pp73-manylinux_2_28_x86_64.whl", hash = "sha256:92a46e1d638daa264ba2971c0b0489c9409787943efae4d60ffda3d091ef832c", size = 4668958, upload-time = "2026-06-09T22:32:06.213Z" },
- { url = "https://files.pythonhosted.org/packages/42/3b/d35750e41d803d1e516fd6d6011f065424924da7af1748cef4cc9cb3ede1/cryptography-48.0.1-pp311-pypy311_pp73-manylinux_2_34_aarch64.whl", hash = "sha256:7e234ac052af99f2700826a5c29ea99d9c1b1f80341cde62d11c8154dc8e0bd9", size = 4640793, upload-time = "2026-06-09T22:32:26.331Z" },
- { url = "https://files.pythonhosted.org/packages/ca/aa/cdb7181fe865285e87e96825aaab239400f1de0c3bfba9bd9769b79f1a92/cryptography-48.0.1-pp311-pypy311_pp73-manylinux_2_34_x86_64.whl", hash = "sha256:33842cf0888951cef5bc7ac724ab844a42044c1727b967b7f8997289a0464f92", size = 4668505, upload-time = "2026-06-09T22:31:27.534Z" },
- { url = "https://files.pythonhosted.org/packages/5d/8c/ce3823c06c2804f194f9e64f0d67fa3f4094a39f2bb1a990cd03603af8fc/cryptography-48.0.1-pp311-pypy311_pp73-win_amd64.whl", hash = "sha256:6184ca7b174f28d7c703f1290d4b297217c45355f77a98f67e9b7f14549ac54a", size = 3742204, upload-time = "2026-06-09T22:31:34.773Z" },
-]
-
-[[package]]
-name = "dict2xml"
-version = "1.7.6"
-source = { registry = "https://pypi.org/simple" }
-sdist = { url = "https://files.pythonhosted.org/packages/07/b3/2db1b077f9a80d30d1729a0af69b7cef8ce5b45c77a1f0f9ebb01b9edce1/dict2xml-1.7.6.tar.gz", hash = "sha256:3e4811f4ef7fca86dede6acf382268ff9bc5735a4aa0e21b465f6eb0c4e81732", size = 15210, upload-time = "2024-08-08T01:12:13.291Z" }
-wheels = [
- { url = "https://files.pythonhosted.org/packages/32/ad/5a193b6461c713058e3c5b6dbec7a9f92230a968650129cc46f32d3c9de2/dict2xml-1.7.6-py3-none-any.whl", hash = "sha256:841a0c1720e4bfa121e958b805f1062fccf5af2970e7a1f81d7fa056f49e5065", size = 8038, upload-time = "2024-08-08T01:12:11.725Z" },
-]
-
-[[package]]
-name = "dnspython"
-version = "2.7.0"
-source = { registry = "https://pypi.org/simple" }
-sdist = { url = "https://files.pythonhosted.org/packages/b5/4a/263763cb2ba3816dd94b08ad3a33d5fdae34ecb856678773cc40a3605829/dnspython-2.7.0.tar.gz", hash = "sha256:ce9c432eda0dc91cf618a5cedf1a4e142651196bbcd2c80e89ed5a907e5cfaf1", size = 345197, upload-time = "2024-10-05T20:14:59.362Z" }
-wheels = [
- { url = "https://files.pythonhosted.org/packages/68/1b/e0a87d256e40e8c888847551b20a017a6b98139178505dc7ffb96f04e954/dnspython-2.7.0-py3-none-any.whl", hash = "sha256:b4c34b7d10b51bcc3a5071e7b8dee77939f1e878477eeecc965e9835f63c6c86", size = 313632, upload-time = "2024-10-05T20:14:57.687Z" },
-]
-
-[[package]]
-name = "email-validator"
-version = "2.2.0"
-source = { registry = "https://pypi.org/simple" }
-dependencies = [
- { name = "dnspython" },
- { name = "idna" },
-]
-sdist = { url = "https://files.pythonhosted.org/packages/48/ce/13508a1ec3f8bb981ae4ca79ea40384becc868bfae97fd1c942bb3a001b1/email_validator-2.2.0.tar.gz", hash = "sha256:cb690f344c617a714f22e66ae771445a1ceb46821152df8e165c5f9a364582b7", size = 48967, upload-time = "2024-06-20T11:30:30.034Z" }
-wheels = [
- { url = "https://files.pythonhosted.org/packages/d7/ee/bf0adb559ad3c786f12bcbc9296b3f5675f529199bef03e2df281fa1fadb/email_validator-2.2.0-py3-none-any.whl", hash = "sha256:561977c2d73ce3611850a06fa56b414621e0c8faa9d66f2611407d87465da631", size = 33521, upload-time = "2024-06-20T11:30:28.248Z" },
-]
-
-[[package]]
-name = "et-xmlfile"
-version = "2.0.0"
-source = { registry = "https://pypi.org/simple" }
-sdist = { url = "https://files.pythonhosted.org/packages/d3/38/af70d7ab1ae9d4da450eeec1fa3918940a5fafb9055e934af8d6eb0c2313/et_xmlfile-2.0.0.tar.gz", hash = "sha256:dab3f4764309081ce75662649be815c4c9081e88f0837825f90fd28317d4da54", size = 17234, upload-time = "2024-10-25T17:25:40.039Z" }
-wheels = [
- { url = "https://files.pythonhosted.org/packages/c1/8b/5fe2cc11fee489817272089c4203e679c63b570a5aaeb18d852ae3cbba6a/et_xmlfile-2.0.0-py3-none-any.whl", hash = "sha256:7a91720bc756843502c3b7504c77b8fe44217c85c537d85037f0f536151b2caa", size = 18059, upload-time = "2024-10-25T17:25:39.051Z" },
-]
-
[[package]]
name = "exceptiongroup"
version = "1.2.2"
@@ -598,75 +154,6 @@ wheels = [
{ url = "https://files.pythonhosted.org/packages/50/b3/b51f09c2ba432a576fe63758bddc81f78f0c6309d9e5c10d194313bf021e/fastapi-0.115.12-py3-none-any.whl", hash = "sha256:e94613d6c05e27be7ffebdd6ea5f388112e5e430c8f7d6494a9d1d88d43e814d", size = 95164, upload-time = "2025-03-23T22:55:42.101Z" },
]
-[[package]]
-name = "frozenlist"
-version = "1.5.0"
-source = { registry = "https://pypi.org/simple" }
-sdist = { url = "https://files.pythonhosted.org/packages/8f/ed/0f4cec13a93c02c47ec32d81d11c0c1efbadf4a471e3f3ce7cad366cbbd3/frozenlist-1.5.0.tar.gz", hash = "sha256:81d5af29e61b9c8348e876d442253723928dce6433e0e76cd925cd83f1b4b817", size = 39930, upload-time = "2024-10-23T09:48:29.903Z" }
-wheels = [
- { url = "https://files.pythonhosted.org/packages/54/79/29d44c4af36b2b240725dce566b20f63f9b36ef267aaaa64ee7466f4f2f8/frozenlist-1.5.0-cp310-cp310-macosx_10_9_universal2.whl", hash = "sha256:5b6a66c18b5b9dd261ca98dffcb826a525334b2f29e7caa54e182255c5f6a65a", size = 94451, upload-time = "2024-10-23T09:46:20.558Z" },
- { url = "https://files.pythonhosted.org/packages/47/47/0c999aeace6ead8a44441b4f4173e2261b18219e4ad1fe9a479871ca02fc/frozenlist-1.5.0-cp310-cp310-macosx_10_9_x86_64.whl", hash = "sha256:d1b3eb7b05ea246510b43a7e53ed1653e55c2121019a97e60cad7efb881a97bb", size = 54301, upload-time = "2024-10-23T09:46:21.759Z" },
- { url = "https://files.pythonhosted.org/packages/8d/60/107a38c1e54176d12e06e9d4b5d755b677d71d1219217cee063911b1384f/frozenlist-1.5.0-cp310-cp310-macosx_11_0_arm64.whl", hash = "sha256:15538c0cbf0e4fa11d1e3a71f823524b0c46299aed6e10ebb4c2089abd8c3bec", size = 52213, upload-time = "2024-10-23T09:46:22.993Z" },
- { url = "https://files.pythonhosted.org/packages/17/62/594a6829ac5679c25755362a9dc93486a8a45241394564309641425d3ff6/frozenlist-1.5.0-cp310-cp310-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:e79225373c317ff1e35f210dd5f1344ff31066ba8067c307ab60254cd3a78ad5", size = 240946, upload-time = "2024-10-23T09:46:24.661Z" },
- { url = "https://files.pythonhosted.org/packages/7e/75/6c8419d8f92c80dd0ee3f63bdde2702ce6398b0ac8410ff459f9b6f2f9cb/frozenlist-1.5.0-cp310-cp310-manylinux_2_17_ppc64le.manylinux2014_ppc64le.whl", hash = "sha256:9272fa73ca71266702c4c3e2d4a28553ea03418e591e377a03b8e3659d94fa76", size = 264608, upload-time = "2024-10-23T09:46:26.017Z" },
- { url = "https://files.pythonhosted.org/packages/88/3e/82a6f0b84bc6fb7e0be240e52863c6d4ab6098cd62e4f5b972cd31e002e8/frozenlist-1.5.0-cp310-cp310-manylinux_2_17_s390x.manylinux2014_s390x.whl", hash = "sha256:498524025a5b8ba81695761d78c8dd7382ac0b052f34e66939c42df860b8ff17", size = 261361, upload-time = "2024-10-23T09:46:27.787Z" },
- { url = "https://files.pythonhosted.org/packages/fd/85/14e5f9ccac1b64ff2f10c927b3ffdf88772aea875882406f9ba0cec8ad84/frozenlist-1.5.0-cp310-cp310-manylinux_2_5_i686.manylinux1_i686.manylinux_2_17_i686.manylinux2014_i686.whl", hash = "sha256:92b5278ed9d50fe610185ecd23c55d8b307d75ca18e94c0e7de328089ac5dcba", size = 231649, upload-time = "2024-10-23T09:46:28.992Z" },
- { url = "https://files.pythonhosted.org/packages/ee/59/928322800306f6529d1852323014ee9008551e9bb027cc38d276cbc0b0e7/frozenlist-1.5.0-cp310-cp310-manylinux_2_5_x86_64.manylinux1_x86_64.manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:7f3c8c1dacd037df16e85227bac13cca58c30da836c6f936ba1df0c05d046d8d", size = 241853, upload-time = "2024-10-23T09:46:30.211Z" },
- { url = "https://files.pythonhosted.org/packages/7d/bd/e01fa4f146a6f6c18c5d34cab8abdc4013774a26c4ff851128cd1bd3008e/frozenlist-1.5.0-cp310-cp310-musllinux_1_2_aarch64.whl", hash = "sha256:f2ac49a9bedb996086057b75bf93538240538c6d9b38e57c82d51f75a73409d2", size = 243652, upload-time = "2024-10-23T09:46:31.758Z" },
- { url = "https://files.pythonhosted.org/packages/a5/bd/e4771fd18a8ec6757033f0fa903e447aecc3fbba54e3630397b61596acf0/frozenlist-1.5.0-cp310-cp310-musllinux_1_2_i686.whl", hash = "sha256:e66cc454f97053b79c2ab09c17fbe3c825ea6b4de20baf1be28919460dd7877f", size = 241734, upload-time = "2024-10-23T09:46:33.044Z" },
- { url = "https://files.pythonhosted.org/packages/21/13/c83821fa5544af4f60c5d3a65d054af3213c26b14d3f5f48e43e5fb48556/frozenlist-1.5.0-cp310-cp310-musllinux_1_2_ppc64le.whl", hash = "sha256:5a3ba5f9a0dfed20337d3e966dc359784c9f96503674c2faf015f7fe8e96798c", size = 260959, upload-time = "2024-10-23T09:46:34.916Z" },
- { url = "https://files.pythonhosted.org/packages/71/f3/1f91c9a9bf7ed0e8edcf52698d23f3c211d8d00291a53c9f115ceb977ab1/frozenlist-1.5.0-cp310-cp310-musllinux_1_2_s390x.whl", hash = "sha256:6321899477db90bdeb9299ac3627a6a53c7399c8cd58d25da094007402b039ab", size = 262706, upload-time = "2024-10-23T09:46:36.159Z" },
- { url = "https://files.pythonhosted.org/packages/4c/22/4a256fdf5d9bcb3ae32622c796ee5ff9451b3a13a68cfe3f68e2c95588ce/frozenlist-1.5.0-cp310-cp310-musllinux_1_2_x86_64.whl", hash = "sha256:76e4753701248476e6286f2ef492af900ea67d9706a0155335a40ea21bf3b2f5", size = 250401, upload-time = "2024-10-23T09:46:37.327Z" },
- { url = "https://files.pythonhosted.org/packages/af/89/c48ebe1f7991bd2be6d5f4ed202d94960c01b3017a03d6954dd5fa9ea1e8/frozenlist-1.5.0-cp310-cp310-win32.whl", hash = "sha256:977701c081c0241d0955c9586ffdd9ce44f7a7795df39b9151cd9a6fd0ce4cfb", size = 45498, upload-time = "2024-10-23T09:46:38.552Z" },
- { url = "https://files.pythonhosted.org/packages/28/2f/cc27d5f43e023d21fe5c19538e08894db3d7e081cbf582ad5ed366c24446/frozenlist-1.5.0-cp310-cp310-win_amd64.whl", hash = "sha256:189f03b53e64144f90990d29a27ec4f7997d91ed3d01b51fa39d2dbe77540fd4", size = 51622, upload-time = "2024-10-23T09:46:39.513Z" },
- { url = "https://files.pythonhosted.org/packages/79/43/0bed28bf5eb1c9e4301003b74453b8e7aa85fb293b31dde352aac528dafc/frozenlist-1.5.0-cp311-cp311-macosx_10_9_universal2.whl", hash = "sha256:fd74520371c3c4175142d02a976aee0b4cb4a7cc912a60586ffd8d5929979b30", size = 94987, upload-time = "2024-10-23T09:46:40.487Z" },
- { url = "https://files.pythonhosted.org/packages/bb/bf/b74e38f09a246e8abbe1e90eb65787ed745ccab6eaa58b9c9308e052323d/frozenlist-1.5.0-cp311-cp311-macosx_10_9_x86_64.whl", hash = "sha256:2f3f7a0fbc219fb4455264cae4d9f01ad41ae6ee8524500f381de64ffaa077d5", size = 54584, upload-time = "2024-10-23T09:46:41.463Z" },
- { url = "https://files.pythonhosted.org/packages/2c/31/ab01375682f14f7613a1ade30149f684c84f9b8823a4391ed950c8285656/frozenlist-1.5.0-cp311-cp311-macosx_11_0_arm64.whl", hash = "sha256:f47c9c9028f55a04ac254346e92977bf0f166c483c74b4232bee19a6697e4778", size = 52499, upload-time = "2024-10-23T09:46:42.451Z" },
- { url = "https://files.pythonhosted.org/packages/98/a8/d0ac0b9276e1404f58fec3ab6e90a4f76b778a49373ccaf6a563f100dfbc/frozenlist-1.5.0-cp311-cp311-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:0996c66760924da6e88922756d99b47512a71cfd45215f3570bf1e0b694c206a", size = 276357, upload-time = "2024-10-23T09:46:44.166Z" },
- { url = "https://files.pythonhosted.org/packages/ad/c9/c7761084fa822f07dac38ac29f841d4587570dd211e2262544aa0b791d21/frozenlist-1.5.0-cp311-cp311-manylinux_2_17_ppc64le.manylinux2014_ppc64le.whl", hash = "sha256:a2fe128eb4edeabe11896cb6af88fca5346059f6c8d807e3b910069f39157869", size = 287516, upload-time = "2024-10-23T09:46:45.369Z" },
- { url = "https://files.pythonhosted.org/packages/a1/ff/cd7479e703c39df7bdab431798cef89dc75010d8aa0ca2514c5b9321db27/frozenlist-1.5.0-cp311-cp311-manylinux_2_17_s390x.manylinux2014_s390x.whl", hash = "sha256:1a8ea951bbb6cacd492e3948b8da8c502a3f814f5d20935aae74b5df2b19cf3d", size = 283131, upload-time = "2024-10-23T09:46:46.654Z" },
- { url = "https://files.pythonhosted.org/packages/59/a0/370941beb47d237eca4fbf27e4e91389fd68699e6f4b0ebcc95da463835b/frozenlist-1.5.0-cp311-cp311-manylinux_2_5_i686.manylinux1_i686.manylinux_2_17_i686.manylinux2014_i686.whl", hash = "sha256:de537c11e4aa01d37db0d403b57bd6f0546e71a82347a97c6a9f0dcc532b3a45", size = 261320, upload-time = "2024-10-23T09:46:47.825Z" },
- { url = "https://files.pythonhosted.org/packages/b8/5f/c10123e8d64867bc9b4f2f510a32042a306ff5fcd7e2e09e5ae5100ee333/frozenlist-1.5.0-cp311-cp311-manylinux_2_5_x86_64.manylinux1_x86_64.manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:9c2623347b933fcb9095841f1cc5d4ff0b278addd743e0e966cb3d460278840d", size = 274877, upload-time = "2024-10-23T09:46:48.989Z" },
- { url = "https://files.pythonhosted.org/packages/fa/79/38c505601ae29d4348f21706c5d89755ceded02a745016ba2f58bd5f1ea6/frozenlist-1.5.0-cp311-cp311-musllinux_1_2_aarch64.whl", hash = "sha256:cee6798eaf8b1416ef6909b06f7dc04b60755206bddc599f52232606e18179d3", size = 269592, upload-time = "2024-10-23T09:46:50.235Z" },
- { url = "https://files.pythonhosted.org/packages/19/e2/39f3a53191b8204ba9f0bb574b926b73dd2efba2a2b9d2d730517e8f7622/frozenlist-1.5.0-cp311-cp311-musllinux_1_2_i686.whl", hash = "sha256:f5f9da7f5dbc00a604fe74aa02ae7c98bcede8a3b8b9666f9f86fc13993bc71a", size = 265934, upload-time = "2024-10-23T09:46:51.829Z" },
- { url = "https://files.pythonhosted.org/packages/d5/c9/3075eb7f7f3a91f1a6b00284af4de0a65a9ae47084930916f5528144c9dd/frozenlist-1.5.0-cp311-cp311-musllinux_1_2_ppc64le.whl", hash = "sha256:90646abbc7a5d5c7c19461d2e3eeb76eb0b204919e6ece342feb6032c9325ae9", size = 283859, upload-time = "2024-10-23T09:46:52.947Z" },
- { url = "https://files.pythonhosted.org/packages/05/f5/549f44d314c29408b962fa2b0e69a1a67c59379fb143b92a0a065ffd1f0f/frozenlist-1.5.0-cp311-cp311-musllinux_1_2_s390x.whl", hash = "sha256:bdac3c7d9b705d253b2ce370fde941836a5f8b3c5c2b8fd70940a3ea3af7f4f2", size = 287560, upload-time = "2024-10-23T09:46:54.162Z" },
- { url = "https://files.pythonhosted.org/packages/9d/f8/cb09b3c24a3eac02c4c07a9558e11e9e244fb02bf62c85ac2106d1eb0c0b/frozenlist-1.5.0-cp311-cp311-musllinux_1_2_x86_64.whl", hash = "sha256:03d33c2ddbc1816237a67f66336616416e2bbb6beb306e5f890f2eb22b959cdf", size = 277150, upload-time = "2024-10-23T09:46:55.361Z" },
- { url = "https://files.pythonhosted.org/packages/37/48/38c2db3f54d1501e692d6fe058f45b6ad1b358d82cd19436efab80cfc965/frozenlist-1.5.0-cp311-cp311-win32.whl", hash = "sha256:237f6b23ee0f44066219dae14c70ae38a63f0440ce6750f868ee08775073f942", size = 45244, upload-time = "2024-10-23T09:46:56.578Z" },
- { url = "https://files.pythonhosted.org/packages/ca/8c/2ddffeb8b60a4bce3b196c32fcc30d8830d4615e7b492ec2071da801b8ad/frozenlist-1.5.0-cp311-cp311-win_amd64.whl", hash = "sha256:0cc974cc93d32c42e7b0f6cf242a6bd941c57c61b618e78b6c0a96cb72788c1d", size = 51634, upload-time = "2024-10-23T09:46:57.6Z" },
- { url = "https://files.pythonhosted.org/packages/79/73/fa6d1a96ab7fd6e6d1c3500700963eab46813847f01ef0ccbaa726181dd5/frozenlist-1.5.0-cp312-cp312-macosx_10_13_universal2.whl", hash = "sha256:31115ba75889723431aa9a4e77d5f398f5cf976eea3bdf61749731f62d4a4a21", size = 94026, upload-time = "2024-10-23T09:46:58.601Z" },
- { url = "https://files.pythonhosted.org/packages/ab/04/ea8bf62c8868b8eada363f20ff1b647cf2e93377a7b284d36062d21d81d1/frozenlist-1.5.0-cp312-cp312-macosx_10_13_x86_64.whl", hash = "sha256:7437601c4d89d070eac8323f121fcf25f88674627505334654fd027b091db09d", size = 54150, upload-time = "2024-10-23T09:46:59.608Z" },
- { url = "https://files.pythonhosted.org/packages/d0/9a/8e479b482a6f2070b26bda572c5e6889bb3ba48977e81beea35b5ae13ece/frozenlist-1.5.0-cp312-cp312-macosx_11_0_arm64.whl", hash = "sha256:7948140d9f8ece1745be806f2bfdf390127cf1a763b925c4a805c603df5e697e", size = 51927, upload-time = "2024-10-23T09:47:00.625Z" },
- { url = "https://files.pythonhosted.org/packages/e3/12/2aad87deb08a4e7ccfb33600871bbe8f0e08cb6d8224371387f3303654d7/frozenlist-1.5.0-cp312-cp312-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:feeb64bc9bcc6b45c6311c9e9b99406660a9c05ca8a5b30d14a78555088b0b3a", size = 282647, upload-time = "2024-10-23T09:47:01.992Z" },
- { url = "https://files.pythonhosted.org/packages/77/f2/07f06b05d8a427ea0060a9cef6e63405ea9e0d761846b95ef3fb3be57111/frozenlist-1.5.0-cp312-cp312-manylinux_2_17_ppc64le.manylinux2014_ppc64le.whl", hash = "sha256:683173d371daad49cffb8309779e886e59c2f369430ad28fe715f66d08d4ab1a", size = 289052, upload-time = "2024-10-23T09:47:04.039Z" },
- { url = "https://files.pythonhosted.org/packages/bd/9f/8bf45a2f1cd4aa401acd271b077989c9267ae8463e7c8b1eb0d3f561b65e/frozenlist-1.5.0-cp312-cp312-manylinux_2_17_s390x.manylinux2014_s390x.whl", hash = "sha256:7d57d8f702221405a9d9b40f9da8ac2e4a1a8b5285aac6100f3393675f0a85ee", size = 291719, upload-time = "2024-10-23T09:47:05.58Z" },
- { url = "https://files.pythonhosted.org/packages/41/d1/1f20fd05a6c42d3868709b7604c9f15538a29e4f734c694c6bcfc3d3b935/frozenlist-1.5.0-cp312-cp312-manylinux_2_5_i686.manylinux1_i686.manylinux_2_17_i686.manylinux2014_i686.whl", hash = "sha256:30c72000fbcc35b129cb09956836c7d7abf78ab5416595e4857d1cae8d6251a6", size = 267433, upload-time = "2024-10-23T09:47:07.807Z" },
- { url = "https://files.pythonhosted.org/packages/af/f2/64b73a9bb86f5a89fb55450e97cd5c1f84a862d4ff90d9fd1a73ab0f64a5/frozenlist-1.5.0-cp312-cp312-manylinux_2_5_x86_64.manylinux1_x86_64.manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:000a77d6034fbad9b6bb880f7ec073027908f1b40254b5d6f26210d2dab1240e", size = 283591, upload-time = "2024-10-23T09:47:09.645Z" },
- { url = "https://files.pythonhosted.org/packages/29/e2/ffbb1fae55a791fd6c2938dd9ea779509c977435ba3940b9f2e8dc9d5316/frozenlist-1.5.0-cp312-cp312-musllinux_1_2_aarch64.whl", hash = "sha256:5d7f5a50342475962eb18b740f3beecc685a15b52c91f7d975257e13e029eca9", size = 273249, upload-time = "2024-10-23T09:47:10.808Z" },
- { url = "https://files.pythonhosted.org/packages/2e/6e/008136a30798bb63618a114b9321b5971172a5abddff44a100c7edc5ad4f/frozenlist-1.5.0-cp312-cp312-musllinux_1_2_i686.whl", hash = "sha256:87f724d055eb4785d9be84e9ebf0f24e392ddfad00b3fe036e43f489fafc9039", size = 271075, upload-time = "2024-10-23T09:47:11.938Z" },
- { url = "https://files.pythonhosted.org/packages/ae/f0/4e71e54a026b06724cec9b6c54f0b13a4e9e298cc8db0f82ec70e151f5ce/frozenlist-1.5.0-cp312-cp312-musllinux_1_2_ppc64le.whl", hash = "sha256:6e9080bb2fb195a046e5177f10d9d82b8a204c0736a97a153c2466127de87784", size = 285398, upload-time = "2024-10-23T09:47:14.071Z" },
- { url = "https://files.pythonhosted.org/packages/4d/36/70ec246851478b1c0b59f11ef8ade9c482ff447c1363c2bd5fad45098b12/frozenlist-1.5.0-cp312-cp312-musllinux_1_2_s390x.whl", hash = "sha256:9b93d7aaa36c966fa42efcaf716e6b3900438632a626fb09c049f6a2f09fc631", size = 294445, upload-time = "2024-10-23T09:47:15.318Z" },
- { url = "https://files.pythonhosted.org/packages/37/e0/47f87544055b3349b633a03c4d94b405956cf2437f4ab46d0928b74b7526/frozenlist-1.5.0-cp312-cp312-musllinux_1_2_x86_64.whl", hash = "sha256:52ef692a4bc60a6dd57f507429636c2af8b6046db8b31b18dac02cbc8f507f7f", size = 280569, upload-time = "2024-10-23T09:47:17.149Z" },
- { url = "https://files.pythonhosted.org/packages/f9/7c/490133c160fb6b84ed374c266f42800e33b50c3bbab1652764e6e1fc498a/frozenlist-1.5.0-cp312-cp312-win32.whl", hash = "sha256:29d94c256679247b33a3dc96cce0f93cbc69c23bf75ff715919332fdbb6a32b8", size = 44721, upload-time = "2024-10-23T09:47:19.012Z" },
- { url = "https://files.pythonhosted.org/packages/b1/56/4e45136ffc6bdbfa68c29ca56ef53783ef4c2fd395f7cbf99a2624aa9aaa/frozenlist-1.5.0-cp312-cp312-win_amd64.whl", hash = "sha256:8969190d709e7c48ea386db202d708eb94bdb29207a1f269bab1196ce0dcca1f", size = 51329, upload-time = "2024-10-23T09:47:20.177Z" },
- { url = "https://files.pythonhosted.org/packages/da/3b/915f0bca8a7ea04483622e84a9bd90033bab54bdf485479556c74fd5eaf5/frozenlist-1.5.0-cp313-cp313-macosx_10_13_universal2.whl", hash = "sha256:7a1a048f9215c90973402e26c01d1cff8a209e1f1b53f72b95c13db61b00f953", size = 91538, upload-time = "2024-10-23T09:47:21.176Z" },
- { url = "https://files.pythonhosted.org/packages/c7/d1/a7c98aad7e44afe5306a2b068434a5830f1470675f0e715abb86eb15f15b/frozenlist-1.5.0-cp313-cp313-macosx_10_13_x86_64.whl", hash = "sha256:dd47a5181ce5fcb463b5d9e17ecfdb02b678cca31280639255ce9d0e5aa67af0", size = 52849, upload-time = "2024-10-23T09:47:22.439Z" },
- { url = "https://files.pythonhosted.org/packages/3a/c8/76f23bf9ab15d5f760eb48701909645f686f9c64fbb8982674c241fbef14/frozenlist-1.5.0-cp313-cp313-macosx_11_0_arm64.whl", hash = "sha256:1431d60b36d15cda188ea222033eec8e0eab488f39a272461f2e6d9e1a8e63c2", size = 50583, upload-time = "2024-10-23T09:47:23.44Z" },
- { url = "https://files.pythonhosted.org/packages/1f/22/462a3dd093d11df623179d7754a3b3269de3b42de2808cddef50ee0f4f48/frozenlist-1.5.0-cp313-cp313-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:6482a5851f5d72767fbd0e507e80737f9c8646ae7fd303def99bfe813f76cf7f", size = 265636, upload-time = "2024-10-23T09:47:24.82Z" },
- { url = "https://files.pythonhosted.org/packages/80/cf/e075e407fc2ae7328155a1cd7e22f932773c8073c1fc78016607d19cc3e5/frozenlist-1.5.0-cp313-cp313-manylinux_2_17_ppc64le.manylinux2014_ppc64le.whl", hash = "sha256:44c49271a937625619e862baacbd037a7ef86dd1ee215afc298a417ff3270608", size = 270214, upload-time = "2024-10-23T09:47:26.156Z" },
- { url = "https://files.pythonhosted.org/packages/a1/58/0642d061d5de779f39c50cbb00df49682832923f3d2ebfb0fedf02d05f7f/frozenlist-1.5.0-cp313-cp313-manylinux_2_17_s390x.manylinux2014_s390x.whl", hash = "sha256:12f78f98c2f1c2429d42e6a485f433722b0061d5c0b0139efa64f396efb5886b", size = 273905, upload-time = "2024-10-23T09:47:27.741Z" },
- { url = "https://files.pythonhosted.org/packages/ab/66/3fe0f5f8f2add5b4ab7aa4e199f767fd3b55da26e3ca4ce2cc36698e50c4/frozenlist-1.5.0-cp313-cp313-manylinux_2_5_i686.manylinux1_i686.manylinux_2_17_i686.manylinux2014_i686.whl", hash = "sha256:ce3aa154c452d2467487765e3adc730a8c153af77ad84096bc19ce19a2400840", size = 250542, upload-time = "2024-10-23T09:47:28.938Z" },
- { url = "https://files.pythonhosted.org/packages/f6/b8/260791bde9198c87a465224e0e2bb62c4e716f5d198fc3a1dacc4895dbd1/frozenlist-1.5.0-cp313-cp313-manylinux_2_5_x86_64.manylinux1_x86_64.manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:9b7dc0c4338e6b8b091e8faf0db3168a37101943e687f373dce00959583f7439", size = 267026, upload-time = "2024-10-23T09:47:30.283Z" },
- { url = "https://files.pythonhosted.org/packages/2e/a4/3d24f88c527f08f8d44ade24eaee83b2627793fa62fa07cbb7ff7a2f7d42/frozenlist-1.5.0-cp313-cp313-musllinux_1_2_aarch64.whl", hash = "sha256:45e0896250900b5aa25180f9aec243e84e92ac84bd4a74d9ad4138ef3f5c97de", size = 257690, upload-time = "2024-10-23T09:47:32.388Z" },
- { url = "https://files.pythonhosted.org/packages/de/9a/d311d660420b2beeff3459b6626f2ab4fb236d07afbdac034a4371fe696e/frozenlist-1.5.0-cp313-cp313-musllinux_1_2_i686.whl", hash = "sha256:561eb1c9579d495fddb6da8959fd2a1fca2c6d060d4113f5844b433fc02f2641", size = 253893, upload-time = "2024-10-23T09:47:34.274Z" },
- { url = "https://files.pythonhosted.org/packages/c6/23/e491aadc25b56eabd0f18c53bb19f3cdc6de30b2129ee0bc39cd387cd560/frozenlist-1.5.0-cp313-cp313-musllinux_1_2_ppc64le.whl", hash = "sha256:df6e2f325bfee1f49f81aaac97d2aa757c7646534a06f8f577ce184afe2f0a9e", size = 267006, upload-time = "2024-10-23T09:47:35.499Z" },
- { url = "https://files.pythonhosted.org/packages/08/c4/ab918ce636a35fb974d13d666dcbe03969592aeca6c3ab3835acff01f79c/frozenlist-1.5.0-cp313-cp313-musllinux_1_2_s390x.whl", hash = "sha256:140228863501b44b809fb39ec56b5d4071f4d0aa6d216c19cbb08b8c5a7eadb9", size = 276157, upload-time = "2024-10-23T09:47:37.522Z" },
- { url = "https://files.pythonhosted.org/packages/c0/29/3b7a0bbbbe5a34833ba26f686aabfe982924adbdcafdc294a7a129c31688/frozenlist-1.5.0-cp313-cp313-musllinux_1_2_x86_64.whl", hash = "sha256:7707a25d6a77f5d27ea7dc7d1fc608aa0a478193823f88511ef5e6b8a48f9d03", size = 264642, upload-time = "2024-10-23T09:47:38.75Z" },
- { url = "https://files.pythonhosted.org/packages/ab/42/0595b3dbffc2e82d7fe658c12d5a5bafcd7516c6bf2d1d1feb5387caa9c1/frozenlist-1.5.0-cp313-cp313-win32.whl", hash = "sha256:31a9ac2b38ab9b5a8933b693db4939764ad3f299fcaa931a3e605bc3460e693c", size = 44914, upload-time = "2024-10-23T09:47:40.145Z" },
- { url = "https://files.pythonhosted.org/packages/17/c4/b7db1206a3fea44bf3b838ca61deb6f74424a8a5db1dd53ecb21da669be6/frozenlist-1.5.0-cp313-cp313-win_amd64.whl", hash = "sha256:11aabdd62b8b9c4b84081a3c246506d1cddd2dd93ff0ad53ede5defec7886b28", size = 51167, upload-time = "2024-10-23T09:47:41.812Z" },
- { url = "https://files.pythonhosted.org/packages/c6/c8/a5be5b7550c10858fcf9b0ea054baccab474da77d37f1e828ce043a3a5d4/frozenlist-1.5.0-py3-none-any.whl", hash = "sha256:d994863bba198a4a518b467bb971c56e1db3f180a25c6cf7bb1949c267f748c3", size = 11901, upload-time = "2024-10-23T09:48:28.851Z" },
-]
-
[[package]]
name = "h11"
version = "0.14.0"
@@ -677,427 +164,66 @@ wheels = [
]
[[package]]
-name = "h2"
-version = "4.2.0"
-source = { registry = "https://pypi.org/simple" }
-dependencies = [
- { name = "hpack" },
- { name = "hyperframe" },
-]
-sdist = { url = "https://files.pythonhosted.org/packages/1b/38/d7f80fd13e6582fb8e0df8c9a653dcc02b03ca34f4d72f34869298c5baf8/h2-4.2.0.tar.gz", hash = "sha256:c8a52129695e88b1a0578d8d2cc6842bbd79128ac685463b887ee278126ad01f", size = 2150682, upload-time = "2025-02-02T07:43:51.815Z" }
-wheels = [
- { url = "https://files.pythonhosted.org/packages/d0/9e/984486f2d0a0bd2b024bf4bc1c62688fcafa9e61991f041fb0e2def4a982/h2-4.2.0-py3-none-any.whl", hash = "sha256:479a53ad425bb29af087f3458a61d30780bc818e4ebcf01f0b536ba916462ed0", size = 60957, upload-time = "2025-02-01T11:02:26.481Z" },
-]
-
-[[package]]
-name = "hpack"
-version = "4.1.0"
-source = { registry = "https://pypi.org/simple" }
-sdist = { url = "https://files.pythonhosted.org/packages/2c/48/71de9ed269fdae9c8057e5a4c0aa7402e8bb16f2c6e90b3aa53327b113f8/hpack-4.1.0.tar.gz", hash = "sha256:ec5eca154f7056aa06f196a557655c5b009b382873ac8d1e66e79e87535f1dca", size = 51276, upload-time = "2025-01-22T21:44:58.347Z" }
-wheels = [
- { url = "https://files.pythonhosted.org/packages/07/c6/80c95b1b2b94682a72cbdbfb85b81ae2daffa4291fbfa1b1464502ede10d/hpack-4.1.0-py3-none-any.whl", hash = "sha256:157ac792668d995c657d93111f46b4535ed114f0c9c8d672271bbec7eae1b496", size = 34357, upload-time = "2025-01-22T21:44:56.92Z" },
-]
-
-[[package]]
-name = "httpcore"
-version = "1.0.7"
-source = { registry = "https://pypi.org/simple" }
-dependencies = [
- { name = "certifi" },
- { name = "h11" },
-]
-sdist = { url = "https://files.pythonhosted.org/packages/6a/41/d7d0a89eb493922c37d343b607bc1b5da7f5be7e383740b4753ad8943e90/httpcore-1.0.7.tar.gz", hash = "sha256:8551cb62a169ec7162ac7be8d4817d561f60e08eaa485234898414bb5a8a0b4c", size = 85196, upload-time = "2024-11-15T12:30:47.531Z" }
-wheels = [
- { url = "https://files.pythonhosted.org/packages/87/f5/72347bc88306acb359581ac4d52f23c0ef445b57157adedb9aee0cd689d2/httpcore-1.0.7-py3-none-any.whl", hash = "sha256:a3fff8f43dc260d5bd363d9f9cf1830fa3a458b332856f34282de498ed420edd", size = 78551, upload-time = "2024-11-15T12:30:45.782Z" },
-]
-
-[[package]]
-name = "httpx"
-version = "0.28.1"
-source = { registry = "https://pypi.org/simple" }
-dependencies = [
- { name = "anyio" },
- { name = "certifi" },
- { name = "httpcore" },
- { name = "idna" },
-]
-sdist = { url = "https://files.pythonhosted.org/packages/b1/df/48c586a5fe32a0f01324ee087459e112ebb7224f646c0b5023f5e79e9956/httpx-0.28.1.tar.gz", hash = "sha256:75e98c5f16b0f35b567856f597f06ff2270a374470a5c2392242528e3e3e42fc", size = 141406, upload-time = "2024-12-06T15:37:23.222Z" }
-wheels = [
- { url = "https://files.pythonhosted.org/packages/2a/39/e50c7c3a983047577ee07d2a9e53faf5a69493943ec3f6a384bdc792deb2/httpx-0.28.1-py3-none-any.whl", hash = "sha256:d909fcccc110f8c7faf814ca82a9a4d816bc5a6dbfea25d6591d6985b8ba59ad", size = 73517, upload-time = "2024-12-06T15:37:21.509Z" },
-]
-
-[package.optional-dependencies]
-http2 = [
- { name = "h2" },
-]
-socks = [
- { name = "socksio" },
-]
-
-[[package]]
-name = "httpx-sse"
-version = "0.4.3"
-source = { registry = "https://pypi.org/simple" }
-sdist = { url = "https://files.pythonhosted.org/packages/0f/4c/751061ffa58615a32c31b2d82e8482be8dd4a89154f003147acee90f2be9/httpx_sse-0.4.3.tar.gz", hash = "sha256:9b1ed0127459a66014aec3c56bebd93da3c1bc8bb6618c8082039a44889a755d", size = 15943, upload-time = "2025-10-10T21:48:22.271Z" }
-wheels = [
- { url = "https://files.pythonhosted.org/packages/d2/fd/6668e5aec43ab844de6fc74927e155a3b37bf40d7c3790e49fc0406b6578/httpx_sse-0.4.3-py3-none-any.whl", hash = "sha256:0ac1c9fe3c0afad2e0ebb25a934a59f4c7823b60792691f779fad2c5568830fc", size = 8960, upload-time = "2025-10-10T21:48:21.158Z" },
-]
-
-[[package]]
-name = "hyperframe"
-version = "6.1.0"
-source = { registry = "https://pypi.org/simple" }
-sdist = { url = "https://files.pythonhosted.org/packages/02/e7/94f8232d4a74cc99514c13a9f995811485a6903d48e5d952771ef6322e30/hyperframe-6.1.0.tar.gz", hash = "sha256:f630908a00854a7adeabd6382b43923a4c4cd4b821fcb527e6ab9e15382a3b08", size = 26566, upload-time = "2025-01-22T21:41:49.302Z" }
-wheels = [
- { url = "https://files.pythonhosted.org/packages/48/30/47d0bf6072f7252e6521f3447ccfa40b421b6824517f82854703d0f5a98b/hyperframe-6.1.0-py3-none-any.whl", hash = "sha256:b03380493a519fce58ea5af42e4a42317bf9bd425596f7a0835ffce80f1a42e5", size = 13007, upload-time = "2025-01-22T21:41:47.295Z" },
-]
-
-[[package]]
-name = "idna"
-version = "3.10"
-source = { registry = "https://pypi.org/simple" }
-sdist = { url = "https://files.pythonhosted.org/packages/f1/70/7703c29685631f5a7590aa73f1f1d3fa9a380e654b86af429e0934a32f7d/idna-3.10.tar.gz", hash = "sha256:12f65c9b470abda6dc35cf8e63cc574b1c52b11df2c86030af0ac09b01b13ea9", size = 190490, upload-time = "2024-09-15T18:07:39.745Z" }
-wheels = [
- { url = "https://files.pythonhosted.org/packages/76/c6/c88e154df9c4e1a2a66ccf0005a88dfb2650c1dffb6f5ce603dfbd452ce3/idna-3.10-py3-none-any.whl", hash = "sha256:946d195a0d259cbba61165e88e65941f16e9b36ea6ddb97f00452bae8b1287d3", size = 70442, upload-time = "2024-09-15T18:07:37.964Z" },
-]
-
-[[package]]
-name = "jieba"
-version = "0.42.1"
-source = { registry = "https://pypi.org/simple" }
-sdist = { url = "https://files.pythonhosted.org/packages/c6/cb/18eeb235f833b726522d7ebed54f2278ce28ba9438e3135ab0278d9792a2/jieba-0.42.1.tar.gz", hash = "sha256:055ca12f62674fafed09427f176506079bc135638a14e23e25be909131928db2", size = 19214172, upload-time = "2020-01-20T14:27:23.5Z" }
-
-[[package]]
-name = "jinja2"
-version = "3.1.6"
-source = { registry = "https://pypi.org/simple" }
-dependencies = [
- { name = "markupsafe" },
-]
-sdist = { url = "https://files.pythonhosted.org/packages/df/bf/f7da0350254c0ed7c72f3e33cef02e048281fec7ecec5f032d4aac52226b/jinja2-3.1.6.tar.gz", hash = "sha256:0137fb05990d35f1275a587e9aee6d56da821fc83491a0fb838183be43f66d6d", size = 245115, upload-time = "2025-03-05T20:05:02.478Z" }
-wheels = [
- { url = "https://files.pythonhosted.org/packages/62/a1/3d680cbfd5f4b8f15abc1d571870c5fc3e594bb582bc3b64ea099db13e56/jinja2-3.1.6-py3-none-any.whl", hash = "sha256:85ece4451f492d0c13c5dd7c13a64681a86afae63a5f347908daf103ce6d2f67", size = 134899, upload-time = "2025-03-05T20:05:00.369Z" },
-]
-
-[[package]]
-name = "joblib"
-version = "1.4.2"
-source = { registry = "https://pypi.org/simple" }
-sdist = { url = "https://files.pythonhosted.org/packages/64/33/60135848598c076ce4b231e1b1895170f45fbcaeaa2c9d5e38b04db70c35/joblib-1.4.2.tar.gz", hash = "sha256:2382c5816b2636fbd20a09e0f4e9dad4736765fdfb7dca582943b9c1366b3f0e", size = 2116621, upload-time = "2024-05-02T12:15:05.765Z" }
-wheels = [
- { url = "https://files.pythonhosted.org/packages/91/29/df4b9b42f2be0b623cbd5e2140cafcaa2bef0759a00b7b70104dcfe2fb51/joblib-1.4.2-py3-none-any.whl", hash = "sha256:06d478d5674cbc267e7496a410ee875abd68e4340feff4490bcb7afb88060ae6", size = 301817, upload-time = "2024-05-02T12:15:00.765Z" },
-]
-
-[[package]]
-name = "jsonschema"
-version = "4.26.0"
-source = { registry = "https://pypi.org/simple" }
-dependencies = [
- { name = "attrs" },
- { name = "jsonschema-specifications" },
- { name = "referencing" },
- { name = "rpds-py", version = "0.30.0", source = { registry = "https://pypi.org/simple" }, marker = "python_full_version < '3.11'" },
- { name = "rpds-py", version = "2026.5.1", source = { registry = "https://pypi.org/simple" }, marker = "python_full_version >= '3.11'" },
-]
-sdist = { url = "https://files.pythonhosted.org/packages/b3/fc/e067678238fa451312d4c62bf6e6cf5ec56375422aee02f9cb5f909b3047/jsonschema-4.26.0.tar.gz", hash = "sha256:0c26707e2efad8aa1bfc5b7ce170f3fccc2e4918ff85989ba9ffa9facb2be326", size = 366583, upload-time = "2026-01-07T13:41:07.246Z" }
-wheels = [
- { url = "https://files.pythonhosted.org/packages/69/90/f63fb5873511e014207a475e2bb4e8b2e570d655b00ac19a9a0ca0a385ee/jsonschema-4.26.0-py3-none-any.whl", hash = "sha256:d489f15263b8d200f8387e64b4c3a75f06629559fb73deb8fdfb525f2dab50ce", size = 90630, upload-time = "2026-01-07T13:41:05.306Z" },
-]
-
-[[package]]
-name = "jsonschema-specifications"
-version = "2025.9.1"
-source = { registry = "https://pypi.org/simple" }
-dependencies = [
- { name = "referencing" },
-]
-sdist = { url = "https://files.pythonhosted.org/packages/19/74/a633ee74eb36c44aa6d1095e7cc5569bebf04342ee146178e2d36600708b/jsonschema_specifications-2025.9.1.tar.gz", hash = "sha256:b540987f239e745613c7a9176f3edb72b832a4ac465cf02712288397832b5e8d", size = 32855, upload-time = "2025-09-08T01:34:59.186Z" }
-wheels = [
- { url = "https://files.pythonhosted.org/packages/41/45/1a4ed80516f02155c51f51e8cedb3c1902296743db0bbc66608a0db2814f/jsonschema_specifications-2025.9.1-py3-none-any.whl", hash = "sha256:98802fee3a11ee76ecaca44429fda8a41bff98b00a0f2838151b113f210cc6fe", size = 18437, upload-time = "2025-09-08T01:34:57.871Z" },
-]
-
-[[package]]
-name = "loguru"
-version = "0.7.3"
-source = { registry = "https://pypi.org/simple" }
-dependencies = [
- { name = "colorama", marker = "sys_platform == 'win32'" },
- { name = "win32-setctime", marker = "sys_platform == 'win32'" },
-]
-sdist = { url = "https://files.pythonhosted.org/packages/3a/05/a1dae3dffd1116099471c643b8924f5aa6524411dc6c63fdae648c4f1aca/loguru-0.7.3.tar.gz", hash = "sha256:19480589e77d47b8d85b2c827ad95d49bf31b0dcde16593892eb51dd18706eb6", size = 63559, upload-time = "2024-12-06T11:20:56.608Z" }
-wheels = [
- { url = "https://files.pythonhosted.org/packages/0c/29/0348de65b8cc732daa3e33e67806420b2ae89bdce2b04af740289c5c6c8c/loguru-0.7.3-py3-none-any.whl", hash = "sha256:31a33c10c8e1e10422bfd431aeb5d351c7cf7fa671e3c4df004162264b28220c", size = 61595, upload-time = "2024-12-06T11:20:54.538Z" },
-]
-
-[[package]]
-name = "macholib"
-version = "1.16.3"
-source = { registry = "https://pypi.org/simple" }
-dependencies = [
- { name = "altgraph" },
-]
-sdist = { url = "https://files.pythonhosted.org/packages/95/ee/af1a3842bdd5902ce133bd246eb7ffd4375c38642aeb5dc0ae3a0329dfa2/macholib-1.16.3.tar.gz", hash = "sha256:07ae9e15e8e4cd9a788013d81f5908b3609aa76f9b1421bae9c4d7606ec86a30", size = 59309, upload-time = "2023-09-25T09:10:16.155Z" }
-wheels = [
- { url = "https://files.pythonhosted.org/packages/d1/5d/c059c180c84f7962db0aeae7c3b9303ed1d73d76f2bfbc32bc231c8be314/macholib-1.16.3-py2.py3-none-any.whl", hash = "sha256:0e315d7583d38b8c77e815b1ecbdbf504a8258d8b3e17b61165c6feb60d18f2c", size = 38094, upload-time = "2023-09-25T09:10:14.188Z" },
-]
-
-[[package]]
-name = "markdown"
-version = "3.10.2"
-source = { registry = "https://pypi.org/simple" }
-sdist = { url = "https://files.pythonhosted.org/packages/2b/f4/69fa6ed85ae003c2378ffa8f6d2e3234662abd02c10d216c0ba96081a238/markdown-3.10.2.tar.gz", hash = "sha256:994d51325d25ad8aa7ce4ebaec003febcce822c3f8c911e3b17c52f7f589f950", size = 368805, upload-time = "2026-02-09T14:57:26.942Z" }
-wheels = [
- { url = "https://files.pythonhosted.org/packages/de/1f/77fa3081e4f66ca3576c896ae5d31c3002ac6607f9747d2e3aa49227e464/markdown-3.10.2-py3-none-any.whl", hash = "sha256:e91464b71ae3ee7afd3017d9f358ef0baf158fd9a298db92f1d4761133824c36", size = 108180, upload-time = "2026-02-09T14:57:25.787Z" },
-]
-
-[[package]]
-name = "markdown-it-py"
-version = "4.2.0"
-source = { registry = "https://pypi.org/simple" }
-dependencies = [
- { name = "mdurl" },
-]
-sdist = { url = "https://files.pythonhosted.org/packages/06/ff/7841249c247aa650a76b9ee4bbaeae59370dc8bfd2f6c01f3630c35eb134/markdown_it_py-4.2.0.tar.gz", hash = "sha256:04a21681d6fbb623de53f6f364d352309d4094dd4194040a10fd51833e418d49", size = 82454, upload-time = "2026-05-07T12:08:28.36Z" }
-wheels = [
- { url = "https://files.pythonhosted.org/packages/b3/81/4da04ced5a082363ecfa159c010d200ecbd959ae410c10c0264a38cac0f5/markdown_it_py-4.2.0-py3-none-any.whl", hash = "sha256:9f7ebbcd14fe59494226453aed97c1070d83f8d24b6fc3a3bcf9a38092641c4a", size = 91687, upload-time = "2026-05-07T12:08:27.182Z" },
-]
-
-[[package]]
-name = "markupsafe"
-version = "3.0.2"
-source = { registry = "https://pypi.org/simple" }
-sdist = { url = "https://files.pythonhosted.org/packages/b2/97/5d42485e71dfc078108a86d6de8fa46db44a1a9295e89c5d6d4a06e23a62/markupsafe-3.0.2.tar.gz", hash = "sha256:ee55d3edf80167e48ea11a923c7386f4669df67d7994554387f84e7d8b0a2bf0", size = 20537, upload-time = "2024-10-18T15:21:54.129Z" }
-wheels = [
- { url = "https://files.pythonhosted.org/packages/04/90/d08277ce111dd22f77149fd1a5d4653eeb3b3eaacbdfcbae5afb2600eebd/MarkupSafe-3.0.2-cp310-cp310-macosx_10_9_universal2.whl", hash = "sha256:7e94c425039cde14257288fd61dcfb01963e658efbc0ff54f5306b06054700f8", size = 14357, upload-time = "2024-10-18T15:20:51.44Z" },
- { url = "https://files.pythonhosted.org/packages/04/e1/6e2194baeae0bca1fae6629dc0cbbb968d4d941469cbab11a3872edff374/MarkupSafe-3.0.2-cp310-cp310-macosx_11_0_arm64.whl", hash = "sha256:9e2d922824181480953426608b81967de705c3cef4d1af983af849d7bd619158", size = 12393, upload-time = "2024-10-18T15:20:52.426Z" },
- { url = "https://files.pythonhosted.org/packages/1d/69/35fa85a8ece0a437493dc61ce0bb6d459dcba482c34197e3efc829aa357f/MarkupSafe-3.0.2-cp310-cp310-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:38a9ef736c01fccdd6600705b09dc574584b89bea478200c5fbf112a6b0d5579", size = 21732, upload-time = "2024-10-18T15:20:53.578Z" },
- { url = "https://files.pythonhosted.org/packages/22/35/137da042dfb4720b638d2937c38a9c2df83fe32d20e8c8f3185dbfef05f7/MarkupSafe-3.0.2-cp310-cp310-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:bbcb445fa71794da8f178f0f6d66789a28d7319071af7a496d4d507ed566270d", size = 20866, upload-time = "2024-10-18T15:20:55.06Z" },
- { url = "https://files.pythonhosted.org/packages/29/28/6d029a903727a1b62edb51863232152fd335d602def598dade38996887f0/MarkupSafe-3.0.2-cp310-cp310-manylinux_2_5_i686.manylinux1_i686.manylinux_2_17_i686.manylinux2014_i686.whl", hash = "sha256:57cb5a3cf367aeb1d316576250f65edec5bb3be939e9247ae594b4bcbc317dfb", size = 20964, upload-time = "2024-10-18T15:20:55.906Z" },
- { url = "https://files.pythonhosted.org/packages/cc/cd/07438f95f83e8bc028279909d9c9bd39e24149b0d60053a97b2bc4f8aa51/MarkupSafe-3.0.2-cp310-cp310-musllinux_1_2_aarch64.whl", hash = "sha256:3809ede931876f5b2ec92eef964286840ed3540dadf803dd570c3b7e13141a3b", size = 21977, upload-time = "2024-10-18T15:20:57.189Z" },
- { url = "https://files.pythonhosted.org/packages/29/01/84b57395b4cc062f9c4c55ce0df7d3108ca32397299d9df00fedd9117d3d/MarkupSafe-3.0.2-cp310-cp310-musllinux_1_2_i686.whl", hash = "sha256:e07c3764494e3776c602c1e78e298937c3315ccc9043ead7e685b7f2b8d47b3c", size = 21366, upload-time = "2024-10-18T15:20:58.235Z" },
- { url = "https://files.pythonhosted.org/packages/bd/6e/61ebf08d8940553afff20d1fb1ba7294b6f8d279df9fd0c0db911b4bbcfd/MarkupSafe-3.0.2-cp310-cp310-musllinux_1_2_x86_64.whl", hash = "sha256:b424c77b206d63d500bcb69fa55ed8d0e6a3774056bdc4839fc9298a7edca171", size = 21091, upload-time = "2024-10-18T15:20:59.235Z" },
- { url = "https://files.pythonhosted.org/packages/11/23/ffbf53694e8c94ebd1e7e491de185124277964344733c45481f32ede2499/MarkupSafe-3.0.2-cp310-cp310-win32.whl", hash = "sha256:fcabf5ff6eea076f859677f5f0b6b5c1a51e70a376b0579e0eadef8db48c6b50", size = 15065, upload-time = "2024-10-18T15:21:00.307Z" },
- { url = "https://files.pythonhosted.org/packages/44/06/e7175d06dd6e9172d4a69a72592cb3f7a996a9c396eee29082826449bbc3/MarkupSafe-3.0.2-cp310-cp310-win_amd64.whl", hash = "sha256:6af100e168aa82a50e186c82875a5893c5597a0c1ccdb0d8b40240b1f28b969a", size = 15514, upload-time = "2024-10-18T15:21:01.122Z" },
- { url = "https://files.pythonhosted.org/packages/6b/28/bbf83e3f76936960b850435576dd5e67034e200469571be53f69174a2dfd/MarkupSafe-3.0.2-cp311-cp311-macosx_10_9_universal2.whl", hash = "sha256:9025b4018f3a1314059769c7bf15441064b2207cb3f065e6ea1e7359cb46db9d", size = 14353, upload-time = "2024-10-18T15:21:02.187Z" },
- { url = "https://files.pythonhosted.org/packages/6c/30/316d194b093cde57d448a4c3209f22e3046c5bb2fb0820b118292b334be7/MarkupSafe-3.0.2-cp311-cp311-macosx_11_0_arm64.whl", hash = "sha256:93335ca3812df2f366e80509ae119189886b0f3c2b81325d39efdb84a1e2ae93", size = 12392, upload-time = "2024-10-18T15:21:02.941Z" },
- { url = "https://files.pythonhosted.org/packages/f2/96/9cdafba8445d3a53cae530aaf83c38ec64c4d5427d975c974084af5bc5d2/MarkupSafe-3.0.2-cp311-cp311-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:2cb8438c3cbb25e220c2ab33bb226559e7afb3baec11c4f218ffa7308603c832", size = 23984, upload-time = "2024-10-18T15:21:03.953Z" },
- { url = "https://files.pythonhosted.org/packages/f1/a4/aefb044a2cd8d7334c8a47d3fb2c9f328ac48cb349468cc31c20b539305f/MarkupSafe-3.0.2-cp311-cp311-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:a123e330ef0853c6e822384873bef7507557d8e4a082961e1defa947aa59ba84", size = 23120, upload-time = "2024-10-18T15:21:06.495Z" },
- { url = "https://files.pythonhosted.org/packages/8d/21/5e4851379f88f3fad1de30361db501300d4f07bcad047d3cb0449fc51f8c/MarkupSafe-3.0.2-cp311-cp311-manylinux_2_5_i686.manylinux1_i686.manylinux_2_17_i686.manylinux2014_i686.whl", hash = "sha256:1e084f686b92e5b83186b07e8a17fc09e38fff551f3602b249881fec658d3eca", size = 23032, upload-time = "2024-10-18T15:21:07.295Z" },
- { url = "https://files.pythonhosted.org/packages/00/7b/e92c64e079b2d0d7ddf69899c98842f3f9a60a1ae72657c89ce2655c999d/MarkupSafe-3.0.2-cp311-cp311-musllinux_1_2_aarch64.whl", hash = "sha256:d8213e09c917a951de9d09ecee036d5c7d36cb6cb7dbaece4c71a60d79fb9798", size = 24057, upload-time = "2024-10-18T15:21:08.073Z" },
- { url = "https://files.pythonhosted.org/packages/f9/ac/46f960ca323037caa0a10662ef97d0a4728e890334fc156b9f9e52bcc4ca/MarkupSafe-3.0.2-cp311-cp311-musllinux_1_2_i686.whl", hash = "sha256:5b02fb34468b6aaa40dfc198d813a641e3a63b98c2b05a16b9f80b7ec314185e", size = 23359, upload-time = "2024-10-18T15:21:09.318Z" },
- { url = "https://files.pythonhosted.org/packages/69/84/83439e16197337b8b14b6a5b9c2105fff81d42c2a7c5b58ac7b62ee2c3b1/MarkupSafe-3.0.2-cp311-cp311-musllinux_1_2_x86_64.whl", hash = "sha256:0bff5e0ae4ef2e1ae4fdf2dfd5b76c75e5c2fa4132d05fc1b0dabcd20c7e28c4", size = 23306, upload-time = "2024-10-18T15:21:10.185Z" },
- { url = "https://files.pythonhosted.org/packages/9a/34/a15aa69f01e2181ed8d2b685c0d2f6655d5cca2c4db0ddea775e631918cd/MarkupSafe-3.0.2-cp311-cp311-win32.whl", hash = "sha256:6c89876f41da747c8d3677a2b540fb32ef5715f97b66eeb0c6b66f5e3ef6f59d", size = 15094, upload-time = "2024-10-18T15:21:11.005Z" },
- { url = "https://files.pythonhosted.org/packages/da/b8/3a3bd761922d416f3dc5d00bfbed11f66b1ab89a0c2b6e887240a30b0f6b/MarkupSafe-3.0.2-cp311-cp311-win_amd64.whl", hash = "sha256:70a87b411535ccad5ef2f1df5136506a10775d267e197e4cf531ced10537bd6b", size = 15521, upload-time = "2024-10-18T15:21:12.911Z" },
- { url = "https://files.pythonhosted.org/packages/22/09/d1f21434c97fc42f09d290cbb6350d44eb12f09cc62c9476effdb33a18aa/MarkupSafe-3.0.2-cp312-cp312-macosx_10_13_universal2.whl", hash = "sha256:9778bd8ab0a994ebf6f84c2b949e65736d5575320a17ae8984a77fab08db94cf", size = 14274, upload-time = "2024-10-18T15:21:13.777Z" },
- { url = "https://files.pythonhosted.org/packages/6b/b0/18f76bba336fa5aecf79d45dcd6c806c280ec44538b3c13671d49099fdd0/MarkupSafe-3.0.2-cp312-cp312-macosx_11_0_arm64.whl", hash = "sha256:846ade7b71e3536c4e56b386c2a47adf5741d2d8b94ec9dc3e92e5e1ee1e2225", size = 12348, upload-time = "2024-10-18T15:21:14.822Z" },
- { url = "https://files.pythonhosted.org/packages/e0/25/dd5c0f6ac1311e9b40f4af06c78efde0f3b5cbf02502f8ef9501294c425b/MarkupSafe-3.0.2-cp312-cp312-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:1c99d261bd2d5f6b59325c92c73df481e05e57f19837bdca8413b9eac4bd8028", size = 24149, upload-time = "2024-10-18T15:21:15.642Z" },
- { url = "https://files.pythonhosted.org/packages/f3/f0/89e7aadfb3749d0f52234a0c8c7867877876e0a20b60e2188e9850794c17/MarkupSafe-3.0.2-cp312-cp312-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:e17c96c14e19278594aa4841ec148115f9c7615a47382ecb6b82bd8fea3ab0c8", size = 23118, upload-time = "2024-10-18T15:21:17.133Z" },
- { url = "https://files.pythonhosted.org/packages/d5/da/f2eeb64c723f5e3777bc081da884b414671982008c47dcc1873d81f625b6/MarkupSafe-3.0.2-cp312-cp312-manylinux_2_5_i686.manylinux1_i686.manylinux_2_17_i686.manylinux2014_i686.whl", hash = "sha256:88416bd1e65dcea10bc7569faacb2c20ce071dd1f87539ca2ab364bf6231393c", size = 22993, upload-time = "2024-10-18T15:21:18.064Z" },
- { url = "https://files.pythonhosted.org/packages/da/0e/1f32af846df486dce7c227fe0f2398dc7e2e51d4a370508281f3c1c5cddc/MarkupSafe-3.0.2-cp312-cp312-musllinux_1_2_aarch64.whl", hash = "sha256:2181e67807fc2fa785d0592dc2d6206c019b9502410671cc905d132a92866557", size = 24178, upload-time = "2024-10-18T15:21:18.859Z" },
- { url = "https://files.pythonhosted.org/packages/c4/f6/bb3ca0532de8086cbff5f06d137064c8410d10779c4c127e0e47d17c0b71/MarkupSafe-3.0.2-cp312-cp312-musllinux_1_2_i686.whl", hash = "sha256:52305740fe773d09cffb16f8ed0427942901f00adedac82ec8b67752f58a1b22", size = 23319, upload-time = "2024-10-18T15:21:19.671Z" },
- { url = "https://files.pythonhosted.org/packages/a2/82/8be4c96ffee03c5b4a034e60a31294daf481e12c7c43ab8e34a1453ee48b/MarkupSafe-3.0.2-cp312-cp312-musllinux_1_2_x86_64.whl", hash = "sha256:ad10d3ded218f1039f11a75f8091880239651b52e9bb592ca27de44eed242a48", size = 23352, upload-time = "2024-10-18T15:21:20.971Z" },
- { url = "https://files.pythonhosted.org/packages/51/ae/97827349d3fcffee7e184bdf7f41cd6b88d9919c80f0263ba7acd1bbcb18/MarkupSafe-3.0.2-cp312-cp312-win32.whl", hash = "sha256:0f4ca02bea9a23221c0182836703cbf8930c5e9454bacce27e767509fa286a30", size = 15097, upload-time = "2024-10-18T15:21:22.646Z" },
- { url = "https://files.pythonhosted.org/packages/c1/80/a61f99dc3a936413c3ee4e1eecac96c0da5ed07ad56fd975f1a9da5bc630/MarkupSafe-3.0.2-cp312-cp312-win_amd64.whl", hash = "sha256:8e06879fc22a25ca47312fbe7c8264eb0b662f6db27cb2d3bbbc74b1df4b9b87", size = 15601, upload-time = "2024-10-18T15:21:23.499Z" },
- { url = "https://files.pythonhosted.org/packages/83/0e/67eb10a7ecc77a0c2bbe2b0235765b98d164d81600746914bebada795e97/MarkupSafe-3.0.2-cp313-cp313-macosx_10_13_universal2.whl", hash = "sha256:ba9527cdd4c926ed0760bc301f6728ef34d841f405abf9d4f959c478421e4efd", size = 14274, upload-time = "2024-10-18T15:21:24.577Z" },
- { url = "https://files.pythonhosted.org/packages/2b/6d/9409f3684d3335375d04e5f05744dfe7e9f120062c9857df4ab490a1031a/MarkupSafe-3.0.2-cp313-cp313-macosx_11_0_arm64.whl", hash = "sha256:f8b3d067f2e40fe93e1ccdd6b2e1d16c43140e76f02fb1319a05cf2b79d99430", size = 12352, upload-time = "2024-10-18T15:21:25.382Z" },
- { url = "https://files.pythonhosted.org/packages/d2/f5/6eadfcd3885ea85fe2a7c128315cc1bb7241e1987443d78c8fe712d03091/MarkupSafe-3.0.2-cp313-cp313-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:569511d3b58c8791ab4c2e1285575265991e6d8f8700c7be0e88f86cb0672094", size = 24122, upload-time = "2024-10-18T15:21:26.199Z" },
- { url = "https://files.pythonhosted.org/packages/0c/91/96cf928db8236f1bfab6ce15ad070dfdd02ed88261c2afafd4b43575e9e9/MarkupSafe-3.0.2-cp313-cp313-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:15ab75ef81add55874e7ab7055e9c397312385bd9ced94920f2802310c930396", size = 23085, upload-time = "2024-10-18T15:21:27.029Z" },
- { url = "https://files.pythonhosted.org/packages/c2/cf/c9d56af24d56ea04daae7ac0940232d31d5a8354f2b457c6d856b2057d69/MarkupSafe-3.0.2-cp313-cp313-manylinux_2_5_i686.manylinux1_i686.manylinux_2_17_i686.manylinux2014_i686.whl", hash = "sha256:f3818cb119498c0678015754eba762e0d61e5b52d34c8b13d770f0719f7b1d79", size = 22978, upload-time = "2024-10-18T15:21:27.846Z" },
- { url = "https://files.pythonhosted.org/packages/2a/9f/8619835cd6a711d6272d62abb78c033bda638fdc54c4e7f4272cf1c0962b/MarkupSafe-3.0.2-cp313-cp313-musllinux_1_2_aarch64.whl", hash = "sha256:cdb82a876c47801bb54a690c5ae105a46b392ac6099881cdfb9f6e95e4014c6a", size = 24208, upload-time = "2024-10-18T15:21:28.744Z" },
- { url = "https://files.pythonhosted.org/packages/f9/bf/176950a1792b2cd2102b8ffeb5133e1ed984547b75db47c25a67d3359f77/MarkupSafe-3.0.2-cp313-cp313-musllinux_1_2_i686.whl", hash = "sha256:cabc348d87e913db6ab4aa100f01b08f481097838bdddf7c7a84b7575b7309ca", size = 23357, upload-time = "2024-10-18T15:21:29.545Z" },
- { url = "https://files.pythonhosted.org/packages/ce/4f/9a02c1d335caabe5c4efb90e1b6e8ee944aa245c1aaaab8e8a618987d816/MarkupSafe-3.0.2-cp313-cp313-musllinux_1_2_x86_64.whl", hash = "sha256:444dcda765c8a838eaae23112db52f1efaf750daddb2d9ca300bcae1039adc5c", size = 23344, upload-time = "2024-10-18T15:21:30.366Z" },
- { url = "https://files.pythonhosted.org/packages/ee/55/c271b57db36f748f0e04a759ace9f8f759ccf22b4960c270c78a394f58be/MarkupSafe-3.0.2-cp313-cp313-win32.whl", hash = "sha256:bcf3e58998965654fdaff38e58584d8937aa3096ab5354d493c77d1fdd66d7a1", size = 15101, upload-time = "2024-10-18T15:21:31.207Z" },
- { url = "https://files.pythonhosted.org/packages/29/88/07df22d2dd4df40aba9f3e402e6dc1b8ee86297dddbad4872bd5e7b0094f/MarkupSafe-3.0.2-cp313-cp313-win_amd64.whl", hash = "sha256:e6a2a455bd412959b57a172ce6328d2dd1f01cb2135efda2e4576e8a23fa3b0f", size = 15603, upload-time = "2024-10-18T15:21:32.032Z" },
- { url = "https://files.pythonhosted.org/packages/62/6a/8b89d24db2d32d433dffcd6a8779159da109842434f1dd2f6e71f32f738c/MarkupSafe-3.0.2-cp313-cp313t-macosx_10_13_universal2.whl", hash = "sha256:b5a6b3ada725cea8a5e634536b1b01c30bcdcd7f9c6fff4151548d5bf6b3a36c", size = 14510, upload-time = "2024-10-18T15:21:33.625Z" },
- { url = "https://files.pythonhosted.org/packages/7a/06/a10f955f70a2e5a9bf78d11a161029d278eeacbd35ef806c3fd17b13060d/MarkupSafe-3.0.2-cp313-cp313t-macosx_11_0_arm64.whl", hash = "sha256:a904af0a6162c73e3edcb969eeeb53a63ceeb5d8cf642fade7d39e7963a22ddb", size = 12486, upload-time = "2024-10-18T15:21:34.611Z" },
- { url = "https://files.pythonhosted.org/packages/34/cf/65d4a571869a1a9078198ca28f39fba5fbb910f952f9dbc5220afff9f5e6/MarkupSafe-3.0.2-cp313-cp313t-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:4aa4e5faecf353ed117801a068ebab7b7e09ffb6e1d5e412dc852e0da018126c", size = 25480, upload-time = "2024-10-18T15:21:35.398Z" },
- { url = "https://files.pythonhosted.org/packages/0c/e3/90e9651924c430b885468b56b3d597cabf6d72be4b24a0acd1fa0e12af67/MarkupSafe-3.0.2-cp313-cp313t-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:c0ef13eaeee5b615fb07c9a7dadb38eac06a0608b41570d8ade51c56539e509d", size = 23914, upload-time = "2024-10-18T15:21:36.231Z" },
- { url = "https://files.pythonhosted.org/packages/66/8c/6c7cf61f95d63bb866db39085150df1f2a5bd3335298f14a66b48e92659c/MarkupSafe-3.0.2-cp313-cp313t-manylinux_2_5_i686.manylinux1_i686.manylinux_2_17_i686.manylinux2014_i686.whl", hash = "sha256:d16a81a06776313e817c951135cf7340a3e91e8c1ff2fac444cfd75fffa04afe", size = 23796, upload-time = "2024-10-18T15:21:37.073Z" },
- { url = "https://files.pythonhosted.org/packages/bb/35/cbe9238ec3f47ac9a7c8b3df7a808e7cb50fe149dc7039f5f454b3fba218/MarkupSafe-3.0.2-cp313-cp313t-musllinux_1_2_aarch64.whl", hash = "sha256:6381026f158fdb7c72a168278597a5e3a5222e83ea18f543112b2662a9b699c5", size = 25473, upload-time = "2024-10-18T15:21:37.932Z" },
- { url = "https://files.pythonhosted.org/packages/e6/32/7621a4382488aa283cc05e8984a9c219abad3bca087be9ec77e89939ded9/MarkupSafe-3.0.2-cp313-cp313t-musllinux_1_2_i686.whl", hash = "sha256:3d79d162e7be8f996986c064d1c7c817f6df3a77fe3d6859f6f9e7be4b8c213a", size = 24114, upload-time = "2024-10-18T15:21:39.799Z" },
- { url = "https://files.pythonhosted.org/packages/0d/80/0985960e4b89922cb5a0bac0ed39c5b96cbc1a536a99f30e8c220a996ed9/MarkupSafe-3.0.2-cp313-cp313t-musllinux_1_2_x86_64.whl", hash = "sha256:131a3c7689c85f5ad20f9f6fb1b866f402c445b220c19fe4308c0b147ccd2ad9", size = 24098, upload-time = "2024-10-18T15:21:40.813Z" },
- { url = "https://files.pythonhosted.org/packages/82/78/fedb03c7d5380df2427038ec8d973587e90561b2d90cd472ce9254cf348b/MarkupSafe-3.0.2-cp313-cp313t-win32.whl", hash = "sha256:ba8062ed2cf21c07a9e295d5b8a2a5ce678b913b45fdf68c32d95d6c1291e0b6", size = 15208, upload-time = "2024-10-18T15:21:41.814Z" },
- { url = "https://files.pythonhosted.org/packages/4f/65/6079a46068dfceaeabb5dcad6d674f5f5c61a6fa5673746f42a9f4c233b3/MarkupSafe-3.0.2-cp313-cp313t-win_amd64.whl", hash = "sha256:e444a31f8db13eb18ada366ab3cf45fd4b31e4db1236a4448f68778c1d1a5a2f", size = 15739, upload-time = "2024-10-18T15:21:42.784Z" },
-]
-
-[[package]]
-name = "mcp"
-version = "1.27.2"
-source = { registry = "https://pypi.org/simple" }
+name = "historyhub"
+version = "1.7.2"
+source = { virtual = "." }
dependencies = [
- { name = "anyio" },
- { name = "httpx" },
- { name = "httpx-sse" },
- { name = "jsonschema" },
+ { name = "fastapi" },
+ { name = "loguru" },
+ { name = "pillow" },
{ name = "pydantic" },
- { name = "pydantic-settings" },
- { name = "pyjwt", extra = ["crypto"] },
- { name = "python-multipart" },
- { name = "pywin32", marker = "sys_platform == 'win32'" },
- { name = "sse-starlette" },
- { name = "starlette" },
- { name = "typing-extensions" },
- { name = "typing-inspection" },
- { name = "uvicorn", marker = "sys_platform != 'emscripten'" },
-]
-sdist = { url = "https://files.pythonhosted.org/packages/27/3c/347cf965d313f5d41764e7d46bea6ffe7d9ef13b983cc429b0340962a082/mcp-1.27.2.tar.gz", hash = "sha256:8e02db104096d1c25b28e64bde29a5c32b31bc241710213e12fd4d84985bdfef", size = 621116, upload-time = "2026-05-29T17:16:04.039Z" }
-wheels = [
- { url = "https://files.pythonhosted.org/packages/c9/11/252c6f971dc4f16af1d98a1c469d8ba523aab00d1bb76b4d3bc1ff32eacc/mcp-1.27.2-py3-none-any.whl", hash = "sha256:d6ff5160c6ca65d93013626efb3fc249de683c30b2d8570755ceddd490344de5", size = 220498, upload-time = "2026-05-29T17:16:02.442Z" },
-]
-
-[package.optional-dependencies]
-cli = [
- { name = "python-dotenv" },
- { name = "typer" },
-]
-
-[[package]]
-name = "mdurl"
-version = "0.1.2"
-source = { registry = "https://pypi.org/simple" }
-sdist = { url = "https://files.pythonhosted.org/packages/d6/54/cfe61301667036ec958cb99bd3efefba235e65cdeb9c84d24a8293ba1d90/mdurl-0.1.2.tar.gz", hash = "sha256:bb413d29f5eea38f31dd4754dd7377d4465116fb207585f97bf925588687c1ba", size = 8729, upload-time = "2022-08-14T12:40:10.846Z" }
-wheels = [
- { url = "https://files.pythonhosted.org/packages/b3/38/89ba8ad64ae25be8de66a6d463314cf1eb366222074cfda9ee839c56a4b4/mdurl-0.1.2-py3-none-any.whl", hash = "sha256:84008a41e51615a49fc9966191ff91509e3c40b939176e643fd50a5c2196b8f8", size = 9979, upload-time = "2022-08-14T12:40:09.779Z" },
+ { name = "pyinstaller" },
+ { name = "pyyaml" },
+ { name = "qrcode" },
+ { name = "requests" },
+ { name = "uvicorn" },
]
-[[package]]
-name = "multidict"
-version = "6.3.2"
-source = { registry = "https://pypi.org/simple" }
-dependencies = [
- { name = "typing-extensions", marker = "python_full_version < '3.11'" },
-]
-sdist = { url = "https://files.pythonhosted.org/packages/fa/2d/6e0d6771cadd5ad14d13193cc8326dc0b341cc1659c306cbfce7a5058fff/multidict-6.3.2.tar.gz", hash = "sha256:c1035eea471f759fa853dd6e76aaa1e389f93b3e1403093fa0fd3ab4db490678", size = 88060, upload-time = "2025-04-03T19:43:56.807Z" }
-wheels = [
- { url = "https://files.pythonhosted.org/packages/4e/9f/96bed056ed3e1fa86fa9880963e21a098e1e94dc6e2ced51a960d56ed802/multidict-6.3.2-cp310-cp310-macosx_10_9_universal2.whl", hash = "sha256:8b3dc0eec9304fa04d84a51ea13b0ec170bace5b7ddeaac748149efd316f1504", size = 62769, upload-time = "2025-04-03T19:41:19.707Z" },
- { url = "https://files.pythonhosted.org/packages/69/6a/c3197d0ff579d2393bab259c6129c963ebec50014fbd757440645402b4c0/multidict-6.3.2-cp310-cp310-macosx_10_9_x86_64.whl", hash = "sha256:9534f3d84addd3b6018fa83f97c9d4247aaa94ac917d1ed7b2523306f99f5c16", size = 37127, upload-time = "2025-04-03T19:41:21.778Z" },
- { url = "https://files.pythonhosted.org/packages/a6/d8/21b15813270d56486041452a44b02b4c02cd492edb8eb13c3ce1de7744f1/multidict-6.3.2-cp310-cp310-macosx_11_0_arm64.whl", hash = "sha256:a003ce1413ae01f0b8789c1c987991346a94620a4d22210f7a8fe753646d3209", size = 36399, upload-time = "2025-04-03T19:41:23.406Z" },
- { url = "https://files.pythonhosted.org/packages/8f/f6/2ffe2d4b565551bf0b1b1e9630c6f21f728fc24cd7d880f1baf5e7025be3/multidict-6.3.2-cp310-cp310-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:5b43f7384e68b1b982c99f489921a459467b5584bdb963b25e0df57c9039d0ad", size = 236561, upload-time = "2025-04-03T19:41:24.596Z" },
- { url = "https://files.pythonhosted.org/packages/c4/d7/935810c224360c63fe3b9233433ea9197399431e362e38ff0daf082624ee/multidict-6.3.2-cp310-cp310-manylinux_2_17_ppc64le.manylinux2014_ppc64le.whl", hash = "sha256:d142ae84047262dc75c1f92eaf95b20680f85ce11d35571b4c97e267f96fadc4", size = 249850, upload-time = "2025-04-03T19:41:25.915Z" },
- { url = "https://files.pythonhosted.org/packages/d0/10/355802a51e4426354b645585a9f0a4a4f0352b7619251da152f0235069ed/multidict-6.3.2-cp310-cp310-manylinux_2_17_s390x.manylinux2014_s390x.whl", hash = "sha256:ec7e86fbc48aa1d6d686501a8547818ba8d645e7e40eaa98232a5d43ee4380ad", size = 245566, upload-time = "2025-04-03T19:41:27.313Z" },
- { url = "https://files.pythonhosted.org/packages/72/cb/2a2b44b207c05018d0909b7c748983753dc9587699664e10709e27605158/multidict-6.3.2-cp310-cp310-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:fe019fb437632b016e6cac67a7e964f1ef827ef4023f1ca0227b54be354da97e", size = 232030, upload-time = "2025-04-03T19:41:28.568Z" },
- { url = "https://files.pythonhosted.org/packages/8e/e5/3db1745e939f4c02275154a5ed2816ea70eb1625e1d9363881047a0f9620/multidict-6.3.2-cp310-cp310-manylinux_2_5_i686.manylinux1_i686.manylinux_2_17_i686.manylinux2014_i686.whl", hash = "sha256:2b60cb81214a9da7cfd8ae2853d5e6e47225ece55fe5833142fe0af321c35299", size = 224255, upload-time = "2025-04-03T19:41:29.908Z" },
- { url = "https://files.pythonhosted.org/packages/48/2d/f187f506ff5ee3a91a8207a744311649cb1541b180514ea9dc235747ac2a/multidict-6.3.2-cp310-cp310-musllinux_1_2_aarch64.whl", hash = "sha256:32d9e8ef2e0312d4e96ca9adc88e0675b6d8e144349efce4a7c95d5ccb6d88e0", size = 233961, upload-time = "2025-04-03T19:41:31.29Z" },
- { url = "https://files.pythonhosted.org/packages/8f/e3/5023396bb5f1858f897d1a44199d0abc3072bb7b7bb47dec94c10b535568/multidict-6.3.2-cp310-cp310-musllinux_1_2_i686.whl", hash = "sha256:335d584312e3fa43633d63175dfc1a5f137dd7aa03d38d1310237d54c3032774", size = 232430, upload-time = "2025-04-03T19:41:32.752Z" },
- { url = "https://files.pythonhosted.org/packages/73/d8/f7b80e886af062dbb9d517e5161d841a08bcf44f6bccfccf9cb0ba92e7de/multidict-6.3.2-cp310-cp310-musllinux_1_2_ppc64le.whl", hash = "sha256:b8df917faa6b8cac3d6870fc21cb7e4d169faca68e43ffe568c156c9c6408a4d", size = 243102, upload-time = "2025-04-03T19:41:34.312Z" },
- { url = "https://files.pythonhosted.org/packages/53/a5/78e3c05c1916ce3e7beca8da8a026c1a4d9e4ce892f472463be22ddd030d/multidict-6.3.2-cp310-cp310-musllinux_1_2_s390x.whl", hash = "sha256:cc060b9b89b701dd8fedef5b99e1f1002b8cb95072693233a63389d37e48212d", size = 235610, upload-time = "2025-04-03T19:41:35.715Z" },
- { url = "https://files.pythonhosted.org/packages/00/29/97b470984a545d09bc5b6b8534559c48d4c427bd6737dc5a6f516061a581/multidict-6.3.2-cp310-cp310-musllinux_1_2_x86_64.whl", hash = "sha256:f2ce3be2500658f3c644494b934628bb0c82e549dde250d2119689ce791cc8b8", size = 232287, upload-time = "2025-04-03T19:41:37.821Z" },
- { url = "https://files.pythonhosted.org/packages/78/a5/121d40559fceb8d78ffe38ee06519fba8c8300ef1eb796c0a790fa0cfbf3/multidict-6.3.2-cp310-cp310-win32.whl", hash = "sha256:dbcb4490d8e74b484449abd51751b8f560dd0a4812eb5dacc6a588498222a9ab", size = 34895, upload-time = "2025-04-03T19:41:39.628Z" },
- { url = "https://files.pythonhosted.org/packages/04/b1/e90e666158b2c65567f8bb2c1507e9983c4b1b7156cd67e69349a38bd2b2/multidict-6.3.2-cp310-cp310-win_amd64.whl", hash = "sha256:06944f9ced30f8602be873563ed4df7e3f40958f60b2db39732c11d615a33687", size = 38307, upload-time = "2025-04-03T19:41:40.804Z" },
- { url = "https://files.pythonhosted.org/packages/b1/e3/443e682e42eaddad0b217b7a59627927fa42b6cd7ba7174f0a01eb3fe6b8/multidict-6.3.2-cp311-cp311-macosx_10_9_universal2.whl", hash = "sha256:45a034f41fcd16968c0470d8912d293d7b0d0822fc25739c5c2ff7835b85bc56", size = 62734, upload-time = "2025-04-03T19:41:42.39Z" },
- { url = "https://files.pythonhosted.org/packages/b1/4f/2126e9bc37f5be2fdfa36cc192e7ef10b3e9c58eec75a4468706aca96891/multidict-6.3.2-cp311-cp311-macosx_10_9_x86_64.whl", hash = "sha256:352585cec45f5d83d886fc522955492bb436fca032b11d487b12d31c5a81b9e3", size = 37115, upload-time = "2025-04-03T19:41:44.365Z" },
- { url = "https://files.pythonhosted.org/packages/6a/af/5aae0c05a66fdf8bf015ee6903d3a250a7d9c6cc75c9478d04995e6ff1e2/multidict-6.3.2-cp311-cp311-macosx_11_0_arm64.whl", hash = "sha256:da9d89d293511fd0a83a90559dc131f8b3292b6975eb80feff19e5f4663647e2", size = 36371, upload-time = "2025-04-03T19:41:45.451Z" },
- { url = "https://files.pythonhosted.org/packages/94/27/42390b75c20ff63f43fce44f36f9f66be466cd9ee05326051e4caacdb75b/multidict-6.3.2-cp311-cp311-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:79fa716592224aa652b9347a586cfe018635229074565663894eb4eb21f8307f", size = 243444, upload-time = "2025-04-03T19:41:46.614Z" },
- { url = "https://files.pythonhosted.org/packages/21/55/77077af851d7678fe0845c4050a537321d82fb12a04d4f6db334a1cc6ff7/multidict-6.3.2-cp311-cp311-manylinux_2_17_ppc64le.manylinux2014_ppc64le.whl", hash = "sha256:0326278a44c56e94792475268e5cd3d47fbc0bd41ee56928c3bbb103ba7f58fe", size = 256750, upload-time = "2025-04-03T19:41:47.968Z" },
- { url = "https://files.pythonhosted.org/packages/f1/09/4c5bfeb2fc8a1e14002239bd6a4d9ba2963fb148889d444b05a20db32a41/multidict-6.3.2-cp311-cp311-manylinux_2_17_s390x.manylinux2014_s390x.whl", hash = "sha256:bb1ea87f7fe45e5079f6315e95d64d4ca8b43ef656d98bed63a02e3756853a22", size = 251630, upload-time = "2025-04-03T19:41:49.367Z" },
- { url = "https://files.pythonhosted.org/packages/24/a9/286756a1afb8648772de851f8f39d2dd4076506f0c0fc2b751259fcbf0dd/multidict-6.3.2-cp311-cp311-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:7cff3c5a98d037024a9065aafc621a8599fad7b423393685dc83cf7a32f8b691", size = 238522, upload-time = "2025-04-03T19:41:50.831Z" },
- { url = "https://files.pythonhosted.org/packages/c2/03/4bb17df70742aae786fcbc27e89e2e49c322134698cd0739aec93e91c669/multidict-6.3.2-cp311-cp311-manylinux_2_5_i686.manylinux1_i686.manylinux_2_17_i686.manylinux2014_i686.whl", hash = "sha256:ed99834b053c655d980fb98029003cb24281e47a796052faad4543aa9e01b8e8", size = 230230, upload-time = "2025-04-03T19:41:52.27Z" },
- { url = "https://files.pythonhosted.org/packages/53/cc/30df95ba07a9f233ae48d0605b3f72457364836b61a8a8e3d333fdcd32c0/multidict-6.3.2-cp311-cp311-musllinux_1_2_aarch64.whl", hash = "sha256:7048440e505d2b4741e5d0b32bd2f427c901f38c7760fc245918be2cf69b3b85", size = 239676, upload-time = "2025-04-03T19:41:54.029Z" },
- { url = "https://files.pythonhosted.org/packages/25/37/2d9fe2944c2df5b71ba90cf657b90ad65f1542989cdabe4d1bdbf8c51530/multidict-6.3.2-cp311-cp311-musllinux_1_2_i686.whl", hash = "sha256:27248c27b563f5889556da8a96e18e98a56ff807ac1a7d56cf4453c2c9e4cd91", size = 238143, upload-time = "2025-04-03T19:41:55.815Z" },
- { url = "https://files.pythonhosted.org/packages/ce/13/8f833f9f992eae49f4cb1a1ad05b8fbe183721a154d51c2136b177a41bdb/multidict-6.3.2-cp311-cp311-musllinux_1_2_ppc64le.whl", hash = "sha256:6323b4ba0e018bd266f776c35f3f0943fc4ee77e481593c9f93bd49888f24e94", size = 248817, upload-time = "2025-04-03T19:41:57.665Z" },
- { url = "https://files.pythonhosted.org/packages/15/d4/4f49c41af6c4cab962ad51436e6c5acfbdab4fa54f5e98faa56f66f89b03/multidict-6.3.2-cp311-cp311-musllinux_1_2_s390x.whl", hash = "sha256:81f7ce5ec7c27d0b45c10449c8f0fed192b93251e2e98cb0b21fec779ef1dc4d", size = 241268, upload-time = "2025-04-03T19:41:59.247Z" },
- { url = "https://files.pythonhosted.org/packages/af/60/e723a00f7bb44366eab8d02fe6f076ecfad58331e10f6f0ce94cb989819c/multidict-6.3.2-cp311-cp311-musllinux_1_2_x86_64.whl", hash = "sha256:03bfcf2825b3bed0ba08a9d854acd18b938cab0d2dba3372b51c78e496bac811", size = 238267, upload-time = "2025-04-03T19:42:00.569Z" },
- { url = "https://files.pythonhosted.org/packages/62/a6/f6b63fc51c8a4e228e6d2105061be3048b02d490d47e67f7ec2de575f1d0/multidict-6.3.2-cp311-cp311-win32.whl", hash = "sha256:f32c2790512cae6ca886920e58cdc8c784bdc4bb2a5ec74127c71980369d18dc", size = 34986, upload-time = "2025-04-03T19:42:01.866Z" },
- { url = "https://files.pythonhosted.org/packages/85/56/ea976a5e3ebe0e871e004d9cacfe4c803f8ade353eaf4a247580e9dd7b9d/multidict-6.3.2-cp311-cp311-win_amd64.whl", hash = "sha256:0b0c15e58e038a2cd75ef7cf7e072bc39b5e0488b165902efb27978984bbad70", size = 38427, upload-time = "2025-04-03T19:42:03.401Z" },
- { url = "https://files.pythonhosted.org/packages/83/ae/bd7518193b4374484c04ba0f6522d0572dc17fcd53d238deb3cb3643c858/multidict-6.3.2-cp312-cp312-macosx_10_13_universal2.whl", hash = "sha256:d1e0ba1ce1b8cc79117196642d95f4365e118eaf5fb85f57cdbcc5a25640b2a4", size = 62680, upload-time = "2025-04-03T19:42:04.537Z" },
- { url = "https://files.pythonhosted.org/packages/59/e0/a0a9247c32f385ac4c1afefe9c3f2271fb8e235aad72332d42384c41b9cb/multidict-6.3.2-cp312-cp312-macosx_10_13_x86_64.whl", hash = "sha256:029bbd7d782251a78975214b78ee632672310f9233d49531fc93e8e99154af25", size = 37366, upload-time = "2025-04-03T19:42:05.727Z" },
- { url = "https://files.pythonhosted.org/packages/c3/fa/8c23cdd4492d59bea0e762662285f2163766e69e5ea715fe6a03a8670660/multidict-6.3.2-cp312-cp312-macosx_11_0_arm64.whl", hash = "sha256:d7db41e3b56817d9175264e5fe00192fbcb8e1265307a59f53dede86161b150e", size = 36103, upload-time = "2025-04-03T19:42:07.034Z" },
- { url = "https://files.pythonhosted.org/packages/87/35/3bcc3616cb54d3a327b1d26dbec284c3eb7b179e8a78a6075852dbb51dac/multidict-6.3.2-cp312-cp312-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:1fcab18e65cc555ac29981a581518c23311f2b1e72d8f658f9891590465383be", size = 248231, upload-time = "2025-04-03T19:42:08.719Z" },
- { url = "https://files.pythonhosted.org/packages/b8/c3/17ddbfd6fc3eed9ab7326a43651e1a97da73f7acc69b78a7bb04b59c073d/multidict-6.3.2-cp312-cp312-manylinux_2_17_ppc64le.manylinux2014_ppc64le.whl", hash = "sha256:0d50eff89aa4d145a5486b171a2177042d08ea5105f813027eb1050abe91839f", size = 259423, upload-time = "2025-04-03T19:42:10.751Z" },
- { url = "https://files.pythonhosted.org/packages/1f/67/64b18180e8f559cc93efaaaac2fe0746b9c978560866b6fdd626d3237129/multidict-6.3.2-cp312-cp312-manylinux_2_17_s390x.manylinux2014_s390x.whl", hash = "sha256:643e57b403d3e240045a3681f9e6a04d35a33eddc501b4cbbbdbc9c70122e7bc", size = 256204, upload-time = "2025-04-03T19:42:12.72Z" },
- { url = "https://files.pythonhosted.org/packages/21/f6/e81a8e4817c2d32787b33ae58c72dc3fe08e0ba8e56e660a225df3cb8619/multidict-6.3.2-cp312-cp312-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:9d17b37b9715b30605b5bab1460569742d0c309e5c20079263b440f5d7746e7e", size = 249663, upload-time = "2025-04-03T19:42:15.946Z" },
- { url = "https://files.pythonhosted.org/packages/3e/e8/44ca66758df031a8119483cf5385e2ff3b09b9c6df8f3396d626c325b553/multidict-6.3.2-cp312-cp312-manylinux_2_5_i686.manylinux1_i686.manylinux_2_17_i686.manylinux2014_i686.whl", hash = "sha256:68acd51fa94e63312b8ddf84bfc9c3d3442fe1f9988bbe1b6c703043af8867fe", size = 232236, upload-time = "2025-04-03T19:42:17.372Z" },
- { url = "https://files.pythonhosted.org/packages/93/76/d2faabbac582dc100a4d7ecf7d0ab8dd2aadf7f10d5d5a19e9932cf63a2e/multidict-6.3.2-cp312-cp312-musllinux_1_2_aarch64.whl", hash = "sha256:347eea2852ab7f697cc5ed9b1aae96b08f8529cca0c6468f747f0781b1842898", size = 252638, upload-time = "2025-04-03T19:42:18.771Z" },
- { url = "https://files.pythonhosted.org/packages/63/37/f5a6ea10dab96491b7300be940f86a5490dc474d18473c438f2550b78da3/multidict-6.3.2-cp312-cp312-musllinux_1_2_i686.whl", hash = "sha256:e4d3f8e57027dcda84a1aa181501c15c45eab9566eb6fcc274cbd1e7561224f8", size = 247917, upload-time = "2025-04-03T19:42:20.707Z" },
- { url = "https://files.pythonhosted.org/packages/d4/b1/2c32b684763b69becbaaa61b7af8a45a6f757fc82d9b4b123ca90cb69f75/multidict-6.3.2-cp312-cp312-musllinux_1_2_ppc64le.whl", hash = "sha256:9ca57a841ffcf712e47875d026aa49d6e67f9560624d54b51628603700d5d287", size = 261754, upload-time = "2025-04-03T19:42:22.094Z" },
- { url = "https://files.pythonhosted.org/packages/cd/f2/badedad94e1731debe56d076c9e61a1658c5e9d65dfa9c1ee74d1e3d31d7/multidict-6.3.2-cp312-cp312-musllinux_1_2_s390x.whl", hash = "sha256:7cafdafb44c4e646118410368307693e49d19167e5f119cbe3a88697d2d1a636", size = 256389, upload-time = "2025-04-03T19:42:26.161Z" },
- { url = "https://files.pythonhosted.org/packages/c6/3a/0a3488be2e5a6499f512e748d31e8fb90b753eb35793ecf390b9d8548e66/multidict-6.3.2-cp312-cp312-musllinux_1_2_x86_64.whl", hash = "sha256:430120c6ce3715a9c6075cabcee557daccbcca8ba25a9fedf05c7bf564532f2d", size = 251902, upload-time = "2025-04-03T19:42:29.6Z" },
- { url = "https://files.pythonhosted.org/packages/fe/44/62f76d0a5d836b96168f39a402a75dd3114d0df3cbb5669e0310034b71be/multidict-6.3.2-cp312-cp312-win32.whl", hash = "sha256:13bec31375235a68457ab887ce1bbf4f59d5810d838ae5d7e5b416242e1f3ed4", size = 35101, upload-time = "2025-04-03T19:42:31.107Z" },
- { url = "https://files.pythonhosted.org/packages/8f/a4/7aaf2313e1766710010c35f9d738fd6309fb71a758f8c0e81853b90afb3d/multidict-6.3.2-cp312-cp312-win_amd64.whl", hash = "sha256:c3b6d7620e6e90c6d97eaf3a63bf7fbd2ba253aab89120a4a9c660bf2d675391", size = 38479, upload-time = "2025-04-03T19:42:32.964Z" },
- { url = "https://files.pythonhosted.org/packages/b1/b2/15db2b1bec1fe8ab5e7c210e3cd247ed902ef86b58b9f39b0a75476d0e8d/multidict-6.3.2-cp313-cp313-macosx_10_13_universal2.whl", hash = "sha256:b9ca24700322816ae0d426aa33671cf68242f8cc85cee0d0e936465ddaee90b5", size = 62345, upload-time = "2025-04-03T19:42:34.716Z" },
- { url = "https://files.pythonhosted.org/packages/5f/91/22ea27da2c3ffb8266a92f91f17a84dec2cbdd0f91aa7e5f7d514534dd92/multidict-6.3.2-cp313-cp313-macosx_10_13_x86_64.whl", hash = "sha256:d9fbbe23667d596ff4f9f74d44b06e40ebb0ab6b262cf14a284f859a66f86457", size = 37205, upload-time = "2025-04-03T19:42:37.566Z" },
- { url = "https://files.pythonhosted.org/packages/23/cb/563a7481ae677531da84aad86c2de7ebc23446d856d2f6d9794ad4fff375/multidict-6.3.2-cp313-cp313-macosx_11_0_arm64.whl", hash = "sha256:9cb602c5bea0589570ad3a4a6f2649c4f13cc7a1e97b4c616e5e9ff8dc490987", size = 35931, upload-time = "2025-04-03T19:42:40.082Z" },
- { url = "https://files.pythonhosted.org/packages/7c/b7/98fe4f4cd7a0b77a4a48fd3f619848b9e8af4e692eb681f9df9f58d86456/multidict-6.3.2-cp313-cp313-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:93ca81dd4d1542e20000ed90f4cc84b7713776f620d04c2b75b8efbe61106c99", size = 246946, upload-time = "2025-04-03T19:42:42.034Z" },
- { url = "https://files.pythonhosted.org/packages/7e/a3/22dcbd0b58d253719acaf0257a2f35bf609bfd6b73690fcc9e7bdbd3b392/multidict-6.3.2-cp313-cp313-manylinux_2_17_ppc64le.manylinux2014_ppc64le.whl", hash = "sha256:18b6310b5454c62242577a128c87df8897f39dd913311cf2e1298e47dfc089eb", size = 260559, upload-time = "2025-04-03T19:42:44.254Z" },
- { url = "https://files.pythonhosted.org/packages/1c/d4/25eb076f0c2c28d73e7959f3fcc8371e7a029815b5d06e79ea3a265500d2/multidict-6.3.2-cp313-cp313-manylinux_2_17_s390x.manylinux2014_s390x.whl", hash = "sha256:7a6dda57de1fc9aedfdb600a8640c99385cdab59a5716cb714b52b6005797f77", size = 257122, upload-time = "2025-04-03T19:42:45.891Z" },
- { url = "https://files.pythonhosted.org/packages/28/f8/18c81f5c5b7453dd8d15dc61ceca23d03c55e69f1937842039be2d8c4428/multidict-6.3.2-cp313-cp313-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:5d8ec42d03cc6b29845552a68151f9e623c541f1708328353220af571e24a247", size = 248535, upload-time = "2025-04-03T19:42:47.358Z" },
- { url = "https://files.pythonhosted.org/packages/9b/17/c175fab75ecfe1c2dd4f28382dd7e80da6d6f0d73c68036f64b6dce9aeeb/multidict-6.3.2-cp313-cp313-manylinux_2_5_i686.manylinux1_i686.manylinux_2_17_i686.manylinux2014_i686.whl", hash = "sha256:80681969cee2fa84dafeb53615d51d24246849984e3e87fbe4fe39956f2e23bf", size = 234013, upload-time = "2025-04-03T19:42:52.03Z" },
- { url = "https://files.pythonhosted.org/packages/2f/03/1611ecf91d7d6249633cb1dd3fb26d456e0dc0dc80cecccfeb89931a126b/multidict-6.3.2-cp313-cp313-musllinux_1_2_aarch64.whl", hash = "sha256:01489b0c3592bb9d238e5690e9566db7f77a5380f054b57077d2c4deeaade0eb", size = 249222, upload-time = "2025-04-03T19:42:55.051Z" },
- { url = "https://files.pythonhosted.org/packages/66/04/0035b77bbffb55f276f00b427e45870194002f9f42e1e3de785d45880372/multidict-6.3.2-cp313-cp313-musllinux_1_2_i686.whl", hash = "sha256:522d9f1fd995d04dfedc0a40bca7e2591bc577d920079df50b56245a4a252c1c", size = 245594, upload-time = "2025-04-03T19:42:56.509Z" },
- { url = "https://files.pythonhosted.org/packages/fe/4c/b52ebcd8ff13a3c833b07cfffa0f50f736b061954a151ee5fe6669bb1bd8/multidict-6.3.2-cp313-cp313-musllinux_1_2_ppc64le.whl", hash = "sha256:2014e9cf0b4e9c75bbad49c1758e5a9bf967a56184fc5fcc51527425baf5abba", size = 258709, upload-time = "2025-04-03T19:42:58.038Z" },
- { url = "https://files.pythonhosted.org/packages/fd/78/9c4433517e8f09035a14aba469617c9cf41a214ca987d9127b84b3de4848/multidict-6.3.2-cp313-cp313-musllinux_1_2_s390x.whl", hash = "sha256:78ced9fcbee79e446ff4bb3018ac7ba1670703de7873d9c1f6f9883db53c71bc", size = 254015, upload-time = "2025-04-03T19:42:59.505Z" },
- { url = "https://files.pythonhosted.org/packages/6d/76/8464b4d2e9980bd754aa1850919caef9854453f0400c60f84c79947b799d/multidict-6.3.2-cp313-cp313-musllinux_1_2_x86_64.whl", hash = "sha256:1faf01af972bd01216a107c195f5294f9f393531bc3e4faddc9b333581255d4d", size = 249475, upload-time = "2025-04-03T19:43:01.106Z" },
- { url = "https://files.pythonhosted.org/packages/c4/e2/2b35b7ce226a2ca8c38125f702090faa8d0a35050461fb111fbaa2e023c4/multidict-6.3.2-cp313-cp313-win32.whl", hash = "sha256:7a699ab13d8d8e1f885de1535b4f477fb93836c87168318244c2685da7b7f655", size = 35204, upload-time = "2025-04-03T19:43:03.029Z" },
- { url = "https://files.pythonhosted.org/packages/c6/c7/09b85dc11cfa83c9a1e3f8367402d56157624e31a05eecd40d5feed1eed1/multidict-6.3.2-cp313-cp313-win_amd64.whl", hash = "sha256:8666bb0d883310c83be01676e302587834dfd185b52758caeab32ef0eb387bc6", size = 38436, upload-time = "2025-04-03T19:43:04.324Z" },
- { url = "https://files.pythonhosted.org/packages/63/d6/b27f9db9a8dcca95b50911436c9f187047911be0d78ade3352a6bcabb87a/multidict-6.3.2-cp313-cp313t-macosx_10_13_universal2.whl", hash = "sha256:d82c95aabee29612b1c4f48b98be98181686eb7d6c0152301f72715705cc787b", size = 67526, upload-time = "2025-04-03T19:43:06.123Z" },
- { url = "https://files.pythonhosted.org/packages/2d/23/bbf220b0fa6378526890f37fd9a63d4e2ea990a4a344b221618adc3fb8b0/multidict-6.3.2-cp313-cp313t-macosx_10_13_x86_64.whl", hash = "sha256:f47709173ea9e87a7fd05cd7e5cf1e5d4158924ff988a9a8e0fbd853705f0e68", size = 39390, upload-time = "2025-04-03T19:43:07.571Z" },
- { url = "https://files.pythonhosted.org/packages/0d/a9/4d1b795b50e6b54609fd7a63db8df30fa0480405b9a46cf8e336f5f28560/multidict-6.3.2-cp313-cp313t-macosx_11_0_arm64.whl", hash = "sha256:0c7f9d0276ceaab41b8ae78534ff28ea33d5de85db551cbf80c44371f2b55d13", size = 38869, upload-time = "2025-04-03T19:43:08.859Z" },
- { url = "https://files.pythonhosted.org/packages/e4/8c/854ee8ad8921335d0b4e740f373390d85d23f6b3956387562de5891ac503/multidict-6.3.2-cp313-cp313t-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:a6eab22df44a25acab2e738f882f5ec551282ab45b2bbda5301e6d2cfb323036", size = 246911, upload-time = "2025-04-03T19:43:10.625Z" },
- { url = "https://files.pythonhosted.org/packages/40/65/d6ae9fecb61d1c2fa86a2889f8b58dbfb91fa6a6d7754597e472c8523f6c/multidict-6.3.2-cp313-cp313t-manylinux_2_17_ppc64le.manylinux2014_ppc64le.whl", hash = "sha256:a947cb7c657f57874021b9b70c7aac049c877fb576955a40afa8df71d01a1390", size = 251680, upload-time = "2025-04-03T19:43:12.122Z" },
- { url = "https://files.pythonhosted.org/packages/a3/6c/098304889a699f5fbad8e74b723847a38d22547743baacdfcc8a17777b5b/multidict-6.3.2-cp313-cp313t-manylinux_2_17_s390x.manylinux2014_s390x.whl", hash = "sha256:5faa346e8e1c371187cf345ab1e02a75889f9f510c9cbc575c31b779f7df084d", size = 246706, upload-time = "2025-04-03T19:43:13.727Z" },
- { url = "https://files.pythonhosted.org/packages/da/9f/a58a04ac1d18f0a2431c48763a8948d0ce65f5911000cc425f8778eb6611/multidict-6.3.2-cp313-cp313t-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:dc6e08d977aebf1718540533b4ba5b351ccec2db093370958a653b1f7f9219cc", size = 242359, upload-time = "2025-04-03T19:43:15.264Z" },
- { url = "https://files.pythonhosted.org/packages/40/fd/3a76265f2748f718cc05f313c44440658ecd1939fa2b5e66087a5edd605f/multidict-6.3.2-cp313-cp313t-manylinux_2_5_i686.manylinux1_i686.manylinux_2_17_i686.manylinux2014_i686.whl", hash = "sha256:98eab7acf55275b5bf09834125fa3a80b143a9f241cdcdd3f1295ffdc3c6d097", size = 229881, upload-time = "2025-04-03T19:43:17.182Z" },
- { url = "https://files.pythonhosted.org/packages/22/a9/5780f71e34adf93443ec0660591d877367991badadab9cc6ac02d7a64760/multidict-6.3.2-cp313-cp313t-musllinux_1_2_aarch64.whl", hash = "sha256:36863655630becc224375c0b99364978a0f95aebfb27fb6dd500f7fb5fb36e79", size = 248520, upload-time = "2025-04-03T19:43:19.594Z" },
- { url = "https://files.pythonhosted.org/packages/f3/72/10988db397e1e819b669213c76a41fde670ba60ecec2c05d5ecdea05526c/multidict-6.3.2-cp313-cp313t-musllinux_1_2_i686.whl", hash = "sha256:d9c0979c096c0d46a963331b0e400d3a9e560e41219df4b35f0d7a2f28f39710", size = 237649, upload-time = "2025-04-03T19:43:21.136Z" },
- { url = "https://files.pythonhosted.org/packages/29/75/52a7d3d1c0ffb2e8367f72845f309850113ea9201a50e4d4cdf8ac9f7d72/multidict-6.3.2-cp313-cp313t-musllinux_1_2_ppc64le.whl", hash = "sha256:0efc04f70f05e70e5945890767e8874da5953a196f5b07c552d305afae0f3bf6", size = 251467, upload-time = "2025-04-03T19:43:22.677Z" },
- { url = "https://files.pythonhosted.org/packages/82/24/e42400008eff60d4af53a2ff313abf0b2715fdd3a71b845d85025844f198/multidict-6.3.2-cp313-cp313t-musllinux_1_2_s390x.whl", hash = "sha256:2c519b3b82c34539fae3e22e4ea965869ac6b628794b1eb487780dde37637ab7", size = 245310, upload-time = "2025-04-03T19:43:24.643Z" },
- { url = "https://files.pythonhosted.org/packages/91/32/8b2e247539d4fdcc6cee36aa71c8898e0acd70e5d0e8a2ce9796a60790e5/multidict-6.3.2-cp313-cp313t-musllinux_1_2_x86_64.whl", hash = "sha256:329160e301f2afd7b43725d3dda8a7ef8ee41d4ceac2083fc0d8c1cc8a4bd56b", size = 243574, upload-time = "2025-04-03T19:43:26.787Z" },
- { url = "https://files.pythonhosted.org/packages/d2/86/cc42cfa9b85b7d174948a17f828ebcacb0247e727fbedf06506ba93387ef/multidict-6.3.2-cp313-cp313t-win32.whl", hash = "sha256:420e5144a5f598dad8db3128f1695cd42a38a0026c2991091dab91697832f8cc", size = 41908, upload-time = "2025-04-03T19:43:28.721Z" },
- { url = "https://files.pythonhosted.org/packages/2a/36/5c015523a7650fb5c55380d1c779b938379bd091968ee822d719e4264ab7/multidict-6.3.2-cp313-cp313t-win_amd64.whl", hash = "sha256:875faded2861c7af2682c67088e6313fec35ede811e071c96d36b081873cea14", size = 45635, upload-time = "2025-04-03T19:43:30.099Z" },
- { url = "https://files.pythonhosted.org/packages/aa/c1/7832c95a50641148b567b5366dd3354489950dcfd01c8fc28472bec63b9a/multidict-6.3.2-py3-none-any.whl", hash = "sha256:71409d4579f716217f23be2f5e7afca5ca926aaeb398aa11b72d793bff637a1f", size = 10347, upload-time = "2025-04-03T19:43:55.427Z" },
+[package.metadata]
+requires-dist = [
+ { name = "fastapi", specifier = "~=0.115.8" },
+ { name = "loguru", specifier = ">=0.7.2" },
+ { name = "pillow", specifier = "~=10.2.0" },
+ { name = "pydantic", specifier = ">=2.11,<3" },
+ { name = "pyinstaller", specifier = ">=6.12.0" },
+ { name = "pyyaml", specifier = "~=6.0.2" },
+ { name = "qrcode", specifier = "~=8.0" },
+ { name = "requests", specifier = "~=2.32.3" },
+ { name = "uvicorn", specifier = "~=0.32.1" },
]
[[package]]
-name = "numpy"
-version = "1.26.4"
+name = "idna"
+version = "3.10"
source = { registry = "https://pypi.org/simple" }
-sdist = { url = "https://files.pythonhosted.org/packages/65/6e/09db70a523a96d25e115e71cc56a6f9031e7b8cd166c1ac8438307c14058/numpy-1.26.4.tar.gz", hash = "sha256:2a02aba9ed12e4ac4eb3ea9421c420301a0c6460d9830d74a9df87efa4912010", size = 15786129, upload-time = "2024-02-06T00:26:44.495Z" }
+sdist = { url = "https://files.pythonhosted.org/packages/f1/70/7703c29685631f5a7590aa73f1f1d3fa9a380e654b86af429e0934a32f7d/idna-3.10.tar.gz", hash = "sha256:12f65c9b470abda6dc35cf8e63cc574b1c52b11df2c86030af0ac09b01b13ea9", size = 190490, upload-time = "2024-09-15T18:07:39.745Z" }
wheels = [
- { url = "https://files.pythonhosted.org/packages/a7/94/ace0fdea5241a27d13543ee117cbc65868e82213fb31a8eb7fe9ff23f313/numpy-1.26.4-cp310-cp310-macosx_10_9_x86_64.whl", hash = "sha256:9ff0f4f29c51e2803569d7a51c2304de5554655a60c5d776e35b4a41413830d0", size = 20631468, upload-time = "2024-02-05T23:48:01.194Z" },
- { url = "https://files.pythonhosted.org/packages/20/f7/b24208eba89f9d1b58c1668bc6c8c4fd472b20c45573cb767f59d49fb0f6/numpy-1.26.4-cp310-cp310-macosx_11_0_arm64.whl", hash = "sha256:2e4ee3380d6de9c9ec04745830fd9e2eccb3e6cf790d39d7b98ffd19b0dd754a", size = 13966411, upload-time = "2024-02-05T23:48:29.038Z" },
- { url = "https://files.pythonhosted.org/packages/fc/a5/4beee6488160798683eed5bdb7eead455892c3b4e1f78d79d8d3f3b084ac/numpy-1.26.4-cp310-cp310-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:d209d8969599b27ad20994c8e41936ee0964e6da07478d6c35016bc386b66ad4", size = 14219016, upload-time = "2024-02-05T23:48:54.098Z" },
- { url = "https://files.pythonhosted.org/packages/4b/d7/ecf66c1cd12dc28b4040b15ab4d17b773b87fa9d29ca16125de01adb36cd/numpy-1.26.4-cp310-cp310-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:ffa75af20b44f8dba823498024771d5ac50620e6915abac414251bd971b4529f", size = 18240889, upload-time = "2024-02-05T23:49:25.361Z" },
- { url = "https://files.pythonhosted.org/packages/24/03/6f229fe3187546435c4f6f89f6d26c129d4f5bed40552899fcf1f0bf9e50/numpy-1.26.4-cp310-cp310-musllinux_1_1_aarch64.whl", hash = "sha256:62b8e4b1e28009ef2846b4c7852046736bab361f7aeadeb6a5b89ebec3c7055a", size = 13876746, upload-time = "2024-02-05T23:49:51.983Z" },
- { url = "https://files.pythonhosted.org/packages/39/fe/39ada9b094f01f5a35486577c848fe274e374bbf8d8f472e1423a0bbd26d/numpy-1.26.4-cp310-cp310-musllinux_1_1_x86_64.whl", hash = "sha256:a4abb4f9001ad2858e7ac189089c42178fcce737e4169dc61321660f1a96c7d2", size = 18078620, upload-time = "2024-02-05T23:50:22.515Z" },
- { url = "https://files.pythonhosted.org/packages/d5/ef/6ad11d51197aad206a9ad2286dc1aac6a378059e06e8cf22cd08ed4f20dc/numpy-1.26.4-cp310-cp310-win32.whl", hash = "sha256:bfe25acf8b437eb2a8b2d49d443800a5f18508cd811fea3181723922a8a82b07", size = 5972659, upload-time = "2024-02-05T23:50:35.834Z" },
- { url = "https://files.pythonhosted.org/packages/19/77/538f202862b9183f54108557bfda67e17603fc560c384559e769321c9d92/numpy-1.26.4-cp310-cp310-win_amd64.whl", hash = "sha256:b97fe8060236edf3662adfc2c633f56a08ae30560c56310562cb4f95500022d5", size = 15808905, upload-time = "2024-02-05T23:51:03.701Z" },
- { url = "https://files.pythonhosted.org/packages/11/57/baae43d14fe163fa0e4c47f307b6b2511ab8d7d30177c491960504252053/numpy-1.26.4-cp311-cp311-macosx_10_9_x86_64.whl", hash = "sha256:4c66707fabe114439db9068ee468c26bbdf909cac0fb58686a42a24de1760c71", size = 20630554, upload-time = "2024-02-05T23:51:50.149Z" },
- { url = "https://files.pythonhosted.org/packages/1a/2e/151484f49fd03944c4a3ad9c418ed193cfd02724e138ac8a9505d056c582/numpy-1.26.4-cp311-cp311-macosx_11_0_arm64.whl", hash = "sha256:edd8b5fe47dab091176d21bb6de568acdd906d1887a4584a15a9a96a1dca06ef", size = 13997127, upload-time = "2024-02-05T23:52:15.314Z" },
- { url = "https://files.pythonhosted.org/packages/79/ae/7e5b85136806f9dadf4878bf73cf223fe5c2636818ba3ab1c585d0403164/numpy-1.26.4-cp311-cp311-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:7ab55401287bfec946ced39700c053796e7cc0e3acbef09993a9ad2adba6ca6e", size = 14222994, upload-time = "2024-02-05T23:52:47.569Z" },
- { url = "https://files.pythonhosted.org/packages/3a/d0/edc009c27b406c4f9cbc79274d6e46d634d139075492ad055e3d68445925/numpy-1.26.4-cp311-cp311-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:666dbfb6ec68962c033a450943ded891bed2d54e6755e35e5835d63f4f6931d5", size = 18252005, upload-time = "2024-02-05T23:53:15.637Z" },
- { url = "https://files.pythonhosted.org/packages/09/bf/2b1aaf8f525f2923ff6cfcf134ae5e750e279ac65ebf386c75a0cf6da06a/numpy-1.26.4-cp311-cp311-musllinux_1_1_aarch64.whl", hash = "sha256:96ff0b2ad353d8f990b63294c8986f1ec3cb19d749234014f4e7eb0112ceba5a", size = 13885297, upload-time = "2024-02-05T23:53:42.16Z" },
- { url = "https://files.pythonhosted.org/packages/df/a0/4e0f14d847cfc2a633a1c8621d00724f3206cfeddeb66d35698c4e2cf3d2/numpy-1.26.4-cp311-cp311-musllinux_1_1_x86_64.whl", hash = "sha256:60dedbb91afcbfdc9bc0b1f3f402804070deed7392c23eb7a7f07fa857868e8a", size = 18093567, upload-time = "2024-02-05T23:54:11.696Z" },
- { url = "https://files.pythonhosted.org/packages/d2/b7/a734c733286e10a7f1a8ad1ae8c90f2d33bf604a96548e0a4a3a6739b468/numpy-1.26.4-cp311-cp311-win32.whl", hash = "sha256:1af303d6b2210eb850fcf03064d364652b7120803a0b872f5211f5234b399f20", size = 5968812, upload-time = "2024-02-05T23:54:26.453Z" },
- { url = "https://files.pythonhosted.org/packages/3f/6b/5610004206cf7f8e7ad91c5a85a8c71b2f2f8051a0c0c4d5916b76d6cbb2/numpy-1.26.4-cp311-cp311-win_amd64.whl", hash = "sha256:cd25bcecc4974d09257ffcd1f098ee778f7834c3ad767fe5db785be9a4aa9cb2", size = 15811913, upload-time = "2024-02-05T23:54:53.933Z" },
- { url = "https://files.pythonhosted.org/packages/95/12/8f2020a8e8b8383ac0177dc9570aad031a3beb12e38847f7129bacd96228/numpy-1.26.4-cp312-cp312-macosx_10_9_x86_64.whl", hash = "sha256:b3ce300f3644fb06443ee2222c2201dd3a89ea6040541412b8fa189341847218", size = 20335901, upload-time = "2024-02-05T23:55:32.801Z" },
- { url = "https://files.pythonhosted.org/packages/75/5b/ca6c8bd14007e5ca171c7c03102d17b4f4e0ceb53957e8c44343a9546dcc/numpy-1.26.4-cp312-cp312-macosx_11_0_arm64.whl", hash = "sha256:03a8c78d01d9781b28a6989f6fa1bb2c4f2d51201cf99d3dd875df6fbd96b23b", size = 13685868, upload-time = "2024-02-05T23:55:56.28Z" },
- { url = "https://files.pythonhosted.org/packages/79/f8/97f10e6755e2a7d027ca783f63044d5b1bc1ae7acb12afe6a9b4286eac17/numpy-1.26.4-cp312-cp312-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:9fad7dcb1aac3c7f0584a5a8133e3a43eeb2fe127f47e3632d43d677c66c102b", size = 13925109, upload-time = "2024-02-05T23:56:20.368Z" },
- { url = "https://files.pythonhosted.org/packages/0f/50/de23fde84e45f5c4fda2488c759b69990fd4512387a8632860f3ac9cd225/numpy-1.26.4-cp312-cp312-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:675d61ffbfa78604709862923189bad94014bef562cc35cf61d3a07bba02a7ed", size = 17950613, upload-time = "2024-02-05T23:56:56.054Z" },
- { url = "https://files.pythonhosted.org/packages/4c/0c/9c603826b6465e82591e05ca230dfc13376da512b25ccd0894709b054ed0/numpy-1.26.4-cp312-cp312-musllinux_1_1_aarch64.whl", hash = "sha256:ab47dbe5cc8210f55aa58e4805fe224dac469cde56b9f731a4c098b91917159a", size = 13572172, upload-time = "2024-02-05T23:57:21.56Z" },
- { url = "https://files.pythonhosted.org/packages/76/8c/2ba3902e1a0fc1c74962ea9bb33a534bb05984ad7ff9515bf8d07527cadd/numpy-1.26.4-cp312-cp312-musllinux_1_1_x86_64.whl", hash = "sha256:1dda2e7b4ec9dd512f84935c5f126c8bd8b9f2fc001e9f54af255e8c5f16b0e0", size = 17786643, upload-time = "2024-02-05T23:57:56.585Z" },
- { url = "https://files.pythonhosted.org/packages/28/4a/46d9e65106879492374999e76eb85f87b15328e06bd1550668f79f7b18c6/numpy-1.26.4-cp312-cp312-win32.whl", hash = "sha256:50193e430acfc1346175fcbdaa28ffec49947a06918b7b92130744e81e640110", size = 5677803, upload-time = "2024-02-05T23:58:08.963Z" },
- { url = "https://files.pythonhosted.org/packages/16/2e/86f24451c2d530c88daf997cb8d6ac622c1d40d19f5a031ed68a4b73a374/numpy-1.26.4-cp312-cp312-win_amd64.whl", hash = "sha256:08beddf13648eb95f8d867350f6a018a4be2e5ad54c8d8caed89ebca558b2818", size = 15517754, upload-time = "2024-02-05T23:58:36.364Z" },
+ { url = "https://files.pythonhosted.org/packages/76/c6/c88e154df9c4e1a2a66ccf0005a88dfb2650c1dffb6f5ce603dfbd452ce3/idna-3.10-py3-none-any.whl", hash = "sha256:946d195a0d259cbba61165e88e65941f16e9b36ea6ddb97f00452bae8b1287d3", size = 70442, upload-time = "2024-09-15T18:07:37.964Z" },
]
[[package]]
-name = "oauthlib"
-version = "3.3.1"
+name = "loguru"
+version = "0.7.3"
source = { registry = "https://pypi.org/simple" }
-sdist = { url = "https://files.pythonhosted.org/packages/0b/5f/19930f824ffeb0ad4372da4812c50edbd1434f678c90c2733e1188edfc63/oauthlib-3.3.1.tar.gz", hash = "sha256:0f0f8aa759826a193cf66c12ea1af1637f87b9b4622d46e866952bb022e538c9", size = 185918, upload-time = "2025-06-19T22:48:08.269Z" }
+dependencies = [
+ { name = "colorama", marker = "sys_platform == 'win32'" },
+ { name = "win32-setctime", marker = "sys_platform == 'win32'" },
+]
+sdist = { url = "https://files.pythonhosted.org/packages/3a/05/a1dae3dffd1116099471c643b8924f5aa6524411dc6c63fdae648c4f1aca/loguru-0.7.3.tar.gz", hash = "sha256:19480589e77d47b8d85b2c827ad95d49bf31b0dcde16593892eb51dd18706eb6", size = 63559, upload-time = "2024-12-06T11:20:56.608Z" }
wheels = [
- { url = "https://files.pythonhosted.org/packages/be/9c/92789c596b8df838baa98fa71844d84283302f7604ed565dafe5a6b5041a/oauthlib-3.3.1-py3-none-any.whl", hash = "sha256:88119c938d2b8fb88561af5f6ee0eec8cc8d552b7bb1f712743136eb7523b7a1", size = 160065, upload-time = "2025-06-19T22:48:06.508Z" },
+ { url = "https://files.pythonhosted.org/packages/0c/29/0348de65b8cc732daa3e33e67806420b2ae89bdce2b04af740289c5c6c8c/loguru-0.7.3-py3-none-any.whl", hash = "sha256:31a33c10c8e1e10422bfd431aeb5d351c7cf7fa671e3c4df004162264b28220c", size = 61595, upload-time = "2024-12-06T11:20:54.538Z" },
]
[[package]]
-name = "openpyxl"
-version = "3.1.5"
+name = "macholib"
+version = "1.16.3"
source = { registry = "https://pypi.org/simple" }
dependencies = [
- { name = "et-xmlfile" },
+ { name = "altgraph" },
]
-sdist = { url = "https://files.pythonhosted.org/packages/3d/f9/88d94a75de065ea32619465d2f77b29a0469500e99012523b91cc4141cd1/openpyxl-3.1.5.tar.gz", hash = "sha256:cf0e3cf56142039133628b5acffe8ef0c12bc902d2aadd3e0fe5878dc08d1050", size = 186464, upload-time = "2024-06-28T14:03:44.161Z" }
+sdist = { url = "https://files.pythonhosted.org/packages/95/ee/af1a3842bdd5902ce133bd246eb7ffd4375c38642aeb5dc0ae3a0329dfa2/macholib-1.16.3.tar.gz", hash = "sha256:07ae9e15e8e4cd9a788013d81f5908b3609aa76f9b1421bae9c4d7606ec86a30", size = 59309, upload-time = "2023-09-25T09:10:16.155Z" }
wheels = [
- { url = "https://files.pythonhosted.org/packages/c0/da/977ded879c29cbd04de313843e76868e6e13408a94ed6b987245dc7c8506/openpyxl-3.1.5-py2.py3-none-any.whl", hash = "sha256:5282c12b107bffeef825f4617dc029afaf41d0ea60823bbb665ef3079dc79de2", size = 250910, upload-time = "2024-06-28T14:03:41.161Z" },
+ { url = "https://files.pythonhosted.org/packages/d1/5d/c059c180c84f7962db0aeae7c3b9303ed1d73d76f2bfbc32bc231c8be314/macholib-1.16.3-py2.py3-none-any.whl", hash = "sha256:0e315d7583d38b8c77e815b1ecbdbf504a8258d8b3e17b61165c6feb60d18f2c", size = 38094, upload-time = "2023-09-25T09:10:14.188Z" },
]
[[package]]
@@ -1109,54 +235,6 @@ wheels = [
{ url = "https://files.pythonhosted.org/packages/88/ef/eb23f262cca3c0c4eb7ab1933c3b1f03d021f2c48f54763065b6f0e321be/packaging-24.2-py3-none-any.whl", hash = "sha256:09abb1bccd265c01f4a3aa3f7a7db064b36514d2cba19a2f694fe6150451a759", size = 65451, upload-time = "2024-11-08T09:47:44.722Z" },
]
-[[package]]
-name = "pandas"
-version = "2.2.3"
-source = { registry = "https://pypi.org/simple" }
-dependencies = [
- { name = "numpy" },
- { name = "python-dateutil" },
- { name = "pytz" },
- { name = "tzdata" },
-]
-sdist = { url = "https://files.pythonhosted.org/packages/9c/d6/9f8431bacc2e19dca897724cd097b1bb224a6ad5433784a44b587c7c13af/pandas-2.2.3.tar.gz", hash = "sha256:4f18ba62b61d7e192368b84517265a99b4d7ee8912f8708660fb4a366cc82667", size = 4399213, upload-time = "2024-09-20T13:10:04.827Z" }
-wheels = [
- { url = "https://files.pythonhosted.org/packages/aa/70/c853aec59839bceed032d52010ff5f1b8d87dc3114b762e4ba2727661a3b/pandas-2.2.3-cp310-cp310-macosx_10_9_x86_64.whl", hash = "sha256:1948ddde24197a0f7add2bdc4ca83bf2b1ef84a1bc8ccffd95eda17fd836ecb5", size = 12580827, upload-time = "2024-09-20T13:08:42.347Z" },
- { url = "https://files.pythonhosted.org/packages/99/f2/c4527768739ffa4469b2b4fff05aa3768a478aed89a2f271a79a40eee984/pandas-2.2.3-cp310-cp310-macosx_11_0_arm64.whl", hash = "sha256:381175499d3802cde0eabbaf6324cce0c4f5d52ca6f8c377c29ad442f50f6348", size = 11303897, upload-time = "2024-09-20T13:08:45.807Z" },
- { url = "https://files.pythonhosted.org/packages/ed/12/86c1747ea27989d7a4064f806ce2bae2c6d575b950be087837bdfcabacc9/pandas-2.2.3-cp310-cp310-manylinux2014_aarch64.manylinux_2_17_aarch64.whl", hash = "sha256:d9c45366def9a3dd85a6454c0e7908f2b3b8e9c138f5dc38fed7ce720d8453ed", size = 66480908, upload-time = "2024-09-20T18:37:13.513Z" },
- { url = "https://files.pythonhosted.org/packages/44/50/7db2cd5e6373ae796f0ddad3675268c8d59fb6076e66f0c339d61cea886b/pandas-2.2.3-cp310-cp310-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:86976a1c5b25ae3f8ccae3a5306e443569ee3c3faf444dfd0f41cda24667ad57", size = 13064210, upload-time = "2024-09-20T13:08:48.325Z" },
- { url = "https://files.pythonhosted.org/packages/61/61/a89015a6d5536cb0d6c3ba02cebed51a95538cf83472975275e28ebf7d0c/pandas-2.2.3-cp310-cp310-musllinux_1_2_aarch64.whl", hash = "sha256:b8661b0238a69d7aafe156b7fa86c44b881387509653fdf857bebc5e4008ad42", size = 16754292, upload-time = "2024-09-20T19:01:54.443Z" },
- { url = "https://files.pythonhosted.org/packages/ce/0d/4cc7b69ce37fac07645a94e1d4b0880b15999494372c1523508511b09e40/pandas-2.2.3-cp310-cp310-musllinux_1_2_x86_64.whl", hash = "sha256:37e0aced3e8f539eccf2e099f65cdb9c8aa85109b0be6e93e2baff94264bdc6f", size = 14416379, upload-time = "2024-09-20T13:08:50.882Z" },
- { url = "https://files.pythonhosted.org/packages/31/9e/6ebb433de864a6cd45716af52a4d7a8c3c9aaf3a98368e61db9e69e69a9c/pandas-2.2.3-cp310-cp310-win_amd64.whl", hash = "sha256:56534ce0746a58afaf7942ba4863e0ef81c9c50d3f0ae93e9497d6a41a057645", size = 11598471, upload-time = "2024-09-20T13:08:53.332Z" },
- { url = "https://files.pythonhosted.org/packages/a8/44/d9502bf0ed197ba9bf1103c9867d5904ddcaf869e52329787fc54ed70cc8/pandas-2.2.3-cp311-cp311-macosx_10_9_x86_64.whl", hash = "sha256:66108071e1b935240e74525006034333f98bcdb87ea116de573a6a0dccb6c039", size = 12602222, upload-time = "2024-09-20T13:08:56.254Z" },
- { url = "https://files.pythonhosted.org/packages/52/11/9eac327a38834f162b8250aab32a6781339c69afe7574368fffe46387edf/pandas-2.2.3-cp311-cp311-macosx_11_0_arm64.whl", hash = "sha256:7c2875855b0ff77b2a64a0365e24455d9990730d6431b9e0ee18ad8acee13dbd", size = 11321274, upload-time = "2024-09-20T13:08:58.645Z" },
- { url = "https://files.pythonhosted.org/packages/45/fb/c4beeb084718598ba19aa9f5abbc8aed8b42f90930da861fcb1acdb54c3a/pandas-2.2.3-cp311-cp311-manylinux2014_aarch64.manylinux_2_17_aarch64.whl", hash = "sha256:cd8d0c3be0515c12fed0bdbae072551c8b54b7192c7b1fda0ba56059a0179698", size = 15579836, upload-time = "2024-09-20T19:01:57.571Z" },
- { url = "https://files.pythonhosted.org/packages/cd/5f/4dba1d39bb9c38d574a9a22548c540177f78ea47b32f99c0ff2ec499fac5/pandas-2.2.3-cp311-cp311-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:c124333816c3a9b03fbeef3a9f230ba9a737e9e5bb4060aa2107a86cc0a497fc", size = 13058505, upload-time = "2024-09-20T13:09:01.501Z" },
- { url = "https://files.pythonhosted.org/packages/b9/57/708135b90391995361636634df1f1130d03ba456e95bcf576fada459115a/pandas-2.2.3-cp311-cp311-musllinux_1_2_aarch64.whl", hash = "sha256:63cc132e40a2e084cf01adf0775b15ac515ba905d7dcca47e9a251819c575ef3", size = 16744420, upload-time = "2024-09-20T19:02:00.678Z" },
- { url = "https://files.pythonhosted.org/packages/86/4a/03ed6b7ee323cf30404265c284cee9c65c56a212e0a08d9ee06984ba2240/pandas-2.2.3-cp311-cp311-musllinux_1_2_x86_64.whl", hash = "sha256:29401dbfa9ad77319367d36940cd8a0b3a11aba16063e39632d98b0e931ddf32", size = 14440457, upload-time = "2024-09-20T13:09:04.105Z" },
- { url = "https://files.pythonhosted.org/packages/ed/8c/87ddf1fcb55d11f9f847e3c69bb1c6f8e46e2f40ab1a2d2abadb2401b007/pandas-2.2.3-cp311-cp311-win_amd64.whl", hash = "sha256:3fc6873a41186404dad67245896a6e440baacc92f5b716ccd1bc9ed2995ab2c5", size = 11617166, upload-time = "2024-09-20T13:09:06.917Z" },
- { url = "https://files.pythonhosted.org/packages/17/a3/fb2734118db0af37ea7433f57f722c0a56687e14b14690edff0cdb4b7e58/pandas-2.2.3-cp312-cp312-macosx_10_9_x86_64.whl", hash = "sha256:b1d432e8d08679a40e2a6d8b2f9770a5c21793a6f9f47fdd52c5ce1948a5a8a9", size = 12529893, upload-time = "2024-09-20T13:09:09.655Z" },
- { url = "https://files.pythonhosted.org/packages/e1/0c/ad295fd74bfac85358fd579e271cded3ac969de81f62dd0142c426b9da91/pandas-2.2.3-cp312-cp312-macosx_11_0_arm64.whl", hash = "sha256:a5a1595fe639f5988ba6a8e5bc9649af3baf26df3998a0abe56c02609392e0a4", size = 11363475, upload-time = "2024-09-20T13:09:14.718Z" },
- { url = "https://files.pythonhosted.org/packages/c6/2a/4bba3f03f7d07207481fed47f5b35f556c7441acddc368ec43d6643c5777/pandas-2.2.3-cp312-cp312-manylinux2014_aarch64.manylinux_2_17_aarch64.whl", hash = "sha256:5de54125a92bb4d1c051c0659e6fcb75256bf799a732a87184e5ea503965bce3", size = 15188645, upload-time = "2024-09-20T19:02:03.88Z" },
- { url = "https://files.pythonhosted.org/packages/38/f8/d8fddee9ed0d0c0f4a2132c1dfcf0e3e53265055da8df952a53e7eaf178c/pandas-2.2.3-cp312-cp312-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:fffb8ae78d8af97f849404f21411c95062db1496aeb3e56f146f0355c9989319", size = 12739445, upload-time = "2024-09-20T13:09:17.621Z" },
- { url = "https://files.pythonhosted.org/packages/20/e8/45a05d9c39d2cea61ab175dbe6a2de1d05b679e8de2011da4ee190d7e748/pandas-2.2.3-cp312-cp312-musllinux_1_2_aarch64.whl", hash = "sha256:6dfcb5ee8d4d50c06a51c2fffa6cff6272098ad6540aed1a76d15fb9318194d8", size = 16359235, upload-time = "2024-09-20T19:02:07.094Z" },
- { url = "https://files.pythonhosted.org/packages/1d/99/617d07a6a5e429ff90c90da64d428516605a1ec7d7bea494235e1c3882de/pandas-2.2.3-cp312-cp312-musllinux_1_2_x86_64.whl", hash = "sha256:062309c1b9ea12a50e8ce661145c6aab431b1e99530d3cd60640e255778bd43a", size = 14056756, upload-time = "2024-09-20T13:09:20.474Z" },
- { url = "https://files.pythonhosted.org/packages/29/d4/1244ab8edf173a10fd601f7e13b9566c1b525c4f365d6bee918e68381889/pandas-2.2.3-cp312-cp312-win_amd64.whl", hash = "sha256:59ef3764d0fe818125a5097d2ae867ca3fa64df032331b7e0917cf5d7bf66b13", size = 11504248, upload-time = "2024-09-20T13:09:23.137Z" },
- { url = "https://files.pythonhosted.org/packages/64/22/3b8f4e0ed70644e85cfdcd57454686b9057c6c38d2f74fe4b8bc2527214a/pandas-2.2.3-cp313-cp313-macosx_10_13_x86_64.whl", hash = "sha256:f00d1345d84d8c86a63e476bb4955e46458b304b9575dcf71102b5c705320015", size = 12477643, upload-time = "2024-09-20T13:09:25.522Z" },
- { url = "https://files.pythonhosted.org/packages/e4/93/b3f5d1838500e22c8d793625da672f3eec046b1a99257666c94446969282/pandas-2.2.3-cp313-cp313-macosx_11_0_arm64.whl", hash = "sha256:3508d914817e153ad359d7e069d752cdd736a247c322d932eb89e6bc84217f28", size = 11281573, upload-time = "2024-09-20T13:09:28.012Z" },
- { url = "https://files.pythonhosted.org/packages/f5/94/6c79b07f0e5aab1dcfa35a75f4817f5c4f677931d4234afcd75f0e6a66ca/pandas-2.2.3-cp313-cp313-manylinux2014_aarch64.manylinux_2_17_aarch64.whl", hash = "sha256:22a9d949bfc9a502d320aa04e5d02feab689d61da4e7764b62c30b991c42c5f0", size = 15196085, upload-time = "2024-09-20T19:02:10.451Z" },
- { url = "https://files.pythonhosted.org/packages/e8/31/aa8da88ca0eadbabd0a639788a6da13bb2ff6edbbb9f29aa786450a30a91/pandas-2.2.3-cp313-cp313-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:f3a255b2c19987fbbe62a9dfd6cff7ff2aa9ccab3fc75218fd4b7530f01efa24", size = 12711809, upload-time = "2024-09-20T13:09:30.814Z" },
- { url = "https://files.pythonhosted.org/packages/ee/7c/c6dbdb0cb2a4344cacfb8de1c5808ca885b2e4dcfde8008266608f9372af/pandas-2.2.3-cp313-cp313-musllinux_1_2_aarch64.whl", hash = "sha256:800250ecdadb6d9c78eae4990da62743b857b470883fa27f652db8bdde7f6659", size = 16356316, upload-time = "2024-09-20T19:02:13.825Z" },
- { url = "https://files.pythonhosted.org/packages/57/b7/8b757e7d92023b832869fa8881a992696a0bfe2e26f72c9ae9f255988d42/pandas-2.2.3-cp313-cp313-musllinux_1_2_x86_64.whl", hash = "sha256:6374c452ff3ec675a8f46fd9ab25c4ad0ba590b71cf0656f8b6daa5202bca3fb", size = 14022055, upload-time = "2024-09-20T13:09:33.462Z" },
- { url = "https://files.pythonhosted.org/packages/3b/bc/4b18e2b8c002572c5a441a64826252ce5da2aa738855747247a971988043/pandas-2.2.3-cp313-cp313-win_amd64.whl", hash = "sha256:61c5ad4043f791b61dd4752191d9f07f0ae412515d59ba8f005832a532f8736d", size = 11481175, upload-time = "2024-09-20T13:09:35.871Z" },
- { url = "https://files.pythonhosted.org/packages/76/a3/a5d88146815e972d40d19247b2c162e88213ef51c7c25993942c39dbf41d/pandas-2.2.3-cp313-cp313t-macosx_10_13_x86_64.whl", hash = "sha256:3b71f27954685ee685317063bf13c7709a7ba74fc996b84fc6821c59b0f06468", size = 12615650, upload-time = "2024-09-20T13:09:38.685Z" },
- { url = "https://files.pythonhosted.org/packages/9c/8c/f0fd18f6140ddafc0c24122c8a964e48294acc579d47def376fef12bcb4a/pandas-2.2.3-cp313-cp313t-macosx_11_0_arm64.whl", hash = "sha256:38cf8125c40dae9d5acc10fa66af8ea6fdf760b2714ee482ca691fc66e6fcb18", size = 11290177, upload-time = "2024-09-20T13:09:41.141Z" },
- { url = "https://files.pythonhosted.org/packages/ed/f9/e995754eab9c0f14c6777401f7eece0943840b7a9fc932221c19d1abee9f/pandas-2.2.3-cp313-cp313t-manylinux2014_aarch64.manylinux_2_17_aarch64.whl", hash = "sha256:ba96630bc17c875161df3818780af30e43be9b166ce51c9a18c1feae342906c2", size = 14651526, upload-time = "2024-09-20T19:02:16.905Z" },
- { url = "https://files.pythonhosted.org/packages/25/b0/98d6ae2e1abac4f35230aa756005e8654649d305df9a28b16b9ae4353bff/pandas-2.2.3-cp313-cp313t-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:1db71525a1538b30142094edb9adc10be3f3e176748cd7acc2240c2f2e5aa3a4", size = 11871013, upload-time = "2024-09-20T13:09:44.39Z" },
- { url = "https://files.pythonhosted.org/packages/cc/57/0f72a10f9db6a4628744c8e8f0df4e6e21de01212c7c981d31e50ffc8328/pandas-2.2.3-cp313-cp313t-musllinux_1_2_aarch64.whl", hash = "sha256:15c0e1e02e93116177d29ff83e8b1619c93ddc9c49083f237d4312337a61165d", size = 15711620, upload-time = "2024-09-20T19:02:20.639Z" },
- { url = "https://files.pythonhosted.org/packages/ab/5f/b38085618b950b79d2d9164a711c52b10aefc0ae6833b96f626b7021b2ed/pandas-2.2.3-cp313-cp313t-musllinux_1_2_x86_64.whl", hash = "sha256:ad5b65698ab28ed8d7f18790a0dc58005c7629f227be9ecc1072aa74c0c1d43a", size = 13098436, upload-time = "2024-09-20T13:09:48.112Z" },
-]
-
[[package]]
name = "pefile"
version = "2023.2.7"
@@ -1213,131 +291,6 @@ wheels = [
{ url = "https://files.pythonhosted.org/packages/08/c1/b5218b5e4966c872bdae69c679b7d8f6e1ebd3338df47659d6c314b99c54/pillow-10.2.0-pp310-pypy310_pp73-win_amd64.whl", hash = "sha256:a2b56ba36e05f973d450582fb015594aaa78834fefe8dfb8fcd79b93e64ba4c6", size = 2621764, upload-time = "2024-01-02T09:16:44.36Z" },
]
-[[package]]
-name = "prettytable"
-version = "3.16.0"
-source = { registry = "https://pypi.org/simple" }
-dependencies = [
- { name = "wcwidth" },
-]
-sdist = { url = "https://files.pythonhosted.org/packages/99/b1/85e18ac92afd08c533603e3393977b6bc1443043115a47bb094f3b98f94f/prettytable-3.16.0.tar.gz", hash = "sha256:3c64b31719d961bf69c9a7e03d0c1e477320906a98da63952bc6698d6164ff57", size = 66276, upload-time = "2025-03-24T19:39:04.008Z" }
-wheels = [
- { url = "https://files.pythonhosted.org/packages/02/c7/5613524e606ea1688b3bdbf48aa64bafb6d0a4ac3750274c43b6158a390f/prettytable-3.16.0-py3-none-any.whl", hash = "sha256:b5eccfabb82222f5aa46b798ff02a8452cf530a352c31bddfa29be41242863aa", size = 33863, upload-time = "2025-03-24T19:39:02.359Z" },
-]
-
-[[package]]
-name = "propcache"
-version = "0.3.1"
-source = { registry = "https://pypi.org/simple" }
-sdist = { url = "https://files.pythonhosted.org/packages/07/c8/fdc6686a986feae3541ea23dcaa661bd93972d3940460646c6bb96e21c40/propcache-0.3.1.tar.gz", hash = "sha256:40d980c33765359098837527e18eddefc9a24cea5b45e078a7f3bb5b032c6ecf", size = 43651, upload-time = "2025-03-26T03:06:12.05Z" }
-wheels = [
- { url = "https://files.pythonhosted.org/packages/20/56/e27c136101addf877c8291dbda1b3b86ae848f3837ce758510a0d806c92f/propcache-0.3.1-cp310-cp310-macosx_10_9_universal2.whl", hash = "sha256:f27785888d2fdd918bc36de8b8739f2d6c791399552333721b58193f68ea3e98", size = 80224, upload-time = "2025-03-26T03:03:35.81Z" },
- { url = "https://files.pythonhosted.org/packages/63/bd/88e98836544c4f04db97eefd23b037c2002fa173dd2772301c61cd3085f9/propcache-0.3.1-cp310-cp310-macosx_10_9_x86_64.whl", hash = "sha256:d4e89cde74154c7b5957f87a355bb9c8ec929c167b59c83d90654ea36aeb6180", size = 46491, upload-time = "2025-03-26T03:03:38.107Z" },
- { url = "https://files.pythonhosted.org/packages/15/43/0b8eb2a55753c4a574fc0899885da504b521068d3b08ca56774cad0bea2b/propcache-0.3.1-cp310-cp310-macosx_11_0_arm64.whl", hash = "sha256:730178f476ef03d3d4d255f0c9fa186cb1d13fd33ffe89d39f2cda4da90ceb71", size = 45927, upload-time = "2025-03-26T03:03:39.394Z" },
- { url = "https://files.pythonhosted.org/packages/ad/6c/d01f9dfbbdc613305e0a831016844987a1fb4861dd221cd4c69b1216b43f/propcache-0.3.1-cp310-cp310-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:967a8eec513dbe08330f10137eacb427b2ca52118769e82ebcfcab0fba92a649", size = 206135, upload-time = "2025-03-26T03:03:40.757Z" },
- { url = "https://files.pythonhosted.org/packages/9a/8a/e6e1c77394088f4cfdace4a91a7328e398ebed745d59c2f6764135c5342d/propcache-0.3.1-cp310-cp310-manylinux_2_17_ppc64le.manylinux2014_ppc64le.whl", hash = "sha256:5b9145c35cc87313b5fd480144f8078716007656093d23059e8993d3a8fa730f", size = 220517, upload-time = "2025-03-26T03:03:42.657Z" },
- { url = "https://files.pythonhosted.org/packages/19/3b/6c44fa59d6418f4239d5db8b1ece757351e85d6f3ca126dfe37d427020c8/propcache-0.3.1-cp310-cp310-manylinux_2_17_s390x.manylinux2014_s390x.whl", hash = "sha256:9e64e948ab41411958670f1093c0a57acfdc3bee5cf5b935671bbd5313bcf229", size = 218952, upload-time = "2025-03-26T03:03:44.549Z" },
- { url = "https://files.pythonhosted.org/packages/7c/e4/4aeb95a1cd085e0558ab0de95abfc5187329616193a1012a6c4c930e9f7a/propcache-0.3.1-cp310-cp310-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:319fa8765bfd6a265e5fa661547556da381e53274bc05094fc9ea50da51bfd46", size = 206593, upload-time = "2025-03-26T03:03:46.114Z" },
- { url = "https://files.pythonhosted.org/packages/da/6a/29fa75de1cbbb302f1e1d684009b969976ca603ee162282ae702287b6621/propcache-0.3.1-cp310-cp310-manylinux_2_5_i686.manylinux1_i686.manylinux_2_17_i686.manylinux2014_i686.whl", hash = "sha256:c66d8ccbc902ad548312b96ed8d5d266d0d2c6d006fd0f66323e9d8f2dd49be7", size = 196745, upload-time = "2025-03-26T03:03:48.02Z" },
- { url = "https://files.pythonhosted.org/packages/19/7e/2237dad1dbffdd2162de470599fa1a1d55df493b16b71e5d25a0ac1c1543/propcache-0.3.1-cp310-cp310-musllinux_1_2_aarch64.whl", hash = "sha256:2d219b0dbabe75e15e581fc1ae796109b07c8ba7d25b9ae8d650da582bed01b0", size = 203369, upload-time = "2025-03-26T03:03:49.63Z" },
- { url = "https://files.pythonhosted.org/packages/a4/bc/a82c5878eb3afb5c88da86e2cf06e1fe78b7875b26198dbb70fe50a010dc/propcache-0.3.1-cp310-cp310-musllinux_1_2_armv7l.whl", hash = "sha256:cd6a55f65241c551eb53f8cf4d2f4af33512c39da5d9777694e9d9c60872f519", size = 198723, upload-time = "2025-03-26T03:03:51.091Z" },
- { url = "https://files.pythonhosted.org/packages/17/76/9632254479c55516f51644ddbf747a45f813031af5adcb8db91c0b824375/propcache-0.3.1-cp310-cp310-musllinux_1_2_i686.whl", hash = "sha256:9979643ffc69b799d50d3a7b72b5164a2e97e117009d7af6dfdd2ab906cb72cd", size = 200751, upload-time = "2025-03-26T03:03:52.631Z" },
- { url = "https://files.pythonhosted.org/packages/3e/c3/a90b773cf639bd01d12a9e20c95be0ae978a5a8abe6d2d343900ae76cd71/propcache-0.3.1-cp310-cp310-musllinux_1_2_ppc64le.whl", hash = "sha256:4cf9e93a81979f1424f1a3d155213dc928f1069d697e4353edb8a5eba67c6259", size = 210730, upload-time = "2025-03-26T03:03:54.498Z" },
- { url = "https://files.pythonhosted.org/packages/ed/ec/ad5a952cdb9d65c351f88db7c46957edd3d65ffeee72a2f18bd6341433e0/propcache-0.3.1-cp310-cp310-musllinux_1_2_s390x.whl", hash = "sha256:2fce1df66915909ff6c824bbb5eb403d2d15f98f1518e583074671a30fe0c21e", size = 213499, upload-time = "2025-03-26T03:03:56.054Z" },
- { url = "https://files.pythonhosted.org/packages/83/c0/ea5133dda43e298cd2010ec05c2821b391e10980e64ee72c0a76cdbb813a/propcache-0.3.1-cp310-cp310-musllinux_1_2_x86_64.whl", hash = "sha256:4d0dfdd9a2ebc77b869a0b04423591ea8823f791293b527dc1bb896c1d6f1136", size = 207132, upload-time = "2025-03-26T03:03:57.398Z" },
- { url = "https://files.pythonhosted.org/packages/79/dd/71aae9dec59333064cfdd7eb31a63fa09f64181b979802a67a90b2abfcba/propcache-0.3.1-cp310-cp310-win32.whl", hash = "sha256:1f6cc0ad7b4560e5637eb2c994e97b4fa41ba8226069c9277eb5ea7101845b42", size = 40952, upload-time = "2025-03-26T03:03:59.146Z" },
- { url = "https://files.pythonhosted.org/packages/31/0a/49ff7e5056c17dfba62cbdcbb90a29daffd199c52f8e65e5cb09d5f53a57/propcache-0.3.1-cp310-cp310-win_amd64.whl", hash = "sha256:47ef24aa6511e388e9894ec16f0fbf3313a53ee68402bc428744a367ec55b833", size = 45163, upload-time = "2025-03-26T03:04:00.672Z" },
- { url = "https://files.pythonhosted.org/packages/90/0f/5a5319ee83bd651f75311fcb0c492c21322a7fc8f788e4eef23f44243427/propcache-0.3.1-cp311-cp311-macosx_10_9_universal2.whl", hash = "sha256:7f30241577d2fef2602113b70ef7231bf4c69a97e04693bde08ddab913ba0ce5", size = 80243, upload-time = "2025-03-26T03:04:01.912Z" },
- { url = "https://files.pythonhosted.org/packages/ce/84/3db5537e0879942783e2256616ff15d870a11d7ac26541336fe1b673c818/propcache-0.3.1-cp311-cp311-macosx_10_9_x86_64.whl", hash = "sha256:43593c6772aa12abc3af7784bff4a41ffa921608dd38b77cf1dfd7f5c4e71371", size = 46503, upload-time = "2025-03-26T03:04:03.704Z" },
- { url = "https://files.pythonhosted.org/packages/e2/c8/b649ed972433c3f0d827d7f0cf9ea47162f4ef8f4fe98c5f3641a0bc63ff/propcache-0.3.1-cp311-cp311-macosx_11_0_arm64.whl", hash = "sha256:a75801768bbe65499495660b777e018cbe90c7980f07f8aa57d6be79ea6f71da", size = 45934, upload-time = "2025-03-26T03:04:05.257Z" },
- { url = "https://files.pythonhosted.org/packages/59/f9/4c0a5cf6974c2c43b1a6810c40d889769cc8f84cea676cbe1e62766a45f8/propcache-0.3.1-cp311-cp311-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:f6f1324db48f001c2ca26a25fa25af60711e09b9aaf4b28488602776f4f9a744", size = 233633, upload-time = "2025-03-26T03:04:07.044Z" },
- { url = "https://files.pythonhosted.org/packages/e7/64/66f2f4d1b4f0007c6e9078bd95b609b633d3957fe6dd23eac33ebde4b584/propcache-0.3.1-cp311-cp311-manylinux_2_17_ppc64le.manylinux2014_ppc64le.whl", hash = "sha256:5cdb0f3e1eb6dfc9965d19734d8f9c481b294b5274337a8cb5cb01b462dcb7e0", size = 241124, upload-time = "2025-03-26T03:04:08.676Z" },
- { url = "https://files.pythonhosted.org/packages/aa/bf/7b8c9fd097d511638fa9b6af3d986adbdf567598a567b46338c925144c1b/propcache-0.3.1-cp311-cp311-manylinux_2_17_s390x.manylinux2014_s390x.whl", hash = "sha256:1eb34d90aac9bfbced9a58b266f8946cb5935869ff01b164573a7634d39fbcb5", size = 240283, upload-time = "2025-03-26T03:04:10.172Z" },
- { url = "https://files.pythonhosted.org/packages/fa/c9/e85aeeeaae83358e2a1ef32d6ff50a483a5d5248bc38510d030a6f4e2816/propcache-0.3.1-cp311-cp311-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:f35c7070eeec2cdaac6fd3fe245226ed2a6292d3ee8c938e5bb645b434c5f256", size = 232498, upload-time = "2025-03-26T03:04:11.616Z" },
- { url = "https://files.pythonhosted.org/packages/8e/66/acb88e1f30ef5536d785c283af2e62931cb934a56a3ecf39105887aa8905/propcache-0.3.1-cp311-cp311-manylinux_2_5_i686.manylinux1_i686.manylinux_2_17_i686.manylinux2014_i686.whl", hash = "sha256:b23c11c2c9e6d4e7300c92e022046ad09b91fd00e36e83c44483df4afa990073", size = 221486, upload-time = "2025-03-26T03:04:13.102Z" },
- { url = "https://files.pythonhosted.org/packages/f5/f9/233ddb05ffdcaee4448508ee1d70aa7deff21bb41469ccdfcc339f871427/propcache-0.3.1-cp311-cp311-musllinux_1_2_aarch64.whl", hash = "sha256:3e19ea4ea0bf46179f8a3652ac1426e6dcbaf577ce4b4f65be581e237340420d", size = 222675, upload-time = "2025-03-26T03:04:14.658Z" },
- { url = "https://files.pythonhosted.org/packages/98/b8/eb977e28138f9e22a5a789daf608d36e05ed93093ef12a12441030da800a/propcache-0.3.1-cp311-cp311-musllinux_1_2_armv7l.whl", hash = "sha256:bd39c92e4c8f6cbf5f08257d6360123af72af9f4da75a690bef50da77362d25f", size = 215727, upload-time = "2025-03-26T03:04:16.207Z" },
- { url = "https://files.pythonhosted.org/packages/89/2d/5f52d9c579f67b8ee1edd9ec073c91b23cc5b7ff7951a1e449e04ed8fdf3/propcache-0.3.1-cp311-cp311-musllinux_1_2_i686.whl", hash = "sha256:b0313e8b923b3814d1c4a524c93dfecea5f39fa95601f6a9b1ac96cd66f89ea0", size = 217878, upload-time = "2025-03-26T03:04:18.11Z" },
- { url = "https://files.pythonhosted.org/packages/7a/fd/5283e5ed8a82b00c7a989b99bb6ea173db1ad750bf0bf8dff08d3f4a4e28/propcache-0.3.1-cp311-cp311-musllinux_1_2_ppc64le.whl", hash = "sha256:e861ad82892408487be144906a368ddbe2dc6297074ade2d892341b35c59844a", size = 230558, upload-time = "2025-03-26T03:04:19.562Z" },
- { url = "https://files.pythonhosted.org/packages/90/38/ab17d75938ef7ac87332c588857422ae126b1c76253f0f5b1242032923ca/propcache-0.3.1-cp311-cp311-musllinux_1_2_s390x.whl", hash = "sha256:61014615c1274df8da5991a1e5da85a3ccb00c2d4701ac6f3383afd3ca47ab0a", size = 233754, upload-time = "2025-03-26T03:04:21.065Z" },
- { url = "https://files.pythonhosted.org/packages/06/5d/3b921b9c60659ae464137508d3b4c2b3f52f592ceb1964aa2533b32fcf0b/propcache-0.3.1-cp311-cp311-musllinux_1_2_x86_64.whl", hash = "sha256:71ebe3fe42656a2328ab08933d420df5f3ab121772eef78f2dc63624157f0ed9", size = 226088, upload-time = "2025-03-26T03:04:22.718Z" },
- { url = "https://files.pythonhosted.org/packages/54/6e/30a11f4417d9266b5a464ac5a8c5164ddc9dd153dfa77bf57918165eb4ae/propcache-0.3.1-cp311-cp311-win32.whl", hash = "sha256:58aa11f4ca8b60113d4b8e32d37e7e78bd8af4d1a5b5cb4979ed856a45e62005", size = 40859, upload-time = "2025-03-26T03:04:24.039Z" },
- { url = "https://files.pythonhosted.org/packages/1d/3a/8a68dd867da9ca2ee9dfd361093e9cb08cb0f37e5ddb2276f1b5177d7731/propcache-0.3.1-cp311-cp311-win_amd64.whl", hash = "sha256:9532ea0b26a401264b1365146c440a6d78269ed41f83f23818d4b79497aeabe7", size = 45153, upload-time = "2025-03-26T03:04:25.211Z" },
- { url = "https://files.pythonhosted.org/packages/41/aa/ca78d9be314d1e15ff517b992bebbed3bdfef5b8919e85bf4940e57b6137/propcache-0.3.1-cp312-cp312-macosx_10_13_universal2.whl", hash = "sha256:f78eb8422acc93d7b69964012ad7048764bb45a54ba7a39bb9e146c72ea29723", size = 80430, upload-time = "2025-03-26T03:04:26.436Z" },
- { url = "https://files.pythonhosted.org/packages/1a/d8/f0c17c44d1cda0ad1979af2e593ea290defdde9eaeb89b08abbe02a5e8e1/propcache-0.3.1-cp312-cp312-macosx_10_13_x86_64.whl", hash = "sha256:89498dd49c2f9a026ee057965cdf8192e5ae070ce7d7a7bd4b66a8e257d0c976", size = 46637, upload-time = "2025-03-26T03:04:27.932Z" },
- { url = "https://files.pythonhosted.org/packages/ae/bd/c1e37265910752e6e5e8a4c1605d0129e5b7933c3dc3cf1b9b48ed83b364/propcache-0.3.1-cp312-cp312-macosx_11_0_arm64.whl", hash = "sha256:09400e98545c998d57d10035ff623266927cb784d13dd2b31fd33b8a5316b85b", size = 46123, upload-time = "2025-03-26T03:04:30.659Z" },
- { url = "https://files.pythonhosted.org/packages/d4/b0/911eda0865f90c0c7e9f0415d40a5bf681204da5fd7ca089361a64c16b28/propcache-0.3.1-cp312-cp312-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:aa8efd8c5adc5a2c9d3b952815ff8f7710cefdcaf5f2c36d26aff51aeca2f12f", size = 243031, upload-time = "2025-03-26T03:04:31.977Z" },
- { url = "https://files.pythonhosted.org/packages/0a/06/0da53397c76a74271621807265b6eb61fb011451b1ddebf43213df763669/propcache-0.3.1-cp312-cp312-manylinux_2_17_ppc64le.manylinux2014_ppc64le.whl", hash = "sha256:c2fe5c910f6007e716a06d269608d307b4f36e7babee5f36533722660e8c4a70", size = 249100, upload-time = "2025-03-26T03:04:33.45Z" },
- { url = "https://files.pythonhosted.org/packages/f1/eb/13090e05bf6b963fc1653cdc922133ced467cb4b8dab53158db5a37aa21e/propcache-0.3.1-cp312-cp312-manylinux_2_17_s390x.manylinux2014_s390x.whl", hash = "sha256:a0ab8cf8cdd2194f8ff979a43ab43049b1df0b37aa64ab7eca04ac14429baeb7", size = 250170, upload-time = "2025-03-26T03:04:35.542Z" },
- { url = "https://files.pythonhosted.org/packages/3b/4c/f72c9e1022b3b043ec7dc475a0f405d4c3e10b9b1d378a7330fecf0652da/propcache-0.3.1-cp312-cp312-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:563f9d8c03ad645597b8d010ef4e9eab359faeb11a0a2ac9f7b4bc8c28ebef25", size = 245000, upload-time = "2025-03-26T03:04:37.501Z" },
- { url = "https://files.pythonhosted.org/packages/e8/fd/970ca0e22acc829f1adf5de3724085e778c1ad8a75bec010049502cb3a86/propcache-0.3.1-cp312-cp312-manylinux_2_5_i686.manylinux1_i686.manylinux_2_17_i686.manylinux2014_i686.whl", hash = "sha256:fb6e0faf8cb6b4beea5d6ed7b5a578254c6d7df54c36ccd3d8b3eb00d6770277", size = 230262, upload-time = "2025-03-26T03:04:39.532Z" },
- { url = "https://files.pythonhosted.org/packages/c4/42/817289120c6b9194a44f6c3e6b2c3277c5b70bbad39e7df648f177cc3634/propcache-0.3.1-cp312-cp312-musllinux_1_2_aarch64.whl", hash = "sha256:1c5c7ab7f2bb3f573d1cb921993006ba2d39e8621019dffb1c5bc94cdbae81e8", size = 236772, upload-time = "2025-03-26T03:04:41.109Z" },
- { url = "https://files.pythonhosted.org/packages/7c/9c/3b3942b302badd589ad6b672da3ca7b660a6c2f505cafd058133ddc73918/propcache-0.3.1-cp312-cp312-musllinux_1_2_armv7l.whl", hash = "sha256:050b571b2e96ec942898f8eb46ea4bfbb19bd5502424747e83badc2d4a99a44e", size = 231133, upload-time = "2025-03-26T03:04:42.544Z" },
- { url = "https://files.pythonhosted.org/packages/98/a1/75f6355f9ad039108ff000dfc2e19962c8dea0430da9a1428e7975cf24b2/propcache-0.3.1-cp312-cp312-musllinux_1_2_i686.whl", hash = "sha256:e1c4d24b804b3a87e9350f79e2371a705a188d292fd310e663483af6ee6718ee", size = 230741, upload-time = "2025-03-26T03:04:44.06Z" },
- { url = "https://files.pythonhosted.org/packages/67/0c/3e82563af77d1f8731132166da69fdfd95e71210e31f18edce08a1eb11ea/propcache-0.3.1-cp312-cp312-musllinux_1_2_ppc64le.whl", hash = "sha256:e4fe2a6d5ce975c117a6bb1e8ccda772d1e7029c1cca1acd209f91d30fa72815", size = 244047, upload-time = "2025-03-26T03:04:45.983Z" },
- { url = "https://files.pythonhosted.org/packages/f7/50/9fb7cca01532a08c4d5186d7bb2da6c4c587825c0ae134b89b47c7d62628/propcache-0.3.1-cp312-cp312-musllinux_1_2_s390x.whl", hash = "sha256:feccd282de1f6322f56f6845bf1207a537227812f0a9bf5571df52bb418d79d5", size = 246467, upload-time = "2025-03-26T03:04:47.699Z" },
- { url = "https://files.pythonhosted.org/packages/a9/02/ccbcf3e1c604c16cc525309161d57412c23cf2351523aedbb280eb7c9094/propcache-0.3.1-cp312-cp312-musllinux_1_2_x86_64.whl", hash = "sha256:ec314cde7314d2dd0510c6787326bbffcbdc317ecee6b7401ce218b3099075a7", size = 241022, upload-time = "2025-03-26T03:04:49.195Z" },
- { url = "https://files.pythonhosted.org/packages/db/19/e777227545e09ca1e77a6e21274ae9ec45de0f589f0ce3eca2a41f366220/propcache-0.3.1-cp312-cp312-win32.whl", hash = "sha256:7d2d5a0028d920738372630870e7d9644ce437142197f8c827194fca404bf03b", size = 40647, upload-time = "2025-03-26T03:04:50.595Z" },
- { url = "https://files.pythonhosted.org/packages/24/bb/3b1b01da5dd04c77a204c84e538ff11f624e31431cfde7201d9110b092b1/propcache-0.3.1-cp312-cp312-win_amd64.whl", hash = "sha256:88c423efef9d7a59dae0614eaed718449c09a5ac79a5f224a8b9664d603f04a3", size = 44784, upload-time = "2025-03-26T03:04:51.791Z" },
- { url = "https://files.pythonhosted.org/packages/58/60/f645cc8b570f99be3cf46714170c2de4b4c9d6b827b912811eff1eb8a412/propcache-0.3.1-cp313-cp313-macosx_10_13_universal2.whl", hash = "sha256:f1528ec4374617a7a753f90f20e2f551121bb558fcb35926f99e3c42367164b8", size = 77865, upload-time = "2025-03-26T03:04:53.406Z" },
- { url = "https://files.pythonhosted.org/packages/6f/d4/c1adbf3901537582e65cf90fd9c26fde1298fde5a2c593f987112c0d0798/propcache-0.3.1-cp313-cp313-macosx_10_13_x86_64.whl", hash = "sha256:dc1915ec523b3b494933b5424980831b636fe483d7d543f7afb7b3bf00f0c10f", size = 45452, upload-time = "2025-03-26T03:04:54.624Z" },
- { url = "https://files.pythonhosted.org/packages/d1/b5/fe752b2e63f49f727c6c1c224175d21b7d1727ce1d4873ef1c24c9216830/propcache-0.3.1-cp313-cp313-macosx_11_0_arm64.whl", hash = "sha256:a110205022d077da24e60b3df8bcee73971be9575dec5573dd17ae5d81751111", size = 44800, upload-time = "2025-03-26T03:04:55.844Z" },
- { url = "https://files.pythonhosted.org/packages/62/37/fc357e345bc1971e21f76597028b059c3d795c5ca7690d7a8d9a03c9708a/propcache-0.3.1-cp313-cp313-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:d249609e547c04d190e820d0d4c8ca03ed4582bcf8e4e160a6969ddfb57b62e5", size = 225804, upload-time = "2025-03-26T03:04:57.158Z" },
- { url = "https://files.pythonhosted.org/packages/0d/f1/16e12c33e3dbe7f8b737809bad05719cff1dccb8df4dafbcff5575002c0e/propcache-0.3.1-cp313-cp313-manylinux_2_17_ppc64le.manylinux2014_ppc64le.whl", hash = "sha256:5ced33d827625d0a589e831126ccb4f5c29dfdf6766cac441d23995a65825dcb", size = 230650, upload-time = "2025-03-26T03:04:58.61Z" },
- { url = "https://files.pythonhosted.org/packages/3e/a2/018b9f2ed876bf5091e60153f727e8f9073d97573f790ff7cdf6bc1d1fb8/propcache-0.3.1-cp313-cp313-manylinux_2_17_s390x.manylinux2014_s390x.whl", hash = "sha256:4114c4ada8f3181af20808bedb250da6bae56660e4b8dfd9cd95d4549c0962f7", size = 234235, upload-time = "2025-03-26T03:05:00.599Z" },
- { url = "https://files.pythonhosted.org/packages/45/5f/3faee66fc930dfb5da509e34c6ac7128870631c0e3582987fad161fcb4b1/propcache-0.3.1-cp313-cp313-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:975af16f406ce48f1333ec5e912fe11064605d5c5b3f6746969077cc3adeb120", size = 228249, upload-time = "2025-03-26T03:05:02.11Z" },
- { url = "https://files.pythonhosted.org/packages/62/1e/a0d5ebda5da7ff34d2f5259a3e171a94be83c41eb1e7cd21a2105a84a02e/propcache-0.3.1-cp313-cp313-manylinux_2_5_i686.manylinux1_i686.manylinux_2_17_i686.manylinux2014_i686.whl", hash = "sha256:a34aa3a1abc50740be6ac0ab9d594e274f59960d3ad253cd318af76b996dd654", size = 214964, upload-time = "2025-03-26T03:05:03.599Z" },
- { url = "https://files.pythonhosted.org/packages/db/a0/d72da3f61ceab126e9be1f3bc7844b4e98c6e61c985097474668e7e52152/propcache-0.3.1-cp313-cp313-musllinux_1_2_aarch64.whl", hash = "sha256:9cec3239c85ed15bfaded997773fdad9fb5662b0a7cbc854a43f291eb183179e", size = 222501, upload-time = "2025-03-26T03:05:05.107Z" },
- { url = "https://files.pythonhosted.org/packages/18/6d/a008e07ad7b905011253adbbd97e5b5375c33f0b961355ca0a30377504ac/propcache-0.3.1-cp313-cp313-musllinux_1_2_armv7l.whl", hash = "sha256:05543250deac8e61084234d5fc54f8ebd254e8f2b39a16b1dce48904f45b744b", size = 217917, upload-time = "2025-03-26T03:05:06.59Z" },
- { url = "https://files.pythonhosted.org/packages/98/37/02c9343ffe59e590e0e56dc5c97d0da2b8b19fa747ebacf158310f97a79a/propcache-0.3.1-cp313-cp313-musllinux_1_2_i686.whl", hash = "sha256:5cb5918253912e088edbf023788de539219718d3b10aef334476b62d2b53de53", size = 217089, upload-time = "2025-03-26T03:05:08.1Z" },
- { url = "https://files.pythonhosted.org/packages/53/1b/d3406629a2c8a5666d4674c50f757a77be119b113eedd47b0375afdf1b42/propcache-0.3.1-cp313-cp313-musllinux_1_2_ppc64le.whl", hash = "sha256:f3bbecd2f34d0e6d3c543fdb3b15d6b60dd69970c2b4c822379e5ec8f6f621d5", size = 228102, upload-time = "2025-03-26T03:05:09.982Z" },
- { url = "https://files.pythonhosted.org/packages/cd/a7/3664756cf50ce739e5f3abd48febc0be1a713b1f389a502ca819791a6b69/propcache-0.3.1-cp313-cp313-musllinux_1_2_s390x.whl", hash = "sha256:aca63103895c7d960a5b9b044a83f544b233c95e0dcff114389d64d762017af7", size = 230122, upload-time = "2025-03-26T03:05:11.408Z" },
- { url = "https://files.pythonhosted.org/packages/35/36/0bbabaacdcc26dac4f8139625e930f4311864251276033a52fd52ff2a274/propcache-0.3.1-cp313-cp313-musllinux_1_2_x86_64.whl", hash = "sha256:5a0a9898fdb99bf11786265468571e628ba60af80dc3f6eb89a3545540c6b0ef", size = 226818, upload-time = "2025-03-26T03:05:12.909Z" },
- { url = "https://files.pythonhosted.org/packages/cc/27/4e0ef21084b53bd35d4dae1634b6d0bad35e9c58ed4f032511acca9d4d26/propcache-0.3.1-cp313-cp313-win32.whl", hash = "sha256:3a02a28095b5e63128bcae98eb59025924f121f048a62393db682f049bf4ac24", size = 40112, upload-time = "2025-03-26T03:05:14.289Z" },
- { url = "https://files.pythonhosted.org/packages/a6/2c/a54614d61895ba6dd7ac8f107e2b2a0347259ab29cbf2ecc7b94fa38c4dc/propcache-0.3.1-cp313-cp313-win_amd64.whl", hash = "sha256:813fbb8b6aea2fc9659815e585e548fe706d6f663fa73dff59a1677d4595a037", size = 44034, upload-time = "2025-03-26T03:05:15.616Z" },
- { url = "https://files.pythonhosted.org/packages/5a/a8/0a4fd2f664fc6acc66438370905124ce62e84e2e860f2557015ee4a61c7e/propcache-0.3.1-cp313-cp313t-macosx_10_13_universal2.whl", hash = "sha256:a444192f20f5ce8a5e52761a031b90f5ea6288b1eef42ad4c7e64fef33540b8f", size = 82613, upload-time = "2025-03-26T03:05:16.913Z" },
- { url = "https://files.pythonhosted.org/packages/4d/e5/5ef30eb2cd81576256d7b6caaa0ce33cd1d2c2c92c8903cccb1af1a4ff2f/propcache-0.3.1-cp313-cp313t-macosx_10_13_x86_64.whl", hash = "sha256:0fbe94666e62ebe36cd652f5fc012abfbc2342de99b523f8267a678e4dfdee3c", size = 47763, upload-time = "2025-03-26T03:05:18.607Z" },
- { url = "https://files.pythonhosted.org/packages/87/9a/87091ceb048efeba4d28e903c0b15bcc84b7c0bf27dc0261e62335d9b7b8/propcache-0.3.1-cp313-cp313t-macosx_11_0_arm64.whl", hash = "sha256:f011f104db880f4e2166bcdcf7f58250f7a465bc6b068dc84c824a3d4a5c94dc", size = 47175, upload-time = "2025-03-26T03:05:19.85Z" },
- { url = "https://files.pythonhosted.org/packages/3e/2f/854e653c96ad1161f96194c6678a41bbb38c7947d17768e8811a77635a08/propcache-0.3.1-cp313-cp313t-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:3e584b6d388aeb0001d6d5c2bd86b26304adde6d9bb9bfa9c4889805021b96de", size = 292265, upload-time = "2025-03-26T03:05:21.654Z" },
- { url = "https://files.pythonhosted.org/packages/40/8d/090955e13ed06bc3496ba4a9fb26c62e209ac41973cb0d6222de20c6868f/propcache-0.3.1-cp313-cp313t-manylinux_2_17_ppc64le.manylinux2014_ppc64le.whl", hash = "sha256:8a17583515a04358b034e241f952f1715243482fc2c2945fd99a1b03a0bd77d6", size = 294412, upload-time = "2025-03-26T03:05:23.147Z" },
- { url = "https://files.pythonhosted.org/packages/39/e6/d51601342e53cc7582449e6a3c14a0479fab2f0750c1f4d22302e34219c6/propcache-0.3.1-cp313-cp313t-manylinux_2_17_s390x.manylinux2014_s390x.whl", hash = "sha256:5aed8d8308215089c0734a2af4f2e95eeb360660184ad3912686c181e500b2e7", size = 294290, upload-time = "2025-03-26T03:05:24.577Z" },
- { url = "https://files.pythonhosted.org/packages/3b/4d/be5f1a90abc1881884aa5878989a1acdafd379a91d9c7e5e12cef37ec0d7/propcache-0.3.1-cp313-cp313t-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:6d8e309ff9a0503ef70dc9a0ebd3e69cf7b3894c9ae2ae81fc10943c37762458", size = 282926, upload-time = "2025-03-26T03:05:26.459Z" },
- { url = "https://files.pythonhosted.org/packages/57/2b/8f61b998c7ea93a2b7eca79e53f3e903db1787fca9373af9e2cf8dc22f9d/propcache-0.3.1-cp313-cp313t-manylinux_2_5_i686.manylinux1_i686.manylinux_2_17_i686.manylinux2014_i686.whl", hash = "sha256:b655032b202028a582d27aeedc2e813299f82cb232f969f87a4fde491a233f11", size = 267808, upload-time = "2025-03-26T03:05:28.188Z" },
- { url = "https://files.pythonhosted.org/packages/11/1c/311326c3dfce59c58a6098388ba984b0e5fb0381ef2279ec458ef99bd547/propcache-0.3.1-cp313-cp313t-musllinux_1_2_aarch64.whl", hash = "sha256:9f64d91b751df77931336b5ff7bafbe8845c5770b06630e27acd5dbb71e1931c", size = 290916, upload-time = "2025-03-26T03:05:29.757Z" },
- { url = "https://files.pythonhosted.org/packages/4b/74/91939924b0385e54dc48eb2e4edd1e4903ffd053cf1916ebc5347ac227f7/propcache-0.3.1-cp313-cp313t-musllinux_1_2_armv7l.whl", hash = "sha256:19a06db789a4bd896ee91ebc50d059e23b3639c25d58eb35be3ca1cbe967c3bf", size = 262661, upload-time = "2025-03-26T03:05:31.472Z" },
- { url = "https://files.pythonhosted.org/packages/c2/d7/e6079af45136ad325c5337f5dd9ef97ab5dc349e0ff362fe5c5db95e2454/propcache-0.3.1-cp313-cp313t-musllinux_1_2_i686.whl", hash = "sha256:bef100c88d8692864651b5f98e871fb090bd65c8a41a1cb0ff2322db39c96c27", size = 264384, upload-time = "2025-03-26T03:05:32.984Z" },
- { url = "https://files.pythonhosted.org/packages/b7/d5/ba91702207ac61ae6f1c2da81c5d0d6bf6ce89e08a2b4d44e411c0bbe867/propcache-0.3.1-cp313-cp313t-musllinux_1_2_ppc64le.whl", hash = "sha256:87380fb1f3089d2a0b8b00f006ed12bd41bd858fabfa7330c954c70f50ed8757", size = 291420, upload-time = "2025-03-26T03:05:34.496Z" },
- { url = "https://files.pythonhosted.org/packages/58/70/2117780ed7edcd7ba6b8134cb7802aada90b894a9810ec56b7bb6018bee7/propcache-0.3.1-cp313-cp313t-musllinux_1_2_s390x.whl", hash = "sha256:e474fc718e73ba5ec5180358aa07f6aded0ff5f2abe700e3115c37d75c947e18", size = 290880, upload-time = "2025-03-26T03:05:36.256Z" },
- { url = "https://files.pythonhosted.org/packages/4a/1f/ecd9ce27710021ae623631c0146719280a929d895a095f6d85efb6a0be2e/propcache-0.3.1-cp313-cp313t-musllinux_1_2_x86_64.whl", hash = "sha256:17d1c688a443355234f3c031349da69444be052613483f3e4158eef751abcd8a", size = 287407, upload-time = "2025-03-26T03:05:37.799Z" },
- { url = "https://files.pythonhosted.org/packages/3e/66/2e90547d6b60180fb29e23dc87bd8c116517d4255240ec6d3f7dc23d1926/propcache-0.3.1-cp313-cp313t-win32.whl", hash = "sha256:359e81a949a7619802eb601d66d37072b79b79c2505e6d3fd8b945538411400d", size = 42573, upload-time = "2025-03-26T03:05:39.193Z" },
- { url = "https://files.pythonhosted.org/packages/cb/8f/50ad8599399d1861b4d2b6b45271f0ef6af1b09b0a2386a46dbaf19c9535/propcache-0.3.1-cp313-cp313t-win_amd64.whl", hash = "sha256:e7fb9a84c9abbf2b2683fa3e7b0d7da4d8ecf139a1c635732a8bda29c5214b0e", size = 46757, upload-time = "2025-03-26T03:05:40.811Z" },
- { url = "https://files.pythonhosted.org/packages/b8/d3/c3cb8f1d6ae3b37f83e1de806713a9b3642c5895f0215a62e1a4bd6e5e34/propcache-0.3.1-py3-none-any.whl", hash = "sha256:9a8ecf38de50a7f518c21568c80f985e776397b902f1ce0b01f799aba1608b40", size = 12376, upload-time = "2025-03-26T03:06:10.5Z" },
-]
-
-[[package]]
-name = "psutil"
-version = "7.0.0"
-source = { registry = "https://pypi.org/simple" }
-sdist = { url = "https://files.pythonhosted.org/packages/2a/80/336820c1ad9286a4ded7e845b2eccfcb27851ab8ac6abece774a6ff4d3de/psutil-7.0.0.tar.gz", hash = "sha256:7be9c3eba38beccb6495ea33afd982a44074b78f28c434a1f51cc07fd315c456", size = 497003, upload-time = "2025-02-13T21:54:07.946Z" }
-wheels = [
- { url = "https://files.pythonhosted.org/packages/ed/e6/2d26234410f8b8abdbf891c9da62bee396583f713fb9f3325a4760875d22/psutil-7.0.0-cp36-abi3-macosx_10_9_x86_64.whl", hash = "sha256:101d71dc322e3cffd7cea0650b09b3d08b8e7c4109dd6809fe452dfd00e58b25", size = 238051, upload-time = "2025-02-13T21:54:12.36Z" },
- { url = "https://files.pythonhosted.org/packages/04/8b/30f930733afe425e3cbfc0e1468a30a18942350c1a8816acfade80c005c4/psutil-7.0.0-cp36-abi3-macosx_11_0_arm64.whl", hash = "sha256:39db632f6bb862eeccf56660871433e111b6ea58f2caea825571951d4b6aa3da", size = 239535, upload-time = "2025-02-13T21:54:16.07Z" },
- { url = "https://files.pythonhosted.org/packages/2a/ed/d362e84620dd22876b55389248e522338ed1bf134a5edd3b8231d7207f6d/psutil-7.0.0-cp36-abi3-manylinux_2_12_i686.manylinux2010_i686.manylinux_2_17_i686.manylinux2014_i686.whl", hash = "sha256:1fcee592b4c6f146991ca55919ea3d1f8926497a713ed7faaf8225e174581e91", size = 275004, upload-time = "2025-02-13T21:54:18.662Z" },
- { url = "https://files.pythonhosted.org/packages/bf/b9/b0eb3f3cbcb734d930fdf839431606844a825b23eaf9a6ab371edac8162c/psutil-7.0.0-cp36-abi3-manylinux_2_12_x86_64.manylinux2010_x86_64.manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:4b1388a4f6875d7e2aff5c4ca1cc16c545ed41dd8bb596cefea80111db353a34", size = 277986, upload-time = "2025-02-13T21:54:21.811Z" },
- { url = "https://files.pythonhosted.org/packages/eb/a2/709e0fe2f093556c17fbafda93ac032257242cabcc7ff3369e2cb76a97aa/psutil-7.0.0-cp36-abi3-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:a5f098451abc2828f7dc6b58d44b532b22f2088f4999a937557b603ce72b1993", size = 279544, upload-time = "2025-02-13T21:54:24.68Z" },
- { url = "https://files.pythonhosted.org/packages/50/e6/eecf58810b9d12e6427369784efe814a1eec0f492084ce8eb8f4d89d6d61/psutil-7.0.0-cp37-abi3-win32.whl", hash = "sha256:ba3fcef7523064a6c9da440fc4d6bd07da93ac726b5733c29027d7dc95b39d99", size = 241053, upload-time = "2025-02-13T21:54:34.31Z" },
- { url = "https://files.pythonhosted.org/packages/50/1b/6921afe68c74868b4c9fa424dad3be35b095e16687989ebbb50ce4fceb7c/psutil-7.0.0-cp37-abi3-win_amd64.whl", hash = "sha256:4cf3d4eb1aa9b348dec30105c55cd9b7d4629285735a102beb4441e38db90553", size = 244885, upload-time = "2025-02-13T21:54:37.486Z" },
-]
-
-[[package]]
-name = "pycparser"
-version = "3.0"
-source = { registry = "https://pypi.org/simple" }
-sdist = { url = "https://files.pythonhosted.org/packages/1b/7d/92392ff7815c21062bea51aa7b87d45576f649f16458d78b7cf94b9ab2e6/pycparser-3.0.tar.gz", hash = "sha256:600f49d217304a5902ac3c37e1281c9fe94e4d0489de643a9504c5cdfdfc6b29", size = 103492, upload-time = "2026-01-21T14:26:51.89Z" }
-wheels = [
- { url = "https://files.pythonhosted.org/packages/0c/c3/44f3fbbfa403ea2a7c779186dc20772604442dde72947e7d01069cbe98e3/pycparser-3.0-py3-none-any.whl", hash = "sha256:b727414169a36b7d524c1c3e31839a521725078d7b2ff038656844266160a992", size = 48172, upload-time = "2026-01-21T14:26:50.693Z" },
-]
-
[[package]]
name = "pydantic"
version = "2.13.4"
@@ -1469,43 +422,6 @@ wheels = [
{ url = "https://files.pythonhosted.org/packages/4b/2d/69abac8f838090bbecd5df894befb2c2619e7996a98ddb949db9f3b93225/pydantic_core-2.46.4-pp311-pypy311_pp73-win_amd64.whl", hash = "sha256:d51026d73fcfd93610abc7b27789c26b313920fcfb20e27462d74a7f8b06e983", size = 2193071, upload-time = "2026-05-06T13:38:08.682Z" },
]
-[[package]]
-name = "pydantic-settings"
-version = "2.14.1"
-source = { registry = "https://pypi.org/simple" }
-dependencies = [
- { name = "pydantic" },
- { name = "python-dotenv" },
- { name = "typing-inspection" },
-]
-sdist = { url = "https://files.pythonhosted.org/packages/07/60/1d1e59c9c90d54591469ada7d268251f71c24bdb765f1a8a832cee8c6653/pydantic_settings-2.14.1.tar.gz", hash = "sha256:e874d3bec7e787b0c9958277956ed9b4dd5de6a80e162188fdaff7c5e26fd5fa", size = 235551, upload-time = "2026-05-08T13:40:06.542Z" }
-wheels = [
- { url = "https://files.pythonhosted.org/packages/ae/8d/f1af3832f5e6eb13ba94ee809e72b8ecb5eef226d27ee0bef7d963d943c7/pydantic_settings-2.14.1-py3-none-any.whl", hash = "sha256:6e3c7edfd8277687cdc598f56e5cff0e9bfff0910a3749deaa8d4401c3a2b9de", size = 60964, upload-time = "2026-05-08T13:40:04.958Z" },
-]
-
-[[package]]
-name = "pyecharts"
-version = "2.0.8"
-source = { registry = "https://pypi.org/simple" }
-dependencies = [
- { name = "jinja2" },
- { name = "prettytable" },
- { name = "simplejson" },
-]
-sdist = { url = "https://files.pythonhosted.org/packages/98/68/c86a3960ab5d97709237e91a5136ae02079c3c39c83192ca16f1a25f8b1a/pyecharts-2.0.8.tar.gz", hash = "sha256:908dbd939862dd3c76bb53697bdb41d3cdd0b5ba48ca69a76a6085d0aa27dbdf", size = 165148, upload-time = "2025-01-24T03:10:07.179Z" }
-wheels = [
- { url = "https://files.pythonhosted.org/packages/ae/18/383622b338e4f6948ba1b75a8155d748ce097ead08a4163ca763f0ad510e/pyecharts-2.0.8-py3-none-any.whl", hash = "sha256:8b711ba139f39f89bc1b2a869d7adda89dc74c910d158a1f9063109fe66bc985", size = 153686, upload-time = "2025-01-24T03:10:03.737Z" },
-]
-
-[[package]]
-name = "pygments"
-version = "2.20.0"
-source = { registry = "https://pypi.org/simple" }
-sdist = { url = "https://files.pythonhosted.org/packages/c3/b2/bc9c9196916376152d655522fdcebac55e66de6603a76a02bca1b6414f6c/pygments-2.20.0.tar.gz", hash = "sha256:6757cd03768053ff99f3039c1a36d6c0aa0b263438fcab17520b30a303a82b5f", size = 4955991, upload-time = "2026-03-29T13:29:33.898Z" }
-wheels = [
- { url = "https://files.pythonhosted.org/packages/f4/7e/a72dd26f3b0f4f2bf1dd8923c85f7ceb43172af56d63c7383eb62b332364/pygments-2.20.0-py3-none-any.whl", hash = "sha256:81a9e26dd42fd28a23a2d169d86d7ac03b46e2f8b59ed4698fb4785f946d0176", size = 1231151, upload-time = "2026-03-29T13:29:30.038Z" },
-]
-
[[package]]
name = "pyinstaller"
version = "6.12.0"
@@ -1547,96 +463,6 @@ wheels = [
{ url = "https://files.pythonhosted.org/packages/5e/14/aaadab954b4d78b2de9368eabda3327f8cdd05bce12712263e1100266bca/pyinstaller_hooks_contrib-2025.2-py3-none-any.whl", hash = "sha256:0b2bc7697075de5eb071ff13ef4a156d3beae6c19c7cbdcd70f37978d2013e30", size = 351020, upload-time = "2025-03-23T23:35:09.03Z" },
]
-[[package]]
-name = "pyjwt"
-version = "2.13.0"
-source = { registry = "https://pypi.org/simple" }
-dependencies = [
- { name = "typing-extensions", marker = "python_full_version < '3.11'" },
-]
-sdist = { url = "https://files.pythonhosted.org/packages/3b/81/58d0ac84e1ef3a3843791d6954d94c0b33d526c75eeb1efbce9d0a4c4077/pyjwt-2.13.0.tar.gz", hash = "sha256:41571c89ca91598c79e8ef18a2d07367d4810fbbd6f637794879baf1b7703423", size = 107515, upload-time = "2026-05-21T19:54:36.618Z" }
-wheels = [
- { url = "https://files.pythonhosted.org/packages/a3/5e/ecf12fdb62546d64385c158514e9b2b671f7832108ef2ecd2020ce0af2d1/pyjwt-2.13.0-py3-none-any.whl", hash = "sha256:66adcc2aff09b3f1bbd95fc1e1577df8ac8723c978552fd43304c8a290ac5728", size = 31274, upload-time = "2026-05-21T19:54:35.362Z" },
-]
-
-[package.optional-dependencies]
-crypto = [
- { name = "cryptography" },
-]
-
-[[package]]
-name = "pymysql"
-version = "1.1.1"
-source = { registry = "https://pypi.org/simple" }
-sdist = { url = "https://files.pythonhosted.org/packages/b3/8f/ce59b5e5ed4ce8512f879ff1fa5ab699d211ae2495f1adaa5fbba2a1eada/pymysql-1.1.1.tar.gz", hash = "sha256:e127611aaf2b417403c60bf4dc570124aeb4a57f5f37b8e95ae399a42f904cd0", size = 47678, upload-time = "2024-05-21T11:03:43.722Z" }
-wheels = [
- { url = "https://files.pythonhosted.org/packages/0c/94/e4181a1f6286f545507528c78016e00065ea913276888db2262507693ce5/PyMySQL-1.1.1-py3-none-any.whl", hash = "sha256:4de15da4c61dc132f4fb9ab763063e693d521a80fd0e87943b9a453dd4c19d6c", size = 44972, upload-time = "2024-05-21T11:03:41.216Z" },
-]
-
-[[package]]
-name = "python-dateutil"
-version = "2.9.0.post0"
-source = { registry = "https://pypi.org/simple" }
-dependencies = [
- { name = "six" },
-]
-sdist = { url = "https://files.pythonhosted.org/packages/66/c0/0c8b6ad9f17a802ee498c46e004a0eb49bc148f2fd230864601a86dcf6db/python-dateutil-2.9.0.post0.tar.gz", hash = "sha256:37dd54208da7e1cd875388217d5e00ebd4179249f90fb72437e91a35459a0ad3", size = 342432, upload-time = "2024-03-01T18:36:20.211Z" }
-wheels = [
- { url = "https://files.pythonhosted.org/packages/ec/57/56b9bcc3c9c6a792fcbaf139543cee77261f3651ca9da0c93f5c1221264b/python_dateutil-2.9.0.post0-py2.py3-none-any.whl", hash = "sha256:a8b2bc7bffae282281c8140a97d3aa9c14da0b136dfe83f850eea9a5f7470427", size = 229892, upload-time = "2024-03-01T18:36:18.57Z" },
-]
-
-[[package]]
-name = "python-dotenv"
-version = "1.2.2"
-source = { registry = "https://pypi.org/simple" }
-sdist = { url = "https://files.pythonhosted.org/packages/82/ed/0301aeeac3e5353ef3d94b6ec08bbcabd04a72018415dcb29e588514bba8/python_dotenv-1.2.2.tar.gz", hash = "sha256:2c371a91fbd7ba082c2c1dc1f8bf89ca22564a087c2c287cd9b662adde799cf3", size = 50135, upload-time = "2026-03-01T16:00:26.196Z" }
-wheels = [
- { url = "https://files.pythonhosted.org/packages/0b/d7/1959b9648791274998a9c3526f6d0ec8fd2233e4d4acce81bbae76b44b2a/python_dotenv-1.2.2-py3-none-any.whl", hash = "sha256:1d8214789a24de455a8b8bd8ae6fe3c6b69a5e3d64aa8a8e5d68e694bbcb285a", size = 22101, upload-time = "2026-03-01T16:00:25.09Z" },
-]
-
-[[package]]
-name = "python-multipart"
-version = "0.0.32"
-source = { registry = "https://pypi.org/simple" }
-sdist = { url = "https://files.pythonhosted.org/packages/5b/42/55c32bb9b12693c092ad250a0e82edb5b31ddeda6eb772de5f308b3804ad/python_multipart-0.0.32.tar.gz", hash = "sha256:be54b7f3fa167bb83e4fcd936b887b708f4e57fe75911c02aebf53efaf8d938e", size = 46881, upload-time = "2026-06-04T16:18:58.647Z" }
-wheels = [
- { url = "https://files.pythonhosted.org/packages/e1/04/e8135ebd1ad02c56ec633277529b2602ff99ff634be76cdba5744cf554fd/python_multipart-0.0.32-py3-none-any.whl", hash = "sha256:ff6d3f776f16878c894e52e107296ffc890e913c611b1a4ec6c44e2821fe2e23", size = 30042, upload-time = "2026-06-04T16:18:57.319Z" },
-]
-
-[[package]]
-name = "pytz"
-version = "2025.2"
-source = { registry = "https://pypi.org/simple" }
-sdist = { url = "https://files.pythonhosted.org/packages/f8/bf/abbd3cdfb8fbc7fb3d4d38d320f2441b1e7cbe29be4f23797b4a2b5d8aac/pytz-2025.2.tar.gz", hash = "sha256:360b9e3dbb49a209c21ad61809c7fb453643e048b38924c765813546746e81c3", size = 320884, upload-time = "2025-03-25T02:25:00.538Z" }
-wheels = [
- { url = "https://files.pythonhosted.org/packages/81/c4/34e93fe5f5429d7570ec1fa436f1986fb1f00c3e0f43a589fe2bbcd22c3f/pytz-2025.2-py2.py3-none-any.whl", hash = "sha256:5ddf76296dd8c44c26eb8f4b6f35488f3ccbf6fbbd7adee0b7262d43f0ec2f00", size = 509225, upload-time = "2025-03-25T02:24:58.468Z" },
-]
-
-[[package]]
-name = "pywin32"
-version = "312"
-source = { registry = "https://pypi.org/simple" }
-wheels = [
- { url = "https://files.pythonhosted.org/packages/fe/1b/9cfdeac80ee45bebbbcb31f1b7b99a0d81a1c72de48d837be984e0e88b1d/pywin32-312-cp310-cp310-win32.whl", hash = "sha256:772235332b5d1024c696f11cea1ae4be7930f0a8b894bb43db14e3f435f1ff7e", size = 6361387, upload-time = "2026-06-04T07:49:14.329Z" },
- { url = "https://files.pythonhosted.org/packages/33/b1/7afc96d041d982c27bc2df6f853d43f01fd273e3d39d04be3647ddeb533d/pywin32-312-cp310-cp310-win_amd64.whl", hash = "sha256:5dbc35d2b5320dc07f25fa31269cfb767471002b17de5eb067d03da68c7cb2db", size = 6926780, upload-time = "2026-06-04T07:49:16.881Z" },
- { url = "https://files.pythonhosted.org/packages/ce/3a/4140da9ad54108e517f4a16b2d83da3033e08662144623e1239587cb7db6/pywin32-312-cp310-cp310-win_arm64.whl", hash = "sha256:3020656e34f1cf7faeb7bccd2b84653a607c6ff0c55ada85e6487d61716deabd", size = 4307203, upload-time = "2026-06-04T07:49:18.993Z" },
- { url = "https://files.pythonhosted.org/packages/1f/f5/10a6e845a00fc5e7afd0a988b744f403d4d57162a28d160a093c4d9322f0/pywin32-312-cp311-cp311-win32.whl", hash = "sha256:17948aeadbdb091f0ced6ef0841620794e68327b94ee415571c1203594b7215c", size = 6362659, upload-time = "2026-06-04T07:49:21.349Z" },
- { url = "https://files.pythonhosted.org/packages/35/c4/dcd2d62b5944b6d5db53413a5899016ccd57ffcb7278f3f81655d25d2027/pywin32-312-cp311-cp311-win_amd64.whl", hash = "sha256:d11417d84412f859b722fad0841b3614459ed0047f7542d8362e77884f6b6e8a", size = 6928825, upload-time = "2026-06-04T07:49:23.934Z" },
- { url = "https://files.pythonhosted.org/packages/b7/56/3cbb433fe4501cdba2eb9040f56a4e1a8243faa4186b25295564d1a7a79d/pywin32-312-cp311-cp311-win_arm64.whl", hash = "sha256:b2200a054ca6d6625c4842fc56a4976a4b47f96b73dbe5538c3f813a80359f47", size = 6721875, upload-time = "2026-06-04T07:49:26.416Z" },
- { url = "https://files.pythonhosted.org/packages/83/ff/32aa7d2ed0ab12b323aaa64f9b75e6ad4f8fd09f9ccfc28c79414d46838d/pywin32-312-cp312-cp312-win32.whl", hash = "sha256:dab4f65ac9c4e48400a2a0530c46c3c579cd5905ecd11b80692373915269208b", size = 6371877, upload-time = "2026-06-04T07:49:28.836Z" },
- { url = "https://files.pythonhosted.org/packages/03/d9/77040d3b43df3f3be32ea289433d660d2727f5ba327bc73be835127d9d60/pywin32-312-cp312-cp312-win_amd64.whl", hash = "sha256:b457f6d628a47e8a7346ce22acb7e1a46a4a78b52e1d17e1af56871bd19a93bc", size = 6914841, upload-time = "2026-06-04T07:49:31.85Z" },
- { url = "https://files.pythonhosted.org/packages/e3/cc/7b1ec671775756020a0ee7f4feeaf3c568f0ab86bd3900088cf986937a92/pywin32-312-cp312-cp312-win_arm64.whl", hash = "sha256:6017c58e12f6809fbb0555b75df144c2922a9ffd18e4b9b5afa863b6c1a9d950", size = 6727901, upload-time = "2026-06-04T07:49:34.244Z" },
- { url = "https://files.pythonhosted.org/packages/2d/41/12fbfd7f36ed2146d8bc9de96c2741296bf0d490b98508496cff322e274c/pywin32-312-cp313-cp313-win32.whl", hash = "sha256:7a27df850933d16a8eabfbaeb73d52b273e2da667f80d70b01a89d1f6828d02c", size = 6370184, upload-time = "2026-06-04T07:49:36.253Z" },
- { url = "https://files.pythonhosted.org/packages/ba/db/36a78e3403099d31d9746d13fdcde5accc43c1155f375a34d15983a479a7/pywin32-312-cp313-cp313-win_amd64.whl", hash = "sha256:c53e878d15a1c44788082bfe712a905433473aa38f86375b7cf8b45e3acbaaf9", size = 6914298, upload-time = "2026-06-04T07:49:38.876Z" },
- { url = "https://files.pythonhosted.org/packages/84/37/c1697194092b76de9ed47ca124323f02c57ffc8a45c06f88a3d5acaf01eb/pywin32-312-cp313-cp313-win_arm64.whl", hash = "sha256:59aba5d5940842075343a5ddc6b11f1cdf0d1567fe745290359dfbcc7c2eb831", size = 6727640, upload-time = "2026-06-04T07:49:41.083Z" },
- { url = "https://files.pythonhosted.org/packages/fc/2b/1f3cded5822fd49c02f40544cbb5f58c7cfd6b1694869fd476cb6170ee97/pywin32-312-cp314-cp314-win32.whl", hash = "sha256:a77a90fbb6881238d2ca9c6fd797b25817f3768fe78d214a90137ff055a75f5b", size = 6468928, upload-time = "2026-06-04T07:49:43.188Z" },
- { url = "https://files.pythonhosted.org/packages/21/82/3bf86d2e2808902013132e1ce905a7da0da53790f3836c64bf44d55e24f3/pywin32-312-cp314-cp314-win_amd64.whl", hash = "sha256:a4dd3a848290ef724347b19f301045831d8e802fa4464f491b98b1e0a081432e", size = 7024157, upload-time = "2026-06-04T07:49:45.34Z" },
- { url = "https://files.pythonhosted.org/packages/a4/0e/73f6d6800b4f27655abd9e9f6aaeaefcddb2b946e4674efa2bab184a7f7b/pywin32-312-cp314-cp314-win_arm64.whl", hash = "sha256:9fce94568364e0155e6dfb781ac5d95903be8baf28670632beab1b523f300daa", size = 6839598, upload-time = "2026-06-04T07:49:47.613Z" },
- { url = "https://files.pythonhosted.org/packages/eb/61/caa39686032d2ebdd04ff0ab5cbe163126c0066d98e00c9018646e42393b/pywin32-312-cp315-cp315-win32.whl", hash = "sha256:5c1fbe4a937a73ae9297384a3da38518cbc694c68ad8a809b2e19acd350f03ed", size = 6471159, upload-time = "2026-06-04T07:49:50.035Z" },
- { url = "https://files.pythonhosted.org/packages/0f/cd/7e1de64a4a6f69c04214169657ccab0d93a670ea50e35eb8f489d7378249/pywin32-312-cp315-cp315-win_amd64.whl", hash = "sha256:c2f03a0f73f804a13c2735b99392b0cd426bb4f2c4d0178e5ac966a0f21618d5", size = 7025293, upload-time = "2026-06-04T07:49:54.857Z" },
- { url = "https://files.pythonhosted.org/packages/23/ed/4532e9388e65fa16b46776ef47ad631a64eda1631884488af707666350ed/pywin32-312-cp315-cp315-win_arm64.whl", hash = "sha256:a8597d28f267b39074aef51fa593530082b39cbe5a074226096857b1fed2dfb9", size = 6840337, upload-time = "2026-06-04T07:49:57.531Z" },
-]
-
[[package]]
name = "pywin32-ctypes"
version = "0.2.3"
@@ -1702,21 +528,6 @@ wheels = [
{ url = "https://files.pythonhosted.org/packages/29/e6/273de1f5cda537b00bc2947082be747f1d76358db8b945f3a60837bcd0f6/qrcode-8.1-py3-none-any.whl", hash = "sha256:9beba317d793ab8b3838c52af72e603b8ad2599c4e9bbd5c3da37c7dcc13c5cf", size = 45711, upload-time = "2025-04-02T14:27:04.786Z" },
]
-[[package]]
-name = "referencing"
-version = "0.37.0"
-source = { registry = "https://pypi.org/simple" }
-dependencies = [
- { name = "attrs" },
- { name = "rpds-py", version = "0.30.0", source = { registry = "https://pypi.org/simple" }, marker = "python_full_version < '3.11'" },
- { name = "rpds-py", version = "2026.5.1", source = { registry = "https://pypi.org/simple" }, marker = "python_full_version >= '3.11'" },
- { name = "typing-extensions", marker = "python_full_version < '3.13'" },
-]
-sdist = { url = "https://files.pythonhosted.org/packages/22/f5/df4e9027acead3ecc63e50fe1e36aca1523e1719559c499951bb4b53188f/referencing-0.37.0.tar.gz", hash = "sha256:44aefc3142c5b842538163acb373e24cce6632bd54bdb01b21ad5863489f50d8", size = 78036, upload-time = "2025-10-13T15:30:48.871Z" }
-wheels = [
- { url = "https://files.pythonhosted.org/packages/2c/58/ca301544e1fa93ed4f80d724bf5b194f6e4b945841c5bfd555878eea9fcb/referencing-0.37.0-py3-none-any.whl", hash = "sha256:381329a9f99628c9069361716891d34ad94af76e461dcb0335825aecc7692231", size = 26766, upload-time = "2025-10-13T15:30:47.625Z" },
-]
-
[[package]]
name = "requests"
version = "2.32.3"
@@ -1732,397 +543,6 @@ wheels = [
{ url = "https://files.pythonhosted.org/packages/f9/9b/335f9764261e915ed497fcdeb11df5dfd6f7bf257d4a6a2a686d80da4d54/requests-2.32.3-py3-none-any.whl", hash = "sha256:70761cfe03c773ceb22aa2f671b4757976145175cdfca038c02654d061d6dcc6", size = 64928, upload-time = "2024-05-29T15:37:47.027Z" },
]
-[[package]]
-name = "requests-oauthlib"
-version = "2.0.0"
-source = { registry = "https://pypi.org/simple" }
-dependencies = [
- { name = "oauthlib" },
- { name = "requests" },
-]
-sdist = { url = "https://files.pythonhosted.org/packages/42/f2/05f29bc3913aea15eb670be136045bf5c5bbf4b99ecb839da9b422bb2c85/requests-oauthlib-2.0.0.tar.gz", hash = "sha256:b3dffaebd884d8cd778494369603a9e7b58d29111bf6b41bdc2dcd87203af4e9", size = 55650, upload-time = "2024-03-22T20:32:29.939Z" }
-wheels = [
- { url = "https://files.pythonhosted.org/packages/3b/5d/63d4ae3b9daea098d5d6f5da83984853c1bbacd5dc826764b249fe119d24/requests_oauthlib-2.0.0-py2.py3-none-any.whl", hash = "sha256:7dd8a5c40426b779b0868c404bdef9768deccf22749cde15852df527e6269b36", size = 24179, upload-time = "2024-03-22T20:32:28.055Z" },
-]
-
-[[package]]
-name = "rich"
-version = "15.0.0"
-source = { registry = "https://pypi.org/simple" }
-dependencies = [
- { name = "markdown-it-py" },
- { name = "pygments" },
-]
-sdist = { url = "https://files.pythonhosted.org/packages/c0/8f/0722ca900cc807c13a6a0c696dacf35430f72e0ec571c4275d2371fca3e9/rich-15.0.0.tar.gz", hash = "sha256:edd07a4824c6b40189fb7ac9bc4c52536e9780fbbfbddf6f1e2502c31b068c36", size = 230680, upload-time = "2026-04-12T08:24:00.75Z" }
-wheels = [
- { url = "https://files.pythonhosted.org/packages/82/3b/64d4899d73f91ba49a8c18a8ff3f0ea8f1c1d75481760df8c68ef5235bf5/rich-15.0.0-py3-none-any.whl", hash = "sha256:33bd4ef74232fb73fe9279a257718407f169c09b78a87ad3d296f548e27de0bb", size = 310654, upload-time = "2026-04-12T08:24:02.83Z" },
-]
-
-[[package]]
-name = "rpds-py"
-version = "0.30.0"
-source = { registry = "https://pypi.org/simple" }
-resolution-markers = [
- "python_full_version < '3.11'",
-]
-sdist = { url = "https://files.pythonhosted.org/packages/20/af/3f2f423103f1113b36230496629986e0ef7e199d2aa8392452b484b38ced/rpds_py-0.30.0.tar.gz", hash = "sha256:dd8ff7cf90014af0c0f787eea34794ebf6415242ee1d6fa91eaba725cc441e84", size = 69469, upload-time = "2025-11-30T20:24:38.837Z" }
-wheels = [
- { url = "https://files.pythonhosted.org/packages/06/0c/0c411a0ec64ccb6d104dcabe0e713e05e153a9a2c3c2bd2b32ce412166fe/rpds_py-0.30.0-cp310-cp310-macosx_10_12_x86_64.whl", hash = "sha256:679ae98e00c0e8d68a7fda324e16b90fd5260945b45d3b824c892cec9eea3288", size = 370490, upload-time = "2025-11-30T20:21:33.256Z" },
- { url = "https://files.pythonhosted.org/packages/19/6a/4ba3d0fb7297ebae71171822554abe48d7cab29c28b8f9f2c04b79988c05/rpds_py-0.30.0-cp310-cp310-macosx_11_0_arm64.whl", hash = "sha256:4cc2206b76b4f576934f0ed374b10d7ca5f457858b157ca52064bdfc26b9fc00", size = 359751, upload-time = "2025-11-30T20:21:34.591Z" },
- { url = "https://files.pythonhosted.org/packages/cd/7c/e4933565ef7f7a0818985d87c15d9d273f1a649afa6a52ea35ad011195ea/rpds_py-0.30.0-cp310-cp310-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:389a2d49eded1896c3d48b0136ead37c48e221b391c052fba3f4055c367f60a6", size = 389696, upload-time = "2025-11-30T20:21:36.122Z" },
- { url = "https://files.pythonhosted.org/packages/5e/01/6271a2511ad0815f00f7ed4390cf2567bec1d4b1da39e2c27a41e6e3b4de/rpds_py-0.30.0-cp310-cp310-manylinux_2_17_armv7l.manylinux2014_armv7l.whl", hash = "sha256:32c8528634e1bf7121f3de08fa85b138f4e0dc47657866630611b03967f041d7", size = 403136, upload-time = "2025-11-30T20:21:37.728Z" },
- { url = "https://files.pythonhosted.org/packages/55/64/c857eb7cd7541e9b4eee9d49c196e833128a55b89a9850a9c9ac33ccf897/rpds_py-0.30.0-cp310-cp310-manylinux_2_17_ppc64le.manylinux2014_ppc64le.whl", hash = "sha256:f207f69853edd6f6700b86efb84999651baf3789e78a466431df1331608e5324", size = 524699, upload-time = "2025-11-30T20:21:38.92Z" },
- { url = "https://files.pythonhosted.org/packages/9c/ed/94816543404078af9ab26159c44f9e98e20fe47e2126d5d32c9d9948d10a/rpds_py-0.30.0-cp310-cp310-manylinux_2_17_s390x.manylinux2014_s390x.whl", hash = "sha256:67b02ec25ba7a9e8fa74c63b6ca44cf5707f2fbfadae3ee8e7494297d56aa9df", size = 412022, upload-time = "2025-11-30T20:21:40.407Z" },
- { url = "https://files.pythonhosted.org/packages/61/b5/707f6cf0066a6412aacc11d17920ea2e19e5b2f04081c64526eb35b5c6e7/rpds_py-0.30.0-cp310-cp310-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:0c0e95f6819a19965ff420f65578bacb0b00f251fefe2c8b23347c37174271f3", size = 390522, upload-time = "2025-11-30T20:21:42.17Z" },
- { url = "https://files.pythonhosted.org/packages/13/4e/57a85fda37a229ff4226f8cbcf09f2a455d1ed20e802ce5b2b4a7f5ed053/rpds_py-0.30.0-cp310-cp310-manylinux_2_31_riscv64.whl", hash = "sha256:a452763cc5198f2f98898eb98f7569649fe5da666c2dc6b5ddb10fde5a574221", size = 404579, upload-time = "2025-11-30T20:21:43.769Z" },
- { url = "https://files.pythonhosted.org/packages/f9/da/c9339293513ec680a721e0e16bf2bac3db6e5d7e922488de471308349bba/rpds_py-0.30.0-cp310-cp310-manylinux_2_5_i686.manylinux1_i686.whl", hash = "sha256:e0b65193a413ccc930671c55153a03ee57cecb49e6227204b04fae512eb657a7", size = 421305, upload-time = "2025-11-30T20:21:44.994Z" },
- { url = "https://files.pythonhosted.org/packages/f9/be/522cb84751114f4ad9d822ff5a1aa3c98006341895d5f084779b99596e5c/rpds_py-0.30.0-cp310-cp310-musllinux_1_2_aarch64.whl", hash = "sha256:858738e9c32147f78b3ac24dc0edb6610000e56dc0f700fd5f651d0a0f0eb9ff", size = 572503, upload-time = "2025-11-30T20:21:46.91Z" },
- { url = "https://files.pythonhosted.org/packages/a2/9b/de879f7e7ceddc973ea6e4629e9b380213a6938a249e94b0cdbcc325bb66/rpds_py-0.30.0-cp310-cp310-musllinux_1_2_i686.whl", hash = "sha256:da279aa314f00acbb803da1e76fa18666778e8a8f83484fba94526da5de2cba7", size = 598322, upload-time = "2025-11-30T20:21:48.709Z" },
- { url = "https://files.pythonhosted.org/packages/48/ac/f01fc22efec3f37d8a914fc1b2fb9bcafd56a299edbe96406f3053edea5a/rpds_py-0.30.0-cp310-cp310-musllinux_1_2_x86_64.whl", hash = "sha256:7c64d38fb49b6cdeda16ab49e35fe0da2e1e9b34bc38bd78386530f218b37139", size = 560792, upload-time = "2025-11-30T20:21:50.024Z" },
- { url = "https://files.pythonhosted.org/packages/e2/da/4e2b19d0f131f35b6146425f846563d0ce036763e38913d917187307a671/rpds_py-0.30.0-cp310-cp310-win32.whl", hash = "sha256:6de2a32a1665b93233cde140ff8b3467bdb9e2af2b91079f0333a0974d12d464", size = 221901, upload-time = "2025-11-30T20:21:51.32Z" },
- { url = "https://files.pythonhosted.org/packages/96/cb/156d7a5cf4f78a7cc571465d8aec7a3c447c94f6749c5123f08438bcf7bc/rpds_py-0.30.0-cp310-cp310-win_amd64.whl", hash = "sha256:1726859cd0de969f88dc8673bdd954185b9104e05806be64bcd87badbe313169", size = 235823, upload-time = "2025-11-30T20:21:52.505Z" },
- { url = "https://files.pythonhosted.org/packages/4d/6e/f964e88b3d2abee2a82c1ac8366da848fce1c6d834dc2132c3fda3970290/rpds_py-0.30.0-cp311-cp311-macosx_10_12_x86_64.whl", hash = "sha256:a2bffea6a4ca9f01b3f8e548302470306689684e61602aa3d141e34da06cf425", size = 370157, upload-time = "2025-11-30T20:21:53.789Z" },
- { url = "https://files.pythonhosted.org/packages/94/ba/24e5ebb7c1c82e74c4e4f33b2112a5573ddc703915b13a073737b59b86e0/rpds_py-0.30.0-cp311-cp311-macosx_11_0_arm64.whl", hash = "sha256:dc4f992dfe1e2bc3ebc7444f6c7051b4bc13cd8e33e43511e8ffd13bf407010d", size = 359676, upload-time = "2025-11-30T20:21:55.475Z" },
- { url = "https://files.pythonhosted.org/packages/84/86/04dbba1b087227747d64d80c3b74df946b986c57af0a9f0c98726d4d7a3b/rpds_py-0.30.0-cp311-cp311-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:422c3cb9856d80b09d30d2eb255d0754b23e090034e1deb4083f8004bd0761e4", size = 389938, upload-time = "2025-11-30T20:21:57.079Z" },
- { url = "https://files.pythonhosted.org/packages/42/bb/1463f0b1722b7f45431bdd468301991d1328b16cffe0b1c2918eba2c4eee/rpds_py-0.30.0-cp311-cp311-manylinux_2_17_armv7l.manylinux2014_armv7l.whl", hash = "sha256:07ae8a593e1c3c6b82ca3292efbe73c30b61332fd612e05abee07c79359f292f", size = 402932, upload-time = "2025-11-30T20:21:58.47Z" },
- { url = "https://files.pythonhosted.org/packages/99/ee/2520700a5c1f2d76631f948b0736cdf9b0acb25abd0ca8e889b5c62ac2e3/rpds_py-0.30.0-cp311-cp311-manylinux_2_17_ppc64le.manylinux2014_ppc64le.whl", hash = "sha256:12f90dd7557b6bd57f40abe7747e81e0c0b119bef015ea7726e69fe550e394a4", size = 525830, upload-time = "2025-11-30T20:21:59.699Z" },
- { url = "https://files.pythonhosted.org/packages/e0/ad/bd0331f740f5705cc555a5e17fdf334671262160270962e69a2bdef3bf76/rpds_py-0.30.0-cp311-cp311-manylinux_2_17_s390x.manylinux2014_s390x.whl", hash = "sha256:99b47d6ad9a6da00bec6aabe5a6279ecd3c06a329d4aa4771034a21e335c3a97", size = 412033, upload-time = "2025-11-30T20:22:00.991Z" },
- { url = "https://files.pythonhosted.org/packages/f8/1e/372195d326549bb51f0ba0f2ecb9874579906b97e08880e7a65c3bef1a99/rpds_py-0.30.0-cp311-cp311-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:33f559f3104504506a44bb666b93a33f5d33133765b0c216a5bf2f1e1503af89", size = 390828, upload-time = "2025-11-30T20:22:02.723Z" },
- { url = "https://files.pythonhosted.org/packages/ab/2b/d88bb33294e3e0c76bc8f351a3721212713629ffca1700fa94979cb3eae8/rpds_py-0.30.0-cp311-cp311-manylinux_2_31_riscv64.whl", hash = "sha256:946fe926af6e44f3697abbc305ea168c2c31d3e3ef1058cf68f379bf0335a78d", size = 404683, upload-time = "2025-11-30T20:22:04.367Z" },
- { url = "https://files.pythonhosted.org/packages/50/32/c759a8d42bcb5289c1fac697cd92f6fe01a018dd937e62ae77e0e7f15702/rpds_py-0.30.0-cp311-cp311-manylinux_2_5_i686.manylinux1_i686.whl", hash = "sha256:495aeca4b93d465efde585977365187149e75383ad2684f81519f504f5c13038", size = 421583, upload-time = "2025-11-30T20:22:05.814Z" },
- { url = "https://files.pythonhosted.org/packages/2b/81/e729761dbd55ddf5d84ec4ff1f47857f4374b0f19bdabfcf929164da3e24/rpds_py-0.30.0-cp311-cp311-musllinux_1_2_aarch64.whl", hash = "sha256:d9a0ca5da0386dee0655b4ccdf46119df60e0f10da268d04fe7cc87886872ba7", size = 572496, upload-time = "2025-11-30T20:22:07.713Z" },
- { url = "https://files.pythonhosted.org/packages/14/f6/69066a924c3557c9c30baa6ec3a0aa07526305684c6f86c696b08860726c/rpds_py-0.30.0-cp311-cp311-musllinux_1_2_i686.whl", hash = "sha256:8d6d1cc13664ec13c1b84241204ff3b12f9bb82464b8ad6e7a5d3486975c2eed", size = 598669, upload-time = "2025-11-30T20:22:09.312Z" },
- { url = "https://files.pythonhosted.org/packages/5f/48/905896b1eb8a05630d20333d1d8ffd162394127b74ce0b0784ae04498d32/rpds_py-0.30.0-cp311-cp311-musllinux_1_2_x86_64.whl", hash = "sha256:3896fa1be39912cf0757753826bc8bdc8ca331a28a7c4ae46b7a21280b06bb85", size = 561011, upload-time = "2025-11-30T20:22:11.309Z" },
- { url = "https://files.pythonhosted.org/packages/22/16/cd3027c7e279d22e5eb431dd3c0fbc677bed58797fe7581e148f3f68818b/rpds_py-0.30.0-cp311-cp311-win32.whl", hash = "sha256:55f66022632205940f1827effeff17c4fa7ae1953d2b74a8581baaefb7d16f8c", size = 221406, upload-time = "2025-11-30T20:22:13.101Z" },
- { url = "https://files.pythonhosted.org/packages/fa/5b/e7b7aa136f28462b344e652ee010d4de26ee9fd16f1bfd5811f5153ccf89/rpds_py-0.30.0-cp311-cp311-win_amd64.whl", hash = "sha256:a51033ff701fca756439d641c0ad09a41d9242fa69121c7d8769604a0a629825", size = 236024, upload-time = "2025-11-30T20:22:14.853Z" },
- { url = "https://files.pythonhosted.org/packages/14/a6/364bba985e4c13658edb156640608f2c9e1d3ea3c81b27aa9d889fff0e31/rpds_py-0.30.0-cp311-cp311-win_arm64.whl", hash = "sha256:47b0ef6231c58f506ef0b74d44e330405caa8428e770fec25329ed2cb971a229", size = 229069, upload-time = "2025-11-30T20:22:16.577Z" },
- { url = "https://files.pythonhosted.org/packages/03/e7/98a2f4ac921d82f33e03f3835f5bf3a4a40aa1bfdc57975e74a97b2b4bdd/rpds_py-0.30.0-cp312-cp312-macosx_10_12_x86_64.whl", hash = "sha256:a161f20d9a43006833cd7068375a94d035714d73a172b681d8881820600abfad", size = 375086, upload-time = "2025-11-30T20:22:17.93Z" },
- { url = "https://files.pythonhosted.org/packages/4d/a1/bca7fd3d452b272e13335db8d6b0b3ecde0f90ad6f16f3328c6fb150c889/rpds_py-0.30.0-cp312-cp312-macosx_11_0_arm64.whl", hash = "sha256:6abc8880d9d036ecaafe709079969f56e876fcf107f7a8e9920ba6d5a3878d05", size = 359053, upload-time = "2025-11-30T20:22:19.297Z" },
- { url = "https://files.pythonhosted.org/packages/65/1c/ae157e83a6357eceff62ba7e52113e3ec4834a84cfe07fa4b0757a7d105f/rpds_py-0.30.0-cp312-cp312-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:ca28829ae5f5d569bb62a79512c842a03a12576375d5ece7d2cadf8abe96ec28", size = 390763, upload-time = "2025-11-30T20:22:21.661Z" },
- { url = "https://files.pythonhosted.org/packages/d4/36/eb2eb8515e2ad24c0bd43c3ee9cd74c33f7ca6430755ccdb240fd3144c44/rpds_py-0.30.0-cp312-cp312-manylinux_2_17_armv7l.manylinux2014_armv7l.whl", hash = "sha256:a1010ed9524c73b94d15919ca4d41d8780980e1765babf85f9a2f90d247153dd", size = 408951, upload-time = "2025-11-30T20:22:23.408Z" },
- { url = "https://files.pythonhosted.org/packages/d6/65/ad8dc1784a331fabbd740ef6f71ce2198c7ed0890dab595adb9ea2d775a1/rpds_py-0.30.0-cp312-cp312-manylinux_2_17_ppc64le.manylinux2014_ppc64le.whl", hash = "sha256:f8d1736cfb49381ba528cd5baa46f82fdc65c06e843dab24dd70b63d09121b3f", size = 514622, upload-time = "2025-11-30T20:22:25.16Z" },
- { url = "https://files.pythonhosted.org/packages/63/8e/0cfa7ae158e15e143fe03993b5bcd743a59f541f5952e1546b1ac1b5fd45/rpds_py-0.30.0-cp312-cp312-manylinux_2_17_s390x.manylinux2014_s390x.whl", hash = "sha256:d948b135c4693daff7bc2dcfc4ec57237a29bd37e60c2fabf5aff2bbacf3e2f1", size = 414492, upload-time = "2025-11-30T20:22:26.505Z" },
- { url = "https://files.pythonhosted.org/packages/60/1b/6f8f29f3f995c7ffdde46a626ddccd7c63aefc0efae881dc13b6e5d5bb16/rpds_py-0.30.0-cp312-cp312-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:47f236970bccb2233267d89173d3ad2703cd36a0e2a6e92d0560d333871a3d23", size = 394080, upload-time = "2025-11-30T20:22:27.934Z" },
- { url = "https://files.pythonhosted.org/packages/6d/d5/a266341051a7a3ca2f4b750a3aa4abc986378431fc2da508c5034d081b70/rpds_py-0.30.0-cp312-cp312-manylinux_2_31_riscv64.whl", hash = "sha256:2e6ecb5a5bcacf59c3f912155044479af1d0b6681280048b338b28e364aca1f6", size = 408680, upload-time = "2025-11-30T20:22:29.341Z" },
- { url = "https://files.pythonhosted.org/packages/10/3b/71b725851df9ab7a7a4e33cf36d241933da66040d195a84781f49c50490c/rpds_py-0.30.0-cp312-cp312-manylinux_2_5_i686.manylinux1_i686.whl", hash = "sha256:a8fa71a2e078c527c3e9dc9fc5a98c9db40bcc8a92b4e8858e36d329f8684b51", size = 423589, upload-time = "2025-11-30T20:22:31.469Z" },
- { url = "https://files.pythonhosted.org/packages/00/2b/e59e58c544dc9bd8bd8384ecdb8ea91f6727f0e37a7131baeff8d6f51661/rpds_py-0.30.0-cp312-cp312-musllinux_1_2_aarch64.whl", hash = "sha256:73c67f2db7bc334e518d097c6d1e6fed021bbc9b7d678d6cc433478365d1d5f5", size = 573289, upload-time = "2025-11-30T20:22:32.997Z" },
- { url = "https://files.pythonhosted.org/packages/da/3e/a18e6f5b460893172a7d6a680e86d3b6bc87a54c1f0b03446a3c8c7b588f/rpds_py-0.30.0-cp312-cp312-musllinux_1_2_i686.whl", hash = "sha256:5ba103fb455be00f3b1c2076c9d4264bfcb037c976167a6047ed82f23153f02e", size = 599737, upload-time = "2025-11-30T20:22:34.419Z" },
- { url = "https://files.pythonhosted.org/packages/5c/e2/714694e4b87b85a18e2c243614974413c60aa107fd815b8cbc42b873d1d7/rpds_py-0.30.0-cp312-cp312-musllinux_1_2_x86_64.whl", hash = "sha256:7cee9c752c0364588353e627da8a7e808a66873672bcb5f52890c33fd965b394", size = 563120, upload-time = "2025-11-30T20:22:35.903Z" },
- { url = "https://files.pythonhosted.org/packages/6f/ab/d5d5e3bcedb0a77f4f613706b750e50a5a3ba1c15ccd3665ecc636c968fd/rpds_py-0.30.0-cp312-cp312-win32.whl", hash = "sha256:1ab5b83dbcf55acc8b08fc62b796ef672c457b17dbd7820a11d6c52c06839bdf", size = 223782, upload-time = "2025-11-30T20:22:37.271Z" },
- { url = "https://files.pythonhosted.org/packages/39/3b/f786af9957306fdc38a74cef405b7b93180f481fb48453a114bb6465744a/rpds_py-0.30.0-cp312-cp312-win_amd64.whl", hash = "sha256:a090322ca841abd453d43456ac34db46e8b05fd9b3b4ac0c78bcde8b089f959b", size = 240463, upload-time = "2025-11-30T20:22:39.021Z" },
- { url = "https://files.pythonhosted.org/packages/f3/d2/b91dc748126c1559042cfe41990deb92c4ee3e2b415f6b5234969ffaf0cc/rpds_py-0.30.0-cp312-cp312-win_arm64.whl", hash = "sha256:669b1805bd639dd2989b281be2cfd951c6121b65e729d9b843e9639ef1fd555e", size = 230868, upload-time = "2025-11-30T20:22:40.493Z" },
- { url = "https://files.pythonhosted.org/packages/ed/dc/d61221eb88ff410de3c49143407f6f3147acf2538c86f2ab7ce65ae7d5f9/rpds_py-0.30.0-cp313-cp313-macosx_10_12_x86_64.whl", hash = "sha256:f83424d738204d9770830d35290ff3273fbb02b41f919870479fab14b9d303b2", size = 374887, upload-time = "2025-11-30T20:22:41.812Z" },
- { url = "https://files.pythonhosted.org/packages/fd/32/55fb50ae104061dbc564ef15cc43c013dc4a9f4527a1f4d99baddf56fe5f/rpds_py-0.30.0-cp313-cp313-macosx_11_0_arm64.whl", hash = "sha256:e7536cd91353c5273434b4e003cbda89034d67e7710eab8761fd918ec6c69cf8", size = 358904, upload-time = "2025-11-30T20:22:43.479Z" },
- { url = "https://files.pythonhosted.org/packages/58/70/faed8186300e3b9bdd138d0273109784eea2396c68458ed580f885dfe7ad/rpds_py-0.30.0-cp313-cp313-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:2771c6c15973347f50fece41fc447c054b7ac2ae0502388ce3b6738cd366e3d4", size = 389945, upload-time = "2025-11-30T20:22:44.819Z" },
- { url = "https://files.pythonhosted.org/packages/bd/a8/073cac3ed2c6387df38f71296d002ab43496a96b92c823e76f46b8af0543/rpds_py-0.30.0-cp313-cp313-manylinux_2_17_armv7l.manylinux2014_armv7l.whl", hash = "sha256:0a59119fc6e3f460315fe9d08149f8102aa322299deaa5cab5b40092345c2136", size = 407783, upload-time = "2025-11-30T20:22:46.103Z" },
- { url = "https://files.pythonhosted.org/packages/77/57/5999eb8c58671f1c11eba084115e77a8899d6e694d2a18f69f0ba471ec8b/rpds_py-0.30.0-cp313-cp313-manylinux_2_17_ppc64le.manylinux2014_ppc64le.whl", hash = "sha256:76fec018282b4ead0364022e3c54b60bf368b9d926877957a8624b58419169b7", size = 515021, upload-time = "2025-11-30T20:22:47.458Z" },
- { url = "https://files.pythonhosted.org/packages/e0/af/5ab4833eadc36c0a8ed2bc5c0de0493c04f6c06de223170bd0798ff98ced/rpds_py-0.30.0-cp313-cp313-manylinux_2_17_s390x.manylinux2014_s390x.whl", hash = "sha256:692bef75a5525db97318e8cd061542b5a79812d711ea03dbc1f6f8dbb0c5f0d2", size = 414589, upload-time = "2025-11-30T20:22:48.872Z" },
- { url = "https://files.pythonhosted.org/packages/b7/de/f7192e12b21b9e9a68a6d0f249b4af3fdcdff8418be0767a627564afa1f1/rpds_py-0.30.0-cp313-cp313-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:9027da1ce107104c50c81383cae773ef5c24d296dd11c99e2629dbd7967a20c6", size = 394025, upload-time = "2025-11-30T20:22:50.196Z" },
- { url = "https://files.pythonhosted.org/packages/91/c4/fc70cd0249496493500e7cc2de87504f5aa6509de1e88623431fec76d4b6/rpds_py-0.30.0-cp313-cp313-manylinux_2_31_riscv64.whl", hash = "sha256:9cf69cdda1f5968a30a359aba2f7f9aa648a9ce4b580d6826437f2b291cfc86e", size = 408895, upload-time = "2025-11-30T20:22:51.87Z" },
- { url = "https://files.pythonhosted.org/packages/58/95/d9275b05ab96556fefff73a385813eb66032e4c99f411d0795372d9abcea/rpds_py-0.30.0-cp313-cp313-manylinux_2_5_i686.manylinux1_i686.whl", hash = "sha256:a4796a717bf12b9da9d3ad002519a86063dcac8988b030e405704ef7d74d2d9d", size = 422799, upload-time = "2025-11-30T20:22:53.341Z" },
- { url = "https://files.pythonhosted.org/packages/06/c1/3088fc04b6624eb12a57eb814f0d4997a44b0d208d6cace713033ff1a6ba/rpds_py-0.30.0-cp313-cp313-musllinux_1_2_aarch64.whl", hash = "sha256:5d4c2aa7c50ad4728a094ebd5eb46c452e9cb7edbfdb18f9e1221f597a73e1e7", size = 572731, upload-time = "2025-11-30T20:22:54.778Z" },
- { url = "https://files.pythonhosted.org/packages/d8/42/c612a833183b39774e8ac8fecae81263a68b9583ee343db33ab571a7ce55/rpds_py-0.30.0-cp313-cp313-musllinux_1_2_i686.whl", hash = "sha256:ba81a9203d07805435eb06f536d95a266c21e5b2dfbf6517748ca40c98d19e31", size = 599027, upload-time = "2025-11-30T20:22:56.212Z" },
- { url = "https://files.pythonhosted.org/packages/5f/60/525a50f45b01d70005403ae0e25f43c0384369ad24ffe46e8d9068b50086/rpds_py-0.30.0-cp313-cp313-musllinux_1_2_x86_64.whl", hash = "sha256:945dccface01af02675628334f7cf49c2af4c1c904748efc5cf7bbdf0b579f95", size = 563020, upload-time = "2025-11-30T20:22:58.2Z" },
- { url = "https://files.pythonhosted.org/packages/0b/5d/47c4655e9bcd5ca907148535c10e7d489044243cc9941c16ed7cd53be91d/rpds_py-0.30.0-cp313-cp313-win32.whl", hash = "sha256:b40fb160a2db369a194cb27943582b38f79fc4887291417685f3ad693c5a1d5d", size = 223139, upload-time = "2025-11-30T20:23:00.209Z" },
- { url = "https://files.pythonhosted.org/packages/f2/e1/485132437d20aa4d3e1d8b3fb5a5e65aa8139f1e097080c2a8443201742c/rpds_py-0.30.0-cp313-cp313-win_amd64.whl", hash = "sha256:806f36b1b605e2d6a72716f321f20036b9489d29c51c91f4dd29a3e3afb73b15", size = 240224, upload-time = "2025-11-30T20:23:02.008Z" },
- { url = "https://files.pythonhosted.org/packages/24/95/ffd128ed1146a153d928617b0ef673960130be0009c77d8fbf0abe306713/rpds_py-0.30.0-cp313-cp313-win_arm64.whl", hash = "sha256:d96c2086587c7c30d44f31f42eae4eac89b60dabbac18c7669be3700f13c3ce1", size = 230645, upload-time = "2025-11-30T20:23:03.43Z" },
- { url = "https://files.pythonhosted.org/packages/ff/1b/b10de890a0def2a319a2626334a7f0ae388215eb60914dbac8a3bae54435/rpds_py-0.30.0-cp313-cp313t-macosx_10_12_x86_64.whl", hash = "sha256:eb0b93f2e5c2189ee831ee43f156ed34e2a89a78a66b98cadad955972548be5a", size = 364443, upload-time = "2025-11-30T20:23:04.878Z" },
- { url = "https://files.pythonhosted.org/packages/0d/bf/27e39f5971dc4f305a4fb9c672ca06f290f7c4e261c568f3dea16a410d47/rpds_py-0.30.0-cp313-cp313t-macosx_11_0_arm64.whl", hash = "sha256:922e10f31f303c7c920da8981051ff6d8c1a56207dbdf330d9047f6d30b70e5e", size = 353375, upload-time = "2025-11-30T20:23:06.342Z" },
- { url = "https://files.pythonhosted.org/packages/40/58/442ada3bba6e8e6615fc00483135c14a7538d2ffac30e2d933ccf6852232/rpds_py-0.30.0-cp313-cp313t-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:cdc62c8286ba9bf7f47befdcea13ea0e26bf294bda99758fd90535cbaf408000", size = 383850, upload-time = "2025-11-30T20:23:07.825Z" },
- { url = "https://files.pythonhosted.org/packages/14/14/f59b0127409a33c6ef6f5c1ebd5ad8e32d7861c9c7adfa9a624fc3889f6c/rpds_py-0.30.0-cp313-cp313t-manylinux_2_17_armv7l.manylinux2014_armv7l.whl", hash = "sha256:47f9a91efc418b54fb8190a6b4aa7813a23fb79c51f4bb84e418f5476c38b8db", size = 392812, upload-time = "2025-11-30T20:23:09.228Z" },
- { url = "https://files.pythonhosted.org/packages/b3/66/e0be3e162ac299b3a22527e8913767d869e6cc75c46bd844aa43fb81ab62/rpds_py-0.30.0-cp313-cp313t-manylinux_2_17_ppc64le.manylinux2014_ppc64le.whl", hash = "sha256:1f3587eb9b17f3789ad50824084fa6f81921bbf9a795826570bda82cb3ed91f2", size = 517841, upload-time = "2025-11-30T20:23:11.186Z" },
- { url = "https://files.pythonhosted.org/packages/3d/55/fa3b9cf31d0c963ecf1ba777f7cf4b2a2c976795ac430d24a1f43d25a6ba/rpds_py-0.30.0-cp313-cp313t-manylinux_2_17_s390x.manylinux2014_s390x.whl", hash = "sha256:39c02563fc592411c2c61d26b6c5fe1e51eaa44a75aa2c8735ca88b0d9599daa", size = 408149, upload-time = "2025-11-30T20:23:12.864Z" },
- { url = "https://files.pythonhosted.org/packages/60/ca/780cf3b1a32b18c0f05c441958d3758f02544f1d613abf9488cd78876378/rpds_py-0.30.0-cp313-cp313t-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:51a1234d8febafdfd33a42d97da7a43f5dcb120c1060e352a3fbc0c6d36e2083", size = 383843, upload-time = "2025-11-30T20:23:14.638Z" },
- { url = "https://files.pythonhosted.org/packages/82/86/d5f2e04f2aa6247c613da0c1dd87fcd08fa17107e858193566048a1e2f0a/rpds_py-0.30.0-cp313-cp313t-manylinux_2_31_riscv64.whl", hash = "sha256:eb2c4071ab598733724c08221091e8d80e89064cd472819285a9ab0f24bcedb9", size = 396507, upload-time = "2025-11-30T20:23:16.105Z" },
- { url = "https://files.pythonhosted.org/packages/4b/9a/453255d2f769fe44e07ea9785c8347edaf867f7026872e76c1ad9f7bed92/rpds_py-0.30.0-cp313-cp313t-manylinux_2_5_i686.manylinux1_i686.whl", hash = "sha256:6bdfdb946967d816e6adf9a3d8201bfad269c67efe6cefd7093ef959683c8de0", size = 414949, upload-time = "2025-11-30T20:23:17.539Z" },
- { url = "https://files.pythonhosted.org/packages/a3/31/622a86cdc0c45d6df0e9ccb6becdba5074735e7033c20e401a6d9d0e2ca0/rpds_py-0.30.0-cp313-cp313t-musllinux_1_2_aarch64.whl", hash = "sha256:c77afbd5f5250bf27bf516c7c4a016813eb2d3e116139aed0096940c5982da94", size = 565790, upload-time = "2025-11-30T20:23:19.029Z" },
- { url = "https://files.pythonhosted.org/packages/1c/5d/15bbf0fb4a3f58a3b1c67855ec1efcc4ceaef4e86644665fff03e1b66d8d/rpds_py-0.30.0-cp313-cp313t-musllinux_1_2_i686.whl", hash = "sha256:61046904275472a76c8c90c9ccee9013d70a6d0f73eecefd38c1ae7c39045a08", size = 590217, upload-time = "2025-11-30T20:23:20.885Z" },
- { url = "https://files.pythonhosted.org/packages/6d/61/21b8c41f68e60c8cc3b2e25644f0e3681926020f11d06ab0b78e3c6bbff1/rpds_py-0.30.0-cp313-cp313t-musllinux_1_2_x86_64.whl", hash = "sha256:4c5f36a861bc4b7da6516dbdf302c55313afa09b81931e8280361a4f6c9a2d27", size = 555806, upload-time = "2025-11-30T20:23:22.488Z" },
- { url = "https://files.pythonhosted.org/packages/f9/39/7e067bb06c31de48de3eb200f9fc7c58982a4d3db44b07e73963e10d3be9/rpds_py-0.30.0-cp313-cp313t-win32.whl", hash = "sha256:3d4a69de7a3e50ffc214ae16d79d8fbb0922972da0356dcf4d0fdca2878559c6", size = 211341, upload-time = "2025-11-30T20:23:24.449Z" },
- { url = "https://files.pythonhosted.org/packages/0a/4d/222ef0b46443cf4cf46764d9c630f3fe4abaa7245be9417e56e9f52b8f65/rpds_py-0.30.0-cp313-cp313t-win_amd64.whl", hash = "sha256:f14fc5df50a716f7ece6a80b6c78bb35ea2ca47c499e422aa4463455dd96d56d", size = 225768, upload-time = "2025-11-30T20:23:25.908Z" },
- { url = "https://files.pythonhosted.org/packages/86/81/dad16382ebbd3d0e0328776d8fd7ca94220e4fa0798d1dc5e7da48cb3201/rpds_py-0.30.0-cp314-cp314-macosx_10_12_x86_64.whl", hash = "sha256:68f19c879420aa08f61203801423f6cd5ac5f0ac4ac82a2368a9fcd6a9a075e0", size = 362099, upload-time = "2025-11-30T20:23:27.316Z" },
- { url = "https://files.pythonhosted.org/packages/2b/60/19f7884db5d5603edf3c6bce35408f45ad3e97e10007df0e17dd57af18f8/rpds_py-0.30.0-cp314-cp314-macosx_11_0_arm64.whl", hash = "sha256:ec7c4490c672c1a0389d319b3a9cfcd098dcdc4783991553c332a15acf7249be", size = 353192, upload-time = "2025-11-30T20:23:29.151Z" },
- { url = "https://files.pythonhosted.org/packages/bf/c4/76eb0e1e72d1a9c4703c69607cec123c29028bff28ce41588792417098ac/rpds_py-0.30.0-cp314-cp314-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:f251c812357a3fed308d684a5079ddfb9d933860fc6de89f2b7ab00da481e65f", size = 384080, upload-time = "2025-11-30T20:23:30.785Z" },
- { url = "https://files.pythonhosted.org/packages/72/87/87ea665e92f3298d1b26d78814721dc39ed8d2c74b86e83348d6b48a6f31/rpds_py-0.30.0-cp314-cp314-manylinux_2_17_armv7l.manylinux2014_armv7l.whl", hash = "sha256:ac98b175585ecf4c0348fd7b29c3864bda53b805c773cbf7bfdaffc8070c976f", size = 394841, upload-time = "2025-11-30T20:23:32.209Z" },
- { url = "https://files.pythonhosted.org/packages/77/ad/7783a89ca0587c15dcbf139b4a8364a872a25f861bdb88ed99f9b0dec985/rpds_py-0.30.0-cp314-cp314-manylinux_2_17_ppc64le.manylinux2014_ppc64le.whl", hash = "sha256:3e62880792319dbeb7eb866547f2e35973289e7d5696c6e295476448f5b63c87", size = 516670, upload-time = "2025-11-30T20:23:33.742Z" },
- { url = "https://files.pythonhosted.org/packages/5b/3c/2882bdac942bd2172f3da574eab16f309ae10a3925644e969536553cb4ee/rpds_py-0.30.0-cp314-cp314-manylinux_2_17_s390x.manylinux2014_s390x.whl", hash = "sha256:4e7fc54e0900ab35d041b0601431b0a0eb495f0851a0639b6ef90f7741b39a18", size = 408005, upload-time = "2025-11-30T20:23:35.253Z" },
- { url = "https://files.pythonhosted.org/packages/ce/81/9a91c0111ce1758c92516a3e44776920b579d9a7c09b2b06b642d4de3f0f/rpds_py-0.30.0-cp314-cp314-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:47e77dc9822d3ad616c3d5759ea5631a75e5809d5a28707744ef79d7a1bcfcad", size = 382112, upload-time = "2025-11-30T20:23:36.842Z" },
- { url = "https://files.pythonhosted.org/packages/cf/8e/1da49d4a107027e5fbc64daeab96a0706361a2918da10cb41769244b805d/rpds_py-0.30.0-cp314-cp314-manylinux_2_31_riscv64.whl", hash = "sha256:b4dc1a6ff022ff85ecafef7979a2c6eb423430e05f1165d6688234e62ba99a07", size = 399049, upload-time = "2025-11-30T20:23:38.343Z" },
- { url = "https://files.pythonhosted.org/packages/df/5a/7ee239b1aa48a127570ec03becbb29c9d5a9eb092febbd1699d567cae859/rpds_py-0.30.0-cp314-cp314-manylinux_2_5_i686.manylinux1_i686.whl", hash = "sha256:4559c972db3a360808309e06a74628b95eaccbf961c335c8fe0d590cf587456f", size = 415661, upload-time = "2025-11-30T20:23:40.263Z" },
- { url = "https://files.pythonhosted.org/packages/70/ea/caa143cf6b772f823bc7929a45da1fa83569ee49b11d18d0ada7f5ee6fd6/rpds_py-0.30.0-cp314-cp314-musllinux_1_2_aarch64.whl", hash = "sha256:0ed177ed9bded28f8deb6ab40c183cd1192aa0de40c12f38be4d59cd33cb5c65", size = 565606, upload-time = "2025-11-30T20:23:42.186Z" },
- { url = "https://files.pythonhosted.org/packages/64/91/ac20ba2d69303f961ad8cf55bf7dbdb4763f627291ba3d0d7d67333cced9/rpds_py-0.30.0-cp314-cp314-musllinux_1_2_i686.whl", hash = "sha256:ad1fa8db769b76ea911cb4e10f049d80bf518c104f15b3edb2371cc65375c46f", size = 591126, upload-time = "2025-11-30T20:23:44.086Z" },
- { url = "https://files.pythonhosted.org/packages/21/20/7ff5f3c8b00c8a95f75985128c26ba44503fb35b8e0259d812766ea966c7/rpds_py-0.30.0-cp314-cp314-musllinux_1_2_x86_64.whl", hash = "sha256:46e83c697b1f1c72b50e5ee5adb4353eef7406fb3f2043d64c33f20ad1c2fc53", size = 553371, upload-time = "2025-11-30T20:23:46.004Z" },
- { url = "https://files.pythonhosted.org/packages/72/c7/81dadd7b27c8ee391c132a6b192111ca58d866577ce2d9b0ca157552cce0/rpds_py-0.30.0-cp314-cp314-win32.whl", hash = "sha256:ee454b2a007d57363c2dfd5b6ca4a5d7e2c518938f8ed3b706e37e5d470801ed", size = 215298, upload-time = "2025-11-30T20:23:47.696Z" },
- { url = "https://files.pythonhosted.org/packages/3e/d2/1aaac33287e8cfb07aab2e6b8ac1deca62f6f65411344f1433c55e6f3eb8/rpds_py-0.30.0-cp314-cp314-win_amd64.whl", hash = "sha256:95f0802447ac2d10bcc69f6dc28fe95fdf17940367b21d34e34c737870758950", size = 228604, upload-time = "2025-11-30T20:23:49.501Z" },
- { url = "https://files.pythonhosted.org/packages/e8/95/ab005315818cc519ad074cb7784dae60d939163108bd2b394e60dc7b5461/rpds_py-0.30.0-cp314-cp314-win_arm64.whl", hash = "sha256:613aa4771c99f03346e54c3f038e4cc574ac09a3ddfb0e8878487335e96dead6", size = 222391, upload-time = "2025-11-30T20:23:50.96Z" },
- { url = "https://files.pythonhosted.org/packages/9e/68/154fe0194d83b973cdedcdcc88947a2752411165930182ae41d983dcefa6/rpds_py-0.30.0-cp314-cp314t-macosx_10_12_x86_64.whl", hash = "sha256:7e6ecfcb62edfd632e56983964e6884851786443739dbfe3582947e87274f7cb", size = 364868, upload-time = "2025-11-30T20:23:52.494Z" },
- { url = "https://files.pythonhosted.org/packages/83/69/8bbc8b07ec854d92a8b75668c24d2abcb1719ebf890f5604c61c9369a16f/rpds_py-0.30.0-cp314-cp314t-macosx_11_0_arm64.whl", hash = "sha256:a1d0bc22a7cdc173fedebb73ef81e07faef93692b8c1ad3733b67e31e1b6e1b8", size = 353747, upload-time = "2025-11-30T20:23:54.036Z" },
- { url = "https://files.pythonhosted.org/packages/ab/00/ba2e50183dbd9abcce9497fa5149c62b4ff3e22d338a30d690f9af970561/rpds_py-0.30.0-cp314-cp314t-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:0d08f00679177226c4cb8c5265012eea897c8ca3b93f429e546600c971bcbae7", size = 383795, upload-time = "2025-11-30T20:23:55.556Z" },
- { url = "https://files.pythonhosted.org/packages/05/6f/86f0272b84926bcb0e4c972262f54223e8ecc556b3224d281e6598fc9268/rpds_py-0.30.0-cp314-cp314t-manylinux_2_17_armv7l.manylinux2014_armv7l.whl", hash = "sha256:5965af57d5848192c13534f90f9dd16464f3c37aaf166cc1da1cae1fd5a34898", size = 393330, upload-time = "2025-11-30T20:23:57.033Z" },
- { url = "https://files.pythonhosted.org/packages/cb/e9/0e02bb2e6dc63d212641da45df2b0bf29699d01715913e0d0f017ee29438/rpds_py-0.30.0-cp314-cp314t-manylinux_2_17_ppc64le.manylinux2014_ppc64le.whl", hash = "sha256:9a4e86e34e9ab6b667c27f3211ca48f73dba7cd3d90f8d5b11be56e5dbc3fb4e", size = 518194, upload-time = "2025-11-30T20:23:58.637Z" },
- { url = "https://files.pythonhosted.org/packages/ee/ca/be7bca14cf21513bdf9c0606aba17d1f389ea2b6987035eb4f62bd923f25/rpds_py-0.30.0-cp314-cp314t-manylinux_2_17_s390x.manylinux2014_s390x.whl", hash = "sha256:e5d3e6b26f2c785d65cc25ef1e5267ccbe1b069c5c21b8cc724efee290554419", size = 408340, upload-time = "2025-11-30T20:24:00.2Z" },
- { url = "https://files.pythonhosted.org/packages/c2/c7/736e00ebf39ed81d75544c0da6ef7b0998f8201b369acf842f9a90dc8fce/rpds_py-0.30.0-cp314-cp314t-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:626a7433c34566535b6e56a1b39a7b17ba961e97ce3b80ec62e6f1312c025551", size = 383765, upload-time = "2025-11-30T20:24:01.759Z" },
- { url = "https://files.pythonhosted.org/packages/4a/3f/da50dfde9956aaf365c4adc9533b100008ed31aea635f2b8d7b627e25b49/rpds_py-0.30.0-cp314-cp314t-manylinux_2_31_riscv64.whl", hash = "sha256:acd7eb3f4471577b9b5a41baf02a978e8bdeb08b4b355273994f8b87032000a8", size = 396834, upload-time = "2025-11-30T20:24:03.687Z" },
- { url = "https://files.pythonhosted.org/packages/4e/00/34bcc2565b6020eab2623349efbdec810676ad571995911f1abdae62a3a0/rpds_py-0.30.0-cp314-cp314t-manylinux_2_5_i686.manylinux1_i686.whl", hash = "sha256:fe5fa731a1fa8a0a56b0977413f8cacac1768dad38d16b3a296712709476fbd5", size = 415470, upload-time = "2025-11-30T20:24:05.232Z" },
- { url = "https://files.pythonhosted.org/packages/8c/28/882e72b5b3e6f718d5453bd4d0d9cf8df36fddeb4ddbbab17869d5868616/rpds_py-0.30.0-cp314-cp314t-musllinux_1_2_aarch64.whl", hash = "sha256:74a3243a411126362712ee1524dfc90c650a503502f135d54d1b352bd01f2404", size = 565630, upload-time = "2025-11-30T20:24:06.878Z" },
- { url = "https://files.pythonhosted.org/packages/3b/97/04a65539c17692de5b85c6e293520fd01317fd878ea1995f0367d4532fb1/rpds_py-0.30.0-cp314-cp314t-musllinux_1_2_i686.whl", hash = "sha256:3e8eeb0544f2eb0d2581774be4c3410356eba189529a6b3e36bbbf9696175856", size = 591148, upload-time = "2025-11-30T20:24:08.445Z" },
- { url = "https://files.pythonhosted.org/packages/85/70/92482ccffb96f5441aab93e26c4d66489eb599efdcf96fad90c14bbfb976/rpds_py-0.30.0-cp314-cp314t-musllinux_1_2_x86_64.whl", hash = "sha256:dbd936cde57abfee19ab3213cf9c26be06d60750e60a8e4dd85d1ab12c8b1f40", size = 556030, upload-time = "2025-11-30T20:24:10.956Z" },
- { url = "https://files.pythonhosted.org/packages/20/53/7c7e784abfa500a2b6b583b147ee4bb5a2b3747a9166bab52fec4b5b5e7d/rpds_py-0.30.0-cp314-cp314t-win32.whl", hash = "sha256:dc824125c72246d924f7f796b4f63c1e9dc810c7d9e2355864b3c3a73d59ade0", size = 211570, upload-time = "2025-11-30T20:24:12.735Z" },
- { url = "https://files.pythonhosted.org/packages/d0/02/fa464cdfbe6b26e0600b62c528b72d8608f5cc49f96b8d6e38c95d60c676/rpds_py-0.30.0-cp314-cp314t-win_amd64.whl", hash = "sha256:27f4b0e92de5bfbc6f86e43959e6edd1425c33b5e69aab0984a72047f2bcf1e3", size = 226532, upload-time = "2025-11-30T20:24:14.634Z" },
- { url = "https://files.pythonhosted.org/packages/69/71/3f34339ee70521864411f8b6992e7ab13ac30d8e4e3309e07c7361767d91/rpds_py-0.30.0-pp311-pypy311_pp73-macosx_10_12_x86_64.whl", hash = "sha256:c2262bdba0ad4fc6fb5545660673925c2d2a5d9e2e0fb603aad545427be0fc58", size = 372292, upload-time = "2025-11-30T20:24:16.537Z" },
- { url = "https://files.pythonhosted.org/packages/57/09/f183df9b8f2d66720d2ef71075c59f7e1b336bec7ee4c48f0a2b06857653/rpds_py-0.30.0-pp311-pypy311_pp73-macosx_11_0_arm64.whl", hash = "sha256:ee6af14263f25eedc3bb918a3c04245106a42dfd4f5c2285ea6f997b1fc3f89a", size = 362128, upload-time = "2025-11-30T20:24:18.086Z" },
- { url = "https://files.pythonhosted.org/packages/7a/68/5c2594e937253457342e078f0cc1ded3dd7b2ad59afdbf2d354869110a02/rpds_py-0.30.0-pp311-pypy311_pp73-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:3adbb8179ce342d235c31ab8ec511e66c73faa27a47e076ccc92421add53e2bb", size = 391542, upload-time = "2025-11-30T20:24:20.092Z" },
- { url = "https://files.pythonhosted.org/packages/49/5c/31ef1afd70b4b4fbdb2800249f34c57c64beb687495b10aec0365f53dfc4/rpds_py-0.30.0-pp311-pypy311_pp73-manylinux_2_17_armv7l.manylinux2014_armv7l.whl", hash = "sha256:250fa00e9543ac9b97ac258bd37367ff5256666122c2d0f2bc97577c60a1818c", size = 404004, upload-time = "2025-11-30T20:24:22.231Z" },
- { url = "https://files.pythonhosted.org/packages/e3/63/0cfbea38d05756f3440ce6534d51a491d26176ac045e2707adc99bb6e60a/rpds_py-0.30.0-pp311-pypy311_pp73-manylinux_2_17_ppc64le.manylinux2014_ppc64le.whl", hash = "sha256:9854cf4f488b3d57b9aaeb105f06d78e5529d3145b1e4a41750167e8c213c6d3", size = 527063, upload-time = "2025-11-30T20:24:24.302Z" },
- { url = "https://files.pythonhosted.org/packages/42/e6/01e1f72a2456678b0f618fc9a1a13f882061690893c192fcad9f2926553a/rpds_py-0.30.0-pp311-pypy311_pp73-manylinux_2_17_s390x.manylinux2014_s390x.whl", hash = "sha256:993914b8e560023bc0a8bf742c5f303551992dcb85e247b1e5c7f4a7d145bda5", size = 413099, upload-time = "2025-11-30T20:24:25.916Z" },
- { url = "https://files.pythonhosted.org/packages/b8/25/8df56677f209003dcbb180765520c544525e3ef21ea72279c98b9aa7c7fb/rpds_py-0.30.0-pp311-pypy311_pp73-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:58edca431fb9b29950807e301826586e5bbf24163677732429770a697ffe6738", size = 392177, upload-time = "2025-11-30T20:24:27.834Z" },
- { url = "https://files.pythonhosted.org/packages/4a/b4/0a771378c5f16f8115f796d1f437950158679bcd2a7c68cf251cfb00ed5b/rpds_py-0.30.0-pp311-pypy311_pp73-manylinux_2_31_riscv64.whl", hash = "sha256:dea5b552272a944763b34394d04577cf0f9bd013207bc32323b5a89a53cf9c2f", size = 406015, upload-time = "2025-11-30T20:24:29.457Z" },
- { url = "https://files.pythonhosted.org/packages/36/d8/456dbba0af75049dc6f63ff295a2f92766b9d521fa00de67a2bd6427d57a/rpds_py-0.30.0-pp311-pypy311_pp73-manylinux_2_5_i686.manylinux1_i686.whl", hash = "sha256:ba3af48635eb83d03f6c9735dfb21785303e73d22ad03d489e88adae6eab8877", size = 423736, upload-time = "2025-11-30T20:24:31.22Z" },
- { url = "https://files.pythonhosted.org/packages/13/64/b4d76f227d5c45a7e0b796c674fd81b0a6c4fbd48dc29271857d8219571c/rpds_py-0.30.0-pp311-pypy311_pp73-musllinux_1_2_aarch64.whl", hash = "sha256:dff13836529b921e22f15cb099751209a60009731a68519630a24d61f0b1b30a", size = 573981, upload-time = "2025-11-30T20:24:32.934Z" },
- { url = "https://files.pythonhosted.org/packages/20/91/092bacadeda3edf92bf743cc96a7be133e13a39cdbfd7b5082e7ab638406/rpds_py-0.30.0-pp311-pypy311_pp73-musllinux_1_2_i686.whl", hash = "sha256:1b151685b23929ab7beec71080a8889d4d6d9fa9a983d213f07121205d48e2c4", size = 599782, upload-time = "2025-11-30T20:24:35.169Z" },
- { url = "https://files.pythonhosted.org/packages/d1/b7/b95708304cd49b7b6f82fdd039f1748b66ec2b21d6a45180910802f1abf1/rpds_py-0.30.0-pp311-pypy311_pp73-musllinux_1_2_x86_64.whl", hash = "sha256:ac37f9f516c51e5753f27dfdef11a88330f04de2d564be3991384b2f3535d02e", size = 562191, upload-time = "2025-11-30T20:24:36.853Z" },
-]
-
-[[package]]
-name = "rpds-py"
-version = "2026.5.1"
-source = { registry = "https://pypi.org/simple" }
-resolution-markers = [
- "python_full_version >= '3.12'",
- "python_full_version == '3.11.*'",
-]
-sdist = { url = "https://files.pythonhosted.org/packages/2e/43/25a8dcd3feedd735039a8f0b5b7e3b118232b5eae288c4fd9ab200d41094/rpds_py-2026.5.1.tar.gz", hash = "sha256:07b24fea40541e28570e5b795a4a38fbdcd12550c06bd0748005ecc8116ca256", size = 64459, upload-time = "2026-05-28T12:02:13.232Z" }
-wheels = [
- { url = "https://files.pythonhosted.org/packages/4f/a0/acf8b6fc20bfdcd3a45bd3f57680fb198e157b7e997b9123b10763798bd2/rpds_py-2026.5.1-cp311-cp311-macosx_10_12_x86_64.whl", hash = "sha256:3397a5ed7174dc2786bb214030232fc36fe8e5584fec43a9952cc542b1a12036", size = 355609, upload-time = "2026-05-28T11:58:50.78Z" },
- { url = "https://files.pythonhosted.org/packages/b6/95/f8203fd997484b1690a6869cd0e503b6c3c6be55b0ecc36d1a491fe742f0/rpds_py-2026.5.1-cp311-cp311-macosx_11_0_arm64.whl", hash = "sha256:99ab6ba7bfa2cb0f96a04e3652355bf04e3f51aceb1e943b8541dab7ba4828cc", size = 348460, upload-time = "2026-05-28T11:58:52.374Z" },
- { url = "https://files.pythonhosted.org/packages/33/8c/b47326ad2f0be545a5e5c1a55937a12afaea7d392ba2837bb9680f57e6c9/rpds_py-2026.5.1-cp311-cp311-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:d0efbe45632665e53e3db8fe1e5692db58fc5cb9bab4459d570b83efefe11164", size = 381031, upload-time = "2026-05-28T11:58:53.775Z" },
- { url = "https://files.pythonhosted.org/packages/22/0b/e83bbd97ffac6f6389b605cd4e1c8ac5761dc7e977769c9255d8c5adb7bd/rpds_py-2026.5.1-cp311-cp311-manylinux_2_17_armv7l.manylinux2014_armv7l.whl", hash = "sha256:01d17b29c0c23d82b1f4751147ec49cf451f1fc2554eb9ef5f957e55d2656ead", size = 387121, upload-time = "2026-05-28T11:58:55.243Z" },
- { url = "https://files.pythonhosted.org/packages/fd/0e/d285d1bc8864245919c61e1ca82263e4a66d337759c3a4cef72766ff9afc/rpds_py-2026.5.1-cp311-cp311-manylinux_2_17_ppc64le.manylinux2014_ppc64le.whl", hash = "sha256:7559f72b94ae52659086c595dfa017cde03155f7832071d30959049052cb3ece", size = 501026, upload-time = "2026-05-28T11:58:56.788Z" },
- { url = "https://files.pythonhosted.org/packages/86/06/ccb2109a1e543437b5e43816f2b43b9554cc6783145528a4e3711e05c011/rpds_py-2026.5.1-cp311-cp311-manylinux_2_17_s390x.manylinux2014_s390x.whl", hash = "sha256:9e25b7088f9ccbfc0dfcaa52bf969300ca229e10ecf758974ebcbb080a4b37bb", size = 391865, upload-time = "2026-05-28T11:58:58.298Z" },
- { url = "https://files.pythonhosted.org/packages/3d/33/237173db1cfef10105b3839a24de00eb8d2a523711add4632447cdf0aedd/rpds_py-2026.5.1-cp311-cp311-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:613fc4ee9eaef26dc5840666214dd6fbcebcf32f46e76f4abc473059f4e13dda", size = 378012, upload-time = "2026-05-28T11:58:59.589Z" },
- { url = "https://files.pythonhosted.org/packages/97/64/1eae54e34d5161f9969295e80bd6b62a55f2b6ac5f2a5b60d02c2140e758/rpds_py-2026.5.1-cp311-cp311-manylinux_2_31_riscv64.whl", hash = "sha256:85264a90ff4c05c1568dd65f5921c837614b67c60358fb4c17df3b7f2e90690a", size = 391111, upload-time = "2026-05-28T11:59:01.104Z" },
- { url = "https://files.pythonhosted.org/packages/d8/34/5bb334a5a0f65d77869217c4654f34c78a7d11b93938a3c076a2edeafc52/rpds_py-2026.5.1-cp311-cp311-manylinux_2_5_i686.manylinux1_i686.whl", hash = "sha256:fe71bca7d547acb17027c7fd1624ff8aae623499c498d3e7011182c4de5c25e0", size = 409225, upload-time = "2026-05-28T11:59:02.433Z" },
- { url = "https://files.pythonhosted.org/packages/16/0f/007ec21283b5b040b4ec3bd95e0402591e22bfa7d5c93dfe01c465c2d2d7/rpds_py-2026.5.1-cp311-cp311-musllinux_1_2_aarch64.whl", hash = "sha256:a05fa4f41f37ec97c9c260441a940450a192f78d774d2b097eee1379f1e1246a", size = 556487, upload-time = "2026-05-28T11:59:04.012Z" },
- { url = "https://files.pythonhosted.org/packages/ff/10/5437c94508169b6b22d8418fef7a66e9ffb5f3b9e9c94460f2eedafe06ff/rpds_py-2026.5.1-cp311-cp311-musllinux_1_2_i686.whl", hash = "sha256:df1d2a1996755b24b9ecee92cb4d36c28f86f464a6a173349c26bab41e94b8c2", size = 620798, upload-time = "2026-05-28T11:59:05.485Z" },
- { url = "https://files.pythonhosted.org/packages/e0/d5/9937dce4d6bda74157b954e7d1460db05a22f5929dccfeeba1ed27a93df0/rpds_py-2026.5.1-cp311-cp311-musllinux_1_2_x86_64.whl", hash = "sha256:8895840ac4809e5f60c88fd07617cd71326e73d6e5a8aa783c5c0f7c24985de2", size = 584053, upload-time = "2026-05-28T11:59:06.837Z" },
- { url = "https://files.pythonhosted.org/packages/6c/31/750617dd0ae1752471bf43f9e41d263398fae7cde7849d23b8574a70e617/rpds_py-2026.5.1-cp311-cp311-win32.whl", hash = "sha256:3684a59b158a7683aaeb8e25352e9a9dd2122cec78f2d8530266e4f91b4c7b3f", size = 214390, upload-time = "2026-05-28T11:59:08.402Z" },
- { url = "https://files.pythonhosted.org/packages/3c/bb/3dcab0e1d9516303f2eb672a5d6f62eca5a69e2886301e9c8c54b520c39b/rpds_py-2026.5.1-cp311-cp311-win_amd64.whl", hash = "sha256:7bd530e6a530bb3ea892f194fafa455f3516ac25ecf7143fd33c09be62b0470a", size = 231097, upload-time = "2026-05-28T11:59:09.786Z" },
- { url = "https://files.pythonhosted.org/packages/49/d6/c6bbf5cb1cf12b9732df8074b57f6ef8341ba884c95d40632ae8bddb44e4/rpds_py-2026.5.1-cp311-cp311-win_arm64.whl", hash = "sha256:0a5ae4dbe43c1076983b72616496919872ae7bbe7a1e21cc48336bc3154d130b", size = 226361, upload-time = "2026-05-28T11:59:11.079Z" },
- { url = "https://files.pythonhosted.org/packages/d4/e7/a78582dc57caa592dcc7d4fb69b61390561e908eb3d2f5df5928a8e354c0/rpds_py-2026.5.1-cp312-cp312-macosx_10_12_x86_64.whl", hash = "sha256:3abe24a66e57adcfa645d718063a5fa5103ecc71ddbf26d78af8f9368018ff1d", size = 353040, upload-time = "2026-05-28T11:59:12.531Z" },
- { url = "https://files.pythonhosted.org/packages/a3/43/35e3f136343aef451e545ce8c38d36c2f93c0ed88703db8b64ba2b205c68/rpds_py-2026.5.1-cp312-cp312-macosx_11_0_arm64.whl", hash = "sha256:58b1d94308ddf0b1982f61f2eb54bf92997c9ece8a8093ef014250f4a517906c", size = 345775, upload-time = "2026-05-28T11:59:13.827Z" },
- { url = "https://files.pythonhosted.org/packages/20/e1/0f2160c5982d3157734d5cb3ed63d8b2d583a73c9864f77b666449f32cf8/rpds_py-2026.5.1-cp312-cp312-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:0fa92420128dadce7f54bd73ba1825a273e9268fe9e35dbf7e6362890efa4e08", size = 376329, upload-time = "2026-05-28T11:59:15.271Z" },
- { url = "https://files.pythonhosted.org/packages/d0/11/ee0ba42aff83bf4effdbc576673c6be64c5e173978c3f6d537e94482f77d/rpds_py-2026.5.1-cp312-cp312-manylinux_2_17_armv7l.manylinux2014_armv7l.whl", hash = "sha256:ca653c6546386227cd9800d1bef6a348099acf8db4250341da6d90f663d6dfcb", size = 383539, upload-time = "2026-05-28T11:59:16.665Z" },
- { url = "https://files.pythonhosted.org/packages/11/df/d94aa6a499d4ac40afe2d7620f2c597fd3c0f182e854ad7cf3f596a81cb6/rpds_py-2026.5.1-cp312-cp312-manylinux_2_17_ppc64le.manylinux2014_ppc64le.whl", hash = "sha256:66c93681c4729e4e3ecba31b8179fae083ff3118841672835140338b4b9867c1", size = 494674, upload-time = "2026-05-28T11:59:17.991Z" },
- { url = "https://files.pythonhosted.org/packages/1f/75/33d30f43bb2f458de11979486a591b1bf6e5651765ed1704c6197c2dc773/rpds_py-2026.5.1-cp312-cp312-manylinux_2_17_s390x.manylinux2014_s390x.whl", hash = "sha256:40ff257542e04796880e011e15cd4dc21c2599975df2aaa8f2c8495ca574e1a5", size = 389268, upload-time = "2026-05-28T11:59:19.434Z" },
- { url = "https://files.pythonhosted.org/packages/f4/1e/2c9096fc19d5fd084b0184ca2b651e659aa0a37e6fdbecf6ece47f147fe1/rpds_py-2026.5.1-cp312-cp312-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:b6825cc329b290e93c5f6a9be2393118a763f6ccf6abd83704e0c102ca583644", size = 376280, upload-time = "2026-05-28T11:59:21Z" },
- { url = "https://files.pythonhosted.org/packages/b9/e5/61ec9f8be8211ea7f48448195549e4aaf02004083475493b0e137702ecb2/rpds_py-2026.5.1-cp312-cp312-manylinux_2_31_riscv64.whl", hash = "sha256:de42116e69cb53b911cc34aee5ab98f36c597b822545045d49e938818b99e5e4", size = 387233, upload-time = "2026-05-28T11:59:22.454Z" },
- { url = "https://files.pythonhosted.org/packages/0d/ca/bcec1005c4f4a234f92a29078631fee49206c7265ccae966f18fd332e80e/rpds_py-2026.5.1-cp312-cp312-manylinux_2_5_i686.manylinux1_i686.whl", hash = "sha256:c0f920015df2a504bebaba6d4c31ccf3fcf942f92655c086da30b671aad19aa6", size = 405009, upload-time = "2026-05-28T11:59:23.845Z" },
- { url = "https://files.pythonhosted.org/packages/72/e6/4d5718c5cf26c522dc7c9999e238da1e77380b81d0c5d1df11e271ddfeb1/rpds_py-2026.5.1-cp312-cp312-musllinux_1_2_aarch64.whl", hash = "sha256:0408a24e44feb919423dc6d9da677cb5cddb894d2ca9e763967d156d9c60fab4", size = 553113, upload-time = "2026-05-28T11:59:25.184Z" },
- { url = "https://files.pythonhosted.org/packages/d4/25/2ee807bdb3e1f0b7eddf7782acd5665a8b5205a331a7d7244a52c4812fd9/rpds_py-2026.5.1-cp312-cp312-musllinux_1_2_i686.whl", hash = "sha256:cea68bcd53467561ae2f96a6bdad1544299ba97b5b0ddcd5ac3d376e5c781c24", size = 618838, upload-time = "2026-05-28T11:59:26.749Z" },
- { url = "https://files.pythonhosted.org/packages/6a/c1/7d4c26f167f8c41501cc073d30ee22082b16ce358cf5b00ec97cbc7804ea/rpds_py-2026.5.1-cp312-cp312-musllinux_1_2_x86_64.whl", hash = "sha256:4be8b1d2a705cc37d08256004e1d07de143fa0075c8e85a3df020b776f62b732", size = 582436, upload-time = "2026-05-28T11:59:28.11Z" },
- { url = "https://files.pythonhosted.org/packages/04/1d/9d12b0a337bab46f4769f8857f4007e3b2d639e14f9a44a0efe157696e64/rpds_py-2026.5.1-cp312-cp312-win32.whl", hash = "sha256:6736718bd4fc49cbcb538ba30516fdbef161522acefb739657d48b97bd864fed", size = 212734, upload-time = "2026-05-28T11:59:29.689Z" },
- { url = "https://files.pythonhosted.org/packages/c5/93/e4116f2de7f56bc7406a76033dc501811ddeb22b7f056b92d632871ebb0c/rpds_py-2026.5.1-cp312-cp312-win_amd64.whl", hash = "sha256:0a7d1eec967df0e9b22614a5e177622e0c89611d03727fa0cb48e45028907870", size = 229045, upload-time = "2026-05-28T11:59:31.033Z" },
- { url = "https://files.pythonhosted.org/packages/cb/53/6c3419d85eb2ec5938a37627c585b42d76a63bb731d6e42ed4b079ebf486/rpds_py-2026.5.1-cp312-cp312-win_arm64.whl", hash = "sha256:1841d067089e117142d79b98aa0df2f08b52f2ecc1819dd2700636c0db74a473", size = 223967, upload-time = "2026-05-28T11:59:32.318Z" },
- { url = "https://files.pythonhosted.org/packages/6c/32/14c961ad295f490eb0849ada8b79683e93a59b9de3afdd983eaf55fa6867/rpds_py-2026.5.1-cp313-cp313-macosx_10_12_x86_64.whl", hash = "sha256:efef4ac29c6ff495531eb17ee705b62841ecaa291b7c7077e848ea03e237164d", size = 352787, upload-time = "2026-05-28T11:59:33.655Z" },
- { url = "https://files.pythonhosted.org/packages/ca/bb/d1b85117967c11191441a7274ae616c65d93901d082c588f89a50a8da5ae/rpds_py-2026.5.1-cp313-cp313-macosx_11_0_arm64.whl", hash = "sha256:c39f5b67a8a2e67179ada2a954227d670fe65fa9098457f698f56ddf248709b3", size = 345179, upload-time = "2026-05-28T11:59:35Z" },
- { url = "https://files.pythonhosted.org/packages/7c/46/d84105f062e626a1b233f863907288a4708c2d833b8b4c6fb2764bc080c0/rpds_py-2026.5.1-cp313-cp313-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:b5c30f3f04eef4fbd362226a6f31d7c8895ca4fbb6e0b790f6890a98d8da8559", size = 376173, upload-time = "2026-05-28T11:59:36.43Z" },
- { url = "https://files.pythonhosted.org/packages/e2/ae/469d7959ce5b1201e1de135dc735b86db3b35dd0d1734f6a44246d5f061c/rpds_py-2026.5.1-cp313-cp313-manylinux_2_17_armv7l.manylinux2014_armv7l.whl", hash = "sha256:277f6c82f0580848796c7ecc8a7173aa3bfb928e4ff831261c2f60a81dc270db", size = 383162, upload-time = "2026-05-28T11:59:37.995Z" },
- { url = "https://files.pythonhosted.org/packages/dc/a2/57853d31a1116a561aa072794602ad3f6341e18d70a8523f1bd5b9fc1e5a/rpds_py-2026.5.1-cp313-cp313-manylinux_2_17_ppc64le.manylinux2014_ppc64le.whl", hash = "sha256:63c2c4c213f1a4e3f3de28ecab029dbdee976324e729c0d7a55211be72576b02", size = 495093, upload-time = "2026-05-28T11:59:39.453Z" },
- { url = "https://files.pythonhosted.org/packages/99/63/3a8eabcad9314b7daf5c65f451d2c33d989235cd8a5762186cf2c3f5a4f8/rpds_py-2026.5.1-cp313-cp313-manylinux_2_17_s390x.manylinux2014_s390x.whl", hash = "sha256:3350ec808fb538fe71a1f94dfaa0e29c598dfad805ce49f0caec5ae3183c652b", size = 389829, upload-time = "2026-05-28T11:59:40.896Z" },
- { url = "https://files.pythonhosted.org/packages/4b/25/05678d97fc25e2622df14dc530fb82023174ecfff6733991ed0d78f167bd/rpds_py-2026.5.1-cp313-cp313-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:b1b964e3ab599e718dc46c018d104b1ebc007cbc6567d827c94a687fca56d77e", size = 374786, upload-time = "2026-05-28T11:59:42.626Z" },
- { url = "https://files.pythonhosted.org/packages/88/d1/8c90b6431e80a3b91b284a5c7c8c0c4f9c006444d90477a740d6e0f9c694/rpds_py-2026.5.1-cp313-cp313-manylinux_2_31_riscv64.whl", hash = "sha256:19cb09fab7b7fc96b2a6e28f2e34b72a3705ff27b37edb77455316e5d3f3dc9b", size = 386920, upload-time = "2026-05-28T11:59:44.124Z" },
- { url = "https://files.pythonhosted.org/packages/ff/99/4638f672ab356682d633ee0da9255f5b67ce6efd0b85eb94ad3e255e65a5/rpds_py-2026.5.1-cp313-cp313-manylinux_2_5_i686.manylinux1_i686.whl", hash = "sha256:abe76bcdba31e576cb83eeb8797aa0d882b738fef6dc65d0601fc753806a5b46", size = 405059, upload-time = "2026-05-28T11:59:47.177Z" },
- { url = "https://files.pythonhosted.org/packages/66/3f/3546524b6eb4cc2e1f363a3d638fa52f6c24faae3500c25fb488b02f1740/rpds_py-2026.5.1-cp313-cp313-musllinux_1_2_aarch64.whl", hash = "sha256:8bff7073db3899158fff55ebf57b113a67030af26f80a18978f9f0aa60250ddf", size = 553030, upload-time = "2026-05-28T11:59:48.603Z" },
- { url = "https://files.pythonhosted.org/packages/c6/c3/7b3388c796fcf471bd17194242d4dc1a7608567c0fa422bcc1c5e79f9c1e/rpds_py-2026.5.1-cp313-cp313-musllinux_1_2_i686.whl", hash = "sha256:8ba264fa49be666cd9cc56bf34ec7002fb3d27a4aee5bcb4d43d0d18feb1bb6f", size = 618975, upload-time = "2026-05-28T11:59:50.314Z" },
- { url = "https://files.pythonhosted.org/packages/61/1e/a3cb07f2795075d1d88efddae2f541359fde5f08c81ee114c29c2949c90a/rpds_py-2026.5.1-cp313-cp313-musllinux_1_2_x86_64.whl", hash = "sha256:4860b603ddda0475a8885499b3729e90229d480105b42651962a5397d995fa89", size = 581178, upload-time = "2026-05-28T11:59:51.673Z" },
- { url = "https://files.pythonhosted.org/packages/a1/74/e758c03a5ef46f04c37f2651a2893db846d569ba8a7bca469d4b58939bcd/rpds_py-2026.5.1-cp313-cp313-win32.whl", hash = "sha256:7944270ae71383f6e2657dd7d5ce4eeb4ac2d0059a6738f0510583d462ab4842", size = 212481, upload-time = "2026-05-28T11:59:53.148Z" },
- { url = "https://files.pythonhosted.org/packages/70/ec/a2aca432db9c7359b40fa393eeeaa0d166c2f70175be956e75fa24197c44/rpds_py-2026.5.1-cp313-cp313-win_amd64.whl", hash = "sha256:88647f43a73c4e01be19b04ceef0c8d3a1958153604d13c773becd8016f2a0cf", size = 228519, upload-time = "2026-05-28T11:59:54.505Z" },
- { url = "https://files.pythonhosted.org/packages/29/60/a73bfdd45b096574556acf303bbd9fa9eed36ca8a818b514e2a5d5fe2b9d/rpds_py-2026.5.1-cp313-cp313-win_arm64.whl", hash = "sha256:453895624ecf7db7063b1004e44037522bbaef9ff6a945e59bc71662d7a03abd", size = 223446, upload-time = "2026-05-28T11:59:56.081Z" },
- { url = "https://files.pythonhosted.org/packages/18/e2/408105fd611823f00882aea810f3989a30d26b1bab8b6beb20f98c724e0e/rpds_py-2026.5.1-cp313-cp313t-macosx_10_12_x86_64.whl", hash = "sha256:b4e4bc98639ec915f512fde3aa7a95e0041d95d9c3cc86eea841fa63cb1e8600", size = 355287, upload-time = "2026-05-28T11:59:57.448Z" },
- { url = "https://files.pythonhosted.org/packages/8d/58/5c4a43436843c90d0f6d19f82c200c80e3843ca9fa07b237623327f6d384/rpds_py-2026.5.1-cp313-cp313t-macosx_11_0_arm64.whl", hash = "sha256:cacedb7a6e167680acba45ad5716e89067d225dc80da0d7040cae8c81d4572fa", size = 347033, upload-time = "2026-05-28T11:59:58.881Z" },
- { url = "https://files.pythonhosted.org/packages/fb/c2/1a71acdacaf4e259b10278fb87b039ded3cf80041bcd89dd8a3ea702ded6/rpds_py-2026.5.1-cp313-cp313t-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:68700371c5d7ae1412862ddfa719090925c93ecf351c566d66f09d04b136ea00", size = 376891, upload-time = "2026-05-28T12:00:00.516Z" },
- { url = "https://files.pythonhosted.org/packages/c2/c8/535f3d9b65addd8e28aa87b83c6e526799c3717a88273db8ea795beeef7a/rpds_py-2026.5.1-cp313-cp313t-manylinux_2_17_armv7l.manylinux2014_armv7l.whl", hash = "sha256:296c799becfa849c779c8725494fe9ed94959ed886787df4364b058465bad7f0", size = 385646, upload-time = "2026-05-28T12:00:02.394Z" },
- { url = "https://files.pythonhosted.org/packages/1c/91/dc033f313345c354ade914dbe73cdb90b615a4409ea02430d5356794f3d8/rpds_py-2026.5.1-cp313-cp313t-manylinux_2_17_ppc64le.manylinux2014_ppc64le.whl", hash = "sha256:d3858b908218ee108d0bbfb2095ccc237648053c9bf98affad7cb079acaf1d97", size = 498830, upload-time = "2026-05-28T12:00:04.189Z" },
- { url = "https://files.pythonhosted.org/packages/27/fc/90fcbea459dbb8ddc18a2e0fd1de9412b48bc84ffff2db771cf714bacfd6/rpds_py-2026.5.1-cp313-cp313t-manylinux_2_17_s390x.manylinux2014_s390x.whl", hash = "sha256:4fb8d2e7cb2f850b169806d61d1b991738acec96500a75c30f49caf064ce7cef", size = 392830, upload-time = "2026-05-28T12:00:05.797Z" },
- { url = "https://files.pythonhosted.org/packages/b2/1d/46cd11a228c9750684a798d98f878be6f614aa762438da7378f035e79e35/rpds_py-2026.5.1-cp313-cp313t-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:27b74c10ed6a8f190f4287f53bcfea348b92a84a9c9f70d30183d1e6172d580d", size = 379613, upload-time = "2026-05-28T12:00:07.433Z" },
- { url = "https://files.pythonhosted.org/packages/24/4a/d9b0c6af3a1de03eb93741bbe8be2bdce84d8fda8224f3005451d86df389/rpds_py-2026.5.1-cp313-cp313t-manylinux_2_31_riscv64.whl", hash = "sha256:b9a6528956191c48c52294a592dbd4a8386d7048bdb25c0efcb6b966466c6d83", size = 388183, upload-time = "2026-05-28T12:00:09.227Z" },
- { url = "https://files.pythonhosted.org/packages/c5/b4/db7aaabdda6d020afc87d981bcc2f57a434c7dec60ecfc2ab3dd50b20351/rpds_py-2026.5.1-cp313-cp313t-manylinux_2_5_i686.manylinux1_i686.whl", hash = "sha256:af03e34e860047bc7a352b842856fcf78798fbb81132cc98bd2f907ab4eb9cd2", size = 408578, upload-time = "2026-05-28T12:00:10.779Z" },
- { url = "https://files.pythonhosted.org/packages/08/d6/070f6a41cbb343e2ac4171859bf3f3623e0ab002f72619d6d505313ec2de/rpds_py-2026.5.1-cp313-cp313t-musllinux_1_2_aarch64.whl", hash = "sha256:fea6e836d10abbe191d557d33bd58bd5987725fe63aa1eefe557d230209855bd", size = 553573, upload-time = "2026-05-28T12:00:12.443Z" },
- { url = "https://files.pythonhosted.org/packages/75/ab/1a71ea3589c4345dac0a0518f0e6a031cb42689277851b683c46d27463a5/rpds_py-2026.5.1-cp313-cp313t-musllinux_1_2_i686.whl", hash = "sha256:fc0c0f878ea770a0a8a462456c5ad36fc9fe6358e6b76fdadc7f17575e0b8bf1", size = 620861, upload-time = "2026-05-28T12:00:14.09Z" },
- { url = "https://files.pythonhosted.org/packages/8a/22/9bf80a56069c0c443fcfefac639a86a744550a2898817a6dfd3e26654924/rpds_py-2026.5.1-cp313-cp313t-musllinux_1_2_x86_64.whl", hash = "sha256:e0b360f316d966b048b085857630b3cc51f3db2f07b06f440eac8f695374d1e3", size = 585633, upload-time = "2026-05-28T12:00:15.66Z" },
- { url = "https://files.pythonhosted.org/packages/da/68/3b2c0a75c9e04125696f84ebdbbf304acf5a40b58ba4481cdb98a922c3ba/rpds_py-2026.5.1-cp313-cp313t-win32.whl", hash = "sha256:a2999883eedf72fdfb7520b92c7d4ec2572a71ff40239377aa604cc529eecafc", size = 210074, upload-time = "2026-05-28T12:00:17.291Z" },
- { url = "https://files.pythonhosted.org/packages/e7/8b/609157d5a25d37d4f29f92840ba531f416907c34ae5c5739dd21fc2bef98/rpds_py-2026.5.1-cp313-cp313t-win_amd64.whl", hash = "sha256:e07be2a9d7122bd6e82dea89814ef8dc893feb1aae97fec1630f3263bbb30e55", size = 228635, upload-time = "2026-05-28T12:00:18.73Z" },
- { url = "https://files.pythonhosted.org/packages/d4/6f/19c1918a4b590d8de87e712e4abe4b3875771eff60216fb6153cf6665c68/rpds_py-2026.5.1-cp314-cp314-macosx_10_12_x86_64.whl", hash = "sha256:1f2c391c3059798093b65df23aca2cac150460ae9c630d99dec83d703d9485b9", size = 349756, upload-time = "2026-05-28T12:00:20.217Z" },
- { url = "https://files.pythonhosted.org/packages/e5/60/a06fe7da34eca79dacbf958a2ba0c6eea85bc2b29de20080bf40f72f66fa/rpds_py-2026.5.1-cp314-cp314-macosx_11_0_arm64.whl", hash = "sha256:413b424f7c4ee65ab5e5be91f5731be0f8b41a1ee2b12dfe810d716312e95a78", size = 343831, upload-time = "2026-05-28T12:00:21.711Z" },
- { url = "https://files.pythonhosted.org/packages/bf/ec/b2333b97b90e2a6ef6ca8ad386ee284968e74bcfe113b3f1a8d9036429a9/rpds_py-2026.5.1-cp314-cp314-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:2c595a1d9255dce0599e13130d1440ab2506654f2b50294226ee06402f8fef63", size = 375127, upload-time = "2026-05-28T12:00:23.326Z" },
- { url = "https://files.pythonhosted.org/packages/14/7f/e00aae54067f2b488c4637961d5f58204d470795fc791085fa3f15060d2e/rpds_py-2026.5.1-cp314-cp314-manylinux_2_17_armv7l.manylinux2014_armv7l.whl", hash = "sha256:1c27c5f6102eac8c03e7595a00827a53b271ba40a53b59ff8709170e0855ea4a", size = 379034, upload-time = "2026-05-28T12:00:24.89Z" },
- { url = "https://files.pythonhosted.org/packages/be/cc/423999bbb8ae8dc93c77fc1d5e984ade5eb89d237d3bb884ccfa72ae2890/rpds_py-2026.5.1-cp314-cp314-manylinux_2_17_ppc64le.manylinux2014_ppc64le.whl", hash = "sha256:6c7fcf61d44cacecaf3aea542b0e053db77972a4573e7ceda16fb2b399161195", size = 490823, upload-time = "2026-05-28T12:00:26.676Z" },
- { url = "https://files.pythonhosted.org/packages/0f/aa/c671bf660f12e68d3c52ff86c7066ed1372df5a0f4f2ff584e419b8207e7/rpds_py-2026.5.1-cp314-cp314-manylinux_2_17_s390x.manylinux2014_s390x.whl", hash = "sha256:2c817a189d4ee14290420e5ff051e4dd6baa13f3edf84685071dee07a6d538ee", size = 388144, upload-time = "2026-05-28T12:00:28.577Z" },
- { url = "https://files.pythonhosted.org/packages/19/c8/d63bb75b68afe77b229e3021c6031bcaf01da5db5b0e69d0d10f9ba679a7/rpds_py-2026.5.1-cp314-cp314-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:21846aac0ed2e0589f38c12dc44e77bb64e494b771eadbcf169cba00566ba7ba", size = 371959, upload-time = "2026-05-28T12:00:30.304Z" },
- { url = "https://files.pythonhosted.org/packages/82/35/c51122014d8274ff37dc606d60049c3db7d83da02b5b282511e5a906a9a6/rpds_py-2026.5.1-cp314-cp314-manylinux_2_31_riscv64.whl", hash = "sha256:b317c87a13f769a4e787819bd508aaa5d69aa09b0880de9af6d3a8a54571cdec", size = 383558, upload-time = "2026-05-28T12:00:31.764Z" },
- { url = "https://files.pythonhosted.org/packages/e3/f9/2790cb99c136a5363acdeacf5c27c56f3de0d4118a1f48fca83404c99c89/rpds_py-2026.5.1-cp314-cp314-manylinux_2_5_i686.manylinux1_i686.whl", hash = "sha256:ce87129d9f2c14fa6c4a8601fb80eb4488c80d38a20cd13758ef11123e14995d", size = 402789, upload-time = "2026-05-28T12:00:33.247Z" },
- { url = "https://files.pythonhosted.org/packages/e5/1b/e4fb584f8c75d35c38150ff6a332cda949e6f97acba1f4fd123b14ab56fe/rpds_py-2026.5.1-cp314-cp314-musllinux_1_2_aarch64.whl", hash = "sha256:9cdddb6c1207d284d94fd1530adf57fbd797fe7c4b8704ba85f49414f2557e7d", size = 551405, upload-time = "2026-05-28T12:00:34.819Z" },
- { url = "https://files.pythonhosted.org/packages/d8/f7/a6731b4216cb3793ea1af5391da240f5683dacc0d13e034fe5fc3503f240/rpds_py-2026.5.1-cp314-cp314-musllinux_1_2_i686.whl", hash = "sha256:4e237e139f94d3c036fd28eb9f564c99055476ff4ff05cd42be55ce349b5aa02", size = 616975, upload-time = "2026-05-28T12:00:36.268Z" },
- { url = "https://files.pythonhosted.org/packages/2c/ea/2e051a81d95d8e63f4b35a1c463a87e8766bc3d083c067c5dfb6bf220747/rpds_py-2026.5.1-cp314-cp314-musllinux_1_2_x86_64.whl", hash = "sha256:ed0954b524873214369184a9c82b0eaa45a3fbb9a798cd95b17e0d98499e7ea0", size = 578701, upload-time = "2026-05-28T12:00:37.82Z" },
- { url = "https://files.pythonhosted.org/packages/65/56/b5f6fdb2083e32bca8a8993d89e70db114b4756c9e2c38421328126689d2/rpds_py-2026.5.1-cp314-cp314-win32.whl", hash = "sha256:2d88621d6a7d4dfa633d21abe90f280bb205274e16b1d1e61c6ad4640b2453b7", size = 209806, upload-time = "2026-05-28T12:00:39.492Z" },
- { url = "https://files.pythonhosted.org/packages/fb/80/65a5aa96c155e611d1ed844e4e1f57f3e36b021f396d9f8585d756e6b90d/rpds_py-2026.5.1-cp314-cp314-win_amd64.whl", hash = "sha256:cef8ac28d26f4dda3533060c20fbf80a325458fa9fd23ea72a73cdfa8e978838", size = 225985, upload-time = "2026-05-28T12:00:40.94Z" },
- { url = "https://files.pythonhosted.org/packages/27/7c/ad185212e87b05f196daef92bc5f3caf07298eb47c295b5585c3dd3093ac/rpds_py-2026.5.1-cp314-cp314-win_arm64.whl", hash = "sha256:eaaea962c68cdc68d4a533ba985ab8e9484277910bbfaa2ab3ef7732667bfed8", size = 221219, upload-time = "2026-05-28T12:00:43.15Z" },
- { url = "https://files.pythonhosted.org/packages/23/58/e14ae18759020334646b031e708ab4158d653a938822bfb7b95ef2e93aa3/rpds_py-2026.5.1-cp314-cp314t-macosx_10_12_x86_64.whl", hash = "sha256:21942f52dbbd5f8758bf021213d28bd45c39e873e65e2407faf5f1846f5761ad", size = 352148, upload-time = "2026-05-28T12:00:44.638Z" },
- { url = "https://files.pythonhosted.org/packages/31/9b/5f4a1e2f960bca3ac5d052b139dd31eed97b259f9d909173821760d542e8/rpds_py-2026.5.1-cp314-cp314t-macosx_11_0_arm64.whl", hash = "sha256:f414556f6e3958300ff941e40c9f97e3dc9774ddd1b3434c475d73dd354bbed3", size = 345196, upload-time = "2026-05-28T12:00:46.14Z" },
- { url = "https://files.pythonhosted.org/packages/1a/71/1d9574d6a2fa20ab60eaa55c7467f5aa20cbc770f341a05f09c0876f59e2/rpds_py-2026.5.1-cp314-cp314t-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:ef1013a8625c74043210190b246f5b1551e09757c1f356c6e4160ef96c5bc081", size = 374981, upload-time = "2026-05-28T12:00:47.531Z" },
- { url = "https://files.pythonhosted.org/packages/0c/9a/37e99f4915a80aa71670263c1267f7ae0af95f53a3f61e6c3bdc016d4515/rpds_py-2026.5.1-cp314-cp314t-manylinux_2_17_armv7l.manylinux2014_armv7l.whl", hash = "sha256:cc68e231a77a5f0d774ae278a1f8e55c0456501820847c1e4efb3829f3441df6", size = 379961, upload-time = "2026-05-28T12:00:49.216Z" },
- { url = "https://files.pythonhosted.org/packages/a8/ff/6e73f74b89d2e0715e0fc86b7dde893f9a61ae2f9b256ff3bdfe41ac4e94/rpds_py-2026.5.1-cp314-cp314t-manylinux_2_17_ppc64le.manylinux2014_ppc64le.whl", hash = "sha256:9baffb505aff33acc69b422a19f77806680f3c8632227d79f48de8a810d1c2c5", size = 495965, upload-time = "2026-05-28T12:00:51.111Z" },
- { url = "https://files.pythonhosted.org/packages/ea/e0/425faba25f59d74d4638b267f7c7a80e8649d2ef4db10a19b0c4a71e6e6f/rpds_py-2026.5.1-cp314-cp314t-manylinux_2_17_s390x.manylinux2014_s390x.whl", hash = "sha256:b8d2f912928d426e8cfa396f7f3f8d29a59e6689c86dcca3c420730c1096322b", size = 389526, upload-time = "2026-05-28T12:00:52.77Z" },
- { url = "https://files.pythonhosted.org/packages/c6/76/7a41960e3fddae47fab43a28684d5da981401dffd88253de0944148654cb/rpds_py-2026.5.1-cp314-cp314t-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:90f628283be835db980c941767d41c9a27b5239e54ba0a9c1335247e82406964", size = 376190, upload-time = "2026-05-28T12:00:54.215Z" },
- { url = "https://files.pythonhosted.org/packages/27/60/5f38dc70824fc6951b51d35377e577a3a3a4c81a6769cc5a2de25ebe0ad1/rpds_py-2026.5.1-cp314-cp314t-manylinux_2_31_riscv64.whl", hash = "sha256:1ebb2f0ab7e16132995a72de805170e0203df0c3dd22e1ef1cd1fdd90bd7a131", size = 383921, upload-time = "2026-05-28T12:00:55.673Z" },
- { url = "https://files.pythonhosted.org/packages/60/1a/d60a38caa1505f4b9483c3fbbde12c94e1079154f4f401a6da96f7e77621/rpds_py-2026.5.1-cp314-cp314t-manylinux_2_5_i686.manylinux1_i686.whl", hash = "sha256:f3df3d16ded76f1f8c9cdebd0e1ea55fdf4c23b812de189814da7cf229c22a81", size = 404766, upload-time = "2026-05-28T12:00:57.518Z" },
- { url = "https://files.pythonhosted.org/packages/87/ff/602fd3f174d6425f0bce05ad0dfbec0e96b38d0f7d08a79af5aa20083885/rpds_py-2026.5.1-cp314-cp314t-musllinux_1_2_aarch64.whl", hash = "sha256:9af8905b8f854990e40d5206aa5ac58d9b0fe0b7f351ff2bb086c20f6c8c6a47", size = 551343, upload-time = "2026-05-28T12:00:58.978Z" },
- { url = "https://files.pythonhosted.org/packages/b8/c1/1be13327acdbead3eca1fde03b6a34dbb011f1e864e217f0d32cc1779a7f/rpds_py-2026.5.1-cp314-cp314t-musllinux_1_2_i686.whl", hash = "sha256:036a36a87fb1cd3b214d11c4b3c4f7d2ddad933625dca1c900b56a057c07740a", size = 618502, upload-time = "2026-05-28T12:01:00.656Z" },
- { url = "https://files.pythonhosted.org/packages/f3/d7/afb49b49d7f2be8b7ba1a9f0977fa5168003437b93086726f066544e8351/rpds_py-2026.5.1-cp314-cp314t-musllinux_1_2_x86_64.whl", hash = "sha256:62ae3853454fe9ef283a03c96c2d835d39e84b14643a9d62c82ef0fb87d702ca", size = 581916, upload-time = "2026-05-28T12:01:02.22Z" },
- { url = "https://files.pythonhosted.org/packages/25/d1/dbef8c1f8a10f07beb62b5f054e20099fd9924b3ec001b8f0b6ac7813a85/rpds_py-2026.5.1-cp314-cp314t-win32.whl", hash = "sha256:6c3d771a46ec18b12af06ce36243a9a80b07a5d0515236332d90863ca8bb326a", size = 207855, upload-time = "2026-05-28T12:01:03.821Z" },
- { url = "https://files.pythonhosted.org/packages/2a/72/bfa4e61ab8e7dc1c8adf397e05e6cbdd4239357bd72b248d3de662f23915/rpds_py-2026.5.1-cp314-cp314t-win_amd64.whl", hash = "sha256:c93c629be4636cf54337bd5f06c104d55e42ced54d681f6fe21ae510a65116f6", size = 225422, upload-time = "2026-05-28T12:01:05.194Z" },
- { url = "https://files.pythonhosted.org/packages/27/3a/7b5da92b640f67b6717ccafc83cdd06bfa7ff2395c3685c68922bb54d703/rpds_py-2026.5.1-cp315-cp315-macosx_10_12_x86_64.whl", hash = "sha256:3574b55c604b8f75dacb007136508bbc0db406e626301778096a133327e7f2fb", size = 349576, upload-time = "2026-05-28T12:01:06.722Z" },
- { url = "https://files.pythonhosted.org/packages/d7/8a/2aafd7ad355a1bd48ca76e2262b74b15e6432b5a1efe150efd4d779cd55d/rpds_py-2026.5.1-cp315-cp315-macosx_11_0_arm64.whl", hash = "sha256:94068eb3ae6d43f5a786b7db96a406a34e6d5c24489feef32fd6e8946ea7b291", size = 343640, upload-time = "2026-05-28T12:01:08.441Z" },
- { url = "https://files.pythonhosted.org/packages/f7/7d/6c9523c1abbe840a1b7fba3c516d48e1d3487cc80fea4366c4071cf56784/rpds_py-2026.5.1-cp315-cp315-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:f3a5b10e8ce894825f380a8f1b6444cf73c294dfea62afbb2d13e3a9e630cec1", size = 375322, upload-time = "2026-05-28T12:01:09.934Z" },
- { url = "https://files.pythonhosted.org/packages/5a/5d/0b7b03fb1dc509321f01de3149784ab773e34c8573022029af8076afcb9c/rpds_py-2026.5.1-cp315-cp315-manylinux_2_17_armv7l.manylinux2014_armv7l.whl", hash = "sha256:fc09f82e63d4bcd58149572f857a431bae851dc747e313c3b5bdf7abb907fda8", size = 379066, upload-time = "2026-05-28T12:01:11.48Z" },
- { url = "https://files.pythonhosted.org/packages/d7/e2/8ef6012999ebf1cb1c22f876d9ce5e63d960fd4631d2af3202d3f480aa25/rpds_py-2026.5.1-cp315-cp315-manylinux_2_17_ppc64le.manylinux2014_ppc64le.whl", hash = "sha256:e10464d17df3b582745c25cec695cb9558bca2cb6ddb631aee1787fc72c767b2", size = 494586, upload-time = "2026-05-28T12:01:13.051Z" },
- { url = "https://files.pythonhosted.org/packages/80/af/1eeb029bec67582c226b7809172207cd005073af4ebd906e65ff494f4983/rpds_py-2026.5.1-cp315-cp315-manylinux_2_17_s390x.manylinux2014_s390x.whl", hash = "sha256:ba05adbf15d994c38ec0b7ab32e858e5110c21e9009a00a86545fd220f84e038", size = 388415, upload-time = "2026-05-28T12:01:14.631Z" },
- { url = "https://files.pythonhosted.org/packages/18/23/ffbe10711c4d766c1cab0557d6906c074f795814863c67b351355d29354a/rpds_py-2026.5.1-cp315-cp315-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:77c004fdc7b891967106f78ddfd7b076bfe6813c6139c6fff6aed3bcaa960b26", size = 372427, upload-time = "2026-05-28T12:01:16.153Z" },
- { url = "https://files.pythonhosted.org/packages/bd/3a/30ba4a6ad457e5b070c18d742a33fb77d8d922b565cc881f8a5313d63bfe/rpds_py-2026.5.1-cp315-cp315-manylinux_2_31_riscv64.whl", hash = "sha256:83bcf894486c9d78dd290d3c0124ff6dd8875d3025e2090a8ec49fcc37c55fdd", size = 383615, upload-time = "2026-05-28T12:01:17.809Z" },
- { url = "https://files.pythonhosted.org/packages/d3/69/62e242b53ce39c0814bd24e1a6e6eba6c92be716277745f317f9540a2e7b/rpds_py-2026.5.1-cp315-cp315-manylinux_2_5_i686.manylinux1_i686.whl", hash = "sha256:c3df104083952a0e0c6f10de33e440eabe98fb6317d23e1a58c68f6df08d01b9", size = 402786, upload-time = "2026-05-28T12:01:19.419Z" },
- { url = "https://files.pythonhosted.org/packages/38/c1/a770b9c186928a1ed0f7e6d7ae50e7f3950ed23e3f9e366dbc8e38cb55de/rpds_py-2026.5.1-cp315-cp315-musllinux_1_2_aarch64.whl", hash = "sha256:980450826cf22e133c57e0835070bdd0dd3f73b9b708c3ce223def2cb9469e14", size = 551583, upload-time = "2026-05-28T12:01:21.013Z" },
- { url = "https://files.pythonhosted.org/packages/21/7c/68e8579b95375b70d2a963103c42e705856cdb98569258bd807f4423891c/rpds_py-2026.5.1-cp315-cp315-musllinux_1_2_i686.whl", hash = "sha256:205dde846f24332ab0c1188699a043b8d165b79bb84529ce272c45048ff6be01", size = 616941, upload-time = "2026-05-28T12:01:22.548Z" },
- { url = "https://files.pythonhosted.org/packages/70/a1/a6135aed5730ff03ab957182259987ac11e55fb392a28dc6f0592048a280/rpds_py-2026.5.1-cp315-cp315-musllinux_1_2_x86_64.whl", hash = "sha256:3966b82dd563176396df030f3dd52a6e54cb69b718e95e78bd555ed3d1e0185d", size = 578349, upload-time = "2026-05-28T12:01:24.118Z" },
- { url = "https://files.pythonhosted.org/packages/09/6e/f24201a76a84e6c49d0bdfdfcb735210e21701e9b21c5bfc0ba497dd62f6/rpds_py-2026.5.1-cp315-cp315-win32.whl", hash = "sha256:7818f8d0a415be74d2be3590b0a1c1f463a642f4d0217e7d10602dceef5b79aa", size = 209922, upload-time = "2026-05-28T12:01:25.522Z" },
- { url = "https://files.pythonhosted.org/packages/9e/e4/966bc240bb0485fc265278f6de44d05834bf0b3618886e0b22e33d54c49a/rpds_py-2026.5.1-cp315-cp315-win_amd64.whl", hash = "sha256:b3cc20c0d800af78fd0fac68086e28c1856cec51ea528bb81ea851aa40d39325", size = 226003, upload-time = "2026-05-28T12:01:27.062Z" },
- { url = "https://files.pythonhosted.org/packages/5c/5c/a15a59269cd5e74472734516c73795c15eccfc841b3d4b0228c3f53f19d0/rpds_py-2026.5.1-cp315-cp315-win_arm64.whl", hash = "sha256:3609e9939a8a76cd904cf98a3f1f13b5dc7e150adeaee89e0ea09652ea213e16", size = 221245, upload-time = "2026-05-28T12:01:28.51Z" },
- { url = "https://files.pythonhosted.org/packages/e0/22/135ce03804e179a71ceb13be095deda4a279bc88f7a6b8fa161c5ad44e12/rpds_py-2026.5.1-cp315-cp315t-macosx_10_12_x86_64.whl", hash = "sha256:5d333a7127d4b307601ac37792bee01bb95c867cbfacf21b6375b804d6bbd723", size = 352015, upload-time = "2026-05-28T12:01:30.214Z" },
- { url = "https://files.pythonhosted.org/packages/3b/5f/f1f6d2652eb9d848f6eb369d8db83a2da6249bb49ad2c2a48f45d54538d3/rpds_py-2026.5.1-cp315-cp315t-macosx_11_0_arm64.whl", hash = "sha256:b5f077b44a4f7808520f66dae234988d867deb9aed9be5da057ce9ba831b2a41", size = 345016, upload-time = "2026-05-28T12:01:31.656Z" },
- { url = "https://files.pythonhosted.org/packages/88/66/b74182775691ea2290c99e52ac8d5db844e56fbec90ce421f107658c8314/rpds_py-2026.5.1-cp315-cp315t-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:55d8f9b7b78c9538fc9e04e82ec0e888ff0c3cffcfad152c77e57cd09351a98a", size = 374775, upload-time = "2026-05-28T12:01:33.136Z" },
- { url = "https://files.pythonhosted.org/packages/ff/8f/15e5a61d9f0a43902d36561d4f07cae6ae9f4716be825159fd72717f33af/rpds_py-2026.5.1-cp315-cp315t-manylinux_2_17_armv7l.manylinux2014_armv7l.whl", hash = "sha256:e3a8ae58895ac107ed934a6bf51e5846f95c53b9b940c2c6d310838fd5846358", size = 380270, upload-time = "2026-05-28T12:01:34.574Z" },
- { url = "https://files.pythonhosted.org/packages/02/c3/f859b12763a80540cdf2af0f15b19904cf756a71d7bdd3f82ff3e5b1bbf9/rpds_py-2026.5.1-cp315-cp315t-manylinux_2_17_ppc64le.manylinux2014_ppc64le.whl", hash = "sha256:0957cf3c2b8632ec7aaebffebea8005b353cc2a237b6e2ae3c2cac0820704cfb", size = 495285, upload-time = "2026-05-28T12:01:36.127Z" },
- { url = "https://files.pythonhosted.org/packages/1c/c7/ff27c2ac8411d30b03b1829fd88cae8dad1a4d0da48dd25e57c4038042e6/rpds_py-2026.5.1-cp315-cp315t-manylinux_2_17_s390x.manylinux2014_s390x.whl", hash = "sha256:c396c1304de421050b3681ea70f371874b54d41b0151e96109758144c231e30b", size = 389581, upload-time = "2026-05-28T12:01:37.635Z" },
- { url = "https://files.pythonhosted.org/packages/6e/67/fe92ee32a6cc05c77228a2f8b1762e7124f386ec20ff83d0757b762d58d0/rpds_py-2026.5.1-cp315-cp315t-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:aad1bff7f666b9598e573815affd666aac6a13a585dde336f843e33350c7fadc", size = 376041, upload-time = "2026-05-28T12:01:39.307Z" },
- { url = "https://files.pythonhosted.org/packages/f8/91/b4d6685c27aba55bd82f25b278be8237038117d05f9659a6213ad3408130/rpds_py-2026.5.1-cp315-cp315t-manylinux_2_31_riscv64.whl", hash = "sha256:656a042550878f12d45752452d47094b7cfe5ad1e9d7b87b5a22ad3ae5ff8015", size = 383946, upload-time = "2026-05-28T12:01:41.043Z" },
- { url = "https://files.pythonhosted.org/packages/bd/79/2c1d832a53c8e0f8e98fc970ec257b950fecd4f62be2ab7182b500a0cbc8/rpds_py-2026.5.1-cp315-cp315t-manylinux_2_5_i686.manylinux1_i686.whl", hash = "sha256:73c4bd4f70294737b5206a3e8e30ccadbf8a60301831c8ea23eec5dbeea1ecfa", size = 405526, upload-time = "2026-05-28T12:01:43.032Z" },
- { url = "https://files.pythonhosted.org/packages/78/c4/c98117b03c6a8581ab2c2dfccfe9a5ad82bd8128a3c28b46a6ad2d97c393/rpds_py-2026.5.1-cp315-cp315t-musllinux_1_2_aarch64.whl", hash = "sha256:43bca78665423cabae77146f2fe7ce55272b6c8d55d82cca83effd42c7e13972", size = 551165, upload-time = "2026-05-28T12:01:44.648Z" },
- { url = "https://files.pythonhosted.org/packages/3b/c1/bc479ca069200af730881b1bd525e3114b2b391a351509fcb1b772f28086/rpds_py-2026.5.1-cp315-cp315t-musllinux_1_2_i686.whl", hash = "sha256:42d0f20e85e549c870749d0e247f0c10d318a45b7e9676d575d2dcb04a1b2e66", size = 618778, upload-time = "2026-05-28T12:01:46.337Z" },
- { url = "https://files.pythonhosted.org/packages/77/65/38ab2f90df44c2febfb63cc10ced40763d9b4bc94d173e734528663fe7f5/rpds_py-2026.5.1-cp315-cp315t-musllinux_1_2_x86_64.whl", hash = "sha256:b1be5c35683684d5331b93600c210e8367c254683d8a6df6bd21bd2da3a334fb", size = 581839, upload-time = "2026-05-28T12:01:48.109Z" },
- { url = "https://files.pythonhosted.org/packages/15/2d/ce1f605fe036aadd460e5822e578c6c7ec3a860936cca37d6e0f299daa77/rpds_py-2026.5.1-cp315-cp315t-win32.whl", hash = "sha256:75808f6c38ce7749bb68cc2770161aae5045e6c6f6781a9782e74b93304399df", size = 207866, upload-time = "2026-05-28T12:01:49.648Z" },
- { url = "https://files.pythonhosted.org/packages/79/cb/966040123eb102371559746908ef2c9471f4d43e17ec9a645a2258dab64b/rpds_py-2026.5.1-cp315-cp315t-win_amd64.whl", hash = "sha256:90bd6630002a1c7f09e7843dd79f0d24f3d2897cc25a753480917865d14f15b3", size = 225441, upload-time = "2026-05-28T12:01:51.408Z" },
- { url = "https://files.pythonhosted.org/packages/42/56/3fe0fb34820ff667be791b3a3c22b85e8bcba54e9c832f47438c191fa7be/rpds_py-2026.5.1-pp311-pypy311_pp73-macosx_10_12_x86_64.whl", hash = "sha256:edf2765d84e42447f112ad877af8fe1db0089aaec5b28e88d6eab45e7fe99cea", size = 357151, upload-time = "2026-05-28T12:01:53.43Z" },
- { url = "https://files.pythonhosted.org/packages/8b/f2/3eb9ccdb9f143b8c9b003978898cb497f942a324c077401e6b8834238e63/rpds_py-2026.5.1-pp311-pypy311_pp73-macosx_11_0_arm64.whl", hash = "sha256:ad3773236e95f7f33991eb125224b7da66f206504d032a253a02da7e134519fb", size = 350195, upload-time = "2026-05-28T12:01:54.901Z" },
- { url = "https://files.pythonhosted.org/packages/a7/24/dbda232bc4f3ed732120692ab0d2c8402cb020516556d8bee622dcef2413/rpds_py-2026.5.1-pp311-pypy311_pp73-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:a04df86b3f0fade39ec8fd0e0aab089b1da9fbd2b48df778a57ef96f5e7d38df", size = 381850, upload-time = "2026-05-28T12:01:56.601Z" },
- { url = "https://files.pythonhosted.org/packages/40/30/32e769839a358f78810c234f160f2cc21d1e4e47e1c0e0e0d535be5a0219/rpds_py-2026.5.1-pp311-pypy311_pp73-manylinux_2_17_armv7l.manylinux2014_armv7l.whl", hash = "sha256:6142dbd80c4df62a5d899f0d616d417f84e0bc8d32526c8e5589019d75d028a7", size = 387899, upload-time = "2026-05-28T12:01:58.212Z" },
- { url = "https://files.pythonhosted.org/packages/ab/86/ec84d243aadb3b34b71dd26a010d0930b2d284ff5fc9a69fec53810ee6fd/rpds_py-2026.5.1-pp311-pypy311_pp73-manylinux_2_17_ppc64le.manylinux2014_ppc64le.whl", hash = "sha256:0b35217adefe87f2fe4db7e9766cabe84744bfe9616d9667be18988928c7f2dc", size = 501618, upload-time = "2026-05-28T12:01:59.888Z" },
- { url = "https://files.pythonhosted.org/packages/74/25/b60e52686bbff777a64f9e4f4d3dd57980dc846913777177a2c92e4937aa/rpds_py-2026.5.1-pp311-pypy311_pp73-manylinux_2_17_s390x.manylinux2014_s390x.whl", hash = "sha256:b95d5e11fc712b752081183a55a244c03cd00570489edd7014d8899f8ceb8162", size = 394003, upload-time = "2026-05-28T12:02:01.482Z" },
- { url = "https://files.pythonhosted.org/packages/9b/c7/b3a6a588cc2219510ef3f42e207483a93950bedd1e3a0fd4015c95cff9e5/rpds_py-2026.5.1-pp311-pypy311_pp73-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:141c9498daf2ace9eda35d2b0e376f9ea8b058d84f2aef4f96fccfd449a2f251", size = 379778, upload-time = "2026-05-28T12:02:03.197Z" },
- { url = "https://files.pythonhosted.org/packages/31/00/c7dba3fc8a3da8cb3f6db1eb3386be4d79c2e97c6890d20eb9ac66ae8c43/rpds_py-2026.5.1-pp311-pypy311_pp73-manylinux_2_31_riscv64.whl", hash = "sha256:6f249f8b860a200ad35193af961183ebe9132710484e6f6ce0cf89fd83c63a9a", size = 392359, upload-time = "2026-05-28T12:02:04.817Z" },
- { url = "https://files.pythonhosted.org/packages/93/dd/472ba494c70753f93745992c99855bee0636daf74e6984e5e003f150316f/rpds_py-2026.5.1-pp311-pypy311_pp73-manylinux_2_5_i686.manylinux1_i686.whl", hash = "sha256:e4abbf391a70be864920858bf360f4fb380577c9a0f732438a1996726e2c195b", size = 412820, upload-time = "2026-05-28T12:02:06.401Z" },
- { url = "https://files.pythonhosted.org/packages/1d/6f/93831a3bfe789542ed0c1d0d74b78b440f055d6dc3ea4640eba2d95e6e23/rpds_py-2026.5.1-pp311-pypy311_pp73-musllinux_1_2_aarch64.whl", hash = "sha256:c74005a7bb87752acf351c93897ec63ad77a07a0da7ecad9c050e32e7286ba34", size = 557243, upload-time = "2026-05-28T12:02:08.013Z" },
- { url = "https://files.pythonhosted.org/packages/1f/ff/0b3d604614ffc77522c6b288fdbce68957eb583da1002aa65ba38ac0ee40/rpds_py-2026.5.1-pp311-pypy311_pp73-musllinux_1_2_i686.whl", hash = "sha256:8213afbe8a3a906fb9acb2014423fe3359ee783d0bf90995f70623a3217bfa6c", size = 623541, upload-time = "2026-05-28T12:02:09.661Z" },
- { url = "https://files.pythonhosted.org/packages/ea/ea/e7b0251441da9adfeaebcf29601d10f2a1455fcf0772fae9e7e19032bd96/rpds_py-2026.5.1-pp311-pypy311_pp73-musllinux_1_2_x86_64.whl", hash = "sha256:8c43a8a973270fd173bf48cdf80bbe66312421cba68d40845034f174f2389049", size = 586326, upload-time = "2026-05-28T12:02:11.47Z" },
-]
-
-[[package]]
-name = "schedule"
-version = "1.2.2"
-source = { registry = "https://pypi.org/simple" }
-sdist = { url = "https://files.pythonhosted.org/packages/0c/91/b525790063015759f34447d4cf9d2ccb52cdee0f1dd6ff8764e863bcb74c/schedule-1.2.2.tar.gz", hash = "sha256:15fe9c75fe5fd9b9627f3f19cc0ef1420508f9f9a46f45cd0769ef75ede5f0b7", size = 26452, upload-time = "2024-06-18T20:03:14.633Z" }
-wheels = [
- { url = "https://files.pythonhosted.org/packages/20/a7/84c96b61fd13205f2cafbe263cdb2745965974bdf3e0078f121dfeca5f02/schedule-1.2.2-py3-none-any.whl", hash = "sha256:5bef4a2a0183abf44046ae0d164cadcac21b1db011bdd8102e4a0c1e91e06a7d", size = 12220, upload-time = "2024-05-25T18:41:59.121Z" },
-]
-
-[[package]]
-name = "scikit-learn"
-version = "1.5.2"
-source = { registry = "https://pypi.org/simple" }
-dependencies = [
- { name = "joblib" },
- { name = "numpy" },
- { name = "scipy" },
- { name = "threadpoolctl" },
-]
-sdist = { url = "https://files.pythonhosted.org/packages/37/59/44985a2bdc95c74e34fef3d10cb5d93ce13b0e2a7baefffe1b53853b502d/scikit_learn-1.5.2.tar.gz", hash = "sha256:b4237ed7b3fdd0a4882792e68ef2545d5baa50aca3bb45aa7df468138ad8f94d", size = 7001680, upload-time = "2024-09-11T15:50:10.957Z" }
-wheels = [
- { url = "https://files.pythonhosted.org/packages/98/89/be41419b4bec629a4691183a5eb1796f91252a13a5ffa243fd958cad7e91/scikit_learn-1.5.2-cp310-cp310-macosx_10_9_x86_64.whl", hash = "sha256:299406827fb9a4f862626d0fe6c122f5f87f8910b86fe5daa4c32dcd742139b6", size = 12106070, upload-time = "2024-09-11T15:49:19.633Z" },
- { url = "https://files.pythonhosted.org/packages/bf/e0/3b6d777d375f3b685f433c93384cdb724fb078e1dc8f8ff0950467e56c30/scikit_learn-1.5.2-cp310-cp310-macosx_12_0_arm64.whl", hash = "sha256:2d4cad1119c77930b235579ad0dc25e65c917e756fe80cab96aa3b9428bd3fb0", size = 10971758, upload-time = "2024-09-11T15:49:22.484Z" },
- { url = "https://files.pythonhosted.org/packages/7b/31/eb7dd56c371640753953277de11356c46a3149bfeebb3d7dcd90b993715a/scikit_learn-1.5.2-cp310-cp310-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:8c412ccc2ad9bf3755915e3908e677b367ebc8d010acbb3f182814524f2e5540", size = 12500080, upload-time = "2024-09-11T15:49:24.975Z" },
- { url = "https://files.pythonhosted.org/packages/4c/1e/a7c7357e704459c7d56a18df4a0bf08669442d1f8878cc0864beccd6306a/scikit_learn-1.5.2-cp310-cp310-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:3a686885a4b3818d9e62904d91b57fa757fc2bed3e465c8b177be652f4dd37c8", size = 13347241, upload-time = "2024-09-11T15:49:27.891Z" },
- { url = "https://files.pythonhosted.org/packages/48/76/154ebda6794faf0b0f3ccb1b5cd9a19f0a63cb9e1f3d2c61b6114002677b/scikit_learn-1.5.2-cp310-cp310-win_amd64.whl", hash = "sha256:c15b1ca23d7c5f33cc2cb0a0d6aaacf893792271cddff0edbd6a40e8319bc113", size = 11000477, upload-time = "2024-09-11T15:49:30.693Z" },
- { url = "https://files.pythonhosted.org/packages/ff/91/609961972f694cb9520c4c3d201e377a26583e1eb83bc5a334c893729214/scikit_learn-1.5.2-cp311-cp311-macosx_10_9_x86_64.whl", hash = "sha256:03b6158efa3faaf1feea3faa884c840ebd61b6484167c711548fce208ea09445", size = 12088580, upload-time = "2024-09-11T15:49:33.55Z" },
- { url = "https://files.pythonhosted.org/packages/cd/7a/19fe32c810c5ceddafcfda16276d98df299c8649e24e84d4f00df4a91e01/scikit_learn-1.5.2-cp311-cp311-macosx_12_0_arm64.whl", hash = "sha256:1ff45e26928d3b4eb767a8f14a9a6efbf1cbff7c05d1fb0f95f211a89fd4f5de", size = 10975994, upload-time = "2024-09-11T15:49:35.728Z" },
- { url = "https://files.pythonhosted.org/packages/4c/75/62e49f8a62bf3c60b0e64d0fce540578ee4f0e752765beb2e1dc7c6d6098/scikit_learn-1.5.2-cp311-cp311-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:f763897fe92d0e903aa4847b0aec0e68cadfff77e8a0687cabd946c89d17e675", size = 12465782, upload-time = "2024-09-11T15:49:38.596Z" },
- { url = "https://files.pythonhosted.org/packages/49/21/3723de321531c9745e40f1badafd821e029d346155b6c79704e0b7197552/scikit_learn-1.5.2-cp311-cp311-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:f8b0ccd4a902836493e026c03256e8b206656f91fbcc4fde28c57a5b752561f1", size = 13322034, upload-time = "2024-09-11T15:49:41.452Z" },
- { url = "https://files.pythonhosted.org/packages/17/1c/ccdd103cfcc9435a18819856fbbe0c20b8fa60bfc3343580de4be13f0668/scikit_learn-1.5.2-cp311-cp311-win_amd64.whl", hash = "sha256:6c16d84a0d45e4894832b3c4d0bf73050939e21b99b01b6fd59cbb0cf39163b6", size = 11015224, upload-time = "2024-09-11T15:49:43.692Z" },
- { url = "https://files.pythonhosted.org/packages/a4/db/b485c1ac54ff3bd9e7e6b39d3cc6609c4c76a65f52ab0a7b22b6c3ab0e9d/scikit_learn-1.5.2-cp312-cp312-macosx_10_9_x86_64.whl", hash = "sha256:f932a02c3f4956dfb981391ab24bda1dbd90fe3d628e4b42caef3e041c67707a", size = 12110344, upload-time = "2024-09-11T15:49:46.253Z" },
- { url = "https://files.pythonhosted.org/packages/54/1a/7deb52fa23aebb855431ad659b3c6a2e1709ece582cb3a63d66905e735fe/scikit_learn-1.5.2-cp312-cp312-macosx_12_0_arm64.whl", hash = "sha256:3b923d119d65b7bd555c73be5423bf06c0105678ce7e1f558cb4b40b0a5502b1", size = 11033502, upload-time = "2024-09-11T15:49:48.656Z" },
- { url = "https://files.pythonhosted.org/packages/a1/32/4a7a205b14c11225609b75b28402c196e4396ac754dab6a81971b811781c/scikit_learn-1.5.2-cp312-cp312-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:f60021ec1574e56632be2a36b946f8143bf4e5e6af4a06d85281adc22938e0dd", size = 12085794, upload-time = "2024-09-11T15:49:51.388Z" },
- { url = "https://files.pythonhosted.org/packages/c6/29/044048c5e911373827c0e1d3051321b9183b2a4f8d4e2f11c08fcff83f13/scikit_learn-1.5.2-cp312-cp312-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:394397841449853c2290a32050382edaec3da89e35b3e03d6cc966aebc6a8ae6", size = 12945797, upload-time = "2024-09-11T15:49:53.579Z" },
- { url = "https://files.pythonhosted.org/packages/aa/ce/c0b912f2f31aeb1b756a6ba56bcd84dd1f8a148470526a48515a3f4d48cd/scikit_learn-1.5.2-cp312-cp312-win_amd64.whl", hash = "sha256:57cc1786cfd6bd118220a92ede80270132aa353647684efa385a74244a41e3b1", size = 10985467, upload-time = "2024-09-11T15:49:56.446Z" },
- { url = "https://files.pythonhosted.org/packages/a4/50/8891028437858cc510e13578fe7046574a60c2aaaa92b02d64aac5b1b412/scikit_learn-1.5.2-cp313-cp313-macosx_10_13_x86_64.whl", hash = "sha256:e9a702e2de732bbb20d3bad29ebd77fc05a6b427dc49964300340e4c9328b3f5", size = 12025584, upload-time = "2024-10-02T18:35:29.369Z" },
- { url = "https://files.pythonhosted.org/packages/d2/79/17feef8a1c14149436083bec0e61d7befb4812e272d5b20f9d79ea3e9ab1/scikit_learn-1.5.2-cp313-cp313-macosx_12_0_arm64.whl", hash = "sha256:b0768ad641981f5d3a198430a1d31c3e044ed2e8a6f22166b4d546a5116d7908", size = 10959795, upload-time = "2024-10-02T18:35:34.22Z" },
- { url = "https://files.pythonhosted.org/packages/b1/c8/f08313f9e2e656bd0905930ae8bf99a573ea21c34666a813b749c338202f/scikit_learn-1.5.2-cp313-cp313-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:178ddd0a5cb0044464fc1bfc4cca5b1833bfc7bb022d70b05db8530da4bb3dd3", size = 12077302, upload-time = "2024-10-02T18:35:38.911Z" },
- { url = "https://files.pythonhosted.org/packages/a7/48/fbfb4dc72bed0fe31fe045fb30e924909ad03f717c36694351612973b1a9/scikit_learn-1.5.2-cp313-cp313-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:f7284ade780084d94505632241bf78c44ab3b6f1e8ccab3d2af58e0e950f9c12", size = 13002811, upload-time = "2024-10-02T18:35:43.28Z" },
- { url = "https://files.pythonhosted.org/packages/a5/e7/0c869f9e60d225a77af90d2aefa7a4a4c0e745b149325d1450f0f0ce5399/scikit_learn-1.5.2-cp313-cp313-win_amd64.whl", hash = "sha256:b7b0f9a0b1040830d38c39b91b3a44e1b643f4b36e36567b80b7c6bd2202a27f", size = 10951354, upload-time = "2024-10-02T18:35:47.954Z" },
-]
-
-[[package]]
-name = "scipy"
-version = "1.15.2"
-source = { registry = "https://pypi.org/simple" }
-dependencies = [
- { name = "numpy" },
-]
-sdist = { url = "https://files.pythonhosted.org/packages/b7/b9/31ba9cd990e626574baf93fbc1ac61cf9ed54faafd04c479117517661637/scipy-1.15.2.tar.gz", hash = "sha256:cd58a314d92838f7e6f755c8a2167ead4f27e1fd5c1251fd54289569ef3495ec", size = 59417316, upload-time = "2025-02-17T00:42:24.791Z" }
-wheels = [
- { url = "https://files.pythonhosted.org/packages/95/df/ef233fff6838fe6f7840d69b5ef9f20d2b5c912a8727b21ebf876cb15d54/scipy-1.15.2-cp310-cp310-macosx_10_13_x86_64.whl", hash = "sha256:a2ec871edaa863e8213ea5df811cd600734f6400b4af272e1c011e69401218e9", size = 38692502, upload-time = "2025-02-17T00:28:56.118Z" },
- { url = "https://files.pythonhosted.org/packages/5c/20/acdd4efb8a68b842968f7bc5611b1aeb819794508771ad104de418701422/scipy-1.15.2-cp310-cp310-macosx_12_0_arm64.whl", hash = "sha256:6f223753c6ea76983af380787611ae1291e3ceb23917393079dcc746ba60cfb5", size = 30085508, upload-time = "2025-02-17T00:29:06.048Z" },
- { url = "https://files.pythonhosted.org/packages/42/55/39cf96ca7126f1e78ee72a6344ebdc6702fc47d037319ad93221063e6cf4/scipy-1.15.2-cp310-cp310-macosx_14_0_arm64.whl", hash = "sha256:ecf797d2d798cf7c838c6d98321061eb3e72a74710e6c40540f0e8087e3b499e", size = 22359166, upload-time = "2025-02-17T00:29:13.553Z" },
- { url = "https://files.pythonhosted.org/packages/51/48/708d26a4ab8a1441536bf2dfcad1df0ca14a69f010fba3ccbdfc02df7185/scipy-1.15.2-cp310-cp310-macosx_14_0_x86_64.whl", hash = "sha256:9b18aa747da280664642997e65aab1dd19d0c3d17068a04b3fe34e2559196cb9", size = 25112047, upload-time = "2025-02-17T00:29:23.204Z" },
- { url = "https://files.pythonhosted.org/packages/dd/65/f9c5755b995ad892020381b8ae11f16d18616208e388621dfacc11df6de6/scipy-1.15.2-cp310-cp310-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:87994da02e73549dfecaed9e09a4f9d58a045a053865679aeb8d6d43747d4df3", size = 35536214, upload-time = "2025-02-17T00:29:33.215Z" },
- { url = "https://files.pythonhosted.org/packages/de/3c/c96d904b9892beec978562f64d8cc43f9cca0842e65bd3cd1b7f7389b0ba/scipy-1.15.2-cp310-cp310-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:69ea6e56d00977f355c0f84eba69877b6df084516c602d93a33812aa04d90a3d", size = 37646981, upload-time = "2025-02-17T00:29:46.188Z" },
- { url = "https://files.pythonhosted.org/packages/3d/74/c2d8a24d18acdeae69ed02e132b9bc1bb67b7bee90feee1afe05a68f9d67/scipy-1.15.2-cp310-cp310-musllinux_1_2_aarch64.whl", hash = "sha256:888307125ea0c4466287191e5606a2c910963405ce9671448ff9c81c53f85f58", size = 37230048, upload-time = "2025-02-17T00:29:56.646Z" },
- { url = "https://files.pythonhosted.org/packages/42/19/0aa4ce80eca82d487987eff0bc754f014dec10d20de2f66754fa4ea70204/scipy-1.15.2-cp310-cp310-musllinux_1_2_x86_64.whl", hash = "sha256:9412f5e408b397ff5641080ed1e798623dbe1ec0d78e72c9eca8992976fa65aa", size = 40010322, upload-time = "2025-02-17T00:30:07.422Z" },
- { url = "https://files.pythonhosted.org/packages/d0/d2/f0683b7e992be44d1475cc144d1f1eeae63c73a14f862974b4db64af635e/scipy-1.15.2-cp310-cp310-win_amd64.whl", hash = "sha256:b5e025e903b4f166ea03b109bb241355b9c42c279ea694d8864d033727205e65", size = 41233385, upload-time = "2025-02-17T00:30:20.268Z" },
- { url = "https://files.pythonhosted.org/packages/40/1f/bf0a5f338bda7c35c08b4ed0df797e7bafe8a78a97275e9f439aceb46193/scipy-1.15.2-cp311-cp311-macosx_10_13_x86_64.whl", hash = "sha256:92233b2df6938147be6fa8824b8136f29a18f016ecde986666be5f4d686a91a4", size = 38703651, upload-time = "2025-02-17T00:30:31.09Z" },
- { url = "https://files.pythonhosted.org/packages/de/54/db126aad3874601048c2c20ae3d8a433dbfd7ba8381551e6f62606d9bd8e/scipy-1.15.2-cp311-cp311-macosx_12_0_arm64.whl", hash = "sha256:62ca1ff3eb513e09ed17a5736929429189adf16d2d740f44e53270cc800ecff1", size = 30102038, upload-time = "2025-02-17T00:30:40.219Z" },
- { url = "https://files.pythonhosted.org/packages/61/d8/84da3fffefb6c7d5a16968fe5b9f24c98606b165bb801bb0b8bc3985200f/scipy-1.15.2-cp311-cp311-macosx_14_0_arm64.whl", hash = "sha256:4c6676490ad76d1c2894d77f976144b41bd1a4052107902238047fb6a473e971", size = 22375518, upload-time = "2025-02-17T00:30:47.547Z" },
- { url = "https://files.pythonhosted.org/packages/44/78/25535a6e63d3b9c4c90147371aedb5d04c72f3aee3a34451f2dc27c0c07f/scipy-1.15.2-cp311-cp311-macosx_14_0_x86_64.whl", hash = "sha256:a8bf5cb4a25046ac61d38f8d3c3426ec11ebc350246a4642f2f315fe95bda655", size = 25142523, upload-time = "2025-02-17T00:30:56.002Z" },
- { url = "https://files.pythonhosted.org/packages/e0/22/4b4a26fe1cd9ed0bc2b2cb87b17d57e32ab72c346949eaf9288001f8aa8e/scipy-1.15.2-cp311-cp311-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:6a8e34cf4c188b6dd004654f88586d78f95639e48a25dfae9c5e34a6dc34547e", size = 35491547, upload-time = "2025-02-17T00:31:07.599Z" },
- { url = "https://files.pythonhosted.org/packages/32/ea/564bacc26b676c06a00266a3f25fdfe91a9d9a2532ccea7ce6dd394541bc/scipy-1.15.2-cp311-cp311-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:28a0d2c2075946346e4408b211240764759e0fabaeb08d871639b5f3b1aca8a0", size = 37634077, upload-time = "2025-02-17T00:31:15.191Z" },
- { url = "https://files.pythonhosted.org/packages/43/c2/bfd4e60668897a303b0ffb7191e965a5da4056f0d98acfb6ba529678f0fb/scipy-1.15.2-cp311-cp311-musllinux_1_2_aarch64.whl", hash = "sha256:42dabaaa798e987c425ed76062794e93a243be8f0f20fff6e7a89f4d61cb3d40", size = 37231657, upload-time = "2025-02-17T00:31:22.041Z" },
- { url = "https://files.pythonhosted.org/packages/4a/75/5f13050bf4f84c931bcab4f4e83c212a36876c3c2244475db34e4b5fe1a6/scipy-1.15.2-cp311-cp311-musllinux_1_2_x86_64.whl", hash = "sha256:6f5e296ec63c5da6ba6fa0343ea73fd51b8b3e1a300b0a8cae3ed4b1122c7462", size = 40035857, upload-time = "2025-02-17T00:31:29.836Z" },
- { url = "https://files.pythonhosted.org/packages/b9/8b/7ec1832b09dbc88f3db411f8cdd47db04505c4b72c99b11c920a8f0479c3/scipy-1.15.2-cp311-cp311-win_amd64.whl", hash = "sha256:597a0c7008b21c035831c39927406c6181bcf8f60a73f36219b69d010aa04737", size = 41217654, upload-time = "2025-02-17T00:31:43.65Z" },
- { url = "https://files.pythonhosted.org/packages/4b/5d/3c78815cbab499610f26b5bae6aed33e227225a9fa5290008a733a64f6fc/scipy-1.15.2-cp312-cp312-macosx_10_13_x86_64.whl", hash = "sha256:c4697a10da8f8765bb7c83e24a470da5797e37041edfd77fd95ba3811a47c4fd", size = 38756184, upload-time = "2025-02-17T00:31:50.623Z" },
- { url = "https://files.pythonhosted.org/packages/37/20/3d04eb066b471b6e171827548b9ddb3c21c6bbea72a4d84fc5989933910b/scipy-1.15.2-cp312-cp312-macosx_12_0_arm64.whl", hash = "sha256:869269b767d5ee7ea6991ed7e22b3ca1f22de73ab9a49c44bad338b725603301", size = 30163558, upload-time = "2025-02-17T00:31:56.721Z" },
- { url = "https://files.pythonhosted.org/packages/a4/98/e5c964526c929ef1f795d4c343b2ff98634ad2051bd2bbadfef9e772e413/scipy-1.15.2-cp312-cp312-macosx_14_0_arm64.whl", hash = "sha256:bad78d580270a4d32470563ea86c6590b465cb98f83d760ff5b0990cb5518a93", size = 22437211, upload-time = "2025-02-17T00:32:03.042Z" },
- { url = "https://files.pythonhosted.org/packages/1d/cd/1dc7371e29195ecbf5222f9afeedb210e0a75057d8afbd942aa6cf8c8eca/scipy-1.15.2-cp312-cp312-macosx_14_0_x86_64.whl", hash = "sha256:b09ae80010f52efddb15551025f9016c910296cf70adbf03ce2a8704f3a5ad20", size = 25232260, upload-time = "2025-02-17T00:32:07.847Z" },
- { url = "https://files.pythonhosted.org/packages/f0/24/1a181a9e5050090e0b5138c5f496fee33293c342b788d02586bc410c6477/scipy-1.15.2-cp312-cp312-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:5a6fd6eac1ce74a9f77a7fc724080d507c5812d61e72bd5e4c489b042455865e", size = 35198095, upload-time = "2025-02-17T00:32:14.565Z" },
- { url = "https://files.pythonhosted.org/packages/c0/53/eaada1a414c026673eb983f8b4a55fe5eb172725d33d62c1b21f63ff6ca4/scipy-1.15.2-cp312-cp312-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:2b871df1fe1a3ba85d90e22742b93584f8d2b8e6124f8372ab15c71b73e428b8", size = 37297371, upload-time = "2025-02-17T00:32:21.411Z" },
- { url = "https://files.pythonhosted.org/packages/e9/06/0449b744892ed22b7e7b9a1994a866e64895363572677a316a9042af1fe5/scipy-1.15.2-cp312-cp312-musllinux_1_2_aarch64.whl", hash = "sha256:03205d57a28e18dfd39f0377d5002725bf1f19a46f444108c29bdb246b6c8a11", size = 36872390, upload-time = "2025-02-17T00:32:29.421Z" },
- { url = "https://files.pythonhosted.org/packages/6a/6f/a8ac3cfd9505ec695c1bc35edc034d13afbd2fc1882a7c6b473e280397bb/scipy-1.15.2-cp312-cp312-musllinux_1_2_x86_64.whl", hash = "sha256:601881dfb761311045b03114c5fe718a12634e5608c3b403737ae463c9885d53", size = 39700276, upload-time = "2025-02-17T00:32:37.431Z" },
- { url = "https://files.pythonhosted.org/packages/f5/6f/e6e5aff77ea2a48dd96808bb51d7450875af154ee7cbe72188afb0b37929/scipy-1.15.2-cp312-cp312-win_amd64.whl", hash = "sha256:e7c68b6a43259ba0aab737237876e5c2c549a031ddb7abc28c7b47f22e202ded", size = 40942317, upload-time = "2025-02-17T00:32:45.47Z" },
- { url = "https://files.pythonhosted.org/packages/53/40/09319f6e0f276ea2754196185f95cd191cb852288440ce035d5c3a931ea2/scipy-1.15.2-cp313-cp313-macosx_10_13_x86_64.whl", hash = "sha256:01edfac9f0798ad6b46d9c4c9ca0e0ad23dbf0b1eb70e96adb9fa7f525eff0bf", size = 38717587, upload-time = "2025-02-17T00:32:53.196Z" },
- { url = "https://files.pythonhosted.org/packages/fe/c3/2854f40ecd19585d65afaef601e5e1f8dbf6758b2f95b5ea93d38655a2c6/scipy-1.15.2-cp313-cp313-macosx_12_0_arm64.whl", hash = "sha256:08b57a9336b8e79b305a143c3655cc5bdbe6d5ece3378578888d2afbb51c4e37", size = 30100266, upload-time = "2025-02-17T00:32:59.318Z" },
- { url = "https://files.pythonhosted.org/packages/dd/b1/f9fe6e3c828cb5930b5fe74cb479de5f3d66d682fa8adb77249acaf545b8/scipy-1.15.2-cp313-cp313-macosx_14_0_arm64.whl", hash = "sha256:54c462098484e7466362a9f1672d20888f724911a74c22ae35b61f9c5919183d", size = 22373768, upload-time = "2025-02-17T00:33:04.091Z" },
- { url = "https://files.pythonhosted.org/packages/15/9d/a60db8c795700414c3f681908a2b911e031e024d93214f2d23c6dae174ab/scipy-1.15.2-cp313-cp313-macosx_14_0_x86_64.whl", hash = "sha256:cf72ff559a53a6a6d77bd8eefd12a17995ffa44ad86c77a5df96f533d4e6c6bb", size = 25154719, upload-time = "2025-02-17T00:33:08.909Z" },
- { url = "https://files.pythonhosted.org/packages/37/3b/9bda92a85cd93f19f9ed90ade84aa1e51657e29988317fabdd44544f1dd4/scipy-1.15.2-cp313-cp313-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:9de9d1416b3d9e7df9923ab23cd2fe714244af10b763975bea9e4f2e81cebd27", size = 35163195, upload-time = "2025-02-17T00:33:15.352Z" },
- { url = "https://files.pythonhosted.org/packages/03/5a/fc34bf1aa14dc7c0e701691fa8685f3faec80e57d816615e3625f28feb43/scipy-1.15.2-cp313-cp313-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:fb530e4794fc8ea76a4a21ccb67dea33e5e0e60f07fc38a49e821e1eae3b71a0", size = 37255404, upload-time = "2025-02-17T00:33:22.21Z" },
- { url = "https://files.pythonhosted.org/packages/4a/71/472eac45440cee134c8a180dbe4c01b3ec247e0338b7c759e6cd71f199a7/scipy-1.15.2-cp313-cp313-musllinux_1_2_aarch64.whl", hash = "sha256:5ea7ed46d437fc52350b028b1d44e002646e28f3e8ddc714011aaf87330f2f32", size = 36860011, upload-time = "2025-02-17T00:33:29.446Z" },
- { url = "https://files.pythonhosted.org/packages/01/b3/21f890f4f42daf20e4d3aaa18182dddb9192771cd47445aaae2e318f6738/scipy-1.15.2-cp313-cp313-musllinux_1_2_x86_64.whl", hash = "sha256:11e7ad32cf184b74380f43d3c0a706f49358b904fa7d5345f16ddf993609184d", size = 39657406, upload-time = "2025-02-17T00:33:39.019Z" },
- { url = "https://files.pythonhosted.org/packages/0d/76/77cf2ac1f2a9cc00c073d49e1e16244e389dd88e2490c91d84e1e3e4d126/scipy-1.15.2-cp313-cp313-win_amd64.whl", hash = "sha256:a5080a79dfb9b78b768cebf3c9dcbc7b665c5875793569f48bf0e2b1d7f68f6f", size = 40961243, upload-time = "2025-02-17T00:34:51.024Z" },
- { url = "https://files.pythonhosted.org/packages/4c/4b/a57f8ddcf48e129e6054fa9899a2a86d1fc6b07a0e15c7eebff7ca94533f/scipy-1.15.2-cp313-cp313t-macosx_10_13_x86_64.whl", hash = "sha256:447ce30cee6a9d5d1379087c9e474628dab3db4a67484be1b7dc3196bfb2fac9", size = 38870286, upload-time = "2025-02-17T00:33:47.62Z" },
- { url = "https://files.pythonhosted.org/packages/0c/43/c304d69a56c91ad5f188c0714f6a97b9c1fed93128c691148621274a3a68/scipy-1.15.2-cp313-cp313t-macosx_12_0_arm64.whl", hash = "sha256:c90ebe8aaa4397eaefa8455a8182b164a6cc1d59ad53f79943f266d99f68687f", size = 30141634, upload-time = "2025-02-17T00:33:54.131Z" },
- { url = "https://files.pythonhosted.org/packages/44/1a/6c21b45d2548eb73be9b9bff421aaaa7e85e22c1f9b3bc44b23485dfce0a/scipy-1.15.2-cp313-cp313t-macosx_14_0_arm64.whl", hash = "sha256:def751dd08243934c884a3221156d63e15234a3155cf25978b0a668409d45eb6", size = 22415179, upload-time = "2025-02-17T00:33:59.948Z" },
- { url = "https://files.pythonhosted.org/packages/74/4b/aefac4bba80ef815b64f55da06f62f92be5d03b467f2ce3668071799429a/scipy-1.15.2-cp313-cp313t-macosx_14_0_x86_64.whl", hash = "sha256:302093e7dfb120e55515936cb55618ee0b895f8bcaf18ff81eca086c17bd80af", size = 25126412, upload-time = "2025-02-17T00:34:06.328Z" },
- { url = "https://files.pythonhosted.org/packages/b1/53/1cbb148e6e8f1660aacd9f0a9dfa2b05e9ff1cb54b4386fe868477972ac2/scipy-1.15.2-cp313-cp313t-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:7cd5b77413e1855351cdde594eca99c1f4a588c2d63711388b6a1f1c01f62274", size = 34952867, upload-time = "2025-02-17T00:34:12.928Z" },
- { url = "https://files.pythonhosted.org/packages/2c/23/e0eb7f31a9c13cf2dca083828b97992dd22f8184c6ce4fec5deec0c81fcf/scipy-1.15.2-cp313-cp313t-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:6d0194c37037707b2afa7a2f2a924cf7bac3dc292d51b6a925e5fcb89bc5c776", size = 36890009, upload-time = "2025-02-17T00:34:19.55Z" },
- { url = "https://files.pythonhosted.org/packages/03/f3/e699e19cabe96bbac5189c04aaa970718f0105cff03d458dc5e2b6bd1e8c/scipy-1.15.2-cp313-cp313t-musllinux_1_2_aarch64.whl", hash = "sha256:bae43364d600fdc3ac327db99659dcb79e6e7ecd279a75fe1266669d9a652828", size = 36545159, upload-time = "2025-02-17T00:34:26.724Z" },
- { url = "https://files.pythonhosted.org/packages/af/f5/ab3838e56fe5cc22383d6fcf2336e48c8fe33e944b9037fbf6cbdf5a11f8/scipy-1.15.2-cp313-cp313t-musllinux_1_2_x86_64.whl", hash = "sha256:f031846580d9acccd0044efd1a90e6f4df3a6e12b4b6bd694a7bc03a89892b28", size = 39136566, upload-time = "2025-02-17T00:34:34.512Z" },
- { url = "https://files.pythonhosted.org/packages/0a/c8/b3f566db71461cabd4b2d5b39bcc24a7e1c119535c8361f81426be39bb47/scipy-1.15.2-cp313-cp313t-win_amd64.whl", hash = "sha256:fe8a9eb875d430d81755472c5ba75e84acc980e4a8f6204d402849234d3017db", size = 40477705, upload-time = "2025-02-17T00:34:43.619Z" },
-]
-
[[package]]
name = "setuptools"
version = "78.1.0"
@@ -2132,85 +552,6 @@ wheels = [
{ url = "https://files.pythonhosted.org/packages/54/21/f43f0a1fa8b06b32812e0975981f4677d28e0f3271601dc88ac5a5b83220/setuptools-78.1.0-py3-none-any.whl", hash = "sha256:3e386e96793c8702ae83d17b853fb93d3e09ef82ec62722e61da5cd22376dcd8", size = 1256108, upload-time = "2025-03-25T22:49:33.13Z" },
]
-[[package]]
-name = "shellingham"
-version = "1.5.4"
-source = { registry = "https://pypi.org/simple" }
-sdist = { url = "https://files.pythonhosted.org/packages/58/15/8b3609fd3830ef7b27b655beb4b4e9c62313a4e8da8c676e142cc210d58e/shellingham-1.5.4.tar.gz", hash = "sha256:8dbca0739d487e5bd35ab3ca4b36e11c4078f3a234bfce294b0a0291363404de", size = 10310, upload-time = "2023-10-24T04:13:40.426Z" }
-wheels = [
- { url = "https://files.pythonhosted.org/packages/e0/f9/0595336914c5619e5f28a1fb793285925a8cd4b432c9da0a987836c7f822/shellingham-1.5.4-py2.py3-none-any.whl", hash = "sha256:7ecfff8f2fd72616f7481040475a65b2bf8af90a56c89140852d1120324e8686", size = 9755, upload-time = "2023-10-24T04:13:38.866Z" },
-]
-
-[[package]]
-name = "simplejson"
-version = "3.20.1"
-source = { registry = "https://pypi.org/simple" }
-sdist = { url = "https://files.pythonhosted.org/packages/af/92/51b417685abd96b31308b61b9acce7ec50d8e1de8fbc39a7fd4962c60689/simplejson-3.20.1.tar.gz", hash = "sha256:e64139b4ec4f1f24c142ff7dcafe55a22b811a74d86d66560c8815687143037d", size = 85591, upload-time = "2025-02-15T05:18:53.15Z" }
-wheels = [
- { url = "https://files.pythonhosted.org/packages/25/c4/627214fb418cd4a17fb0230ff0b6c3bb4a85cbb48dd69c85dcc3b85df828/simplejson-3.20.1-cp310-cp310-macosx_10_9_universal2.whl", hash = "sha256:e580aa65d5f6c3bf41b9b4afe74be5d5ddba9576701c107c772d936ea2b5043a", size = 93790, upload-time = "2025-02-15T05:15:32.954Z" },
- { url = "https://files.pythonhosted.org/packages/15/ca/56a6a2a33cbcf330c4d71af3f827c47e4e0ba791e78f2642f3d1ab02ff31/simplejson-3.20.1-cp310-cp310-macosx_10_9_x86_64.whl", hash = "sha256:4a586ce4f78cec11f22fe55c5bee0f067e803aab9bad3441afe2181693b5ebb5", size = 75707, upload-time = "2025-02-15T05:15:34.954Z" },
- { url = "https://files.pythonhosted.org/packages/a9/c8/3d92b67e03a3b6207d97202669f9454ed700b35ade9bd4428265a078fb6c/simplejson-3.20.1-cp310-cp310-macosx_11_0_arm64.whl", hash = "sha256:74a1608f9e6e8c27a4008d70a54270868306d80ed48c9df7872f9f4b8ac87808", size = 75700, upload-time = "2025-02-15T05:15:37.144Z" },
- { url = "https://files.pythonhosted.org/packages/74/30/20001219d6fdca4aaa3974c96dfb6955a766b4e2cc950505a5b51fd050b0/simplejson-3.20.1-cp310-cp310-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:03db8cb64154189a92a7786209f24e391644f3a3fa335658be2df2af1960b8d8", size = 138672, upload-time = "2025-02-15T05:15:38.547Z" },
- { url = "https://files.pythonhosted.org/packages/21/47/50157810876c2a7ebbd6e6346ec25eda841fe061fecaa02538a7742a3d2a/simplejson-3.20.1-cp310-cp310-manylinux_2_17_ppc64le.manylinux2014_ppc64le.whl", hash = "sha256:eea7e2b7d858f6fdfbf0fe3cb846d6bd8a45446865bc09960e51f3d473c2271b", size = 146616, upload-time = "2025-02-15T05:15:39.871Z" },
- { url = "https://files.pythonhosted.org/packages/95/60/8c97cdc93096437b0aca2745aca63c880fe2315fd7f6a6ce6edbb344a2ae/simplejson-3.20.1-cp310-cp310-manylinux_2_5_i686.manylinux1_i686.manylinux_2_17_i686.manylinux2014_i686.whl", hash = "sha256:e66712b17d8425bb7ff8968d4c7c7fd5a2dd7bd63728b28356223c000dd2f91f", size = 134344, upload-time = "2025-02-15T05:15:42.091Z" },
- { url = "https://files.pythonhosted.org/packages/bb/9e/da184f0e9bb3a5d7ffcde713bd41b4fe46cca56b6f24d9bd155fac56805a/simplejson-3.20.1-cp310-cp310-manylinux_2_5_x86_64.manylinux1_x86_64.manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:a2cc4f6486f9f515b62f5831ff1888886619b84fc837de68f26d919ba7bbdcbc", size = 138017, upload-time = "2025-02-15T05:15:43.542Z" },
- { url = "https://files.pythonhosted.org/packages/31/db/00d1a8d9b036db98f678c8a3c69ed17d2894d1768d7a00576e787ad3e546/simplejson-3.20.1-cp310-cp310-musllinux_1_2_aarch64.whl", hash = "sha256:a3c2df555ee4016148fa192e2b9cd9e60bc1d40769366134882685e90aee2a1e", size = 140118, upload-time = "2025-02-15T05:15:45.7Z" },
- { url = "https://files.pythonhosted.org/packages/52/21/57fc47eab8c1c73390b933a5ba9271f08e3e1ec83162c580357f28f5b97c/simplejson-3.20.1-cp310-cp310-musllinux_1_2_i686.whl", hash = "sha256:78520f04b7548a5e476b5396c0847e066f1e0a4c0c5e920da1ad65e95f410b11", size = 140314, upload-time = "2025-02-15T05:16:07.949Z" },
- { url = "https://files.pythonhosted.org/packages/ad/cc/7cfd78d1e0fa5e57350b98cfe77353b6dfa13dce21afa4060e1019223852/simplejson-3.20.1-cp310-cp310-musllinux_1_2_ppc64le.whl", hash = "sha256:f4bd49ecde87b0fe9f55cc971449a32832bca9910821f7072bbfae1155eaa007", size = 148544, upload-time = "2025-02-15T05:16:09.455Z" },
- { url = "https://files.pythonhosted.org/packages/63/26/1c894a1c2bd95dc8be0cf5a2fa73b0d173105b6ca18c90cb981ff10443d0/simplejson-3.20.1-cp310-cp310-musllinux_1_2_x86_64.whl", hash = "sha256:7eaae2b88eb5da53caaffdfa50e2e12022553949b88c0df4f9a9663609373f72", size = 141172, upload-time = "2025-02-15T05:16:10.966Z" },
- { url = "https://files.pythonhosted.org/packages/93/27/0717dccc10cd9988dbf1314def52ab32678a95a95328bb37cafacf499400/simplejson-3.20.1-cp310-cp310-win32.whl", hash = "sha256:e836fb88902799eac8debc2b642300748f4860a197fa3d9ea502112b6bb8e142", size = 74181, upload-time = "2025-02-15T05:16:12.361Z" },
- { url = "https://files.pythonhosted.org/packages/5f/af/593f896573f306519332d4287b1ab8b7b888c239bbd5159f7054d7055c2d/simplejson-3.20.1-cp310-cp310-win_amd64.whl", hash = "sha256:b122a19b552b212fc3b5b96fc5ce92333d4a9ac0a800803e1f17ebb16dac4be5", size = 75738, upload-time = "2025-02-15T05:16:14.438Z" },
- { url = "https://files.pythonhosted.org/packages/76/59/74bc90d1c051bc2432c96b34bd4e8036875ab58b4fcbe4d6a5a76985f853/simplejson-3.20.1-cp311-cp311-macosx_10_9_universal2.whl", hash = "sha256:325b8c107253d3217e89d7b50c71015b5b31e2433e6c5bf38967b2f80630a8ca", size = 92132, upload-time = "2025-02-15T05:16:15.743Z" },
- { url = "https://files.pythonhosted.org/packages/71/c7/1970916e0c51794fff89f76da2f632aaf0b259b87753c88a8c409623d3e1/simplejson-3.20.1-cp311-cp311-macosx_10_9_x86_64.whl", hash = "sha256:88a7baa8211089b9e58d78fbc1b0b322103f3f3d459ff16f03a36cece0d0fcf0", size = 74956, upload-time = "2025-02-15T05:16:17.062Z" },
- { url = "https://files.pythonhosted.org/packages/c8/0d/98cc5909180463f1d75fac7180de62d4cdb4e82c4fef276b9e591979372c/simplejson-3.20.1-cp311-cp311-macosx_11_0_arm64.whl", hash = "sha256:299b1007b8101d50d95bc0db1bf5c38dc372e85b504cf77f596462083ee77e3f", size = 74772, upload-time = "2025-02-15T05:16:19.204Z" },
- { url = "https://files.pythonhosted.org/packages/e1/94/a30a5211a90d67725a3e8fcc1c788189f2ae2ed2b96b63ed15d0b7f5d6bb/simplejson-3.20.1-cp311-cp311-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:03ec618ed65caab48e81e3ed29586236a8e57daef792f1f3bb59504a7e98cd10", size = 143575, upload-time = "2025-02-15T05:16:21.337Z" },
- { url = "https://files.pythonhosted.org/packages/ee/08/cdb6821f1058eb5db46d252de69ff7e6c53f05f1bae6368fe20d5b51d37e/simplejson-3.20.1-cp311-cp311-manylinux_2_17_ppc64le.manylinux2014_ppc64le.whl", hash = "sha256:cd2cdead1d3197f0ff43373cf4730213420523ba48697743e135e26f3d179f38", size = 153241, upload-time = "2025-02-15T05:16:22.859Z" },
- { url = "https://files.pythonhosted.org/packages/4c/2d/ca3caeea0bdc5efc5503d5f57a2dfb56804898fb196dfada121323ee0ccb/simplejson-3.20.1-cp311-cp311-manylinux_2_5_i686.manylinux1_i686.manylinux_2_17_i686.manylinux2014_i686.whl", hash = "sha256:3466d2839fdc83e1af42e07b90bc8ff361c4e8796cd66722a40ba14e458faddd", size = 141500, upload-time = "2025-02-15T05:16:25.068Z" },
- { url = "https://files.pythonhosted.org/packages/e1/33/d3e0779d5c58245e7370c98eb969275af6b7a4a5aec3b97cbf85f09ad328/simplejson-3.20.1-cp311-cp311-manylinux_2_5_x86_64.manylinux1_x86_64.manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:d492ed8e92f3a9f9be829205f44b1d0a89af6582f0cf43e0d129fa477b93fe0c", size = 144757, upload-time = "2025-02-15T05:16:28.301Z" },
- { url = "https://files.pythonhosted.org/packages/54/53/2d93128bb55861b2fa36c5944f38da51a0bc6d83e513afc6f7838440dd15/simplejson-3.20.1-cp311-cp311-musllinux_1_2_aarch64.whl", hash = "sha256:f924b485537b640dc69434565463fd6fc0c68c65a8c6e01a823dd26c9983cf79", size = 144409, upload-time = "2025-02-15T05:16:29.687Z" },
- { url = "https://files.pythonhosted.org/packages/99/4c/dac310a98f897ad3435b4bdc836d92e78f09e38c5dbf28211ed21dc59fa2/simplejson-3.20.1-cp311-cp311-musllinux_1_2_i686.whl", hash = "sha256:9e8eacf6a3491bf76ea91a8d46726368a6be0eb94993f60b8583550baae9439e", size = 146082, upload-time = "2025-02-15T05:16:31.064Z" },
- { url = "https://files.pythonhosted.org/packages/ee/22/d7ba958cfed39827335b82656b1c46f89678faecda9a7677b47e87b48ee6/simplejson-3.20.1-cp311-cp311-musllinux_1_2_ppc64le.whl", hash = "sha256:d34d04bf90b4cea7c22d8b19091633908f14a096caa301b24c2f3d85b5068fb8", size = 154339, upload-time = "2025-02-15T05:16:32.719Z" },
- { url = "https://files.pythonhosted.org/packages/b8/c8/b072b741129406a7086a0799c6f5d13096231bf35fdd87a0cffa789687fc/simplejson-3.20.1-cp311-cp311-musllinux_1_2_x86_64.whl", hash = "sha256:69dd28d4ce38390ea4aaf212902712c0fd1093dc4c1ff67e09687c3c3e15a749", size = 147915, upload-time = "2025-02-15T05:16:34.291Z" },
- { url = "https://files.pythonhosted.org/packages/6c/46/8347e61e9cf3db5342a42f7fd30a81b4f5cf85977f916852d7674a540907/simplejson-3.20.1-cp311-cp311-win32.whl", hash = "sha256:dfe7a9da5fd2a3499436cd350f31539e0a6ded5da6b5b3d422df016444d65e43", size = 73972, upload-time = "2025-02-15T05:16:35.712Z" },
- { url = "https://files.pythonhosted.org/packages/01/85/b52f24859237b4e9d523d5655796d911ba3d46e242eb1959c45b6af5aedd/simplejson-3.20.1-cp311-cp311-win_amd64.whl", hash = "sha256:896a6c04d7861d507d800da7642479c3547060bf97419d9ef73d98ced8258766", size = 75595, upload-time = "2025-02-15T05:16:36.957Z" },
- { url = "https://files.pythonhosted.org/packages/8d/eb/34c16a1ac9ba265d024dc977ad84e1659d931c0a700967c3e59a98ed7514/simplejson-3.20.1-cp312-cp312-macosx_10_9_universal2.whl", hash = "sha256:f31c4a3a7ab18467ee73a27f3e59158255d1520f3aad74315edde7a940f1be23", size = 93100, upload-time = "2025-02-15T05:16:38.801Z" },
- { url = "https://files.pythonhosted.org/packages/41/fc/2c2c007d135894971e6814e7c0806936e5bade28f8db4dd7e2a58b50debd/simplejson-3.20.1-cp312-cp312-macosx_10_9_x86_64.whl", hash = "sha256:884e6183d16b725e113b83a6fc0230152ab6627d4d36cb05c89c2c5bccfa7bc6", size = 75464, upload-time = "2025-02-15T05:16:40.905Z" },
- { url = "https://files.pythonhosted.org/packages/0f/05/2b5ecb33b776c34bb5cace5de5d7669f9b60e3ca13c113037b2ca86edfbd/simplejson-3.20.1-cp312-cp312-macosx_11_0_arm64.whl", hash = "sha256:03d7a426e416fe0d3337115f04164cd9427eb4256e843a6b8751cacf70abc832", size = 75112, upload-time = "2025-02-15T05:16:42.246Z" },
- { url = "https://files.pythonhosted.org/packages/fe/36/1f3609a2792f06cd4b71030485f78e91eb09cfd57bebf3116bf2980a8bac/simplejson-3.20.1-cp312-cp312-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:000602141d0bddfcff60ea6a6e97d5e10c9db6b17fd2d6c66199fa481b6214bb", size = 150182, upload-time = "2025-02-15T05:16:43.557Z" },
- { url = "https://files.pythonhosted.org/packages/2f/b0/053fbda38b8b602a77a4f7829def1b4f316cd8deb5440a6d3ee90790d2a4/simplejson-3.20.1-cp312-cp312-manylinux_2_17_ppc64le.manylinux2014_ppc64le.whl", hash = "sha256:af8377a8af78226e82e3a4349efdde59ffa421ae88be67e18cef915e4023a595", size = 158363, upload-time = "2025-02-15T05:16:45.748Z" },
- { url = "https://files.pythonhosted.org/packages/d1/4b/2eb84ae867539a80822e92f9be4a7200dffba609275faf99b24141839110/simplejson-3.20.1-cp312-cp312-manylinux_2_5_i686.manylinux1_i686.manylinux_2_17_i686.manylinux2014_i686.whl", hash = "sha256:15c7de4c88ab2fbcb8781a3b982ef883696736134e20b1210bca43fb42ff1acf", size = 148415, upload-time = "2025-02-15T05:16:47.861Z" },
- { url = "https://files.pythonhosted.org/packages/e0/bd/400b0bd372a5666addf2540c7358bfc3841b9ce5cdbc5cc4ad2f61627ad8/simplejson-3.20.1-cp312-cp312-manylinux_2_5_x86_64.manylinux1_x86_64.manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:455a882ff3f97d810709f7b620007d4e0aca8da71d06fc5c18ba11daf1c4df49", size = 152213, upload-time = "2025-02-15T05:16:49.25Z" },
- { url = "https://files.pythonhosted.org/packages/50/12/143f447bf6a827ee9472693768dc1a5eb96154f8feb140a88ce6973a3cfa/simplejson-3.20.1-cp312-cp312-musllinux_1_2_aarch64.whl", hash = "sha256:fc0f523ce923e7f38eb67804bc80e0a028c76d7868500aa3f59225574b5d0453", size = 150048, upload-time = "2025-02-15T05:16:51.5Z" },
- { url = "https://files.pythonhosted.org/packages/5e/ea/dd9b3e8e8ed710a66f24a22c16a907c9b539b6f5f45fd8586bd5c231444e/simplejson-3.20.1-cp312-cp312-musllinux_1_2_i686.whl", hash = "sha256:76461ec929282dde4a08061071a47281ad939d0202dc4e63cdd135844e162fbc", size = 151668, upload-time = "2025-02-15T05:16:53Z" },
- { url = "https://files.pythonhosted.org/packages/99/af/ee52a8045426a0c5b89d755a5a70cc821815ef3c333b56fbcad33c4435c0/simplejson-3.20.1-cp312-cp312-musllinux_1_2_ppc64le.whl", hash = "sha256:ab19c2da8c043607bde4d4ef3a6b633e668a7d2e3d56f40a476a74c5ea71949f", size = 158840, upload-time = "2025-02-15T05:16:54.851Z" },
- { url = "https://files.pythonhosted.org/packages/68/db/ab32869acea6b5de7d75fa0dac07a112ded795d41eaa7e66c7813b17be95/simplejson-3.20.1-cp312-cp312-musllinux_1_2_x86_64.whl", hash = "sha256:b2578bedaedf6294415197b267d4ef678fea336dd78ee2a6d2f4b028e9d07be3", size = 154212, upload-time = "2025-02-15T05:16:56.318Z" },
- { url = "https://files.pythonhosted.org/packages/fa/7a/e3132d454977d75a3bf9a6d541d730f76462ebf42a96fea2621498166f41/simplejson-3.20.1-cp312-cp312-win32.whl", hash = "sha256:339f407373325a36b7fd744b688ba5bae0666b5d340ec6d98aebc3014bf3d8ea", size = 74101, upload-time = "2025-02-15T05:16:57.746Z" },
- { url = "https://files.pythonhosted.org/packages/bc/5d/4e243e937fa3560107c69f6f7c2eed8589163f5ed14324e864871daa2dd9/simplejson-3.20.1-cp312-cp312-win_amd64.whl", hash = "sha256:627d4486a1ea7edf1f66bb044ace1ce6b4c1698acd1b05353c97ba4864ea2e17", size = 75736, upload-time = "2025-02-15T05:16:59.017Z" },
- { url = "https://files.pythonhosted.org/packages/c4/03/0f453a27877cb5a5fff16a975925f4119102cc8552f52536b9a98ef0431e/simplejson-3.20.1-cp313-cp313-macosx_10_13_universal2.whl", hash = "sha256:71e849e7ceb2178344998cbe5ade101f1b329460243c79c27fbfc51c0447a7c3", size = 93109, upload-time = "2025-02-15T05:17:00.377Z" },
- { url = "https://files.pythonhosted.org/packages/74/1f/a729f4026850cabeaff23e134646c3f455e86925d2533463420635ae54de/simplejson-3.20.1-cp313-cp313-macosx_10_13_x86_64.whl", hash = "sha256:b63fdbab29dc3868d6f009a59797cefaba315fd43cd32ddd998ee1da28e50e29", size = 75475, upload-time = "2025-02-15T05:17:02.544Z" },
- { url = "https://files.pythonhosted.org/packages/e2/14/50a2713fee8ff1f8d655b1a14f4a0f1c0c7246768a1b3b3d12964a4ed5aa/simplejson-3.20.1-cp313-cp313-macosx_11_0_arm64.whl", hash = "sha256:1190f9a3ce644fd50ec277ac4a98c0517f532cfebdcc4bd975c0979a9f05e1fb", size = 75112, upload-time = "2025-02-15T05:17:03.875Z" },
- { url = "https://files.pythonhosted.org/packages/45/86/ea9835abb646755140e2d482edc9bc1e91997ed19a59fd77ae4c6a0facea/simplejson-3.20.1-cp313-cp313-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:c1336ba7bcb722ad487cd265701ff0583c0bb6de638364ca947bb84ecc0015d1", size = 150245, upload-time = "2025-02-15T05:17:06.899Z" },
- { url = "https://files.pythonhosted.org/packages/12/b4/53084809faede45da829fe571c65fbda8479d2a5b9c633f46b74124d56f5/simplejson-3.20.1-cp313-cp313-manylinux_2_17_ppc64le.manylinux2014_ppc64le.whl", hash = "sha256:e975aac6a5acd8b510eba58d5591e10a03e3d16c1cf8a8624ca177491f7230f0", size = 158465, upload-time = "2025-02-15T05:17:08.707Z" },
- { url = "https://files.pythonhosted.org/packages/a9/7d/d56579468d1660b3841e1f21c14490d103e33cf911886b22652d6e9683ec/simplejson-3.20.1-cp313-cp313-manylinux_2_5_i686.manylinux1_i686.manylinux_2_17_i686.manylinux2014_i686.whl", hash = "sha256:6a6dd11ee282937ad749da6f3b8d87952ad585b26e5edfa10da3ae2536c73078", size = 148514, upload-time = "2025-02-15T05:17:11.323Z" },
- { url = "https://files.pythonhosted.org/packages/19/e3/874b1cca3d3897b486d3afdccc475eb3a09815bf1015b01cf7fcb52a55f0/simplejson-3.20.1-cp313-cp313-manylinux_2_5_x86_64.manylinux1_x86_64.manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:ab980fcc446ab87ea0879edad41a5c28f2d86020014eb035cf5161e8de4474c6", size = 152262, upload-time = "2025-02-15T05:17:13.543Z" },
- { url = "https://files.pythonhosted.org/packages/32/84/f0fdb3625292d945c2bd13a814584603aebdb38cfbe5fe9be6b46fe598c4/simplejson-3.20.1-cp313-cp313-musllinux_1_2_aarch64.whl", hash = "sha256:f5aee2a4cb6b146bd17333ac623610f069f34e8f31d2f4f0c1a2186e50c594f0", size = 150164, upload-time = "2025-02-15T05:17:15.021Z" },
- { url = "https://files.pythonhosted.org/packages/95/51/6d625247224f01eaaeabace9aec75ac5603a42f8ebcce02c486fbda8b428/simplejson-3.20.1-cp313-cp313-musllinux_1_2_i686.whl", hash = "sha256:652d8eecbb9a3b6461b21ec7cf11fd0acbab144e45e600c817ecf18e4580b99e", size = 151795, upload-time = "2025-02-15T05:17:16.542Z" },
- { url = "https://files.pythonhosted.org/packages/7f/d9/bb921df6b35be8412f519e58e86d1060fddf3ad401b783e4862e0a74c4c1/simplejson-3.20.1-cp313-cp313-musllinux_1_2_ppc64le.whl", hash = "sha256:8c09948f1a486a89251ee3a67c9f8c969b379f6ffff1a6064b41fea3bce0a112", size = 159027, upload-time = "2025-02-15T05:17:18.083Z" },
- { url = "https://files.pythonhosted.org/packages/03/c5/5950605e4ad023a6621cf4c931b29fd3d2a9c1f36be937230bfc83d7271d/simplejson-3.20.1-cp313-cp313-musllinux_1_2_x86_64.whl", hash = "sha256:cbbd7b215ad4fc6f058b5dd4c26ee5c59f72e031dfda3ac183d7968a99e4ca3a", size = 154380, upload-time = "2025-02-15T05:17:20.334Z" },
- { url = "https://files.pythonhosted.org/packages/66/ad/b74149557c5ec1e4e4d55758bda426f5d2ec0123cd01a53ae63b8de51fa3/simplejson-3.20.1-cp313-cp313-win32.whl", hash = "sha256:ae81e482476eaa088ef9d0120ae5345de924f23962c0c1e20abbdff597631f87", size = 74102, upload-time = "2025-02-15T05:17:22.475Z" },
- { url = "https://files.pythonhosted.org/packages/db/a9/25282fdd24493e1022f30b7f5cdf804255c007218b2bfaa655bd7ad34b2d/simplejson-3.20.1-cp313-cp313-win_amd64.whl", hash = "sha256:1b9fd15853b90aec3b1739f4471efbf1ac05066a2c7041bf8db821bb73cd2ddc", size = 75736, upload-time = "2025-02-15T05:17:24.122Z" },
- { url = "https://files.pythonhosted.org/packages/4b/30/00f02a0a921556dd5a6db1ef2926a1bc7a8bbbfb1c49cfed68a275b8ab2b/simplejson-3.20.1-py3-none-any.whl", hash = "sha256:8a6c1bbac39fa4a79f83cbf1df6ccd8ff7069582a9fd8db1e52cea073bc2c697", size = 57121, upload-time = "2025-02-15T05:18:51.243Z" },
-]
-
-[[package]]
-name = "six"
-version = "1.17.0"
-source = { registry = "https://pypi.org/simple" }
-sdist = { url = "https://files.pythonhosted.org/packages/94/e7/b2c673351809dca68a0e064b6af791aa332cf192da575fd474ed7d6f16a2/six-1.17.0.tar.gz", hash = "sha256:ff70335d468e7eb6ec65b95b99d3a2836546063f63acc5171de367e834932a81", size = 34031, upload-time = "2024-12-04T17:35:28.174Z" }
-wheels = [
- { url = "https://files.pythonhosted.org/packages/b7/ce/149a00dd41f10bc29e5921b496af8b574d8413afcd5e30dfa0ed46c2cc5e/six-1.17.0-py2.py3-none-any.whl", hash = "sha256:4721f391ed90541fddacab5acf947aa0d3dc7d27b2e1e8eda2be8970586c3274", size = 11050, upload-time = "2024-12-04T17:35:26.475Z" },
-]
-
[[package]]
name = "sniffio"
version = "1.3.1"
@@ -2220,33 +561,6 @@ wheels = [
{ url = "https://files.pythonhosted.org/packages/e9/44/75a9c9421471a6c4805dbf2356f7c181a29c1879239abab1ea2cc8f38b40/sniffio-1.3.1-py3-none-any.whl", hash = "sha256:2f6da418d1f1e0fddd844478f41680e794e6051915791a034ff65e5f100525a2", size = 10235, upload-time = "2024-02-25T23:20:01.196Z" },
]
-[[package]]
-name = "snownlp"
-version = "0.12.3"
-source = { registry = "https://pypi.org/simple" }
-sdist = { url = "https://files.pythonhosted.org/packages/3d/b3/37567686662100d3bce62d3b0f2adec18ab4b9ff2b61abd7a61c39343c1d/snownlp-0.12.3.tar.gz", hash = "sha256:c92accd025b70dd16706a10690f556ac9204bb6189f7dc68ece5c207c9bc27d8", size = 37609458, upload-time = "2015-09-27T16:35:23.07Z" }
-
-[[package]]
-name = "socksio"
-version = "1.0.0"
-source = { registry = "https://pypi.org/simple" }
-sdist = { url = "https://files.pythonhosted.org/packages/f8/5c/48a7d9495be3d1c651198fd99dbb6ce190e2274d0f28b9051307bdec6b85/socksio-1.0.0.tar.gz", hash = "sha256:f88beb3da5b5c38b9890469de67d0cb0f9d494b78b106ca1845f96c10b91c4ac", size = 19055, upload-time = "2020-04-17T15:50:34.664Z" }
-wheels = [
- { url = "https://files.pythonhosted.org/packages/37/c3/6eeb6034408dac0fa653d126c9204ade96b819c936e136c5e8a6897eee9c/socksio-1.0.0-py3-none-any.whl", hash = "sha256:95dc1f15f9b34e8d7b16f06d74b8ccf48f609af32ab33c608d08761c5dcbb1f3", size = 12763, upload-time = "2020-04-17T15:50:31.878Z" },
-]
-
-[[package]]
-name = "sse-starlette"
-version = "3.0.3"
-source = { registry = "https://pypi.org/simple" }
-dependencies = [
- { name = "anyio" },
-]
-sdist = { url = "https://files.pythonhosted.org/packages/db/3c/fa6517610dc641262b77cc7bf994ecd17465812c1b0585fe33e11be758ab/sse_starlette-3.0.3.tar.gz", hash = "sha256:88cfb08747e16200ea990c8ca876b03910a23b547ab3bd764c0d8eb81019b971", size = 21943, upload-time = "2025-10-30T18:44:20.117Z" }
-wheels = [
- { url = "https://files.pythonhosted.org/packages/23/a0/984525d19ca5c8a6c33911a0c164b11490dd0f90ff7fd689f704f84e9a11/sse_starlette-3.0.3-py3-none-any.whl", hash = "sha256:af5bf5a6f3933df1d9c7f8539633dc8444ca6a97ab2e2a7cd3b6e431ac03a431", size = 11765, upload-time = "2025-10-30T18:44:18.834Z" },
-]
-
[[package]]
name = "starlette"
version = "0.46.1"
@@ -2259,81 +573,6 @@ wheels = [
{ url = "https://files.pythonhosted.org/packages/a0/4b/528ccf7a982216885a1ff4908e886b8fb5f19862d1962f56a3fce2435a70/starlette-0.46.1-py3-none-any.whl", hash = "sha256:77c74ed9d2720138b25875133f3a2dae6d854af2ec37dceb56aef370c1d8a227", size = 71995, upload-time = "2025-03-08T10:55:32.662Z" },
]
-[[package]]
-name = "threadpoolctl"
-version = "3.6.0"
-source = { registry = "https://pypi.org/simple" }
-sdist = { url = "https://files.pythonhosted.org/packages/b7/4d/08c89e34946fce2aec4fbb45c9016efd5f4d7f24af8e5d93296e935631d8/threadpoolctl-3.6.0.tar.gz", hash = "sha256:8ab8b4aa3491d812b623328249fab5302a68d2d71745c8a4c719a2fcaba9f44e", size = 21274, upload-time = "2025-03-13T13:49:23.031Z" }
-wheels = [
- { url = "https://files.pythonhosted.org/packages/32/d5/f9a850d79b0851d1d4ef6456097579a9005b31fea68726a4ae5f2d82ddd9/threadpoolctl-3.6.0-py3-none-any.whl", hash = "sha256:43a0b8fd5a2928500110039e43a5eed8480b918967083ea48dc3ab9f13c4a7fb", size = 18638, upload-time = "2025-03-13T13:49:21.846Z" },
-]
-
-[[package]]
-name = "tomli"
-version = "2.2.1"
-source = { registry = "https://pypi.org/simple" }
-sdist = { url = "https://files.pythonhosted.org/packages/18/87/302344fed471e44a87289cf4967697d07e532f2421fdaf868a303cbae4ff/tomli-2.2.1.tar.gz", hash = "sha256:cd45e1dc79c835ce60f7404ec8119f2eb06d38b1deba146f07ced3bbc44505ff", size = 17175, upload-time = "2024-11-27T22:38:36.873Z" }
-wheels = [
- { url = "https://files.pythonhosted.org/packages/43/ca/75707e6efa2b37c77dadb324ae7d9571cb424e61ea73fad7c56c2d14527f/tomli-2.2.1-cp311-cp311-macosx_10_9_x86_64.whl", hash = "sha256:678e4fa69e4575eb77d103de3df8a895e1591b48e740211bd1067378c69e8249", size = 131077, upload-time = "2024-11-27T22:37:54.956Z" },
- { url = "https://files.pythonhosted.org/packages/c7/16/51ae563a8615d472fdbffc43a3f3d46588c264ac4f024f63f01283becfbb/tomli-2.2.1-cp311-cp311-macosx_11_0_arm64.whl", hash = "sha256:023aa114dd824ade0100497eb2318602af309e5a55595f76b626d6d9f3b7b0a6", size = 123429, upload-time = "2024-11-27T22:37:56.698Z" },
- { url = "https://files.pythonhosted.org/packages/f1/dd/4f6cd1e7b160041db83c694abc78e100473c15d54620083dbd5aae7b990e/tomli-2.2.1-cp311-cp311-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:ece47d672db52ac607a3d9599a9d48dcb2f2f735c6c2d1f34130085bb12b112a", size = 226067, upload-time = "2024-11-27T22:37:57.63Z" },
- { url = "https://files.pythonhosted.org/packages/a9/6b/c54ede5dc70d648cc6361eaf429304b02f2871a345bbdd51e993d6cdf550/tomli-2.2.1-cp311-cp311-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:6972ca9c9cc9f0acaa56a8ca1ff51e7af152a9f87fb64623e31d5c83700080ee", size = 236030, upload-time = "2024-11-27T22:37:59.344Z" },
- { url = "https://files.pythonhosted.org/packages/1f/47/999514fa49cfaf7a92c805a86c3c43f4215621855d151b61c602abb38091/tomli-2.2.1-cp311-cp311-manylinux_2_5_i686.manylinux1_i686.manylinux_2_17_i686.manylinux2014_i686.whl", hash = "sha256:c954d2250168d28797dd4e3ac5cf812a406cd5a92674ee4c8f123c889786aa8e", size = 240898, upload-time = "2024-11-27T22:38:00.429Z" },
- { url = "https://files.pythonhosted.org/packages/73/41/0a01279a7ae09ee1573b423318e7934674ce06eb33f50936655071d81a24/tomli-2.2.1-cp311-cp311-musllinux_1_2_aarch64.whl", hash = "sha256:8dd28b3e155b80f4d54beb40a441d366adcfe740969820caf156c019fb5c7ec4", size = 229894, upload-time = "2024-11-27T22:38:02.094Z" },
- { url = "https://files.pythonhosted.org/packages/55/18/5d8bc5b0a0362311ce4d18830a5d28943667599a60d20118074ea1b01bb7/tomli-2.2.1-cp311-cp311-musllinux_1_2_i686.whl", hash = "sha256:e59e304978767a54663af13c07b3d1af22ddee3bb2fb0618ca1593e4f593a106", size = 245319, upload-time = "2024-11-27T22:38:03.206Z" },
- { url = "https://files.pythonhosted.org/packages/92/a3/7ade0576d17f3cdf5ff44d61390d4b3febb8a9fc2b480c75c47ea048c646/tomli-2.2.1-cp311-cp311-musllinux_1_2_x86_64.whl", hash = "sha256:33580bccab0338d00994d7f16f4c4ec25b776af3ffaac1ed74e0b3fc95e885a8", size = 238273, upload-time = "2024-11-27T22:38:04.217Z" },
- { url = "https://files.pythonhosted.org/packages/72/6f/fa64ef058ac1446a1e51110c375339b3ec6be245af9d14c87c4a6412dd32/tomli-2.2.1-cp311-cp311-win32.whl", hash = "sha256:465af0e0875402f1d226519c9904f37254b3045fc5084697cefb9bdde1ff99ff", size = 98310, upload-time = "2024-11-27T22:38:05.908Z" },
- { url = "https://files.pythonhosted.org/packages/6a/1c/4a2dcde4a51b81be3530565e92eda625d94dafb46dbeb15069df4caffc34/tomli-2.2.1-cp311-cp311-win_amd64.whl", hash = "sha256:2d0f2fdd22b02c6d81637a3c95f8cd77f995846af7414c5c4b8d0545afa1bc4b", size = 108309, upload-time = "2024-11-27T22:38:06.812Z" },
- { url = "https://files.pythonhosted.org/packages/52/e1/f8af4c2fcde17500422858155aeb0d7e93477a0d59a98e56cbfe75070fd0/tomli-2.2.1-cp312-cp312-macosx_10_13_x86_64.whl", hash = "sha256:4a8f6e44de52d5e6c657c9fe83b562f5f4256d8ebbfe4ff922c495620a7f6cea", size = 132762, upload-time = "2024-11-27T22:38:07.731Z" },
- { url = "https://files.pythonhosted.org/packages/03/b8/152c68bb84fc00396b83e7bbddd5ec0bd3dd409db4195e2a9b3e398ad2e3/tomli-2.2.1-cp312-cp312-macosx_11_0_arm64.whl", hash = "sha256:8d57ca8095a641b8237d5b079147646153d22552f1c637fd3ba7f4b0b29167a8", size = 123453, upload-time = "2024-11-27T22:38:09.384Z" },
- { url = "https://files.pythonhosted.org/packages/c8/d6/fc9267af9166f79ac528ff7e8c55c8181ded34eb4b0e93daa767b8841573/tomli-2.2.1-cp312-cp312-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:4e340144ad7ae1533cb897d406382b4b6fede8890a03738ff1683af800d54192", size = 233486, upload-time = "2024-11-27T22:38:10.329Z" },
- { url = "https://files.pythonhosted.org/packages/5c/51/51c3f2884d7bab89af25f678447ea7d297b53b5a3b5730a7cb2ef6069f07/tomli-2.2.1-cp312-cp312-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:db2b95f9de79181805df90bedc5a5ab4c165e6ec3fe99f970d0e302f384ad222", size = 242349, upload-time = "2024-11-27T22:38:11.443Z" },
- { url = "https://files.pythonhosted.org/packages/ab/df/bfa89627d13a5cc22402e441e8a931ef2108403db390ff3345c05253935e/tomli-2.2.1-cp312-cp312-manylinux_2_5_i686.manylinux1_i686.manylinux_2_17_i686.manylinux2014_i686.whl", hash = "sha256:40741994320b232529c802f8bc86da4e1aa9f413db394617b9a256ae0f9a7f77", size = 252159, upload-time = "2024-11-27T22:38:13.099Z" },
- { url = "https://files.pythonhosted.org/packages/9e/6e/fa2b916dced65763a5168c6ccb91066f7639bdc88b48adda990db10c8c0b/tomli-2.2.1-cp312-cp312-musllinux_1_2_aarch64.whl", hash = "sha256:400e720fe168c0f8521520190686ef8ef033fb19fc493da09779e592861b78c6", size = 237243, upload-time = "2024-11-27T22:38:14.766Z" },
- { url = "https://files.pythonhosted.org/packages/b4/04/885d3b1f650e1153cbb93a6a9782c58a972b94ea4483ae4ac5cedd5e4a09/tomli-2.2.1-cp312-cp312-musllinux_1_2_i686.whl", hash = "sha256:02abe224de6ae62c19f090f68da4e27b10af2b93213d36cf44e6e1c5abd19fdd", size = 259645, upload-time = "2024-11-27T22:38:15.843Z" },
- { url = "https://files.pythonhosted.org/packages/9c/de/6b432d66e986e501586da298e28ebeefd3edc2c780f3ad73d22566034239/tomli-2.2.1-cp312-cp312-musllinux_1_2_x86_64.whl", hash = "sha256:b82ebccc8c8a36f2094e969560a1b836758481f3dc360ce9a3277c65f374285e", size = 244584, upload-time = "2024-11-27T22:38:17.645Z" },
- { url = "https://files.pythonhosted.org/packages/1c/9a/47c0449b98e6e7d1be6cbac02f93dd79003234ddc4aaab6ba07a9a7482e2/tomli-2.2.1-cp312-cp312-win32.whl", hash = "sha256:889f80ef92701b9dbb224e49ec87c645ce5df3fa2cc548664eb8a25e03127a98", size = 98875, upload-time = "2024-11-27T22:38:19.159Z" },
- { url = "https://files.pythonhosted.org/packages/ef/60/9b9638f081c6f1261e2688bd487625cd1e660d0a85bd469e91d8db969734/tomli-2.2.1-cp312-cp312-win_amd64.whl", hash = "sha256:7fc04e92e1d624a4a63c76474610238576942d6b8950a2d7f908a340494e67e4", size = 109418, upload-time = "2024-11-27T22:38:20.064Z" },
- { url = "https://files.pythonhosted.org/packages/04/90/2ee5f2e0362cb8a0b6499dc44f4d7d48f8fff06d28ba46e6f1eaa61a1388/tomli-2.2.1-cp313-cp313-macosx_10_13_x86_64.whl", hash = "sha256:f4039b9cbc3048b2416cc57ab3bda989a6fcf9b36cf8937f01a6e731b64f80d7", size = 132708, upload-time = "2024-11-27T22:38:21.659Z" },
- { url = "https://files.pythonhosted.org/packages/c0/ec/46b4108816de6b385141f082ba99e315501ccd0a2ea23db4a100dd3990ea/tomli-2.2.1-cp313-cp313-macosx_11_0_arm64.whl", hash = "sha256:286f0ca2ffeeb5b9bd4fcc8d6c330534323ec51b2f52da063b11c502da16f30c", size = 123582, upload-time = "2024-11-27T22:38:22.693Z" },
- { url = "https://files.pythonhosted.org/packages/a0/bd/b470466d0137b37b68d24556c38a0cc819e8febe392d5b199dcd7f578365/tomli-2.2.1-cp313-cp313-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:a92ef1a44547e894e2a17d24e7557a5e85a9e1d0048b0b5e7541f76c5032cb13", size = 232543, upload-time = "2024-11-27T22:38:24.367Z" },
- { url = "https://files.pythonhosted.org/packages/d9/e5/82e80ff3b751373f7cead2815bcbe2d51c895b3c990686741a8e56ec42ab/tomli-2.2.1-cp313-cp313-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:9316dc65bed1684c9a98ee68759ceaed29d229e985297003e494aa825ebb0281", size = 241691, upload-time = "2024-11-27T22:38:26.081Z" },
- { url = "https://files.pythonhosted.org/packages/05/7e/2a110bc2713557d6a1bfb06af23dd01e7dde52b6ee7dadc589868f9abfac/tomli-2.2.1-cp313-cp313-manylinux_2_5_i686.manylinux1_i686.manylinux_2_17_i686.manylinux2014_i686.whl", hash = "sha256:e85e99945e688e32d5a35c1ff38ed0b3f41f43fad8df0bdf79f72b2ba7bc5272", size = 251170, upload-time = "2024-11-27T22:38:27.921Z" },
- { url = "https://files.pythonhosted.org/packages/64/7b/22d713946efe00e0adbcdfd6d1aa119ae03fd0b60ebed51ebb3fa9f5a2e5/tomli-2.2.1-cp313-cp313-musllinux_1_2_aarch64.whl", hash = "sha256:ac065718db92ca818f8d6141b5f66369833d4a80a9d74435a268c52bdfa73140", size = 236530, upload-time = "2024-11-27T22:38:29.591Z" },
- { url = "https://files.pythonhosted.org/packages/38/31/3a76f67da4b0cf37b742ca76beaf819dca0ebef26d78fc794a576e08accf/tomli-2.2.1-cp313-cp313-musllinux_1_2_i686.whl", hash = "sha256:d920f33822747519673ee656a4b6ac33e382eca9d331c87770faa3eef562aeb2", size = 258666, upload-time = "2024-11-27T22:38:30.639Z" },
- { url = "https://files.pythonhosted.org/packages/07/10/5af1293da642aded87e8a988753945d0cf7e00a9452d3911dd3bb354c9e2/tomli-2.2.1-cp313-cp313-musllinux_1_2_x86_64.whl", hash = "sha256:a198f10c4d1b1375d7687bc25294306e551bf1abfa4eace6650070a5c1ae2744", size = 243954, upload-time = "2024-11-27T22:38:31.702Z" },
- { url = "https://files.pythonhosted.org/packages/5b/b9/1ed31d167be802da0fc95020d04cd27b7d7065cc6fbefdd2f9186f60d7bd/tomli-2.2.1-cp313-cp313-win32.whl", hash = "sha256:d3f5614314d758649ab2ab3a62d4f2004c825922f9e370b29416484086b264ec", size = 98724, upload-time = "2024-11-27T22:38:32.837Z" },
- { url = "https://files.pythonhosted.org/packages/c7/32/b0963458706accd9afcfeb867c0f9175a741bf7b19cd424230714d722198/tomli-2.2.1-cp313-cp313-win_amd64.whl", hash = "sha256:a38aa0308e754b0e3c67e344754dff64999ff9b513e691d0e786265c93583c69", size = 109383, upload-time = "2024-11-27T22:38:34.455Z" },
- { url = "https://files.pythonhosted.org/packages/6e/c2/61d3e0f47e2b74ef40a68b9e6ad5984f6241a942f7cd3bbfbdbd03861ea9/tomli-2.2.1-py3-none-any.whl", hash = "sha256:cb55c73c5f4408779d0cf3eef9f762b9c9f147a77de7b258bef0a5628adc85cc", size = 14257, upload-time = "2024-11-27T22:38:35.385Z" },
-]
-
-[[package]]
-name = "tqdm"
-version = "4.67.1"
-source = { registry = "https://pypi.org/simple" }
-dependencies = [
- { name = "colorama", marker = "sys_platform == 'win32'" },
-]
-sdist = { url = "https://files.pythonhosted.org/packages/a8/4b/29b4ef32e036bb34e4ab51796dd745cdba7ed47ad142a9f4a1eb8e0c744d/tqdm-4.67.1.tar.gz", hash = "sha256:f8aef9c52c08c13a65f30ea34f4e5aac3fd1a34959879d7e59e63027286627f2", size = 169737, upload-time = "2024-11-24T20:12:22.481Z" }
-wheels = [
- { url = "https://files.pythonhosted.org/packages/d0/30/dc54f88dd4a2b5dc8a0279bdd7270e735851848b762aeb1c1184ed1f6b14/tqdm-4.67.1-py3-none-any.whl", hash = "sha256:26445eca388f82e72884e0d580d5464cd801a3ea01e63e5601bdff9ba6a48de2", size = 78540, upload-time = "2024-11-24T20:12:19.698Z" },
-]
-
-[[package]]
-name = "typer"
-version = "0.26.7"
-source = { registry = "https://pypi.org/simple" }
-dependencies = [
- { name = "annotated-doc" },
- { name = "colorama", marker = "sys_platform == 'win32'" },
- { name = "rich" },
- { name = "shellingham" },
-]
-sdist = { url = "https://files.pythonhosted.org/packages/5e/ed/ef06584ccdd5c410df0837951ecd7e15d9a6144ea1bd4c73cecab1a89891/typer-0.26.7.tar.gz", hash = "sha256:e314a34c617e419c091b2830dda3ea1f257134ff593061a8f5b9717ab8dddb3a", size = 201709, upload-time = "2026-06-03T07:18:06.843Z" }
-wheels = [
- { url = "https://files.pythonhosted.org/packages/24/25/2201973529af2c954de0bb725323c3aaed6d7f0ceee8f550dec9185df013/typer-0.26.7-py3-none-any.whl", hash = "sha256:5c87cfbc5d34491c5346ebf49c23e18d56ccb863268d3a8d592b26087c2f5e58", size = 122456, upload-time = "2026-06-03T07:18:05.732Z" },
-]
-
[[package]]
name = "typing-extensions"
version = "4.15.0"
@@ -2355,15 +594,6 @@ wheels = [
{ url = "https://files.pythonhosted.org/packages/dc/9b/47798a6c91d8bdb567fe2698fe81e0c6b7cb7ef4d13da4114b41d239f65d/typing_inspection-0.4.2-py3-none-any.whl", hash = "sha256:4ed1cacbdc298c220f1bd249ed5287caa16f34d44ef4e9c3d0cbad5b521545e7", size = 14611, upload-time = "2025-10-01T02:14:40.154Z" },
]
-[[package]]
-name = "tzdata"
-version = "2025.2"
-source = { registry = "https://pypi.org/simple" }
-sdist = { url = "https://files.pythonhosted.org/packages/95/32/1a225d6164441be760d75c2c42e2780dc0873fe382da3e98a2e1e48361e5/tzdata-2025.2.tar.gz", hash = "sha256:b60a638fcc0daffadf82fe0f57e53d06bdec2f36c4df66280ae79bce6bd6f2b9", size = 196380, upload-time = "2025-03-23T13:54:43.652Z" }
-wheels = [
- { url = "https://files.pythonhosted.org/packages/5c/23/c7abc0ca0a1526a0774eca151daeb8de62ec457e77262b66b359c3c7679e/tzdata-2025.2-py2.py3-none-any.whl", hash = "sha256:1a403fada01ff9221ca8044d701868fa132215d84beb92242d9acd2147f667a8", size = 347839, upload-time = "2025-03-23T13:54:41.845Z" },
-]
-
[[package]]
name = "urllib3"
version = "2.3.0"
@@ -2387,15 +617,6 @@ wheels = [
{ url = "https://files.pythonhosted.org/packages/50/c1/2d27b0a15826c2b71dcf6e2f5402181ef85acf439617bb2f1453125ce1f3/uvicorn-0.32.1-py3-none-any.whl", hash = "sha256:82ad92fd58da0d12af7482ecdb5f2470a04c9c9a53ced65b9bbb4a205377602e", size = 63828, upload-time = "2024-11-20T19:41:11.244Z" },
]
-[[package]]
-name = "wcwidth"
-version = "0.2.13"
-source = { registry = "https://pypi.org/simple" }
-sdist = { url = "https://files.pythonhosted.org/packages/6c/63/53559446a878410fc5a5974feb13d31d78d752eb18aeba59c7fef1af7598/wcwidth-0.2.13.tar.gz", hash = "sha256:72ea0c06399eb286d978fdedb6923a9eb47e1c486ce63e9b4e64fc18303972b5", size = 101301, upload-time = "2024-01-06T02:10:57.829Z" }
-wheels = [
- { url = "https://files.pythonhosted.org/packages/fd/84/fd2ba7aafacbad3c4201d395674fc6348826569da3c0937e75505ead3528/wcwidth-0.2.13-py2.py3-none-any.whl", hash = "sha256:3da69048e4540d84af32131829ff948f1e022c1c6bdb8d6102117aac784f6859", size = 34166, upload-time = "2024-01-06T02:10:55.763Z" },
-]
-
[[package]]
name = "win32-setctime"
version = "1.2.0"
@@ -2404,104 +625,3 @@ sdist = { url = "https://files.pythonhosted.org/packages/b3/8f/705086c9d734d3b66
wheels = [
{ url = "https://files.pythonhosted.org/packages/e1/07/c6fe3ad3e685340704d314d765b7912993bcb8dc198f0e7a89382d37974b/win32_setctime-1.2.0-py3-none-any.whl", hash = "sha256:95d644c4e708aba81dc3704a116d8cbc974d70b3bdb8be1d150e36be6e9d1390", size = 4083, upload-time = "2024-12-07T15:28:26.465Z" },
]
-
-[[package]]
-name = "yarl"
-version = "1.19.0"
-source = { registry = "https://pypi.org/simple" }
-dependencies = [
- { name = "idna" },
- { name = "multidict" },
- { name = "propcache" },
-]
-sdist = { url = "https://files.pythonhosted.org/packages/fc/4d/8a8f57caccce49573e567744926f88c6ab3ca0b47a257806d1cf88584c5f/yarl-1.19.0.tar.gz", hash = "sha256:01e02bb80ae0dbed44273c304095295106e1d9470460e773268a27d11e594892", size = 184396, upload-time = "2025-04-06T02:36:26.161Z" }
-wheels = [
- { url = "https://files.pythonhosted.org/packages/96/0f/e5bd0d7d98bb194a30740dea2c4324f85dfc2f8daba9d7bc7e47b45d1034/yarl-1.19.0-cp310-cp310-macosx_10_9_universal2.whl", hash = "sha256:0bae32f8ebd35c04d6528cedb4a26b8bf25339d3616b04613b97347f919b76d3", size = 144954, upload-time = "2025-04-06T02:33:31.943Z" },
- { url = "https://files.pythonhosted.org/packages/07/bf/2acc4b643dbdfc823d0d2058768197198a3d93b41fffb41b83359c520a4d/yarl-1.19.0-cp310-cp310-macosx_10_9_x86_64.whl", hash = "sha256:8015a076daf77823e7ebdcba474156587391dab4e70c732822960368c01251e6", size = 96613, upload-time = "2025-04-06T02:33:34.924Z" },
- { url = "https://files.pythonhosted.org/packages/ca/38/c60ccca9aad0bb939e665b63a4e1550fecc922971f1f246dd7ad709a1a72/yarl-1.19.0-cp310-cp310-macosx_11_0_arm64.whl", hash = "sha256:9973ac95327f5d699eb620286c39365990b240031672b5c436a4cd00539596c5", size = 94408, upload-time = "2025-04-06T02:33:37.58Z" },
- { url = "https://files.pythonhosted.org/packages/9a/43/2d5b49b4784743d88054e612a97aee2a9d2d463983c6a8e2fa4c872b294a/yarl-1.19.0-cp310-cp310-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:fd4b5fbd7b9dde785cfeb486b8cca211a0b138d4f3a7da27db89a25b3c482e5c", size = 330774, upload-time = "2025-04-06T02:33:39.506Z" },
- { url = "https://files.pythonhosted.org/packages/3b/48/7decce219b6eedce321345f61461ee140ee6b3faf4875efe518f0e7b5817/yarl-1.19.0-cp310-cp310-manylinux_2_17_armv7l.manylinux2014_armv7l.manylinux_2_31_armv7l.whl", hash = "sha256:75460740005de5a912b19f657848aef419387426a40f581b1dc9fac0eb9addb5", size = 323399, upload-time = "2025-04-06T02:33:41.467Z" },
- { url = "https://files.pythonhosted.org/packages/67/2f/d6253528e49ce1c6f5119ec5269314752b06dd670f5a81721648d98b1dc7/yarl-1.19.0-cp310-cp310-manylinux_2_17_ppc64le.manylinux2014_ppc64le.whl", hash = "sha256:57abd66ca913f2cfbb51eb3dbbbac3648f1f6983f614a4446e0802e241441d2a", size = 343329, upload-time = "2025-04-06T02:33:43.416Z" },
- { url = "https://files.pythonhosted.org/packages/fc/6b/efeb1a088e8addbf5841a84b74dad2a06346b0e4a712eb269a0cd9ada8b7/yarl-1.19.0-cp310-cp310-manylinux_2_17_s390x.manylinux2014_s390x.whl", hash = "sha256:46ade37911b7c99ce28a959147cb28bffbd14cea9e7dd91021e06a8d2359a5aa", size = 338275, upload-time = "2025-04-06T02:33:45.394Z" },
- { url = "https://files.pythonhosted.org/packages/a6/b6/31acc2efcaf6999fd256d11f26ccc95ea773bc790ad1973331d7294b25db/yarl-1.19.0-cp310-cp310-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:8346ec72ada749a6b5d82bff7be72578eab056ad7ec38c04f668a685abde6af0", size = 334014, upload-time = "2025-04-06T02:33:47.037Z" },
- { url = "https://files.pythonhosted.org/packages/79/16/1deb54324842479e4d8b34841a383653587dfcc403c132f88b493f0c513e/yarl-1.19.0-cp310-cp310-manylinux_2_5_i686.manylinux1_i686.manylinux_2_17_i686.manylinux2014_i686.whl", hash = "sha256:7e4cb14a6ee5b6649ccf1c6d648b4da9220e8277d4d4380593c03cc08d8fe937", size = 322007, upload-time = "2025-04-06T02:33:48.679Z" },
- { url = "https://files.pythonhosted.org/packages/80/77/4a073cec4f40ce84897510ee9d347bc10128f715be59b36e5c037463523b/yarl-1.19.0-cp310-cp310-musllinux_1_2_aarch64.whl", hash = "sha256:66fc1c2926a73a2fb46e4b92e3a6c03904d9bc3a0b65e01cb7d2b84146a8bd3b", size = 336569, upload-time = "2025-04-06T02:33:50.341Z" },
- { url = "https://files.pythonhosted.org/packages/73/e1/2f0455379bbee5f4ece8bc0968106386ec4e74237e8d68ced00bbff0a1fc/yarl-1.19.0-cp310-cp310-musllinux_1_2_armv7l.whl", hash = "sha256:5a70201dd1e0a4304849b6445a9891d7210604c27e67da59091d5412bc19e51c", size = 336384, upload-time = "2025-04-06T02:33:52.286Z" },
- { url = "https://files.pythonhosted.org/packages/74/e0/307aa8ae96bc0e72644855c76e8960019fc24c511a5dda73f05214da46f0/yarl-1.19.0-cp310-cp310-musllinux_1_2_i686.whl", hash = "sha256:e4807aab1bdeab6ae6f296be46337a260ae4b1f3a8c2fcd373e236b4b2b46efd", size = 340454, upload-time = "2025-04-06T02:33:54.602Z" },
- { url = "https://files.pythonhosted.org/packages/af/19/2dcdb1e5eef26751c9e79369d1f80d6a1162dababb5070f62bc5b1a8f81e/yarl-1.19.0-cp310-cp310-musllinux_1_2_ppc64le.whl", hash = "sha256:ae584afe81a1de4c1bb06672481050f0d001cad13163e3c019477409f638f9b7", size = 355804, upload-time = "2025-04-06T02:33:56.201Z" },
- { url = "https://files.pythonhosted.org/packages/c1/af/8c1e102c6d61713ed31022ab8f8866d263b87cb8f466c37f20a99019d169/yarl-1.19.0-cp310-cp310-musllinux_1_2_s390x.whl", hash = "sha256:30eaf4459df6e91f21b2999d1ee18f891bcd51e3cbe1de301b4858c84385895b", size = 359877, upload-time = "2025-04-06T02:33:58.366Z" },
- { url = "https://files.pythonhosted.org/packages/1a/cf/c3c4bd85ecc7f189e14d21c3bea67ce389511d9178a302d97281868477aa/yarl-1.19.0-cp310-cp310-musllinux_1_2_x86_64.whl", hash = "sha256:0e617d45d03c8dec0dfce6f51f3e1b8a31aa81aaf4a4d1442fdb232bcf0c6d8c", size = 351282, upload-time = "2025-04-06T02:34:00.384Z" },
- { url = "https://files.pythonhosted.org/packages/c6/85/0994f1c607b0520ef007717ff74f3317df3f7b7f32756ba2bf26c0c58ddf/yarl-1.19.0-cp310-cp310-win32.whl", hash = "sha256:32ba32d0fa23893fd8ea8d05bdb05de6eb19d7f2106787024fd969f4ba5466cb", size = 86529, upload-time = "2025-04-06T02:34:03.118Z" },
- { url = "https://files.pythonhosted.org/packages/59/00/39bc8da1f67614633a099a44a5f69d056bb4d65a8e52a4003460e3fa4cc7/yarl-1.19.0-cp310-cp310-win_amd64.whl", hash = "sha256:545575ecfcd465891b51546c2bcafdde0acd2c62c2097d8d71902050b20e4922", size = 92707, upload-time = "2025-04-06T02:34:05.08Z" },
- { url = "https://files.pythonhosted.org/packages/9b/df/5fa7cd75e46306e0f9baf38a7c8969ff6730ea503b86232e85cb740304cf/yarl-1.19.0-cp311-cp311-macosx_10_9_universal2.whl", hash = "sha256:163ff326680de5f6d4966954cf9e3fe1bf980f5fee2255e46e89b8cf0f3418b5", size = 145126, upload-time = "2025-04-06T02:34:06.708Z" },
- { url = "https://files.pythonhosted.org/packages/2a/be/c1b52129cd2166ab7337f08e701a61baa7c260c7b03b534098cc8297aecc/yarl-1.19.0-cp311-cp311-macosx_10_9_x86_64.whl", hash = "sha256:a626c4d9cca298d1be8625cff4b17004a9066330ac82d132bbda64a4c17c18d3", size = 96691, upload-time = "2025-04-06T02:34:08.664Z" },
- { url = "https://files.pythonhosted.org/packages/8d/39/ad62139b45515f9bf129c805aeaaedf86fd93ae57ffe911f4caeabef3e74/yarl-1.19.0-cp311-cp311-macosx_11_0_arm64.whl", hash = "sha256:961c3e401ea7f13d02b8bb7cb0c709152a632a6e14cdc8119e9c6ee5596cd45d", size = 94505, upload-time = "2025-04-06T02:34:10.175Z" },
- { url = "https://files.pythonhosted.org/packages/be/be/04e3202cdc9bb5f81761e327af7095cffb0d81e32421a6b87f926052d2ae/yarl-1.19.0-cp311-cp311-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:a39d7b807ab58e633ed760f80195cbd145b58ba265436af35f9080f1810dfe64", size = 355485, upload-time = "2025-04-06T02:34:11.69Z" },
- { url = "https://files.pythonhosted.org/packages/00/7d/1463203663ca1ae62af8fb9ebc9601dd07f04dbced7edb1df3141a2cb2fe/yarl-1.19.0-cp311-cp311-manylinux_2_17_armv7l.manylinux2014_armv7l.manylinux_2_31_armv7l.whl", hash = "sha256:c4228978fb59c6b10f60124ba8e311c26151e176df364e996f3f8ff8b93971b5", size = 344569, upload-time = "2025-04-06T02:34:13.661Z" },
- { url = "https://files.pythonhosted.org/packages/b0/1b/5263203017348669e637bb73856fb9632110538e92d5e9f8214fcc764da9/yarl-1.19.0-cp311-cp311-manylinux_2_17_ppc64le.manylinux2014_ppc64le.whl", hash = "sha256:9ba536b17ecf3c74a94239ec1137a3ad3caea8c0e4deb8c8d2ffe847d870a8c5", size = 371426, upload-time = "2025-04-06T02:34:15.329Z" },
- { url = "https://files.pythonhosted.org/packages/78/59/90ca5f16d56b7741e5383951acc2e065fce41920eb5d8fda3065b5e288dc/yarl-1.19.0-cp311-cp311-manylinux_2_17_s390x.manylinux2014_s390x.whl", hash = "sha256:a251e00e445d2e9df7b827c9843c0b87f58a3254aaa3f162fb610747491fe00f", size = 368102, upload-time = "2025-04-06T02:34:18.16Z" },
- { url = "https://files.pythonhosted.org/packages/84/f2/5e33aa0251ffd2c2a9041bf887e163eeefdc1dca238fdabac444d9463c3f/yarl-1.19.0-cp311-cp311-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:f9b92431d8b4d4ca5ccbfdbac95b05a3a6cd70cd73aa62f32f9627acfde7549c", size = 358740, upload-time = "2025-04-06T02:34:20.775Z" },
- { url = "https://files.pythonhosted.org/packages/22/9e/ba92d234c81cf94495fc01eaa0b6000175733f76bd63e60ff748bce22c81/yarl-1.19.0-cp311-cp311-manylinux_2_5_i686.manylinux1_i686.manylinux_2_17_i686.manylinux2014_i686.whl", hash = "sha256:ec2f56edaf476f70b5831bbd59700b53d9dd011b1f77cd4846b5ab5c5eafdb3f", size = 346965, upload-time = "2025-04-06T02:34:22.706Z" },
- { url = "https://files.pythonhosted.org/packages/8d/0b/d4f53136ef12ddad540855a886d7503a6cc17cfabb9a03ce0c179f3b9e51/yarl-1.19.0-cp311-cp311-musllinux_1_2_aarch64.whl", hash = "sha256:acf9b92c4245ac8b59bc7ec66a38d3dcb8d1f97fac934672529562bb824ecadb", size = 368547, upload-time = "2025-04-06T02:34:24.753Z" },
- { url = "https://files.pythonhosted.org/packages/31/4b/35ec8622908a728f378a8511f0ab2d47878b2c0b8cbe035f2d907914a5fc/yarl-1.19.0-cp311-cp311-musllinux_1_2_armv7l.whl", hash = "sha256:57711f1465c06fee8825b95c0b83e82991e6d9425f9a042c3c19070a70ac92bf", size = 357610, upload-time = "2025-04-06T02:34:26.342Z" },
- { url = "https://files.pythonhosted.org/packages/c1/71/1f39f7c55b0684834d945a2bcfdfe59e6e02ca2483a3d33c2f77a0c3b177/yarl-1.19.0-cp311-cp311-musllinux_1_2_i686.whl", hash = "sha256:528e86f5b1de0ad8dd758ddef4e0ed24f5d946d4a1cef80ffb2d4fca4e10f122", size = 365331, upload-time = "2025-04-06T02:34:28.43Z" },
- { url = "https://files.pythonhosted.org/packages/2e/13/57675964de5c8ccf6427df93ac97f9bb7328f3f8f7ebc31a5f5a286ab1c0/yarl-1.19.0-cp311-cp311-musllinux_1_2_ppc64le.whl", hash = "sha256:3b77173663e075d9e5a57e09d711e9da2f3266be729ecca0b8ae78190990d260", size = 378624, upload-time = "2025-04-06T02:34:30.467Z" },
- { url = "https://files.pythonhosted.org/packages/d4/c6/5868e40f8da041ed0c3b5fd8c08cece849d9f609e970e6043308767fbb60/yarl-1.19.0-cp311-cp311-musllinux_1_2_s390x.whl", hash = "sha256:d8717924cf0a825b62b1a96fc7d28aab7f55a81bf5338b8ef41d7a76ab9223e9", size = 383981, upload-time = "2025-04-06T02:34:32.585Z" },
- { url = "https://files.pythonhosted.org/packages/f4/3f/e40124c986d96741d3d341ffac35be42b6df82ef8c18b5984ca2e7d838dd/yarl-1.19.0-cp311-cp311-musllinux_1_2_x86_64.whl", hash = "sha256:0df9f0221a78d858793f40cbea3915c29f969c11366646a92ca47e080a14f881", size = 378868, upload-time = "2025-04-06T02:34:34.727Z" },
- { url = "https://files.pythonhosted.org/packages/01/eb/caf2774c770288bd87a818b11f3a56ada6a855f1987d93421aae01a175bf/yarl-1.19.0-cp311-cp311-win32.whl", hash = "sha256:8b3ade62678ee2c7c10dcd6be19045135e9badad53108f7d2ed14896ee396045", size = 86446, upload-time = "2025-04-06T02:34:36.757Z" },
- { url = "https://files.pythonhosted.org/packages/4a/97/d4fe6168c1bb789507ffeb58c2e8c675a7e71de732dc02e12bda904c1362/yarl-1.19.0-cp311-cp311-win_amd64.whl", hash = "sha256:0626ee31edb23ac36bdffe607231de2cca055ad3a5e2dc5da587ef8bc6a321bc", size = 93121, upload-time = "2025-04-06T02:34:38.296Z" },
- { url = "https://files.pythonhosted.org/packages/b8/70/44ef8f69d61cb5123167a4dda87f6c739a833fbdb2ed52960b4e8409d65c/yarl-1.19.0-cp312-cp312-macosx_10_13_universal2.whl", hash = "sha256:7b687c334da3ff8eab848c9620c47a253d005e78335e9ce0d6868ed7e8fd170b", size = 146855, upload-time = "2025-04-06T02:34:40.177Z" },
- { url = "https://files.pythonhosted.org/packages/c3/94/38c14d6c8217cc818647689f2dd647b976ced8fea08d0ac84e3c8168252b/yarl-1.19.0-cp312-cp312-macosx_10_13_x86_64.whl", hash = "sha256:b0fe766febcf523a2930b819c87bb92407ae1368662c1bc267234e79b20ff894", size = 97523, upload-time = "2025-04-06T02:34:41.817Z" },
- { url = "https://files.pythonhosted.org/packages/35/a5/43a613586a6255105c4655a911c307ef3420e49e540d6ae2c5829863fb25/yarl-1.19.0-cp312-cp312-macosx_11_0_arm64.whl", hash = "sha256:742ceffd3c7beeb2b20d47cdb92c513eef83c9ef88c46829f88d5b06be6734ee", size = 95540, upload-time = "2025-04-06T02:34:43.4Z" },
- { url = "https://files.pythonhosted.org/packages/d4/60/ed26049f4a8b06ebfa6d5f3cb6a51b152fd57081aa818b6497474f65a631/yarl-1.19.0-cp312-cp312-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:2af682a1e97437382ee0791eacbf540318bd487a942e068e7e0a6c571fadbbd3", size = 344386, upload-time = "2025-04-06T02:34:45.275Z" },
- { url = "https://files.pythonhosted.org/packages/49/a6/b84899cab411f49af5986cfb44b514040788d81c8084f5811e6a7c0f1ce6/yarl-1.19.0-cp312-cp312-manylinux_2_17_armv7l.manylinux2014_armv7l.manylinux_2_31_armv7l.whl", hash = "sha256:63702f1a098d0eaaea755e9c9d63172be1acb9e2d4aeb28b187092bcc9ca2d17", size = 338889, upload-time = "2025-04-06T02:34:47.359Z" },
- { url = "https://files.pythonhosted.org/packages/cc/ce/0704f7166a781b1f81bdd45c4f49eadbae0230ebd35b9ec7cd7769d3a6ff/yarl-1.19.0-cp312-cp312-manylinux_2_17_ppc64le.manylinux2014_ppc64le.whl", hash = "sha256:3560dcba3c71ae7382975dc1e912ee76e50b4cd7c34b454ed620d55464f11876", size = 353107, upload-time = "2025-04-06T02:34:49.32Z" },
- { url = "https://files.pythonhosted.org/packages/75/e5/0ecd6f2a9cc4264c16d8dfb0d3d71ba8d03cb58f3bcd42b1df4358331189/yarl-1.19.0-cp312-cp312-manylinux_2_17_s390x.manylinux2014_s390x.whl", hash = "sha256:68972df6a0cc47c8abaf77525a76ee5c5f6ea9bbdb79b9565b3234ded3c5e675", size = 353128, upload-time = "2025-04-06T02:34:51.312Z" },
- { url = "https://files.pythonhosted.org/packages/ad/c7/cd0fd1de581f1c2e8f996e704c9fd979e00106f18eebd91b0173cf1a13c6/yarl-1.19.0-cp312-cp312-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:5684e7ff93ea74e47542232bd132f608df4d449f8968fde6b05aaf9e08a140f9", size = 349107, upload-time = "2025-04-06T02:34:53.022Z" },
- { url = "https://files.pythonhosted.org/packages/e6/34/ba3e5a20bd1d6a09034fc7985aaf1309976f2a7a5aefd093c9e56f6e1e0c/yarl-1.19.0-cp312-cp312-manylinux_2_5_i686.manylinux1_i686.manylinux_2_17_i686.manylinux2014_i686.whl", hash = "sha256:8182ad422bfacdebd4759ce3adc6055c0c79d4740aea1104e05652a81cd868c6", size = 335144, upload-time = "2025-04-06T02:34:54.767Z" },
- { url = "https://files.pythonhosted.org/packages/1e/98/d9b7beb932fade015906efe0980aa7d522b8f93cf5ebf1082e74faa314b7/yarl-1.19.0-cp312-cp312-musllinux_1_2_aarch64.whl", hash = "sha256:aee5b90a5a9b71ac57400a7bdd0feaa27c51e8f961decc8d412e720a004a1791", size = 360795, upload-time = "2025-04-06T02:34:57.08Z" },
- { url = "https://files.pythonhosted.org/packages/9a/11/70b8770039cc54af5948970591517a1e1d093df3f04f328c655c9a0fefb7/yarl-1.19.0-cp312-cp312-musllinux_1_2_armv7l.whl", hash = "sha256:8c0b2371858d5a814b08542d5d548adb03ff2d7ab32f23160e54e92250961a72", size = 360140, upload-time = "2025-04-06T02:34:59.341Z" },
- { url = "https://files.pythonhosted.org/packages/d4/67/708e3e36fafc4d9d96b4eecc6c8b9f37c8ad50df8a16c7a1d5ba9df53050/yarl-1.19.0-cp312-cp312-musllinux_1_2_i686.whl", hash = "sha256:cd430c2b7df4ae92498da09e9b12cad5bdbb140d22d138f9e507de1aa3edfea3", size = 364431, upload-time = "2025-04-06T02:35:01.126Z" },
- { url = "https://files.pythonhosted.org/packages/c3/8b/937fbbcc895553a7e16fcd86ae4e0724c6ac9468237ad8e7c29cc3b1c9d9/yarl-1.19.0-cp312-cp312-musllinux_1_2_ppc64le.whl", hash = "sha256:a93208282c0ccdf73065fd76c6c129bd428dba5ff65d338ae7d2ab27169861a0", size = 373832, upload-time = "2025-04-06T02:35:03.244Z" },
- { url = "https://files.pythonhosted.org/packages/f8/ca/288ddc2230c9b6647fe907504f1119adb41252ac533eb564d3fc73511215/yarl-1.19.0-cp312-cp312-musllinux_1_2_s390x.whl", hash = "sha256:b8179280cdeb4c36eb18d6534a328f9d40da60d2b96ac4a295c5f93e2799e9d9", size = 378122, upload-time = "2025-04-06T02:35:05.365Z" },
- { url = "https://files.pythonhosted.org/packages/4f/5a/79e1ef31d14968fbfc0ecec70a6683b574890d9c7550c376dd6d40de7754/yarl-1.19.0-cp312-cp312-musllinux_1_2_x86_64.whl", hash = "sha256:eda3c2b42dc0c389b7cfda2c4df81c12eeb552019e0de28bde8f913fc3d1fcf3", size = 375178, upload-time = "2025-04-06T02:35:07.106Z" },
- { url = "https://files.pythonhosted.org/packages/95/38/9b0e56bf14026c3f550ad6425679f6d1a2f4821d70767f39d6f4c56a0820/yarl-1.19.0-cp312-cp312-win32.whl", hash = "sha256:57f3fed859af367b9ca316ecc05ce79ce327d6466342734305aa5cc380e4d8be", size = 86172, upload-time = "2025-04-06T02:35:09.224Z" },
- { url = "https://files.pythonhosted.org/packages/b3/96/5c2f3987c4bb4e5cdebea3caf99a45946b13a9516f849c02222203d99860/yarl-1.19.0-cp312-cp312-win_amd64.whl", hash = "sha256:5507c1f7dd3d41251b67eecba331c8b2157cfd324849879bebf74676ce76aff7", size = 92617, upload-time = "2025-04-06T02:35:11.283Z" },
- { url = "https://files.pythonhosted.org/packages/cd/a7/222144efa2f4a47363a5fee27d8a1d24851283b5a7f628890805fe7f7a66/yarl-1.19.0-cp313-cp313-macosx_10_13_universal2.whl", hash = "sha256:59281b9ed27bc410e0793833bcbe7fc149739d56ffa071d1e0fe70536a4f7b61", size = 144789, upload-time = "2025-04-06T02:35:13.176Z" },
- { url = "https://files.pythonhosted.org/packages/72/4f/3ee8de3f94baa33c0716260b0048b1fd5306f104b3efc6e1713693e7063e/yarl-1.19.0-cp313-cp313-macosx_10_13_x86_64.whl", hash = "sha256:d27a6482ad5e05e8bafd47bf42866f8a1c0c3345abcb48d4511b3c29ecc197dc", size = 96685, upload-time = "2025-04-06T02:35:14.852Z" },
- { url = "https://files.pythonhosted.org/packages/3e/7c/fbeebf875c1ededd872d6fefabd8a8526ef8aba6e9e8bcdf230d895d487b/yarl-1.19.0-cp313-cp313-macosx_11_0_arm64.whl", hash = "sha256:7a8e19fd5a6fdf19a91f2409665c7a089ffe7b9b5394ab33c0eec04cbecdd01f", size = 94307, upload-time = "2025-04-06T02:35:16.722Z" },
- { url = "https://files.pythonhosted.org/packages/f3/ff/b7a9c1d7df37e594b43b7a8030e228ccd4ce361eeff24a92b17fe210e57d/yarl-1.19.0-cp313-cp313-manylinux_2_17_aarch64.manylinux2014_aarch64.whl", hash = "sha256:cda34ab19099c3a1685ad48fe45172536610c312b993310b5f1ca3eb83453b36", size = 342811, upload-time = "2025-04-06T02:35:18.648Z" },
- { url = "https://files.pythonhosted.org/packages/79/e2/9e092876b2156c1d386e4864e85eba541ccabf2b9dcc47da64624bad0cc9/yarl-1.19.0-cp313-cp313-manylinux_2_17_armv7l.manylinux2014_armv7l.manylinux_2_31_armv7l.whl", hash = "sha256:7908a25d33f94852b479910f9cae6cdb9e2a509894e8d5f416c8342c0253c397", size = 336928, upload-time = "2025-04-06T02:35:20.59Z" },
- { url = "https://files.pythonhosted.org/packages/71/24/648d99c134f2e14fc01ba790ad36ab56815e00069e60a12a4af893448b83/yarl-1.19.0-cp313-cp313-manylinux_2_17_ppc64le.manylinux2014_ppc64le.whl", hash = "sha256:e66c14d162bac94973e767b24de5d7e6c5153f7305a64ff4fcba701210bcd638", size = 351021, upload-time = "2025-04-06T02:35:22.614Z" },
- { url = "https://files.pythonhosted.org/packages/0c/ee/7278d475784d407d1990a5939722e66a0fef057046fb5f1721f0a6eb156c/yarl-1.19.0-cp313-cp313-manylinux_2_17_s390x.manylinux2014_s390x.whl", hash = "sha256:c03607bf932aa4cfae371e2dc9ca8b76faf031f106dac6a6ff1458418140c165", size = 354454, upload-time = "2025-04-06T02:35:24.72Z" },
- { url = "https://files.pythonhosted.org/packages/15/ae/242546114e052a7de21a75bd7d4860266439f90bbc21c5e4dd696866d91d/yarl-1.19.0-cp313-cp313-manylinux_2_17_x86_64.manylinux2014_x86_64.whl", hash = "sha256:9931343d1c1f4e77421687b6b94bbebd8a15a64ab8279adf6fbb047eff47e536", size = 347594, upload-time = "2025-04-06T02:35:26.665Z" },
- { url = "https://files.pythonhosted.org/packages/46/2c/35f4347f76ea4c986e9c1f774b085f489b3a1bf1503c67a4dfc5d8e68e92/yarl-1.19.0-cp313-cp313-manylinux_2_5_i686.manylinux1_i686.manylinux_2_17_i686.manylinux2014_i686.whl", hash = "sha256:262087a8a0d73e1d169d45c2baf968126f93c97cf403e1af23a7d5455d52721f", size = 334113, upload-time = "2025-04-06T02:35:28.4Z" },
- { url = "https://files.pythonhosted.org/packages/20/89/3086bc8ec8d7bd505531c51056452d7ae6af906d29c427374f1170ac1938/yarl-1.19.0-cp313-cp313-musllinux_1_2_aarch64.whl", hash = "sha256:70f384921c24e703d249a6ccdabeb57dd6312b568b504c69e428a8dd3e8e68ca", size = 361037, upload-time = "2025-04-06T02:35:30.509Z" },
- { url = "https://files.pythonhosted.org/packages/a1/5b/2c9765524a70d1c51922b41c91caa30c8094a416734349166e1a3d8de055/yarl-1.19.0-cp313-cp313-musllinux_1_2_armv7l.whl", hash = "sha256:756b9ea5292a2c180d1fe782a377bc4159b3cfefaca7e41b5b0a00328ef62fa9", size = 361025, upload-time = "2025-04-06T02:35:32.904Z" },
- { url = "https://files.pythonhosted.org/packages/ca/f8/c4a190bcc3cd98fb428d1dd31519e58004153dc7f2acd1236ecae54e3433/yarl-1.19.0-cp313-cp313-musllinux_1_2_i686.whl", hash = "sha256:cbeb9c145d534c240a63b6ecc8a8dd451faeb67b3dc61d729ec197bb93e29497", size = 364397, upload-time = "2025-04-06T02:35:34.807Z" },
- { url = "https://files.pythonhosted.org/packages/6b/fb/f65b1347be8e12ac4e3e37a9bb880e6b9b604f252aaafd88e4879b1e9348/yarl-1.19.0-cp313-cp313-musllinux_1_2_ppc64le.whl", hash = "sha256:087ae8f8319848c18e0d114d0f56131a9c017f29200ab1413b0137ad7c83e2ae", size = 374065, upload-time = "2025-04-06T02:35:36.669Z" },
- { url = "https://files.pythonhosted.org/packages/1c/c5/102cc3b9baad1a76f9127453ad08e0f5bc9c996c18128b1e28fe03817d6c/yarl-1.19.0-cp313-cp313-musllinux_1_2_s390x.whl", hash = "sha256:362f5480ba527b6c26ff58cff1f229afe8b7fdd54ee5ffac2ab827c1a75fc71c", size = 381341, upload-time = "2025-04-06T02:35:38.912Z" },
- { url = "https://files.pythonhosted.org/packages/f7/ce/f5dc0439320dfe59fadab8cdd24ac324be19cf6ae4736422c7e2a510ddf3/yarl-1.19.0-cp313-cp313-musllinux_1_2_x86_64.whl", hash = "sha256:f408d4b4315e814e5c3668094e33d885f13c7809cbe831cbdc5b1bb8c7a448f4", size = 376552, upload-time = "2025-04-06T02:35:40.846Z" },
- { url = "https://files.pythonhosted.org/packages/a9/4a/4833a134c76af987eff3ce8cb71e42932234120e6be061eb2555061e8844/yarl-1.19.0-cp313-cp313-win32.whl", hash = "sha256:24e4c367ad69988a2283dd45ea88172561ca24b2326b9781e164eb46eea68345", size = 85878, upload-time = "2025-04-06T02:35:43.517Z" },
- { url = "https://files.pythonhosted.org/packages/32/e9/59327daab3af8f79221638a8f0d11474d20f6a8fbc41e9da80c5ef69e688/yarl-1.19.0-cp313-cp313-win_amd64.whl", hash = "sha256:0110f91c57ab43d1538dfa92d61c45e33b84df9257bd08fcfcda90cce931cbc9", size = 92448, upload-time = "2025-04-06T02:35:45.694Z" },
- { url = "https://files.pythonhosted.org/packages/a4/06/ae25a353e8f032322df6f30d6bb1fc329773ee48e1a80a2196ccb8d1206b/yarl-1.19.0-py3-none-any.whl", hash = "sha256:a727101eb27f66727576630d02985d8a065d09cd0b5fcbe38a5793f71b2a97ef", size = 45990, upload-time = "2025-04-06T02:36:24.343Z" },
-]
-
-[[package]]
-name = "yutto"
-version = "2.0.2"
-source = { registry = "https://pypi.org/simple" }
-dependencies = [
- { name = "aiofiles" },
- { name = "biliass" },
- { name = "colorama", marker = "sys_platform == 'win32'" },
- { name = "dict2xml" },
- { name = "httpx", extra = ["http2", "socks"] },
- { name = "pydantic" },
- { name = "tomli", marker = "python_full_version < '3.11'" },
- { name = "typing-extensions" },
-]
-sdist = { url = "https://files.pythonhosted.org/packages/4a/17/83e856294b8aaeb83b82cb74f5f5520cf5cb5c404be8f87ae7a4e6653525/yutto-2.0.2.tar.gz", hash = "sha256:7176d7361157ab8e473a93e799cca6301bad3b35c682d8788d6f3100f4144622", size = 326042, upload-time = "2025-03-15T15:58:16.012Z" }
-wheels = [
- { url = "https://files.pythonhosted.org/packages/73/d5/c5fc985804497af6d5430d59d20571a3a0d98981d633c68361e8501a0c34/yutto-2.0.2-py3-none-any.whl", hash = "sha256:e9ae2329b3c92830f51e4b9f0fdebe831e4374d879d3ce09f6e147690f9a0ff6", size = 103945, upload-time = "2025-03-15T15:58:13.032Z" },
-]
 -
 -
 -
 -
 -
 -
 -
 -
-
 -
 -
 -
 -
 -
 -
 -
-**2. 主页** 支持列表/网格切换与日期、分区筛选,一键实时更新,支持隐私模式。
-
 -
-**3. 评论** 登录后查看我的评论,支持关键词与类型筛选,并可跳转原文。
-
 -
-**4. 我的收藏** 支持查看我创建/收藏及本地收藏夹,可同步到本地并下载收藏内容。
-
 -
-**5. 媒体管理** 集中管理已下载视频与图片,查看/编辑备注与评论,并可批量补全视频详情。
-
 -
-**6. 计划任务** 统一管理定时与链式任务,支持新建/编辑/执行/启用或禁用,并查看历史与成功率。
-
 -
-**7. 设置** 配置服务器、隐私与布局、数据导出,也可以启用/关闭后端 MCP 只读服务并复制 AI 连接提示词。
-
 -
-**8. 视频下载功能** 输入 BV/链接或 UP UID 下载单个/合集/投稿,过程实时反馈。
-
 -
 -
 -
-
-**9. 动态下载** 输入用户MID下载B站动态内容,实时显示下载进度
-
 -
-
-## 使用 Tauri 构建桌面应用
-
-### GitHub Actions 自动构建(多平台包体)
-
-推送 tag(例如 `v1.0.0`)后,会自动在 GitHub Releases 里生成 Windows/macOS/Linux 的安装包与产物。
-
-**环境准备**
-
-1. 安装 Rust 开发环境
- - 按照 [Rust 官方指南](https://www.rust-lang.org/tools/install) 安装 Rust
- - Windows 用户还需安装 [Visual Studio C++ 构建工具](https://visualstudio.microsoft.com/visual-cpp-build-tools/)
-
-2. 安装 Node.js 依赖
- ```bash
- npm install
- ```
-
-**开发与构建**
-
-1. 开发模式
- ```bash
- npm run tauri:dev
- ```
- 这将启动一个开发服务器,并自动打开应用窗口,支持热重载。
-
-2. 构建可执行文件
- ```bash
- npm run tauri:build:exe
- ```
- 构建完成后,将在 `frontend/` 目录生成 `HistoryHub.exe` 可执行文件。
-
-3. 清理构建文件
- ```bash
- npm run tauri:clean
- ```
- 清理 `src-tauri/target` 目录中的构建产物,释放磁盘空间。
+前端默认连接 `http://localhost:8899`,可在“设置”中修改后端地址。
-## 贡献指南
+## B站历史
-欢迎提交 Issue 和 Pull Request 来帮助改进这个项目。
+在“设置”中扫码登录 B站,也可在后端 `config/config.yaml` 中配置 `SESSDATA`。点击“同步历史”获取观看记录;首次同步回填历史,之后续取新记录。已有本地历史无需当前登录即可查看和搜索,点击记录标题打开原链接。
-## 致谢
+## 网页历史
-- [bilibili-API-collect](https://github.com/SocialSisterYi/bilibili-API-collect) - 没有它就没有这个项目
-- [Yutto](https://yutto.nyakku.moe/) - 可爱的 B 站视频下载工具
-- [ArtPlayer](https://github.com/zhw2590582/ArtPlayer) - 强大且灵活的 HTML5 视频播放器
-- [aicu.cc](https://www.aicu.cc/) - 第三方 B 站用户评论 API
-- 所有贡献者,特别感谢:
- - [@eli-yip](https://github.com/eli-yip) 对 Docker 部署的贡献
- - [@QYG2297248353](https://github.com/QYG2297248353) 对 1Panel 部署的贡献
+在后端配置 `HISTORYHUB_SYNC_TOKEN`,或在 `config/config.yaml` 中设置 `browser_history.sync_token`。将 Chrome 扩展连接到同一后端并使用相同密钥,在“网页历史”输入密钥并保存连接。可按标题或网址搜索,点击标题打开原链接。
-## Star History
+网页历史无需 B站登录。连接密钥仅保存在当前浏览器,按后端地址隔离,仅随网页历史请求发送。浏览器扩展位于仓库的 [extension](../extension/) 目录。
-[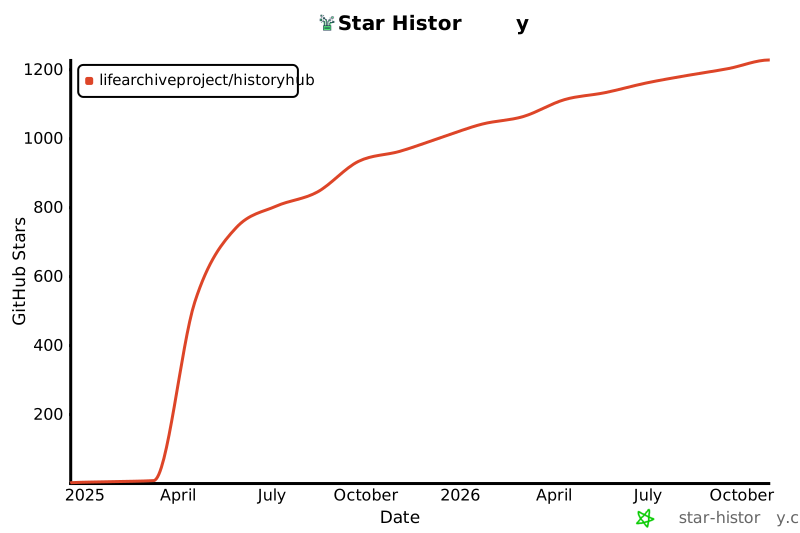](https://star-history.com/#LifeArchiveProject/HistoryHub&Date)
+设置中可切换深色模式和隐私模式。
diff --git a/frontend/bun.lock b/frontend/bun.lock
deleted file mode 100644
index 386a272..0000000
--- a/frontend/bun.lock
+++ /dev/null
@@ -1,817 +0,0 @@
-{
- "lockfileVersion": 1,
- "workspaces": {
- "": {
- "name": "historyhub-frontend",
- "dependencies": {
- "@headlessui/vue": "^1.7.23",
- "@heroicons/vue": "^2.1.5",
- "@tailwindcss/forms": "^0.5.9",
- "@vant/touch-emulator": "^1.4.0",
- "@vueuse/components": "^12.3.0",
- "@vueuse/core": "^12.3.0",
- "@vueuse/motion": "^2.2.6",
- "animate.css": "^4.1.1",
- "aos": "^2.3.4",
- "artplayer": "^5.2.2",
- "artplayer-plugin-danmuku": "^5.1.5",
- "axios": "^1.7.7",
- "crypto-js": "^4.2.0",
- "echarts": "^5.6.0",
- "echarts-wordcloud": "^2.1.0",
- "gsap": "^3.12.5",
- "jsencrypt": "^3.3.2",
- "lottie-web": "^5.12.2",
- "typeit": "^8.8.7",
- "vant": "^4.9.15",
- "vue": "^3.5.11",
- "vue-countup-v3": "^1.4.2",
- "vue-echarts": "^7.0.3",
- "vue-router": "^4.4.5",
- "vue3-lottie": "^3.3.1",
- },
- "devDependencies": {
- "@tauri-apps/api": "^2.4.0",
- "@tauri-apps/cli": "^2.4.0",
- "@types/node": "^20.17.6",
- "@vitejs/plugin-vue": "^5.1.4",
- "@vue/runtime-core": "^3.5.13",
- "autoprefixer": "^10.4.20",
- "cross-env": "^7.0.3",
- "postcss": "^8.4.47",
- "prettier": "^3.3.3",
- "prettier-plugin-tailwindcss": "^0.6.8",
- "tailwindcss": "^3.4.13",
- "vite": "^5.4.8",
- "vite-plugin-vue-inspector": "^5.3.1",
- },
- },
- },
- "packages": {
- "@alloc/quick-lru": ["@alloc/quick-lru@5.2.0", "", {}, "sha512-UrcABB+4bUrFABwbluTIBErXwvbsU/V7TZWfmbgJfbkwiBuziS9gxdODUyuiecfdGQ85jglMW6juS3+z5TsKLw=="],
-
- "@ampproject/remapping": ["@ampproject/remapping@2.3.0", "", { "dependencies": { "@jridgewell/gen-mapping": "^0.3.5", "@jridgewell/trace-mapping": "^0.3.24" } }, "sha512-30iZtAPgz+LTIYoeivqYo853f02jBYSd5uGnGpkFV0M3xOt9aN73erkgYAmZU43x4VfqcnLxW9Kpg3R5LC4YYw=="],
-
- "@babel/code-frame": ["@babel/code-frame@7.26.2", "", { "dependencies": { "@babel/helper-validator-identifier": "^7.25.9", "js-tokens": "^4.0.0", "picocolors": "^1.0.0" } }, "sha512-RJlIHRueQgwWitWgF8OdFYGZX328Ax5BCemNGlqHfplnRT9ESi8JkFlvaVYbS+UubVY6dpv87Fs2u5M29iNFVQ=="],
-
- "@babel/compat-data": ["@babel/compat-data@7.26.8", "", {}, "sha512-oH5UPLMWR3L2wEFLnFJ1TZXqHufiTKAiLfqw5zkhS4dKXLJ10yVztfil/twG8EDTA4F/tvVNw9nOl4ZMslB8rQ=="],
-
- "@babel/core": ["@babel/core@7.26.10", "", { "dependencies": { "@ampproject/remapping": "^2.2.0", "@babel/code-frame": "^7.26.2", "@babel/generator": "^7.26.10", "@babel/helper-compilation-targets": "^7.26.5", "@babel/helper-module-transforms": "^7.26.0", "@babel/helpers": "^7.26.10", "@babel/parser": "^7.26.10", "@babel/template": "^7.26.9", "@babel/traverse": "^7.26.10", "@babel/types": "^7.26.10", "convert-source-map": "^2.0.0", "debug": "^4.1.0", "gensync": "^1.0.0-beta.2", "json5": "^2.2.3", "semver": "^6.3.1" } }, "sha512-vMqyb7XCDMPvJFFOaT9kxtiRh42GwlZEg1/uIgtZshS5a/8OaduUfCi7kynKgc3Tw/6Uo2D+db9qBttghhmxwQ=="],
-
- "@babel/generator": ["@babel/generator@7.27.0", "", { "dependencies": { "@babel/parser": "^7.27.0", "@babel/types": "^7.27.0", "@jridgewell/gen-mapping": "^0.3.5", "@jridgewell/trace-mapping": "^0.3.25", "jsesc": "^3.0.2" } }, "sha512-VybsKvpiN1gU1sdMZIp7FcqphVVKEwcuj02x73uvcHE0PTihx1nlBcowYWhDwjpoAXRv43+gDzyggGnn1XZhVw=="],
-
- "@babel/helper-annotate-as-pure": ["@babel/helper-annotate-as-pure@7.25.9", "", { "dependencies": { "@babel/types": "^7.25.9" } }, "sha512-gv7320KBUFJz1RnylIg5WWYPRXKZ884AGkYpgpWW02TH66Dl+HaC1t1CKd0z3R4b6hdYEcmrNZHUmfCP+1u3/g=="],
-
- "@babel/helper-compilation-targets": ["@babel/helper-compilation-targets@7.27.0", "", { "dependencies": { "@babel/compat-data": "^7.26.8", "@babel/helper-validator-option": "^7.25.9", "browserslist": "^4.24.0", "lru-cache": "^5.1.1", "semver": "^6.3.1" } }, "sha512-LVk7fbXml0H2xH34dFzKQ7TDZ2G4/rVTOrq9V+icbbadjbVxxeFeDsNHv2SrZeWoA+6ZiTyWYWtScEIW07EAcA=="],
-
- "@babel/helper-create-class-features-plugin": ["@babel/helper-create-class-features-plugin@7.27.0", "", { "dependencies": { "@babel/helper-annotate-as-pure": "^7.25.9", "@babel/helper-member-expression-to-functions": "^7.25.9", "@babel/helper-optimise-call-expression": "^7.25.9", "@babel/helper-replace-supers": "^7.26.5", "@babel/helper-skip-transparent-expression-wrappers": "^7.25.9", "@babel/traverse": "^7.27.0", "semver": "^6.3.1" }, "peerDependencies": { "@babel/core": "^7.0.0" } }, "sha512-vSGCvMecvFCd/BdpGlhpXYNhhC4ccxyvQWpbGL4CWbvfEoLFWUZuSuf7s9Aw70flgQF+6vptvgK2IfOnKlRmBg=="],
-
- "@babel/helper-member-expression-to-functions": ["@babel/helper-member-expression-to-functions@7.25.9", "", { "dependencies": { "@babel/traverse": "^7.25.9", "@babel/types": "^7.25.9" } }, "sha512-wbfdZ9w5vk0C0oyHqAJbc62+vet5prjj01jjJ8sKn3j9h3MQQlflEdXYvuqRWjHnM12coDEqiC1IRCi0U/EKwQ=="],
-
- "@babel/helper-module-imports": ["@babel/helper-module-imports@7.25.9", "", { "dependencies": { "@babel/traverse": "^7.25.9", "@babel/types": "^7.25.9" } }, "sha512-tnUA4RsrmflIM6W6RFTLFSXITtl0wKjgpnLgXyowocVPrbYrLUXSBXDgTs8BlbmIzIdlBySRQjINYs2BAkiLtw=="],
-
- "@babel/helper-module-transforms": ["@babel/helper-module-transforms@7.26.0", "", { "dependencies": { "@babel/helper-module-imports": "^7.25.9", "@babel/helper-validator-identifier": "^7.25.9", "@babel/traverse": "^7.25.9" }, "peerDependencies": { "@babel/core": "^7.0.0" } }, "sha512-xO+xu6B5K2czEnQye6BHA7DolFFmS3LB7stHZFaOLb1pAwO1HWLS8fXA+eh0A2yIvltPVmx3eNNDBJA2SLHXFw=="],
-
- "@babel/helper-optimise-call-expression": ["@babel/helper-optimise-call-expression@7.25.9", "", { "dependencies": { "@babel/types": "^7.25.9" } }, "sha512-FIpuNaz5ow8VyrYcnXQTDRGvV6tTjkNtCK/RYNDXGSLlUD6cBuQTSw43CShGxjvfBTfcUA/r6UhUCbtYqkhcuQ=="],
-
- "@babel/helper-plugin-utils": ["@babel/helper-plugin-utils@7.26.5", "", {}, "sha512-RS+jZcRdZdRFzMyr+wcsaqOmld1/EqTghfaBGQQd/WnRdzdlvSZ//kF7U8VQTxf1ynZ4cjUcYgjVGx13ewNPMg=="],
-
- "@babel/helper-replace-supers": ["@babel/helper-replace-supers@7.26.5", "", { "dependencies": { "@babel/helper-member-expression-to-functions": "^7.25.9", "@babel/helper-optimise-call-expression": "^7.25.9", "@babel/traverse": "^7.26.5" }, "peerDependencies": { "@babel/core": "^7.0.0" } }, "sha512-bJ6iIVdYX1YooY2X7w1q6VITt+LnUILtNk7zT78ykuwStx8BauCzxvFqFaHjOpW1bVnSUM1PN1f0p5P21wHxvg=="],
-
- "@babel/helper-skip-transparent-expression-wrappers": ["@babel/helper-skip-transparent-expression-wrappers@7.25.9", "", { "dependencies": { "@babel/traverse": "^7.25.9", "@babel/types": "^7.25.9" } }, "sha512-K4Du3BFa3gvyhzgPcntrkDgZzQaq6uozzcpGbOO1OEJaI+EJdqWIMTLgFgQf6lrfiDFo5FU+BxKepI9RmZqahA=="],
-
- "@babel/helper-string-parser": ["@babel/helper-string-parser@7.25.9", "", {}, "sha512-4A/SCr/2KLd5jrtOMFzaKjVtAei3+2r/NChoBNoZ3EyP/+GlhoaEGoWOZUmFmoITP7zOJyHIMm+DYRd8o3PvHA=="],
-
- "@babel/helper-validator-identifier": ["@babel/helper-validator-identifier@7.25.9", "", {}, "sha512-Ed61U6XJc3CVRfkERJWDz4dJwKe7iLmmJsbOGu9wSloNSFttHV0I8g6UAgb7qnK5ly5bGLPd4oXZlxCdANBOWQ=="],
-
- "@babel/helper-validator-option": ["@babel/helper-validator-option@7.25.9", "", {}, "sha512-e/zv1co8pp55dNdEcCynfj9X7nyUKUXoUEwfXqaZt0omVOmDe9oOTdKStH4GmAw6zxMFs50ZayuMfHDKlO7Tfw=="],
-
- "@babel/helpers": ["@babel/helpers@7.27.0", "", { "dependencies": { "@babel/template": "^7.27.0", "@babel/types": "^7.27.0" } }, "sha512-U5eyP/CTFPuNE3qk+WZMxFkp/4zUzdceQlfzf7DdGdhp+Fezd7HD+i8Y24ZuTMKX3wQBld449jijbGq6OdGNQg=="],
-
- "@babel/parser": ["@babel/parser@7.27.0", "", { "dependencies": { "@babel/types": "^7.27.0" }, "bin": "./bin/babel-parser.js" }, "sha512-iaepho73/2Pz7w2eMS0Q5f83+0RKI7i4xmiYeBmDzfRVbQtTOG7Ts0S4HzJVsTMGI9keU8rNfuZr8DKfSt7Yyg=="],
-
- "@babel/plugin-proposal-decorators": ["@babel/plugin-proposal-decorators@7.25.9", "", { "dependencies": { "@babel/helper-create-class-features-plugin": "^7.25.9", "@babel/helper-plugin-utils": "^7.25.9", "@babel/plugin-syntax-decorators": "^7.25.9" }, "peerDependencies": { "@babel/core": "^7.0.0-0" } }, "sha512-smkNLL/O1ezy9Nhy4CNosc4Va+1wo5w4gzSZeLe6y6dM4mmHfYOCPolXQPHQxonZCF+ZyebxN9vqOolkYrSn5g=="],
-
- "@babel/plugin-syntax-decorators": ["@babel/plugin-syntax-decorators@7.25.9", "", { "dependencies": { "@babel/helper-plugin-utils": "^7.25.9" }, "peerDependencies": { "@babel/core": "^7.0.0-0" } }, "sha512-ryzI0McXUPJnRCvMo4lumIKZUzhYUO/ScI+Mz4YVaTLt04DHNSjEUjKVvbzQjZFLuod/cYEc07mJWhzl6v4DPg=="],
-
- "@babel/plugin-syntax-import-attributes": ["@babel/plugin-syntax-import-attributes@7.26.0", "", { "dependencies": { "@babel/helper-plugin-utils": "^7.25.9" }, "peerDependencies": { "@babel/core": "^7.0.0-0" } }, "sha512-e2dttdsJ1ZTpi3B9UYGLw41hifAubg19AtCu/2I/F1QNVclOBr1dYpTdmdyZ84Xiz43BS/tCUkMAZNLv12Pi+A=="],
-
- "@babel/plugin-syntax-import-meta": ["@babel/plugin-syntax-import-meta@7.10.4", "", { "dependencies": { "@babel/helper-plugin-utils": "^7.10.4" }, "peerDependencies": { "@babel/core": "^7.0.0-0" } }, "sha512-Yqfm+XDx0+Prh3VSeEQCPU81yC+JWZ2pDPFSS4ZdpfZhp4MkFMaDC1UqseovEKwSUpnIL7+vK+Clp7bfh0iD7g=="],
-
- "@babel/plugin-syntax-jsx": ["@babel/plugin-syntax-jsx@7.25.9", "", { "dependencies": { "@babel/helper-plugin-utils": "^7.25.9" }, "peerDependencies": { "@babel/core": "^7.0.0-0" } }, "sha512-ld6oezHQMZsZfp6pWtbjaNDF2tiiCYYDqQszHt5VV437lewP9aSi2Of99CK0D0XB21k7FLgnLcmQKyKzynfeAA=="],
-
- "@babel/plugin-syntax-typescript": ["@babel/plugin-syntax-typescript@7.25.9", "", { "dependencies": { "@babel/helper-plugin-utils": "^7.25.9" }, "peerDependencies": { "@babel/core": "^7.0.0-0" } }, "sha512-hjMgRy5hb8uJJjUcdWunWVcoi9bGpJp8p5Ol1229PoN6aytsLwNMgmdftO23wnCLMfVmTwZDWMPNq/D1SY60JQ=="],
-
- "@babel/plugin-transform-typescript": ["@babel/plugin-transform-typescript@7.27.0", "", { "dependencies": { "@babel/helper-annotate-as-pure": "^7.25.9", "@babel/helper-create-class-features-plugin": "^7.27.0", "@babel/helper-plugin-utils": "^7.26.5", "@babel/helper-skip-transparent-expression-wrappers": "^7.25.9", "@babel/plugin-syntax-typescript": "^7.25.9" }, "peerDependencies": { "@babel/core": "^7.0.0-0" } }, "sha512-fRGGjO2UEGPjvEcyAZXRXAS8AfdaQoq7HnxAbJoAoW10B9xOKesmmndJv+Sym2a+9FHWZ9KbyyLCe9s0Sn5jtg=="],
-
- "@babel/template": ["@babel/template@7.27.0", "", { "dependencies": { "@babel/code-frame": "^7.26.2", "@babel/parser": "^7.27.0", "@babel/types": "^7.27.0" } }, "sha512-2ncevenBqXI6qRMukPlXwHKHchC7RyMuu4xv5JBXRfOGVcTy1mXCD12qrp7Jsoxll1EV3+9sE4GugBVRjT2jFA=="],
-
- "@babel/traverse": ["@babel/traverse@7.27.0", "", { "dependencies": { "@babel/code-frame": "^7.26.2", "@babel/generator": "^7.27.0", "@babel/parser": "^7.27.0", "@babel/template": "^7.27.0", "@babel/types": "^7.27.0", "debug": "^4.3.1", "globals": "^11.1.0" } }, "sha512-19lYZFzYVQkkHkl4Cy4WrAVcqBkgvV2YM2TU3xG6DIwO7O3ecbDPfW3yM3bjAGcqcQHi+CCtjMR3dIEHxsd6bA=="],
-
- "@babel/types": ["@babel/types@7.27.0", "", { "dependencies": { "@babel/helper-string-parser": "^7.25.9", "@babel/helper-validator-identifier": "^7.25.9" } }, "sha512-H45s8fVLYjbhFH62dIJ3WtmJ6RSPt/3DRO0ZcT2SUiYiQyz3BLVb9ADEnLl91m74aQPS3AzzeajZHYOalWe3bg=="],
-
- "@esbuild/aix-ppc64": ["@esbuild/aix-ppc64@0.21.5", "", { "os": "aix", "cpu": "ppc64" }, "sha512-1SDgH6ZSPTlggy1yI6+Dbkiz8xzpHJEVAlF/AM1tHPLsf5STom9rwtjE4hKAF20FfXXNTFqEYXyJNWh1GiZedQ=="],
-
- "@esbuild/android-arm": ["@esbuild/android-arm@0.21.5", "", { "os": "android", "cpu": "arm" }, "sha512-vCPvzSjpPHEi1siZdlvAlsPxXl7WbOVUBBAowWug4rJHb68Ox8KualB+1ocNvT5fjv6wpkX6o/iEpbDrf68zcg=="],
-
- "@esbuild/android-arm64": ["@esbuild/android-arm64@0.21.5", "", { "os": "android", "cpu": "arm64" }, "sha512-c0uX9VAUBQ7dTDCjq+wdyGLowMdtR/GoC2U5IYk/7D1H1JYC0qseD7+11iMP2mRLN9RcCMRcjC4YMclCzGwS/A=="],
-
- "@esbuild/android-x64": ["@esbuild/android-x64@0.21.5", "", { "os": "android", "cpu": "x64" }, "sha512-D7aPRUUNHRBwHxzxRvp856rjUHRFW1SdQATKXH2hqA0kAZb1hKmi02OpYRacl0TxIGz/ZmXWlbZgjwWYaCakTA=="],
-
- "@esbuild/darwin-arm64": ["@esbuild/darwin-arm64@0.21.5", "", { "os": "darwin", "cpu": "arm64" }, "sha512-DwqXqZyuk5AiWWf3UfLiRDJ5EDd49zg6O9wclZ7kUMv2WRFr4HKjXp/5t8JZ11QbQfUS6/cRCKGwYhtNAY88kQ=="],
-
- "@esbuild/darwin-x64": ["@esbuild/darwin-x64@0.21.5", "", { "os": "darwin", "cpu": "x64" }, "sha512-se/JjF8NlmKVG4kNIuyWMV/22ZaerB+qaSi5MdrXtd6R08kvs2qCN4C09miupktDitvh8jRFflwGFBQcxZRjbw=="],
-
- "@esbuild/freebsd-arm64": ["@esbuild/freebsd-arm64@0.21.5", "", { "os": "freebsd", "cpu": "arm64" }, "sha512-5JcRxxRDUJLX8JXp/wcBCy3pENnCgBR9bN6JsY4OmhfUtIHe3ZW0mawA7+RDAcMLrMIZaf03NlQiX9DGyB8h4g=="],
-
- "@esbuild/freebsd-x64": ["@esbuild/freebsd-x64@0.21.5", "", { "os": "freebsd", "cpu": "x64" }, "sha512-J95kNBj1zkbMXtHVH29bBriQygMXqoVQOQYA+ISs0/2l3T9/kj42ow2mpqerRBxDJnmkUDCaQT/dfNXWX/ZZCQ=="],
-
- "@esbuild/linux-arm": ["@esbuild/linux-arm@0.21.5", "", { "os": "linux", "cpu": "arm" }, "sha512-bPb5AHZtbeNGjCKVZ9UGqGwo8EUu4cLq68E95A53KlxAPRmUyYv2D6F0uUI65XisGOL1hBP5mTronbgo+0bFcA=="],
-
- "@esbuild/linux-arm64": ["@esbuild/linux-arm64@0.21.5", "", { "os": "linux", "cpu": "arm64" }, "sha512-ibKvmyYzKsBeX8d8I7MH/TMfWDXBF3db4qM6sy+7re0YXya+K1cem3on9XgdT2EQGMu4hQyZhan7TeQ8XkGp4Q=="],
-
- "@esbuild/linux-ia32": ["@esbuild/linux-ia32@0.21.5", "", { "os": "linux", "cpu": "ia32" }, "sha512-YvjXDqLRqPDl2dvRODYmmhz4rPeVKYvppfGYKSNGdyZkA01046pLWyRKKI3ax8fbJoK5QbxblURkwK/MWY18Tg=="],
-
- "@esbuild/linux-loong64": ["@esbuild/linux-loong64@0.21.5", "", { "os": "linux", "cpu": "none" }, "sha512-uHf1BmMG8qEvzdrzAqg2SIG/02+4/DHB6a9Kbya0XDvwDEKCoC8ZRWI5JJvNdUjtciBGFQ5PuBlpEOXQj+JQSg=="],
-
- "@esbuild/linux-mips64el": ["@esbuild/linux-mips64el@0.21.5", "", { "os": "linux", "cpu": "none" }, "sha512-IajOmO+KJK23bj52dFSNCMsz1QP1DqM6cwLUv3W1QwyxkyIWecfafnI555fvSGqEKwjMXVLokcV5ygHW5b3Jbg=="],
-
- "@esbuild/linux-ppc64": ["@esbuild/linux-ppc64@0.21.5", "", { "os": "linux", "cpu": "ppc64" }, "sha512-1hHV/Z4OEfMwpLO8rp7CvlhBDnjsC3CttJXIhBi+5Aj5r+MBvy4egg7wCbe//hSsT+RvDAG7s81tAvpL2XAE4w=="],
-
- "@esbuild/linux-riscv64": ["@esbuild/linux-riscv64@0.21.5", "", { "os": "linux", "cpu": "none" }, "sha512-2HdXDMd9GMgTGrPWnJzP2ALSokE/0O5HhTUvWIbD3YdjME8JwvSCnNGBnTThKGEB91OZhzrJ4qIIxk/SBmyDDA=="],
-
- "@esbuild/linux-s390x": ["@esbuild/linux-s390x@0.21.5", "", { "os": "linux", "cpu": "s390x" }, "sha512-zus5sxzqBJD3eXxwvjN1yQkRepANgxE9lgOW2qLnmr8ikMTphkjgXu1HR01K4FJg8h1kEEDAqDcZQtbrRnB41A=="],
-
- "@esbuild/linux-x64": ["@esbuild/linux-x64@0.21.5", "", { "os": "linux", "cpu": "x64" }, "sha512-1rYdTpyv03iycF1+BhzrzQJCdOuAOtaqHTWJZCWvijKD2N5Xu0TtVC8/+1faWqcP9iBCWOmjmhoH94dH82BxPQ=="],
-
- "@esbuild/netbsd-x64": ["@esbuild/netbsd-x64@0.21.5", "", { "os": "none", "cpu": "x64" }, "sha512-Woi2MXzXjMULccIwMnLciyZH4nCIMpWQAs049KEeMvOcNADVxo0UBIQPfSmxB3CWKedngg7sWZdLvLczpe0tLg=="],
-
- "@esbuild/openbsd-x64": ["@esbuild/openbsd-x64@0.21.5", "", { "os": "openbsd", "cpu": "x64" }, "sha512-HLNNw99xsvx12lFBUwoT8EVCsSvRNDVxNpjZ7bPn947b8gJPzeHWyNVhFsaerc0n3TsbOINvRP2byTZ5LKezow=="],
-
- "@esbuild/sunos-x64": ["@esbuild/sunos-x64@0.21.5", "", { "os": "sunos", "cpu": "x64" }, "sha512-6+gjmFpfy0BHU5Tpptkuh8+uw3mnrvgs+dSPQXQOv3ekbordwnzTVEb4qnIvQcYXq6gzkyTnoZ9dZG+D4garKg=="],
-
- "@esbuild/win32-arm64": ["@esbuild/win32-arm64@0.21.5", "", { "os": "win32", "cpu": "arm64" }, "sha512-Z0gOTd75VvXqyq7nsl93zwahcTROgqvuAcYDUr+vOv8uHhNSKROyU961kgtCD1e95IqPKSQKH7tBTslnS3tA8A=="],
-
- "@esbuild/win32-ia32": ["@esbuild/win32-ia32@0.21.5", "", { "os": "win32", "cpu": "ia32" }, "sha512-SWXFF1CL2RVNMaVs+BBClwtfZSvDgtL//G/smwAc5oVK/UPu2Gu9tIaRgFmYFFKrmg3SyAjSrElf0TiJ1v8fYA=="],
-
- "@esbuild/win32-x64": ["@esbuild/win32-x64@0.21.5", "", { "os": "win32", "cpu": "x64" }, "sha512-tQd/1efJuzPC6rCFwEvLtci/xNFcTZknmXs98FYDfGE4wP9ClFV98nyKrzJKVPMhdDnjzLhdUyMX4PsQAPjwIw=="],
-
- "@headlessui/vue": ["@headlessui/vue@1.7.23", "", { "dependencies": { "@tanstack/vue-virtual": "^3.0.0-beta.60" }, "peerDependencies": { "vue": "^3.2.0" } }, "sha512-JzdCNqurrtuu0YW6QaDtR2PIYCKPUWq28csDyMvN4zmGccmE7lz40Is6hc3LA4HFeCI7sekZ/PQMTNmn9I/4Wg=="],
-
- "@heroicons/vue": ["@heroicons/vue@2.2.0", "", { "peerDependencies": { "vue": ">= 3" } }, "sha512-G3dbSxoeEKqbi/DFalhRxJU4mTXJn7GwZ7ae8NuEQzd1bqdd0jAbdaBZlHPcvPD2xI1iGzNVB4k20Un2AguYPw=="],
-
- "@isaacs/cliui": ["@isaacs/cliui@8.0.2", "", { "dependencies": { "string-width": "^5.1.2", "string-width-cjs": "npm:string-width@^4.2.0", "strip-ansi": "^7.0.1", "strip-ansi-cjs": "npm:strip-ansi@^6.0.1", "wrap-ansi": "^8.1.0", "wrap-ansi-cjs": "npm:wrap-ansi@^7.0.0" } }, "sha512-O8jcjabXaleOG9DQ0+ARXWZBTfnP4WNAqzuiJK7ll44AmxGKv/J2M4TPjxjY3znBCfvBXFzucm1twdyFybFqEA=="],
-
- "@jridgewell/gen-mapping": ["@jridgewell/gen-mapping@0.3.8", "", { "dependencies": { "@jridgewell/set-array": "^1.2.1", "@jridgewell/sourcemap-codec": "^1.4.10", "@jridgewell/trace-mapping": "^0.3.24" } }, "sha512-imAbBGkb+ebQyxKgzv5Hu2nmROxoDOXHh80evxdoXNOrvAnVx7zimzc1Oo5h9RlfV4vPXaE2iM5pOFbvOCClWA=="],
-
- "@jridgewell/resolve-uri": ["@jridgewell/resolve-uri@3.1.2", "", {}, "sha512-bRISgCIjP20/tbWSPWMEi54QVPRZExkuD9lJL+UIxUKtwVJA8wW1Trb1jMs1RFXo1CBTNZ/5hpC9QvmKWdopKw=="],
-
- "@jridgewell/set-array": ["@jridgewell/set-array@1.2.1", "", {}, "sha512-R8gLRTZeyp03ymzP/6Lil/28tGeGEzhx1q2k703KGWRAI1VdvPIXdG70VJc2pAMw3NA6JKL5hhFu1sJX0Mnn/A=="],
-
- "@jridgewell/sourcemap-codec": ["@jridgewell/sourcemap-codec@1.5.0", "", {}, "sha512-gv3ZRaISU3fjPAgNsriBRqGWQL6quFx04YMPW/zD8XMLsU32mhCCbfbO6KZFLjvYpCZ8zyDEgqsgf+PwPaM7GQ=="],
-
- "@jridgewell/trace-mapping": ["@jridgewell/trace-mapping@0.3.25", "", { "dependencies": { "@jridgewell/resolve-uri": "^3.1.0", "@jridgewell/sourcemap-codec": "^1.4.14" } }, "sha512-vNk6aEwybGtawWmy/PzwnGDOjCkLWSD2wqvjGGAgOAwCGWySYXfYoxt00IJkTF+8Lb57DwOb3Aa0o9CApepiYQ=="],
-
- "@nodelib/fs.scandir": ["@nodelib/fs.scandir@2.1.5", "", { "dependencies": { "@nodelib/fs.stat": "2.0.5", "run-parallel": "^1.1.9" } }, "sha512-vq24Bq3ym5HEQm2NKCr3yXDwjc7vTsEThRDnkp2DK9p1uqLR+DHurm/NOTo0KG7HYHU7eppKZj3MyqYuMBf62g=="],
-
- "@nodelib/fs.stat": ["@nodelib/fs.stat@2.0.5", "", {}, "sha512-RkhPPp2zrqDAQA/2jNhnztcPAlv64XdhIp7a7454A5ovI7Bukxgt7MX7udwAu3zg1DcpPU0rz3VV1SeaqvY4+A=="],
-
- "@nodelib/fs.walk": ["@nodelib/fs.walk@1.2.8", "", { "dependencies": { "@nodelib/fs.scandir": "2.1.5", "fastq": "^1.6.0" } }, "sha512-oGB+UxlgWcgQkgwo8GcEGwemoTFt3FIO9ababBmaGwXIoBKZ+GTy0pP185beGg7Llih/NSHSV2XAs1lnznocSg=="],
-
- "@nuxt/kit": ["@nuxt/kit@3.16.2", "", { "dependencies": { "c12": "^3.0.2", "consola": "^3.4.2", "defu": "^6.1.4", "destr": "^2.0.3", "errx": "^0.1.0", "exsolve": "^1.0.4", "globby": "^14.1.0", "ignore": "^7.0.3", "jiti": "^2.4.2", "klona": "^2.0.6", "knitwork": "^1.2.0", "mlly": "^1.7.4", "ohash": "^2.0.11", "pathe": "^2.0.3", "pkg-types": "^2.1.0", "scule": "^1.3.0", "semver": "^7.7.1", "std-env": "^3.8.1", "ufo": "^1.5.4", "unctx": "^2.4.1", "unimport": "^4.1.3", "untyped": "^2.0.0" } }, "sha512-K1SAUo2vweTfudKZzjKsZ5YJoxPLTspR5qz5+G61xtZreLpsdpDYfBseqsIAl5VFLJuszeRpWQ01jP9LfQ6Ksw=="],
-
- "@pkgjs/parseargs": ["@pkgjs/parseargs@0.11.0", "", {}, "sha512-+1VkjdD0QBLPodGrJUeqarH8VAIvQODIbwh9XpP5Syisf7YoQgsJKPNFoqqLQlu+VQ/tVSshMR6loPMn8U+dPg=="],
-
- "@rollup/rollup-android-arm-eabi": ["@rollup/rollup-android-arm-eabi@4.39.0", "", { "os": "android", "cpu": "arm" }, "sha512-lGVys55Qb00Wvh8DMAocp5kIcaNzEFTmGhfFd88LfaogYTRKrdxgtlO5H6S49v2Nd8R2C6wLOal0qv6/kCkOwA=="],
-
- "@rollup/rollup-android-arm64": ["@rollup/rollup-android-arm64@4.39.0", "", { "os": "android", "cpu": "arm64" }, "sha512-It9+M1zE31KWfqh/0cJLrrsCPiF72PoJjIChLX+rEcujVRCb4NLQ5QzFkzIZW8Kn8FTbvGQBY5TkKBau3S8cCQ=="],
-
- "@rollup/rollup-darwin-arm64": ["@rollup/rollup-darwin-arm64@4.39.0", "", { "os": "darwin", "cpu": "arm64" }, "sha512-lXQnhpFDOKDXiGxsU9/l8UEGGM65comrQuZ+lDcGUx+9YQ9dKpF3rSEGepyeR5AHZ0b5RgiligsBhWZfSSQh8Q=="],
-
- "@rollup/rollup-darwin-x64": ["@rollup/rollup-darwin-x64@4.39.0", "", { "os": "darwin", "cpu": "x64" }, "sha512-mKXpNZLvtEbgu6WCkNij7CGycdw9cJi2k9v0noMb++Vab12GZjFgUXD69ilAbBh034Zwn95c2PNSz9xM7KYEAQ=="],
-
- "@rollup/rollup-freebsd-arm64": ["@rollup/rollup-freebsd-arm64@4.39.0", "", { "os": "freebsd", "cpu": "arm64" }, "sha512-jivRRlh2Lod/KvDZx2zUR+I4iBfHcu2V/BA2vasUtdtTN2Uk3jfcZczLa81ESHZHPHy4ih3T/W5rPFZ/hX7RtQ=="],
-
- "@rollup/rollup-freebsd-x64": ["@rollup/rollup-freebsd-x64@4.39.0", "", { "os": "freebsd", "cpu": "x64" }, "sha512-8RXIWvYIRK9nO+bhVz8DwLBepcptw633gv/QT4015CpJ0Ht8punmoHU/DuEd3iw9Hr8UwUV+t+VNNuZIWYeY7Q=="],
-
- "@rollup/rollup-linux-arm-gnueabihf": ["@rollup/rollup-linux-arm-gnueabihf@4.39.0", "", { "os": "linux", "cpu": "arm" }, "sha512-mz5POx5Zu58f2xAG5RaRRhp3IZDK7zXGk5sdEDj4o96HeaXhlUwmLFzNlc4hCQi5sGdR12VDgEUqVSHer0lI9g=="],
-
- "@rollup/rollup-linux-arm-musleabihf": ["@rollup/rollup-linux-arm-musleabihf@4.39.0", "", { "os": "linux", "cpu": "arm" }, "sha512-+YDwhM6gUAyakl0CD+bMFpdmwIoRDzZYaTWV3SDRBGkMU/VpIBYXXEvkEcTagw/7VVkL2vA29zU4UVy1mP0/Yw=="],
-
- "@rollup/rollup-linux-arm64-gnu": ["@rollup/rollup-linux-arm64-gnu@4.39.0", "", { "os": "linux", "cpu": "arm64" }, "sha512-EKf7iF7aK36eEChvlgxGnk7pdJfzfQbNvGV/+l98iiMwU23MwvmV0Ty3pJ0p5WQfm3JRHOytSIqD9LB7Bq7xdQ=="],
-
- "@rollup/rollup-linux-arm64-musl": ["@rollup/rollup-linux-arm64-musl@4.39.0", "", { "os": "linux", "cpu": "arm64" }, "sha512-vYanR6MtqC7Z2SNr8gzVnzUul09Wi1kZqJaek3KcIlI/wq5Xtq4ZPIZ0Mr/st/sv/NnaPwy/D4yXg5x0B3aUUA=="],
-
- "@rollup/rollup-linux-loongarch64-gnu": ["@rollup/rollup-linux-loongarch64-gnu@4.39.0", "", { "os": "linux", "cpu": "none" }, "sha512-NMRUT40+h0FBa5fb+cpxtZoGAggRem16ocVKIv5gDB5uLDgBIwrIsXlGqYbLwW8YyO3WVTk1FkFDjMETYlDqiw=="],
-
- "@rollup/rollup-linux-powerpc64le-gnu": ["@rollup/rollup-linux-powerpc64le-gnu@4.39.0", "", { "os": "linux", "cpu": "ppc64" }, "sha512-0pCNnmxgduJ3YRt+D+kJ6Ai/r+TaePu9ZLENl+ZDV/CdVczXl95CbIiwwswu4L+K7uOIGf6tMo2vm8uadRaICQ=="],
-
- "@rollup/rollup-linux-riscv64-gnu": ["@rollup/rollup-linux-riscv64-gnu@4.39.0", "", { "os": "linux", "cpu": "none" }, "sha512-t7j5Zhr7S4bBtksT73bO6c3Qa2AV/HqiGlj9+KB3gNF5upcVkx+HLgxTm8DK4OkzsOYqbdqbLKwvGMhylJCPhQ=="],
-
- "@rollup/rollup-linux-riscv64-musl": ["@rollup/rollup-linux-riscv64-musl@4.39.0", "", { "os": "linux", "cpu": "none" }, "sha512-m6cwI86IvQ7M93MQ2RF5SP8tUjD39Y7rjb1qjHgYh28uAPVU8+k/xYWvxRO3/tBN2pZkSMa5RjnPuUIbrwVxeA=="],
-
- "@rollup/rollup-linux-s390x-gnu": ["@rollup/rollup-linux-s390x-gnu@4.39.0", "", { "os": "linux", "cpu": "s390x" }, "sha512-iRDJd2ebMunnk2rsSBYlsptCyuINvxUfGwOUldjv5M4tpa93K8tFMeYGpNk2+Nxl+OBJnBzy2/JCscGeO507kA=="],
-
- "@rollup/rollup-linux-x64-gnu": ["@rollup/rollup-linux-x64-gnu@4.39.0", "", { "os": "linux", "cpu": "x64" }, "sha512-t9jqYw27R6Lx0XKfEFe5vUeEJ5pF3SGIM6gTfONSMb7DuG6z6wfj2yjcoZxHg129veTqU7+wOhY6GX8wmf90dA=="],
-
- "@rollup/rollup-linux-x64-musl": ["@rollup/rollup-linux-x64-musl@4.39.0", "", { "os": "linux", "cpu": "x64" }, "sha512-ThFdkrFDP55AIsIZDKSBWEt/JcWlCzydbZHinZ0F/r1h83qbGeenCt/G/wG2O0reuENDD2tawfAj2s8VK7Bugg=="],
-
- "@rollup/rollup-win32-arm64-msvc": ["@rollup/rollup-win32-arm64-msvc@4.39.0", "", { "os": "win32", "cpu": "arm64" }, "sha512-jDrLm6yUtbOg2TYB3sBF3acUnAwsIksEYjLeHL+TJv9jg+TmTwdyjnDex27jqEMakNKf3RwwPahDIt7QXCSqRQ=="],
-
- "@rollup/rollup-win32-ia32-msvc": ["@rollup/rollup-win32-ia32-msvc@4.39.0", "", { "os": "win32", "cpu": "ia32" }, "sha512-6w9uMuza+LbLCVoNKL5FSLE7yvYkq9laSd09bwS0tMjkwXrmib/4KmoJcrKhLWHvw19mwU+33ndC69T7weNNjQ=="],
-
- "@rollup/rollup-win32-x64-msvc": ["@rollup/rollup-win32-x64-msvc@4.39.0", "", { "os": "win32", "cpu": "x64" }, "sha512-yAkUOkIKZlK5dl7u6dg897doBgLXmUHhIINM2c+sND3DZwnrdQkkSiDh7N75Ll4mM4dxSkYfXqU9fW3lLkMFug=="],
-
- "@sindresorhus/merge-streams": ["@sindresorhus/merge-streams@2.3.0", "", {}, "sha512-LtoMMhxAlorcGhmFYI+LhPgbPZCkgP6ra1YL604EeF6U98pLlQ3iWIGMdWSC+vWmPBWBNgmDBAhnAobLROJmwg=="],
-
- "@tailwindcss/forms": ["@tailwindcss/forms@0.5.10", "", { "dependencies": { "mini-svg-data-uri": "^1.2.3" }, "peerDependencies": { "tailwindcss": ">=3.0.0 || >= 3.0.0-alpha.1 || >= 4.0.0-alpha.20 || >= 4.0.0-beta.1" } }, "sha512-utI1ONF6uf/pPNO68kmN1b8rEwNXv3czukalo8VtJH8ksIkZXr3Q3VYudZLkCsDd4Wku120uF02hYK25XGPorw=="],
-
- "@tanstack/virtual-core": ["@tanstack/virtual-core@3.13.6", "", {}, "sha512-cnQUeWnhNP8tJ4WsGcYiX24Gjkc9ALstLbHcBj1t3E7EimN6n6kHH+DPV4PpDnuw00NApQp+ViojMj1GRdwYQg=="],
-
- "@tanstack/vue-virtual": ["@tanstack/vue-virtual@3.13.6", "", { "dependencies": { "@tanstack/virtual-core": "3.13.6" }, "peerDependencies": { "vue": "^2.7.0 || ^3.0.0" } }, "sha512-GYdZ3SJBQPzgxhuCE2fvpiH46qzHiVx5XzBSdtESgiqh4poj8UgckjGWYEhxaBbcVt1oLzh1m3Ql4TyH32TOzQ=="],
-
- "@tauri-apps/api": ["@tauri-apps/api@2.4.1", "", {}, "sha512-5sYwZCSJb6PBGbBL4kt7CnE5HHbBqwH+ovmOW6ZVju3nX4E3JX6tt2kRklFEH7xMOIwR0btRkZktuLhKvyEQYg=="],
-
- "@tauri-apps/cli": ["@tauri-apps/cli@2.4.1", "", { "optionalDependencies": { "@tauri-apps/cli-darwin-arm64": "2.4.1", "@tauri-apps/cli-darwin-x64": "2.4.1", "@tauri-apps/cli-linux-arm-gnueabihf": "2.4.1", "@tauri-apps/cli-linux-arm64-gnu": "2.4.1", "@tauri-apps/cli-linux-arm64-musl": "2.4.1", "@tauri-apps/cli-linux-riscv64-gnu": "2.4.1", "@tauri-apps/cli-linux-x64-gnu": "2.4.1", "@tauri-apps/cli-linux-x64-musl": "2.4.1", "@tauri-apps/cli-win32-arm64-msvc": "2.4.1", "@tauri-apps/cli-win32-ia32-msvc": "2.4.1", "@tauri-apps/cli-win32-x64-msvc": "2.4.1" }, "bin": { "tauri": "tauri.js" } }, "sha512-9Ta81jx9+57FhtU/mPIckDcOBtPTUdKM75t4+aA0X84b8Sclb0jy1xA8NplmcRzp2fsfIHNngU2NiRxsW5+yOQ=="],
-
- "@tauri-apps/cli-darwin-arm64": ["@tauri-apps/cli-darwin-arm64@2.4.1", "", { "os": "darwin", "cpu": "arm64" }, "sha512-QME7s8XQwy3LWClTVlIlwXVSLKkeJ/z88pr917Mtn9spYOjnBfsgHAgGdmpWD3NfJxjg7CtLbhH49DxoFL+hLg=="],
-
- "@tauri-apps/cli-darwin-x64": ["@tauri-apps/cli-darwin-x64@2.4.1", "", { "os": "darwin", "cpu": "x64" }, "sha512-/r89IcW6Ya1sEsFUEH7wLNruDTj7WmDWKGpPy7gATFtQr5JEY4heernqE82isjTUimnHZD8SCr0jA3NceI4ybw=="],
-
- "@tauri-apps/cli-linux-arm-gnueabihf": ["@tauri-apps/cli-linux-arm-gnueabihf@2.4.1", "", { "os": "linux", "cpu": "arm" }, "sha512-9tDijkRB+CchAGjXxYdY9l/XzFpLp1yihUtGXJz9eh+3qIoRI043n3e+6xmU8ZURr7XPnu+R4sCmXs6HD+NCEQ=="],
-
- "@tauri-apps/cli-linux-arm64-gnu": ["@tauri-apps/cli-linux-arm64-gnu@2.4.1", "", { "os": "linux", "cpu": "arm64" }, "sha512-pnFGDEXBAzS4iDYAVxTRhAzNu3K2XPGflYyBc0czfHDBXopqRgMyj5Q9Wj7HAwv6cM8BqzXINxnb2ZJFGmbSgA=="],
-
- "@tauri-apps/cli-linux-arm64-musl": ["@tauri-apps/cli-linux-arm64-musl@2.4.1", "", { "os": "linux", "cpu": "arm64" }, "sha512-Hp0zXgeZNKmT+eoJSCxSBUm2QndNuRxR55tmIeNm3vbyUMJN/49uW7nurZ5fBPsacN4Pzwlx1dIMK+Gnr9A69w=="],
-
- "@tauri-apps/cli-linux-riscv64-gnu": ["@tauri-apps/cli-linux-riscv64-gnu@2.4.1", "", { "os": "linux", "cpu": "none" }, "sha512-3T3bo2E4fdYRvzcXheWUeQOVB+LunEEi92iPRgOyuSVexVE4cmHYl+MPJF+EUV28Et0hIVTsHibmDO0/04lAFg=="],
-
- "@tauri-apps/cli-linux-x64-gnu": ["@tauri-apps/cli-linux-x64-gnu@2.4.1", "", { "os": "linux", "cpu": "x64" }, "sha512-kLN0FdNONO+2i+OpU9+mm6oTGufRC00e197TtwjpC0N6K2K8130w7Q3FeODIM2CMyg0ov3tH+QWqKW7GNhHFzg=="],
-
- "@tauri-apps/cli-linux-x64-musl": ["@tauri-apps/cli-linux-x64-musl@2.4.1", "", { "os": "linux", "cpu": "x64" }, "sha512-a8exvA5Ub9eg66a6hsMQKJIkf63QAf9OdiuFKOsEnKZkNN2x0NLgfvEcqdw88VY0UMs9dBoZ1AGbWMeYnLrLwQ=="],
-
- "@tauri-apps/cli-win32-arm64-msvc": ["@tauri-apps/cli-win32-arm64-msvc@2.4.1", "", { "os": "win32", "cpu": "arm64" }, "sha512-4JFrslsMCJQG1c573T9uqQSAbF3j/tMKkMWzsIssv8jvPiP++OG61A2/F+y9te9/Q/O95cKhDK63kaiO5xQaeg=="],
-
- "@tauri-apps/cli-win32-ia32-msvc": ["@tauri-apps/cli-win32-ia32-msvc@2.4.1", "", { "os": "win32", "cpu": "ia32" }, "sha512-9eXfFORehYSCRwxg2KodfmX/mhr50CI7wyBYGbPLePCjr5z0jK/9IyW6r0tC+ZVjwpX48dkk7hKiUgI25jHjzA=="],
-
- "@tauri-apps/cli-win32-x64-msvc": ["@tauri-apps/cli-win32-x64-msvc@2.4.1", "", { "os": "win32", "cpu": "x64" }, "sha512-60a4Ov7Jrwqz2hzDltlS7301dhSAmM9dxo+IRBD3xz7yobKrgaHXYpWvnRomYItHcDd51VaKc9292H8/eE/gsw=="],
-
- "@types/estree": ["@types/estree@1.0.7", "", {}, "sha512-w28IoSUCJpidD/TGviZwwMJckNESJZXFu7NBZ5YJ4mEUnNraUn9Pm8HSZm/jDF1pDWYKspWE7oVphigUPRakIQ=="],
-
- "@types/node": ["@types/node@20.17.30", "", { "dependencies": { "undici-types": "~6.19.2" } }, "sha512-7zf4YyHA+jvBNfVrk2Gtvs6x7E8V+YDW05bNfG2XkWDJfYRXrTiP/DsB2zSYTaHX0bGIujTBQdMVAhb+j7mwpg=="],
-
- "@types/web-animations-js": ["@types/web-animations-js@2.2.16", "", {}, "sha512-ATELeWMFwj8eQiH0KmvsCl1V2lu/qx/CjOBmv4ADSZS5u8r4reMyjCXtxG7khqyiwH3IOMNdrON/Ugn94OUcRA=="],
-
- "@types/web-bluetooth": ["@types/web-bluetooth@0.0.21", "", {}, "sha512-oIQLCGWtcFZy2JW77j9k8nHzAOpqMHLQejDA48XXMWH6tjCQHz5RCFz1bzsmROyL6PUm+LLnUiI4BCn221inxA=="],
-
- "@vant/popperjs": ["@vant/popperjs@1.3.0", "", {}, "sha512-hB+czUG+aHtjhaEmCJDuXOep0YTZjdlRR+4MSmIFnkCQIxJaXLQdSsR90XWvAI2yvKUI7TCGqR8pQg2RtvkMHw=="],
-
- "@vant/touch-emulator": ["@vant/touch-emulator@1.4.0", "", {}, "sha512-Zt+zISV0+wpOew2S1siOJ3G22y+hapHAKmXM+FhpvWzsRc4qahaYXatCAITuuXt0EcDp7WvEeTO4F7p9AtX/pw=="],
-
- "@vant/use": ["@vant/use@1.6.0", "", { "peerDependencies": { "vue": "^3.0.0" } }, "sha512-PHHxeAASgiOpSmMjceweIrv2AxDZIkWXyaczksMoWvKV2YAYEhoizRuk/xFnKF+emUIi46TsQ+rvlm/t2BBCfA=="],
-
- "@vitejs/plugin-vue": ["@vitejs/plugin-vue@5.2.3", "", { "peerDependencies": { "vite": "^5.0.0 || ^6.0.0", "vue": "^3.2.25" } }, "sha512-IYSLEQj4LgZZuoVpdSUCw3dIynTWQgPlaRP6iAvMle4My0HdYwr5g5wQAfwOeHQBmYwEkqF70nRpSilr6PoUDg=="],
-
- "@vue/babel-helper-vue-transform-on": ["@vue/babel-helper-vue-transform-on@1.4.0", "", {}, "sha512-mCokbouEQ/ocRce/FpKCRItGo+013tHg7tixg3DUNS+6bmIchPt66012kBMm476vyEIJPafrvOf4E5OYj3shSw=="],
-
- "@vue/babel-plugin-jsx": ["@vue/babel-plugin-jsx@1.4.0", "", { "dependencies": { "@babel/helper-module-imports": "^7.25.9", "@babel/helper-plugin-utils": "^7.26.5", "@babel/plugin-syntax-jsx": "^7.25.9", "@babel/template": "^7.26.9", "@babel/traverse": "^7.26.9", "@babel/types": "^7.26.9", "@vue/babel-helper-vue-transform-on": "1.4.0", "@vue/babel-plugin-resolve-type": "1.4.0", "@vue/shared": "^3.5.13" }, "peerDependencies": { "@babel/core": "^7.0.0-0" }, "optionalPeers": ["@babel/core"] }, "sha512-9zAHmwgMWlaN6qRKdrg1uKsBKHvnUU+Py+MOCTuYZBoZsopa90Di10QRjB+YPnVss0BZbG/H5XFwJY1fTxJWhA=="],
-
- "@vue/babel-plugin-resolve-type": ["@vue/babel-plugin-resolve-type@1.4.0", "", { "dependencies": { "@babel/code-frame": "^7.26.2", "@babel/helper-module-imports": "^7.25.9", "@babel/helper-plugin-utils": "^7.26.5", "@babel/parser": "^7.26.9", "@vue/compiler-sfc": "^3.5.13" }, "peerDependencies": { "@babel/core": "^7.0.0-0" } }, "sha512-4xqDRRbQQEWHQyjlYSgZsWj44KfiF6D+ktCuXyZ8EnVDYV3pztmXJDf1HveAjUAXxAnR8daCQT51RneWWxtTyQ=="],
-
- "@vue/compiler-core": ["@vue/compiler-core@3.5.13", "", { "dependencies": { "@babel/parser": "^7.25.3", "@vue/shared": "3.5.13", "entities": "^4.5.0", "estree-walker": "^2.0.2", "source-map-js": "^1.2.0" } }, "sha512-oOdAkwqUfW1WqpwSYJce06wvt6HljgY3fGeM9NcVA1HaYOij3mZG9Rkysn0OHuyUAGMbEbARIpsG+LPVlBJ5/Q=="],
-
- "@vue/compiler-dom": ["@vue/compiler-dom@3.5.13", "", { "dependencies": { "@vue/compiler-core": "3.5.13", "@vue/shared": "3.5.13" } }, "sha512-ZOJ46sMOKUjO3e94wPdCzQ6P1Lx/vhp2RSvfaab88Ajexs0AHeV0uasYhi99WPaogmBlRHNRuly8xV75cNTMDA=="],
-
- "@vue/compiler-sfc": ["@vue/compiler-sfc@3.5.13", "", { "dependencies": { "@babel/parser": "^7.25.3", "@vue/compiler-core": "3.5.13", "@vue/compiler-dom": "3.5.13", "@vue/compiler-ssr": "3.5.13", "@vue/shared": "3.5.13", "estree-walker": "^2.0.2", "magic-string": "^0.30.11", "postcss": "^8.4.48", "source-map-js": "^1.2.0" } }, "sha512-6VdaljMpD82w6c2749Zhf5T9u5uLBWKnVue6XWxprDobftnletJ8+oel7sexFfM3qIxNmVE7LSFGTpv6obNyaQ=="],
-
- "@vue/compiler-ssr": ["@vue/compiler-ssr@3.5.13", "", { "dependencies": { "@vue/compiler-dom": "3.5.13", "@vue/shared": "3.5.13" } }, "sha512-wMH6vrYHxQl/IybKJagqbquvxpWCuVYpoUJfCqFZwa/JY1GdATAQ+TgVtgrwwMZ0D07QhA99rs/EAAWfvG6KpA=="],
-
- "@vue/devtools-api": ["@vue/devtools-api@6.6.4", "", {}, "sha512-sGhTPMuXqZ1rVOk32RylztWkfXTRhuS7vgAKv0zjqk8gbsHkJ7xfFf+jbySxt7tWObEJwyKaHMikV/WGDiQm8g=="],
-
- "@vue/reactivity": ["@vue/reactivity@3.5.13", "", { "dependencies": { "@vue/shared": "3.5.13" } }, "sha512-NaCwtw8o48B9I6L1zl2p41OHo/2Z4wqYGGIK1Khu5T7yxrn+ATOixn/Udn2m+6kZKB/J7cuT9DbWWhRxqixACg=="],
-
- "@vue/runtime-core": ["@vue/runtime-core@3.5.13", "", { "dependencies": { "@vue/reactivity": "3.5.13", "@vue/shared": "3.5.13" } }, "sha512-Fj4YRQ3Az0WTZw1sFe+QDb0aXCerigEpw418pw1HBUKFtnQHWzwojaukAs2X/c9DQz4MQ4bsXTGlcpGxU/RCIw=="],
-
- "@vue/runtime-dom": ["@vue/runtime-dom@3.5.13", "", { "dependencies": { "@vue/reactivity": "3.5.13", "@vue/runtime-core": "3.5.13", "@vue/shared": "3.5.13", "csstype": "^3.1.3" } }, "sha512-dLaj94s93NYLqjLiyFzVs9X6dWhTdAlEAciC3Moq7gzAc13VJUdCnjjRurNM6uTLFATRHexHCTu/Xp3eW6yoog=="],
-
- "@vue/server-renderer": ["@vue/server-renderer@3.5.13", "", { "dependencies": { "@vue/compiler-ssr": "3.5.13", "@vue/shared": "3.5.13" }, "peerDependencies": { "vue": "3.5.13" } }, "sha512-wAi4IRJV/2SAW3htkTlB+dHeRmpTiVIK1OGLWV1yeStVSebSQQOwGwIq0D3ZIoBj2C2qpgz5+vX9iEBkTdk5YA=="],
-
- "@vue/shared": ["@vue/shared@3.5.13", "", {}, "sha512-/hnE/qP5ZoGpol0a5mDi45bOd7t3tjYJBjsgCsivow7D48cJeV5l05RD82lPqi7gRiphZM37rnhW1l6ZoCNNnQ=="],
-
- "@vueuse/components": ["@vueuse/components@12.8.2", "", { "dependencies": { "@vueuse/core": "12.8.2", "@vueuse/shared": "12.8.2", "vue": "^3.5.13" } }, "sha512-Nj27u1KsDWzoTthlChzVndJ9g0sW5APCXO3EJkSxlG11nN/ANTUlPPeoJOFvtbdDRnvsMJalboJyE0rRyg7yNg=="],
-
- "@vueuse/core": ["@vueuse/core@12.8.2", "", { "dependencies": { "@types/web-bluetooth": "^0.0.21", "@vueuse/metadata": "12.8.2", "@vueuse/shared": "12.8.2", "vue": "^3.5.13" } }, "sha512-HbvCmZdzAu3VGi/pWYm5Ut+Kd9mn1ZHnn4L5G8kOQTPs/IwIAmJoBrmYk2ckLArgMXZj0AW3n5CAejLUO+PhdQ=="],
-
- "@vueuse/metadata": ["@vueuse/metadata@12.8.2", "", {}, "sha512-rAyLGEuoBJ/Il5AmFHiziCPdQzRt88VxR+Y/A/QhJ1EWtWqPBBAxTAFaSkviwEuOEZNtW8pvkPgoCZQ+HxqW1A=="],
-
- "@vueuse/motion": ["@vueuse/motion@2.2.6", "", { "dependencies": { "@vueuse/core": "^10.10.0", "@vueuse/shared": "^10.10.0", "csstype": "^3.1.3", "framesync": "^6.1.2", "popmotion": "^11.0.5", "style-value-types": "^5.1.2" }, "optionalDependencies": { "@nuxt/kit": "^3.13.0" }, "peerDependencies": { "vue": ">=3.0.0" } }, "sha512-gKFktPtrdypSv44SaW1oBJKLBiP6kE5NcoQ6RsAU3InemESdiAutgQncfPe/rhLSLCtL4jTAhMmFfxoR6gm5LQ=="],
-
- "@vueuse/shared": ["@vueuse/shared@12.8.2", "", { "dependencies": { "vue": "^3.5.13" } }, "sha512-dznP38YzxZoNloI0qpEfpkms8knDtaoQ6Y/sfS0L7Yki4zh40LFHEhur0odJC6xTHG5dxWVPiUWBXn+wCG2s5w=="],
-
- "acorn": ["acorn@8.14.1", "", { "bin": { "acorn": "bin/acorn" } }, "sha512-OvQ/2pUDKmgfCg++xsTX1wGxfTaszcHVcTctW4UJB4hibJx2HXxxO5UmVgyjMa+ZDsiaf5wWLXYpRWMmBI0QHg=="],
-
- "animate.css": ["animate.css@4.1.1", "", {}, "sha512-+mRmCTv6SbCmtYJCN4faJMNFVNN5EuCTTprDTAo7YzIGji2KADmakjVA3+8mVDkZ2Bf09vayB35lSQIex2+QaQ=="],
-
- "ansi-regex": ["ansi-regex@6.1.0", "", {}, "sha512-7HSX4QQb4CspciLpVFwyRe79O3xsIZDDLER21kERQ71oaPodF8jL725AgJMFAYbooIqolJoRLuM81SpeUkpkvA=="],
-
- "ansi-styles": ["ansi-styles@6.2.1", "", {}, "sha512-bN798gFfQX+viw3R7yrGWRqnrN2oRkEkUjjl4JNn4E8GxxbjtG3FbrEIIY3l8/hrwUwIeCZvi4QuOTP4MErVug=="],
-
- "any-promise": ["any-promise@1.3.0", "", {}, "sha512-7UvmKalWRt1wgjL1RrGxoSJW/0QZFIegpeGvZG9kjp8vrRu55XTHbwnqq2GpXm9uLbcuhxm3IqX9OB4MZR1b2A=="],
-
- "anymatch": ["anymatch@3.1.3", "", { "dependencies": { "normalize-path": "^3.0.0", "picomatch": "^2.0.4" } }, "sha512-KMReFUr0B4t+D+OBkjR3KYqvocp2XaSzO55UcB6mgQMd3KbcE+mWTyvVV7D/zsdEbNnV6acZUutkiHQXvTr1Rw=="],
-
- "aos": ["aos@2.3.4", "", { "dependencies": { "classlist-polyfill": "^1.0.3", "lodash.debounce": "^4.0.6", "lodash.throttle": "^4.0.1" } }, "sha512-zh/ahtR2yME4I51z8IttIt4lC1Nw0ktsFtmeDzID1m9naJnWXhCoARaCgNOGXb5CLy3zm+wqmRAEgMYB5E2HUw=="],
-
- "arg": ["arg@5.0.2", "", {}, "sha512-PYjyFOLKQ9y57JvQ6QLo8dAgNqswh8M1RMJYdQduT6xbWSgK36P/Z/v+p888pM69jMMfS8Xd8F6I1kQ/I9HUGg=="],
-
- "artplayer": ["artplayer@5.2.2", "", { "dependencies": { "option-validator": "^2.0.6" } }, "sha512-JsPRA9e+7KyWTh5KBeKLTcCigzGhpZulRFXvOeiFMbxnpPz9kZ/1STp1LZONqQXHkxX9wHTO6JhGOvzrduH2Lw=="],
-
- "artplayer-plugin-danmuku": ["artplayer-plugin-danmuku@5.1.5", "", {}, "sha512-iFjdXVbkw5FbkB98SOwMPQEFJp7k6Io4nHfehpSdCc7Eo1gkmjNShOT6dAtAH1kLMHjh38vRnf/oYwCvTKkVOw=="],
-
- "asynckit": ["asynckit@0.4.0", "", {}, "sha512-Oei9OH4tRh0YqU3GxhX79dM/mwVgvbZJaSNaRk+bshkj0S5cfHcgYakreBjrHwatXKbz+IoIdYLxrKim2MjW0Q=="],
-
- "autoprefixer": ["autoprefixer@10.4.21", "", { "dependencies": { "browserslist": "^4.24.4", "caniuse-lite": "^1.0.30001702", "fraction.js": "^4.3.7", "normalize-range": "^0.1.2", "picocolors": "^1.1.1", "postcss-value-parser": "^4.2.0" }, "peerDependencies": { "postcss": "^8.1.0" }, "bin": { "autoprefixer": "bin/autoprefixer" } }, "sha512-O+A6LWV5LDHSJD3LjHYoNi4VLsj/Whi7k6zG12xTYaU4cQ8oxQGckXNX8cRHK5yOZ/ppVHe0ZBXGzSV9jXdVbQ=="],
-
- "axios": ["axios@1.8.4", "", { "dependencies": { "follow-redirects": "^1.15.6", "form-data": "^4.0.0", "proxy-from-env": "^1.1.0" } }, "sha512-eBSYY4Y68NNlHbHBMdeDmKNtDgXWhQsJcGqzO3iLUM0GraQFSS9cVgPX5I9b3lbdFKyYoAEGAZF1DwhTaljNAw=="],
-
- "balanced-match": ["balanced-match@1.0.2", "", {}, "sha512-3oSeUO0TMV67hN1AmbXsK4yaqU7tjiHlbxRDZOpH0KW9+CeX4bRAaX0Anxt0tx2MrpRpWwQaPwIlISEJhYU5Pw=="],
-
- "binary-extensions": ["binary-extensions@2.3.0", "", {}, "sha512-Ceh+7ox5qe7LJuLHoY0feh3pHuUDHAcRUeyL2VYghZwfpkNIy/+8Ocg0a3UuSoYzavmylwuLWQOf3hl0jjMMIw=="],
-
- "brace-expansion": ["brace-expansion@2.0.1", "", { "dependencies": { "balanced-match": "^1.0.0" } }, "sha512-XnAIvQ8eM+kC6aULx6wuQiwVsnzsi9d3WxzV3FpWTGA19F621kwdbsAcFKXgKUHZWsy+mY6iL1sHTxWEFCytDA=="],
-
- "braces": ["braces@3.0.3", "", { "dependencies": { "fill-range": "^7.1.1" } }, "sha512-yQbXgO/OSZVD2IsiLlro+7Hf6Q18EJrKSEsdoMzKePKXct3gvD8oLcOQdIzGupr5Fj+EDe8gO/lxc1BzfMpxvA=="],
-
- "browserslist": ["browserslist@4.24.4", "", { "dependencies": { "caniuse-lite": "^1.0.30001688", "electron-to-chromium": "^1.5.73", "node-releases": "^2.0.19", "update-browserslist-db": "^1.1.1" }, "bin": { "browserslist": "cli.js" } }, "sha512-KDi1Ny1gSePi1vm0q4oxSF8b4DR44GF4BbmS2YdhPLOEqd8pDviZOGH/GsmRwoWJ2+5Lr085X7naowMwKHDG1A=="],
-
- "c12": ["c12@3.0.3", "", { "dependencies": { "chokidar": "^4.0.3", "confbox": "^0.2.2", "defu": "^6.1.4", "dotenv": "^16.4.7", "exsolve": "^1.0.4", "giget": "^2.0.0", "jiti": "^2.4.2", "ohash": "^2.0.11", "pathe": "^2.0.3", "perfect-debounce": "^1.0.0", "pkg-types": "^2.1.0", "rc9": "^2.1.2" }, "peerDependencies": { "magicast": "^0.3.5" }, "optionalPeers": ["magicast"] }, "sha512-uC3MacKBb0Z15o5QWCHvHWj5Zv34pGQj9P+iXKSpTuSGFS0KKhUWf4t9AJ+gWjYOdmWCPEGpEzm8sS0iqbpo1w=="],
-
- "call-bind-apply-helpers": ["call-bind-apply-helpers@1.0.2", "", { "dependencies": { "es-errors": "^1.3.0", "function-bind": "^1.1.2" } }, "sha512-Sp1ablJ0ivDkSzjcaJdxEunN5/XvksFJ2sMBFfq6x0ryhQV/2b/KwFe21cMpmHtPOSij8K99/wSfoEuTObmuMQ=="],
-
- "camelcase-css": ["camelcase-css@2.0.1", "", {}, "sha512-QOSvevhslijgYwRx6Rv7zKdMF8lbRmx+uQGx2+vDc+KI/eBnsy9kit5aj23AgGu3pa4t9AgwbnXWqS+iOY+2aA=="],
-
- "caniuse-lite": ["caniuse-lite@1.0.30001712", "", {}, "sha512-MBqPpGYYdQ7/hfKiet9SCI+nmN5/hp4ZzveOJubl5DTAMa5oggjAuoi0Z4onBpKPFI2ePGnQuQIzF3VxDjDJig=="],
-
- "chokidar": ["chokidar@3.6.0", "", { "dependencies": { "anymatch": "~3.1.2", "braces": "~3.0.2", "glob-parent": "~5.1.2", "is-binary-path": "~2.1.0", "is-glob": "~4.0.1", "normalize-path": "~3.0.0", "readdirp": "~3.6.0" }, "optionalDependencies": { "fsevents": "~2.3.2" } }, "sha512-7VT13fmjotKpGipCW9JEQAusEPE+Ei8nl6/g4FBAmIm0GOOLMua9NDDo/DWp0ZAxCr3cPq5ZpBqmPAQgDda2Pw=="],
-
- "citty": ["citty@0.1.6", "", { "dependencies": { "consola": "^3.2.3" } }, "sha512-tskPPKEs8D2KPafUypv2gxwJP8h/OaJmC82QQGGDQcHvXX43xF2VDACcJVmZ0EuSxkpO9Kc4MlrA3q0+FG58AQ=="],
-
- "classlist-polyfill": ["classlist-polyfill@1.2.0", "", {}, "sha512-GzIjNdcEtH4ieA2S8NmrSxv7DfEV5fmixQeyTmqmRmRJPGpRBaSnA2a0VrCjyT8iW8JjEdMbKzDotAJf+ajgaQ=="],
-
- "color-convert": ["color-convert@2.0.1", "", { "dependencies": { "color-name": "~1.1.4" } }, "sha512-RRECPsj7iu/xb5oKYcsFHSppFNnsj/52OVTRKb4zP5onXwVF3zVmmToNcOfGC+CRDpfK/U584fMg38ZHCaElKQ=="],
-
- "color-name": ["color-name@1.1.4", "", {}, "sha512-dOy+3AuW3a2wNbZHIuMZpTcgjGuLU/uBL/ubcZF9OXbDo8ff4O8yVp5Bf0efS8uEoYo5q4Fx7dY9OgQGXgAsQA=="],
-
- "combined-stream": ["combined-stream@1.0.8", "", { "dependencies": { "delayed-stream": "~1.0.0" } }, "sha512-FQN4MRfuJeHf7cBbBMJFXhKSDq+2kAArBlmRBvcvFE5BB1HZKXtSFASDhdlz9zOYwxh8lDdnvmMOe/+5cdoEdg=="],
-
- "commander": ["commander@4.1.1", "", {}, "sha512-NOKm8xhkzAjzFx8B2v5OAHT+u5pRQc2UCa2Vq9jYL/31o2wi9mxBA7LIFs3sV5VSC49z6pEhfbMULvShKj26WA=="],
-
- "confbox": ["confbox@0.2.2", "", {}, "sha512-1NB+BKqhtNipMsov4xI/NnhCKp9XG9NamYp5PVm9klAT0fsrNPjaFICsCFhNhwZJKNh7zB/3q8qXz0E9oaMNtQ=="],
-
- "consola": ["consola@3.4.2", "", {}, "sha512-5IKcdX0nnYavi6G7TtOhwkYzyjfJlatbjMjuLSfE2kYT5pMDOilZ4OvMhi637CcDICTmz3wARPoyhqyX1Y+XvA=="],
-
- "convert-source-map": ["convert-source-map@2.0.0", "", {}, "sha512-Kvp459HrV2FEJ1CAsi1Ku+MY3kasH19TFykTz2xWmMeq6bk2NU3XXvfJ+Q61m0xktWwt+1HSYf3JZsTms3aRJg=="],
-
- "countup.js": ["countup.js@2.8.0", "", {}, "sha512-f7xEhX0awl4NOElHulrl4XRfKoNH3rB+qfNSZZyjSZhaAoUk6elvhH+MNxMmlmuUJ2/QNTWPSA7U4mNtIAKljQ=="],
-
- "cross-env": ["cross-env@7.0.3", "", { "dependencies": { "cross-spawn": "^7.0.1" }, "bin": { "cross-env": "src/bin/cross-env.js", "cross-env-shell": "src/bin/cross-env-shell.js" } }, "sha512-+/HKd6EgcQCJGh2PSjZuUitQBQynKor4wrFbRg4DtAgS1aWO+gU52xpH7M9ScGgXSYmAVS9bIJ8EzuaGw0oNAw=="],
-
- "cross-spawn": ["cross-spawn@7.0.6", "", { "dependencies": { "path-key": "^3.1.0", "shebang-command": "^2.0.0", "which": "^2.0.1" } }, "sha512-uV2QOWP2nWzsy2aMp8aRibhi9dlzF5Hgh5SHaB9OiTGEyDTiJJyx0uy51QXdyWbtAHNua4XJzUKca3OzKUd3vA=="],
-
- "crypto-js": ["crypto-js@4.2.0", "", {}, "sha512-KALDyEYgpY+Rlob/iriUtjV6d5Eq+Y191A5g4UqLAi8CyGP9N1+FdVbkc1SxKc2r4YAYqG8JzO2KGL+AizD70Q=="],
-
- "cssesc": ["cssesc@3.0.0", "", { "bin": { "cssesc": "bin/cssesc" } }, "sha512-/Tb/JcjK111nNScGob5MNtsntNM1aCNUDipB/TkwZFhyDrrE47SOx/18wF2bbjgc3ZzCSKW1T5nt5EbFoAz/Vg=="],
-
- "csstype": ["csstype@3.1.3", "", {}, "sha512-M1uQkMl8rQK/szD0LNhtqxIPLpimGm8sOBwU7lLnCpSbTyY3yeU1Vc7l4KT5zT4s/yOxHH5O7tIuuLOCnLADRw=="],
-
- "debug": ["debug@4.4.0", "", { "dependencies": { "ms": "^2.1.3" } }, "sha512-6WTZ/IxCY/T6BALoZHaE4ctp9xm+Z5kY/pzYaCHRFeyVhojxlrm+46y68HA6hr0TcwEssoxNiDEUJQjfPZ/RYA=="],
-
- "defu": ["defu@6.1.4", "", {}, "sha512-mEQCMmwJu317oSz8CwdIOdwf3xMif1ttiM8LTufzc3g6kR+9Pe236twL8j3IYT1F7GfRgGcW6MWxzZjLIkuHIg=="],
-
- "delayed-stream": ["delayed-stream@1.0.0", "", {}, "sha512-ZySD7Nf91aLB0RxL4KGrKHBXl7Eds1DAmEdcoVawXnLD7SDhpNgtuII2aAkg7a7QS41jxPSZ17p4VdGnMHk3MQ=="],
-
- "destr": ["destr@2.0.5", "", {}, "sha512-ugFTXCtDZunbzasqBxrK93Ik/DRYsO6S/fedkWEMKqt04xZ4csmnmwGDBAb07QWNaGMAmnTIemsYZCksjATwsA=="],
-
- "didyoumean": ["didyoumean@1.2.2", "", {}, "sha512-gxtyfqMg7GKyhQmb056K7M3xszy/myH8w+B4RT+QXBQsvAOdc3XymqDDPHx1BgPgsdAA5SIifona89YtRATDzw=="],
-
- "dlv": ["dlv@1.1.3", "", {}, "sha512-+HlytyjlPKnIG8XuRG8WvmBP8xs8P71y+SKKS6ZXWoEgLuePxtDoUEiH7WkdePWrQ5JBpE6aoVqfZfJUQkjXwA=="],
-
- "dotenv": ["dotenv@16.4.7", "", {}, "sha512-47qPchRCykZC03FhkYAhrvwU4xDBFIj1QPqaarj6mdM/hgUzfPHcpkHJOn3mJAufFeeAxAzeGsr5X0M4k6fLZQ=="],
-
- "dunder-proto": ["dunder-proto@1.0.1", "", { "dependencies": { "call-bind-apply-helpers": "^1.0.1", "es-errors": "^1.3.0", "gopd": "^1.2.0" } }, "sha512-KIN/nDJBQRcXw0MLVhZE9iQHmG68qAVIBg9CqmUYjmQIhgij9U5MFvrqkUL5FbtyyzZuOeOt0zdeRe4UY7ct+A=="],
-
- "eastasianwidth": ["eastasianwidth@0.2.0", "", {}, "sha512-I88TYZWc9XiYHRQ4/3c5rjjfgkjhLyW2luGIheGERbNQ6OY7yTybanSpDXZa8y7VUP9YmDcYa+eyq4ca7iLqWA=="],
-
- "echarts": ["echarts@5.6.0", "", { "dependencies": { "tslib": "2.3.0", "zrender": "5.6.1" } }, "sha512-oTbVTsXfKuEhxftHqL5xprgLoc0k7uScAwtryCgWF6hPYFLRwOUHiFmHGCBKP5NPFNkDVopOieyUqYGH8Fa3kA=="],
-
- "echarts-wordcloud": ["echarts-wordcloud@2.1.0", "", { "peerDependencies": { "echarts": "^5.0.1" } }, "sha512-Kt1JmbcROgb+3IMI48KZECK2AP5lG6bSsOEs+AsuwaWJxQom31RTNd6NFYI01E/YaI1PFZeueaupjlmzSQasjQ=="],
-
- "electron-to-chromium": ["electron-to-chromium@1.5.132", "", {}, "sha512-QgX9EBvWGmvSRa74zqfnG7+Eno0Ak0vftBll0Pt2/z5b3bEGYL6OUXLgKPtvx73dn3dvwrlyVkjPKRRlhLYTEg=="],
-
- "emoji-regex": ["emoji-regex@9.2.2", "", {}, "sha512-L18DaJsXSUk2+42pv8mLs5jJT2hqFkFE4j21wOmgbUqsZ2hL72NsUU785g9RXgo3s0ZNgVl42TiHp3ZtOv/Vyg=="],
-
- "entities": ["entities@4.5.0", "", {}, "sha512-V0hjH4dGPh9Ao5p0MoRY6BVqtwCjhz6vI5LT8AJ55H+4g9/4vbHx1I54fS0XuclLhDHArPQCiMjDxjaL8fPxhw=="],
-
- "errx": ["errx@0.1.0", "", {}, "sha512-fZmsRiDNv07K6s2KkKFTiD2aIvECa7++PKyD5NC32tpRw46qZA3sOz+aM+/V9V0GDHxVTKLziveV4JhzBHDp9Q=="],
-
- "es-define-property": ["es-define-property@1.0.1", "", {}, "sha512-e3nRfgfUZ4rNGL232gUgX06QNyyez04KdjFrF+LTRoOXmrOgFKDg4BCdsjW8EnT69eqdYGmRpJwiPVYNrCaW3g=="],
-
- "es-errors": ["es-errors@1.3.0", "", {}, "sha512-Zf5H2Kxt2xjTvbJvP2ZWLEICxA6j+hAmMzIlypy4xcBg1vKVnx89Wy0GbS+kf5cwCVFFzdCFh2XSCFNULS6csw=="],
-
- "es-object-atoms": ["es-object-atoms@1.1.1", "", { "dependencies": { "es-errors": "^1.3.0" } }, "sha512-FGgH2h8zKNim9ljj7dankFPcICIK9Cp5bm+c2gQSYePhpaG5+esrLODihIorn+Pe6FGJzWhXQotPv73jTaldXA=="],
-
- "es-set-tostringtag": ["es-set-tostringtag@2.1.0", "", { "dependencies": { "es-errors": "^1.3.0", "get-intrinsic": "^1.2.6", "has-tostringtag": "^1.0.2", "hasown": "^2.0.2" } }, "sha512-j6vWzfrGVfyXxge+O0x5sh6cvxAog0a/4Rdd2K36zCMV5eJ+/+tOAngRO8cODMNWbVRdVlmGZQL2YS3yR8bIUA=="],
-
- "esbuild": ["esbuild@0.21.5", "", { "optionalDependencies": { "@esbuild/aix-ppc64": "0.21.5", "@esbuild/android-arm": "0.21.5", "@esbuild/android-arm64": "0.21.5", "@esbuild/android-x64": "0.21.5", "@esbuild/darwin-arm64": "0.21.5", "@esbuild/darwin-x64": "0.21.5", "@esbuild/freebsd-arm64": "0.21.5", "@esbuild/freebsd-x64": "0.21.5", "@esbuild/linux-arm": "0.21.5", "@esbuild/linux-arm64": "0.21.5", "@esbuild/linux-ia32": "0.21.5", "@esbuild/linux-loong64": "0.21.5", "@esbuild/linux-mips64el": "0.21.5", "@esbuild/linux-ppc64": "0.21.5", "@esbuild/linux-riscv64": "0.21.5", "@esbuild/linux-s390x": "0.21.5", "@esbuild/linux-x64": "0.21.5", "@esbuild/netbsd-x64": "0.21.5", "@esbuild/openbsd-x64": "0.21.5", "@esbuild/sunos-x64": "0.21.5", "@esbuild/win32-arm64": "0.21.5", "@esbuild/win32-ia32": "0.21.5", "@esbuild/win32-x64": "0.21.5" }, "bin": { "esbuild": "bin/esbuild" } }, "sha512-mg3OPMV4hXywwpoDxu3Qda5xCKQi+vCTZq8S9J/EpkhB2HzKXq4SNFZE3+NK93JYxc8VMSep+lOUSC/RVKaBqw=="],
-
- "escalade": ["escalade@3.2.0", "", {}, "sha512-WUj2qlxaQtO4g6Pq5c29GTcWGDyd8itL8zTlipgECz3JesAiiOKotd8JU6otB3PACgG6xkJUyVhboMS+bje/jA=="],
-
- "escape-string-regexp": ["escape-string-regexp@5.0.0", "", {}, "sha512-/veY75JbMK4j1yjvuUxuVsiS/hr/4iHs9FTT6cgTexxdE0Ly/glccBAkloH/DofkjRbZU3bnoj38mOmhkZ0lHw=="],
-
- "estree-walker": ["estree-walker@2.0.2", "", {}, "sha512-Rfkk/Mp/DL7JVje3u18FxFujQlTNR2q6QfMSMB7AvCBx91NGj/ba3kCfza0f6dVDbw7YlRf/nDrn7pQrCCyQ/w=="],
-
- "exsolve": ["exsolve@1.0.4", "", {}, "sha512-xsZH6PXaER4XoV+NiT7JHp1bJodJVT+cxeSH1G0f0tlT0lJqYuHUP3bUx2HtfTDvOagMINYp8rsqusxud3RXhw=="],
-
- "fast-deep-equal": ["fast-deep-equal@3.1.3", "", {}, "sha512-f3qQ9oQy9j2AhBe/H9VC91wLmKBCCU/gDOnKNAYG5hswO7BLKj09Hc5HYNz9cGI++xlpDCIgDaitVs03ATR84Q=="],
-
- "fast-glob": ["fast-glob@3.3.3", "", { "dependencies": { "@nodelib/fs.stat": "^2.0.2", "@nodelib/fs.walk": "^1.2.3", "glob-parent": "^5.1.2", "merge2": "^1.3.0", "micromatch": "^4.0.8" } }, "sha512-7MptL8U0cqcFdzIzwOTHoilX9x5BrNqye7Z/LuC7kCMRio1EMSyqRK3BEAUD7sXRq4iT4AzTVuZdhgQ2TCvYLg=="],
-
- "fastq": ["fastq@1.19.1", "", { "dependencies": { "reusify": "^1.0.4" } }, "sha512-GwLTyxkCXjXbxqIhTsMI2Nui8huMPtnxg7krajPJAjnEG/iiOS7i+zCtWGZR9G0NBKbXKh6X9m9UIsYX/N6vvQ=="],
-
- "fdir": ["fdir@6.4.3", "", { "peerDependencies": { "picomatch": "^3 || ^4" }, "optionalPeers": ["picomatch"] }, "sha512-PMXmW2y1hDDfTSRc9gaXIuCCRpuoz3Kaz8cUelp3smouvfT632ozg2vrT6lJsHKKOF59YLbOGfAWGUcKEfRMQw=="],
-
- "fill-range": ["fill-range@7.1.1", "", { "dependencies": { "to-regex-range": "^5.0.1" } }, "sha512-YsGpe3WHLK8ZYi4tWDg2Jy3ebRz2rXowDxnld4bkQB00cc/1Zw9AWnC0i9ztDJitivtQvaI9KaLyKrc+hBW0yg=="],
-
- "follow-redirects": ["follow-redirects@1.15.9", "", {}, "sha512-gew4GsXizNgdoRyqmyfMHyAmXsZDk6mHkSxZFCzW9gwlbtOW44CDtYavM+y+72qD/Vq2l550kMF52DT8fOLJqQ=="],
-
- "foreground-child": ["foreground-child@3.3.1", "", { "dependencies": { "cross-spawn": "^7.0.6", "signal-exit": "^4.0.1" } }, "sha512-gIXjKqtFuWEgzFRJA9WCQeSJLZDjgJUOMCMzxtvFq/37KojM1BFGufqsCy0r4qSQmYLsZYMeyRqzIWOMup03sw=="],
-
- "form-data": ["form-data@4.0.2", "", { "dependencies": { "asynckit": "^0.4.0", "combined-stream": "^1.0.8", "es-set-tostringtag": "^2.1.0", "mime-types": "^2.1.12" } }, "sha512-hGfm/slu0ZabnNt4oaRZ6uREyfCj6P4fT/n6A1rGV+Z0VdGXjfOhVUpkn6qVQONHGIFwmveGXyDs75+nr6FM8w=="],
-
- "fraction.js": ["fraction.js@4.3.7", "", {}, "sha512-ZsDfxO51wGAXREY55a7la9LScWpwv9RxIrYABrlvOFBlH/ShPnrtsXeuUIfXKKOVicNxQ+o8JTbJvjS4M89yew=="],
-
- "framesync": ["framesync@6.1.2", "", { "dependencies": { "tslib": "2.4.0" } }, "sha512-jBTqhX6KaQVDyus8muwZbBeGGP0XgujBRbQ7gM7BRdS3CadCZIHiawyzYLnafYcvZIh5j8WE7cxZKFn7dXhu9g=="],
-
- "fsevents": ["fsevents@2.3.3", "", { "os": "darwin" }, "sha512-5xoDfX+fL7faATnagmWPpbFtwh/R77WmMMqqHGS65C3vvB0YHrgF+B1YmZ3441tMj5n63k0212XNoJwzlhffQw=="],
-
- "function-bind": ["function-bind@1.1.2", "", {}, "sha512-7XHNxH7qX9xG5mIwxkhumTox/MIRNcOgDrxWsMt2pAr23WHp6MrRlN7FBSFpCpr+oVO0F744iUgR82nJMfG2SA=="],
-
- "gensync": ["gensync@1.0.0-beta.2", "", {}, "sha512-3hN7NaskYvMDLQY55gnW3NQ+mesEAepTqlg+VEbj7zzqEMBVNhzcGYYeqFo/TlYz6eQiFcp1HcsCZO+nGgS8zg=="],
-
- "get-intrinsic": ["get-intrinsic@1.3.0", "", { "dependencies": { "call-bind-apply-helpers": "^1.0.2", "es-define-property": "^1.0.1", "es-errors": "^1.3.0", "es-object-atoms": "^1.1.1", "function-bind": "^1.1.2", "get-proto": "^1.0.1", "gopd": "^1.2.0", "has-symbols": "^1.1.0", "hasown": "^2.0.2", "math-intrinsics": "^1.1.0" } }, "sha512-9fSjSaos/fRIVIp+xSJlE6lfwhES7LNtKaCBIamHsjr2na1BiABJPo0mOjjz8GJDURarmCPGqaiVg5mfjb98CQ=="],
-
- "get-proto": ["get-proto@1.0.1", "", { "dependencies": { "dunder-proto": "^1.0.1", "es-object-atoms": "^1.0.0" } }, "sha512-sTSfBjoXBp89JvIKIefqw7U2CCebsc74kiY6awiGogKtoSGbgjYE/G/+l9sF3MWFPNc9IcoOC4ODfKHfxFmp0g=="],
-
- "giget": ["giget@2.0.0", "", { "dependencies": { "citty": "^0.1.6", "consola": "^3.4.0", "defu": "^6.1.4", "node-fetch-native": "^1.6.6", "nypm": "^0.6.0", "pathe": "^2.0.3" }, "bin": { "giget": "dist/cli.mjs" } }, "sha512-L5bGsVkxJbJgdnwyuheIunkGatUF/zssUoxxjACCseZYAVbaqdh9Tsmmlkl8vYan09H7sbvKt4pS8GqKLBrEzA=="],
-
- "glob": ["glob@10.4.5", "", { "dependencies": { "foreground-child": "^3.1.0", "jackspeak": "^3.1.2", "minimatch": "^9.0.4", "minipass": "^7.1.2", "package-json-from-dist": "^1.0.0", "path-scurry": "^1.11.1" }, "bin": { "glob": "dist/esm/bin.mjs" } }, "sha512-7Bv8RF0k6xjo7d4A/PxYLbUCfb6c+Vpd2/mB2yRDlew7Jb5hEXiCD9ibfO7wpk8i4sevK6DFny9h7EYbM3/sHg=="],
-
- "glob-parent": ["glob-parent@6.0.2", "", { "dependencies": { "is-glob": "^4.0.3" } }, "sha512-XxwI8EOhVQgWp6iDL+3b0r86f4d6AX6zSU55HfB4ydCEuXLXc5FcYeOu+nnGftS4TEju/11rt4KJPTMgbfmv4A=="],
-
- "globals": ["globals@11.12.0", "", {}, "sha512-WOBp/EEGUiIsJSp7wcv/y6MO+lV9UoncWqxuFfm8eBwzWNgyfBd6Gz+IeKQ9jCmyhoH99g15M3T+QaVHFjizVA=="],
-
- "globby": ["globby@14.1.0", "", { "dependencies": { "@sindresorhus/merge-streams": "^2.1.0", "fast-glob": "^3.3.3", "ignore": "^7.0.3", "path-type": "^6.0.0", "slash": "^5.1.0", "unicorn-magic": "^0.3.0" } }, "sha512-0Ia46fDOaT7k4og1PDW4YbodWWr3scS2vAr2lTbsplOt2WkKp0vQbkI9wKis/T5LV/dqPjO3bpS/z6GTJB82LA=="],
-
- "gopd": ["gopd@1.2.0", "", {}, "sha512-ZUKRh6/kUFoAiTAtTYPZJ3hw9wNxx+BIBOijnlG9PnrJsCcSjs1wyyD6vJpaYtgnzDrKYRSqf3OO6Rfa93xsRg=="],
-
- "gsap": ["gsap@3.12.7", "", {}, "sha512-V4GsyVamhmKefvcAKaoy0h6si0xX7ogwBoBSs2CTJwt7luW0oZzC0LhdkyuKV8PJAXr7Yaj8pMjCKD4GJ+eEMg=="],
-
- "has-symbols": ["has-symbols@1.1.0", "", {}, "sha512-1cDNdwJ2Jaohmb3sg4OmKaMBwuC48sYni5HUw2DvsC8LjGTLK9h+eb1X6RyuOHe4hT0ULCW68iomhjUoKUqlPQ=="],
-
- "has-tostringtag": ["has-tostringtag@1.0.2", "", { "dependencies": { "has-symbols": "^1.0.3" } }, "sha512-NqADB8VjPFLM2V0VvHUewwwsw0ZWBaIdgo+ieHtK3hasLz4qeCRjYcqfB6AQrBggRKppKF8L52/VqdVsO47Dlw=="],
-
- "hasown": ["hasown@2.0.2", "", { "dependencies": { "function-bind": "^1.1.2" } }, "sha512-0hJU9SCPvmMzIBdZFqNPXWa6dqh7WdH0cII9y+CyS8rG3nL48Bclra9HmKhVVUHyPWNH5Y7xDwAB7bfgSjkUMQ=="],
-
- "hey-listen": ["hey-listen@1.0.8", "", {}, "sha512-COpmrF2NOg4TBWUJ5UVyaCU2A88wEMkUPK4hNqyCkqHbxT92BbvfjoSozkAIIm6XhicGlJHhFdullInrdhwU8Q=="],
-
- "ignore": ["ignore@7.0.3", "", {}, "sha512-bAH5jbK/F3T3Jls4I0SO1hmPR0dKU0a7+SY6n1yzRtG54FLO8d6w/nxLFX2Nb7dBu6cCWXPaAME6cYqFUMmuCA=="],
-
- "is-binary-path": ["is-binary-path@2.1.0", "", { "dependencies": { "binary-extensions": "^2.0.0" } }, "sha512-ZMERYes6pDydyuGidse7OsHxtbI7WVeUEozgR/g7rd0xUimYNlvZRE/K2MgZTjWy725IfelLeVcEM97mmtRGXw=="],
-
- "is-core-module": ["is-core-module@2.16.1", "", { "dependencies": { "hasown": "^2.0.2" } }, "sha512-UfoeMA6fIJ8wTYFEUjelnaGI67v6+N7qXJEvQuIGa99l4xsCruSYOVSQ0uPANn4dAzm8lkYPaKLrrijLq7x23w=="],
-
- "is-extglob": ["is-extglob@2.1.1", "", {}, "sha512-SbKbANkN603Vi4jEZv49LeVJMn4yGwsbzZworEoyEiutsN3nJYdbO36zfhGJ6QEDpOZIFkDtnq5JRxmvl3jsoQ=="],
-
- "is-fullwidth-code-point": ["is-fullwidth-code-point@3.0.0", "", {}, "sha512-zymm5+u+sCsSWyD9qNaejV3DFvhCKclKdizYaJUuHA83RLjb7nSuGnddCHGv0hk+KY7BMAlsWeK4Ueg6EV6XQg=="],
-
- "is-glob": ["is-glob@4.0.3", "", { "dependencies": { "is-extglob": "^2.1.1" } }, "sha512-xelSayHH36ZgE7ZWhli7pW34hNbNl8Ojv5KVmkJD4hBdD3th8Tfk9vYasLM+mXWOZhFkgZfxhLSnrwRr4elSSg=="],
-
- "is-number": ["is-number@7.0.0", "", {}, "sha512-41Cifkg6e8TylSpdtTpeLVMqvSBEVzTttHvERD741+pnZ8ANv0004MRL43QKPDlK9cGvNp6NZWZUBlbGXYxxng=="],
-
- "isexe": ["isexe@2.0.0", "", {}, "sha512-RHxMLp9lnKHGHRng9QFhRCMbYAcVpn69smSGcq3f36xjgVVWThj4qqLbTLlq7Ssj8B+fIQ1EuCEGI2lKsyQeIw=="],
-
- "jackspeak": ["jackspeak@3.4.3", "", { "dependencies": { "@isaacs/cliui": "^8.0.2" }, "optionalDependencies": { "@pkgjs/parseargs": "^0.11.0" } }, "sha512-OGlZQpz2yfahA/Rd1Y8Cd9SIEsqvXkLVoSw/cgwhnhFMDbsQFeZYoJJ7bIZBS9BcamUW96asq/npPWugM+RQBw=="],
-
- "jiti": ["jiti@1.21.7", "", { "bin": { "jiti": "bin/jiti.js" } }, "sha512-/imKNG4EbWNrVjoNC/1H5/9GFy+tqjGBHCaSsN+P2RnPqjsLmv6UD3Ej+Kj8nBWaRAwyk7kK5ZUc+OEatnTR3A=="],
-
- "js-tokens": ["js-tokens@4.0.0", "", {}, "sha512-RdJUflcE3cUzKiMqQgsCu06FPu9UdIJO0beYbPhHN4k6apgJtifcoCtT9bcxOpYBtpD2kCM6Sbzg4CausW/PKQ=="],
-
- "jsencrypt": ["jsencrypt@3.3.2", "", {}, "sha512-arQR1R1ESGdAxY7ZheWr12wCaF2yF47v5qpB76TtV64H1pyGudk9Hvw8Y9tb/FiTIaaTRUyaSnm5T/Y53Ghm/A=="],
-
- "jsesc": ["jsesc@3.1.0", "", { "bin": { "jsesc": "bin/jsesc" } }, "sha512-/sM3dO2FOzXjKQhJuo0Q173wf2KOo8t4I8vHy6lF9poUp7bKT0/NHE8fPX23PwfhnykfqnC2xRxOnVw5XuGIaA=="],
-
- "json5": ["json5@2.2.3", "", { "bin": { "json5": "lib/cli.js" } }, "sha512-XmOWe7eyHYH14cLdVPoyg+GOH3rYX++KpzrylJwSW98t3Nk+U8XOl8FWKOgwtzdb8lXGf6zYwDUzeHMWfxasyg=="],
-
- "kind-of": ["kind-of@6.0.3", "", {}, "sha512-dcS1ul+9tmeD95T+x28/ehLgd9mENa3LsvDTtzm3vyBEO7RPptvAD+t44WVXaUjTBRcrpFeFlC8WCruUR456hw=="],
-
- "klona": ["klona@2.0.6", "", {}, "sha512-dhG34DXATL5hSxJbIexCft8FChFXtmskoZYnoPWjXQuebWYCNkVeV3KkGegCK9CP1oswI/vQibS2GY7Em/sJJA=="],
-
- "knitwork": ["knitwork@1.2.0", "", {}, "sha512-xYSH7AvuQ6nXkq42x0v5S8/Iry+cfulBz/DJQzhIyESdLD7425jXsPy4vn5cCXU+HhRN2kVw51Vd1K6/By4BQg=="],
-
- "kolorist": ["kolorist@1.8.0", "", {}, "sha512-Y+60/zizpJ3HRH8DCss+q95yr6145JXZo46OTpFvDZWLfRCE4qChOyk1b26nMaNpfHHgxagk9dXT5OP0Tfe+dQ=="],
-
- "lilconfig": ["lilconfig@3.1.3", "", {}, "sha512-/vlFKAoH5Cgt3Ie+JLhRbwOsCQePABiU3tJ1egGvyQ+33R/vcwM2Zl2QR/LzjsBeItPt3oSVXapn+m4nQDvpzw=="],
-
- "lines-and-columns": ["lines-and-columns@1.2.4", "", {}, "sha512-7ylylesZQ/PV29jhEDl3Ufjo6ZX7gCqJr5F7PKrqc93v7fzSymt1BpwEU8nAUXs8qzzvqhbjhK5QZg6Mt/HkBg=="],
-
- "local-pkg": ["local-pkg@1.1.1", "", { "dependencies": { "mlly": "^1.7.4", "pkg-types": "^2.0.1", "quansync": "^0.2.8" } }, "sha512-WunYko2W1NcdfAFpuLUoucsgULmgDBRkdxHxWQ7mK0cQqwPiy8E1enjuRBrhLtZkB5iScJ1XIPdhVEFK8aOLSg=="],
-
- "lodash.debounce": ["lodash.debounce@4.0.8", "", {}, "sha512-FT1yDzDYEoYWhnSGnpE/4Kj1fLZkDFyqRb7fNt6FdYOSxlUWAtp42Eh6Wb0rGIv/m9Bgo7x4GhQbm5Ys4SG5ow=="],
-
- "lodash.throttle": ["lodash.throttle@4.1.1", "", {}, "sha512-wIkUCfVKpVsWo3JSZlc+8MB5it+2AN5W8J7YVMST30UrvcQNZ1Okbj+rbVniijTWE6FGYy4XJq/rHkas8qJMLQ=="],
-
- "lottie-web": ["lottie-web@5.12.2", "", {}, "sha512-uvhvYPC8kGPjXT3MyKMrL3JitEAmDMp30lVkuq/590Mw9ok6pWcFCwXJveo0t5uqYw1UREQHofD+jVpdjBv8wg=="],
-
- "lru-cache": ["lru-cache@5.1.1", "", { "dependencies": { "yallist": "^3.0.2" } }, "sha512-KpNARQA3Iwv+jTA0utUVVbrh+Jlrr1Fv0e56GGzAFOXN7dk/FviaDW8LHmK52DlcH4WP2n6gI8vN1aesBFgo9w=="],
-
- "magic-string": ["magic-string@0.30.17", "", { "dependencies": { "@jridgewell/sourcemap-codec": "^1.5.0" } }, "sha512-sNPKHvyjVf7gyjwS4xGTaW/mCnF8wnjtifKBEhxfZ7E/S8tQ0rssrwGNn6q8JH/ohItJfSQp9mBtQYuTlH5QnA=="],
-
- "math-intrinsics": ["math-intrinsics@1.1.0", "", {}, "sha512-/IXtbwEk5HTPyEwyKX6hGkYXxM9nbj64B+ilVJnC/R6B0pH5G4V3b0pVbL7DBj4tkhBAppbQUlf6F6Xl9LHu1g=="],
-
- "merge2": ["merge2@1.4.1", "", {}, "sha512-8q7VEgMJW4J8tcfVPy8g09NcQwZdbwFEqhe/WZkoIzjn/3TGDwtOCYtXGxA3O8tPzpczCCDgv+P2P5y00ZJOOg=="],
-
- "micromatch": ["micromatch@4.0.8", "", { "dependencies": { "braces": "^3.0.3", "picomatch": "^2.3.1" } }, "sha512-PXwfBhYu0hBCPw8Dn0E+WDYb7af3dSLVWKi3HGv84IdF4TyFoC0ysxFd0Goxw7nSv4T/PzEJQxsYsEiFCKo2BA=="],
-
- "mime-db": ["mime-db@1.52.0", "", {}, "sha512-sPU4uV7dYlvtWJxwwxHD0PuihVNiE7TyAbQ5SWxDCB9mUYvOgroQOwYQQOKPJ8CIbE+1ETVlOoK1UC2nU3gYvg=="],
-
- "mime-types": ["mime-types@2.1.35", "", { "dependencies": { "mime-db": "1.52.0" } }, "sha512-ZDY+bPm5zTTF+YpCrAU9nK0UgICYPT0QtT1NZWFv4s++TNkcgVaT0g6+4R2uI4MjQjzysHB1zxuWL50hzaeXiw=="],
-
- "mini-svg-data-uri": ["mini-svg-data-uri@1.4.4", "", { "bin": { "mini-svg-data-uri": "cli.js" } }, "sha512-r9deDe9p5FJUPZAk3A59wGH7Ii9YrjjWw0jmw/liSbHl2CHiyXj6FcDXDu2K3TjVAXqiJdaw3xxwlZZr9E6nHg=="],
-
- "minimatch": ["minimatch@9.0.5", "", { "dependencies": { "brace-expansion": "^2.0.1" } }, "sha512-G6T0ZX48xgozx7587koeX9Ys2NYy6Gmv//P89sEte9V9whIapMNF4idKxnW2QtCcLiTWlb/wfCabAtAFWhhBow=="],
-
- "minipass": ["minipass@7.1.2", "", {}, "sha512-qOOzS1cBTWYF4BH8fVePDBOO9iptMnGUEZwNc/cMWnTV2nVLZ7VoNWEPHkYczZA0pdoA7dl6e7FL659nX9S2aw=="],
-
- "mlly": ["mlly@1.7.4", "", { "dependencies": { "acorn": "^8.14.0", "pathe": "^2.0.1", "pkg-types": "^1.3.0", "ufo": "^1.5.4" } }, "sha512-qmdSIPC4bDJXgZTCR7XosJiNKySV7O215tsPtDN9iEO/7q/76b/ijtgRu/+epFXSJhijtTCCGp3DWS549P3xKw=="],
-
- "ms": ["ms@2.1.3", "", {}, "sha512-6FlzubTLZG3J2a/NVCAleEhjzq5oxgHyaCU9yYXvcLsvoVaHJq/s5xXI6/XXP6tz7R9xAOtHnSO/tXtF3WRTlA=="],
-
- "mz": ["mz@2.7.0", "", { "dependencies": { "any-promise": "^1.0.0", "object-assign": "^4.0.1", "thenify-all": "^1.0.0" } }, "sha512-z81GNO7nnYMEhrGh9LeymoE4+Yr0Wn5McHIZMK5cfQCl+NDX08sCZgUc9/6MHni9IWuFLm1Z3HTCXu2z9fN62Q=="],
-
- "nanoid": ["nanoid@3.3.11", "", { "bin": { "nanoid": "bin/nanoid.cjs" } }, "sha512-N8SpfPUnUp1bK+PMYW8qSWdl9U+wwNWI4QKxOYDy9JAro3WMX7p2OeVRF9v+347pnakNevPmiHhNmZ2HbFA76w=="],
-
- "node-fetch-native": ["node-fetch-native@1.6.6", "", {}, "sha512-8Mc2HhqPdlIfedsuZoc3yioPuzp6b+L5jRCRY1QzuWZh2EGJVQrGppC6V6cF0bLdbW0+O2YpqCA25aF/1lvipQ=="],
-
- "node-releases": ["node-releases@2.0.19", "", {}, "sha512-xxOWJsBKtzAq7DY0J+DTzuz58K8e7sJbdgwkbMWQe8UYB6ekmsQ45q0M/tJDsGaZmbC+l7n57UV8Hl5tHxO9uw=="],
-
- "normalize-path": ["normalize-path@3.0.0", "", {}, "sha512-6eZs5Ls3WtCisHWp9S2GUy8dqkpGi4BVSz3GaqiE6ezub0512ESztXUwUB6C6IKbQkY2Pnb/mD4WYojCRwcwLA=="],
-
- "normalize-range": ["normalize-range@0.1.2", "", {}, "sha512-bdok/XvKII3nUpklnV6P2hxtMNrCboOjAcyBuQnWEhO665FwrSNRxU+AqpsyvO6LgGYPspN+lu5CLtw4jPRKNA=="],
-
- "nypm": ["nypm@0.6.0", "", { "dependencies": { "citty": "^0.1.6", "consola": "^3.4.0", "pathe": "^2.0.3", "pkg-types": "^2.0.0", "tinyexec": "^0.3.2" }, "bin": { "nypm": "dist/cli.mjs" } }, "sha512-mn8wBFV9G9+UFHIrq+pZ2r2zL4aPau/by3kJb3cM7+5tQHMt6HGQB8FDIeKFYp8o0D2pnH6nVsO88N4AmUxIWg=="],
-
- "object-assign": ["object-assign@4.1.1", "", {}, "sha512-rJgTQnkUnH1sFw8yT6VSU3zD3sWmu6sZhIseY8VX+GRu3P6F7Fu+JNDoXfklElbLJSnc3FUQHVe4cU5hj+BcUg=="],
-
- "object-hash": ["object-hash@3.0.0", "", {}, "sha512-RSn9F68PjH9HqtltsSnqYC1XXoWe9Bju5+213R98cNGttag9q9yAOTzdbsqvIa7aNm5WffBZFpWYr2aWrklWAw=="],
-
- "ohash": ["ohash@2.0.11", "", {}, "sha512-RdR9FQrFwNBNXAr4GixM8YaRZRJ5PUWbKYbE5eOsrwAjJW0q2REGcf79oYPsLyskQCZG1PLN+S/K1V00joZAoQ=="],
-
- "option-validator": ["option-validator@2.0.6", "", { "dependencies": { "kind-of": "^6.0.3" } }, "sha512-tmZDan2LRIRQyhUGvkff68/O0R8UmF+Btmiiz0SmSw2ng3CfPZB9wJlIjHpe/MKUZqyIZkVIXCrwr1tIN+0Dzg=="],
-
- "package-json-from-dist": ["package-json-from-dist@1.0.1", "", {}, "sha512-UEZIS3/by4OC8vL3P2dTXRETpebLI2NiI5vIrjaD/5UtrkFX/tNbwjTSRAGC/+7CAo2pIcBaRgWmcBBHcsaCIw=="],
-
- "path-key": ["path-key@3.1.1", "", {}, "sha512-ojmeN0qd+y0jszEtoY48r0Peq5dwMEkIlCOu6Q5f41lfkswXuKtYrhgoTpLnyIcHm24Uhqx+5Tqm2InSwLhE6Q=="],
-
- "path-parse": ["path-parse@1.0.7", "", {}, "sha512-LDJzPVEEEPR+y48z93A0Ed0yXb8pAByGWo/k5YYdYgpY2/2EsOsksJrq7lOHxryrVOn1ejG6oAp8ahvOIQD8sw=="],
-
- "path-scurry": ["path-scurry@1.11.1", "", { "dependencies": { "lru-cache": "^10.2.0", "minipass": "^5.0.0 || ^6.0.2 || ^7.0.0" } }, "sha512-Xa4Nw17FS9ApQFJ9umLiJS4orGjm7ZzwUrwamcGQuHSzDyth9boKDaycYdDcZDuqYATXw4HFXgaqWTctW/v1HA=="],
-
- "path-type": ["path-type@6.0.0", "", {}, "sha512-Vj7sf++t5pBD637NSfkxpHSMfWaeig5+DKWLhcqIYx6mWQz5hdJTGDVMQiJcw1ZYkhs7AazKDGpRVji1LJCZUQ=="],
-
- "pathe": ["pathe@2.0.3", "", {}, "sha512-WUjGcAqP1gQacoQe+OBJsFA7Ld4DyXuUIjZ5cc75cLHvJ7dtNsTugphxIADwspS+AraAUePCKrSVtPLFj/F88w=="],
-
- "perfect-debounce": ["perfect-debounce@1.0.0", "", {}, "sha512-xCy9V055GLEqoFaHoC1SoLIaLmWctgCUaBaWxDZ7/Zx4CTyX7cJQLJOok/orfjZAh9kEYpjJa4d0KcJmCbctZA=="],
-
- "picocolors": ["picocolors@1.1.1", "", {}, "sha512-xceH2snhtb5M9liqDsmEw56le376mTZkEX/jEb/RxNFyegNul7eNslCXP9FDj/Lcu0X8KEyMceP2ntpaHrDEVA=="],
-
- "picomatch": ["picomatch@2.3.1", "", {}, "sha512-JU3teHTNjmE2VCGFzuY8EXzCDVwEqB2a8fsIvwaStHhAWJEeVd1o1QD80CU6+ZdEXXSLbSsuLwJjkCBWqRQUVA=="],
-
- "pify": ["pify@2.3.0", "", {}, "sha512-udgsAY+fTnvv7kI7aaxbqwWNb0AHiB0qBO89PZKPkoTmGOgdbrHDKD+0B2X4uTfJ/FT1R09r9gTsjUjNJotuog=="],
-
- "pirates": ["pirates@4.0.7", "", {}, "sha512-TfySrs/5nm8fQJDcBDuUng3VOUKsd7S+zqvbOTiGXHfxX4wK31ard+hoNuvkicM/2YFzlpDgABOevKSsB4G/FA=="],
-
- "pkg-types": ["pkg-types@2.1.0", "", { "dependencies": { "confbox": "^0.2.1", "exsolve": "^1.0.1", "pathe": "^2.0.3" } }, "sha512-wmJwA+8ihJixSoHKxZJRBQG1oY8Yr9pGLzRmSsNms0iNWyHHAlZCa7mmKiFR10YPZuz/2k169JiS/inOjBCZ2A=="],
-
- "popmotion": ["popmotion@11.0.5", "", { "dependencies": { "framesync": "6.1.2", "hey-listen": "^1.0.8", "style-value-types": "5.1.2", "tslib": "2.4.0" } }, "sha512-la8gPM1WYeFznb/JqF4GiTkRRPZsfaj2+kCxqQgr2MJylMmIKUwBfWW8Wa5fml/8gmtlD5yI01MP1QCZPWmppA=="],
-
- "postcss": ["postcss@8.5.3", "", { "dependencies": { "nanoid": "^3.3.8", "picocolors": "^1.1.1", "source-map-js": "^1.2.1" } }, "sha512-dle9A3yYxlBSrt8Fu+IpjGT8SY8hN0mlaA6GY8t0P5PjIOZemULz/E2Bnm/2dcUOena75OTNkHI76uZBNUUq3A=="],
-
- "postcss-import": ["postcss-import@15.1.0", "", { "dependencies": { "postcss-value-parser": "^4.0.0", "read-cache": "^1.0.0", "resolve": "^1.1.7" }, "peerDependencies": { "postcss": "^8.0.0" } }, "sha512-hpr+J05B2FVYUAXHeK1YyI267J/dDDhMU6B6civm8hSY1jYJnBXxzKDKDswzJmtLHryrjhnDjqqp/49t8FALew=="],
-
- "postcss-js": ["postcss-js@4.0.1", "", { "dependencies": { "camelcase-css": "^2.0.1" }, "peerDependencies": { "postcss": "^8.4.21" } }, "sha512-dDLF8pEO191hJMtlHFPRa8xsizHaM82MLfNkUHdUtVEV3tgTp5oj+8qbEqYM57SLfc74KSbw//4SeJma2LRVIw=="],
-
- "postcss-load-config": ["postcss-load-config@4.0.2", "", { "dependencies": { "lilconfig": "^3.0.0", "yaml": "^2.3.4" }, "peerDependencies": { "postcss": ">=8.0.9", "ts-node": ">=9.0.0" }, "optionalPeers": ["postcss", "ts-node"] }, "sha512-bSVhyJGL00wMVoPUzAVAnbEoWyqRxkjv64tUl427SKnPrENtq6hJwUojroMz2VB+Q1edmi4IfrAPpami5VVgMQ=="],
-
- "postcss-nested": ["postcss-nested@6.2.0", "", { "dependencies": { "postcss-selector-parser": "^6.1.1" }, "peerDependencies": { "postcss": "^8.2.14" } }, "sha512-HQbt28KulC5AJzG+cZtj9kvKB93CFCdLvog1WFLf1D+xmMvPGlBstkpTEZfK5+AN9hfJocyBFCNiqyS48bpgzQ=="],
-
- "postcss-selector-parser": ["postcss-selector-parser@6.1.2", "", { "dependencies": { "cssesc": "^3.0.0", "util-deprecate": "^1.0.2" } }, "sha512-Q8qQfPiZ+THO/3ZrOrO0cJJKfpYCagtMUkXbnEfmgUjwXg6z/WBeOyS9APBBPCTSiDV+s4SwQGu8yFsiMRIudg=="],
-
- "postcss-value-parser": ["postcss-value-parser@4.2.0", "", {}, "sha512-1NNCs6uurfkVbeXG4S8JFT9t19m45ICnif8zWLd5oPSZ50QnwMfK+H3jv408d4jw/7Bttv5axS5IiHoLaVNHeQ=="],
-
- "prettier": ["prettier@3.5.3", "", { "bin": { "prettier": "bin/prettier.cjs" } }, "sha512-QQtaxnoDJeAkDvDKWCLiwIXkTgRhwYDEQCghU9Z6q03iyek/rxRh/2lC3HB7P8sWT2xC/y5JDctPLBIGzHKbhw=="],
-
- "prettier-plugin-tailwindcss": ["prettier-plugin-tailwindcss@0.6.11", "", { "peerDependencies": { "@ianvs/prettier-plugin-sort-imports": "*", "@prettier/plugin-pug": "*", "@shopify/prettier-plugin-liquid": "*", "@trivago/prettier-plugin-sort-imports": "*", "@zackad/prettier-plugin-twig": "*", "prettier": "^3.0", "prettier-plugin-astro": "*", "prettier-plugin-css-order": "*", "prettier-plugin-import-sort": "*", "prettier-plugin-jsdoc": "*", "prettier-plugin-marko": "*", "prettier-plugin-multiline-arrays": "*", "prettier-plugin-organize-attributes": "*", "prettier-plugin-organize-imports": "*", "prettier-plugin-sort-imports": "*", "prettier-plugin-style-order": "*", "prettier-plugin-svelte": "*" }, "optionalPeers": ["@ianvs/prettier-plugin-sort-imports", "@prettier/plugin-pug", "@shopify/prettier-plugin-liquid", "@trivago/prettier-plugin-sort-imports", "@zackad/prettier-plugin-twig", "prettier-plugin-astro", "prettier-plugin-css-order", "prettier-plugin-import-sort", "prettier-plugin-jsdoc", "prettier-plugin-marko", "prettier-plugin-multiline-arrays", "prettier-plugin-organize-attributes", "prettier-plugin-organize-imports", "prettier-plugin-sort-imports", "prettier-plugin-style-order", "prettier-plugin-svelte"] }, "sha512-YxaYSIvZPAqhrrEpRtonnrXdghZg1irNg4qrjboCXrpybLWVs55cW2N3juhspVJiO0JBvYJT8SYsJpc8OQSnsA=="],
-
- "proxy-from-env": ["proxy-from-env@1.1.0", "", {}, "sha512-D+zkORCbA9f1tdWRK0RaCR3GPv50cMxcrz4X8k5LTSUD1Dkw47mKJEZQNunItRTkWwgtaUSo1RVFRIG9ZXiFYg=="],
-
- "quansync": ["quansync@0.2.10", "", {}, "sha512-t41VRkMYbkHyCYmOvx/6URnN80H7k4X0lLdBMGsz+maAwrJQYB1djpV6vHrQIBE0WBSGqhtEHrK9U3DWWH8v7A=="],
-
- "queue-microtask": ["queue-microtask@1.2.3", "", {}, "sha512-NuaNSa6flKT5JaSYQzJok04JzTL1CA6aGhv5rfLW3PgqA+M2ChpZQnAC8h8i4ZFkBS8X5RqkDBHA7r4hej3K9A=="],
-
- "rc9": ["rc9@2.1.2", "", { "dependencies": { "defu": "^6.1.4", "destr": "^2.0.3" } }, "sha512-btXCnMmRIBINM2LDZoEmOogIZU7Qe7zn4BpomSKZ/ykbLObuBdvG+mFq11DL6fjH1DRwHhrlgtYWG96bJiC7Cg=="],
-
- "read-cache": ["read-cache@1.0.0", "", { "dependencies": { "pify": "^2.3.0" } }, "sha512-Owdv/Ft7IjOgm/i0xvNDZ1LrRANRfew4b2prF3OWMQLxLfu3bS8FVhCsrSCMK4lR56Y9ya+AThoTpDCTxCmpRA=="],
-
- "readdirp": ["readdirp@3.6.0", "", { "dependencies": { "picomatch": "^2.2.1" } }, "sha512-hOS089on8RduqdbhvQ5Z37A0ESjsqz6qnRcffsMU3495FuTdqSm+7bhJ29JvIOsBDEEnan5DPu9t3To9VRlMzA=="],
-
- "resolve": ["resolve@1.22.10", "", { "dependencies": { "is-core-module": "^2.16.0", "path-parse": "^1.0.7", "supports-preserve-symlinks-flag": "^1.0.0" }, "bin": { "resolve": "bin/resolve" } }, "sha512-NPRy+/ncIMeDlTAsuqwKIiferiawhefFJtkNSW0qZJEqMEb+qBt/77B/jGeeek+F0uOeN05CDa6HXbbIgtVX4w=="],
-
- "reusify": ["reusify@1.1.0", "", {}, "sha512-g6QUff04oZpHs0eG5p83rFLhHeV00ug/Yf9nZM6fLeUrPguBTkTQOdpAWWspMh55TZfVQDPaN3NQJfbVRAxdIw=="],
-
- "rollup": ["rollup@4.39.0", "", { "dependencies": { "@types/estree": "1.0.7" }, "optionalDependencies": { "@rollup/rollup-android-arm-eabi": "4.39.0", "@rollup/rollup-android-arm64": "4.39.0", "@rollup/rollup-darwin-arm64": "4.39.0", "@rollup/rollup-darwin-x64": "4.39.0", "@rollup/rollup-freebsd-arm64": "4.39.0", "@rollup/rollup-freebsd-x64": "4.39.0", "@rollup/rollup-linux-arm-gnueabihf": "4.39.0", "@rollup/rollup-linux-arm-musleabihf": "4.39.0", "@rollup/rollup-linux-arm64-gnu": "4.39.0", "@rollup/rollup-linux-arm64-musl": "4.39.0", "@rollup/rollup-linux-loongarch64-gnu": "4.39.0", "@rollup/rollup-linux-powerpc64le-gnu": "4.39.0", "@rollup/rollup-linux-riscv64-gnu": "4.39.0", "@rollup/rollup-linux-riscv64-musl": "4.39.0", "@rollup/rollup-linux-s390x-gnu": "4.39.0", "@rollup/rollup-linux-x64-gnu": "4.39.0", "@rollup/rollup-linux-x64-musl": "4.39.0", "@rollup/rollup-win32-arm64-msvc": "4.39.0", "@rollup/rollup-win32-ia32-msvc": "4.39.0", "@rollup/rollup-win32-x64-msvc": "4.39.0", "fsevents": "~2.3.2" }, "bin": { "rollup": "dist/bin/rollup" } }, "sha512-thI8kNc02yNvnmJp8dr3fNWJ9tCONDhp6TV35X6HkKGGs9E6q7YWCHbe5vKiTa7TAiNcFEmXKj3X/pG2b3ci0g=="],
-
- "run-parallel": ["run-parallel@1.2.0", "", { "dependencies": { "queue-microtask": "^1.2.2" } }, "sha512-5l4VyZR86LZ/lDxZTR6jqL8AFE2S0IFLMP26AbjsLVADxHdhB/c0GUsH+y39UfCi3dzz8OlQuPmnaJOMoDHQBA=="],
-
- "scule": ["scule@1.3.0", "", {}, "sha512-6FtHJEvt+pVMIB9IBY+IcCJ6Z5f1iQnytgyfKMhDKgmzYG+TeH/wx1y3l27rshSbLiSanrR9ffZDrEsmjlQF2g=="],
-
- "semver": ["semver@6.3.1", "", { "bin": { "semver": "bin/semver.js" } }, "sha512-BR7VvDCVHO+q2xBEWskxS6DJE1qRnb7DxzUrogb71CWoSficBxYsiAGd+Kl0mmq/MprG9yArRkyrQxTO6XjMzA=="],
-
- "shebang-command": ["shebang-command@2.0.0", "", { "dependencies": { "shebang-regex": "^3.0.0" } }, "sha512-kHxr2zZpYtdmrN1qDjrrX/Z1rR1kG8Dx+gkpK1G4eXmvXswmcE1hTWBWYUzlraYw1/yZp6YuDY77YtvbN0dmDA=="],
-
- "shebang-regex": ["shebang-regex@3.0.0", "", {}, "sha512-7++dFhtcx3353uBaq8DDR4NuxBetBzC7ZQOhmTQInHEd6bSrXdiEyzCvG07Z44UYdLShWUyXt5M/yhz8ekcb1A=="],
-
- "signal-exit": ["signal-exit@4.1.0", "", {}, "sha512-bzyZ1e88w9O1iNJbKnOlvYTrWPDl46O1bG0D3XInv+9tkPrxrN8jUUTiFlDkkmKWgn1M6CfIA13SuGqOa9Korw=="],
-
- "slash": ["slash@5.1.0", "", {}, "sha512-ZA6oR3T/pEyuqwMgAKT0/hAv8oAXckzbkmR0UkUosQ+Mc4RxGoJkRmwHgHufaenlyAgE1Mxgpdcrf75y6XcnDg=="],
-
- "source-map-js": ["source-map-js@1.2.1", "", {}, "sha512-UXWMKhLOwVKb728IUtQPXxfYU+usdybtUrK/8uGE8CQMvrhOpwvzDBwj0QhSL7MQc7vIsISBG8VQ8+IDQxpfQA=="],
-
- "std-env": ["std-env@3.9.0", "", {}, "sha512-UGvjygr6F6tpH7o2qyqR6QYpwraIjKSdtzyBdyytFOHmPZY917kwdwLG0RbOjWOnKmnm3PeHjaoLLMie7kPLQw=="],
-
- "string-width": ["string-width@5.1.2", "", { "dependencies": { "eastasianwidth": "^0.2.0", "emoji-regex": "^9.2.2", "strip-ansi": "^7.0.1" } }, "sha512-HnLOCR3vjcY8beoNLtcjZ5/nxn2afmME6lhrDrebokqMap+XbeW8n9TXpPDOqdGK5qcI3oT0GKTW6wC7EMiVqA=="],
-
- "string-width-cjs": ["string-width@4.2.3", "", { "dependencies": { "emoji-regex": "^8.0.0", "is-fullwidth-code-point": "^3.0.0", "strip-ansi": "^6.0.1" } }, "sha512-wKyQRQpjJ0sIp62ErSZdGsjMJWsap5oRNihHhu6G7JVO/9jIB6UyevL+tXuOqrng8j/cxKTWyWUwvSTriiZz/g=="],
-
- "strip-ansi": ["strip-ansi@7.1.0", "", { "dependencies": { "ansi-regex": "^6.0.1" } }, "sha512-iq6eVVI64nQQTRYq2KtEg2d2uU7LElhTJwsH4YzIHZshxlgZms/wIc4VoDQTlG/IvVIrBKG06CrZnp0qv7hkcQ=="],
-
- "strip-ansi-cjs": ["strip-ansi@6.0.1", "", { "dependencies": { "ansi-regex": "^5.0.1" } }, "sha512-Y38VPSHcqkFrCpFnQ9vuSXmquuv5oXOKpGeT6aGrr3o3Gc9AlVa6JBfUSOCnbxGGZF+/0ooI7KrPuUSztUdU5A=="],
-
- "strip-literal": ["strip-literal@3.0.0", "", { "dependencies": { "js-tokens": "^9.0.1" } }, "sha512-TcccoMhJOM3OebGhSBEmp3UZ2SfDMZUEBdRA/9ynfLi8yYajyWX3JiXArcJt4Umh4vISpspkQIY8ZZoCqjbviA=="],
-
- "style-value-types": ["style-value-types@5.1.2", "", { "dependencies": { "hey-listen": "^1.0.8", "tslib": "2.4.0" } }, "sha512-Vs9fNreYF9j6W2VvuDTP7kepALi7sk0xtk2Tu8Yxi9UoajJdEVpNpCov0HsLTqXvNGKX+Uv09pkozVITi1jf3Q=="],
-
- "sucrase": ["sucrase@3.35.0", "", { "dependencies": { "@jridgewell/gen-mapping": "^0.3.2", "commander": "^4.0.0", "glob": "^10.3.10", "lines-and-columns": "^1.1.6", "mz": "^2.7.0", "pirates": "^4.0.1", "ts-interface-checker": "^0.1.9" }, "bin": { "sucrase": "bin/sucrase", "sucrase-node": "bin/sucrase-node" } }, "sha512-8EbVDiu9iN/nESwxeSxDKe0dunta1GOlHufmSSXxMD2z2/tMZpDMpvXQGsc+ajGo8y2uYUmixaSRUc/QPoQ0GA=="],
-
- "supports-preserve-symlinks-flag": ["supports-preserve-symlinks-flag@1.0.0", "", {}, "sha512-ot0WnXS9fgdkgIcePe6RHNk1WA8+muPa6cSjeR3V8K27q9BB1rTE3R1p7Hv0z1ZyAc8s6Vvv8DIyWf681MAt0w=="],
-
- "tailwindcss": ["tailwindcss@3.4.17", "", { "dependencies": { "@alloc/quick-lru": "^5.2.0", "arg": "^5.0.2", "chokidar": "^3.6.0", "didyoumean": "^1.2.2", "dlv": "^1.1.3", "fast-glob": "^3.3.2", "glob-parent": "^6.0.2", "is-glob": "^4.0.3", "jiti": "^1.21.6", "lilconfig": "^3.1.3", "micromatch": "^4.0.8", "normalize-path": "^3.0.0", "object-hash": "^3.0.0", "picocolors": "^1.1.1", "postcss": "^8.4.47", "postcss-import": "^15.1.0", "postcss-js": "^4.0.1", "postcss-load-config": "^4.0.2", "postcss-nested": "^6.2.0", "postcss-selector-parser": "^6.1.2", "resolve": "^1.22.8", "sucrase": "^3.35.0" }, "bin": { "tailwind": "lib/cli.js", "tailwindcss": "lib/cli.js" } }, "sha512-w33E2aCvSDP0tW9RZuNXadXlkHXqFzSkQew/aIa2i/Sj8fThxwovwlXHSPXTbAHwEIhBFXAedUhP2tueAKP8Og=="],
-
- "thenify": ["thenify@3.3.1", "", { "dependencies": { "any-promise": "^1.0.0" } }, "sha512-RVZSIV5IG10Hk3enotrhvz0T9em6cyHBLkH/YAZuKqd8hRkKhSfCGIcP2KUY0EPxndzANBmNllzWPwak+bheSw=="],
-
- "thenify-all": ["thenify-all@1.6.0", "", { "dependencies": { "thenify": ">= 3.1.0 < 4" } }, "sha512-RNxQH/qI8/t3thXJDwcstUO4zeqo64+Uy/+sNVRBx4Xn2OX+OZ9oP+iJnNFqplFra2ZUVeKCSa2oVWi3T4uVmA=="],
-
- "tinyexec": ["tinyexec@0.3.2", "", {}, "sha512-KQQR9yN7R5+OSwaK0XQoj22pwHoTlgYqmUscPYoknOoWCWfj/5/ABTMRi69FrKU5ffPVh5QcFikpWJI/P1ocHA=="],
-
- "tinyglobby": ["tinyglobby@0.2.12", "", { "dependencies": { "fdir": "^6.4.3", "picomatch": "^4.0.2" } }, "sha512-qkf4trmKSIiMTs/E63cxH+ojC2unam7rJ0WrauAzpT3ECNTxGRMlaXxVbfxMUC/w0LaYk6jQ4y/nGR9uBO3tww=="],
-
- "to-regex-range": ["to-regex-range@5.0.1", "", { "dependencies": { "is-number": "^7.0.0" } }, "sha512-65P7iz6X5yEr1cwcgvQxbbIw7Uk3gOy5dIdtZ4rDveLqhrdJP+Li/Hx6tyK0NEb+2GCyneCMJiGqrADCSNk8sQ=="],
-
- "ts-interface-checker": ["ts-interface-checker@0.1.13", "", {}, "sha512-Y/arvbn+rrz3JCKl9C4kVNfTfSm2/mEp5FSz5EsZSANGPSlQrpRI5M4PKF+mJnE52jOO90PnPSc3Ur3bTQw0gA=="],
-
- "tslib": ["tslib@2.3.0", "", {}, "sha512-N82ooyxVNm6h1riLCoyS9e3fuJ3AMG2zIZs2Gd1ATcSFjSA23Q0fzjjZeh0jbJvWVDZ0cJT8yaNNaaXHzueNjg=="],
-
- "typeit": ["typeit@8.8.7", "", { "dependencies": { "@types/web-animations-js": "^2.2.16" } }, "sha512-sSVpy+cjeFP6Z+fZqiHzUSShg5yYFeJEt/Qut/bX945+Axyq+Yq+GPOuuk+sofoccSv8nNX/ibOOHkbki2mEpg=="],
-
- "ufo": ["ufo@1.5.4", "", {}, "sha512-UsUk3byDzKd04EyoZ7U4DOlxQaD14JUKQl6/P7wiX4FNvUfm3XL246n9W5AmqwW5RSFJ27NAuM0iLscAOYUiGQ=="],
-
- "unctx": ["unctx@2.4.1", "", { "dependencies": { "acorn": "^8.14.0", "estree-walker": "^3.0.3", "magic-string": "^0.30.17", "unplugin": "^2.1.0" } }, "sha512-AbaYw0Nm4mK4qjhns67C+kgxR2YWiwlDBPzxrN8h8C6VtAdCgditAY5Dezu3IJy4XVqAnbrXt9oQJvsn3fyozg=="],
-
- "undici-types": ["undici-types@6.19.8", "", {}, "sha512-ve2KP6f/JnbPBFyobGHuerC9g1FYGn/F8n1LWTwNxCEzd6IfqTwUQcNXgEtmmQ6DlRrC1hrSrBnCZPokRrDHjw=="],
-
- "unicorn-magic": ["unicorn-magic@0.3.0", "", {}, "sha512-+QBBXBCvifc56fsbuxZQ6Sic3wqqc3WWaqxs58gvJrcOuN83HGTCwz3oS5phzU9LthRNE9VrJCFCLUgHeeFnfA=="],
-
- "unimport": ["unimport@4.1.3", "", { "dependencies": { "acorn": "^8.14.1", "escape-string-regexp": "^5.0.0", "estree-walker": "^3.0.3", "local-pkg": "^1.1.1", "magic-string": "^0.30.17", "mlly": "^1.7.4", "pathe": "^2.0.3", "picomatch": "^4.0.2", "pkg-types": "^2.1.0", "scule": "^1.3.0", "strip-literal": "^3.0.0", "tinyglobby": "^0.2.12", "unplugin": "^2.2.2", "unplugin-utils": "^0.2.4" } }, "sha512-H+IVJ7rAkE3b+oC8rSJ2FsPaVsweeMC8eKZc+C6Mz7+hxDF45AnrY/tVCNRBvzMwWNcJEV67WdAVcal27iMjOw=="],
-
- "unplugin": ["unplugin@2.2.2", "", { "dependencies": { "acorn": "^8.14.1", "webpack-virtual-modules": "^0.6.2" } }, "sha512-Qp+iiD+qCRnUek+nDoYvtWX7tfnYyXsrOnJ452FRTgOyKmTM7TUJ3l+PLPJOOWPTUyKISKp4isC5JJPSXUjGgw=="],
-
- "unplugin-utils": ["unplugin-utils@0.2.4", "", { "dependencies": { "pathe": "^2.0.2", "picomatch": "^4.0.2" } }, "sha512-8U/MtpkPkkk3Atewj1+RcKIjb5WBimZ/WSLhhR3w6SsIj8XJuKTacSP8g+2JhfSGw0Cb125Y+2zA/IzJZDVbhA=="],
-
- "untyped": ["untyped@2.0.0", "", { "dependencies": { "citty": "^0.1.6", "defu": "^6.1.4", "jiti": "^2.4.2", "knitwork": "^1.2.0", "scule": "^1.3.0" }, "bin": { "untyped": "dist/cli.mjs" } }, "sha512-nwNCjxJTjNuLCgFr42fEak5OcLuB3ecca+9ksPFNvtfYSLpjf+iJqSIaSnIile6ZPbKYxI5k2AfXqeopGudK/g=="],
-
- "update-browserslist-db": ["update-browserslist-db@1.1.3", "", { "dependencies": { "escalade": "^3.2.0", "picocolors": "^1.1.1" }, "peerDependencies": { "browserslist": ">= 4.21.0" }, "bin": { "update-browserslist-db": "cli.js" } }, "sha512-UxhIZQ+QInVdunkDAaiazvvT/+fXL5Osr0JZlJulepYu6Jd7qJtDZjlur0emRlT71EN3ScPoE7gvsuIKKNavKw=="],
-
- "util-deprecate": ["util-deprecate@1.0.2", "", {}, "sha512-EPD5q1uXyFxJpCrLnCc1nHnq3gOa6DZBocAIiI2TaSCA7VCJ1UJDMagCzIkXNsUYfD1daK//LTEQ8xiIbrHtcw=="],
-
- "vant": ["vant@4.9.18", "", { "dependencies": { "@vant/popperjs": "^1.3.0", "@vant/use": "^1.6.0", "@vue/shared": "^3.5.13" }, "peerDependencies": { "vue": "^3.0.0" } }, "sha512-1bmWv/G0xz45btPqSasgv4TUdTqCneyFfnrQJ3xgerGvfTC5aP/rpO4wJb5FItCZjaSw5+9FNBj2Tz6n9TLXYA=="],
-
- "vite": ["vite@5.4.17", "", { "dependencies": { "esbuild": "^0.21.3", "postcss": "^8.4.43", "rollup": "^4.20.0" }, "optionalDependencies": { "fsevents": "~2.3.3" }, "peerDependencies": { "@types/node": "^18.0.0 || >=20.0.0", "less": "*", "lightningcss": "^1.21.0", "sass": "*", "sass-embedded": "*", "stylus": "*", "sugarss": "*", "terser": "^5.4.0" }, "optionalPeers": ["@types/node", "less", "lightningcss", "sass", "sass-embedded", "stylus", "sugarss", "terser"], "bin": { "vite": "bin/vite.js" } }, "sha512-5+VqZryDj4wgCs55o9Lp+p8GE78TLVg0lasCH5xFZ4jacZjtqZa6JUw9/p0WeAojaOfncSM6v77InkFPGnvPvg=="],
-
- "vite-plugin-vue-inspector": ["vite-plugin-vue-inspector@5.3.1", "", { "dependencies": { "@babel/core": "^7.23.0", "@babel/plugin-proposal-decorators": "^7.23.0", "@babel/plugin-syntax-import-attributes": "^7.22.5", "@babel/plugin-syntax-import-meta": "^7.10.4", "@babel/plugin-transform-typescript": "^7.22.15", "@vue/babel-plugin-jsx": "^1.1.5", "@vue/compiler-dom": "^3.3.4", "kolorist": "^1.8.0", "magic-string": "^0.30.4" }, "peerDependencies": { "vite": "^3.0.0-0 || ^4.0.0-0 || ^5.0.0-0 || ^6.0.0-0" } }, "sha512-cBk172kZKTdvGpJuzCCLg8lJ909wopwsu3Ve9FsL1XsnLBiRT9U3MePcqrgGHgCX2ZgkqZmAGR8taxw+TV6s7A=="],
-
- "vue": ["vue@3.5.13", "", { "dependencies": { "@vue/compiler-dom": "3.5.13", "@vue/compiler-sfc": "3.5.13", "@vue/runtime-dom": "3.5.13", "@vue/server-renderer": "3.5.13", "@vue/shared": "3.5.13" }, "peerDependencies": { "typescript": "*" }, "optionalPeers": ["typescript"] }, "sha512-wmeiSMxkZCSc+PM2w2VRsOYAZC8GdipNFRTsLSfodVqI9mbejKeXEGr8SckuLnrQPGe3oJN5c3K0vpoU9q/wCQ=="],
-
- "vue-countup-v3": ["vue-countup-v3@1.4.2", "", { "dependencies": { "countup.js": "^2.6.2" }, "peerDependencies": { "vue": "^3.0.0" } }, "sha512-nRC65jBcdgwybxqztgd/WaK8ZN5T9ECPyiCFGYFMewCsvqdRVo1CtpT7JREcPNF837Fgu/izTSFiuzrIGD6w0A=="],
-
- "vue-demi": ["vue-demi@0.13.11", "", { "peerDependencies": { "@vue/composition-api": "^1.0.0-rc.1", "vue": "^3.0.0-0 || ^2.6.0" }, "optionalPeers": ["@vue/composition-api"], "bin": { "vue-demi-fix": "bin/vue-demi-fix.js", "vue-demi-switch": "bin/vue-demi-switch.js" } }, "sha512-IR8HoEEGM65YY3ZJYAjMlKygDQn25D5ajNFNoKh9RSDMQtlzCxtfQjdQgv9jjK+m3377SsJXY8ysq8kLCZL25A=="],
-
- "vue-echarts": ["vue-echarts@7.0.3", "", { "dependencies": { "vue-demi": "^0.13.11" }, "peerDependencies": { "@vue/runtime-core": "^3.0.0", "echarts": "^5.5.1", "vue": "^2.7.0 || ^3.1.1" }, "optionalPeers": ["@vue/runtime-core"] }, "sha512-/jSxNwOsw5+dYAUcwSfkLwKPuzTQ0Cepz1LxCOpj2QcHrrmUa/Ql0eQqMmc1rTPQVrh2JQ29n2dhq75ZcHvRDw=="],
-
- "vue-router": ["vue-router@4.5.0", "", { "dependencies": { "@vue/devtools-api": "^6.6.4" }, "peerDependencies": { "vue": "^3.2.0" } }, "sha512-HDuk+PuH5monfNuY+ct49mNmkCRK4xJAV9Ts4z9UFc4rzdDnxQLyCMGGc8pKhZhHTVzfanpNwB/lwqevcBwI4w=="],
-
- "vue3-lottie": ["vue3-lottie@3.3.1", "", { "dependencies": { "fast-deep-equal": "^3.1.3", "klona": "^2.0.6", "lottie-web": "5.12.2" }, "peerDependencies": { "vue": "^3.2" } }, "sha512-60uQmx4eefi3FdPjAxWnblrgJJjnVTXUA6e4BAI3jGzgOSR76pyzL1rrWDiyPmMFo4mTw4wGTW6Gbkg3HR1mYw=="],
-
- "webpack-virtual-modules": ["webpack-virtual-modules@0.6.2", "", {}, "sha512-66/V2i5hQanC51vBQKPH4aI8NMAcBW59FVBs+rC7eGHupMyfn34q7rZIE+ETlJ+XTevqfUhVVBgSUNSW2flEUQ=="],
-
- "which": ["which@2.0.2", "", { "dependencies": { "isexe": "^2.0.0" }, "bin": { "node-which": "./bin/node-which" } }, "sha512-BLI3Tl1TW3Pvl70l3yq3Y64i+awpwXqsGBYWkkqMtnbXgrMD+yj7rhW0kuEDxzJaYXGjEW5ogapKNMEKNMjibA=="],
-
- "wrap-ansi": ["wrap-ansi@8.1.0", "", { "dependencies": { "ansi-styles": "^6.1.0", "string-width": "^5.0.1", "strip-ansi": "^7.0.1" } }, "sha512-si7QWI6zUMq56bESFvagtmzMdGOtoxfR+Sez11Mobfc7tm+VkUckk9bW2UeffTGVUbOksxmSw0AA2gs8g71NCQ=="],
-
- "wrap-ansi-cjs": ["wrap-ansi@7.0.0", "", { "dependencies": { "ansi-styles": "^4.0.0", "string-width": "^4.1.0", "strip-ansi": "^6.0.0" } }, "sha512-YVGIj2kamLSTxw6NsZjoBxfSwsn0ycdesmc4p+Q21c5zPuZ1pl+NfxVdxPtdHvmNVOQ6XSYG4AUtyt/Fi7D16Q=="],
-
- "yallist": ["yallist@3.1.1", "", {}, "sha512-a4UGQaWPH59mOXUYnAG2ewncQS4i4F43Tv3JoAM+s2VDAmS9NsK8GpDMLrCHPksFT7h3K6TOoUNn2pb7RoXx4g=="],
-
- "yaml": ["yaml@2.7.1", "", { "bin": { "yaml": "bin.mjs" } }, "sha512-10ULxpnOCQXxJvBgxsn9ptjq6uviG/htZKk9veJGhlqn3w/DxQ631zFF+nlQXLwmImeS5amR2dl2U8sg6U9jsQ=="],
-
- "zrender": ["zrender@5.6.1", "", { "dependencies": { "tslib": "2.3.0" } }, "sha512-OFXkDJKcrlx5su2XbzJvj/34Q3m6PvyCZkVPHGYpcCJ52ek4U/ymZyfuV1nKE23AyBJ51E/6Yr0mhZ7xGTO4ag=="],
-
- "@nuxt/kit/jiti": ["jiti@2.4.2", "", { "bin": { "jiti": "lib/jiti-cli.mjs" } }, "sha512-rg9zJN+G4n2nfJl5MW3BMygZX56zKPNVEYYqq7adpmMh4Jn2QNEwhvQlFy6jPVdcod7txZtKHWnyZiA3a0zP7A=="],
-
- "@nuxt/kit/semver": ["semver@7.7.1", "", { "bin": { "semver": "bin/semver.js" } }, "sha512-hlq8tAfn0m/61p4BVRcPzIGr6LKiMwo4VM6dGi6pt4qcRkmNzTcWq6eCEjEh+qXjkMDvPlOFFSGwQjoEa6gyMA=="],
-
- "@vueuse/motion/@vueuse/core": ["@vueuse/core@10.11.1", "", { "dependencies": { "@types/web-bluetooth": "^0.0.20", "@vueuse/metadata": "10.11.1", "@vueuse/shared": "10.11.1", "vue-demi": ">=0.14.8" } }, "sha512-guoy26JQktXPcz+0n3GukWIy/JDNKti9v6VEMu6kV2sYBsWuGiTU8OWdg+ADfUbHg3/3DlqySDe7JmdHrktiww=="],
-
- "@vueuse/motion/@vueuse/shared": ["@vueuse/shared@10.11.1", "", { "dependencies": { "vue-demi": ">=0.14.8" } }, "sha512-LHpC8711VFZlDaYUXEBbFBCQ7GS3dVU9mjOhhMhXP6txTV4EhYQg/KGnQuvt/sPAtoUKq7VVUnL6mVtFoL42sA=="],
-
- "c12/chokidar": ["chokidar@4.0.3", "", { "dependencies": { "readdirp": "^4.0.1" } }, "sha512-Qgzu8kfBvo+cA4962jnP1KkS6Dop5NS6g7R5LFYJr4b8Ub94PPQXUksCw9PvXoeXPRRddRNC5C1JQUR2SMGtnA=="],
-
- "c12/jiti": ["jiti@2.4.2", "", { "bin": { "jiti": "lib/jiti-cli.mjs" } }, "sha512-rg9zJN+G4n2nfJl5MW3BMygZX56zKPNVEYYqq7adpmMh4Jn2QNEwhvQlFy6jPVdcod7txZtKHWnyZiA3a0zP7A=="],
-
- "chokidar/glob-parent": ["glob-parent@5.1.2", "", { "dependencies": { "is-glob": "^4.0.1" } }, "sha512-AOIgSQCepiJYwP3ARnGx+5VnTu2HBYdzbGP45eLw1vr3zB3vZLeyed1sC9hnbcOc9/SrMyM5RPQrkGz4aS9Zow=="],
-
- "fast-glob/glob-parent": ["glob-parent@5.1.2", "", { "dependencies": { "is-glob": "^4.0.1" } }, "sha512-AOIgSQCepiJYwP3ARnGx+5VnTu2HBYdzbGP45eLw1vr3zB3vZLeyed1sC9hnbcOc9/SrMyM5RPQrkGz4aS9Zow=="],
-
- "framesync/tslib": ["tslib@2.4.0", "", {}, "sha512-d6xOpEDfsi2CZVlPQzGeux8XMwLT9hssAsaPYExaQMuYskwb+x1x7J371tWlbBdWHroy99KnVB6qIkUbs5X3UQ=="],
-
- "mlly/pkg-types": ["pkg-types@1.3.1", "", { "dependencies": { "confbox": "^0.1.8", "mlly": "^1.7.4", "pathe": "^2.0.1" } }, "sha512-/Jm5M4RvtBFVkKWRu2BLUTNP8/M2a+UwuAX+ae4770q1qVGtfjG+WTCupoZixokjmHiry8uI+dlY8KXYV5HVVQ=="],
-
- "path-scurry/lru-cache": ["lru-cache@10.4.3", "", {}, "sha512-JNAzZcXrCt42VGLuYz0zfAzDfAvJWW6AfYlDBQyDV5DClI2m5sAmK+OIO7s59XfsRsWHp02jAJrRadPRGTt6SQ=="],
-
- "popmotion/tslib": ["tslib@2.4.0", "", {}, "sha512-d6xOpEDfsi2CZVlPQzGeux8XMwLT9hssAsaPYExaQMuYskwb+x1x7J371tWlbBdWHroy99KnVB6qIkUbs5X3UQ=="],
-
- "string-width-cjs/emoji-regex": ["emoji-regex@8.0.0", "", {}, "sha512-MSjYzcWNOA0ewAHpz0MxpYFvwg6yjy1NG3xteoqz644VCo/RPgnr1/GGt+ic3iJTzQ8Eu3TdM14SawnVUmGE6A=="],
-
- "string-width-cjs/strip-ansi": ["strip-ansi@6.0.1", "", { "dependencies": { "ansi-regex": "^5.0.1" } }, "sha512-Y38VPSHcqkFrCpFnQ9vuSXmquuv5oXOKpGeT6aGrr3o3Gc9AlVa6JBfUSOCnbxGGZF+/0ooI7KrPuUSztUdU5A=="],
-
- "strip-ansi-cjs/ansi-regex": ["ansi-regex@5.0.1", "", {}, "sha512-quJQXlTSUGL2LH9SUXo8VwsY4soanhgo6LNSm84E1LBcE8s3O0wpdiRzyR9z/ZZJMlMWv37qOOb9pdJlMUEKFQ=="],
-
- "strip-literal/js-tokens": ["js-tokens@9.0.1", "", {}, "sha512-mxa9E9ITFOt0ban3j6L5MpjwegGz6lBQmM1IJkWeBZGcMxto50+eWdjC/52xDbS2vy0k7vIMK0Fe2wfL9OQSpQ=="],
-
- "style-value-types/tslib": ["tslib@2.4.0", "", {}, "sha512-d6xOpEDfsi2CZVlPQzGeux8XMwLT9hssAsaPYExaQMuYskwb+x1x7J371tWlbBdWHroy99KnVB6qIkUbs5X3UQ=="],
-
- "tinyglobby/picomatch": ["picomatch@4.0.2", "", {}, "sha512-M7BAV6Rlcy5u+m6oPhAPFgJTzAioX/6B0DxyvDlo9l8+T3nLKbrczg2WLUyzd45L8RqfUMyGPzekbMvX2Ldkwg=="],
-
- "unctx/estree-walker": ["estree-walker@3.0.3", "", { "dependencies": { "@types/estree": "^1.0.0" } }, "sha512-7RUKfXgSMMkzt6ZuXmqapOurLGPPfgj6l9uRZ7lRGolvk0y2yocc35LdcxKC5PQZdn2DMqioAQ2NoWcrTKmm6g=="],
-
- "unimport/estree-walker": ["estree-walker@3.0.3", "", { "dependencies": { "@types/estree": "^1.0.0" } }, "sha512-7RUKfXgSMMkzt6ZuXmqapOurLGPPfgj6l9uRZ7lRGolvk0y2yocc35LdcxKC5PQZdn2DMqioAQ2NoWcrTKmm6g=="],
-
- "unimport/picomatch": ["picomatch@4.0.2", "", {}, "sha512-M7BAV6Rlcy5u+m6oPhAPFgJTzAioX/6B0DxyvDlo9l8+T3nLKbrczg2WLUyzd45L8RqfUMyGPzekbMvX2Ldkwg=="],
-
- "unplugin-utils/picomatch": ["picomatch@4.0.2", "", {}, "sha512-M7BAV6Rlcy5u+m6oPhAPFgJTzAioX/6B0DxyvDlo9l8+T3nLKbrczg2WLUyzd45L8RqfUMyGPzekbMvX2Ldkwg=="],
-
- "untyped/jiti": ["jiti@2.4.2", "", { "bin": { "jiti": "lib/jiti-cli.mjs" } }, "sha512-rg9zJN+G4n2nfJl5MW3BMygZX56zKPNVEYYqq7adpmMh4Jn2QNEwhvQlFy6jPVdcod7txZtKHWnyZiA3a0zP7A=="],
-
- "wrap-ansi-cjs/ansi-styles": ["ansi-styles@4.3.0", "", { "dependencies": { "color-convert": "^2.0.1" } }, "sha512-zbB9rCJAT1rbjiVDb2hqKFHNYLxgtk8NURxZ3IZwD3F6NtxbXZQCnnSi1Lkx+IDohdPlFp222wVALIheZJQSEg=="],
-
- "wrap-ansi-cjs/string-width": ["string-width@4.2.3", "", { "dependencies": { "emoji-regex": "^8.0.0", "is-fullwidth-code-point": "^3.0.0", "strip-ansi": "^6.0.1" } }, "sha512-wKyQRQpjJ0sIp62ErSZdGsjMJWsap5oRNihHhu6G7JVO/9jIB6UyevL+tXuOqrng8j/cxKTWyWUwvSTriiZz/g=="],
-
- "wrap-ansi-cjs/strip-ansi": ["strip-ansi@6.0.1", "", { "dependencies": { "ansi-regex": "^5.0.1" } }, "sha512-Y38VPSHcqkFrCpFnQ9vuSXmquuv5oXOKpGeT6aGrr3o3Gc9AlVa6JBfUSOCnbxGGZF+/0ooI7KrPuUSztUdU5A=="],
-
- "@vueuse/motion/@vueuse/core/@types/web-bluetooth": ["@types/web-bluetooth@0.0.20", "", {}, "sha512-g9gZnnXVq7gM7v3tJCWV/qw7w+KeOlSHAhgF9RytFyifW6AF61hdT2ucrYhPq9hLs5JIryeupHV3qGk95dH9ow=="],
-
- "@vueuse/motion/@vueuse/core/@vueuse/metadata": ["@vueuse/metadata@10.11.1", "", {}, "sha512-IGa5FXd003Ug1qAZmyE8wF3sJ81xGLSqTqtQ6jaVfkeZ4i5kS2mwQF61yhVqojRnenVew5PldLyRgvdl4YYuSw=="],
-
- "@vueuse/motion/@vueuse/core/vue-demi": ["vue-demi@0.14.10", "", { "peerDependencies": { "@vue/composition-api": "^1.0.0-rc.1", "vue": "^3.0.0-0 || ^2.6.0" }, "optionalPeers": ["@vue/composition-api"], "bin": { "vue-demi-fix": "bin/vue-demi-fix.js", "vue-demi-switch": "bin/vue-demi-switch.js" } }, "sha512-nMZBOwuzabUO0nLgIcc6rycZEebF6eeUfaiQx9+WSk8e29IbLvPU9feI6tqW4kTo3hvoYAJkMh8n8D0fuISphg=="],
-
- "@vueuse/motion/@vueuse/shared/vue-demi": ["vue-demi@0.14.10", "", { "peerDependencies": { "@vue/composition-api": "^1.0.0-rc.1", "vue": "^3.0.0-0 || ^2.6.0" }, "optionalPeers": ["@vue/composition-api"], "bin": { "vue-demi-fix": "bin/vue-demi-fix.js", "vue-demi-switch": "bin/vue-demi-switch.js" } }, "sha512-nMZBOwuzabUO0nLgIcc6rycZEebF6eeUfaiQx9+WSk8e29IbLvPU9feI6tqW4kTo3hvoYAJkMh8n8D0fuISphg=="],
-
- "c12/chokidar/readdirp": ["readdirp@4.1.2", "", {}, "sha512-GDhwkLfywWL2s6vEjyhri+eXmfH6j1L7JE27WhqLeYzoh/A3DBaYGEj2H/HFZCn/kMfim73FXxEJTw06WtxQwg=="],
-
- "mlly/pkg-types/confbox": ["confbox@0.1.8", "", {}, "sha512-RMtmw0iFkeR4YV+fUOSucriAQNb9g8zFR52MWCtl+cCZOFRNL6zeB395vPzFhEjjn4fMxXudmELnl/KF/WrK6w=="],
-
- "string-width-cjs/strip-ansi/ansi-regex": ["ansi-regex@5.0.1", "", {}, "sha512-quJQXlTSUGL2LH9SUXo8VwsY4soanhgo6LNSm84E1LBcE8s3O0wpdiRzyR9z/ZZJMlMWv37qOOb9pdJlMUEKFQ=="],
-
- "wrap-ansi-cjs/string-width/emoji-regex": ["emoji-regex@8.0.0", "", {}, "sha512-MSjYzcWNOA0ewAHpz0MxpYFvwg6yjy1NG3xteoqz644VCo/RPgnr1/GGt+ic3iJTzQ8Eu3TdM14SawnVUmGE6A=="],
-
- "wrap-ansi-cjs/strip-ansi/ansi-regex": ["ansi-regex@5.0.1", "", {}, "sha512-quJQXlTSUGL2LH9SUXo8VwsY4soanhgo6LNSm84E1LBcE8s3O0wpdiRzyR9z/ZZJMlMWv37qOOb9pdJlMUEKFQ=="],
- }
-}
diff --git a/frontend/index.html b/frontend/index.html
index 624e57d..45fb500 100644
--- a/frontend/index.html
+++ b/frontend/index.html
@@ -1,40 +1,11 @@
-
+
-
-
-
-
-
-
-
+
+
+