Repository navigation
Tutorials Topic Modeling
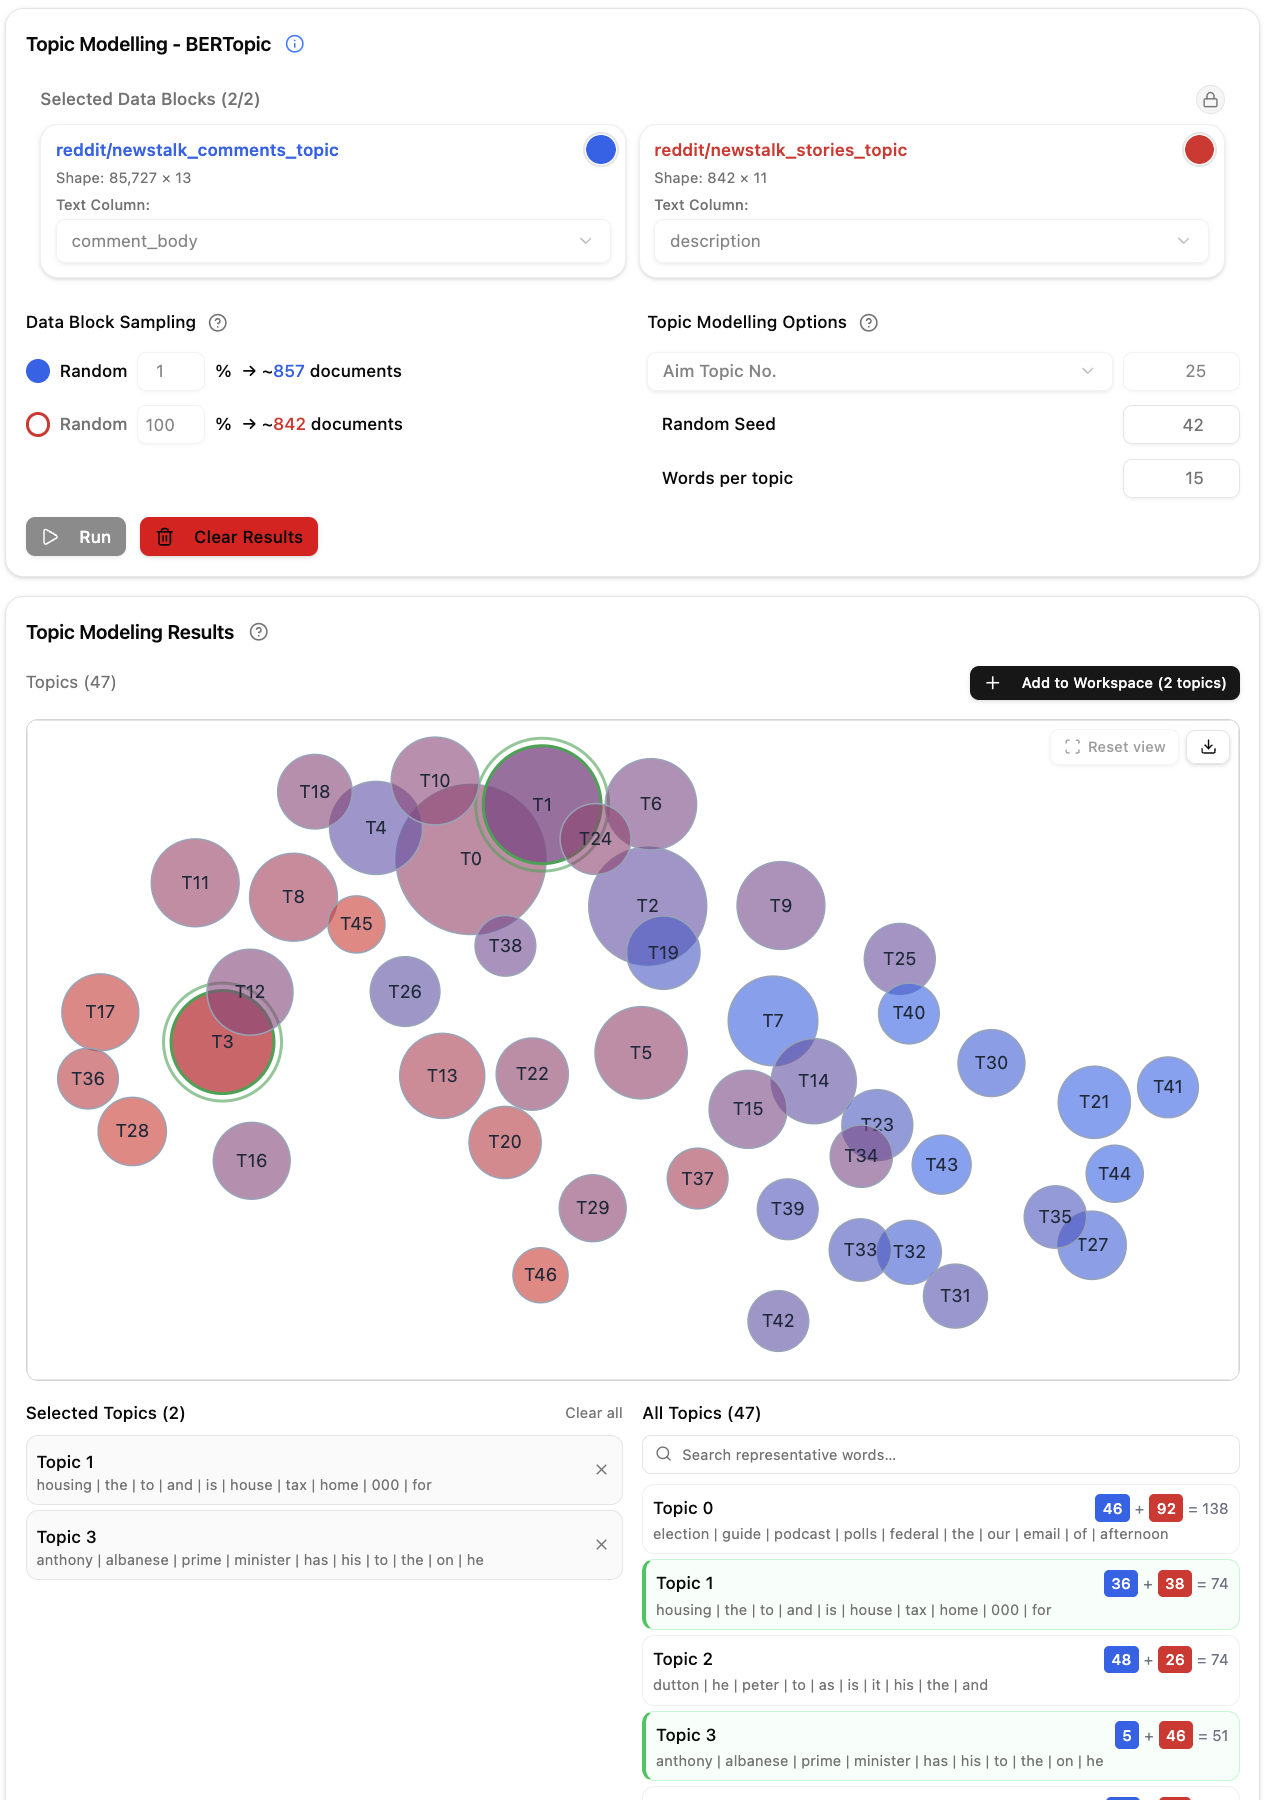
Topic modelling discovers recurring themes in a collection. Wordflow divides each document into passages, embeds those passages, groups similar passages, and rolls their topic assignments back up to each source document.
Choose one or two Data Blocks and select the text column for each. A run on two Data Blocks fits one shared model and shows how each topic is distributed between the two corpora.
Each Data Block has an independent sampling percentage. The default is 100%. Lower sampling makes exploratory runs faster but can hide rare themes or make small topics less stable. For a very large corpus, Topic sampling shortens clustering and keeps every document in the result. When the selected text is long (over about 5 million tokens), a note under the Data Blocks gives the number of tokens and a first-run time for a fast recent computer. Treat it as a best case: older or slower computers often take several times longer. Reading the text into the model takes most of a first run, and later runs on the same text reuse that work. With Suggestions on, a large input also shows a suggestion that outlines Sampling and Topic sampling. The label reports the effective document count, for example Sampling (1,380 documents). The sample uses the Seed setting, so the same Seed and percentage always pick the same documents, whichever order the Data Blocks are in. The Colour square sets the Data Block's colour in the bubble chart and topic lists.
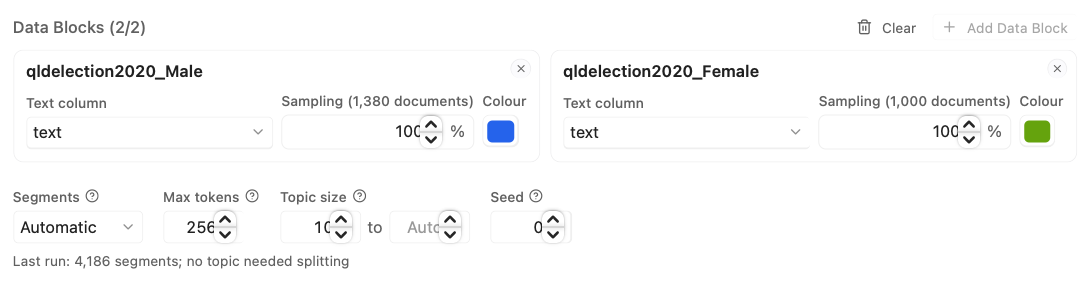
Model, Topic size and, when you have a Topic Modelling server, Remote GPU are always shown. Passages, Max tokens, Seed, Topic sampling and Ungrouped passages are advanced settings: turn on Advanced at the top right of the Topic Modelling parameters to see them. With Advanced off, a run uses Automatic passages, Max tokens Auto, seed 0 and no Topic sampling, and leaves Ungrouped passages as they are, which suits most corpora; what you set under Advanced settings is kept for when you turn it on again.
The model reads each passage and turns it into numbers, so that passages about the same subject end up close together. There are two:
| Model | Languages | Max tokens |
|---|---|---|
| English (the default) | English | up to 256 |
| Multilingual | Chinese, Japanese, Korean and about 50 other languages | up to 128 |
The English model can read Chinese, Japanese or Korean text, but it does not understand it: it mostly matches the characters two passages share, so topics form around common characters and function words rather than subjects. The Multilingual model understands these languages, and also places a Chinese sentence close to its English translation. It reads at most 128 tokens per passage and is slower than the English model.
Multilingual is chosen for you, and Max tokens drops to 128, when:
- a selected Data Block's tokeniser (set in Frequency Analysis) is a Chinese, Japanese or Korean one, such as Jieba or IPADIC; or
- otherwise, its text column looks like a language other than English. Wordflow guesses the language from the first 100 rows, as it does for the stop word lists.
A note under the settings says why. You can switch back to English, which restores your Max tokens. With Suggestions on, choosing English for such a Data Block shows a suggestion with a Use Multilingual button. A saved run keeps the model it used.
On a Mac with Apple silicon, Wordflow reads the text on the graphics processor, which is several times faster than on the processor. The first run after installing or updating Wordflow prepares the model for it once, which can add up to a minute; later runs start straight away. Results on a Mac can differ very slightly from those on another computer, so topics may differ a little.
This setting controls which spans become passages. The same method is used for every selected Data Block.
| Method | Starting unit | Short neighbouring units | Oversized unit |
|---|---|---|---|
| Automatic | Each paragraph: a blank-line block when the text has blank lines, otherwise each non-empty line | Packed into one passage while together they fit the token cap | Split into its sentences, packed the same way within the paragraph, then as below |
| Paragraph | Each trimmed, non-empty line, treated as a paragraph | Kept apart: at most one paragraph per passage | Split at the sentence boundary nearest its middle, repeatedly, then as below |
| Sentence | Each Unicode UAX #29 sentence | Kept apart: one sentence per passage | Split as below |
Automatic packs neighbouring paragraphs: it adds the next paragraph to the current passage while the passage still fits Max tokens, and starts a new passage when it would not. A paragraph is never cut to fill a passage, so every passage still begins and ends at a paragraph boundary. News articles, speeches and transcripts often have many one- or two-sentence paragraphs; packing them gives each passage enough context to embed well and cuts the number of passages several times (about 5 times fewer on a 26,000-article news corpus at 256 tokens), which makes the run much faster. A paragraph longer than the cap on its own ends the current passage and is split into its sentences, which are packed the same way within that paragraph, so an article stored as one long paragraph gives a few full passages rather than one per sentence.
Choose Paragraph when each paragraph should be its own observation (for example, short survey answers or social media posts stored one per line), and Sentence for sentence-level topics. Neither packs. In Paragraph mode a paragraph longer than the cap is cut at the sentence boundary nearest its middle, and each half again if it is still too long, so a long paragraph becomes a few similar-sized pieces that end at full stops.
A sentence that is still too long is split at the clause punctuation (commas, semicolons, colons, dashes) nearest its middle, repeatedly, so the pieces stay similar in size and end at natural pauses. Only a stretch with no usable punctuation is cut at the token cap, and a leftover of fewer than four tokens from such a cut is dropped. Passages with no letters or digits (a stray quotation mark or full stop) are dropped in every mode.
Automatic and Paragraph differ in two ways: Automatic packs short neighbouring paragraphs, and for text that uses blank lines between paragraphs it keeps each blank-line block together, while Paragraph starts a new passage at every line break. Sentence uses a language-independent Unicode boundary algorithm, so abbreviations may occasionally form a short passage.
Sets the maximum size of a passage in model tokens: Auto (the default), or 32, 64, 128 or 256, up to 128 with the Multilingual model. These are the fixed lengths the model is prepared for, so every passage fits one exactly. A run saved with another value opens at the size below it.
Auto chooses the size when the run starts. Before splitting anything, the run counts the tokens of every unit Passages keeps whole, in every text it reads (of both Data Blocks when there are two): the sentences for Sentence, the paragraphs for Paragraph, and for Automatic whole texts, or their paragraphs when nearly every text is longer than the model reads. It then takes the smallest of 32, 64, 128 and 256 that holds at least 9 in 10 of those units whole, or the model's limit when none does, and splits the text once with it. Counting units never splits them, so the choice does not depend on the size chosen and nothing is split twice. The run records the size, and Max tokens then shows it, for example Auto (64), as Max topic size shows what its Auto did. Before a run it may show an estimate from the first 200 texts, such as Auto (about 64). Choosing a size fixes it; choose Auto again to go back. Tokens may be complete words or parts of words, and the cap includes special tokens added by the embedding model. A smaller cap gives more local observations; a larger cap gives each observation more context. With Automatic, the cap is also how far short paragraphs are packed together, so a larger cap gives fewer, fuller passages.
All modes split over-cap text into non-overlapping source spans. Apart from the tiny leftovers and letterless passages described above, no text is discarded. Very small caps (such as 32 tokens) produce many short, fragment-like passages, which can make the number of topics unstable; 128–256 tokens usually gives more stable topics.
With Suggestions on and a size chosen by hand, Wordflow measures the first 200 documents of each selected Data Block in the same way. When at least 9 in 10 of their units fit whole in a smaller cap of 32, 64 or 128 tokens, a suggestion such as "Your sentences are short: 64 tokens per passage is plenty" offers to set it. Under Auto there is no suggestion: Auto already takes that size. Most passages then stay as they are, and the few longer ones are split into pieces of about that size. It only ever suggests a smaller cap.
This needs access to a GPU server for Topic Modelling, which most people don't have. Your university, a research cloud or a shared Wordflow server may offer one; you then get its address and an API key. Without one, nothing changes: Topic Modelling reads the text on this computer, and Remote GPU isn't shown at all.
Reading the text into the model takes most of a first run. Remote GPU, beside Max tokens, has a Topic Modelling server do that part on a remote graphics processor, which takes seconds where this computer can take many minutes on a large corpus. Everything else (passages, grouping, topic words) still runs here, and the text read is kept for later runs as usual.
-
Where the servers come from. On a shared Wordflow server, it provides
them and you can see them under Settings → Servers, in Topic
Modelling. On the desktop app, add your own there: a name, the address
(ending in
/v1) and an API key if the server needs one, then Check. Check lists the server's embedding models, which also confirms the key; choose which of them is English and which is Multilingual (likely names are chosen for you) before you can save. Wordflow picks the model a run needs, so there is no default model to set. These servers are listed apart from the generative AI ones Annotation uses, although one gateway can provide both. - A suggestion after a slow run. On the desktop app, when a run took five minutes or more reading the text on this computer's processor and no server is set up, a suggestion asks whether you have access to one, and Show me in Settings walks you to where it is added.
- When the tick is available. It appears once a server is set up, and can be ticked when that server serves the selected Model; otherwise it is greyed out and the text is read on this computer (or the Wordflow server). With more than one server for the model, choose which one beside the tick.
- If the server fails. A run that can't reach the server, or that the server refuses, stops with the server's error. It doesn't switch to reading on this computer part way, because the two give very slightly different results. Untick Remote GPU to run here instead.
- Saved runs remember the server they used. The text read remotely is kept apart from text read on this computer, so switching reads it again once.
Sets the smallest number of passages a Topic can have. The default is 10 and the minimum is 2. A smaller value finds more, smaller Topics, which may be noisier; a larger value needs more passages behind each Topic. Changing this value needs a new Run.
Limits the largest number of passages one Topic can hold. Topic size counts passages, not documents. Leave it empty for Auto: sometimes one huge Topic swallows most of the corpus, so Auto steps in when one Topic is the main topic of more than half of the documents (a document's main topic is the one that covers most of its text). It then splits that Topic into smaller ones and keeps the split whenever it gives more Topics; passages that fit none of them become Ungrouped. A fixed value must be larger than Min topic size, and is used exactly as you set it: Auto never changes it.
After a run with Auto, the empty field shows in grey the size Auto worked with: the cap it applied, or the size of the largest Topic when nothing was split. It tells you which way to go: a smaller Max gives more, smaller Topics, though more text may become Ungrouped; a larger one gives fewer, broader Topics. Press Tab to fill it in and change it, or type a number.
After each run, the line under the settings shows the passage count and what Auto decided, for example one topic was the main topic of 83% of documents, so topics larger than 1,540 passages were split. When splitting does not give more Topics, Auto keeps the large Topic and says so; try a fixed Max topic size then, for example a few thousand passages, and compare.
Controls the random steps of the run. The default is 0. The same seed always picks the same documents for each Data Block's sample and, with Topic sampling, the same passages.
Running again with the same seed and settings gives very similar topics, but not always identical ones: the step that maps passages before clustering spreads its work over all processor cores, and the order in which they finish can shift a few borderline passages, and occasionally add or merge a small topic. The main topics stay the same. To check how stable the topics are, compare runs with a few different seeds.
Topic sampling is off by default. When ticked, Wordflow finds the topics from a sample of passages picked at random with the Seed, then gives every other passage the topic of the sampled passage most similar to it (the nearest one by embedding cosine similarity). Every passage is still embedded and still gets a topic, or is Ungrouped when its nearest sampled passage is, so document coverage and the bubble chart cover the whole corpus. After the run the summary line reads, for example, topics found from a sample of 100,000 (seed 0).
Passages to sample. The field shows a suggested size in grey. Run uses it as it is; press Tab to fill it in and change it, or just type your own number (at least 1,000). The note under the checkbox shows the sample, the estimated number of passages in the corpus, and what the sample may miss.
Why it can help. Clustering (HDBSCAN) compares passages with their neighbours, and its time grows with the square of the number of passages: twice the passages take about four times as long. With Automatic passages a corpus of 26,000 news articles makes about 107,000 passages, and clustering all of them takes under a minute. Corpora many times larger can take much longer, and that is where sampling saves time. When the estimated passage count is large, the note under the unticked checkbox suggests it.
What it costs. A topic must have at least Min topic size passages inside the sample to be found, so the smallest topic a sample can find is about Min topic size × (all passages ÷ sample size). With 107,000 passages, a sample of 20,000 and Min topic size 10, a theme needs about 54 passages in the corpus to show up. A thin sample also blurs the gaps between neighbouring themes, so they can merge into one large topic. Use the largest sample that runs in acceptable time, and compare two seeds to check that the topics are stable.
What it does not change. Embedding takes most of a long run, and every passage is still embedded, so sampling only shortens clustering. Embeddings are saved, so a second run on the same text (for example with another Topic size) skips embedding. Topic sampling is also different from Step 2's sampling percentage, which leaves documents out of the run: with Topic sampling no document is left out of the result.
Grouping finds topics as dense groups of similar passages, and leaves out a passage that sits in a thinner area when a topic separates from its neighbours. On varied text that is often more than half of the passages. Most of them are not unlike everything: they lie between topics, or beside one. This setting says what happens to them once the topics are found.
| Choice | What happens | Use it when |
|---|---|---|
| Stay Ungrouped (the default) | A passage is in a topic only when grouping put it there. | You want each topic to hold only its clearest passages, and do not read topic sizes as shares of the corpus. |
| Join a topic they fit | Each Ungrouped passage is compared with the topic it is most similar to, and joins it when it is at least as similar to that topic as the topic's own least similar passage. The rest stay Ungrouped. | Much of the corpus is Ungrouped and you want topic sizes that describe most of it. No topic becomes looser than it already was. |
| Always join the nearest topic | Every Ungrouped passage joins the topic it is most similar to, however loosely. Nothing stays Ungrouped. | Not recommended for most work. Use it only when every passage must be in a topic, and read the topics knowing they include passages that are only loosely about them. |
Neither choice finds different topics. The topics are found first, exactly as with Stay Ungrouped, and each topic's words stay those of the passages grouping put in it. Joining only adds passages to topics that already exist, so every passage that joins makes its topic a little less tightly about one thing: slightly with Join a topic they fit, where a passage must be as similar as the topic's own passages, and more with Always join the nearest topic, which takes in passages that fit no topic well. It is unlike methods that put every text in a group from the start, where the groups themselves shift to make room. Similarity is measured between a passage and the centre of a topic, which is the average of the passages grouping put in it. After a run, the line under the settings says how many Ungrouped passages joined a topic and how many stayed, for example 35,666 Ungrouped passages joined their most similar topic; 15,550 (18%) are Ungrouped.
A topic stays defined by the passages grouping put in it. Its words, its centre, its place on the map and the way topics merge when you lower Topics all come from those passages only, so they are the same with any choice here. Passages that join are counted in the topic, in its bubble and in Add to Project, and each is marked Joined in the topic's examples.
Joining is decided once, during the run, against the topics the run found. It is not decided again when topics are merged with Topics: a passage that joined a topic stays with it when that topic merges into a broader one, so the number Ungrouped is the same at every number of topics.
With Suggestions on, a result in which 30% or more of the documents are Ungrouped suggests Join a topic they fit, and, if that was already chosen, Always join the nearest topic.
In Wordflow's own measurement, 85,727 news comments went from 58% Ungrouped to 18% with Join a topic they fit, with the same 271 topics; of 26,163 news articles, the share with no topic at all went from 39% to 6%. Lowering Min topic size instead reduced Ungrouped far less and made several times as many small topics, so it is not the way to place more text in topics.
Choose Run. The native pipeline constructs passages, embeds them with the configured sentence-transformer model, reduces the embeddings with PaCMAP, clusters them with HDBSCAN, calculates c-TF-IDF representative words, and saves the Result. The first run can be slower while model resources are loaded or downloaded.
Every mode uses this same downstream pipeline. Each passage is one equal clustering observation. When assignments are rolled back to documents, each passage is weighted by the Unicode-character length of its owned source span. Outlier coverage remains part of normalised Topic Coverage and can be dominant.
Settings are locked while Run works. After it finishes, Run turns on again only when you change a setting that affects the topics. Words per topic, stop words, search, selection, and chart controls only change what is shown, so they do not turn Run on. After a failure or a stop, Run stays off until you choose Clear; your Passages setting, token cap, and Min topic size stay selected. See How Preview, Run and Clear work.
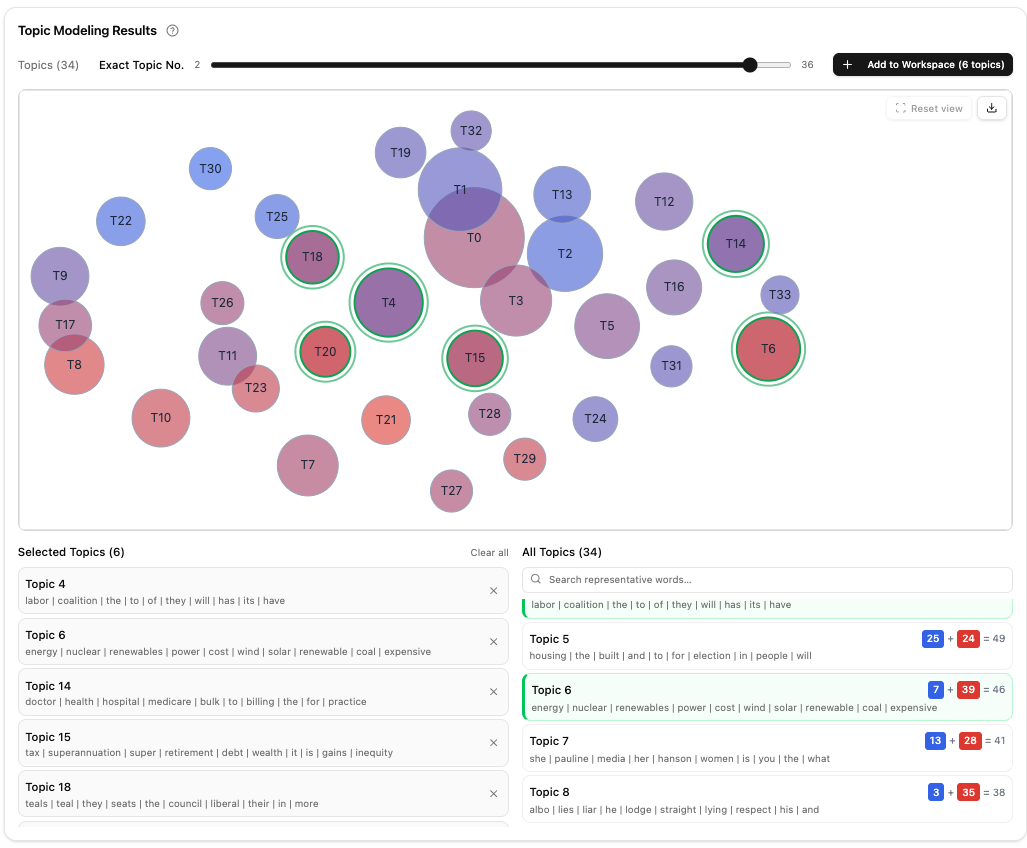
The Display options change how the result is shown: Topics, Topics per doc (top topics per document), Words per topic, Colour by, the stop word controls and the Search term, with Add to Project. Question-mark icons beside some of these controls give a short explanation. On a wide results panel the options sit beside the bubble chart, with the colour legend, in a compact column: one option per row, the search term last and Add to Project at the bottom. The chart takes the rest of the width. Drag the divider between the chart and the options to widen or narrow the chart (double-click it to go back). The panel icon at the right of the Display options heading moves the options below the chart, in a compact row, and back beside it. On a narrower panel they always sit below the chart. Click Display options to fold them to one summary line, such as "2 topics per doc · 15 words per topic · Colour: Data Block · Stop words on"; the search term and Add to Project stay available. The tab remembers these choices on this computer. Below the chart and options, the topic list takes the left third and the examples of one topic the rest; drag the divider between them to widen the list (double-click it to go back to a third). In a narrow window the list sits above the examples. The area has its own resize grip, like the chart itself.
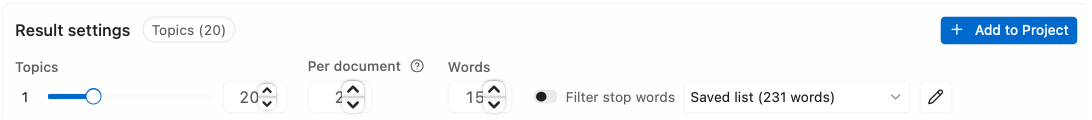
The Result starts with the number of Topics the run found, up to 100. A run that finds more, for example with a low Min topic size on a large corpus, opens with them merged into 100, so the chart stays readable, and a suggestion names how many the run found. Use Number of topics to merge them, down to one Topic, or to show more, up to every Topic the run found, without running the analysis again. Passages that fit no Topic are Ungrouped; they stay as they are and do not count toward the number shown. Results with zero or one real Topic show a fixed disabled control.
The lower bound appears to the left of the slider. Change the topic count with either the slider or the number field on its right; both stay synchronised. Wordflow updates the topics once you finish changing either control: when you release the slider, after a short pause in the arrow keys, or when you press Enter or leave the number field. The slider stays selected after each update, so the arrow keys can step the count again straight away. The current chart remains visible with Updating topics… until the new representative words, coordinates, sizes, and document assignments arrive. A failed request restores the previous value. Changing the count clears Topic selection and chart hover or zoom state. Search, stop words, and Words per topic remain in place.
A changed topic count is remembered with the result. If a lower cluster count cannot support the current Top topics per row, Wordflow sends one update with that value clamped to the new count. Running again starts from the natural count (at most 100) and Top 2. Export and Add to Project use the topics on screen and are unavailable while an update is pending.
A passage joins a Topic only when it sits in a dense group of similar passages. Passages that are not close enough to any group stay Ungrouped rather than being forced into the nearest Topic, so a Topic remains a group of passages that really are alike. Ungrouped is what BERTopic calls outliers and HDBSCAN calls noise. It does not mean the analysis failed on those passages: they were read and compared like every other passage, but were too varied, or too much like everything else, to form a group of their own.
On varied text such as news, much can be Ungrouped. In the informal benchmark below, about 60% of the text was Ungrouped, and 37% of the documents had no Topic at all. That is a fair reason to say the topics do not describe the whole corpus: topic sizes then cannot be read as shares of it. To place that text in topics, use Ungrouped passages under Advanced, which lets Ungrouped passages join the topic they are most similar to. A lower Min topic size is not the remedy: it places little more text and makes many more small topics.
The Ungrouped bubble and list entry. Ungrouped has a bubble of its own, in the grey Wordflow uses for things not analysed, always in the bottom-left corner of the map, and an entry in the Topic list with no topic words, sorted by size like the Topics. Its size is the number of documents that are fully Ungrouped: none of their text is in any Topic. Selecting it works like selecting a Topic. Its examples are shown in random order, since Ungrouped has no centre to rank them by.
Why only fully Ungrouped documents. Ungrouped is not ranked in Topics per doc (Top topics per document), because it is not a theme: it is the passages that matched none. If it were ranked, a document that is 60% Ungrouped and 40% about a sugar tax would leave the sugar tax bubble at Top 1, hiding the one thing it is about, and the Ungrouped bubble would hold two thirds of the documents. Kept out of the ranking:
- every document with any real Topic is in at least one Topic bubble, since its strongest Topic always counts;
- every document with no real Topic is in the Ungrouped bubble;
- so the bubbles cover the whole corpus, and selecting all of them and adding One row per document gives back every document.
A document's main topic (TOPIC_top1) is a different measure: the label that
covers most of its text, where Ungrouped counts. A document with 40% of its
text in a Topic and 60% Ungrouped has Ungrouped as its main topic, but is still
in that Topic's bubble.
Ungrouped in Add to Project follows the same rules as a Topic:
- One row per document takes the documents in the chosen bubbles: those whose Top topics per document include a chosen Topic, and, for Ungrouped, the fully Ungrouped documents.
- One row per topic takes every passage of each chosen Topic, from every document that has any, whatever the Topic's rank in the document. So it can have more documents than the bubble counts. In the benchmark this added about 6% more documents across all Topics; for one Topic, 656 documents against a bubble of 552. With Ungrouped chosen, it takes the Ungrouped passages of every document: for example 500 fully Ungrouped documents (their full text) and 1,000 partly Ungrouped documents (only their Ungrouped passages) give 1,500 rows.
A theme every document shares does not become a Topic. Topics come from what makes groups of passages different from one another, and topic words favour what one Topic has that the others do not. In a corpus collected with a search term, such as obesity, that term is the background of every document; the Topics are the many settings it appears in (sleep, school canteens, a sugar tax, a sports doping case).
Fewer Ungrouped documents. Min topic size and Max topic size are not the way: they decide which topics are found, and change how much is Ungrouped only a little. A slightly smaller Min topic size may group a few more documents, but makes many more, smaller Topics; in the benchmark, 37% fell to 30% at 5, with 2,848 Topics instead of 782, and on other corpora the change can be about one percentage point. A larger size can put almost everything into one Topic. To place Ungrouped text in the topics already found, use Ungrouped passages under Advanced. With Suggestions on, a result with 30% or more of its documents Ungrouped suggests that setting.
Top topics per document controls how many of each source row's strongest positive real-topic shares contribute to bubble counts. The default is 2. Topic −1 and zero shares never count. If several Topics tie at the cutoff, all tied Topics count, so one row may contribute to more than this number and to several bubbles. The question-mark tooltip beside the control summarises this counting behaviour.
Enter a value and press Enter or leave the input to request one update. Partial input and the already-applied value make no request. Changing only this value updates bubble sizes, corpus composition, Topic lists, tooltip counts, CSV, and publication membership without moving the Topic layout or clearing selection, search, lasso filters, pan, zoom, or an open Add to Project dialog.
For a single-corpus result, Colour by colours the bubbles by a metadata column instead of the Data Block colour, so you can see, for example, which topics each party or decade talks about most. The list offers every column (other than the text column) with 2 to 8 distinct values among the analysed documents: text, true/false, or numbers. Each name is followed by its number of values, for example Country (3). A column with a single value is not listed, because every bubble would get the same colour. Values are read from the Data Block when you choose them, so columns added after the run, such as annotation columns, are included. Empty values form a grey (missing) group.
When no column has 2 to 8 values, Colour by stays on Data Block colour and cannot be changed; hover over it to see why. It is also unavailable for a result from two Data Blocks, where the bubble colours already show which Data Block each topic comes from.
Each value counts the documents whose Top topics per document include the topic, the same rule as bubble size. To stop common values dominating, each count is divided by how many documents have that value, and the bubble blends the two values most over-represented in the topic, as in a two-corpus run. The hover card and topic list show every value's count and percentage (see Counts and percentages), a legend under the graph maps colours to values, and a downloaded graph includes that legend. Choose Data Block colour to return to the usual colouring. The choice is not saved and resets when you run the analysis again. No re-run is needed.
The blended colour shows the two values most over-represented in a topic, but not whether the topic is concentrated in those values or spread across all of them. Bubble opacity adds that: the more a topic is concentrated in a few values, the more solid its bubble; the more evenly it is spread, the paler. A topic from a single value is the most solid, and a topic spread evenly across every value is the palest.
Opacity comes from the topic's concentration, which is one minus Pielou's evenness:
- Each value's share: its count in the topic divided by how many documents have that value (as for the colour), then scaled so that the shares of all K values of the column add up to 1: p₁, p₂, …, pK.
- Evenness J = H ÷ ln K, where H = −Σ pᵢ ln pᵢ is the Shannon entropy of the shares (values with a share of 0 add nothing). J is 1 for a perfectly even spread and 0 when one value has everything.
- Concentration C = 1 − J.
- Opacity = 0.25 + 0.55 × √C, so it ranges from 0.25 (even) to 0.8 (one value). The square root spreads out the middle, where most topics are.
For example, with three values of equal size, a topic with counts 60, 58, and 10 has C ≈ 0.17 and opacity ≈ 0.48, while counts 60, 58, and 57 give C ≈ 0 and opacity ≈ 0.26. Hovering over a bubble lifts it above this range, and selected topics are marked by an outline, so neither changes what the opacity means. Without Colour by, every bubble uses the same opacity.
Words per topic controls how many representative words appear in the topic
list, search, and hover cloud. The default is 15 and the range is 3-100. The
switch before the stop words dropdown applies the Tab's saved list. While it is
off, the dropdown reads Use stop words. Choosing a list from the dropdown
switches it on, and the dropdown then shows Saved list (N words). To stop
using the list, turn the switch off or choose Don't use stop words; the
saved list is kept for next time. You can edit the list while it is off.
The dropdown's From other tabs group lists stop words saved in your other
Frequency or Topic Modelling tabs; Wordflow classic lists offers the built-in
lists earlier Wordflow versions used; Languages (stopword library) offers
default lists from the open-source stopword package: it shows the language
detected from the first selected Data Block, marked (Detected), and Show
all languages reveals the rest. Any choice appends its words to the
saved list (duplicates are skipped, so you can combine lists and keep custom
words), copied tab lists stay independent afterwards, and Clear stop words
empties the list. These controls change presentation without rerunning or refetching the
Result.
Each bubble is a discovered topic. Bubble size reflects source rows whose positive share for that Topic is within the displayed Top topics per document; in a two-corpus run, colour composition compares the Topic's share of each analysed corpus, then normalises those two shares for the colour blend. This prevents a larger corpus from dominating the colour solely because it has more rows. With two Data Blocks, a Bubble colour legend under the graph names each Data Block beside its colour, and the blend between them; downloads carry the same legend. A row may count in multiple bubbles, so bubble totals need not equal the source-row count. Nearby bubbles have more similar topic representations. Only closeness matters: left, right, up and down have no meaning, so the map is stretched to fill the chart area, from 2.5 times as wide as it is tall to 2.5 times as tall as it is wide, and is laid out again when you resize the chart. Bubbles may overlap, but positions are nudged apart just enough that no topic is hidden: the centre (and label) of the smaller of two bubbles always stays outside the larger one, the smaller bubble moves more, and bubbles stay as close to their original positions as possible. Smaller bubbles are drawn on top. The grey Ungrouped bubble sits in the bottom-left corner, apart from the Topics, and holds the documents that are fully Ungrouped. Topics with a total bubble count of zero are omitted from the graph but remain available in the Topic lists and Result data.
The hover card and the topic list show a topic's size as one coloured chip per Data Block, or per value when Colour by is on, followed by the total. Each chip has two numbers, for example 296 · 7.9%:
- The count is how many documents from that group are in the topic. These are the rows you get from that group when you add the topic to your Project.
- The percentage is that count out of all the group's documents in this run (after sampling). Hover over a chip to see both numbers, for example Senate: 353 of 2,871 documents (12.3%).
The percentages in one topic do not add up to 100%, because each one is out of a different group. A topic that every group talks about can hold 70% of each group's documents, and a small topic may hold 2% of each.
When Top topics per document is more than 1, one document can be in several topics. Then a group's percentages across all the topics can add up to more than 100%.
The bubble colour compares these percentages, not the counts. That is why a group with few documents can colour a bubble with only a few of them: 1 of 15 documents (6.7%) weighs about as much as 296 of 3,729 (7.9%).
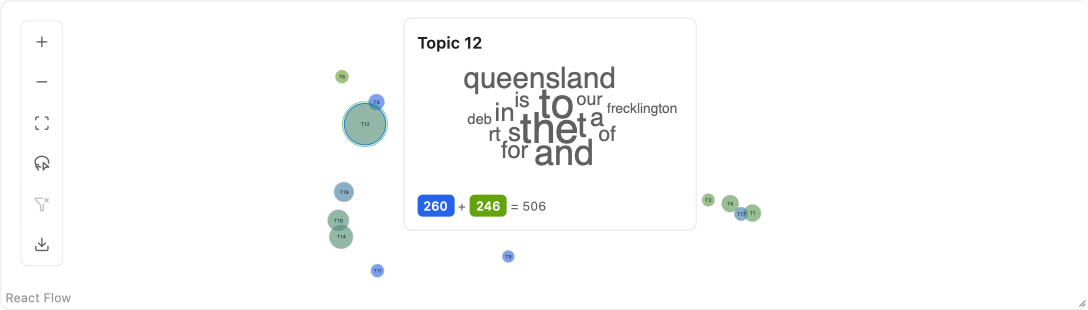
Hover for a representative-word cloud. Word order reflects c-TF-IDF distinctiveness, while word size reflects occurrences in assigned passages. Because passages do not overlap, source tokens are not counted twice. These are not source-document frequencies.
Drag empty graph space to pan. To zoom, pinch on a trackpad, or hold ⌘ on a Mac (Ctrl elsewhere) while scrolling; a plain scroll scrolls the page, even over the graph. The graph initially
fits every bubble; use Fit view to restore that complete view after moving
around. Select topics directly, or enable the lasso control and draw around
several Topic centres. Lasso mode remains active and later strokes add to the
filter of the topic list; use Clear filter in the graph toolbar to
remove that accumulated filter without changing manually selected Topics.
A Search term further narrows the list and fades the other topics in the
graph. Spaces, commas and other punctuation separate several terms, and a topic
matches when any one of its words contains any one term: chil, home finds
topics with child, children or chill, and topics with home or
homeless. * (any letters) and ? (one letter) match a whole word, so gs*
and gs? both find topics with gst wherever it is in their list. Matching
words are bold in the topic list and in a bubble's word cloud, in one colour
per term: orange for the first term, then blue, green, purple, red and yellow.
The list heading counts the topics, for example Topics 249. While Find topics or the lasso is filtering, it shows how many match out of all of them, for example Topics 15 / 249. Click a topic in the chart or in the list to select it; click it again to deselect it, or use Clear to deselect them all. Selected topics move to the Selected group at the top of the list, the latest selected first. The group scrolls on its own, so the Others below always stay in reach. Selected topics stay in their group even when the search or lasso leaves them out; they are then shown faded. Hover over a topic's words to see all of them.
To see the texts behind a topic, click the eye at the right of its card in the list, or right-click its bubble. Its example passages then appear beside the list, and an eye marks its card and its bubble. Only one topic is shown at a time: showing another replaces it. Click the eye or right-click the bubble again, or close the examples with ×, to stop showing them. Faded bubbles cannot be right-clicked. The search term and the lasso never hide the examples; if they leave out the shown topic, a note says so, with Clear filters.
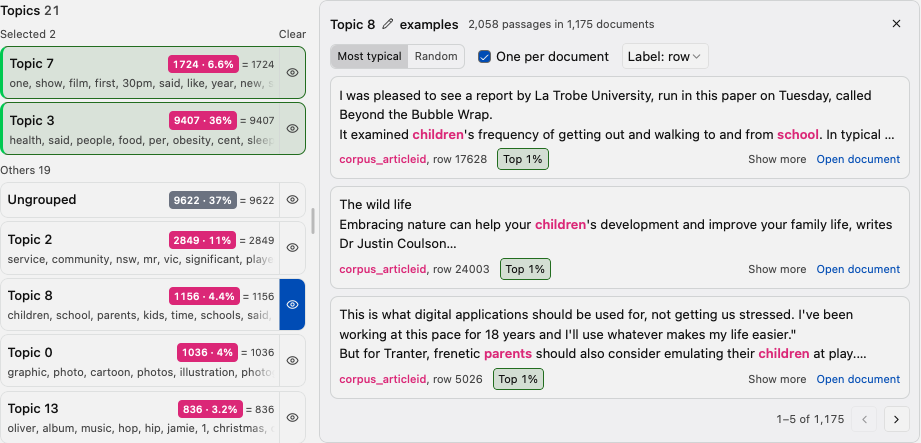
- Most typical lists the passages closest to the centre of the topic first. The centre is the average of the passages grouping put in the topic. Random lists them in a random order set by the run's seed, so the same run always gives the same examples.
- One per document (on by default) shows only the most typical (or first random) passage of each document.
- With Colour by on, you can limit the examples to one of its values. For a two-corpus run, you can limit them to one Data Block.
- Each example is named by its Data Block, in the Data Block's colour, and its row. Label replaces the row with another column, such as a speaker or a date; a row without a value says so, for example (no speaker). For a two-corpus run, the menu lists only the columns both Data Blocks have.
Each example shows about three lines (Show more shows the whole passage), the topic's words in the bubble's colour, and a badge such as Top 10%: this passage is more typical of the topic than 90% of its passages. Green marks the top quarter, amber the middle half and grey the bottom quarter. Hover over the badge for the passage's similarity to the topic's centre. The badge ranks passages within one topic; it is not the chance that the passage belongs to the topic. For a topic merged from several, the centre and the rank are those of all its grouped passages together, so a passage's badge changes as you change Topics.
With Ungrouped passages set to let passages join, an example that joined after grouping is marked, for example Joined · Top 60%. Its rank is on the same scale as the others: where it falls among the passages grouping put in the topic, measured from their centre. Grouped passages therefore keep the badge they would have had with Stay Ungrouped. Joined · Outside marks a passage that is less similar to the centre than every grouped passage. With Join a topic they fit that is uncommon and happens in a merged topic, because the passage was admitted against the topic it joined, not against the broader one; with Always join the nearest topic it is common. Runs from Wordflow 0.7.10 or earlier list their examples without a badge; run Topic Modelling again to rank them.
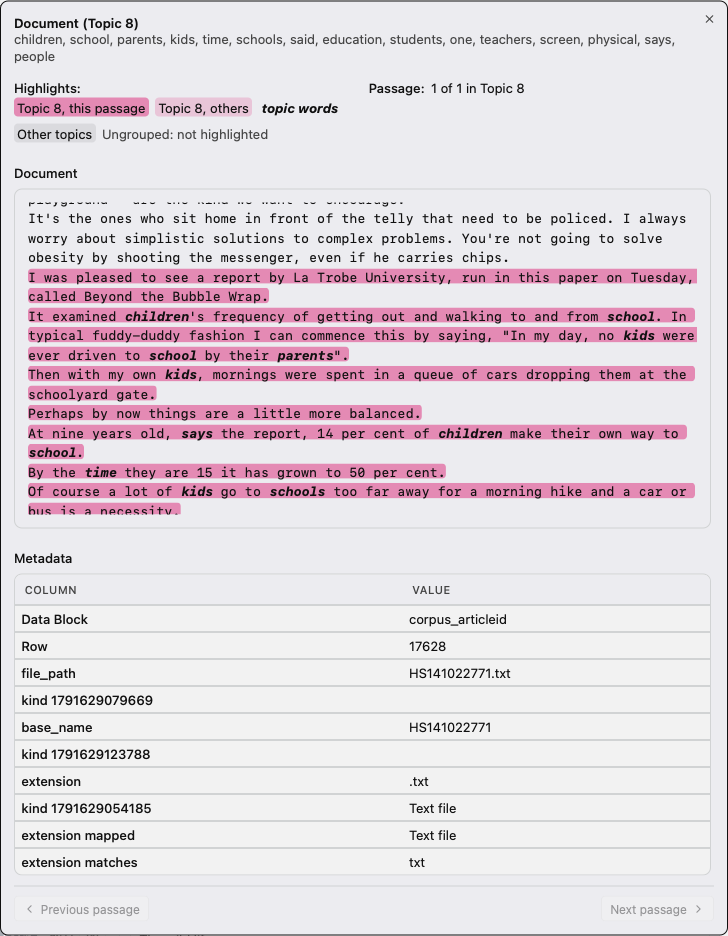
Open document shows the whole document with its metadata, and the topic's words under the title for reference. The opened passage has a tint of the bubble's colour; the topic's other passages in the document have a lighter tint of it, and passages of other topics a grey one. In the topic's passages, its words are bold and italic. Ungrouped text is not highlighted. Previous passage and Next passage step through the shown topic's passages in that document.
Choose Add to Project to publish
manually selected topic data and linked topic meanings as new Data Blocks.
For a two-source result, Sync columns applies exact, case-sensitive shared
source-column selections to both checked Data Blocks. Enabling it combines the
currently selected shared names; individual choices and Select all or
Select none then update both sources. Source-only columns are disabled while
sync is active, and an unchecked source keeps its independent selection.
TOPIC_top1 remains required and is not synchronised. If fewer than two sources
remain checked, Sync columns turns off automatically. When the source Data Block
was itself made by Topic Modelling, its old TOPIC_ columns are not offered: the
new ones replace them. A TOPIC_ column cannot be the text to model, because it
holds topics from an earlier run rather than documents; Wordflow says so.
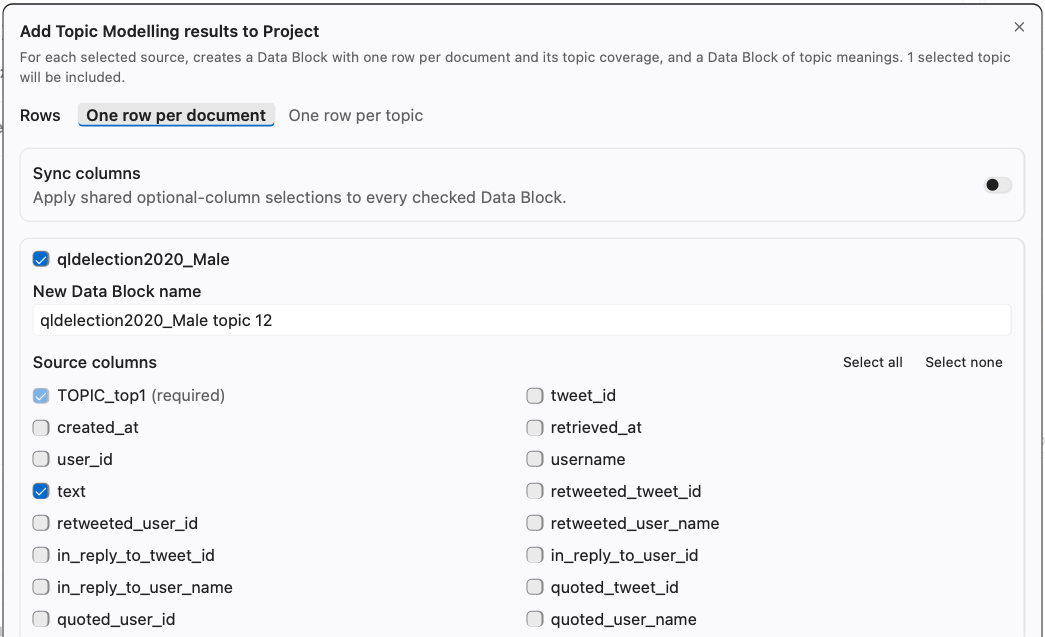
The Rows choice in the dialog sets how rows are formed:
-
One row per document (default): one row per source document, with its dominant topic (
TOPIC_top1) and full topic coverage (TOPIC_coverage).Most tools cannot use the
TOPIC_coveragecolumn yet. Analyses leave it out of the metadata they show and carry; in the Data Builder only Filter can use it (to keep rows by a topic threshold), and in the Data Editor it can only be duplicated, renamed, or deleted. CSV and Excel exports write it as text; Parquet keeps it as it is. -
One row per topic: one row for each topic in each document. The document column holds only the passages assigned to that topic, joined by line breaks in source order, so a document with three topics becomes three rows. Each row also carries the topic (
TOPIC_topic), its share of the document's text (TOPIC_share), and how many passages it joined (TOPIC_segment_count). Ungrouped passages are left out unless you choose Ungrouped (its rows haveTOPIC_topic−1), and every passage of a chosen topic is taken, so there can be more documents than its bubble counts (see Ungrouped). Use this when you are interested in particular topics rather than whole documents.
The suggested name for each new Data Block includes the selected topic numbers, for example Corpus topic 5, Corpus ungrouped or Corpus topics 3, 7 (with more than three topics selected, Corpus 8 topics). One row per topic names end in passages, for example Corpus topic 5 passages. You can edit the name before adding it.
Both modes use the topics as currently shown, including any merging from Number of topics. One row per topic needs a result from this version of Wordflow; for older results, re-run the analysis first.
The download control exports the current panned and zoomed graph viewport. Its header records Data Block, cluster count, Top topics per document, random seed, and Topic count. CSV output still contains every topic and its current counts.
Choose Interactive HTML to save the graph as one web page that opens in any browser, offline. It shows the graph exactly as on screen (positions, colours, selection rings and faded topics) and keeps three things to explore: hover a bubble for its words, sized by count, and the same size chips as the app (per colour-by value, or per Data Block); type a Search term to highlight matching topics, with the same rules as the app's search; and drag to move, or hold Command (Mac) or Control (Windows) while scrolling to zoom. Once zoomed in, plain scrolling moves the graph in any direction; at full size it scrolls the page. Reset view returns to the whole graph. The last line links to the Wordflow home page. It cannot change the topics or add anything to a Project.
Clear removes this tab's result. The selected Passages method, Max tokens value, and Topic size range remain available for the next run.
| Symptom | What to try |
|---|---|
| Almost all passages are Ungrouped | Increase sampling, try another Passages setting, or check whether the corpus has shared themes |
| 30% or more of the documents are Ungrouped | Under Advanced, set Ungrouped passages to Join a topic they fit and run again |
| Topics change substantially between runs | Increase sampling and compare runs with fixed seeds |
| Representative words describe formatting rather than subject matter | Clean boilerplate or choose a Passages setting that better matches the document structure |
| A structural unit becomes many passages | Increase Maximum tokens per passage or choose a coarser Passages setting |
| Run time is very long | Reading the text takes most of a first run and depends on how much text there is, so reduce the per-Data-Block sampling percentage. A larger Max tokens and Topic sampling shorten only the later grouping step |
| Setting | Default |
|---|---|
| Sampling | 100% per Data Block |
| Passages | Automatic |
| Max tokens | Auto |
| Topic size | 10 to Auto |
| Seed | 0 |
| Topic sampling | Off; suggested for very large corpora |
| Ungrouped passages | Stay Ungrouped |
| Topics per doc | 2, or the available Topic count when smaller |
| Words per topic | 15 |
- Run a corpus with Passages set to Automatic.
- Change Top topics per document and compare bubble membership without moving the map.
- Move Number of topics down and compare the merged representative words.
- Clear the Result, choose Paragraph or Sentence, and run again with the same sample and seed.
- Compare the topic map, representative words, and how many passages are Ungrouped.
This is one ad hoc comparison, made once while developing Wordflow. It used one corpus, one computer and two seeds. It is here for reference only and is not guidance: other corpora, languages, computers and settings can behave quite differently, so try settings on your own data.
- Corpus: 26,163 news articles that mention obesity (about 25 million tokens, about 3,800 characters per article).
- Computer: Apple M5 Pro, 18 cores, 64 GB memory.
- Settings: Automatic passages, Topic size 10 to Auto, no sampling, no Topic sampling, seeds 0 and 1. Max tokens 128 and 256.
- Times: the first run of each Max tokens read the text into the model; the second seed reused that work.
| Max tokens 128 | Max tokens 256 | |
|---|---|---|
| Passages | 224,502 | 107,551 |
| First run (seed 0) | 13 minutes | 14 minutes |
| Second run, reading reused (seed 1) | 2.9 minutes | 1.0 minute |
| Topics (seed 0, seed 1) | 1,215 and 60 | 782 and 815 |
| Largest topic's share of passages (seed 0, seed 1) | 2% and 95% | 2% and 2% |
| Topics that are the main topic of 10 or more documents | 83 and 4 | 167 and 157 |
| Text Ungrouped (seed 0) | 69% | 62% |
| Agreement between the two seeds on each document's main topic (0 to 1) | 0.22 | 0.68 |
| Topic word coherence, 20 largest topics (seed 0, seed 1) | 0.29 and 0.16 | 0.26 and 0.29 |
What it showed for this corpus:
- Reading the text took about as long at both sizes; it follows the amount of text, not the passage size.
- 256 grouped the passages about three times faster, because there were half as many.
- 256 gave similar results with both seeds. 128 did not: with seed 1, one Topic took 95% of the passages.
- The largest Topics were much the same at both sizes (for example sleep, junk food advertising, a sugar tax, weight-loss surgery), so 128 did not give sharper Topics.
Topic word coherence is the average normalised pointwise mutual information of each Topic's top 10 words, counted over the corpus's paragraphs; higher means the words appear together more often. Agreement is the normalised mutual information of the documents' main topics in the two runs.
A second comparison on the same corpus and computer, at Max tokens 256 and seed 0, changed Min topic size with the text already read:
| Min topic size | Topics | Grouping time | Text Ungrouped | Documents fully Ungrouped |
|---|---|---|---|---|
| 3 | 9,675 | 6.8 hours | 45% | 16% |
| 5 | 2,848 | 7.6 minutes | 58% | 30% |
| 10 (default) | 782 | about 1 minute | 62% | 37% |
| 20 | 26 | 1.2 minutes | none: one Topic held 94% of the passages | none |
A smaller Min topic size left fewer documents Ungrouped, but made many more, smaller Topics and, at 3, took hours to group. A larger one put almost everything into one Topic (with Wordflow 0.7.11; Auto now splits such a Topic).